
binda
Read and write binary data using Pandas.
Map the data in the binary file to variables, single data structures or repeating data structures. Once mapped, the binary file can be viewed and edited using Pandas DataFrames.
Installation
binda can be installed using pip or conda.
pip install binda
or
conda install binda
Docs
The documentation for binda is available on GitHub Docs here: https://jamiecash.github.io/binda/binda.html
Usage
Given the following binary data (represented as hex):
42:4c:4f:43:4b:44:41:54:41:64:4a:61:6d:69:65:20
43:61:73:68:20:20:20:20:20:01:65:42:6f:62:62:79
20:53:6d:69:74:68:20:20:20:20:00:66:4d:72:20:42
65:61:6e:20:20:20:20:20:20:20:20:01:4d:72:20:41
75:74:68:6f:72:20:20:20:20:20:20:0a:00:ff:ec:00
00:f7:42
Which contaains:
- A 9 bytes string containing 'BLOCKDATA'
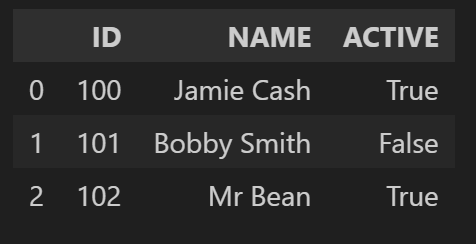
- 3 repeating records of 17 bytes containing a 1 byte integer ID, a 15 bytes string NAME and a 1 byte interger ACTIVE flag
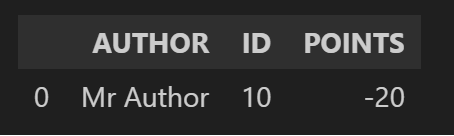
- 19 bytes containing a 15 bytes string AUTHOR, a 2 bytes integer ID and a 2 bytes bigendian signed integer POINTS.
First create the data handler with the data.
data = b'BLOCKDATAdJamie Cash     \x01eBobby Smith    \x00fMr Bean        '\
      +b'\x01Mr Author      \n\x00\xff\xec\x00\x00\xf7B'

handler = bd.DataHandler(data)
The name from the first record can be read by creating a variable, specifying a name for the variable, it's size, it's datatye and it's offset.
print("Name: " + handler.read_variable(bd.Variable('name', 15, str, 10)))
Name: Jamie Cash
The 19 bytes of author data starting at offset 60 can be read into a Pandas DataFrame by specifying the layout of the structure, including its variables. The DataHandler can then be used to read it.
author_struct = \
      bd.Structure(60, [bd.Variable('AUTHOR', 15, str),
                        bd.Variable('ID', 2, int),
                        bd.Variable('POINTS', 2, int,
                                    byteorder=bd.ByteOrder.BIG, signed=True)])
handler.add_structure('author', author_struct)
df = handler.read_structure('author')
df
The three row repeating structure can be read in a similar way, but this time also specifying the number of rows.
people_struct = \
  bd.Structure(9, [bd.Variable('ID', 1, int),
                    bd.Variable('NAME', 15, str),
                    bd.Variable('ACTIVE', 1, bool)], rows=3)

handler.add_structure('people', people_struct)
df = handler.read_structure('people')
df
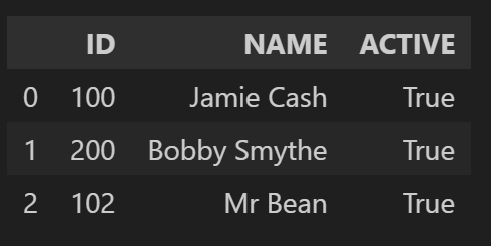
The dataframe can be edited, and saved back to edit the binary data.
# Change Bobby Smiths name to Bobby Smythe, his ID to 200 and is active
# status to True
df.loc[df['ID'] == 101, 'ID'] = 200
df.loc[df['ID'] == 200, 'NAME'] = 'Bobby Smythe   '
df.loc[df['ID'] == 200, 'ACTIVE'] = True
handler.write_structure('people', df)

# Confirm that the change has been made to the data by re-reading it and
# displaying
df = handler.read_structure('people')
df
We can also check the binary data to see the change.
print(handler.data[26:43])
b'\xc8Bobby Smythe \x01'
Examples
2 Jupyter notebooks are provided in the examples folder, one containing the code from the Usage section above and one containing an example on reading and writimg Exif data to a .jpeg file.
Joining the Project Team
This project is maintained on GitHub:
If you would like to contribute to this project by fixing issues or adding features, please follow the below steps:
- If adding functionality or fixing an issue not already raised on GitHub, raise an issue.
- Assign the issue(s) to yourself.
- Fork the project.
- Create a branch from master.
- Make the required changes to the project in your local branch.
- Commit your changes, adding comments referencing the issues that your changes fix.
- Push this branch to your GitHub project.
- Open a Pull Request on GitHub.
- Email me at jlcash@gmail.com to discuss the changes made.
- Once changes have been agreed, I will merge or close the pull request.
- Sync the updated master back to your fork.
- Close the issues that were fixed.
1 maintainer

Metadata
1 maintainer
Release files for binda 1.0.22
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| binda-1.0.22.tar.gz | 7.0 MB | Without provenance | Details for binda-1.0.22.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| binda-1.0.22-py3-none-any.whl | Python 3 | none | any | Details for binda-1.0.22-py3-none-any.whl |
Total release size: 13.9 MB
Release files / binda-1.0.22.tar.gz
| Download URL | binda-1.0.22.tar.gz |
|---|---|
| Size | 7.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4c902a5cf5034eaf9e88e1ad04e9108121da72dc1c2ea71cd3520a1f3fff7691
|
|
BLAKE2b-256 checksum How to use checksums |
bd64d00fbe3d2e07e8d7bbd73e17acd8da834c98e9850b855c00b8aa7b4733e7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.11.5
|
Release files / binda-1.0.22-py3-none-any.whl
| Download URL | binda-1.0.22-py3-none-any.whl |
|---|---|
| Size | 7.0 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
57a542c21d37b271109759d2c37aed4eff73789d03e88714571d5ea0fe616367
|
|
BLAKE2b-256 checksum How to use checksums |
898dff9b7b57da8f754bceda13e1a494361824daabdd86665828e03e2333622a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.11.5
|
Security for binda 1.0.22
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














