
Brickflow


BrickFlow is specifically designed to enable the development of Databricks workflows using Python, streamlining the process through a command-line interface (CLI) tool.
Contributors
Thanks to all the contributors who have helped ideate, develop and bring Brickflow to its current state.
Contributing
We're delighted that you're interested in contributing to our project! To get started, please carefully read and follow the guidelines provided in our contributing document.
Documentation
Brickflow documentation can be found here.
Getting Started
Prerequisites
- Install brickflows
pip install brickflows
- Install Databricks CLI
curl -fsSL https://raw.githubusercontent.com/databricks/setup-cli/main/install.sh | sudo sh
- Configure Databricks cli with workspace token. This configures your
~/.databrickscfgfile.
databricks configure --token
Hello World workflow
- Create your first workflow using brickflow
mkdir hello-world-brickflow
cd hello-world-brickflow
brickflow projects add
- Provide the following inputs
Project name: hello-world-brickflow
Path from repo root to project root (optional) [.]: .
Path from project root to workflows dir: workflows
Git https url: https://github.com/Nike-Inc/brickflow.git
Brickflow version [auto]:<hit enter>
Spark expectations version [0.5.0]: 0.8.0
Skip entrypoint [y/N]: N
Note: You can provide your own github repo url.
- Create a new file hello_world_wf.py in the workflows directory
touch workflows/hello_world_wf.py
- Copy the following code in hello_world_wf.py file
from brickflow import (
    ctx,
    Cluster,
    Workflow,
    NotebookTask,
)
from airflow.operators.bash import BashOperator


cluster = Cluster(
    name="job_cluster",
    node_type_id="m6gd.xlarge",
    spark_version="13.3.x-scala2.12",
    min_workers=1,
    max_workers=2,
)

wf = Workflow(
    "hello_world_workflow",
    default_cluster=cluster,
    tags={
        "product_id": "brickflow_demo",
    },
    common_task_parameters={
        "catalog": "<uc-catalog-name>",
        "database": "<uc-schema-name>",
    },
)

@wf.task
# this task does nothing but explains the use of context object
def start():
    print(f"Environment: {ctx.env}")

@wf.notebook_task
# this task runs a databricks notebook
def example_notebook():
    return NotebookTask(
        notebook_path="notebooks/example_notebook.py",
        base_parameters={
            "some_parameter": "some_value",  # in the notebook access these via dbutils.widgets.get("some_parameter")
        },
    )


@wf.task(depends_on=[start, example_notebook])
# this task runs a bash command
def list_lending_club_data_files():
    return BashOperator(
        task_id=list_lending_club_data_files.__name__,
        bash_command="ls -lrt /dbfs/databricks-datasets/samples/lending_club/parquet/",
    )

@wf.task(depends_on=list_lending_club_data_files)
# this task runs the pyspark code
def lending_data_ingest():
    ctx.spark.sql(
        f"""
        CREATE TABLE IF NOT EXISTS
        {ctx.dbutils_widget_get_or_else(key="catalog", debug="development")}.\
        {ctx.dbutils_widget_get_or_else(key="database", debug="dummy_database")}.\
        {ctx.dbutils_widget_get_or_else(key="brickflow_env", debug="local")}_lending_data_ingest
        USING DELTA -- this is default just for explicit purpose
        SELECT * FROM parquet.`dbfs:/databricks-datasets/samples/lending_club/parquet/`
    """
    )
Note: Modify the values of catalog/database for common_task_parameters.
- Create a new file example_notebook.py in the notebooks directory
mkdir notebooks
touch notebooks/example_notebook.py
- Copy the following code in the example_notebook.py file
# Databricks notebook source

print("hello world")
Deploy the workflow to databricks
brickflow projects deploy --project hello-world-brickflow -e local
Run the demo workflow
- Login to databricks workspace
- Go to the workflows and select the workflow
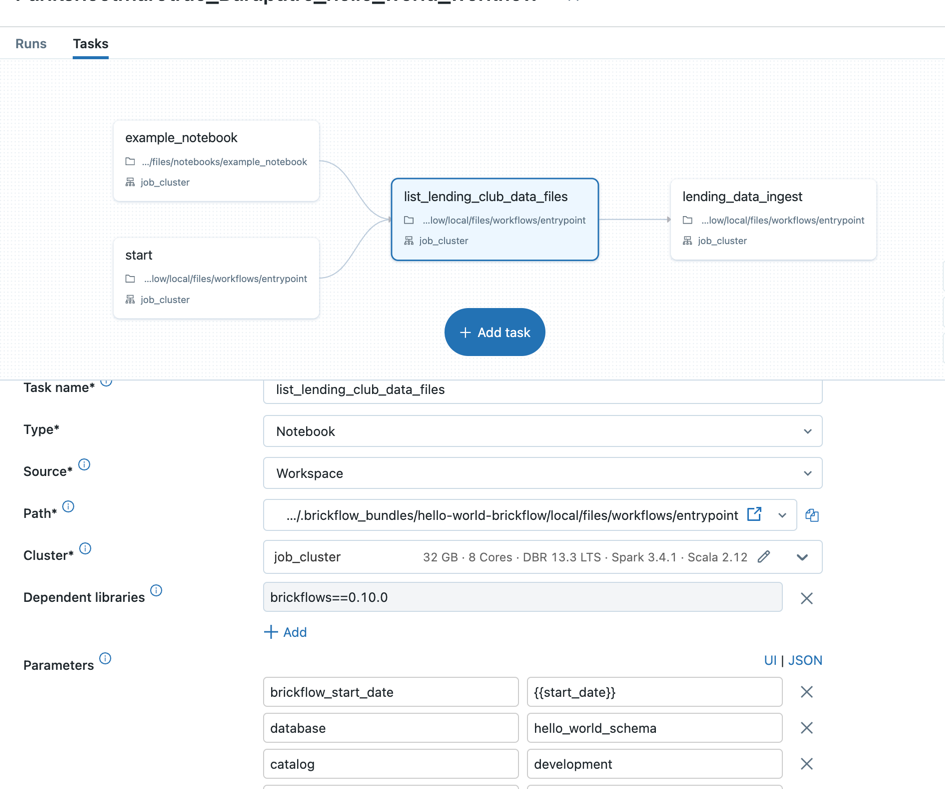
Examples
Refer to the examples for more examples.
1 maintainer

Metadata
1 maintainer
Release files for brickflows 2.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| brickflows-2.0.0.tar.gz | 139.1 kB | Without provenance | Details for brickflows-2.0.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| brickflows-2.0.0-py3-none-any.whl | Python 3 | none | any | Details for brickflows-2.0.0-py3-none-any.whl |
Total release size: 297.5 kB
Release files / brickflows-2.0.0.tar.gz
| Download URL | brickflows-2.0.0.tar.gz |
|---|---|
| Size | 139.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8331e1711b0a28768bc7bec75f3bd323e8f225c7a30a663c0a88babc22f01e1f
|
|
BLAKE2b-256 checksum How to use checksums |
40abbda686bb4fcbe745a8751d9dcf9639b270833392d4c4a981a0f89b18ab59
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.20
|
Release files / brickflows-2.0.0-py3-none-any.whl
| Download URL | brickflows-2.0.0-py3-none-any.whl |
|---|---|
| Size | 158.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3d80aeb9c55a5e0e7cba5cad8b72260cd7f4ba9ef6a4b7eca90f6aab3d379ab8
|
|
BLAKE2b-256 checksum How to use checksums |
fe2a8f995b67bfff74b4196285c85ffee4bd5d89119cc7aa27163ffb385d9738
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.20
|
Security for brickflows 2.0.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














