
CoCrawler


CoCrawler is a versatile web crawler built using modern tools and concurrency.
Crawling the web can be easy or hard, depending upon the details. Mature crawlers like Nutch and Heritrix work great in many situations, and fall short in others. Some of the most demanding crawl situations include open-ended crawling of the whole web.
The object of this project is to create a modular crawler with pluggable modules, capable of working well for a large variety of crawl tasks. The core of the crawler is written in Python 3.5+ using coroutines.
Status
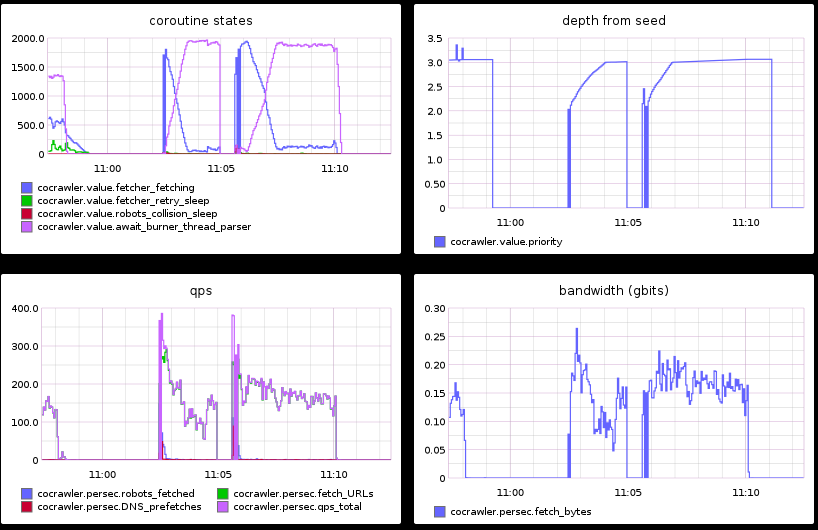
CoCrawler is pre-release, with major restructuring going on. It is currently able to crawl at around 170 megabits / 170 pages/sec on a 4 core machine.
Screenshot:
Installing
We recommend that you use pyenv, because (1) CoCrawler requires Python 3.5+, and (2) requirements.txt specifies exact module versions.
git clone https://github.com/cocrawler/cocrawler.git
cd cocrawler
make init  # will install requirements using pip
make pytest
make test_coverage
Pluggable Modules
Pluggable modules make policy decisions, and use utility routines to keep policy modules short and sweet.
An additional set of pluggable modules provide support for a variety of databases. These databases are mostly used to orchestrate the cooperation of multiple crawl processes, enabling the horizontal scalability of the crawler over many cores and many nodes.
Crawled web assets are intended to be stored as WARC files, although this interface should also pluggable.
Ranking
Everyone knows that ranking is extremely important to search queries, but it's also important to crawling. Crawling the most important stuff is one of the best ways to avoid crawling too much webspam, soft 404s, and crawler trap pages.
SEO is a multi-billion-dollar industry created to game search engine ranking, and any crawl of a wide swath of the web is going to run into poor-quality content attempting to appear to have high quality. There's little chance that CoCrawler's algorithms will beat the most sophisticated SEO techniques, but a little ranking goes a long way.
Credits
CoCrawler draws on ideas from the Python 3.4 code in "500 Lines or Less", which can be found at https://github.com/aosabook/500lines. It is also heavily influenced by the experiences that Greg acquired while working at blekko and the Internet Archive.
License
Apache 2.0
1 maintainer

Release files for cocrawler 0.1.14
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cocrawler-0.1.14-py3-none-any.whl | Python 3 | none | any | Details |
Release files / cocrawler-0.1.14-py3-none-any.whl
| Download URL | cocrawler-0.1.14-py3-none-any.whl |
|---|---|
| Size | 85.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7c0122368295ebb5171833c58a4c32c858c656c4b72a82add1ed805ef927ac6f
|
|
BLAKE2b-256 checksum How to use checksums |
5ac233cb7b8050aa2be077099b033330a32caaaf95ff293658ad7aa619acc4ab
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.3.0 pkginfo/1.5.0.1 requests/2.24.0 setuptools/53.1.0 requests-toolbelt/0.9.1 tqdm/4.46.0 CPython/3.8.1
|














