
Contextualized Topic Models


Contextualized Topic Models (CTM) are a family of topic models that use pre-trained representations of language (e.g., BERT) to support topic modeling. See the papers for details:
Cross-lingual Contextualized Topic Models with Zero-shot Learning https://arxiv.org/pdf/2004.07737v1.pdf
Pre-training is a Hot Topic: Contextualized Document Embeddings Improve Topic Coherence https://arxiv.org/pdf/2004.03974.pdf
Combined Topic Model
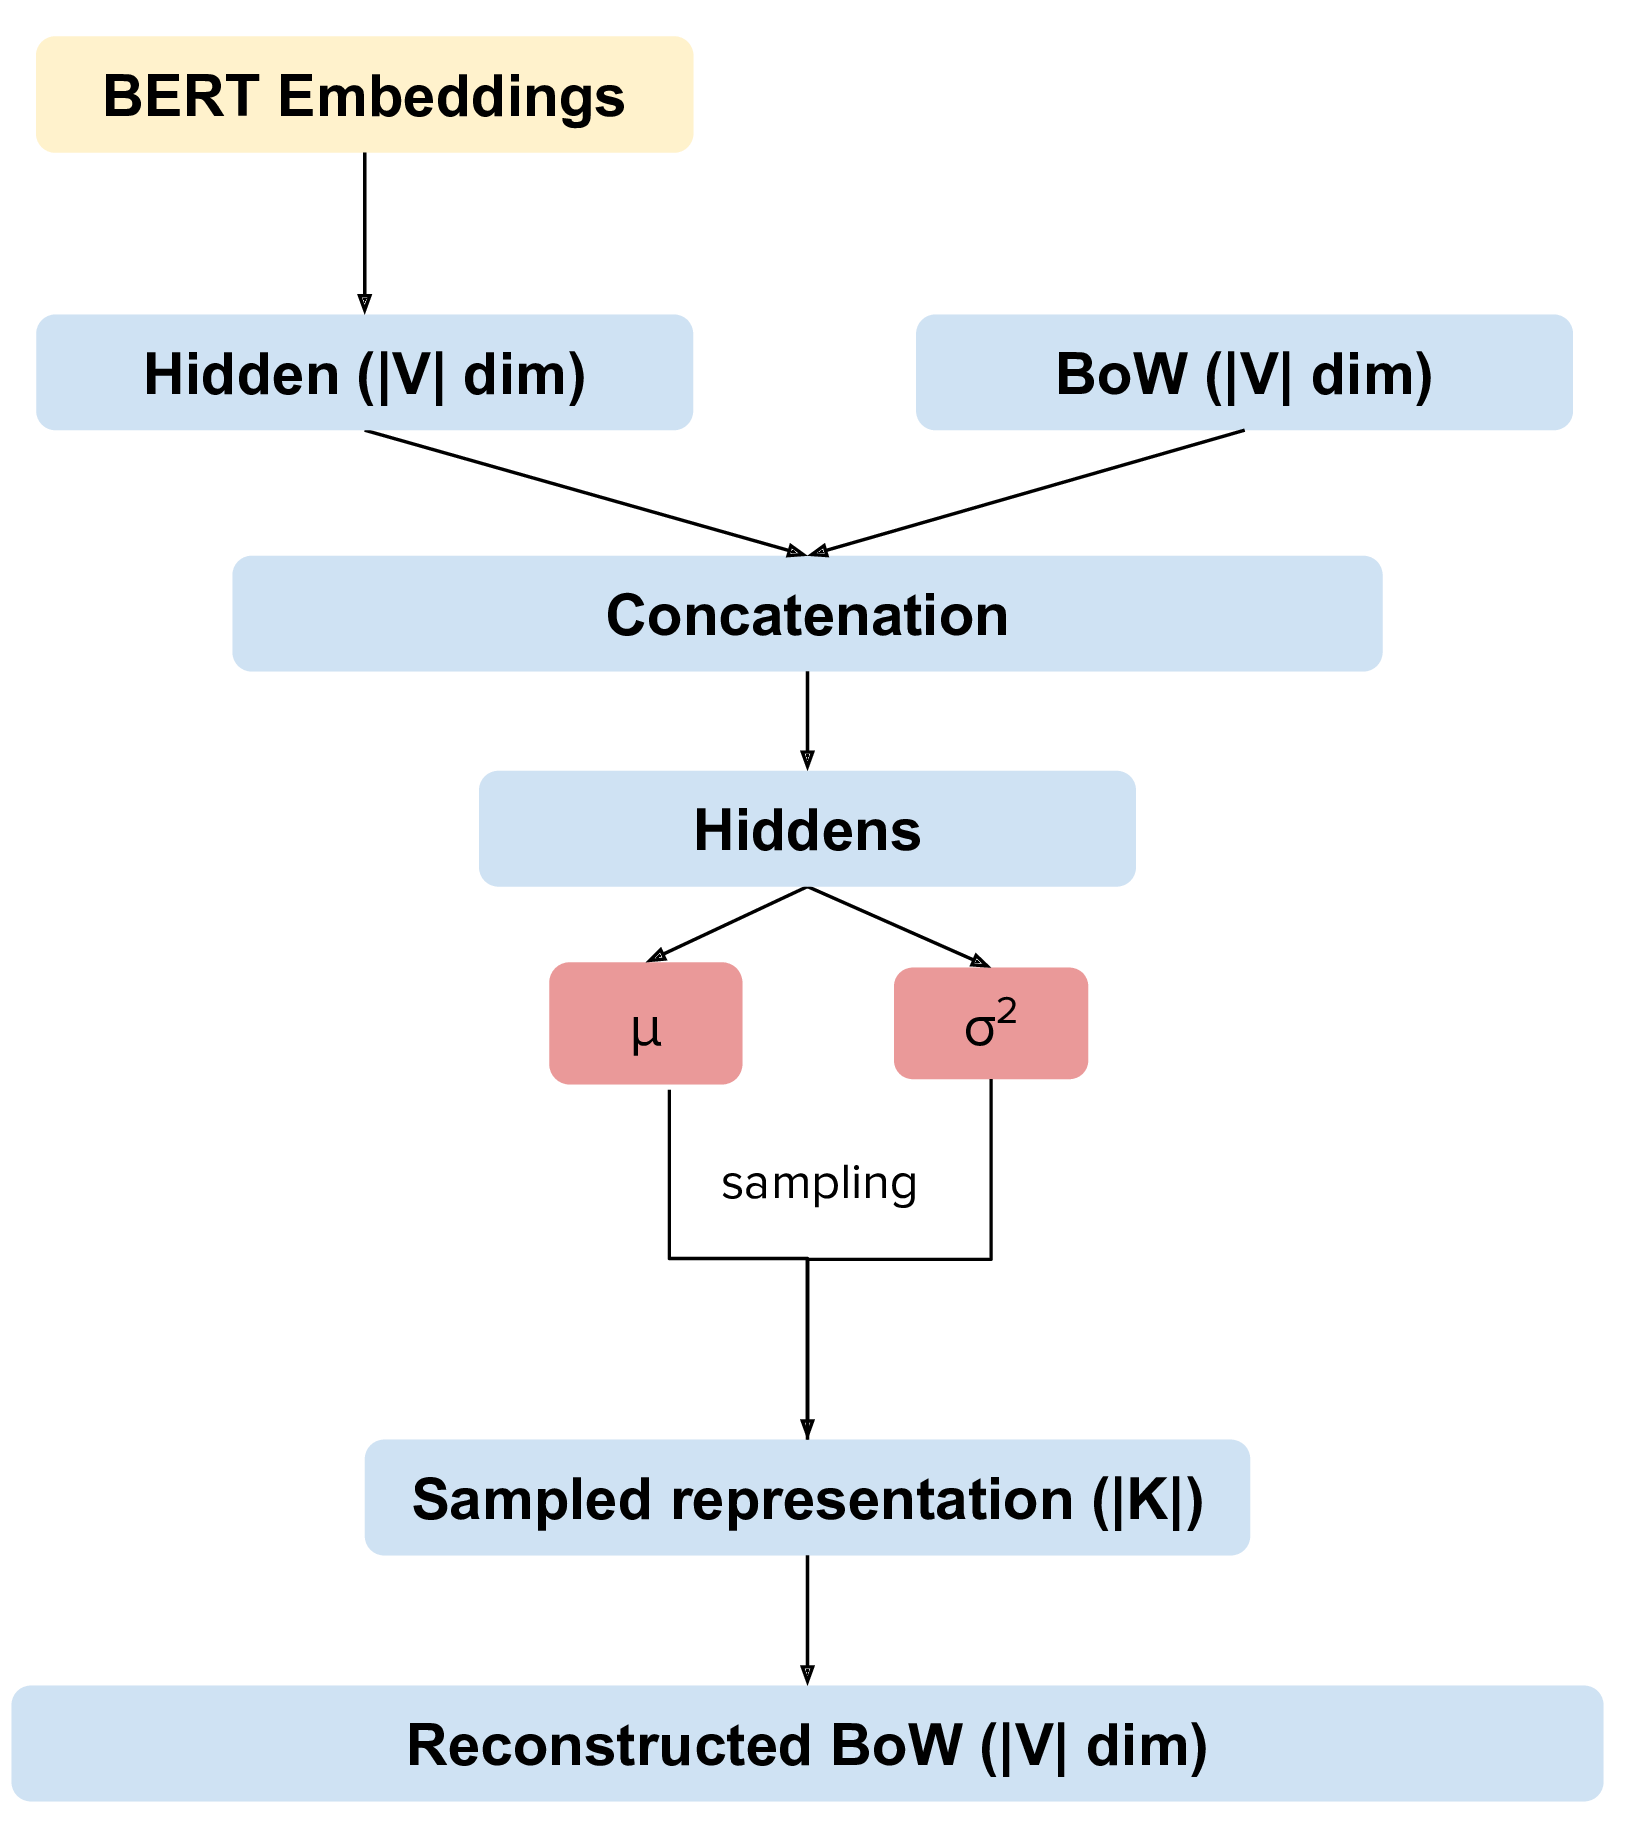
Fully Contextual Topic Model
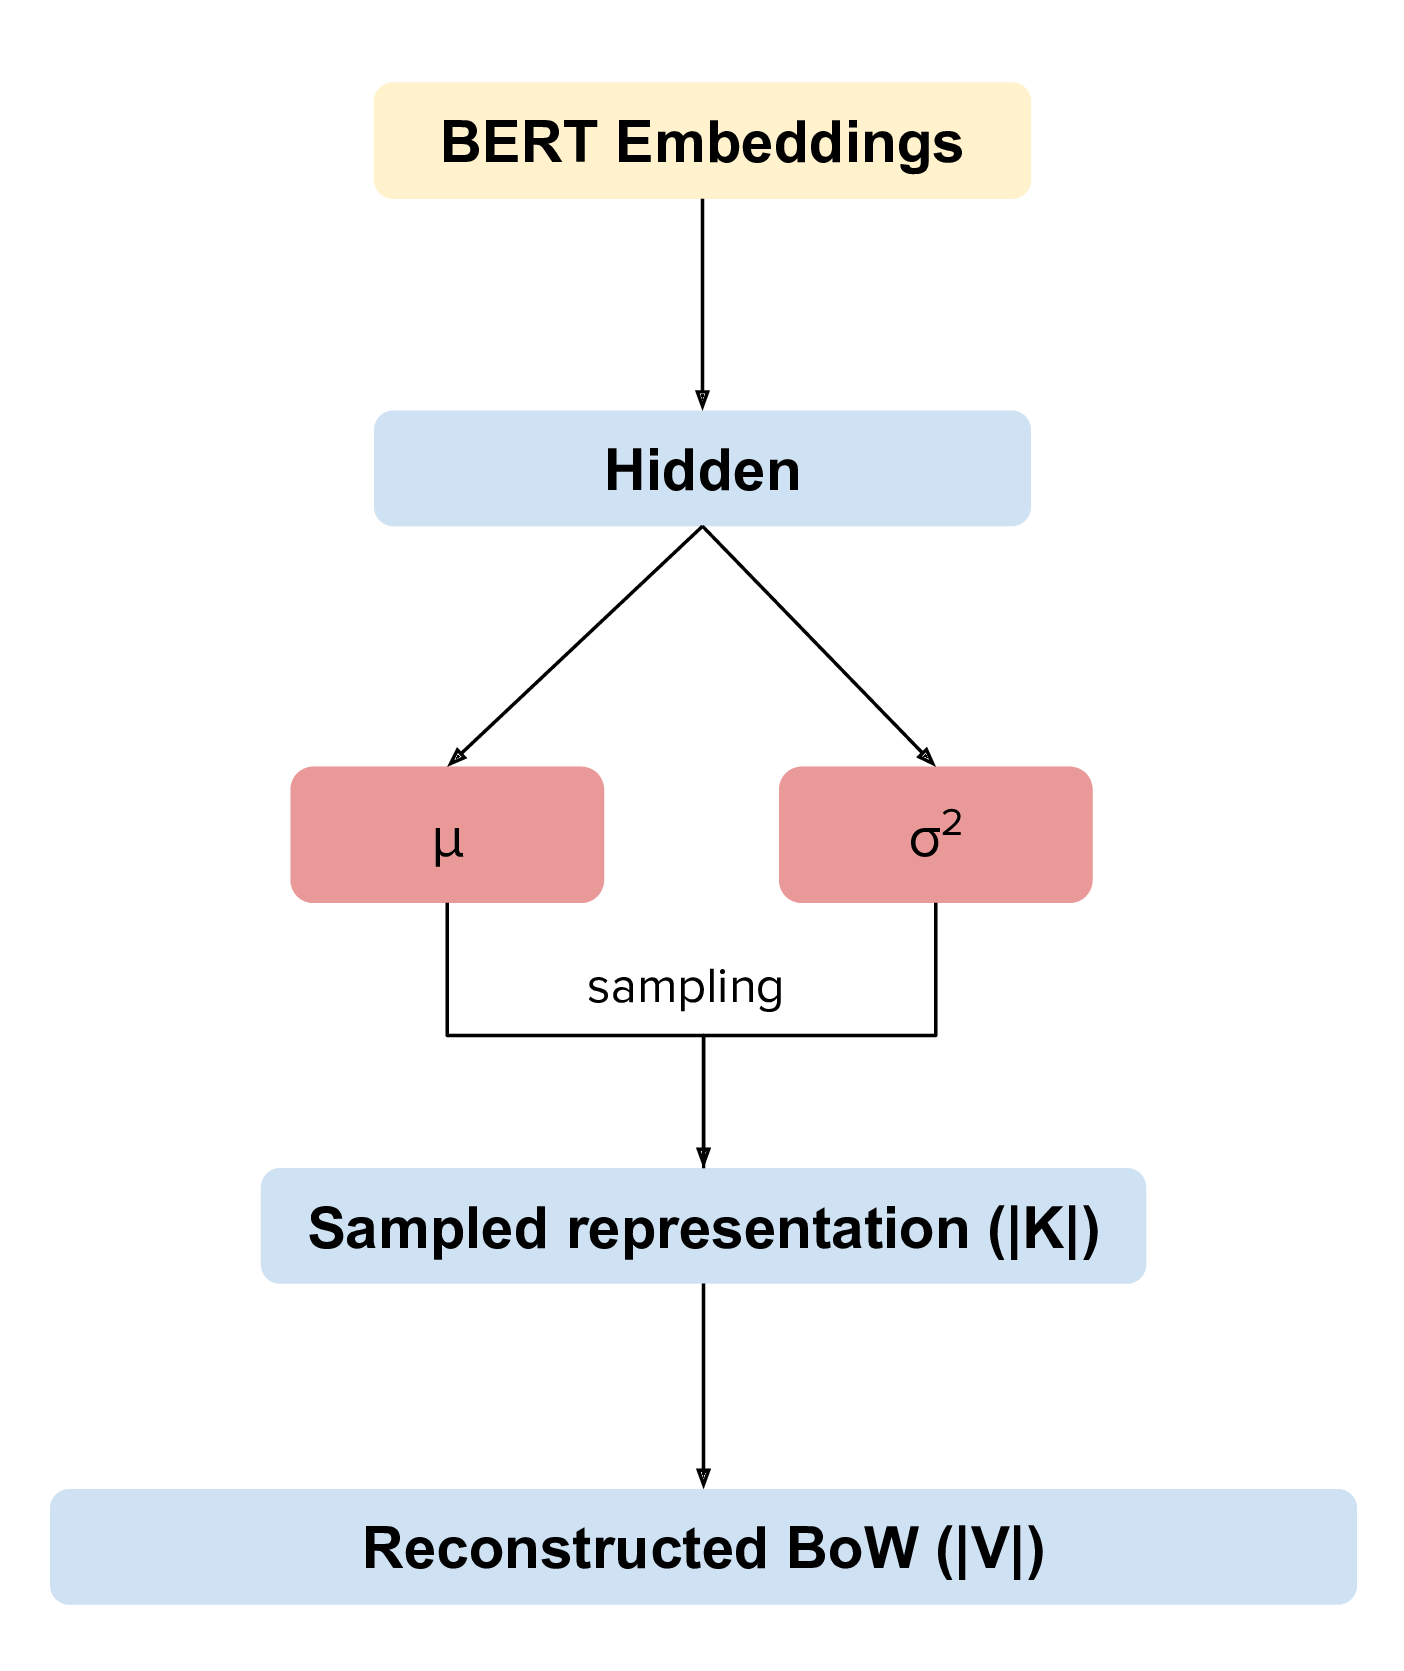
Software details:
Free software: MIT license
Documentation: https://contextualized-topic-models.readthedocs.io.
Super big shout-out to Stephen Carrow for creating the awesome https://github.com/estebandito22/PyTorchAVITM package from which we constructed the foundations of this package. We are happy to redistribute again this software under the MIT License.
Features
Combines BERT and Neural Variational Topic Models
Two different methodologies: combined, where we combine BoW and BERT embeddings and contextual, that uses only BERT embeddings
Includes methods to create embedded representations and BoW
Includes evaluation metrics
Overview
Install the package using pip
pip install -U contextualized_topic_modelsThe contextual neural topic model can be easily instantiated using few parameters (although there is a wide range of parameters you can use to change the behaviour of the neural topic model). When you generate embeddings with BERT remember that there is a maximum length and for documents that are too long some words will be ignored.
An important aspect to take into account is which network you want to use: the one that combines BERT and the BoW or the one that just uses BERT. It’s easy to swap from one to the other:
Combined Topic Model:
CTM(input_size=len(handler.vocab), bert_input_size=512, inference_type="combined", n_components=50)Fully Contextual Topic Model:
CTM(input_size=len(handler.vocab), bert_input_size=512, inference_type="contextual", n_components=50)Contextual Topic Modeling
Here is how you can use the combined topic model. The high level API is pretty easy to use:
from contextualized_topic_models.models.ctm import CTM
from contextualized_topic_models.utils.data_preparation import TextHandler
from contextualized_topic_models.utils.data_preparation import bert_embeddings_from_file
from contextualized_topic_models.datasets.dataset import CTMDataset

handler = TextHandler("documents.txt")
handler.prepare() # create vocabulary and training data

# generate BERT data
training_bert = bert_embeddings_from_file("documents.txt", "distiluse-base-multilingual-cased")

training_dataset = CTMDataset(handler.bow, training_bert, handler.idx2token)

ctm = CTM(input_size=len(handler.vocab), bert_input_size=512, inference_type="combined", n_components=50)

ctm.fit(training_dataset) # run the model
See the example notebook in the contextualized_topic_models/examples folder. We have also included some of the metrics normally used in the evaluation of topic models, for example you can compute the coherence of your topics using NPMI using our simple and high-level API.
from contextualized_topic_models.evaluation.measures import CoherenceNPMI

with open('documents.txt',"r") as fr:
    texts = [doc.split() for doc in fr.read().splitlines()] # load text for NPMI

npmi = CoherenceNPMI(texts=texts, topics=ctm.get_topic_lists(10))
npmi.score()
Cross-lingual Topic Modeling
The fully contextual topic model can be used for cross-lingual topic modeling! See the paper (https://arxiv.org/pdf/2004.07737v1.pdf)
from contextualized_topic_models.models.ctm import CTM
from contextualized_topic_models.utils.data_preparation import TextHandler
from contextualized_topic_models.utils.data_preparation import bert_embeddings_from_file
from contextualized_topic_models.datasets.dataset import CTMDataset

handler = TextHandler("english_documents.txt")
handler.prepare() # create vocabulary and training data

training_bert = bert_embeddings_from_file("documents.txt", "distiluse-base-multilingual-cased")

training_dataset = CTMDataset(handler.bow, training_bert, handler.idx2token)

ctm = CTM(input_size=len(handler.vocab), bert_input_size=512, inference_type="contextual", n_components=50)

ctm.fit(training_dataset) # run the model
Predict topics for novel documents
test_handler = TextHandler("spanish_documents.txt")
test_handler.prepare() # create vocabulary and training data

# generate BERT data
testing_bert = bert_embeddings_from_file("spanish_documents.txt", "distiluse-base-multilingual-cased")

testing_dataset = CTMDataset(test_handler.bow, testing_bert, test_handler.idx2token)
ctm.get_thetas(testing_dataset)
Mono vs Cross-lingual
All the examples we saw used a multilingual embedding model distiluse-base-multilingual-cased.
However, if you are doing topic modeling in English, you can use the English sentence-bert model. In that case,
it’s really easy to update the code to support mono-lingual english topic modeling.
training_bert = bert_embeddings_from_file("documents.txt", "bert-base-nli-mean-tokens")
ctm = CTM(input_size=len(handler.vocab), bert_input_size=768, inference_type="combined", n_components=50)
In general, our package should be able to support all the models described in the sentence transformer package.
Development Team
Federico Bianchi <f.bianchi@unibocconi.it> Bocconi University
Silvia Terragni <s.terragni4@campus.unimib.it> University of Milan-Bicocca
Dirk Hovy <dirk.hovy@unibocconi.it> Bocconi University
References
Combined Topic Model
@article{bianchi2020pretraining,
    title={Pre-training is a Hot Topic: Contextualized Document Embeddings Improve Topic Coherence},
    author={Federico Bianchi and Silvia Terragni and Dirk Hovy},
    year={2020},
   journal={arXiv preprint arXiv:2004.03974},
}
Fully Contextual Topic Model
@article{bianchi2020crosslingual,
    title={Cross-lingual Contextualized Topic Models with Zero-shot Learning},
    author={Federico Bianchi and Silvia Terragni and Dirk Hovy and Debora Nozza and Elisabetta Fersini},
    year={2020},
   journal={arXiv preprint arXiv:2004.07737},
}
Credits
This package was created with Cookiecutter and the audreyr/cookiecutter-pypackage project template. To ease the use of the library we have also incuded the rbo package, all the rights reserved to the author of that package.
Note
Remember that this is a research tool :)
History
1.4.2 (2020-08-04)
Changed the encoding on file load for the SBERT embedding function
1.4.1 (2020-08-04)
Fixed bug over sparse matrices
1.4.0 (2020-08-01)
New feature handling sparse bow for optimized processing
New method to return topic distributions for words
1.0.0 (2020-04-05)
Released models with the main features implemented
0.1.0 (2020-04-04)
First release on PyPI.
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file contextualized_topic_models-1.4.2.tar.gz.
File metadata
- Download URL: contextualized_topic_models-1.4.2.tar.gz
- Upload date:
- Size: 27.5 kB
- Tags: Source
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/3.2.0 pkginfo/1.5.0.1 requests/2.24.0 setuptools/49.6.0 requests-toolbelt/0.9.1 tqdm/4.48.2 CPython/3.8.0
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
25d2890638a62a3ec64d2073a66ddf784a5a64fe25161c4a8aff9345db51f03e
|
|
| MD5 |
c977bae6f8580ae32cfe7397b881e47a
|
|
| BLAKE2b-256 |
5d9f216abdab6a8b3ded71de769bdce3c1bc745995d979f20d8a830c7dfac7c2
|
File details
Details for the file contextualized_topic_models-1.4.2-py2.py3-none-any.whl.
File metadata
- Download URL: contextualized_topic_models-1.4.2-py2.py3-none-any.whl
- Upload date:
- Size: 21.1 kB
- Tags: Python 2, Python 3
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/3.2.0 pkginfo/1.5.0.1 requests/2.24.0 setuptools/49.6.0 requests-toolbelt/0.9.1 tqdm/4.48.2 CPython/3.8.0
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
e65119cbe1a5eb640541f7145c76838e336e9b292f719ee4f288da3453c1bd2f
|
|
| MD5 |
2e7a2ca63654db95b3d5b77e59670068
|
|
| BLAKE2b-256 |
e88316ee302ae54b21692ac995d71ae90265473becfd73bcf942c41c0a9b5950
|














