
Python Document Scanner SDK
A Python wrapper for the Dynamsoft Document Normalizer SDK, providing simple and user-friendly APIs across Windows, Linux, and macOS. Compatible with desktop PCs, embedded devices, Raspberry Pi, and Jetson Nano.
Note: This is an unofficial, community-maintained wrapper. For official support and full feature coverage, consider the Dynamsoft Capture Vision Bundle on PyPI.
Quick Links
Comparison: Community vs Official
| Feature | Community Wrapper | Official Dynamsoft SDK |
|---|---|---|
| Support | Community-driven | ✅ Official Dynamsoft support |
| Documentation | Basic README and limited examples | ✅ Comprehensive online documentation |
| API Coverage | Core features only | ✅ Full API coverage |
| Updates | May lag behind | ✅ Always includes the latest features |
| Testing | Tested in limited environments | ✅ Thoroughly tested |
| API Usage | ✅ Simple and intuitive | More complex and verbose |
Installation
Requirements
-
Python 3.x
-
OpenCV (for UI display)
pip install opencv-python
-
Dynamsoft Capture Vision Bundle SDK
pip install dynamsoft-capture-vision-bundle
Build from Source
# Source distribution
python setup.py sdist

# Build wheel
python setup.py bdist_wheel
Command-line Usage
After installation, you can use the built-in command-line interface:
# Scan document from image file
scandocument -f <file-name> -l <license-key>

# Scan documents from camera (camera index 0)
scandocument -c 1 -l <license-key>
Quick Start
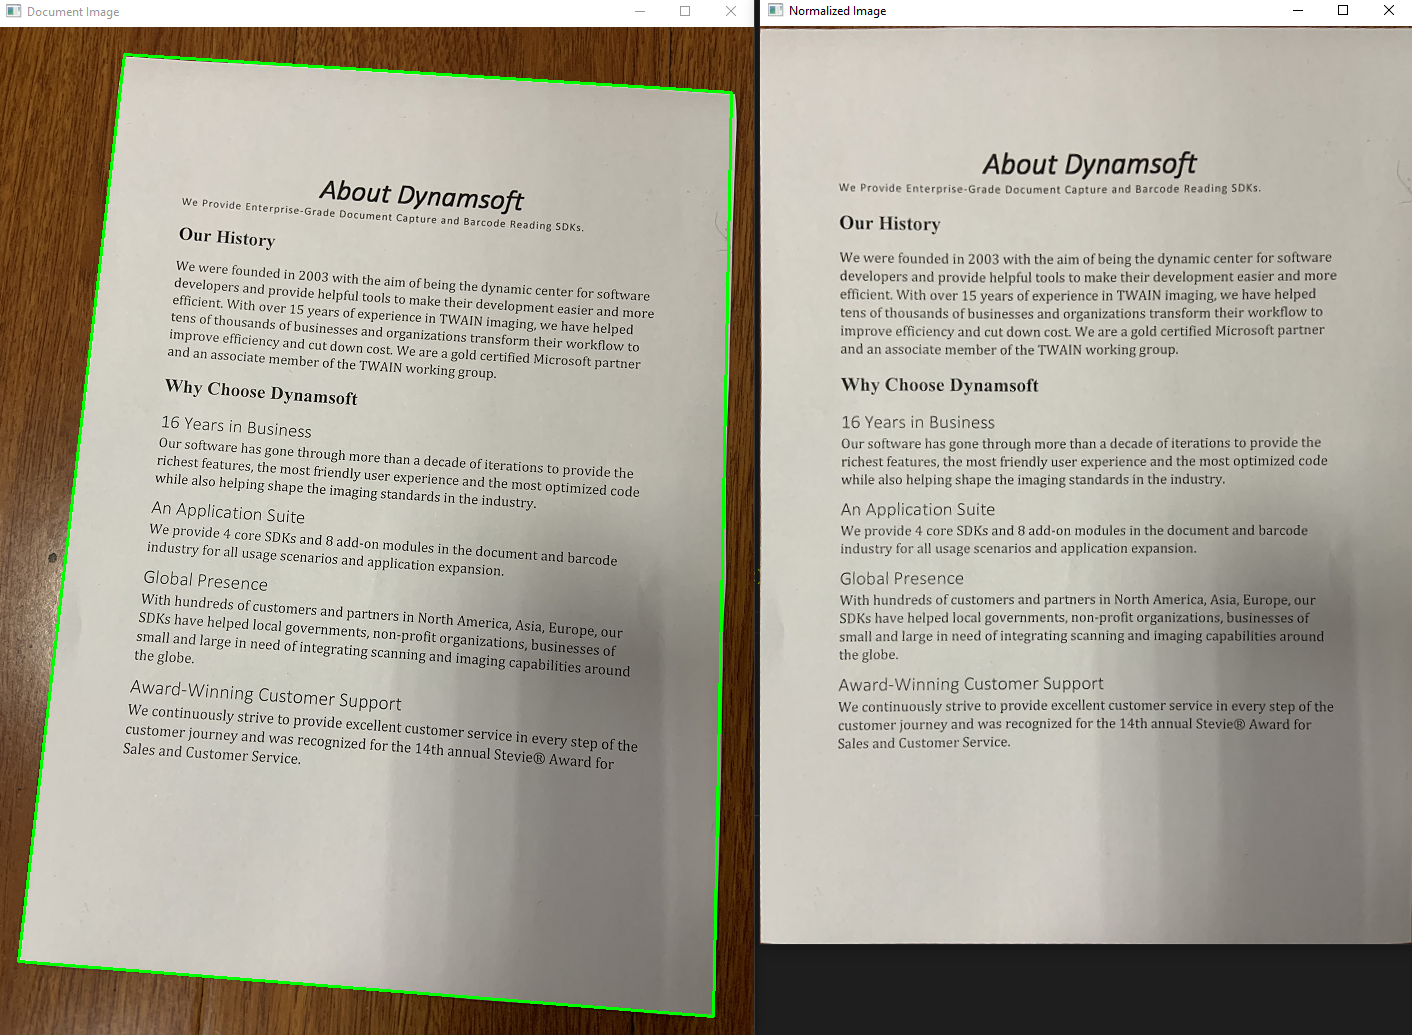
Basic Document Detection
import docscanner
import cv2

# Initialize license (required)
docscanner.initLicense("YOUR_LICENSE_KEY")  # Get trial key from Dynamsoft

# Create scanner instance
scanner = docscanner.createInstance()

# Detect from image file
results = scanner.detect("document.jpg")

# OR detect from OpenCV image matrix
image = cv2.imread("document.jpg")
results = scanner.detect(image)

# Process results
for result in results:
    print(f"Document found:")
    print(f"  Top-left: ({result.x1}, {result.y1})")
    print(f"  Top-right: ({result.x2}, {result.y2})")
    print(f"  Bottom-right: ({result.x3}, {result.y3})")
    print(f"  Bottom-left: ({result.x4}, {result.y4})")

    # Draw detection rectangle
    import numpy as np
    corners = np.array([(result.x1, result.y1), (result.x2, result.y2),
                       (result.x3, result.y3), (result.x4, result.y4)])
    cv2.drawContours(image, [corners.astype(int)], -1, (0, 255, 0), 2)

cv2.imshow("Detected Documents", image)
cv2.waitKey(0)
Document Normalization (Perspective Correction)
import docscanner
import cv2
from docscanner import *

# Setup (license + scanner)
docscanner.initLicense("YOUR_LICENSE_KEY")
scanner = docscanner.createInstance()

# Detect documents
results = scanner.detect("skewed_document.jpg")

if results:
    result = results[0]  # Process first detected document

    # Normalize the document (correct perspective) - now returns the image
    normalized_img = scanner.normalize(result, EnumImageColourMode.ICM_COLOUR)

    # Use the returned normalized image directly
    if normalized_img is not None:
        cv2.imshow("Original", cv2.imread("skewed_document.jpg"))
        cv2.imshow("Normalized", normalized_img)
        cv2.waitKey(0)

        # Save normalized image
        cv2.imwrite("normalized_document.jpg", normalized_img)
        print("Normalized document saved!")
Real-time Camera Scanning
import docscanner
import cv2
import numpy as np

def on_document_detected(results):
    """Callback function for async document detection"""
    for result in results:
        print(f"Document detected at ({result.x1},{result.y1}), ({result.x2},{result.y2}), ({result.x3},{result.y3}), ({result.x4},{result.y4})")

# Setup
docscanner.initLicense("YOUR_LICENSE_KEY")
scanner = docscanner.createInstance()

# Start async detection
scanner.addAsyncListener(on_document_detected)

# Camera loop
cap = cv2.VideoCapture(0)

while True:
    ret, frame = cap.read()
    if not ret:
        break

    # Queue frame for async processing
    scanner.detectMatAsync(frame)

    # Display frame
    cv2.imshow("Document Scanner", frame)

    key = cv2.waitKey(1) & 0xFF
    if key == ord('q'):
        break

# Cleanup
scanner.clearAsyncListener()
cap.release()
cv2.destroyAllWindows()
API Reference
Core Functions
docscanner.initLicense(license_key: str) -> Tuple[int, str]
Initialize the Dynamsoft license. Required before using any other functions.
Parameters:
license_key: Your Dynamsoft license key
Returns:
(error_code, error_message): License initialization result
Example:
error_code, error_msg = docscanner.initLicense("YOUR_LICENSE_KEY")
if error_code != 0:
    print(f"License error: {error_msg}")
docscanner.createInstance() -> DocumentScanner
Create a new DocumentScanner instance.
Returns:
DocumentScanner: Ready-to-use scanner instance
DocumentScanner Class
Detection Methods
detect(input: Union[str, numpy.ndarray]) -> List[DocumentResult]
Detect documents from various input sources (unified detection method).
Parameters:
input: Input source for document detection:str: File path to image (JPEG, PNG, BMP, TIFF, etc.)numpy.ndarray: OpenCV image matrix (BGR or grayscale)
Returns:
List[DocumentResult]: List of detected documents with boundary coordinates
Examples:
# Detect from file path
results = scanner.detect("document.jpg")

# Detect from OpenCV matrix
import cv2
image = cv2.imread("document.jpg")
results = scanner.detect(image)

# Process results
for result in results:
    print(f"Found document at ({result.x1},{result.y1}), ({result.x2},{result.y2}), ({result.x3},{result.y3}), ({result.x4},{result.y4})")
Asynchronous Processing
addAsyncListener(callback: Callable[[List[DocumentResult]], None]) -> None
Start asynchronous document detection with callback.
Parameters:
callback: Function called with detection results
Example:
def on_documents_found(results):
    print(f"Found {len(results)} documents")

scanner.addAsyncListener(on_documents_found)
detectMatAsync(image: numpy.ndarray) -> None
Queue an image for asynchronous processing.
Parameters:
image: OpenCV image to process
clearAsyncListener() -> None
Stop asynchronous processing and remove callback.
Document Normalization
normalize(document: DocumentResult, color: EnumImageColourMode) -> numpy.ndarray
Perform document normalization (perspective correction) on a detected document.
Parameters:
document: DocumentResult containing boundary coordinates and source imagecolor: Color mode for output (ICM_COLOUR, ICM_GRAYSCALE, or ICM_BINARY)
Returns:
numpy.ndarray or None: The normalized document image as numpy array, or None if normalization fails
Usage Patterns:
# Method 1: Use return value directly
normalized_img = scanner.normalize(result, EnumImageColourMode.ICM_COLOUR)
if normalized_img is not None:
    cv2.imshow("Normalized", normalized_img)

# Method 2: Access from document object (also available)
scanner.normalize(result, EnumImageColourMode.ICM_COLOUR)
if result.normalized_image is not None:
    cv2.imwrite("output.jpg", result.normalized_image)
DocumentResult Class
Container for document detection results.
Attributes:
x1, y1: Top-left corner coordinatesx2, y2: Top-right corner coordinatesx3, y3: Bottom-right corner coordinatesx4, y4: Bottom-left corner coordinatessource: Original image (file path or numpy array)normalized_image: Perspective-corrected image (numpy array)
Utility Functions
convertMat2ImageData(mat: numpy.ndarray) -> ImageData
Convert OpenCV matrix to Dynamsoft ImageData format.
Parameters:
mat: OpenCV image (RGB, BGR, or grayscale)
Returns:
ImageData: SDK-compatible image data
convertNormalizedImage2Mat(normalized_image: ImageData) -> numpy.ndarray
Convert Dynamsoft ImageData back to OpenCV-compatible numpy array.
Parameters:
normalized_image: ImageData object from SDK normalization results
Returns:
numpy.ndarray: OpenCV-compatible image matrix
Supported Formats:
- Binary images (1-bit): Converted to 8-bit grayscale
- Grayscale images: Single channel 8-bit
- Color images: 3-channel RGB format
1 maintainer

Metadata
1 maintainer
Release files for document-scanner-sdk 3.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| document_scanner_sdk-3.0.0.tar.gz | 14.8 kB | Without provenance | Details for document_scanner_sdk-3.0.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| document_scanner_sdk-3.0.0-py3-none-any.whl | Python 3 | none | any | Details for document_scanner_sdk-3.0.0-py3-none-any.whl |
Total release size: 28.5 kB
Release files / document_scanner_sdk-3.0.0.tar.gz
| Download URL | document_scanner_sdk-3.0.0.tar.gz |
|---|---|
| Size | 14.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f3ab394bc3d3d530a03c8df81ea07c630c6d7e9cac6f9a7c1d15c6cc4f29dadd
|
|
BLAKE2b-256 checksum How to use checksums |
b746bc035af6b530dc43dd684c4b10744a68c6a4ef4f10e18491da049357398c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.9.24
|
Release files / document_scanner_sdk-3.0.0-py3-none-any.whl
| Download URL | document_scanner_sdk-3.0.0-py3-none-any.whl |
|---|---|
| Size | 13.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6b543544cac8a59c4c1f1452ee2125309e51ee5037177012f868c8b1dde836f2
|
|
BLAKE2b-256 checksum How to use checksums |
08ff52a4ac0345a10d34ff1a120177da943a4d4ae5e0f35e4aff0c39b7e22cf1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.9.24
|
Security for document-scanner-sdk 3.0.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














