
ExPDF
Overview
ExPDF is a tool that can generate citation relationship between PDFs, and create beautiful, interactive SVG figure inside Jupyter Notebook.
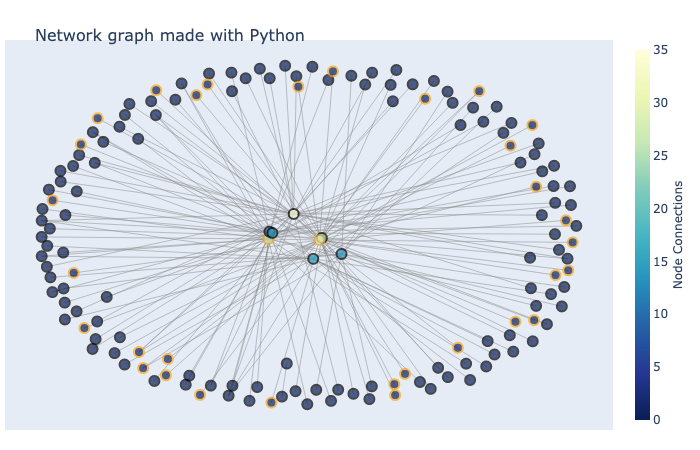
Quickstart
With Jupyter Notebook, it is easy to visuzlize citation relationship between PDFs.
Firstly, download and install by:
git clone https://github.com/bupt-ipcr/expdf
cd expdf
pip install ./
Secondly, use expdf to generate json file like:
expdf -d pdfs/ASV -o data.json
Finally, open jupyter notebook and try:
  import json
  from expdf.visualize import create_fig
  with open('data.json', 'r') as f:
    data = json.load(f)
  fig = create_fig(data)
  fig
Installation
download expdf with github and install it with pip
git clone https://github.com/bupt-ipcr/expdf
cd expdf
pip install ./
run expdf -h to see the help output:
usage: expdf [-h] [-a APPEND_PDF] [-r] [-o OUTPUT_DIR] PDF_PATH

Generate reference relation of all PDFs(given or inside PDF)

positional arguments:
  PDF_PATH              PDF path, or directory of PDFs if -r is used

optional arguments:
  -h, --help            show this help message and exit
  -a APPEND_PDF, --append APPEND_PDF
                        append a PDF file
  -d, --dir, --directory
                        treat PDF_PATH as a directory
  -e EXCLUDE_PDF, --exclude EXCLUDE_PDF
                        exclude a PDF file
  -o OUTPUT_DIR, -O OUTPUT_DIR, --output OUTPUT_DIR
                        output directory, default is current directory
  -v, --vis, --visualize
                        create a html file for visualize
  --vis-html HTML_FILENAME
                        output file name of html visualize
Examples
simply use epdf like:
expdf pdfs/test.pdf
Treat as a directory with -d and it will scan all PDFs in specify directory:
expdf -d pdfs
Append PDFs with -a, since there may be sporadic papers not in the same folder:
expdf -d pdfs -a 1.pdf -a 2.pdf
Exclude PDFs with -e, to exclude some PDFs. Note that even if exclude pdf not exists,
there will be no error.
expdf -d pdfs -e test.pdf
To specify output directory, use -o, -O or --output like:
expdf pdfs/test.pdf -O ./urdir
To generate visualize html file, use -v and --vis-html like:
expdf -r pdfs/ASV -v --vis-html='vis.html'
Usage as Python library
Here we have three main parts of expdfs: ExPDFParser, Graph and render.
-
ExPDFParsera parser built top on pdfminer, look for metadata, links and references of a PDF file.
# ensure you have ./tests/test.pdf
from expdf import ExPDFParser
pdf = ExPDFParser("tests/test.pdf")
print('title: ', pdf.title)
print('info: ', pdf.info)
print('metadata: ', pdf.metadata)

print('Links: ')
for link in pdf.links:
  print(f'- {link}')

print('Refs: ')
for ref in pdf.refs:
  print(f'- {ref}')
-
PDFNodePDFNodeis a class that maintain a dict of all its instances. Two PDF that have same title(or just have difference in punctuations) will point to same node.LocalPDFNodeis a subclass ofPDFNode, which enables you to modify references of a PDF.usually it is used with parser like:
from expdf import ExPDFParser, LocalPDFNode

expdf_parser = ExPDFParser("tests/test.pdf")
localPDFNode = LocalPDFNode(expdf_parser.title, expdf_parser.refs)
pdf_info = PDFNode.get_json()
print(pdf_info)
otherwise, you can also assign title and refs without parser(maybe human is more precise than parser and regex expressions), just like:
from expdf.graph import PDFNode, LocalPDFNode

# just a example, we wwill never see title like this
LocalPDFNode('title0', refs=['title1', 'title2'])
LocalPDFNode('title1', refs=['title3'])
LocalPDFNode('title2', refs=['title3'])
pdf_info = PDFNode.get_json()
print(pdf_info)
-
visualizePDFNode give you infos of PDFs, such as citation relationship(show as parents and children). But why not visualize it?
visuzlizeprovides a top-level functioncreate_figbuilt onnetworkx,plotly.networkxprovedes methods to allocate positions of all nodes andplotlyis a powerful visualization tool.renderinvokescreate_figand write it into html file.Visualize is recommended to be use inside
jupyter notebook, since plotly only support events(click, hover, etc) with it. You can use like:expdf -d pdfs/ASV -o data.json
# in your jupyter notebook
import json
from expdf.visualize import create_fig
with open('data.json', 'r') as f:
  data = json.load(f)
fig = create_fig(data)
fig
You can also save it as html, just like:
expdf -d pdfs/ASV -o data.json -v --vis-html=vis.html
Various
- Author: Jiawei Wu 13260322877@163.com
- License: MIT
1 maintainer

Metadata
1 maintainer
Release files for expdf 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| expdf-0.3.0.tar.gz | 21.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| expdf-0.3.0-py2.py3-none-any.whl | Python 3, Python 2 | none | any | Details |
Total release size: 44.5 kB
Release files / expdf-0.3.0.tar.gz
| Download URL | expdf-0.3.0.tar.gz |
|---|---|
| Size | 21.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
dd944e8b62867242d0dff0524ad0b405b7c396155044bfff836de7efa129f654
|
|
BLAKE2b-256 checksum How to use checksums |
f82db89533401ee1e155cf68a8d0777f9e12617a7f4f419475af23332f8ce0fb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.1.1 pkginfo/1.5.0.1 requests/2.22.0 setuptools/46.1.3 requests-toolbelt/0.9.1 tqdm/4.36.1 CPython/3.7.5
|
Release files / expdf-0.3.0-py2.py3-none-any.whl
| Download URL | expdf-0.3.0-py2.py3-none-any.whl |
|---|---|
| Size | 22.9 kB |
| Tags | Python 2 Python 3 |
|
SHA-256 checksum How to use checksums |
e441938722d5f64368c9ec3469ef2e127c541460a50dd539b366e703d189ead3
|
|
BLAKE2b-256 checksum How to use checksums |
ea99df732e43840699acfcab3d9bb333c2f6f5aba63423a0fb825c50defdd18a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.1.1 pkginfo/1.5.0.1 requests/2.22.0 setuptools/46.1.3 requests-toolbelt/0.9.1 tqdm/4.36.1 CPython/3.7.5
|













