
This release is a pre-release and may not be stable for production use.
Finnish Media Scrapers

Scrapers for extracting articles from Finnish journalistic media websites by the University of Helsinki Human Sciences – Computing Interaction research group.
Included are scrapers for YLE, Helsingin Sanomat, Iltalehti and Iltasanomat. See below for limitations relating to individual sources.
Installation
Install the scripts (and Python module) using pip install finnish_media_scrapers. After this, the scripts should be useable from the command line, and the functionality importable from Python.
General workflow
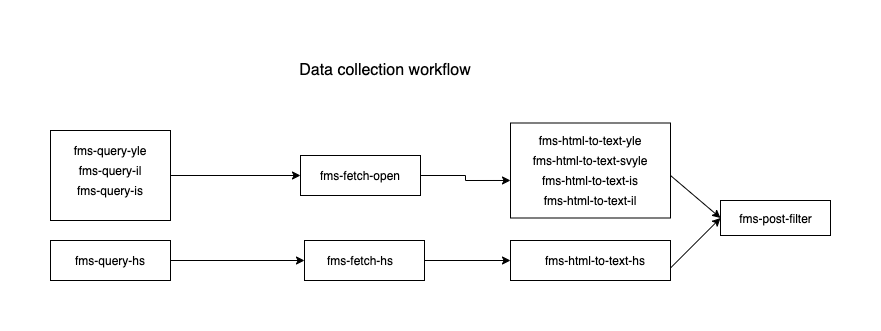
The general workflow for using the scrapers is as follows:
- Query YLE/HS/IL/IS APIs for matching articles using the scripts
fms-query-{yle|hs|il|is}, which output all matching articles with links into CSVs. - Fetch the matching articles using
fms-fetch-{hs|open}. These save the articles as HTML files in a specified directory. - Extract the plain text from the article HMTL using
fms-html-to-text-{yle|svyle|hs|il|is}. - Optionally refilter the results using
fms-post-filter.
Important to know when applying the workflow is that due to the fact that all the sources use some kind of stemming for their search, they can often return also spurious hits. Further, if searching for multiple words, the engines often perform a search for either word instead of the complete phrase. The post-filtering script above exists to counteract this by allowing the refiltering of the results more rigorously and uniformly locally.
At the same time and equally importantly, the stemming for a particular media may not cover e.g. all inflectional forms of words. Thus, it often makes sense to query for at least all common inflected variants and merge the results. For a complete worked up example of this kind of use, see the members_of_parliament folder, which demonstrates how one can collect and count how many articles in each media mention the members of the Finnish Parliament.
Apart from using the scripts, the functionality of the package is also provided as a python module that you may use programmatically from within Python. For the functionalities thus provided, see the module documentation
Media-specific instructions and caveats
Helsingin Sanomat
First, query the articles you want using fms-query-hs. For example, fms-query-hs -f 2020-02-16 -t 2020-02-18 -o hs-sdp.csv -q SDP.
For downloading articles, this scraper requires 1) a user id and password for Helsingin Sanomat and 2) a Selenium Docker container to be running. After installing Docker, run docker run -p 4444:4444 -v /dev/shm:/dev/shm selenium/standalone-chrome:4.0.0-beta-1-20210215 in another console before invoking the script. After these prequisites are fulfilled, you can fetch the articles using fms-fetch-hs. For example fms-fetch-hs -i hs-sdp.csv -o hs-sdp -u username -p password. After fetching the articles, extract texts with fms-html-to-text-hs -o hs-sdp-output hs-sdp.
Known special considerations:
- The search engine used seems to be employing some sort of stemming/lemmatization, so e.g. the query string
kokseems to matchkokki,kokoandkoki. - A single query can return at most 9,950 hits. This can be sidestepped by invoking the script multiple times with smaller query time spans.
Yle
example: fms-query-yle -f 2020-02-16 -t 2020-02-18 -o yle-sdp.csv -q SDP + fms-fetch-open -i yle-sdp.csv -o yle-sdp + fms-html-to-text-yle -o yle-sdp-output yle-sdp (or fms-html-to-text-svyle -o svyle-sdp-output svyle-sdp if articles come from Svenska YLE)
Known special considerations:
- A single query can return at most 10,000 hits. This can be sidestepped by invoking the script multiple times with smaller query time spans.
Iltalehti
example: fms-query-il -f 2020-02-16 -t 2020-02-18 -o il-sdp.csv -q SDP + fms-fetch-open -i il-sdp.csv -o il-sdp + fms-html-to-text-il -o il-sdp-output il-sdp
Iltasanomat
example: fms-query-is -f 2020-02-16 -t 2020-02-18 -o is-sdp.csv -q SDP + fms-fetch-open -i is-sdp.csv -o is-sdp + fms-html-to-text-is -o is-sdp-output is-sdp
Known special considerations:
- The search engine used seems to be employing some sort of stemming/lemmatization, so e.g. the query string
kokseems to matchkokki,kokoandkoki. - A single query can return at most 9,950 hits. This can be sidestepped by invoking the script multiple times with smaller query time spans.
Using the fms-post-filter script
For example, after collecting texts from Helsingin Sanomat with the example above, run:
fms-post-filter -i hs-sdp.csv -t hs-sdp-output/ -o hs-sdp-filtered.csv -q SDP
where -i parameter specifies the query output file, -t the folder name to search extracted texts, -o the output filename and -q search word to filter.
There is also an option -ci for configuring the case-insensitiveness (default false).
Contact
For more information on the scrapers, please contact associate professor Eetu Mäkelä.
1 maintainer

Metadata
1 maintainer
Release files for finnish-media-scrapers 0.9.0b4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| finnish_media_scrapers-0.9.0b4-py3-none-any.whl | Python 3 | none | any | Details |
Release files / finnish_media_scrapers-0.9.0b4-py3-none-any.whl
| Download URL | finnish_media_scrapers-0.9.0b4-py3-none-any.whl |
|---|---|
| Size | 22.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7546ad0e01e0af59bd6a5a80cb1f4f4b11c5ce06474a41f0cb0532d72f28caed
|
|
BLAKE2b-256 checksum How to use checksums |
c52c2c7f588332666539f6df9de416e9abc657f8d90e6871ad479ed7dd60fad7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.4.1 importlib_metadata/3.10.0 pkginfo/1.7.0 requests/2.25.1 requests-toolbelt/0.9.1 tqdm/4.59.0 CPython/3.7.10
|














