
🚀 We are granting access to Ivy's Tracer and Transpiler to all of our users, sign up on our console if you want to test them out!



Status


Unified AI
Ivy is an open-source machine learning framework that enables you to:
- 🔥 Autotune your model: Automatically find the optimal framework, compiler infrastructure and hardware for your specific use case using
ivy.autotune. - 🔄 Convert code into any framework: Use and build on top of any model, library, or device by converting any code from one framework to another using
ivy.transpile. - ⚒️ Write framework-agnostic code: Write your code once in ivy and then choose the most appropriate ML framework as the backend to leverage all the benefits and tools.
Join our growing community 🌍 to connect with people using Ivy. Let's unify.ai together 🦾
Getting started
The best way to get familiar with Ivy is to go through the Demos, a good starting point is Learn The Basics.
The most important notebooks are:
- How to convert your code between frameworks?
- How to write framework-agnostic code?
- Accelerate your development (WIP)
- Autotune and optimize models (WIP)
Installing ivy
There are various ways to use Ivy, depending on your preferred environment:
Installing using pip
The easiest way to set up Ivy is to install it using pip with the following command:
pip install ivy
or alternatively:
python3 -m pip install ivy
Docker
If you prefer to use containers, we also have pre-built Docker images with all the supported frameworks and some relevant packages already installed, which you can pull from:
docker pull unifyai/ivy:latest
If you are working on a GPU device, you can pull from:
docker pull unifyai/ivy:latest-gpu
From Source
You can also install Ivy from source if you want to take advantage of the latest changes, but we can't ensure everything will work as expected. :sweat_smile:
git clone https://github.com/unifyai/ivy.git
cd ivy
pip install --user -e .
or alternatively, for the last step:
python3 -m pip install --user -e .
If you want to set up testing and various frameworks it's probably best to check out the [Contributing - Setting Up](https://unify.ai/docs/ivy/overview/contributing/setting_up. html#setting-up) page, where OS-specific and IDE-specific instructions and video tutorials to do so are available!
Using Ivy
After installing Ivy, you can start using it straight away, for example:
Transpiling any code from one framework to another
import ivy
import torch
import jax

def jax_fn(x):
    a = jax.numpy.dot(x, x)
    b = jax.numpy.mean(x)
    return x * a + b

jax_x = jax.numpy.array([1, 2, 3])
torch_x = torch.tensor([1, 2, 3])
torch_fn = ivy.transpile(jax_fn, source="jax", to="torch", args=(jax_x,))
ret = torch_fn(torch_x)
Running your code with any backend
 import ivy
 import torch
 import jax

 ivy.set_backend("jax")

 x = jax.numpy.array([1, 2, 3])
 y = jax.numpy.array([3, 2, 1])
 z = ivy.add(x, y)

 ivy.set_backend('torch')

 x = torch.tensor([1, 2, 3])
 y = torch.tensor([3, 2, 1])
 z = ivy.add(x, y)
Documentation
You can find Ivy's documentation on the Docs page, which includes:
- Motivation: This contextualizes the problem Ivy is trying to solve by going over
- The current ML Explosion.
- Explaining why it is important to solve this problem.
- Explaining how we adhere to existing standards to make this happen.
- Related Work: Which paints a picture of the role Ivy plays in the ML stack, comparing it to other existing solutions in terms of functionalities and abstraction level.
- Design: A user-focused guide about the design decision behind the architecture and the main building blocks of Ivy.
- Deep Dive: Which delves deeper into the implementation details of Ivy and is oriented towards potential contributors to the code base.
Examples
The Examples page features a wide range of demos and tutorials showcasing the functionalities of Ivy along with multiple use cases, but feel free to check out some shorter framework-specific examples here ⬇️
I'm using PyTorch 
You can use Ivy to get PyTorch code from:Any model
From TensorFlow
import ivy
import torch
import tensorflow as tf

# Get a pretrained keras model
eff_encoder = tf.keras.applications.efficientnet_v2.EfficientNetV2B0(
    include_top=False, weights="imagenet", input_shape=(224, 224, 3)
)

# Transpile it into a torch.nn.Module with the corresponding parameters
noise = tf.random.normal(shape=(1, 224, 224, 3))
torch_eff_encoder = ivy.transpile(eff_encoder, to="torch", args=(noise,))

# Build a classifier using the transpiled encoder
class Classifier(torch.nn.Module):
    def __init__(self, num_classes=20):
        super().__init__()
        self.encoder = torch_eff_encoder
        self.fc = torch.nn.Linear(1280, num_classes)

    def forward(self, x):
        x = self.encoder(x)
        return self.fc(x)

# Initialize a trainable, customizable, torch.nn.Module
classifier = Classifier()
ret = classifier(torch.rand((1, 244, 244, 3)))
From JAX
import ivy
import jax
import torch

# Get a pretrained haiku model
# https://unify.ai/demos/scripts/deepmind_perceiver_io.py
from deepmind_perceiver_io import key, perceiver_backbone

# Transpile it into a torch.nn.Module with the corresponding parameters
dummy_input = jax.random.uniform(key, shape=(1, 3, 224, 224))
params = perceiver_backbone.init(rng=key, images=dummy_input)
backbone = ivy.transpile(
    perceiver_backbone, to="torch", params_v=params, kwargs={"images": dummy_input}
)

# Build a classifier using the transpiled backbone
class PerceiverIOClassifier(torch.nn.Module):
    def __init__(self, num_classes=20):
        super().__init__()
        self.backbone = backbone
        self.max_pool = torch.nn.MaxPool2d((512, 1))
        self.flatten = torch.nn.Flatten()
        self.fc = torch.nn.Linear(1024, num_classes)

    def forward(self, x):
        x = self.backbone(images=x)
        x = self.flatten(self.max_pool(x))
        return self.fc(x)

# Initialize a trainable, customizable, torch.nn.Module
classifier = PerceiverIOClassifier()
ret = classifier(torch.rand((1, 3, 224, 224)))
Any library
From Tensorflow
import ivy
import torch
import os
os.environ["SM_FRAMEWORK"] = "tf.keras"
import segmentation_models as sm

# transpile sm from tensorflow to torch
torch_sm = ivy.transpile(sm, source="tensorflow", to="torch")

# get some image-like arrays
output = torch.rand((1, 3, 512, 512))
target = torch.rand((1, 3, 512, 512))

# and use the transpiled version of any function from the library!
out = torch_sm.metrics.iou_score(output, target)
From JAX
import ivy
import rax
import torch

# transpile rax from jax to torch
torch_rax = ivy.transpile(rax, source="jax", to="torch")

# get some arrays
scores = torch.tensor([2.2, 1.3, 5.4])
labels = torch.tensor([1.0, 0.0, 0.0])

# and use the transpiled version of any function from the library!
out = torch_rax.poly1_softmax_loss(scores, labels)
From NumPy
import ivy
import torch
import madmom

# transpile madmon from numpy to torch
torch_madmom = ivy.transpile(madmom, source="numpy", to="torch")

# get some arrays
freqs = torch.arange(20) * 10

# and use the transpiled version of any function from the library!
out = torch_madmom.audio.filters.hz2midi(freqs)
Any function
From Tensorflow
import ivy
import tensorflow as tf
import torch

def loss(predictions, targets):
    return tf.sqrt(tf.reduce_mean(tf.square(predictions - targets)))

# transpile any function from tf to torch
torch_loss = ivy.transpile(loss, source="tensorflow", to="torch")

# get some arrays
p = torch.tensor([3.0, 2.0, 1.0])
t = torch.tensor([0.0, 0.0, 0.0])

# and use the transpiled version!
out = torch_loss(p, t)
From JAX
import ivy
import jax.numpy as jnp
import torch

def loss(predictions, targets):
    return jnp.sqrt(jnp.mean((predictions - targets) ** 2))

# transpile any function from jax to torch
torch_loss = ivy.transpile(loss, source="jax", to="torch")

# get some arrays
p = torch.tensor([3.0, 2.0, 1.0])
t = torch.tensor([0.0, 0.0, 0.0])

# and use the transpiled version!
out = torch_loss(p, t)
From NumPy
import ivy
import numpy as np
import torch

def loss(predictions, targets):
    return np.sqrt(np.mean((predictions - targets) ** 2))

# transpile any function from numpy to torch
torch_loss = ivy.transpile(loss, source="numpy", to="torch")

# get some arrays
p = torch.tensor([3.0, 2.0, 1.0])
t = torch.tensor([0.0, 0.0, 0.0])

# and use the transpiled version!
out = torch_loss(p, t)
I'm using TensorFlow 
You can use Ivy to get TensorFlow code from:Any model
From PyTorch
import ivy
import torch
import timm
import tensorflow as tf

# Get a pretrained pytorch model
mlp_encoder = timm.create_model("mixer_b16_224", pretrained=True, num_classes=0)

# Transpile it into a keras.Model with the corresponding parameters
noise = torch.randn(1, 3, 224, 224)
mlp_encoder = ivy.transpile(mlp_encoder, to="tensorflow", args=(noise,))

# Build a classifier using the transpiled encoder
class Classifier(tf.keras.Model):
    def __init__(self):
        super().__init__()
        self.encoder = mlp_encoder
        self.output_dense = tf.keras.layers.Dense(units=1000, activation="softmax")

    def call(self, x):
        x = self.encoder(x)
        return self.output_dense(x)

# Transform the classifier and use it as a standard keras.Model
x = tf.random.normal(shape=(1, 3, 224, 224))
model = Classifier()
ret = model(x)
From JAX
import ivy
import jax
import tensorflow as tf

# Get a pretrained haiku model
# https://unify.ai/demos/scripts/deepmind_perceiver_io.py
from deepmind_perceiver_io import key, perceiver_backbone

# Transpile it into a tf.keras.Model with the corresponding parameters
dummy_input = jax.random.uniform(key, shape=(1, 3, 224, 224))
params = perceiver_backbone.init(rng=key, images=dummy_input)
backbone = ivy.transpile(
    perceiver_backbone, to="tensorflow", params_v=params, args=(dummy_input,)
)

# Build a classifier using the transpiled backbone
class PerceiverIOClassifier(tf.keras.Model):
    def __init__(self, num_classes=20):
        super().__init__()
        self.backbone = backbone
        self.max_pool = tf.keras.layers.MaxPooling1D(pool_size=512)
        self.flatten = tf.keras.layers.Flatten()
        self.fc = tf.keras.layers.Dense(num_classes)

    def call(self, x):
        x = self.backbone(x)
        x = self.flatten(self.max_pool(x))
        return self.fc(x)

# Initialize a trainable, customizable, tf.keras.Model
x = tf.random.normal(shape=(1, 3, 224, 224))
classifier = PerceiverIOClassifier()
ret = classifier(x)
Any library
From PyTorch
import ivy
import kornia
import requests
import numpy as np
import tensorflow as tf
from PIL import Image

# transpile kornia from torch to tensorflow
tf_kornia = ivy.transpile(kornia, source="torch", to="tensorflow")

# get an image
url = "http://images.cocodataset.org/train2017/000000000034.jpg"
raw_img = Image.open(requests.get(url, stream=True).raw)

# convert it to the format expected by kornia
img = np.array(raw_img)
img = tf.transpose(tf.constant(img), (2, 0, 1))
img = tf.expand_dims(img, 0) / 255

# and use the transpiled version of any function from the library!
out = tf_kornia.enhance.sharpness(img, 5)
From JAX
import ivy
import rax
import tensorflow as tf

# transpile rax from jax to tensorflow
tf_rax = ivy.transpile(rax, source="jax", to="tensorflow")

# get some arrays
scores = tf.constant([2.2, 1.3, 5.4])
labels = tf.constant([1.0, 0.0, 0.0])

# and use the transpiled version of any function from the library!
out = tf_rax.poly1_softmax_loss(scores, labels)
From NumPy
import ivy
import madmom
import tensorflow as tf

# transpile madmom from numpy to tensorflow
tf_madmom = ivy.transpile(madmom, source="numpy", to="tensorflow")

# get some arrays
freqs = tf.range(20) * 10

# and use the transpiled version of any function from the library!
out = tf_madmom.audio.filters.hz2midi(freqs)
Any function
From PyTorch
import ivy
import torch
import tensorflow as tf

def loss(predictions, targets):
    return torch.sqrt(torch.mean((predictions - targets) ** 2))

# transpile any function from torch to tensorflow
tf_loss = ivy.transpile(loss, source="torch", to="tensorflow")

# get some arrays
p = tf.constant([3.0, 2.0, 1.0])
t = tf.constant([0.0, 0.0, 0.0])

# and use the transpiled version!
out = tf_loss(p, t)
From JAX
import ivy
import jax.numpy as jnp
import tensorflow as tf

def loss(predictions, targets):
    return jnp.sqrt(jnp.mean((predictions - targets) ** 2))

# transpile any function from jax to tensorflow
tf_loss = ivy.transpile(loss, source="jax", to="tensorflow")

# get some arrays
p = tf.constant([3.0, 2.0, 1.0])
t = tf.constant([0.0, 0.0, 0.0])

# and use the transpiled version!
out = tf_loss(p, t)
From NumPy
import ivy
import numpy as np
import tensorflow as tf

def loss(predictions, targets):
    return np.sqrt(np.mean((predictions - targets) ** 2))

# transpile any function from numpy to tensorflow
tf_loss = ivy.transpile(loss, source="numpy", to="tensorflow")

# get some arrays
p = tf.constant([3.0, 2.0, 1.0])
t = tf.constant([0.0, 0.0, 0.0])

# and use the transpiled version!
out = tf_loss(p, t)
I'm using Jax 
You can use Ivy to get JAX code from:Any model
From PyTorch
import ivy
import timm
import torch
import jax
import haiku as hk

# Get a pretrained pytorch model
mlp_encoder = timm.create_model("mixer_b16_224", pretrained=True, num_classes=0)

# Transpile it into a hk.Module with the corresponding parameters
noise = torch.randn(1, 3, 224, 224)
mlp_encoder = ivy.transpile(mlp_encoder, to="jax", args=(noise,))

# Build a classifier using the transpiled encoder
class Classifier(hk.Module):
    def __init__(self, num_classes=1000):
        super().__init__()
        self.encoder = mlp_encoder()
        self.fc = hk.Linear(output_size=num_classes, with_bias=True)

    def __call__(self, x):
        x = self.encoder(x)
        x = self.fc(x)
        return x

def _forward_classifier(x):
    module = Classifier()
    return module(x)

# Transform the classifier and use it as a standard hk.Module
rng_key = jax.random.PRNGKey(42)
x = jax.random.uniform(key=rng_key, shape=(1, 3, 224, 224), dtype=jax.numpy.float32)
forward_classifier = hk.transform(_forward_classifier)
params = forward_classifier.init(rng=rng_key, x=x)

ret = forward_classifier.apply(params, None, x)
From TensorFlow
import ivy
import jax
import haiku as hk
import tensorflow as tf

# Get a pretrained keras model
eff_encoder = tf.keras.applications.efficientnet_v2.EfficientNetV2B0(
    include_top=False, weights="imagenet", input_shape=(224, 224, 3)
)

# Transpile it into a hk.Module with the corresponding parameters
noise = tf.random.normal(shape=(1, 224, 224, 3))
hk_eff_encoder = ivy.transpile(eff_encoder, to="jax", args=(noise,))

# Build a classifier using the transpiled encoder
class Classifier(hk.Module):
    def __init__(self, num_classes=1000):
        super().__init__()
        self.encoder = hk_eff_encoder()
        self.fc = hk.Linear(output_size=num_classes, with_bias=True)

    def __call__(self, x):
        x = self.encoder(x)
        x = self.fc(x)
        return x

def _forward_classifier(x):
    module = Classifier()
    return module(x)

# Transform the classifier and use it as a standard hk.Module
rng_key = jax.random.PRNGKey(42)
dummy_x = jax.random.uniform(key=rng_key, shape=(1, 224, 224, 3))
forward_classifier = hk.transform(_forward_classifier)
params = forward_classifier.init(rng=rng_key, x=dummy_x)

ret = forward_classifier.apply(params, None, dummy_x)
Any library
From PyTorch
import ivy
import kornia
import requests
import jax.numpy as jnp
from PIL import Image

# transpile kornia from torch to jax
jax_kornia = ivy.transpile(kornia, source="torch", to="jax")

# get an image
url = "http://images.cocodataset.org/train2017/000000000034.jpg"
raw_img = Image.open(requests.get(url, stream=True).raw)

# convert it to the format expected by kornia
img = jnp.transpose(jnp.array(raw_img), (2, 0, 1))
img = jnp.expand_dims(img, 0) / 255

# and use the transpiled version of any function from the library!
out = jax_kornia.enhance.sharpness(img, 5)
From TensorFlow
import ivy
import jax
import os
os.environ["SM_FRAMEWORK"] = "tf.keras"
import segmentation_models as sm

# transpile sm from tensorflow to jax
jax_sm = ivy.transpile(sm, source="tensorflow", to="jax")

# get some image-like arrays
key = jax.random.PRNGKey(23)
key1, key2 = jax.random.split(key)
output = jax.random.uniform(key1, (1, 3, 512, 512))
target = jax.random.uniform(key2, (1, 3, 512, 512))

# and use the transpiled version of any function from the library!
out = jax_sm.metrics.iou_score(output, target)
From NumPy
import ivy
import madmom
import jax.numpy as jnp

# transpile madmon from numpy to jax
jax_madmom = ivy.transpile(madmom, source="numpy", to="jax")

# get some arrays
freqs = jnp.arange(20) * 10

# and use the transpiled version of any function from the library!
out = jax_madmom.audio.filters.hz2midi(freqs)
Any function
From PyTorch
import ivy
import torch
import jax.numpy as jnp

def loss(predictions, targets):
    return torch.sqrt(torch.mean((predictions - targets) ** 2))

# transpile any function from torch to jax
jax_loss = ivy.transpile(loss, source="torch", to="jax")

# get some arrays
p = jnp.array([3.0, 2.0, 1.0])
t = jnp.array([0.0, 0.0, 0.0])

# and use the transpiled version!
out = jax_loss(p, t)
From TensorFlow
import ivy
import tensorflow as tf
import jax.numpy as jnp

def loss(predictions, targets):
    return tf.sqrt(tf.reduce_mean(tf.square(predictions - targets)))

# transpile any function from tf to jax
jax_loss = ivy.transpile(loss, source="tensorflow", to="jax")

# get some arrays
p = jnp.array([3.0, 2.0, 1.0])
t = jnp.array([0.0, 0.0, 0.0])

# and use the transpiled version!
out = jax_loss(p, t)
From NumPy
import ivy
import numpy as np
import jax
import jax.numpy as jnp
jax.config.update('jax_enable_x64', True)

def loss(predictions, targets):
    return np.sqrt(np.mean((predictions - targets) ** 2))

# transpile any function from numpy to jax
jax_loss = ivy.transpile(loss, source="numpy", to="jax")

# get some arrays
p = jnp.array([3.0, 2.0, 1.0])
t = jnp.array([0.0, 0.0, 0.0])

# and use the transpiled version!
out = jax_loss(p, t)
I'm using NumPy 
You can use Ivy to get NumPy code from:Any library
From PyTorch
import ivy
import kornia
import requests
import numpy as np
from PIL import Image

# transpile kornia from torch to np
np_kornia = ivy.transpile(kornia, source="torch", to="numpy")

# get an image
url = "http://images.cocodataset.org/train2017/000000000034.jpg"
raw_img = Image.open(requests.get(url, stream=True).raw)

# convert it to the format expected by kornia
img = np.transpose(np.array(raw_img), (2, 0, 1))
img = np.expand_dims(img, 0) / 255

# and use the transpiled version of any function from the library!
out = np_kornia.enhance.sharpness(img, 5)
From TensorFlow
import ivy
import numpy as np
import os
os.environ["SM_FRAMEWORK"] = "tf.keras"
import segmentation_models as sm

# transpile sm from tensorflow to numpy
np_sm = ivy.transpile(sm, source="tensorflow", to="numpy")

# get some image-like arrays
output = np.random.rand(1, 3, 512, 512).astype(dtype=np.float32)
target = np.random.rand(1, 3, 512, 512).astype(dtype=np.float32)

# and use the transpiled version of any function from the library!
out = np_sm.metrics.iou_score(output, target)
From Jax
import ivy
import rax
import numpy as np

# transpile rax from jax to numpy
np_rax = ivy.transpile(rax, source="jax", to="numpy")

# get some arrays
scores = np.array([2.2, 1.3, 5.4])
labels = np.array([1.0, 0.0, 0.0])

# and use the transpiled version of any function from the library!
out = np_rax.poly1_softmax_loss(scores, labels)
Any function
From PyTorch
import ivy
import torch
import numpy as np

def loss(predictions, targets):
    return torch.sqrt(torch.mean((predictions - targets) ** 2))

# transpile any function from torch to numpy
np_loss = ivy.transpile(loss, source="torch", to="numpy")

# get some arrays
p = np.array([3.0, 2.0, 1.0])
t = np.array([0.0, 0.0, 0.0])

# and use the transpiled version!
out = np_loss(p, t)
From TensorFlow
import ivy
import tensorflow as tf
import numpy as np

def loss(predictions, targets):
    return tf.sqrt(tf.reduce_mean(tf.square(predictions - targets)))

# transpile any function from tf to numpy
np_loss = ivy.transpile(loss, source="tensorflow", to="numpy")

# get some arrays
p = np.array([3.0, 2.0, 1.0])
t = np.array([0.0, 0.0, 0.0])

# and use the transpiled version!
out = np_loss(p, t)
From JAX
import ivy
import jax.numpy as jnp
import numpy as np

def loss(predictions, targets):
    return jnp.sqrt(jnp.mean((predictions - targets) ** 2))

# transpile any function from jax to numpy
np_loss = ivy.transpile(loss, source="jax", to="numpy")

# get some arrays
p = np.array([3.0, 2.0, 1.0])
t = np.array([0.0, 0.0, 0.0])

# and use the transpiled version!
out = np_loss(p, t)
I'm using Ivy 
Or you can use Ivy as a framework, breaking yourself (and your code)
free from deciding which community to support, allowing anyone to run
your code in their framework of choice!
import ivy

# A simple image classification model
class IvyNet(ivy.Module):
    def __init__(
        self,
        h_w=(32, 32),
        input_channels=3,
        output_channels=512,
        num_classes=2,
        data_format="NCHW",
        device="cpu",
    ):
        self.h_w = h_w
        self.input_channels = input_channels
        self.output_channels = output_channels
        self.num_classes = num_classes
        self.data_format = data_format
        self.device = device
        super().__init__()

    def _build(self, *args, **kwargs):
        self.extractor = ivy.Sequential(
            ivy.Conv2D(self.input_channels, 6, [5, 5], 1, "SAME", data_format=self.data_format),
            ivy.GELU(),
            ivy.Conv2D(6, 16, [5, 5], 1, "SAME", data_format=self.data_format),
            ivy.GELU(),
            ivy.Conv2D(16, self.output_channels, [5, 5], 1, "SAME", data_format=self.data_format),
            ivy.GELU(),
        )

        self.classifier = ivy.Sequential(
            # Since the padding is "SAME", this would be image_height x image_width x output_channels
            ivy.Linear(self.h_w[0] * self.h_w[1] * self.output_channels, 512),
            ivy.GELU(),
            ivy.Linear(512, self.num_classes),
        )

    def _forward(self, x):
        x = self.extractor(x)
        # flatten all dims except batch dim
        x = ivy.flatten(x, start_dim=1, end_dim=-1)
        logits = self.classifier(x)
        probs = ivy.softmax(logits)
        return logits, probs
After building your model in Ivy, you can set your favourite framework as the backend to use its operations under the hood!
ivy.set_backend("torch")
model = IvyNet()
x = torch.randn(1, 3, 32, 32)
logits, probs = model(x)
ivy.set_backend("tensorflow")
model = IvyNet()
x = tf.random.uniform(shape=(1, 3, 32, 32))
logits, probs = model(x)
ivy.set_backend("jax")
model = IvyNet()
x = jax.random.uniform(key, shape=(1, 3, 32, 32))
logits, probs = model(x)
ivy.set_backend("numpy")
model = IvyNet()
x = np.random.uniform(size=(1, 3, 32, 32))
logits, probs = model(x)
Last but not least, we can also build the training pipeline in pure ivy ⬇️
Let's define some helper functions first
# helper function for loading the dataset in batches
def generate_batches(images, classes, dataset_size, batch_size=32):
    targets = {k: v for v, k in enumerate(np.unique(classes))}
    y_train = [targets[classes[i]] for i in range(len(classes))]
    if batch_size > dataset_size:
        raise ivy.utils.exceptions.IvyError("Use a smaller batch size")
    for idx in range(0, dataset_size, batch_size):
        yield ivy.stack(images[idx : min(idx + batch_size, dataset_size)]), ivy.array(
            y_train[idx : min(idx + batch_size, dataset_size)]
        )


# helper function to get the number of current predictions
def num_correct(preds, labels):
    return (preds.argmax() == labels).sum().to_numpy().item()


# define a loss function
def loss_fn(params):
    v, model, x, y = params
    y_pred, probs = model(x)
    return ivy.cross_entropy(y, probs), probs
And train this model!
# train the model on gpu if it's available
device = "cuda:0" if ivy.gpu_is_available() else "cpu"

# training hyperparams
optimizer= ivy.Adam(1e-4)
batch_size = 64
num_epochs = 20
num_classes = 10

model = IvyNet(
    h_w=(28, 28),
    input_channels=1,
    output_channels=120,
    num_classes=num_classes,
    device=device,
)
model_name = type(model).__name__.lower()


# training loop
def train(images, classes, epochs, model, device, num_classes=10, batch_size=32):
    # training metrics
    epoch_loss = 0.0
    running_loss = 0.0
    fields = ["epoch", "epoch_loss", "training_accuracy"]
    metrics = []
    dataset_size = len(images)

    for epoch in range(epochs):
        train_loss, train_correct = 0, 0
        train_loop = tqdm(
            generate_batches(images, classes, len(images), batch_size=batch_size),
            total=dataset_size // batch_size,
            position=0,
            leave=True,
        )

        for xbatch, ybatch in train_loop:
            if device != "cpu":
                xbatch, ybatch = xbatch.to_device("gpu:0"), ybatch.to_device("gpu:0")

            # Since the cross entropy function expects the target classes to be in one-hot encoded format
            ybatch_encoded = ivy.one_hot(ybatch, num_classes)

            # update model params
            loss_probs, grads = ivy.execute_with_gradients(
                loss_fn,
                (model.v, model, xbatch, ybatch_encoded),
            )

            model.v = optimizer.step(model.v, grads["0"])

            batch_loss = ivy.to_numpy(loss_probs[0]).mean().item()  # batch mean loss
            epoch_loss += batch_loss * xbatch.shape[0]
            train_correct += num_correct(loss_probs[1], ybatch)

            train_loop.set_description(f"Epoch [{epoch + 1:2d}/{epochs}]")
            train_loop.set_postfix(
                running_loss=batch_loss,
                accuracy_percentage=(train_correct / dataset_size) * 100,
            )

        epoch_loss = epoch_loss / dataset_size
        training_accuracy = train_correct / dataset_size

        metrics.append([epoch, epoch_loss, training_accuracy])

        train_loop.write(
            f"\nAverage training loss: {epoch_loss:.6f}, Train Correct: {train_correct}",
            end="\n",
        )

    # write metrics for plotting
    with open(f"/{model_name}_train_summary.csv", "w") as f:
        f = csv.writer(f)
        f.writerow(fields)
        f.writerows(metrics)


# assuming the dataset(images and classes) are already prepared in a folder
train(images, classes, num_epochs, model, device, num_classes = num_classes, batch_size = batch_size)
Diving deeper
Although the Docs are the best place to learn more, in the next section we will take a look at how Ivy works both as a transpiler and a framework in a bit more detail to get an idea of why and where to use it.
Ivy as a transpiler
Ivy's transpiler allows you to use code from any other framework (or from any other version of the same framework!) in your own code, by just adding one line of code. Under the hood, Ivy traces a computational graph and leverages the frontends and backends to link one framework to another.
This way, Ivy makes all ML-related projects available for you, independently of the framework you want to use to research, develop, or deploy systems. Feel free to head over to the docs for the full API reference, but the functions you'd most likely want to use are:
# Traces an efficient fully-functional graph from a function, removing all wrapping and redundant code
ivy.trace_graph()

# Converts framework-specific code to a different framework
ivy.transpile()

# Converts framework-specific code to Ivy
ivy.unify()
These functions can be used eagerly or lazily. If you pass the necessary arguments for function tracing, the graph tracing/transpilation step will happen instantly (eagerly). Otherwise, the graph tracing/transpilation will happen only when the returned function is first invoked.
import ivy
import jax
ivy.set_backend("jax")

# Simple JAX function to transpile
def test_fn(x):
    return jax.numpy.sum(x)

x1 = ivy.array([1., 2.])
# Arguments are available -> transpilation happens eagerly
eager_graph = ivy.transpile(test_fn, source="jax", to="torch", args=(x1,))

# eager_graph is now torch code and runs efficiently
ret = eager_graph(x1)
# Arguments are not available -> transpilation happens lazily
lazy_graph = ivy.transpile(test_fn, source="jax", to="torch")

# The transpiled graph is initialized, transpilation will happen here
ret = lazy_graph(x1)

# lazy_graph is now torch code and runs efficiently
ret = lazy_graph(x1)
If you want to learn more, you can find more information in the Ivy as a transpiler section of the docs!
When should I use Ivy as a transpiler?
If you want to use building blocks published in other frameworks (neural networks, layers, array computing libraries, training pipelines...), you want to integrate code developed in various frameworks, or maybe straight up move code from one framework to another, the transpiler is definitely the tool 🔧 for the job! As the output of transpilation is native code in the target framework, you can use the converted code just as if it was code originally developed in that framework, applying framework-specific optimizations or tools, instantly exposing your project to all of the unique perks of a different framework.
Ivy as a framework
The Ivy framework is built on top of various essential components,
mainly the Backend
Handler,
which manages what framework is being used behind the scenes and the
Backend Functional
APIs,
which provide framework-specific implementations of the Ivy functions.
Likewise, classes such as ivy.Container or ivy.Array are also
available, facilitating the use of structured data and array-like
objects (learn more about them
here!).
All of the functionalities in Ivy are exposed through the
Ivy functional API and the Ivy stateful API. All functions in the
Functional
API
are Framework Agnostic Functions, which means that we can use them
like this:
import ivy
import jax.numpy as jnp
import tensorflow as tf
import numpy as np
import torch

def mse_loss(y, target):
    return ivy.mean((y - target)**2)

jax_mse   = mse_loss(jnp.ones((5,)), jnp.ones((5,)))
tf_mse    = mse_loss(tf.ones((5,)), tf.ones((5,)))
np_mse    = mse_loss(np.ones((5,)), np.ones((5,)))
torch_mse = mse_loss(torch.ones((5,)), torch.ones((5,)))
In the example above we show how Ivy's functions are compatible with tensors from different frameworks. This is the same for ALL Ivy functions. They can accept tensors from any framework and return the correct result.
The Ivy Stateful API, on the other hand, allows you to define trainable modules and layers, which you can use alone or as a part of any other framework code!
import ivy


class Regressor(ivy.Module):
    def __init__(self, input_dim, output_dim):
        self.input_dim = input_dim
        self.output_dim = output_dim
        super().__init__()

    def _build(self, *args, **kwargs):
        self.linear0 = ivy.Linear(self.input_dim, 128)
        self.linear1 = ivy.Linear(128, self.output_dim)

    def _forward(self, x):
        x = self.linear0(x)
        x = ivy.functional.relu(x)
        x = self.linear1(x)
        return x
If we put it all together, we'll have something like this. This example uses PyTorch as the backend, but this can easily be changed to your favorite frameworks, such as TensorFlow, or JAX.
import ivy


class Regressor(ivy.Module):
    def __init__(self, input_dim, output_dim):
        self.input_dim = input_dim
        self.output_dim = output_dim
        super().__init__()

    def _build(self, *args, **kwargs):
        self.linear0 = ivy.Linear(self.input_dim, 128)
        self.linear1 = ivy.Linear(128, self.output_dim)

    def _forward(self, x):
        x = self.linear0(x)
        x = ivy.functional.relu(x)
        x = self.linear1(x)
        return x

ivy.set_backend('torch')  # set backend to PyTorch (or any other backend!)

model = Regressor(input_dim=1, output_dim=1)
optimizer = ivy.Adam(0.3)

n_training_examples = 2000
noise = ivy.random.random_normal(shape=(n_training_examples, 1), mean=0, std=0.1)
x = ivy.linspace(-6, 3, n_training_examples).reshape((n_training_examples, 1))
y = 0.2 * x ** 2 + 0.5 * x + 0.1 + noise


def loss_fn(v, x, target):
    pred = model(x, v=v)
    return ivy.mean((pred - target) ** 2)

for epoch in range(40):
    # forward pass
    pred = model(x)

    # compute loss and gradients
    loss, grads = ivy.execute_with_gradients(lambda params: loss_fn(*params), (model.v, x, y))

    # update parameters
    model.v = optimizer.step(model.v, grads)

    # print current loss
    print(f'Epoch: {epoch + 1:2d} --- Loss: {ivy.to_numpy(loss).item():.5f}')

print('Finished training!')
The model's output can be visualized as follows:
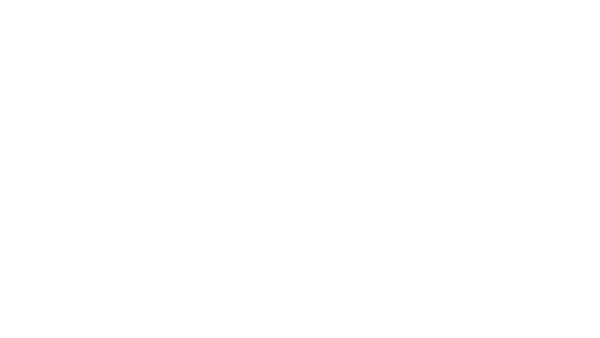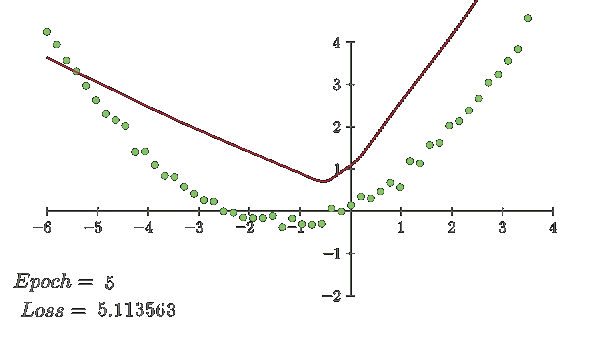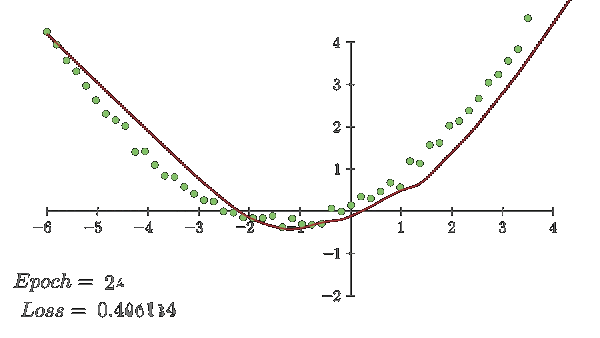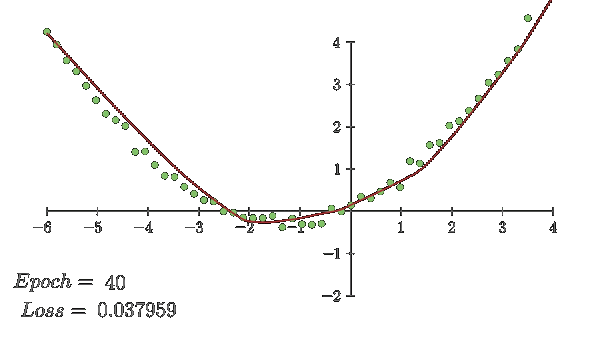
As always, you can find more information about Ivy as a framework in the docs!
When should I use Ivy as a framework?
As Ivy supports multiple backends, writing code in Ivy breaks you free from framework limitations. If you want to publish highly flexible code for everyone to use, independently of the framework they are using, or you plan to develop ML-related tools and want them to be interoperable with not only the already existing frameworks, but also with future frameworks, then Ivy is for you!
Contributing
We believe that everyone can contribute and make a difference. Whether it's writing code 💻, fixing bugs 🐛, or simply sharing feedback 💬, your contributions are definitely welcome and appreciated 🙌
Check out all of our open tasks, and find out more info in our Contributing guide in the docs!
Join our amazing community as a code contributor, and help accelerate our journey to unify all ML frameworks!

Community
In order to achieve the ambitious goal of unifying AI, we definitely need as many hands as possible on it! Whether you are a seasoned developer or just starting out, you'll find a place here! Join the Ivy community on our Discord 👾 server, which is the perfect place to ask questions, share ideas, and get help from both fellow developers and the Ivy Team directly!
Also! Feel free to follow us on Twitter 🐦 as well, we use it to share updates, sneak peeks, and all sorts of relevant news, certainly a great way to stay in the loop 😄
Can't wait to see you there!
Citation
If you use Ivy for your work, please don't forget to give proper credit by including the accompanying paper 📄 in your references. It's a small way to show appreciation and help to continue to support this and other open source projects 🙌
@article{lenton2021ivy,
  title={Ivy: Templated deep learning for inter-framework portability},
  author={Lenton, Daniel and Pardo, Fabio and Falck, Fabian and James, Stephen and Clark, Ronald},
  journal={arXiv preprint arXiv:2102.02886},
  year={2021}
}
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distributions
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file ivy-0.0.7.1.tar.gz.
File metadata
- Download URL: ivy-0.0.7.1.tar.gz
- Upload date:
- Size: 9.5 MB
- Tags: Source
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
499504d2e05bcaad3540cac1f92c644459d8bb56b817859c7ea19d6dfd1aa67d
|
|
| MD5 |
4701f8aae75f766da4a4358876bc7b67
|
|
| BLAKE2b-256 |
6f4722ea36e8ddcdcd1e0b7f9145fa07440f744ad23d611c1509ce9299dfc051
|
File details
Details for the file ivy-0.0.7.1-cp311-cp311-win_amd64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp311-cp311-win_amd64.whl
- Upload date:
- Size: 16.6 MB
- Tags: CPython 3.11, Windows x86-64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
392b3aa48a5292eb51aed492a4d59baf5ea3a0ea73e590101b89762f1aeefd15
|
|
| MD5 |
f554e4fd63d0578d755a4a1b9e238f1f
|
|
| BLAKE2b-256 |
6901993b991a79e46ac622c31e3bc85e0daf8adee16b8429383068b6176f9d8e
|
File details
Details for the file ivy-0.0.7.1-cp311-cp311-manylinux_2_17_x86_64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp311-cp311-manylinux_2_17_x86_64.whl
- Upload date:
- Size: 16.6 MB
- Tags: CPython 3.11, manylinux: glibc 2.17+ x86-64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
900b4c5813b0b81e7cb49343222b67d5b25b9ba89859e9f3019c303b462537c9
|
|
| MD5 |
a8e85ea6a484474f7c09ea9e3b456927
|
|
| BLAKE2b-256 |
35a46dea07ddc98f177765f81e0d3eb46a9d9603e28912001f85779ccf2cf981
|
File details
Details for the file ivy-0.0.7.1-cp311-cp311-macosx_12_0_arm64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp311-cp311-macosx_12_0_arm64.whl
- Upload date:
- Size: 9.9 MB
- Tags: CPython 3.11, macOS 12.0+ ARM64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
f69e85b3bf92fb613504c57114e1294bdfe1bafa8d1419e2c87ac6b08c96f488
|
|
| MD5 |
c41b08d8265475401d08c2cbab0996c7
|
|
| BLAKE2b-256 |
43ed8f7224bd9a03f44523805f887cb2e30f90ae39a843b18e6f16e6a91de6fb
|
File details
Details for the file ivy-0.0.7.1-cp310-cp310-win_amd64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp310-cp310-win_amd64.whl
- Upload date:
- Size: 16.3 MB
- Tags: CPython 3.10, Windows x86-64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
af8a6c253847e65ef655c1aad56e25e3bf80482e35ba653f7bcc7a79ab504712
|
|
| MD5 |
8c3323f08d0b62d33ddea97e20f13d78
|
|
| BLAKE2b-256 |
d8a0d1cb3aad3f6ac75f7b9a87f849fb6feaff33e3066682e97754e65a6e4554
|
File details
Details for the file ivy-0.0.7.1-cp310-cp310-manylinux_2_17_x86_64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp310-cp310-manylinux_2_17_x86_64.whl
- Upload date:
- Size: 16.3 MB
- Tags: CPython 3.10, manylinux: glibc 2.17+ x86-64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
a7e1b029f48df962629dae68326332f59e5bab3251173bcbb75f53e1136875c2
|
|
| MD5 |
e6afb6284b8c5326fdc542445b856fcd
|
|
| BLAKE2b-256 |
3d8eb27cf24d2c15db8cc138351b889ffe34cd0f28c029530c261f8181f6e29d
|
File details
Details for the file ivy-0.0.7.1-cp310-cp310-macosx_12_0_arm64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp310-cp310-macosx_12_0_arm64.whl
- Upload date:
- Size: 9.9 MB
- Tags: CPython 3.10, macOS 12.0+ ARM64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
a15090b44ff19b5a963b2186d0ed9f10728d4b3c311b4d579c7b95ecd4ba61d6
|
|
| MD5 |
b07fe89198eb81bca351f551d27ff068
|
|
| BLAKE2b-256 |
c5e7749acdda99acd3a11a04947e348c53920cba976fad33d3cd615c0ab5fead
|
File details
Details for the file ivy-0.0.7.1-cp39-cp39-win_amd64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp39-cp39-win_amd64.whl
- Upload date:
- Size: 16.4 MB
- Tags: CPython 3.9, Windows x86-64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
4edad10c47f57ebd3c896e9d3cbebe859a14334447b2e79524c5f8e9bb2b9056
|
|
| MD5 |
d70977bba32f20c6522e903041cdbe50
|
|
| BLAKE2b-256 |
79170749ccc38f139ef93ccd523d48d1a3596b1db153e9e2c70dd05a268c35ea
|
File details
Details for the file ivy-0.0.7.1-cp39-cp39-manylinux_2_17_x86_64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp39-cp39-manylinux_2_17_x86_64.whl
- Upload date:
- Size: 16.4 MB
- Tags: CPython 3.9, manylinux: glibc 2.17+ x86-64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
bdfafc924f5b2871dd6e593ac3087cf03418dc4f1592f909dacef450a3dcfbfa
|
|
| MD5 |
987889f0a5fac60cc0cedb7381860f07
|
|
| BLAKE2b-256 |
5fa1072621e2ff6305f76d6516e5cc9fa2f9961b6399c0ba34825fa757252cbd
|
File details
Details for the file ivy-0.0.7.1-cp38-cp38-win_amd64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp38-cp38-win_amd64.whl
- Upload date:
- Size: 16.2 MB
- Tags: CPython 3.8, Windows x86-64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
b360b8821a5608953564eaa94834c509bd134e9bc29a03f5e8eee7d6be53e909
|
|
| MD5 |
ab4d47318d6567f8a3f9a84c40ff6e7b
|
|
| BLAKE2b-256 |
b8c738a35b56d1451b126e38d697da118f2ba138c28abe5c46fd062bc175b00d
|
File details
Details for the file ivy-0.0.7.1-cp38-cp38-manylinux_2_17_x86_64.whl.
File metadata
- Download URL: ivy-0.0.7.1-cp38-cp38-manylinux_2_17_x86_64.whl
- Upload date:
- Size: 16.2 MB
- Tags: CPython 3.8, manylinux: glibc 2.17+ x86-64
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.0.0 CPython/3.10.12
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
ed7bec488d0c79430dced59f37e5917e7bce40d82eb7ac2d17e9c7fe65568afc
|
|
| MD5 |
1da2fb1a39936cdd495eb45f350ec46b
|
|
| BLAKE2b-256 |
f891975035eae2296bafc17bfbf5a04211eed14c4b23a109321161546ea85c9f
|














