
libtabular
A general purpose library for reading and writing tabular data (CSV, TSV, gsheets, ods, xlsx).
Pitch
Imagine a csv.DictReader-like API you can use to "open" and "read" any source
of tabular data (CSV, TSV, gsheets, ods, xlsx) without having to worry about a
million libraries and authentication APIs.
Tabular data with metadata headers
The main "new feature" that libtabular provides is a way to parse "metadata headers"
in tabular data (e.g. CSV) automatically. These "CSV metadata headers" are directly
analogous to the YAML headers that sometimes appear in Markdown files used in
static site generators.
Example
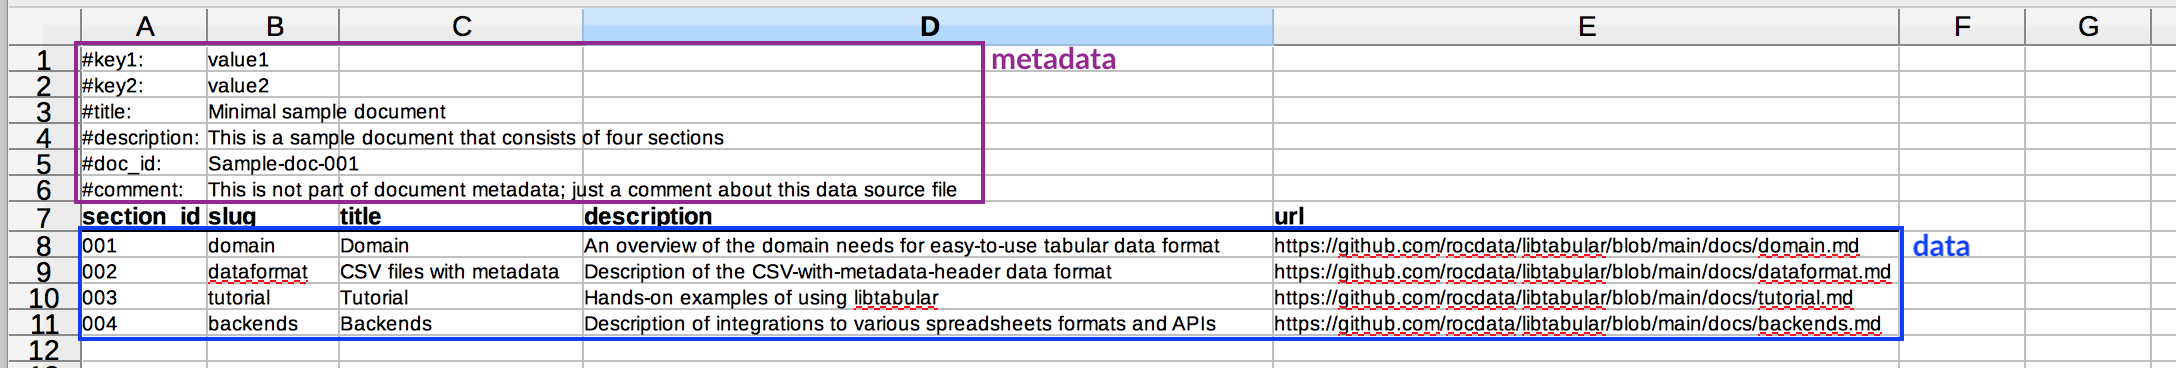
Using libtabular, you could "extract" the data and metadata from this source
file using a few commands:
>>> from libtabular import fromcsvwithheader

>>> table = fromcsvwithheader('samples/minimal.csv')

>>> table.metadata
{'key1': 'value1',
 'key2': 'value2',
 'title': 'Minimal sample document',
 'description': 'This is a sample document that consists of four sections',
 'doc_id': 'Sample-doc-001',
 'comment': 'This is not part of document metadata; just a comment...'}

>>> list(table.dicts())
[{'section_id': '002',
  'slug': 'dataformat',
  'title': 'CSV files with metadata',
  'description': 'Description of the CSV-with-metadata-header data format',
  'url': 'https://github.com/rocdata/libtabular/blob/main/docs/dataformat.md'},
 {'section_id': '003',
  'slug': 'tutorial',
  'title': 'Tutorial',
  'description': 'Hands-on examples of using libtabular',
  'url': 'https://github.com/rocdata/libtabular/blob/main/docs/tutorial.md'},
 {'section_id': '004',
  'slug': 'backends',
  'title': 'Backends',
  'description': 'Description of integrations to various spreadsheets formats and APIs  ',
  'url': 'https://github.com/rocdata/libtabular/blob/main/docs/backends.md'}]


>>> table.header
('section_id', 'slug', 'title', 'description', 'url')
Why is this needed?
Recent work on a repository of curriculum documents, see rocdata.global, requires an easy-to-use process for import and export of curriculum data like:
- Curriculum standards documents (excel sheets that specify what students should be learning)
- Content collections data (excel sheets that consists of links to useful learning resources)
- Content correlations data (excel sheets that contain "links" between curriculum standards and relevant learning resources)
The spreadsheet/CSV format is a natural choice for teachers and administrators, who have experience working with this file type, so it is worth developing tools that facilitate reading and writing tabular data:
- Curriculum bodies and ministries of education can publish curriculum standards documents information in machine-readable formats (instead of publishing PDFs, publish spreadsheets).
- Teachers can download standards data in easy-to-use spreadsheet formats (use standards for your grade level to plan your lessons).
- Curriculum experts and teachers can download blank templates with appropriate headers to fill in when need to specify standards documents or content correlations.
Related projects
csvin stdlibpandas.read_csvwhich is a few more bells and whistles.petlhas a lot of functionality for loading CSV, TSV, Excel, and a bunch of other format. Thepetllibrary also supports convenient transformation of columns. There is even a PR for integration with google sheets (not merged).pyexcelis a general-purpose backend for all kinds of spreadsheet formats (csv, xlsx, ods, etc.)- For other spreadsheet Python libs, see http://www.python-excel.org/
TODOs
- Add
fromxlsxwithheaderfor parsing Excel files - Add
fromodswithheaderbased onpyexcel - Add minimal tests to check all source formats result in same data
- Add
prependheader(metadata, header, data)function to export in this format, ideally generic workflow that works for any output format (csv,ods,xlsx).
Roadmap
- Add tree-parsing logic utils? (libtree ;)
- Includes statements (include another .CSV file as a node in current location)
- Optional enhancements for templates: add formatting of header etc. (only for Excel and ODS)
Ideas
- Investigate CSVW standard and libraries, specifically options for validation.
- Investigate
tablibas an alternative base topetl(although seems less versatile).
1 maintainer

Metadata
1 maintainer
Release files for libtabular 0.0.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| libtabular-0.0.3.tar.gz | 5.8 kB | Without provenance | Details |
Release files / libtabular-0.0.3.tar.gz
| Download URL | libtabular-0.0.3.tar.gz |
|---|---|
| Size | 5.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
95368354408938613c11c25399fa237f45ae059404f39d1c8727ff8bc9f8d4d0
|
|
BLAKE2b-256 checksum How to use checksums |
d0f3ed324819051c9dcf258474105ad2af0286e99dbcf99a8c9d8f3b970ae6cf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.3.0 pkginfo/1.7.0 requests/2.25.1 setuptools/52.0.0 requests-toolbelt/0.9.1 tqdm/4.56.0 CPython/3.6.9
|
Security for libtabular 0.0.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














