
LitServe: Deploy AI models Lightning fast ⚡
High-throughput serving engine for AI models.
Friendly interface. Enterprise scale.
LitServe is a FastAPI-based engine for scalable AI model deployment. Features like batching, streaming, and GPU autoscaling eliminate the need to rebuild a FastAPI server for each model.
✅ Batching       ✅ Streaming          ✅ Auto-GPU, multi-GPU
✅ Multi-modal    ✅ PyTorch/JAX/TF     ✅ Full control
✅ Auth           ✅ Built on Fast API  ✅ Custom specs (Open AI)


Performance
LitServe (built on FastAPI), is optimized for AI workloads like model serving, embeddings, and LLM serving.
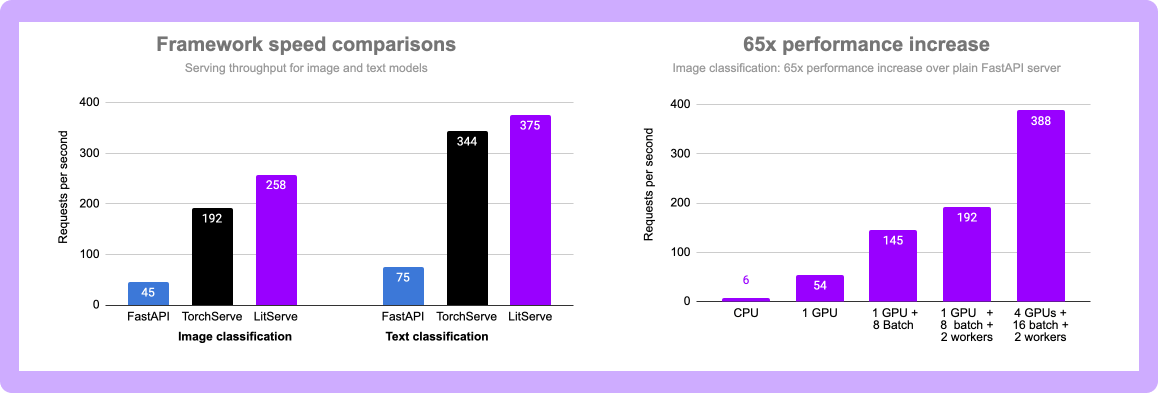
These benchmarks are for image and text classification as examples. Reproduce the full benchmarks here.
💡 Note on LLM serving: For high-performance LLM serving (like Ollama/VLLM), use LitGPT or build your custom VLLM-like server with LitServe. Optimizations like kv-caching, which can be done with LitServe, are needed to maximize LLM performance.
Featured examples
Key features |
Featured examples |
Quick start
Install LitServe via pip (or advanced installs):
pip install litserve
Define a server
Here's a hello world example (explore real examples):
# server.py
import litserve as ls

# STEP 1: DEFINE A MODEL API
class SimpleLitAPI(ls.LitAPI):
    # Called once at startup. Setup models, DB connections, etc...
    def setup(self, device):
        self.model = lambda x: x**2

    # Convert the request payload to model input.
    def decode_request(self, request):
        return request["input"]

    # Run inference on the the model, return the output.
    def predict(self, x):
        return self.model(x)

    # Convert the model output to a response payload.
    def encode_response(self, output):
        return {"output": output}

# STEP 2: START THE SERVER
if __name__ == "__main__":
    api = SimpleLitAPI()
    server = ls.LitServer(api, accelerator="auto")
    server.run(port=8000)
Now run the server via the command-line
python server.py
LitAPI class gives full control and hackability.
LitServer handles optimizations like batching, auto-GPU scaling, etc...
Query the server
Use the automatically generated LitServe client or write your own:
Option A - Use generated client: |
Option B - Custom client example: |
Deployment options
LitServe is developed by Lightning AI which provides infrastructure for deploying AI models. Self-manage deployments or use Lightning Studios for production-grade deployments without cloud headaches, security and 99.95% uptime SLA.

| Feature | Self Managed | Fully Managed on Studios |
|---|---|---|
| Deployment | ✅ Do it yourself deployment | ✅ One-button cloud deploy |
| Load balancing | ❌ | ✅ |
| Autoscaling | ❌ | ✅ |
| Multi-machine inference | ❌ | ✅ |
| Authentication | ❌ | ✅ |
| Own VPC | ❌ | ✅ |
| AWS, GCP | ❌ | ✅ |
| Use your own cloud commits | ❌ | ✅ |
Features
LitServe supports multiple advanced state-of-the-art features.
✅ All model types: LLMs, vision, time series, etc....
✅ Auto-GPU scaling.
✅ Authentication.
✅ Autoscaling.
✅ Batching.
✅ Streaming.
✅ All ML frameworks: PyTorch, Jax, Tensorflow, Hugging Face....
✅ Open AI spec.
10+ features....
Note: Our goal is not to jump on every hype train, but instead support features that scale under the most demanding enterprise deployments.
Community
LitServe is a community project accepting contributions - Let's make the world's most advanced AI inference engine.
Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file litserve-0.1.4.tar.gz.
File metadata
- Download URL: litserve-0.1.4.tar.gz
- Upload date:
- Size: 28.8 kB
- Tags: Source
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.1.0 CPython/3.12.4
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
8183f71ea2537165b1dfeaa209441008473b3e6ed2fe5330b67f62b1c8188546
|
|
| MD5 |
94411b573f70c10ad151a7342fdb212b
|
|
| BLAKE2b-256 |
237997182c6473f1fe7099751ec75a6aa469c6cc5b5af52d72abce1e36d9e387
|
File details
Details for the file litserve-0.1.4-py3-none-any.whl.
File metadata
- Download URL: litserve-0.1.4-py3-none-any.whl
- Upload date:
- Size: 29.9 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.1.0 CPython/3.12.4
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
2fc54aa1d088917b2d9462f6c599b91e845402ae8ace0c26ef02df110e1be961
|
|
| MD5 |
beefb0568c4e14b96bf672a6515328ff
|
|
| BLAKE2b-256 |
b6e4329d4a087f038082f693c8f20ef0affa6690df5bff853d5dc5c572bede9d
|














