
LitServe: Easily serve AI models Lightning fast ⚡
Flexible, high-throughput serving engine for AI models.
Friendly interface. Enterprise scale.
LitServe is a flexible serving engine for AI models built on FastAPI. Features like batching, streaming, and GPU autoscaling eliminate the need to rebuild a FastAPI server per model.
LitServe is at least 2x faster than plain FastAPI.
✅ (2x)+ faster serving   ✅ Self-host or fully managed  ✅ Auto-GPU, multi-GPU
✅ Multi-modal            ✅ PyTorch/JAX/TF              ✅ Full control
✅ Batching               ✅ Built on Fast API           ✅ Streaming


Quick start
Install LitServe via pip (other install options):
pip install litserve
Define a server
Here's a hello world example (explore real examples):
# server.py
import litserve as ls

# STEP 1: DEFINE A MODEL API
class SimpleLitAPI(ls.LitAPI):
    # Called once at startup. Setup models, DB connections, etc...
    def setup(self, device):
        self.model = lambda x: x**2

    # Convert the request payload to model input.
    def decode_request(self, request):
        return request["input"]

    # Run inference on the the model, return the output.
    def predict(self, x):
        return self.model(x)

    # Convert the model output to a response payload.
    def encode_response(self, output):
        return {"output": output}

# STEP 2: START THE SERVER
if __name__ == "__main__":
    api = SimpleLitAPI()
    server = ls.LitServer(api, accelerator="auto")
    server.run(port=8000)
Now run the server via the command-line
python server.py
LitAPI class gives full control and hackability.
LitServer handles optimizations like batching, auto-GPU scaling, etc...
Query the server
Use the automatically generated LitServe client:
python client.py
Write a custom client
import requests
response = requests.post(
    "http://127.0.0.1:8000/predict",
    json={"input": 4.0}
)
Featured examples
Use LitServe to deploy any model or AI service: (Gen AI, classical ML, embedding servers, LLMs, vision, audio, multi-modal systems, etc...)
Featured examples

Toy model:      Hello world
LLMs:           Llama 3 (8B), LLM Proxy server
NLP:            Hugging face, BERT, Text embedding API
Multimodal:     OpenAI Clip, MiniCPM, Chameleon 30B
Audio:          Whisper, AudioCraft, StableAudio, Noise cancellation (DeepFilterNet)
Vision:         Stable diffusion 2, AuroraFlow, Flux, Image super resolution (Aura SR)
Speech:         Text-speech (XTTS V2)
Classical ML:   Random forest, XGBoost
Miscellaneous:  Media conversion API (ffmpeg)
Browse 100s of community-built templates.
Features
LitServe supports multiple advanced state-of-the-art features.
✅ (2x)+ faster serving than plain FastAPI
✅ Self host on your own machines
✅ Host fully managed on Lightning AI
✅ Serve all models: LLMs, vision, time series, etc...
✅ Auto-GPU scaling
✅ Authentication
✅ Autoscaling
✅ Batching
✅ Streaming
✅ Scale to zero (serverless)
✅ All ML frameworks: PyTorch, Jax, Tensorflow, Hugging Face...
✅ Open AI compatibility
Note: Our goal is not to jump on every hype train, but instead support features that scale under the most demanding enterprise deployments.
Performance
LitServe is highly optimized for parallel execution with native features optimized to scale AI workloads. Our benchmarks show that LitServe (built on FastAPI) handles more simultaneous requests than FastAPI and TorchServe (higher is better).
Reproduce the full benchmarks here.
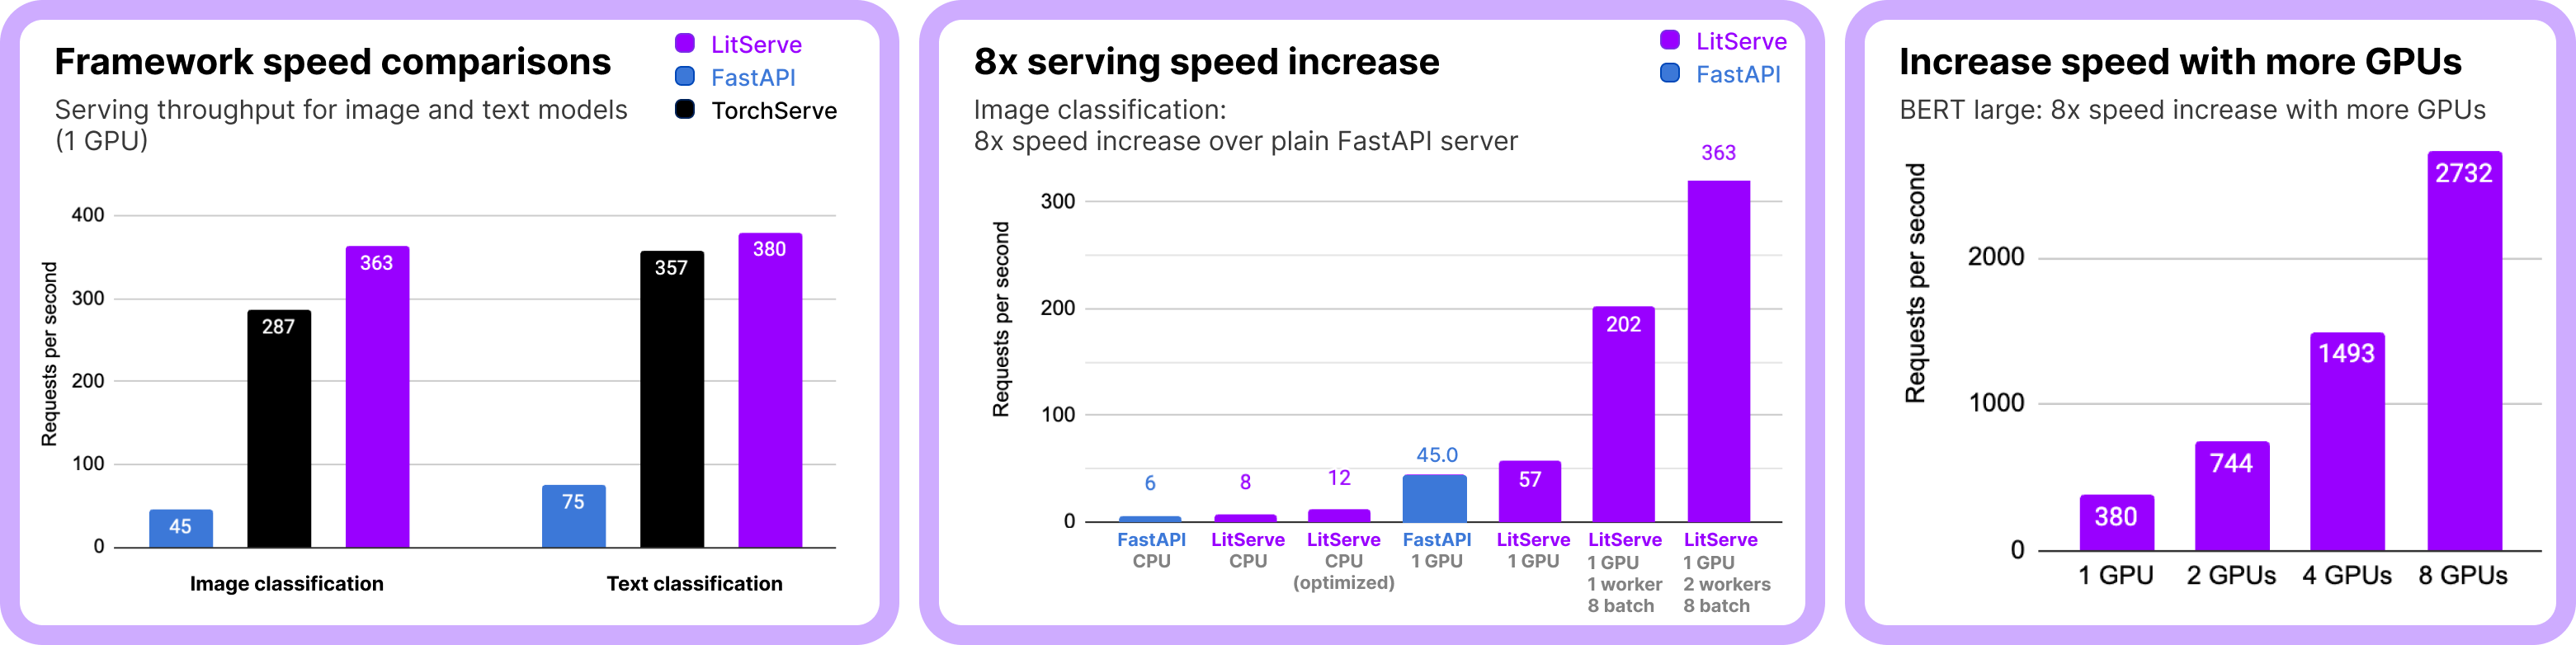
These results are for image and text classification ML tasks. The performance relationships hold for other ML tasks (embedding, LLM serving, audio, segmentation, object detection, summarization etc...).
💡 Note on LLM serving: For high-performance LLM serving (like Ollama/VLLM), use LitGPT or build your custom VLLM-like server with LitServe. Optimizations like kv-caching, which can be done with LitServe, are needed to maximize LLM performance.
Hosting options
LitServe can be hosted independently on your own machines or fully managed via Lightning Studios.
Self-hosting is ideal for hackers, students, and DIY developers, while fully managed hosting is ideal for enterprise developers needing easy autoscaling, security, release management, and 99.995% uptime and observability.

| Feature | Self Managed | Fully Managed on Studios |
|---|---|---|
| Deployment | ✅ Do it yourself deployment | ✅ One-button cloud deploy |
| Load balancing | ❌ | ✅ |
| Autoscaling | ❌ | ✅ |
| Scale to zero | ❌ | ✅ |
| Multi-machine inference | ❌ | ✅ |
| Authentication | ❌ | ✅ |
| Own VPC | ❌ | ✅ |
| AWS, GCP | ❌ | ✅ |
| Use your own cloud commits | ❌ | ✅ |
Community
LitServe is a community project accepting contributions - Let's make the world's most advanced AI inference engine.
Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file litserve-0.2.0.tar.gz.
File metadata
- Download URL: litserve-0.2.0.tar.gz
- Upload date:
- Size: 31.2 kB
- Tags: Source
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.1.0 CPython/3.12.5
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
1f7d3d417bcc8690909efb25755561ee7df9f24c6e9b54ab3c932f1041268fd1
|
|
| MD5 |
4f10a58da5164a5c1722b9309c0a092f
|
|
| BLAKE2b-256 |
fab773415e4cac2ae0f1b3572a8e1cdbe5a3454704f211de23580a2ee9bdadbe
|
File details
Details for the file litserve-0.2.0-py3-none-any.whl.
File metadata
- Download URL: litserve-0.2.0-py3-none-any.whl
- Upload date:
- Size: 31.3 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.1.0 CPython/3.12.5
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
f9a3163fcfbec2f5ea7ef59a1ccb7941a732cf37b8502e75cb69477db3929402
|
|
| MD5 |
9827e04288cc24573d5c357e5ba40c79
|
|
| BLAKE2b-256 |
0179cccafca06607b2d684303bbb1a50da2c4f51b70281730cee6630f6cd1869
|














