
This release has been yanked by its maintainers, and will be ignored by installers, except when explicitly specified.
Consider using release 0.2.18 instead.
Easily serve AI models Lightning fast ⚡
Lightning-fast serving engine for AI models.
Easy. Flexible. Enterprise-scale.
LitServe is an easy-to-use, flexible serving engine for AI models built on FastAPI. It augments FastAPI with features like batching, streaming, and GPU autoscaling eliminate the need to rebuild a FastAPI server per model.
LitServe is at least 2x faster than plain FastAPI due to AI-specific multi-worker handling.
✅ (2x)+ faster serving  ✅ Easy to use          ✅ LLMs, non LLMs and more
✅ Bring your own model  ✅ PyTorch/JAX/TF/...   ✅ Built on FastAPI
✅ GPU autoscaling       ✅ Batching, Streaming  ✅ Self-host or ⚡️ managed
✅ Compound AI           ✅ Integrate with vLLM and more


Quick start
Install LitServe via pip (more options):
pip install litserve
Define a server
This toy example with 2 models (AI compound system) shows LitServe's flexibility (see real examples):
# server.py
import litserve as ls

# (STEP 1) - DEFINE THE API (compound AI system)
class SimpleLitAPI(ls.LitAPI):
    def setup(self, device):
        # setup is called once at startup. Build a compound AI system (1+ models), connect DBs, load data, etc...
        self.model1 = lambda x: x**2
        self.model2 = lambda x: x**3

    def decode_request(self, request):
        # Convert the request payload to model input.
        return request["input"]

    def predict(self, x):
        # Easily build compound systems. Run inference and return the output.
        squared = self.model1(x)
        cubed = self.model2(x)
        output = squared + cubed
        return {"output": output}

    def encode_response(self, output):
        # Convert the model output to a response payload.
        return {"output": output}

# (STEP 2) - START THE SERVER
if __name__ == "__main__":
    # scale with advanced features (batching, GPUs, etc...)
    server = ls.LitServer(SimpleLitAPI(), accelerator="auto", max_batch_size=1)
    server.run(port=8000)
Now run the server via the command-line
python server.py
Test the server
Run the auto-generated test client:
python client.py
Or use this terminal command:
curl -X POST http://127.0.0.1:8000/predict -H "Content-Type: application/json" -d '{"input": 4.0}'
LLM serving
LitServe isn’t just for LLMs like vLLM or Ollama; it serves any AI model with full control over internals (learn more).
For easy LLM serving, integrate vLLM with LitServe, or use LitGPT (built on LitServe).
litgpt serve microsoft/phi-2
Summary
- LitAPI lets you easily build complex AI systems with one or more models (docs).
- Use the setup method for one-time tasks like connecting models, DBs, and loading data (docs).
- LitServer handles optimizations like batching, GPU autoscaling, streaming, etc... (docs).
- Self host on your own machines or use Lightning Studios for a fully managed deployment (learn more).
Learn how to make this server 200x faster.
Featured examples
Use LitServe to deploy any model or AI service: (Compound AI, Gen AI, classic ML, embeddings, LLMs, vision, audio, etc...)
Examples
Toy model:      Hello world
LLMs:           Llama 3.2, LLM Proxy server, Agent with tool use
RAG:            vLLM RAG (Llama 3.2), RAG API (LlamaIndex)
NLP:            Hugging face, BERT, Text embedding API
Multimodal:     OpenAI Clip, MiniCPM, Phi-3.5 Vision Instruct, Qwen2-VL, Pixtral
Audio:          Whisper, AudioCraft, StableAudio, Noise cancellation (DeepFilterNet)
Vision:         Stable diffusion 2, AuraFlow, Flux, Image Super Resolution (Aura SR),
                Background Removal, Control Stable Diffusion (ControlNet)
Speech:         Text-speech (XTTS V2), Parler-TTS
Classical ML:   Random forest, XGBoost
Miscellaneous:  Media conversion API (ffmpeg), PyTorch + TensorFlow in one API, LLM proxy server
Browse 100+ community-built templates
Features
State-of-the-art features:
✅ (2x)+ faster than plain FastAPI
✅ Bring your own model
✅ Build compound systems (1+ models)
✅ GPU autoscaling
✅ Batching
✅ Streaming
✅ Worker autoscaling
✅ Self-host on your machines
✅ Host fully managed on Lightning AI
✅ Serve all models: (LLMs, vision, etc.)
✅ Scale to zero (serverless)
✅ Supports PyTorch, JAX, TF, etc...
✅ OpenAPI compliant
✅ Open AI compatibility
✅ Authentication
✅ Dockerization
Note: We prioritize scalable, enterprise-level features over hype.
Performance
LitServe is designed for AI workloads. Specialized multi-worker handling delivers a minimum 2x speedup over FastAPI.
Additional features like batching and GPU autoscaling can drive performance well beyond 2x, scaling efficiently to handle more simultaneous requests than FastAPI and TorchServe.
Reproduce the full benchmarks here (higher is better).
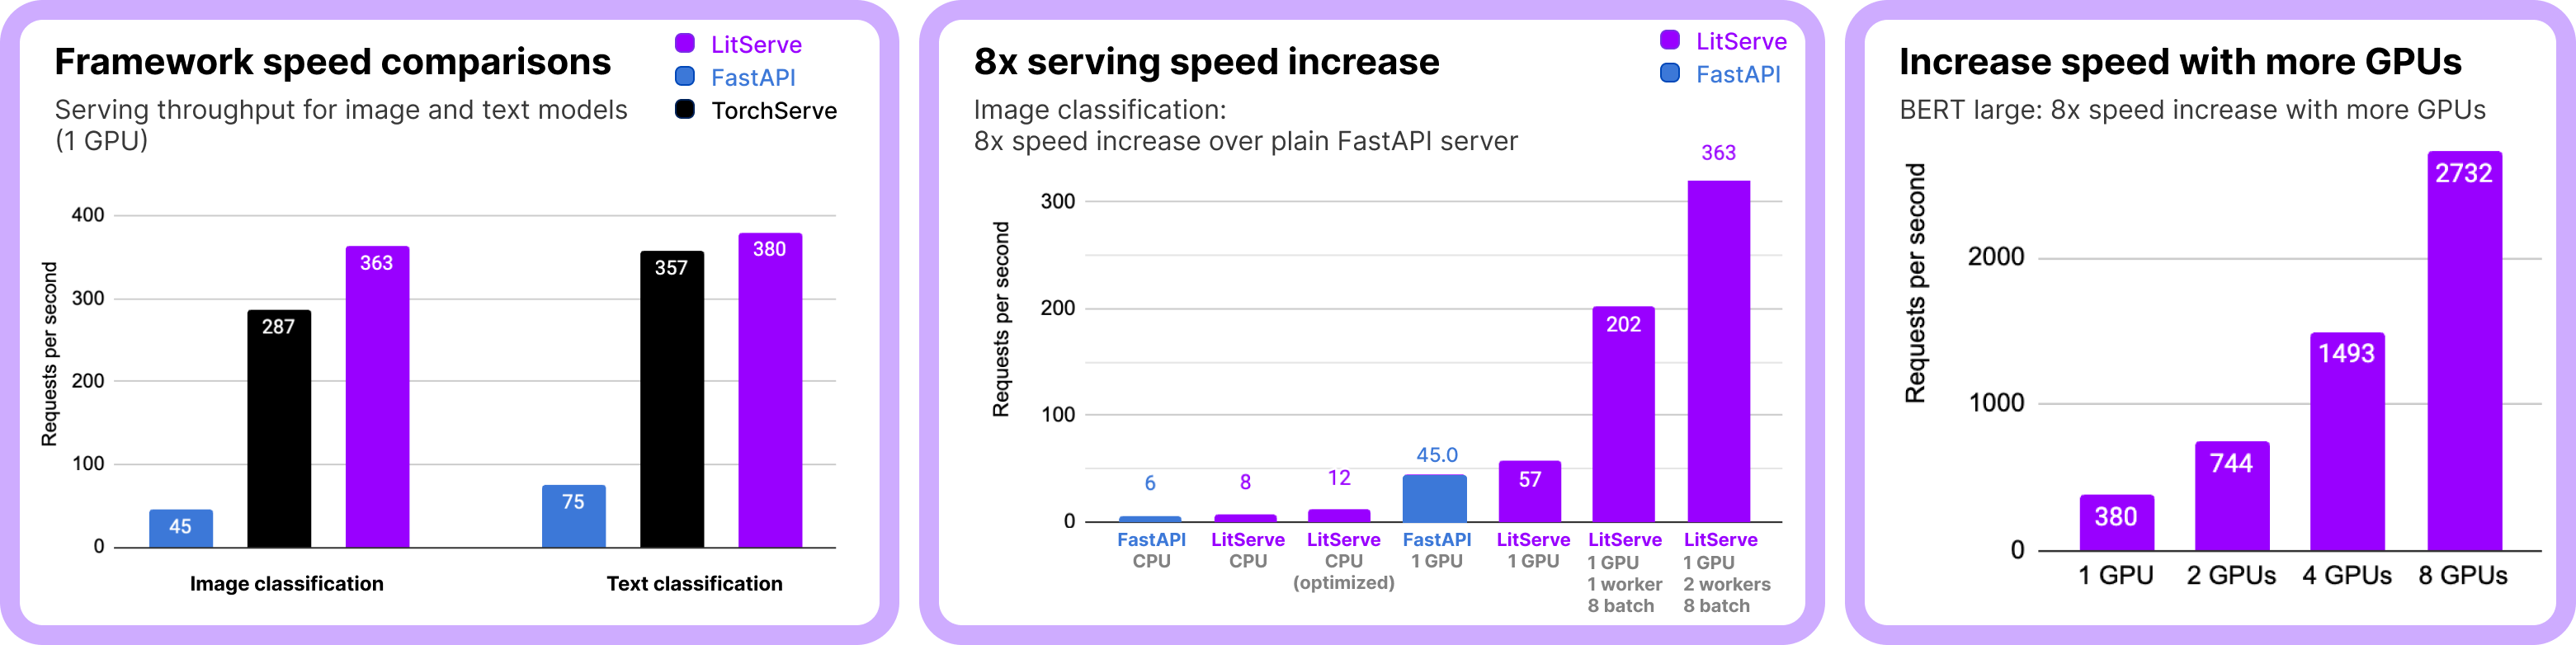
These results are for image and text classification ML tasks. The performance relationships hold for other ML tasks (embedding, LLM serving, audio, segmentation, object detection, summarization etc...).
💡 Note on LLM serving: For high-performance LLM serving (like Ollama/vLLM), integrate vLLM with LitServe, use LitGPT, or build your custom vLLM-like server with LitServe. Optimizations like kv-caching, which can be done with LitServe, are needed to maximize LLM performance.
Hosting options
LitServe can be hosted independently on your own machines or fully managed via Lightning Studios.
Self-hosting is ideal for hackers, students, and DIY developers, while fully managed hosting is ideal for enterprise developers needing easy autoscaling, security, release management, and 99.995% uptime and observability.
| Feature | Self Managed | Fully Managed on Studios |
|---|---|---|
| Deployment | ✅ Do it yourself deployment | ✅ One-button cloud deploy |
| Load balancing | ❌ | ✅ |
| Autoscaling | ❌ | ✅ |
| Scale to zero | ❌ | ✅ |
| Multi-machine inference | ❌ | ✅ |
| Authentication | ❌ | ✅ |
| Own VPC | ❌ | ✅ |
| AWS, GCP | ❌ | ✅ |
| Use your own cloud commits | ❌ | ✅ |
Community
LitServe is a community project accepting contributions - Let's make the world's most advanced AI inference engine.
Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file litserve-0.2.6.dev3.tar.gz.
File metadata
- Download URL: litserve-0.2.6.dev3.tar.gz
- Upload date:
- Size: 50.6 kB
- Tags: Source
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.1.0 CPython/3.12.8
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
a0e49e8917ff7e61168ff9d9c15f621b04987319aac8bb9dedb5ae90e554c369
|
|
| MD5 |
74e69ed49f09185b76e9c2fcdf48474b
|
|
| BLAKE2b-256 |
892dc0e8e1b39fb279a15691cdc59cf24c9c9c8b4b18822b6d48cd4ea1ba0021
|
File details
Details for the file litserve-0.2.6.dev3-py3-none-any.whl.
File metadata
- Download URL: litserve-0.2.6.dev3-py3-none-any.whl
- Upload date:
- Size: 62.1 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/5.1.0 CPython/3.12.8
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
d9e14d4e9164bd9764fc1529353d53598e0d0d0edcb690ba095926a6e72ed1f5
|
|
| MD5 |
47e00ba5638ac675c26c853f4d2357f5
|
|
| BLAKE2b-256 |
e6cca2d357b183ab7e763d77bea30610ea9e4ac54b4c2cb0a3375edc200d0c97
|














