
panoptica



Computing instance-wise segmentation quality metrics for 2D and 3D semantic- and instance segmentation maps.
Use Cases & Tutorials | Documentation
Features
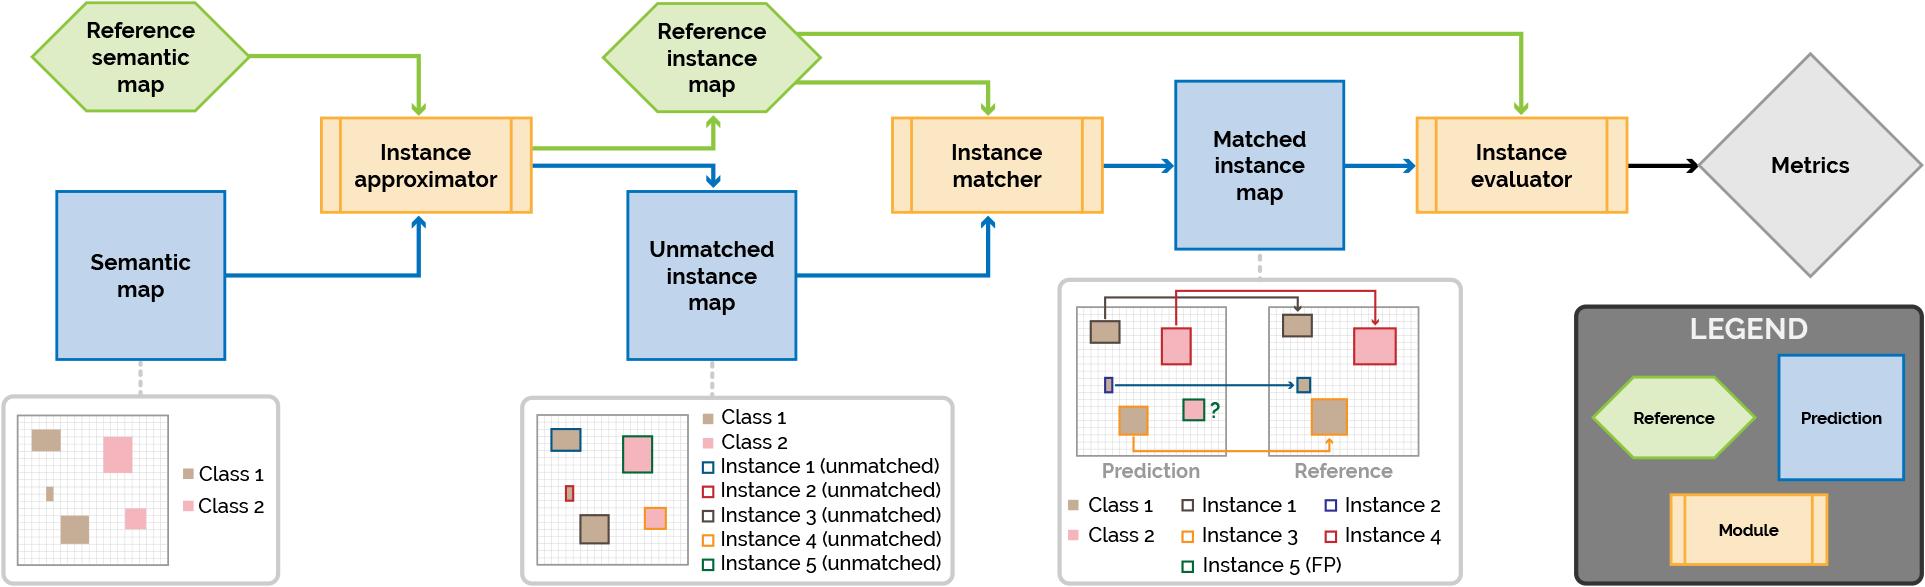
The package provides three core modules:
- Instance Approximator: instance approximation algorithms to extract instances from semantic segmentation maps/model outputs.
- Instance Matcher: matches predicted instances with reference instances.
- Instance Evaluator: computes segmentation and detection quality metrics for pairs of predicted - and reference segmentation maps.
Installation
With a Python 3.10+ environment, you can install panoptica from pypi.org
pip install panoptica

# or with optional GPU capabilities
pip install panoptica[gpu]
Or, alternatively, from conda:
conda install -c conda-forge panoptica
Available Metrics
Use Cases & Tutorials
Minimal example
A minimal example of using panoptica could look e.g. like this (here with Matched Instances as Input):
from panoptica import InputType, Panoptica_Evaluator
from panoptica.metrics import Metric

ref_masks = "<path-to-your>/reference.nii.gz"
pred_masks = "<path-to-your>/prediction.nii.gz"

evaluator = Panoptica_Evaluator(
    expected_input=InputType.MATCHED_INSTANCE,
    decision_metric=Metric.IOU,
    decision_threshold=0.5,
)

result = evaluator.evaluate(pred_masks, ref_masks)["ungrouped"]
Semantic Segmentation Input
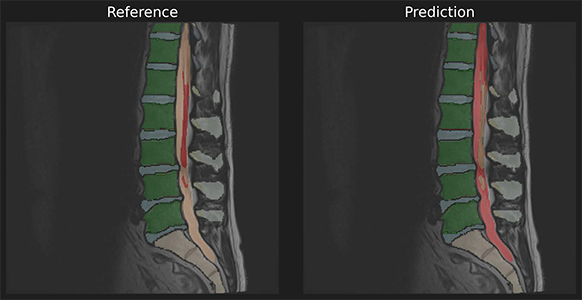
Although an instance-wise evaluation is highly relevant and desirable for many biomedical segmentation problems, they are still addressed as semantic segmentation problems due to the lack of appropriate instance labels.
This tutorial leverages all three modules of panoptica: instance approximation, -matching and -evaluation.

Unmatched Instances Input
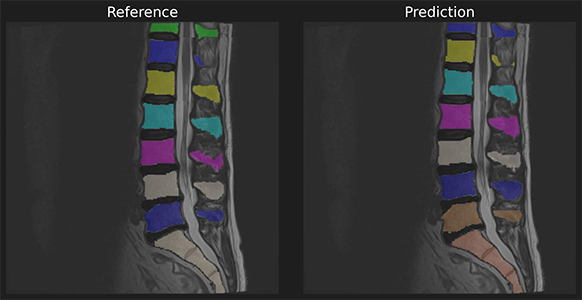
It is a common issue that instance segmentation outputs feature good outlines but mismatched instance labels. For this case, the matcher module can be utilized to match instances and the evaluator to report metrics.
Matched Instances Input
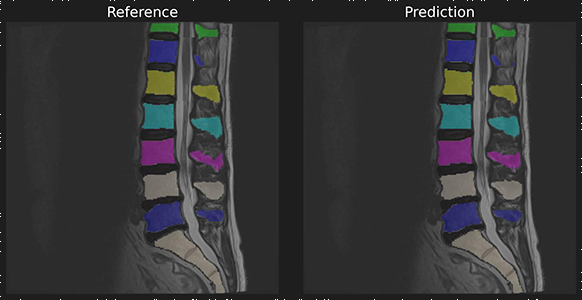
If your predicted instances already match the reference instances, you can directly compute metrics using the evaluator module.
Matching Algorithm Example
Using Configs (saving and loading)
You can construct Panoptica_Evaluator (among many others) objects and save their arguments, so you can save project-specific configurations and use them later. It uses ruamel.yaml in a readable way.
Using Panoptica Aggregator
Using our Panoptica Aggregator, you can evaluate your data while the Aggregator takes care of writing the results into a .tsv file (threading-safe). This allows you to focus only on the important part, that is loading and iterating over your data. From the aggregator, you can immediately get a Panoptica Statistics object that yield you the statistics over your metrics as well as create nice figures for you.
Tutorial: TBD
Documentation
We provide a readthedocs documentation of our codebase here
Citation
Kofler, F., Möller, H., Buchner, J. A., de la Rosa, E., Ezhov, I., Rosier, M., Mekki, I., Shit, S., Negwer, M., Al-Maskari, R., Ertürk, A., Vinayahalingam, S., Isensee, F., Pati, S., Rueckert, D., Kirschke, J. S., Ehrlich, S. K., Reinke, A., Menze, B., Wiestler, B., & Piraud, M. (2023). Panoptica -- instance-wise evaluation of 3D semantic and instance segmentation maps. arXiv preprint arXiv:2312.02608.
@misc{kofler2023panoptica,
      title={Panoptica -- instance-wise evaluation of 3D semantic and instance segmentation maps},
      author={Florian Kofler and Hendrik Möller and Josef A. Buchner and Ezequiel de la Rosa and Ivan Ezhov and Marcel Rosier and Isra Mekki and Suprosanna Shit and Moritz Negwer and Rami Al-Maskari and Ali Ertürk and Shankeeth Vinayahalingam and Fabian Isensee and Sarthak Pati and Daniel Rueckert and Jan S. Kirschke and Stefan K. Ehrlich and Annika Reinke and Bjoern Menze and Benedikt Wiestler and Marie Piraud},
      year={2023},
      eprint={2312.02608},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
Contributing
We welcome all kinds of contributions from the community!
Reporting Bugs, Feature Requests and Questions
Please open a new issue here.
Code contributions
Nice to have you on board! Please have a look at our CONTRIBUTING.md file.
2 maintainers


Metadata
2 maintainers
Release files for panoptica 2.1.7
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| panoptica-2.1.7.tar.gz | 106.3 kB | Without provenance | Details |
Release files / panoptica-2.1.7.tar.gz
| Download URL | panoptica-2.1.7.tar.gz |
|---|---|
| Size | 106.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fd8b34fc9e7068360d0dcacb40d7ec601b41f9047181bb55162fb9bd5e08ca3a
|
|
BLAKE2b-256 checksum How to use checksums |
d8df397889ac1850ba058d311058e16cf546999f8e5aa963a6a62dde7bda4058
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.7
|
Security for panoptica 2.1.7
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














