
pdf2docx


- Parse text, table and layout from PDF file with
PyMuPDF - Generate docx with
python-docx
Features
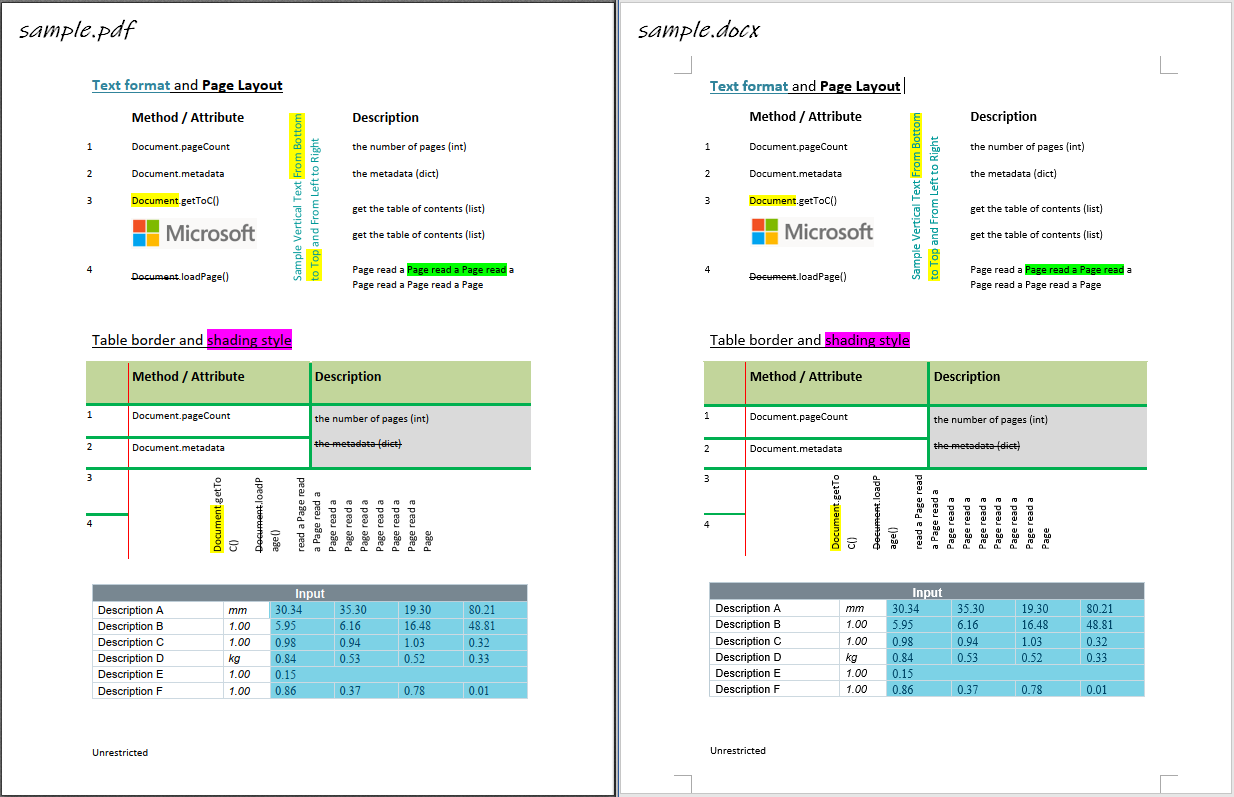
- Parse and re-create text format
- font style, e.g. font name, size, weight, italic and color
- highlight, underline, strike-through converted from docx or PDF annotations
- text alignment, e.g. left/right/center/adjust
- Parse and re-create list style
- Parse and re-create table
- border style, e.g. width, color
- shading style, i.e. background color
- merged cells
- vertical direction cell
- table with partly hidden borders
- Rebuild page layout in docx
- text in horizontal direction: from left to right
- text in vertical direction: from bottom to top
- in-line image
- paragraph layout: horizontal alignment and vertical spacing
- Parsing pages with multi-processing
It can also be used as a tool to extract table contents since both table content and format/style is parsed.
Limitations
- Text-based PDF file only
- Normal reading direction only
- horizontal/vertical paragraph/line/word
- no word transformation, e.g. rotation
- No floating images
Installation
From Pypi
$ pip install pdf2docx
From source code
Clone or download this project, and navigate to the root directory:
$ python setup.py install
Or install it in developing mode:
$ python setup.py develop
Uninstall
$ pip uninstall pdf2docx
Usage
$ pdf2docx --help

NAME
    pdf2docx - Run the pdf2docx parser.

SYNOPSIS
    pdf2docx PDF_FILE <flags>

DESCRIPTION
    Run the pdf2docx parser.

POSITIONAL ARGUMENTS
    PDF_FILE
        PDF filename to read from

FLAGS
    --docx_file=DOCX_FILE
        DOCX filename to write to
    --start=START
        first page to process, starting from zero
    --end=END
        last page to process, starting from zero
    --pages=PAGES
        range of pages
    --multi_processing=MULTI_PROCESSING

NOTES
    You can also use flags syntax for POSITIONAL ARGUMENTS
By range of pages
$ pdf2docx test.pdf test.docx --start=5 --end=10
By page numbers
$ pdf2docx test.pdf test.docx --pages=5,7,9
Multi-Processing
$ pdf2docx test.pdf --multi_processing=True
As a library
''' With this library installed with
    `pip install pdf2docx`, or `python setup.py install`.
'''

from pdf2docx import parse

pdf_file = '/path/to/sample.pdf'
docx_file = 'path/to/sample.docx'

# convert pdf to docx
parse(pdf_file, docx_file, start=0, end=1)
Or just to extract tables,
from pdf2docx import extract_tables

pdf_file = '/path/to/sample.pdf'

tables = extract_tables(pdf_file, start=0, end=1)
for table in tables:
    print(table)

# outputs
...
[['Input ', None, None, None, None, None],
['Description A ', 'mm ', '30.34 ', '35.30 ', '19.30 ', '80.21 '],
['Description B ', '1.00 ', '5.95 ', '6.16 ', '16.48 ', '48.81 '],
['Description C ', '1.00 ', '0.98 ', '0.94 ', '1.03 ', '0.32 '],
['Description D ', 'kg ', '0.84 ', '0.53 ', '0.52 ', '0.33 '],
['Description E ', '1.00 ', '0.15 ', None, None, None],
['Description F ', '1.00 ', '0.86 ', '0.37 ', '0.78 ', '0.01 ']]
Sample
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
pdf2docx-0.4.5.tar.gz
(1.3 MB
view details)
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
pdf2docx-0.4.5-py3-none-any.whl
(93.5 kB
view details)
File details
Details for the file pdf2docx-0.4.5.tar.gz.
File metadata
- Download URL: pdf2docx-0.4.5.tar.gz
- Upload date:
- Size: 1.3 MB
- Tags: Source
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/3.2.0 pkginfo/1.5.0.1 requests/2.24.0 setuptools/50.3.0 requests-toolbelt/0.9.1 tqdm/4.50.0 CPython/3.8.6
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
d6a1675023d690eac935390ac017e98e804f8745095bb25777c4e7517f953d47
|
|
| MD5 |
58af7bd89e8e511520fff7af2b0240b8
|
|
| BLAKE2b-256 |
194f768e71bb75292a5cfbc244cb630ba3b5892e7e62f7fbd58aed702e557206
|
File details
Details for the file pdf2docx-0.4.5-py3-none-any.whl.
File metadata
- Download URL: pdf2docx-0.4.5-py3-none-any.whl
- Upload date:
- Size: 93.5 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/3.2.0 pkginfo/1.5.0.1 requests/2.24.0 setuptools/50.3.0 requests-toolbelt/0.9.1 tqdm/4.50.0 CPython/3.8.6
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
e1e2f6b9f3381627ceb92f01fff51c5f3ba68f919c5c4a8fe7eb4ea7c7b7fe5c
|
|
| MD5 |
a3bcbef0e0e167a9d3a409fbff5e4f2d
|
|
| BLAKE2b-256 |
718a6cda2cc797a955ac7f7e8337be862e5ab415e71eb9e9c44789ab6f9cdf68
|














