
PSPSO 1.0
PSPSO is a modern local framework for reproducible tabular machine-learning experiments and hyperparameter optimization. Particle swarm optimization is the primary search engine, with random and grid search available as comparison baselines.
Version 1.0 provides one typed contract across:
- a notebook-friendly Python API;
- a React dashboard backed by FastAPI;
- a local experiment and artifact store;
- a managed subprocess worker;
- a CLI for datasets, experiments, and runs.
Haidar A, Field M, Sykes J, Carolan M, Holloway L. PSPSO: A package for parameters selection using particle swarm optimization. SoftwareX. 2021; 15:100706.
Dashboard Snapshots
Overview
Data Setup and Evaluation
Experiment Results
Dashboard Workflow
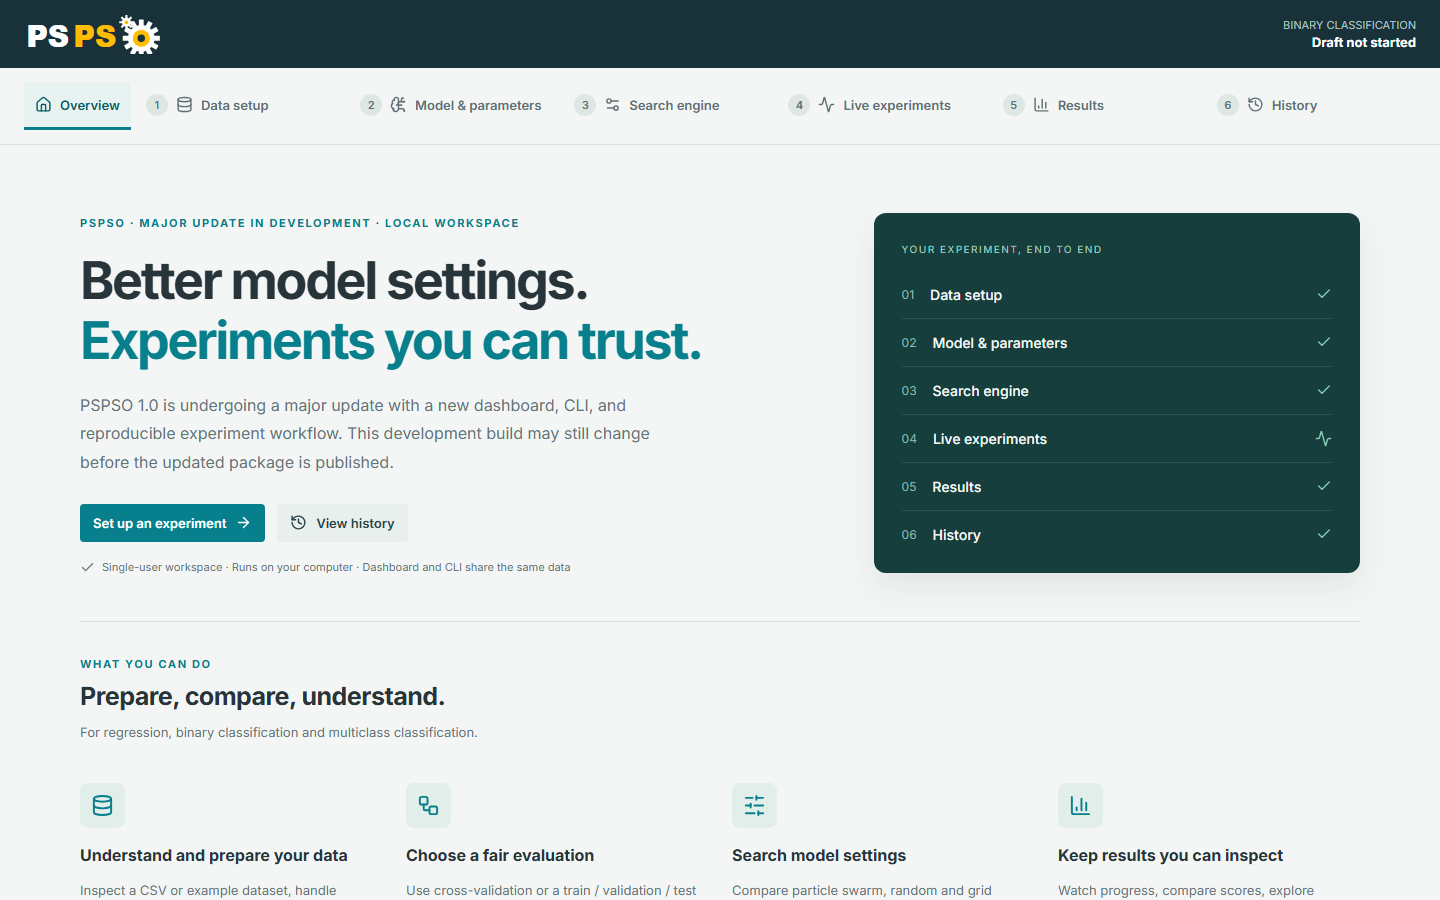
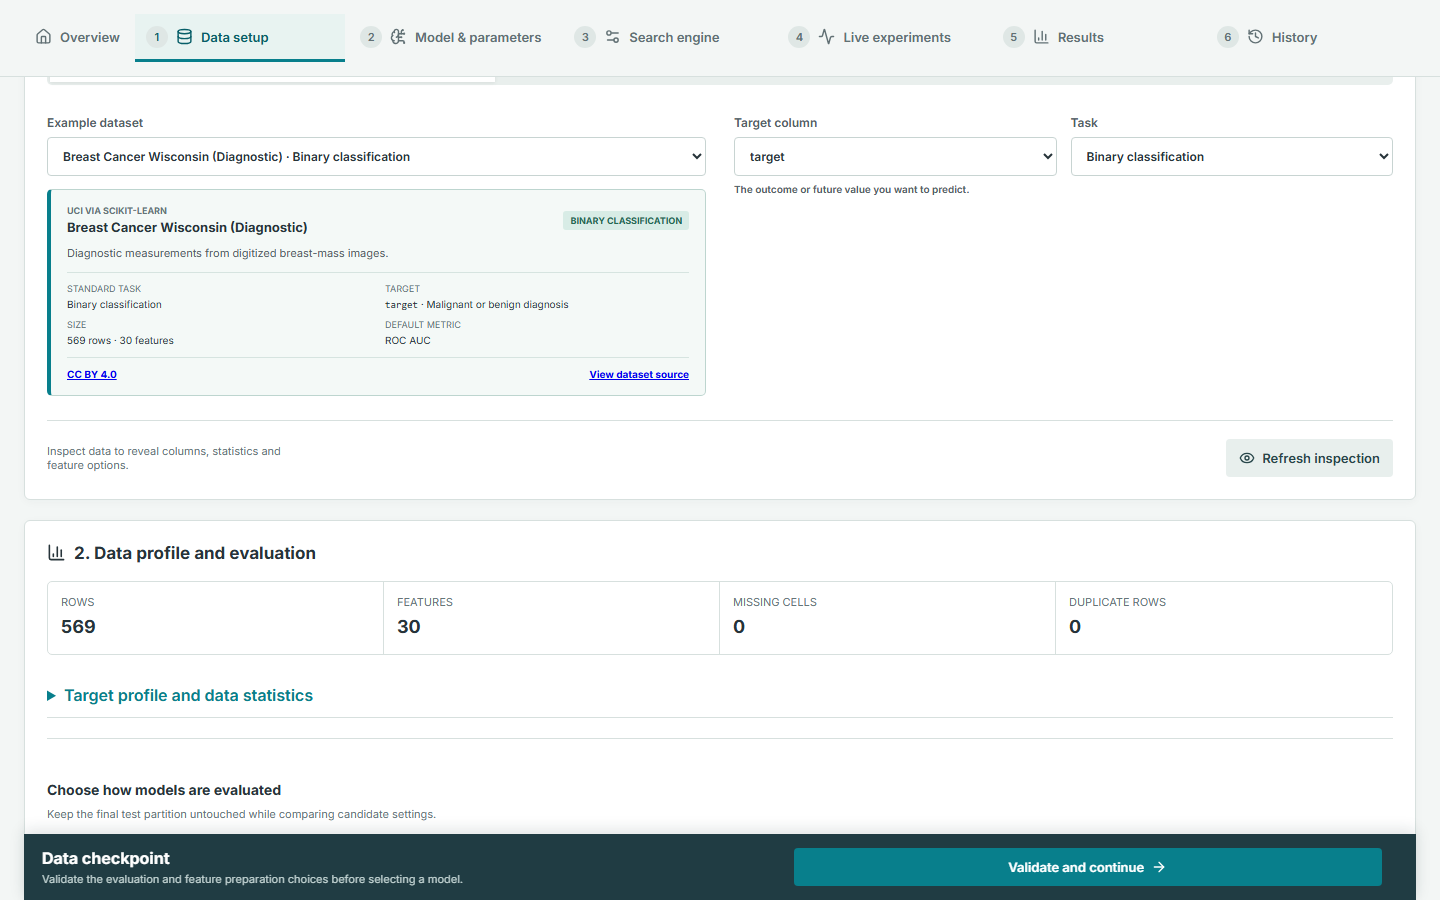
The dashboard opens with an overview of its capabilities. Data Setup contains three sections for dataset selection, profile/evaluation, and feature engineering. Choose cross-validation or train/validation/test, keep chronological order for time series, and configure missing values, outlier clipping and categorical encoding.
The interface is organized into six stages:
- Data Setup inspects values, types, missingness, duplicates, target distribution, descriptive statistics, and split composition.
- Model & Parameters presents compatible models and separates fixed training settings from tunable domains.
- Search Engine configures PSO, random, or grid search and calculates the expected model-fit budget.
- Live Experiments shows worker activity, particles or candidates, metrics, failures, logs, and the persisted event timeline.
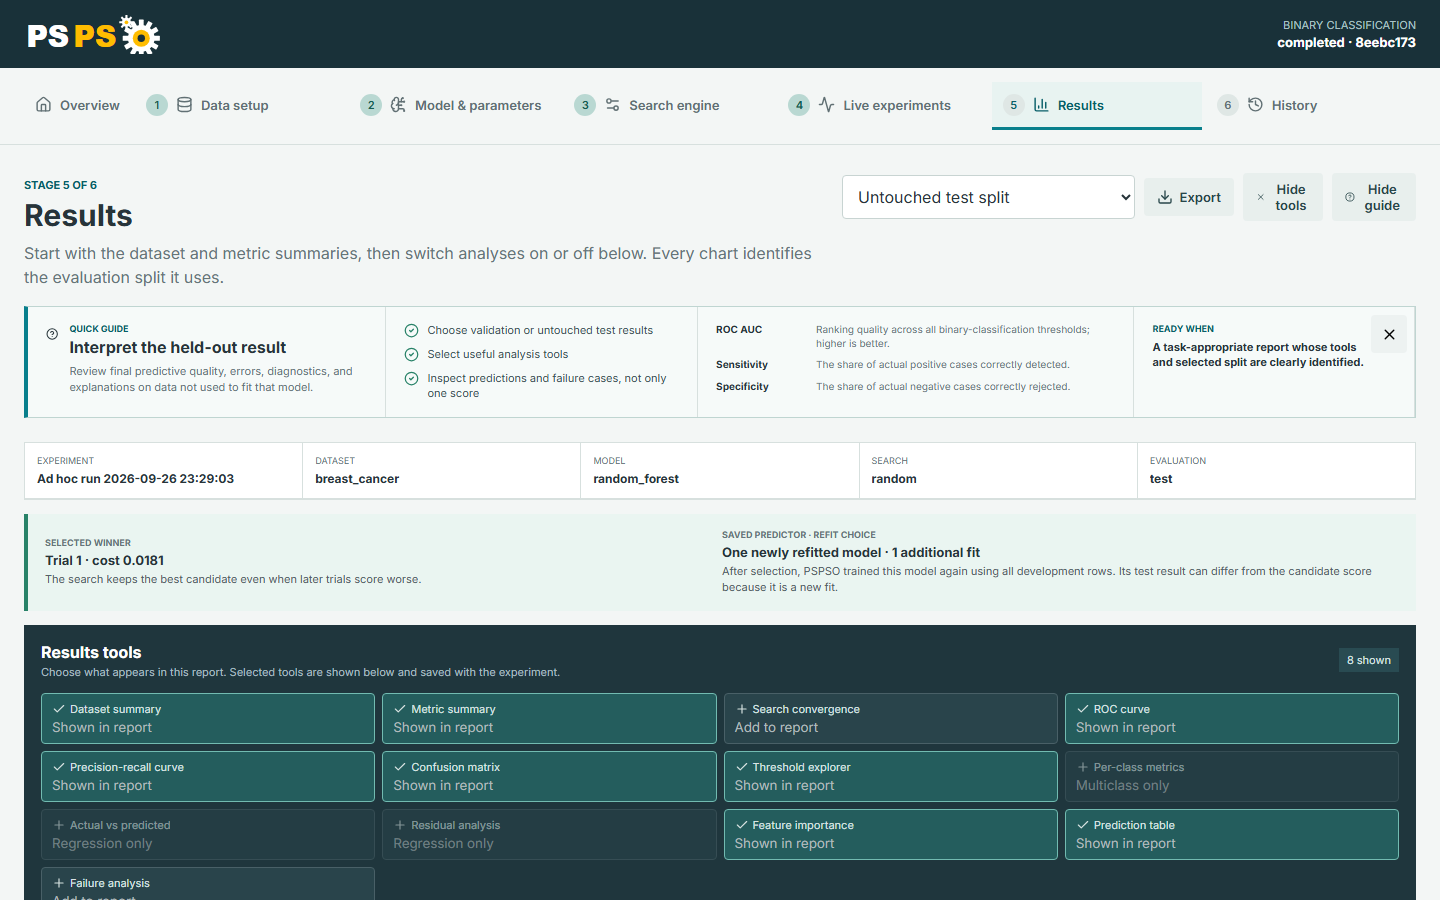
- Results provides task-specific diagnostics, predictions, dataset summaries, and feature importance where available.
- History combines dashboard, CLI, and tracked notebook runs.
Each stage includes a quick guide, checklist, glossary, and contextual field help.
Installation
Python 3.10 through 3.12 is supported. Install PSPSO from PyPI to get the dashboard, CLI and Python API together. Node.js is only needed for frontend development.
With uv, install the dashboard and CLI as a tool:
uv tool install pspso
This installs PSPSO from PyPI and makes pspso and pspso-dashboard
available as commands. To use the Python API in an existing uv project, add
PSPSO as a project dependency:
uv add pspso
With pip, use your current Python environment:
python -m pip install --upgrade pspso
Optional model engines can be included when installing the uv tool. Choose the extras you need in one command:
uv tool install "pspso[xgboost]"
uv tool install "pspso[xgboost,lightgbm,torch]"
For an existing uv project, use uv add "pspso[xgboost]" or combine the
extras in the same way.
With pip:
python -m pip install --upgrade "pspso[xgboost]"
python -m pip install --upgrade "pspso[lightgbm]"
python -m pip install --upgrade "pspso[torch]"
Contributors working from the repository should follow the source setup.
Start the Dashboard
After installing with either uv or pip:
pspso-dashboard
Open the dashboard. The installed package serves the interface directly. API documentation is available at API v1 docs. The browser submits managed jobs; it does not open a machine terminal or execute arbitrary Python.
Dashboard defaults use five-fold CV, per-fold preprocessing, a final refit on all development rows and one untouched test partition. Exact datasets, partition and fold indices, models, environments and seeds are saved. Candidate concurrency is bounded, and progress reports actual fit totals and worker slots. If the additional refit is disabled, PSPSO saves the winning candidate's fold models as an ensemble and averages them for predictions.
The long-lived service owns the durable queue. CLI start, cancel and retry use
that same service. Queued work survives a restart; interrupted attempts remain
historical. For foreground execution without HTTP, use
pspso run start SPEC --standalone --wait. The compatible api extra remains
accepted, but service dependencies are included in the base package.
See evaluation, CLI, architecture and the release completion record for details and verification.
Notebook API
Use optimize() for concise, in-process work:
from sklearn.datasets import load_diabetes
from pspso import IntRange, OptimizationConfig, SearchSpace, optimize

X, y = load_diabetes(return_X_y=True)
space = SearchSpace({
    "n_estimators": IntRange(20, 80),
    "max_depth": IntRange(2, 10),
})
config = OptimizationConfig(
    task="regression",
    metric="rmse",
    strategy="pso",
    n_particles=4,
    n_iterations=3,
    random_state=42,
)
result = optimize(
    X,
    y,
    estimator="random_forest",
    search_space=space,
    config=config,
)

print(result.summary())
display(result.trials_frame())
predictions = result.predict(X[:5])
PSPSOOptimizer remains available when the optimizer instance itself is needed.
OptimizationResult provides the best model and parameters, trials, failures,
duration, prediction, probability, evaluation, tabular, and notebook-display
helpers.
Optional Notebook Tracking
Notebook runs do not write to disk by default. Supply TrackingConfig to record
one in the same experiment history used by the dashboard and CLI:
from pspso import TrackingConfig

result = optimize(
    X,
    y,
    estimator="random_forest",
    search_space=space,
    config=config,
    tracking=TrackingConfig(
        experiment_name="Diabetes study",
        run_name="Notebook PSO",
        tags=("notebook",),
        snapshot_data=True,
    ),
)
Tracked notebook calls do not require FastAPI.
Typed Search Spaces
Version 1.0 accepts explicit domains only:
from pspso import Choice, FloatRange, IntRange, LogFloatRange, SearchSpace

space = SearchSpace({
    "kernel": Choice(["linear", "rbf"]),
    "max_depth": IntRange(2, 12),
    "subsample": FloatRange(0.7, 1.0, precision=2),
    "learning_rate": LogFloatRange(0.001, 0.3, precision=5),
})
Use space.decode(), space.encode(), space.iter_grid(), space.grid_size,
and space.to_schema() for optimizer and API representations.
Models and Metrics
Built-in canonical model IDs are:
linear_regression,logistic_regression, andelastic_net;random_forest,extra_trees, andhist_gradient_boosting;svmandsklearn_mlp;- optional
xgboost,lightgbm, andpytorch_mlp.
Use list_estimators() and get_estimator_info() to inspect task support,
dependencies, capabilities, defaults, and typed search spaces.
Canonical tasks are regression, binary_classification, and
multiclass_classification. Supported metrics include RMSE, MAE, R2, accuracy,
ROC AUC, PR AUC, log loss, and macro F1. Classification diagnostics include
sensitivity, specificity, confusion matrices, and threshold analysis.
Data Preparation
Built-in examples include Breast Cancer, Diabetes, Wine Recognition, Banknote Authentication, Auto MPG, and Palmer Penguins. Each shows its source, license, standard task, target, and default metric; selecting it applies those defaults. The external examples are packaged for offline use. CSV files can also be inspected directly or saved as fingerprinted local dataset versions.
Numeric and categorical imputation, missingness indicators, categorical encoding, scaling, ignored columns, stratification, and deterministic split seeds are configurable. Transformers are fitted on training rows only to avoid validation and test leakage.
CLI
The CLI consumes the same ExperimentSpec as the dashboard. Save the complete
example from the CLI guide as
experiment.json, then run
these commands in a second terminal while the dashboard service is running.
If PSPSO is a dependency of an existing uv project instead of an installed tool,
prefix commands with uv run.
pspso --help
pspso run validate experiment.json
pspso run start experiment.json --wait
pspso run list
pspso run show <run_id>
pspso run cancel <run_id>
pspso run retry <run_id>
Experiments and Storage
Version 1.0 uses an isolated workspace:
.pspso/v1/
  tracking.sqlite3
  datasets/
  artifacts/runs/<run_id>/
Set PSPSO_HOME to relocate the workspace root. Pre-1.0 files under .pspso/
are not read, displayed, migrated, or deleted.
SQLite stores experiments, runs, attempts, summaries, and ordered events. Artifact directories store specifications, results, analysis, environment details, and serializable models and preprocessors.
REST API and Monitoring
The supported API is versioned under /api/v1. Important endpoints include:
GET  /api/v1/estimators
GET  /api/v1/datasets
POST /api/v1/datasets/inspect
POST /api/v1/workflow/validate
POST /api/v1/runs
GET  /api/v1/runs/{run_id}
GET  /api/v1/runs/{run_id}/events
GET  /api/v1/runs/{run_id}/history
GET  /api/v1/runs/{run_id}/analysis
GET  /api/v1/runs/{run_id}/predictions
POST /api/v1/runs/{run_id}/cancel
POST /api/v1/runs/{run_id}/retry
OpenAPI is served at /api/v1/docs and /api/v1/openapi.json. Live progress
uses Server-Sent Events with polling and persisted-history recovery.
Security
The dashboard is a local application without built-in user accounts or API
authentication. It binds to 127.0.0.1 by default for normal single-user use.
Other bind addresses, including 0.0.0.0, remain available and produce a clear
warning. Keep the workspace and exported model files trusted: model artifacts
use Python's ML serialization formats and should not be loaded after modification
by an untrusted party. See SECURITY.md for supported versions and
private vulnerability reporting.
Tests and Documentation
uv run pytest
cd frontend && npm run build
uv run mkdocs build --strict
uv build
These checks run from a development checkout.
Run the documentation alongside the dashboard with
uv run --no-sync mkdocs serve --dev-addr 127.0.0.1:8001. The detailed guides
cover notebooks, the CLI, dashboard workflow, data preparation, search
strategies, model recipes, REST/SSE contracts, tracking, architecture, and the
0.2 to 1.0 migration.
1 maintainer

Metadata
1 maintainer
Release files for pspso 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| pspso-1.0.0.tar.gz | 1.4 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pspso-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.8 MB
Release files / pspso-1.0.0.tar.gz
| Download URL | pspso-1.0.0.tar.gz |
|---|---|
| Size | 1.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f38bedf3dbcadfc00fad44c11957f3fd801459d9c9d2e0d56dc20cd45ec5e7e5
|
|
BLAKE2b-256 checksum How to use checksums |
6d8b45f11a9bacf2905a98e72bbb9b6455918208a733247c0b265ef741e30356
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency logRelease files / pspso-1.0.0-py3-none-any.whl
| Download URL | pspso-1.0.0-py3-none-any.whl |
|---|---|
| Size | 445.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
49df6b8cf407e7ac70670f9ccd1371092a817a040f79e6aad6af36871f9420b9
|
|
BLAKE2b-256 checksum How to use checksums |
1b583fb3819d326426cff95db2cae10b66da58ffe84aafab4b7c9ffd79c8bef9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency log













