
Python Web Crawler 
A web crawler written in Python to crawl a given website.
Features!
- Faster
- Ablility to specify the number of threads to use to crawl the given website
- Ability to use proxies to bypass IP restrictions
- Clear summary of all the urls that were crawled. View the crawled.txt file to see the complete list of all the links crawled
- Ability to specify delay between each HTTP Request
- Stop and resume crawler whenever you need
- Gather all the urls with their titles to a csv, incase if you are planning to create a search engine
- Search for specific text throughout the website
- Clear statistics about how many links ended up as Files,Timeout Errors,Connecrion Errors
- Crawl until you need. You can specify upto what level the crawler should crawl.
- Random browser user agents will be used while crawling.
Upcoming Features!
- Gather AWS Buckets,Emails,Phone Numbers etc
- Download all images
Dependencies
This tool uses a number of open source projects to work properly:
- BeautifulSoup - Parser to parse the HTML response of each request made.
- Requests - To make GET requests to the URLs.
Usage
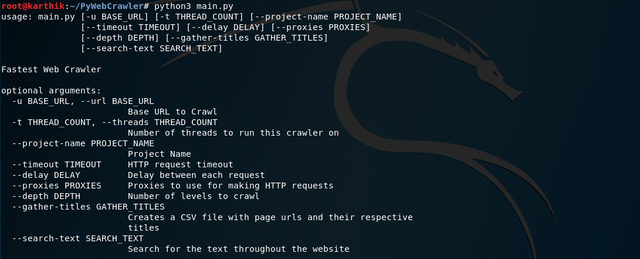
If you like to see the list of supported features, simply run
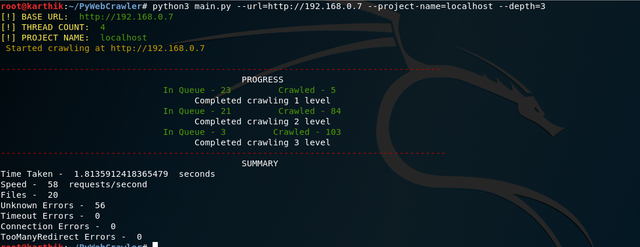
Specifying only to crawl for 3 levels
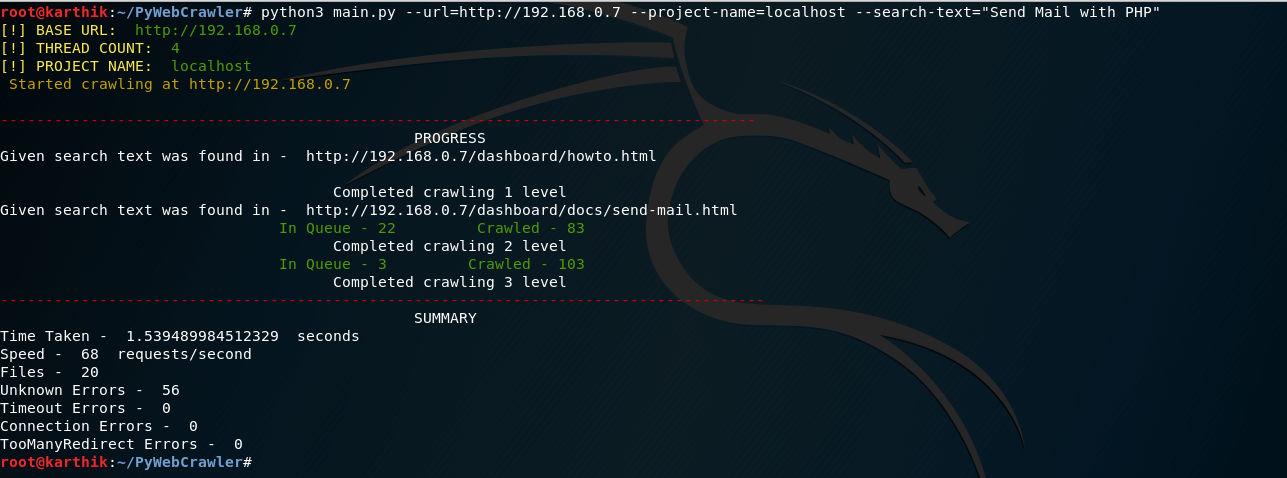
Search for specific text throughout the website
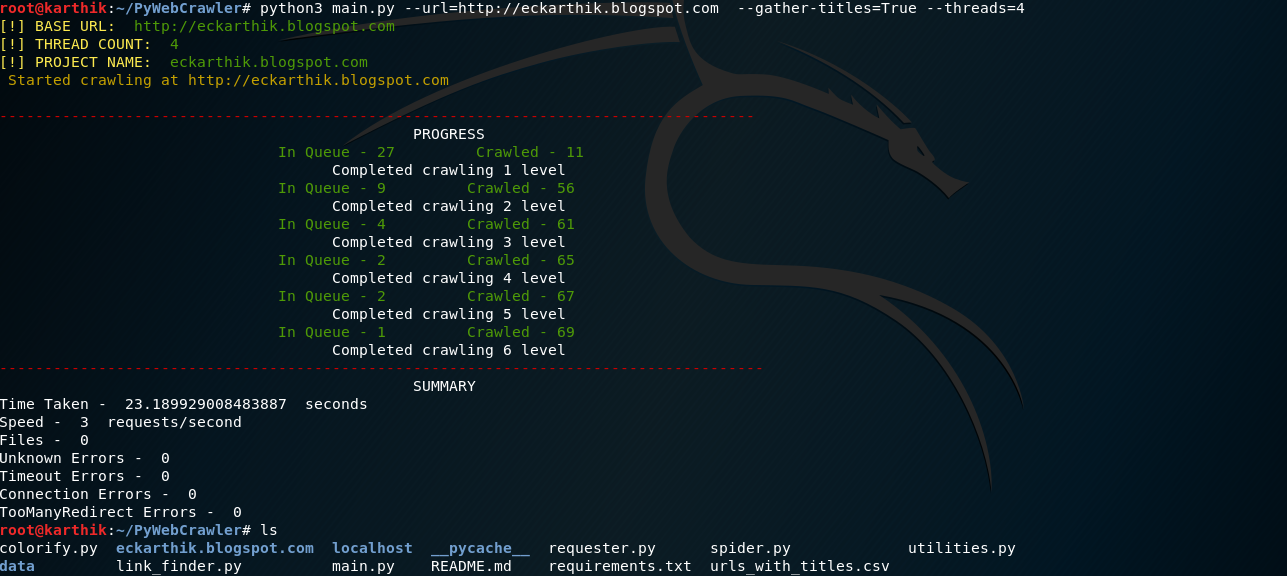
Gather all the links along with their titles to a CSV file. A CSV file with the links and their titles will be created after the crawl completes
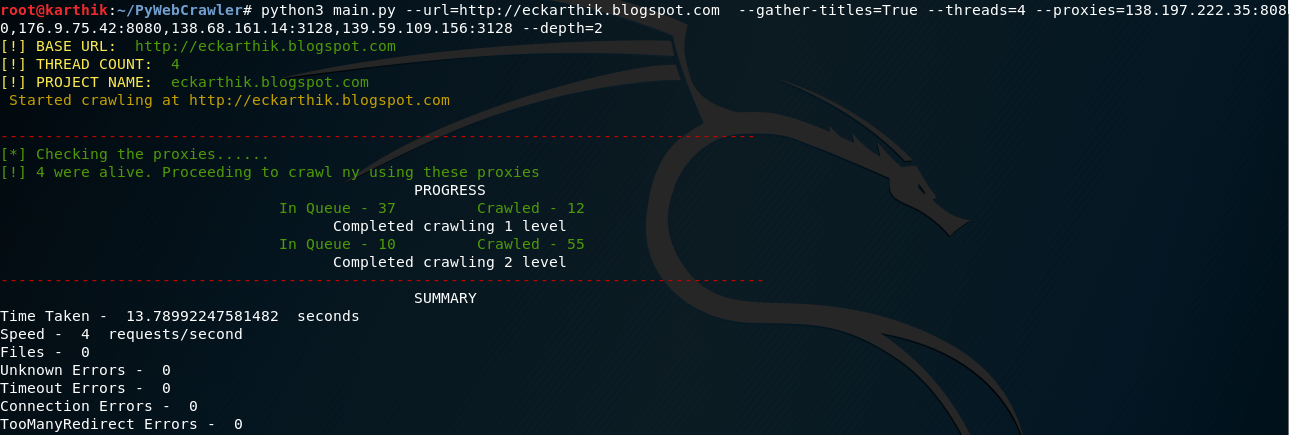
Use proxies to crawl the site.
1 maintainer

Metadata
1 maintainer
Release files for pywebcrawler 0.0.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| pywebcrawler-0.0.1.tar.gz | 8.2 kB | Without provenance | Details for pywebcrawler-0.0.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| pywebcrawler-0.0.1-py3-none-any.whl | Python 3 | none | any | Details for pywebcrawler-0.0.1-py3-none-any.whl |
Total release size: 25.5 kB
Release files / pywebcrawler-0.0.1.tar.gz
| Download URL | pywebcrawler-0.0.1.tar.gz |
|---|---|
| Size | 8.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8746bb0d60b12be062757375718a4fd96d58619f1edcaddc8c5ac4ee67223e01
|
|
BLAKE2b-256 checksum How to use checksums |
7810a5debfdd4e9c6949fca4233e152fb3d5dbe9a52eb6c3918978c6919517d1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.1.1 pkginfo/1.5.0.1 requests/2.22.0 setuptools/45.0.0 requests-toolbelt/0.9.1 tqdm/4.41.1 CPython/3.7.5
|
Release files / pywebcrawler-0.0.1-py3-none-any.whl
| Download URL | pywebcrawler-0.0.1-py3-none-any.whl |
|---|---|
| Size | 17.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9decb290e655c1bd8b851cdf95556162c8285bb404b459dabada1f0ac8c70d2a
|
|
BLAKE2b-256 checksum How to use checksums |
3138877e41e197bf1aec6a73533b0fb7ae326ec5decf7a3d7ce4b6ad577070de
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.1.1 pkginfo/1.5.0.1 requests/2.22.0 setuptools/45.0.0 requests-toolbelt/0.9.1 tqdm/4.41.1 CPython/3.7.5
|
Security for pywebcrawler 0.0.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













