
rtmlib
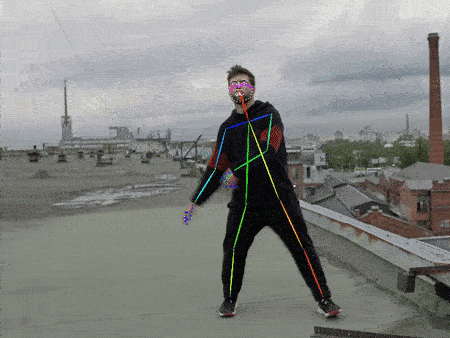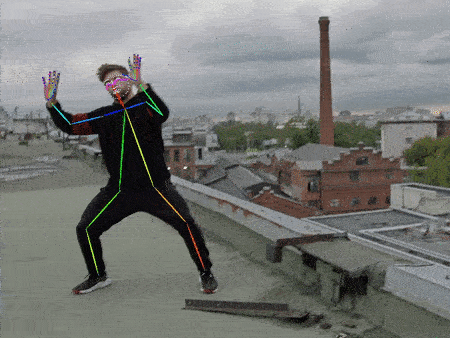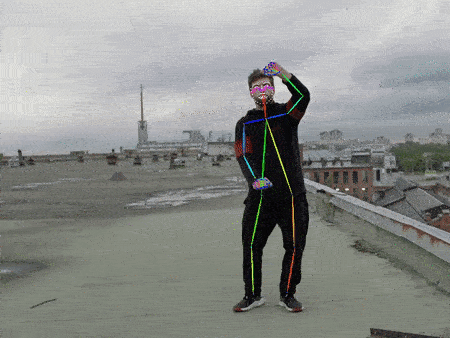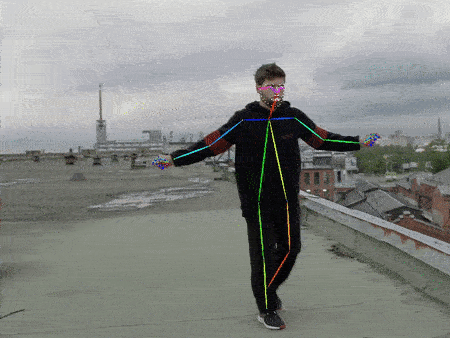
rtmlib is a super lightweight library to conduct human and animal pose estimation based on RTMPose and ViTPose models WITHOUT any dependencies like mmcv, mmpose, mmdet, etc.
Basically, rtmlib only requires these dependencies:
- numpy
- opencv-python
- opencv-contrib-python
- onnxruntime
Optionally, you can use other common backends like opencv, onnxruntime, openvino, tensorrt to accelerate the inference process.
- For openvino users, please add the path
<your python path>\envs\<your env name>\Lib\site-packages\openvino\libsinto your environment path.
Contents
Installation
- install from pypi:
pip install rtmlib -i https://pypi.org/simple
- install from source code:
git clone https://github.com/Tau-J/rtmlib.git
cd rtmlib

pip install -r requirements.txt

pip install -e .

# [optional]
# pip install onnxruntime-gpu
# pip install openvino
Quick Start
Here is a simple demo to show how to use rtmlib to conduct pose estimation on a single image.
import cv2
from rtmlib import Wholebody, draw_skeleton

img = cv2.imread('./demo.jpg')

device = 'cpu'  # cpu, cuda, mps
backend = 'onnxruntime'  # opencv, onnxruntime, openvino
openpose_skeleton = False  # True for openpose-style (required for animals), False for mmpose-style

wholebody = Wholebody(to_openpose=openpose_skeleton,
                      mode='balanced',  # 'performance', 'lightweight', 'balanced'. Default: 'balanced'
                      backend=backend, device=device)
keypoints, scores = wholebody(img)

# visualize
# if you want to use black background instead of original image,
# img = np.zeros(img.shape, dtype=np.uint8)
img = draw_skeleton(img, keypoints, scores, kpt_thr=0.5, to_openpose=openpose_skeleton)
cv2.imshow('img', img)
cv2.waitKey(0)
Or on a webcam stream or a video file.
from rtmlib import Body, Custom, PoseTracker, draw_skeleton
import cv2

cap = cv2.VideoCapture(0)  # for video file instead of webcam, use cap = cv2.VideoCapture('./demo.mp4')

device = 'cpu'
backend = 'onnxruntime'
openpose_skeleton = False

pose_tracker = PoseTracker(Body,
                        mode='balanced',
                        det_frequency=10,  # detect every 10 frames
                        backend=backend, device=device,
                        to_openpose=False)

# # Or with a custom class
# from functools import partial
# custom = partial(Custom,
#                 det_class='YOLOX',
#                 det='https://download.openmmlab.com/mmpose/v1/projects/rtmposev1/onnx_sdk/yolox_m_8xb8-300e_humanart-c2c7a14a.zip',
#                 det_input_size=(640, 640),
#                 pose_class='RTMPose',
#                 pose='https://download.openmmlab.com/mmpose/v1/projects/rtmposev1/onnx_sdk/rtmpose-m_simcc-body7_pt-body7-halpe26_700e-256x192-4d3e73dd_20230605.zip',
#                 pose_input_size=(192, 256))
# pose_tracker = PoseTracker(custom,
#                         det_frequency=10,
#                         backend=backend, device=device,
#                         to_openpose=False)

frame_idx = 0
while cap.isOpened():
    success, frame = cap.read()
    frame_idx += 1
    if not success:
        break

    keypoints, scores = pose_tracker(frame)

    img_show = frame.copy()
    img_show = draw_skeleton(img_show,
                             keypoints,
                             scores,
                             openpose_skeleton=openpose_skeleton,
                             kpt_thr=0.43)
    cv2.imshow('img', img_show)
    cv2.waitKey(10)
Usage
WebUI
Run webui.py:
# Please make sure you have installed gradio
# pip install gradio

python webui.py

APIs
- Solutions (High-level APIs)
- PoseTracker
- Wholebody
- Body
- Body_with_feet
- Hand
- Animal (bird, cat, dog, horse, sheep, cow, elephant, bear, zebra, giraffe)
- Custom
- Wholebody3d
- Detectors (Low-level APIs)
- Pose Estimators (Low-level APIs)
- RTMPose
- RTMPose for 17 keypoints
- RTMO for 17 keypoints (one-stage)
- RTMPose for 21 keypoints (hand)
- RTMPose for 26 keypoints
- RTMW for 133 keypoints
- DWPose for 133 keypoints
- RTMW3D for 133 keypoints (3D)
- ViTPose
- ViTPose for 17 keypoints
- ViTPose for 17 keypoints (animal)
- ViTPose for 25 keypoints
- ViTPose for 133 keypoints
- RTMPose
- Visualization
For high-level APIs (Solution), you can choose to pass mode or det+pose arguments to specify the detector and pose estimator you want to use.
# By mode
from rtmlib import Wholebody
wholebody = Wholebody(mode='performance',  # 'performance', 'lightweight', 'balanced'. Default: 'balanced'
                      backend=backend,
                      device=device)

# By det and pose
from rtmlib import Body
body = Body(det='https://download.openmmlab.com/mmpose/v1/projects/rtmposev1/onnx_sdk/yolox_x_8xb8-300e_humanart-a39d44ed.zip',
            det_input_size=(640, 640),
            pose='https://download.openmmlab.com/mmpose/v1/projects/rtmposev1/onnx_sdk/rtmpose-x_simcc-body7_pt-body7_700e-384x288-71d7b7e9_20230629.zip',
            pose_input_size=(288, 384),
            backend=backend,
            device=device)

# By det and pose with custom classes
from rtmlib import Custom
# Human pose estimation using YOLOX and RTMPose
custom = Custom(det_class='YOLOX',
               det='https://download.openmmlab.com/mmpose/v1/projects/rtmposev1/onnx_sdk/yolox_m_8xb8-300e_humanart-c2c7a14a.ip',
               det_input_size=(640, 640),
               pose_class='RTMPose',
               pose='https://download.openmmlab.com/mmpose/v1/projects/rtmposev1/onnx_sdk/rtmpose-m_simcc-body7_pt-body7_420e-256x192-e48f03d0_20230504.zip',
               pose_input_size=(192, 256),
               backend=backend,
               device=device)

# Human and animal pose estimation using YOLOX in multiclass mode and ViTPose
# Requires openpose_skeleton = True in draw_skeleton for visualization
custom = Custom(det_class='YOLOX',
               det_mode='multiclass', # or det_categories=[0,23] (for example)
               det='https://github.com/Megvii-BaseDetection/YOLOX/releases/download/0.1.1rc0/yolox_s.onnx',
               det_input_size=(640, 640),
               pose_class='ViTPose',
               pose='https://huggingface.co/JunkyByte/easy_ViTPose/resolve/main/onnx/apt36k/vitpose-b-apt36k.onnx',
               pose_input_size=(192, 256),
               backend=backend,
               device=device)
For low-level APIs (Model), you can specify the model you want to use by passing the onnx_model argument.
# By onnx_model (.onnx or .zip) by download link or local path
# YOLOX human detector
det_model = YOLOX(onnx_model='https://download.openmmlab.com/mmpose/v1/projects/rtmposev1/onnx_sdk/yolox_s_8xb8-300e_humanart-3ef259a7.zip',
                     backend=backend, device=device)

# YOLOX multiclass detector
det_model = YOLOX('https://github.com/Megvii-BaseDetection/YOLOX/releases/download/0.1.1rc0/yolox_s.onnx',
                     det_mode='multiclass', # or det_categories=[0,1,etc] if you want specific COCO_CLASSES IDs
                     backend=backend, device=device)

# RTMPose pose estimator
pose_model = RTMPose(onnx_model='https://download.openmmlab.com/mmpose/v1/projects/rtmposev1/onnx_sdk/rtmpose-m_simcc-body7_pt-body7_420e-256x192-e48f03d0_20230504.zip',
                     backend=backend, device=device)

# ViTPose pose estimator
pose_model = ViTPose(onnx_model='https://huggingface.co/JunkyByte/easy_ViTPose/resolve/main/onnx/apt36k/vitpose-b-apt36k.onnx',
                     backend=backend, device=device)
Model Zoo
By defaults, rtmlib will automatically download and apply models with the best performance.
More models can be found in RTMPose and ViTPose Model Zoos for pose estimation, and YOLOX for multiclass detection.
All checkpoints hosted on download.openmmlab.com are also mirrored at huggingface.co/Tau-J/RTMPose. If the original OpenMMLab download server is ever unreachable, rtmlib will automatically retry the download from this mirror -- no extra configuration is needed.
Detectors
Person
Notes:
- Models trained on HumanArt can detect both real human and cartoon characters.
- Models trained on COCO can only detect real human.
| ONNX Model | Input Size | AP (person) | Description |
|---|---|---|---|
| YOLOX-l | 640x640 | - | trained on COCO |
| YOLOX-nano | 416x416 | 38.9 | trained on HumanArt+COCO |
| YOLOX-tiny | 416x416 | 47.7 | trained on HumanArt+COCO |
| YOLOX-s | 640x640 | 54.6 | trained on HumanArt+COCO |
| YOLOX-m | 640x640 | 59.1 | trained on HumanArt+COCO |
| YOLOX-l | 640x640 | 60.2 | trained on HumanArt+COCO |
| YOLOX-x | 640x640 | 61.3 | trained on HumanArt+COCO |
Hand
| ONNX Model | Input Size | AP (hand) | Description |
|---|---|---|---|
| RTMDet-nano | 320x320 | 76.0 | trained on 5 datasets |
Multi-class
COCO_CLASSES = [
    'person', 'bicycle', 'car', 'motorcycle', 'airplane', 'bus', 'train', 'truck', 'boat', 'traffic light',
    'fire hydrant', 'stop sign', 'parking meter', 'bench', 'bird', 'cat', 'dog', 'horse', 'sheep', 'cow',
    'elephant', 'bear', 'zebra', 'giraffe', 'backpack', 'umbrella', 'handbag', 'tie', 'suitcase', 'frisbee',
    'skis', 'snowboard', 'sports ball', 'kite', 'baseball bat', 'baseball glove', 'skateboard', 'surfboard',
    'tennis racket', 'bottle', 'wine glass', 'cup', 'fork', 'knife', 'spoon', 'bowl', 'banana', 'apple',
    'sandwich', 'orange', 'broccoli', 'carrot', 'hot dog', 'pizza', 'donut', 'cake', 'chair', 'couch',
    'potted plant', 'bed', 'dining table', 'toilet', 'tv', 'laptop', 'mouse', 'remote', 'keyboard',
    'cell phone', 'microwave', 'oven', 'toaster', 'sink', 'refrigerator', 'book', 'clock', 'vase',
    'scissors', 'teddy bear', 'hair drier', 'toothbrush']
| ONNX Model | Input Size | AP (COCO classes) | Description |
|---|---|---|---|
| YOLOX-nano | 416x416 | 25.8 | trained on coco |
| YOLOX-t | 416x416 | 32.8 | trained on coco |
| YOLOX-s | 640x640 | 40.5 | trained on coco |
| YOLOX-m | 640x640 | 47.2 | trained on coco |
| YOLOX-l | 640x640 | 50.1 | trained on coco |
| YOLOX-Darknet53 | 640x640 | 48.0 | trained on coco |
| YOLOX-X | 640x640 | 51.5 | trained on coco |
Pose Estimators
Body 17 Keypoints
| ONNX Model | Input Size | AP (COCO) | Description |
|---|---|---|---|
| RTMPose-t | 256x192 | 65.9 | trained on 7 datasets |
| RTMPose-s | 256x192 | 69.7 | trained on 7 datasets |
| RTMPose-m | 256x192 | 74.9 | trained on 7 datasets |
| RTMPose-l | 256x192 | 76.7 | trained on 7 datasets |
| RTMPose-l | 384x288 | 78.3 | trained on 7 datasets |
| RTMPose-x | 384x288 | 78.8 | trained on 7 datasets |
| RTMO-s | 640x640 | 68.6 | trained on 7 datasets |
| RTMO-m | 640x640 | 72.6 | trained on 7 datasets |
| RTMO-l | 640x640 | 74.8 | trained on 7 datasets |
| ViTPose++-s | 256x192 | 75.8 | trained on 6 datasets |
| ViTPose++-b | 256x192 | 77.0 | trained on 6 datasets |
| ViTPose++-l | 256x192 | 78.6 | trained on 6 datasets |
Body 25 Keypoints
| ONNX Model | Input Size | AP (COCO) | Description |
|---|---|---|---|
| ViTPose-s | 256x192 | - | fine-tuned on COCO+feet |
| ViTPose-b | 256x192 | - | fine-tuned on COCO+feet |
| ViTPose-l | 256x192 | - | fine-tuned on COCO+feet |
Body 26 Keypoints
| ONNX Model | Input Size | AP (Body8) | Description |
|---|---|---|---|
| RTMPose-t | 256x192 | 68.0 | trained on 7 datasets |
| RTMPose-s | 256x192 | 72.0 | trained on 7 datasets |
| RTMPose-m | 256x192 | 76.7 | trained on 7 datasets |
| RTMPose-l | 256x192 | 78.4 | trained on 7 datasets |
| RTMPose-x* | 384x288 | 80.0 | trained on 7 datasets |
WholeBody 133 Keypoints
| ONNX Model | Input Size | AP (Whole) | Description |
|---|---|---|---|
| ViTPose++-s | 256x192 | 54.4 | trained on 6 datasets |
| ViTPose++-b | 256x192 | 57.4 | trained on 6 datasets |
| ViTPose++-l | 256x192 | 60.6 | trained on 6 datasets |
| DWPose-t | 256x192 | 48.5 | trained on COCO-Wholebody+UBody |
| DWPose-s | 256x192 | 53.8 | trained on COCO-Wholebody+UBody |
| DWPose-m | 256x192 | 60.6 | trained on COCO-Wholebody+UBody |
| DWPose-l | 256x192 | 63.1 | trained on COCO-Wholebody+UBody |
| DWPose-l | 384x288 | 66.5 | trained on COCO-Wholebody+UBody |
| RTMW-m | 256x192 | 58.2 | trained on 14 datasets |
| RTMW-l | 256x192 | 66.0 | trained on 14 datasets |
| RTMW-l* | 384x288 | 70.1 | trained on 14 datasets |
| RTMW-x* | 384x288 | 70.2 | trained on 14 datasets |
WholeBody 133 Keypoints
| ONNX Model | Input Size | AP (Whole) | Description |
|---|---|---|---|
| RTMW3D-x | 384x288 | 68.0 | trained on COCO-Wholebody |
Hand
| ONNX Model | Input Size | AUC (Hand56) | Description |
|---|---|---|---|
| RTMPose-m* | 256x256 | 83.9 | trained on 5 datasets |
Face
| ONNX Model | Input Size | AP (Face6) | Description |
|---|---|---|---|
| RTMPose-t* | 256x256 | - | trained on 6 datasets |
| RTMPose-s* | 256x256 | - | trained on 6 datasets |
| RTMPose-m* | 256x256 | - | trained on 6 datasets |
Animal
CATEGORIES = ['gorilla', 'spider-monkey', 'howling-monkey', 'zebra', 'elephant', 'hippo', 'raccon', 'rhino', 'giraffe', 'tiger', 'deer', 'lion', 'panda', 'cheetah', 'black-bear', 'polar-bear', 'antelope', 'fox', 'buffalo', 'cow', 'wolf', 'dog', 'sheep', 'cat', 'horse', 'rabbit', 'pig', 'chimpanzee', 'monkey', 'orangutan']
| ONNX Model | Input Size | AP (AP10K) | Description |
|---|---|---|---|
| RTMPose-m | 256x256 | 72.2 | trained on AP-10K |
| ViTPose++-s | 256x192 | 74.2 | trained on 6 datasets |
| ViTPose++-b | 256x192 | 75.9 | trained on 6 datasets |
| ViTPose++-l | 256x192 | 80.8 | trained on 6 datasets |
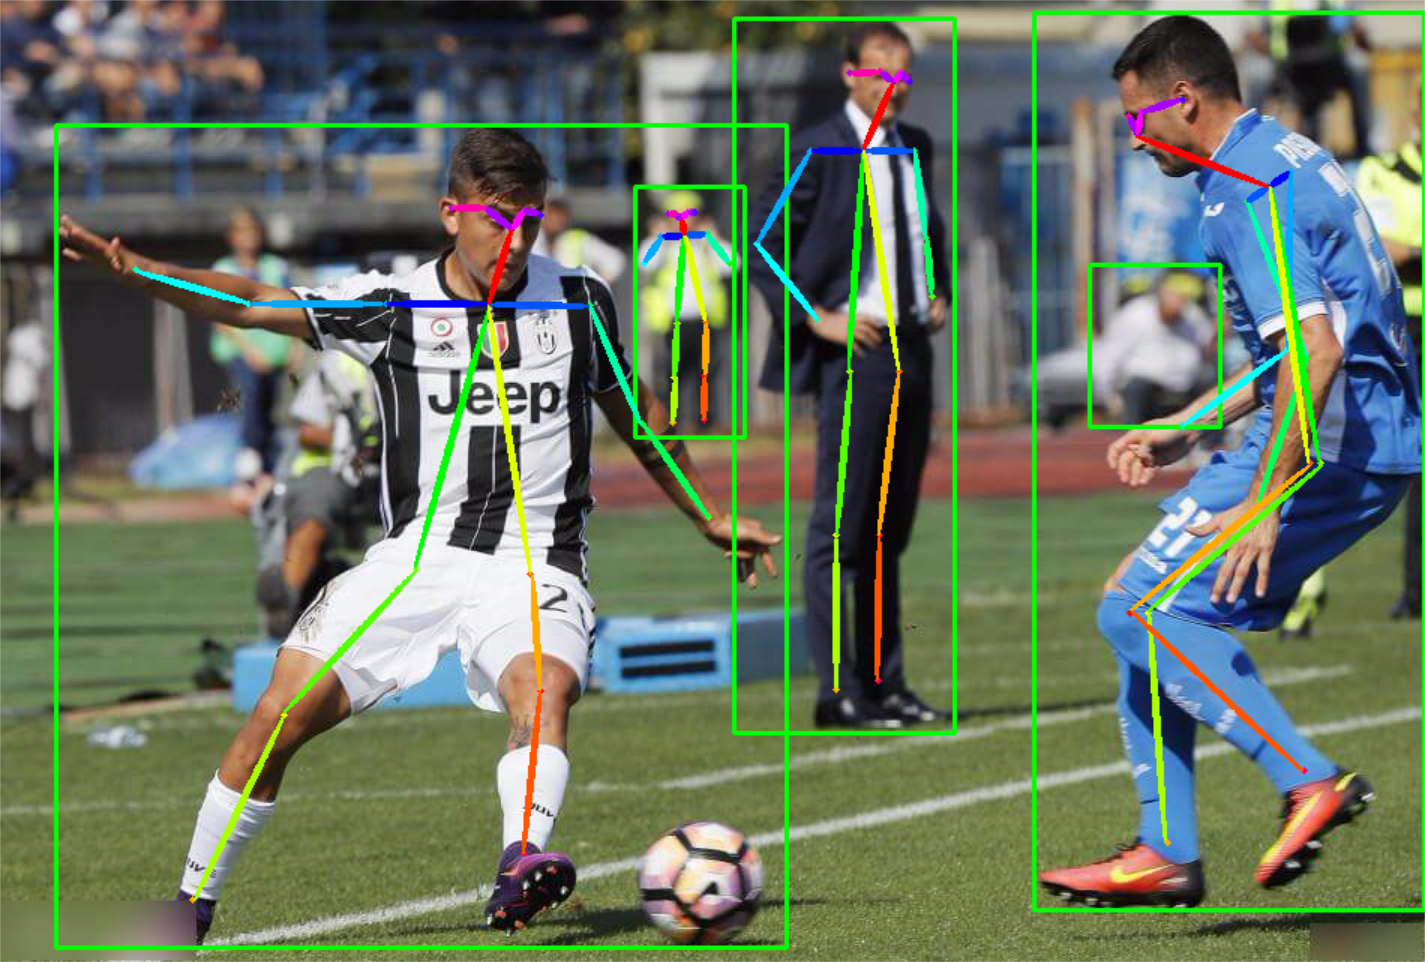
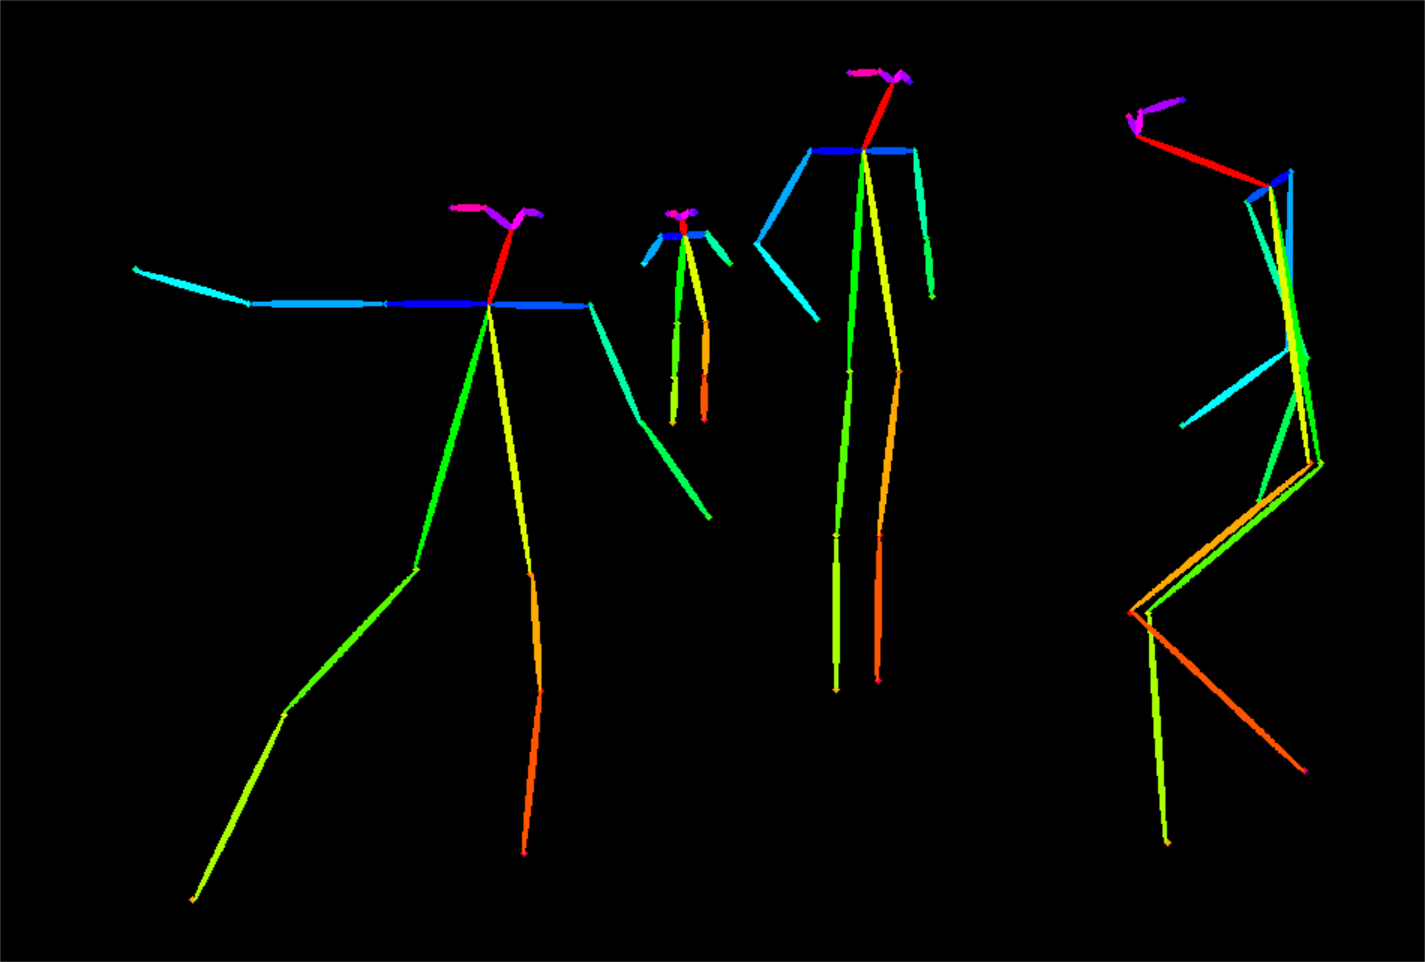
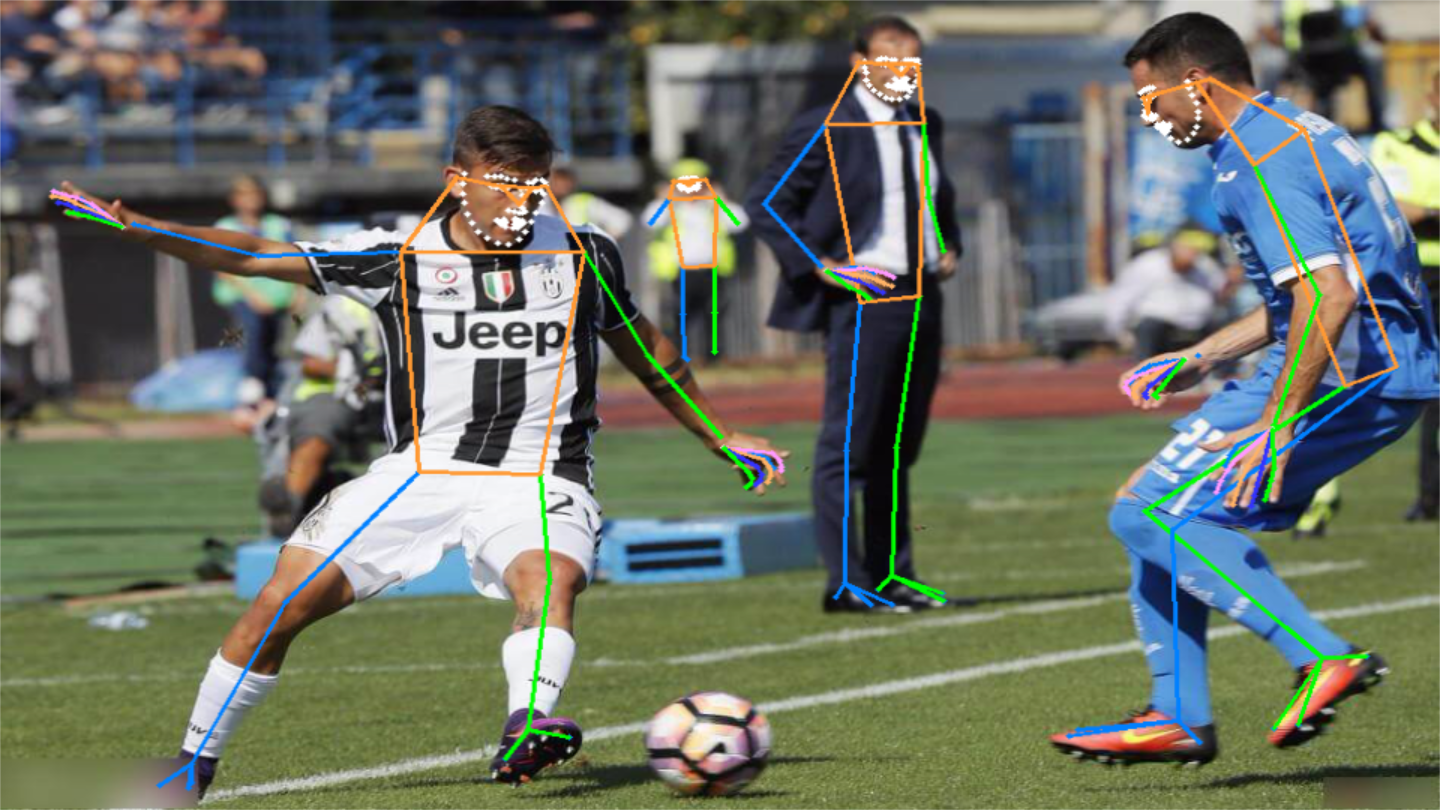
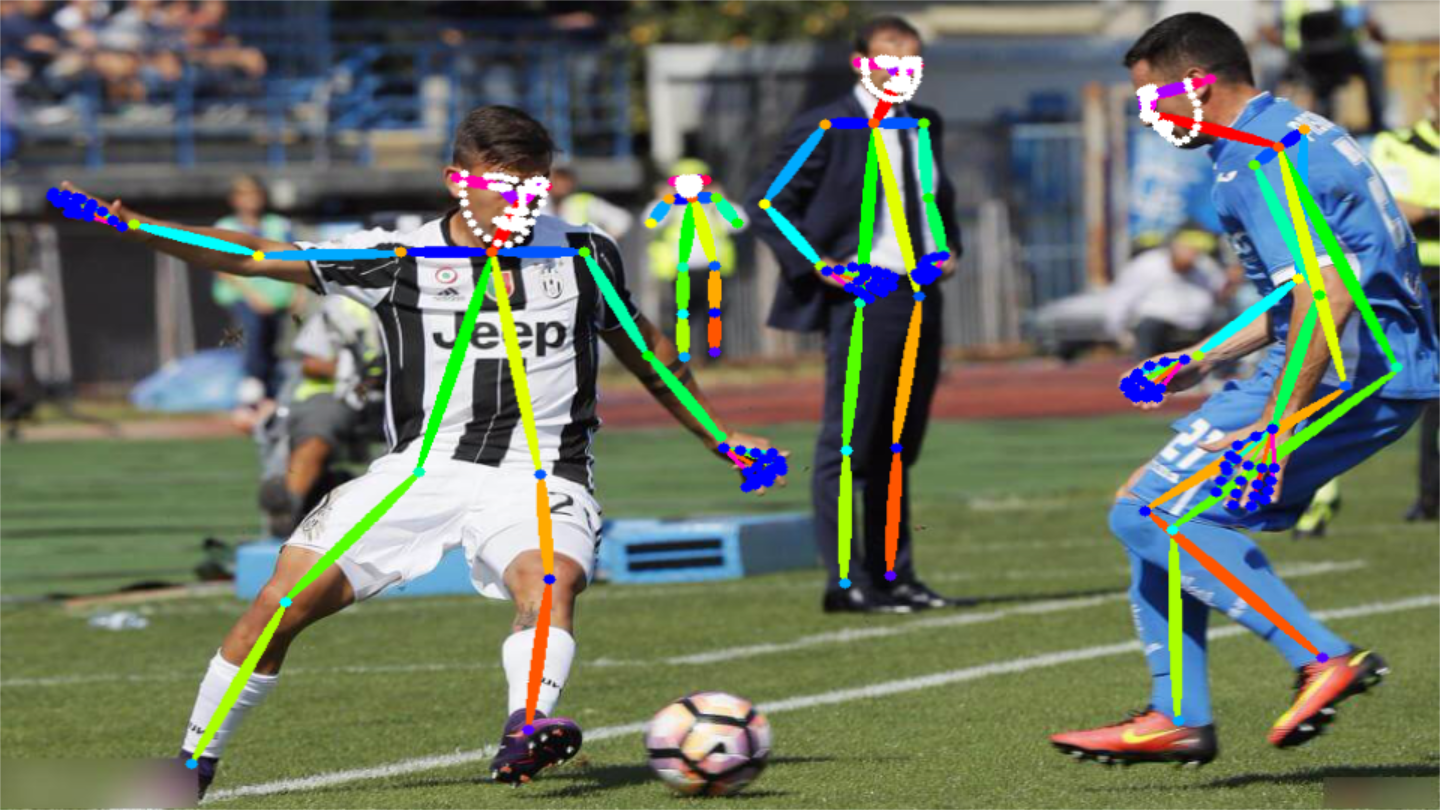
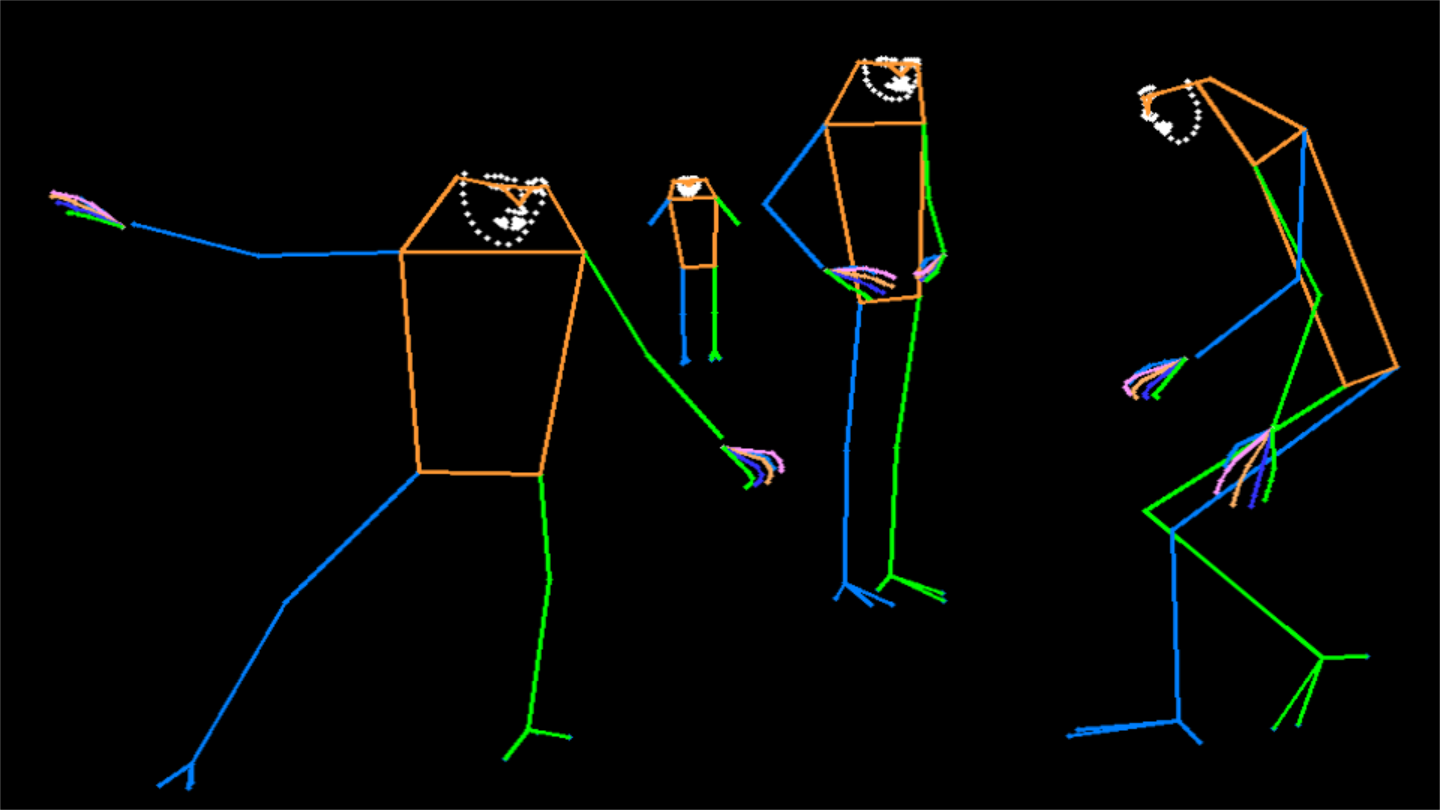
Visualization
| MMPose-style | OpenPose-style |
|---|---|
 |
 |
 |
 |
 |
 |
 |
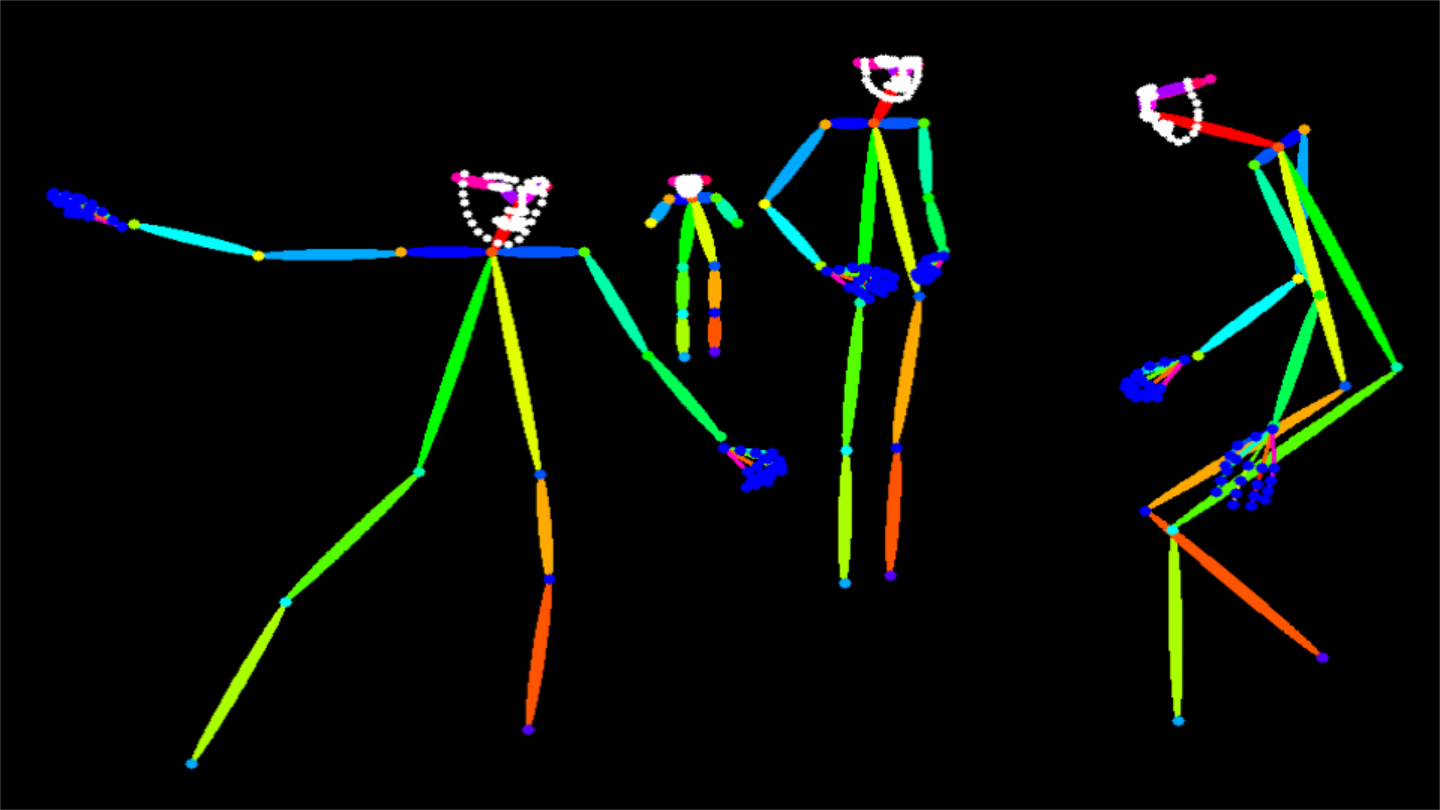 |
Additional resources
Citation
@misc{rtmlib,
  title={rtmlib},
  author={Jiang, Tao},
  year={2023},
  howpublished = {\url{https://github.com/Tau-J/rtmlib}},
}

@misc{jiang2023,
  doi = {10.48550/ARXIV.2303.07399},
  url = {https://arxiv.org/abs/2303.07399},
  author = {Jiang, Tao and Lu, Peng and Zhang, Li and Ma, Ningsheng and Han, Rui and Lyu, Chengqi and Li, Yining and Chen, Kai},
  keywords = {Computer Vision and Pattern Recognition (cs.CV), FOS: Computer and information sciences, FOS: Computer and information sciences},
  title = {RTMPose: Real-Time Multi-Person Pose Estimation based on MMPose},
  publisher = {arXiv},
  year = {2023},
  copyright = {Creative Commons Attribution 4.0 International}
}

@misc{lu2023rtmo,
      title={{RTMO}: Towards High-Performance One-Stage Real-Time Multi-Person Pose Estimation},
      author={Peng Lu and Tao Jiang and Yining Li and Xiangtai Li and Kai Chen and Wenming Yang},
      year={2023},
      eprint={2312.07526},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}

@misc{jiang2024rtmwrealtimemultiperson2d,
      title={RTMW: Real-Time Multi-Person 2D and 3D Whole-body Pose Estimation},
      author={Tao Jiang and Xinchen Xie and Yining Li},
      year={2024},
      eprint={2407.08634},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2407.08634},
}

@article{xu2022vitpose,
      title={Vitpose: Simple vision transformer baselines for human pose estimation},
      author={Xu, Yufei and Zhang, Jing and Zhang, Qiming and Tao, Dacheng},
      journal={Advances in neural information processing systems},
      volume={35},
      pages={38571--38584},
      year={2022}
}

@misc{robinson2025rfdetr,
    title={RF-DETR: Neural Architecture Search for Real-Time Detection Transformers},
    author={Isaac Robinson and Peter Robicheaux and Matvei Popov and Deva Ramanan and Neehar Peri},
    year={2025},
    eprint={2511.09554},
    archivePrefix={arXiv},
    primaryClass={cs.CV},
    url={https://arxiv.org/abs/2511.09554},
}
Acknowledgement
Our code is based on these repos:
1 maintainer

Metadata
1 maintainer
Release files for rtmlib 0.0.16
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| rtmlib-0.0.16.tar.gz | 68.5 kB | With provenance | Details for rtmlib-0.0.16.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| rtmlib-0.0.16-py3-none-any.whl | Python 3 | none | any | Details for rtmlib-0.0.16-py3-none-any.whl |
Total release size: 138.1 kB
Release files / rtmlib-0.0.16.tar.gz
| Download URL | rtmlib-0.0.16.tar.gz |
|---|---|
| Size | 68.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6976ed12efde3b061adb04bcf28830c696c72cb26814832b76b7c05086054cc3
|
|
BLAKE2b-256 checksum How to use checksums |
738a50225d6e11e0002a3860940807184170a443a5b62b13623157054418b833
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 4, 2026.
Transparency logRelease files / rtmlib-0.0.16-py3-none-any.whl
| Download URL | rtmlib-0.0.16-py3-none-any.whl |
|---|---|
| Size | 69.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ba932b25f7d264d7ec4837545c5e7c392001f48b53e22e514cb1497882389eaa
|
|
BLAKE2b-256 checksum How to use checksums |
2fe5458732286f895e154a1ee1c371904238063d35698a155e41ecc4fd2f64f0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 4, 2026.
Transparency logSecurity for rtmlib 0.0.16
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for rtmlib-0.0.16.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 4, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














