
Segment Anything in High Quality


Segment Anything in High Quality
Lei Ke, Mingqiao Ye, Martin Danelljan, Yifan Liu, Yu-Wing Tai, Chi-Keung Tang, Fisher Yu
ETH Zurich & HKUST
We propose HQ-SAM to upgrade SAM for high-quality zero-shot segmentation. Refer to our paper for more details.
Updates
2023/07/25: Light HQ-SAM is in EfficientSAM series combining with Grounded SAM, thanks the support!
2023/07/21: HQ-SAM is also in OpenXLab apps, thanks their support!
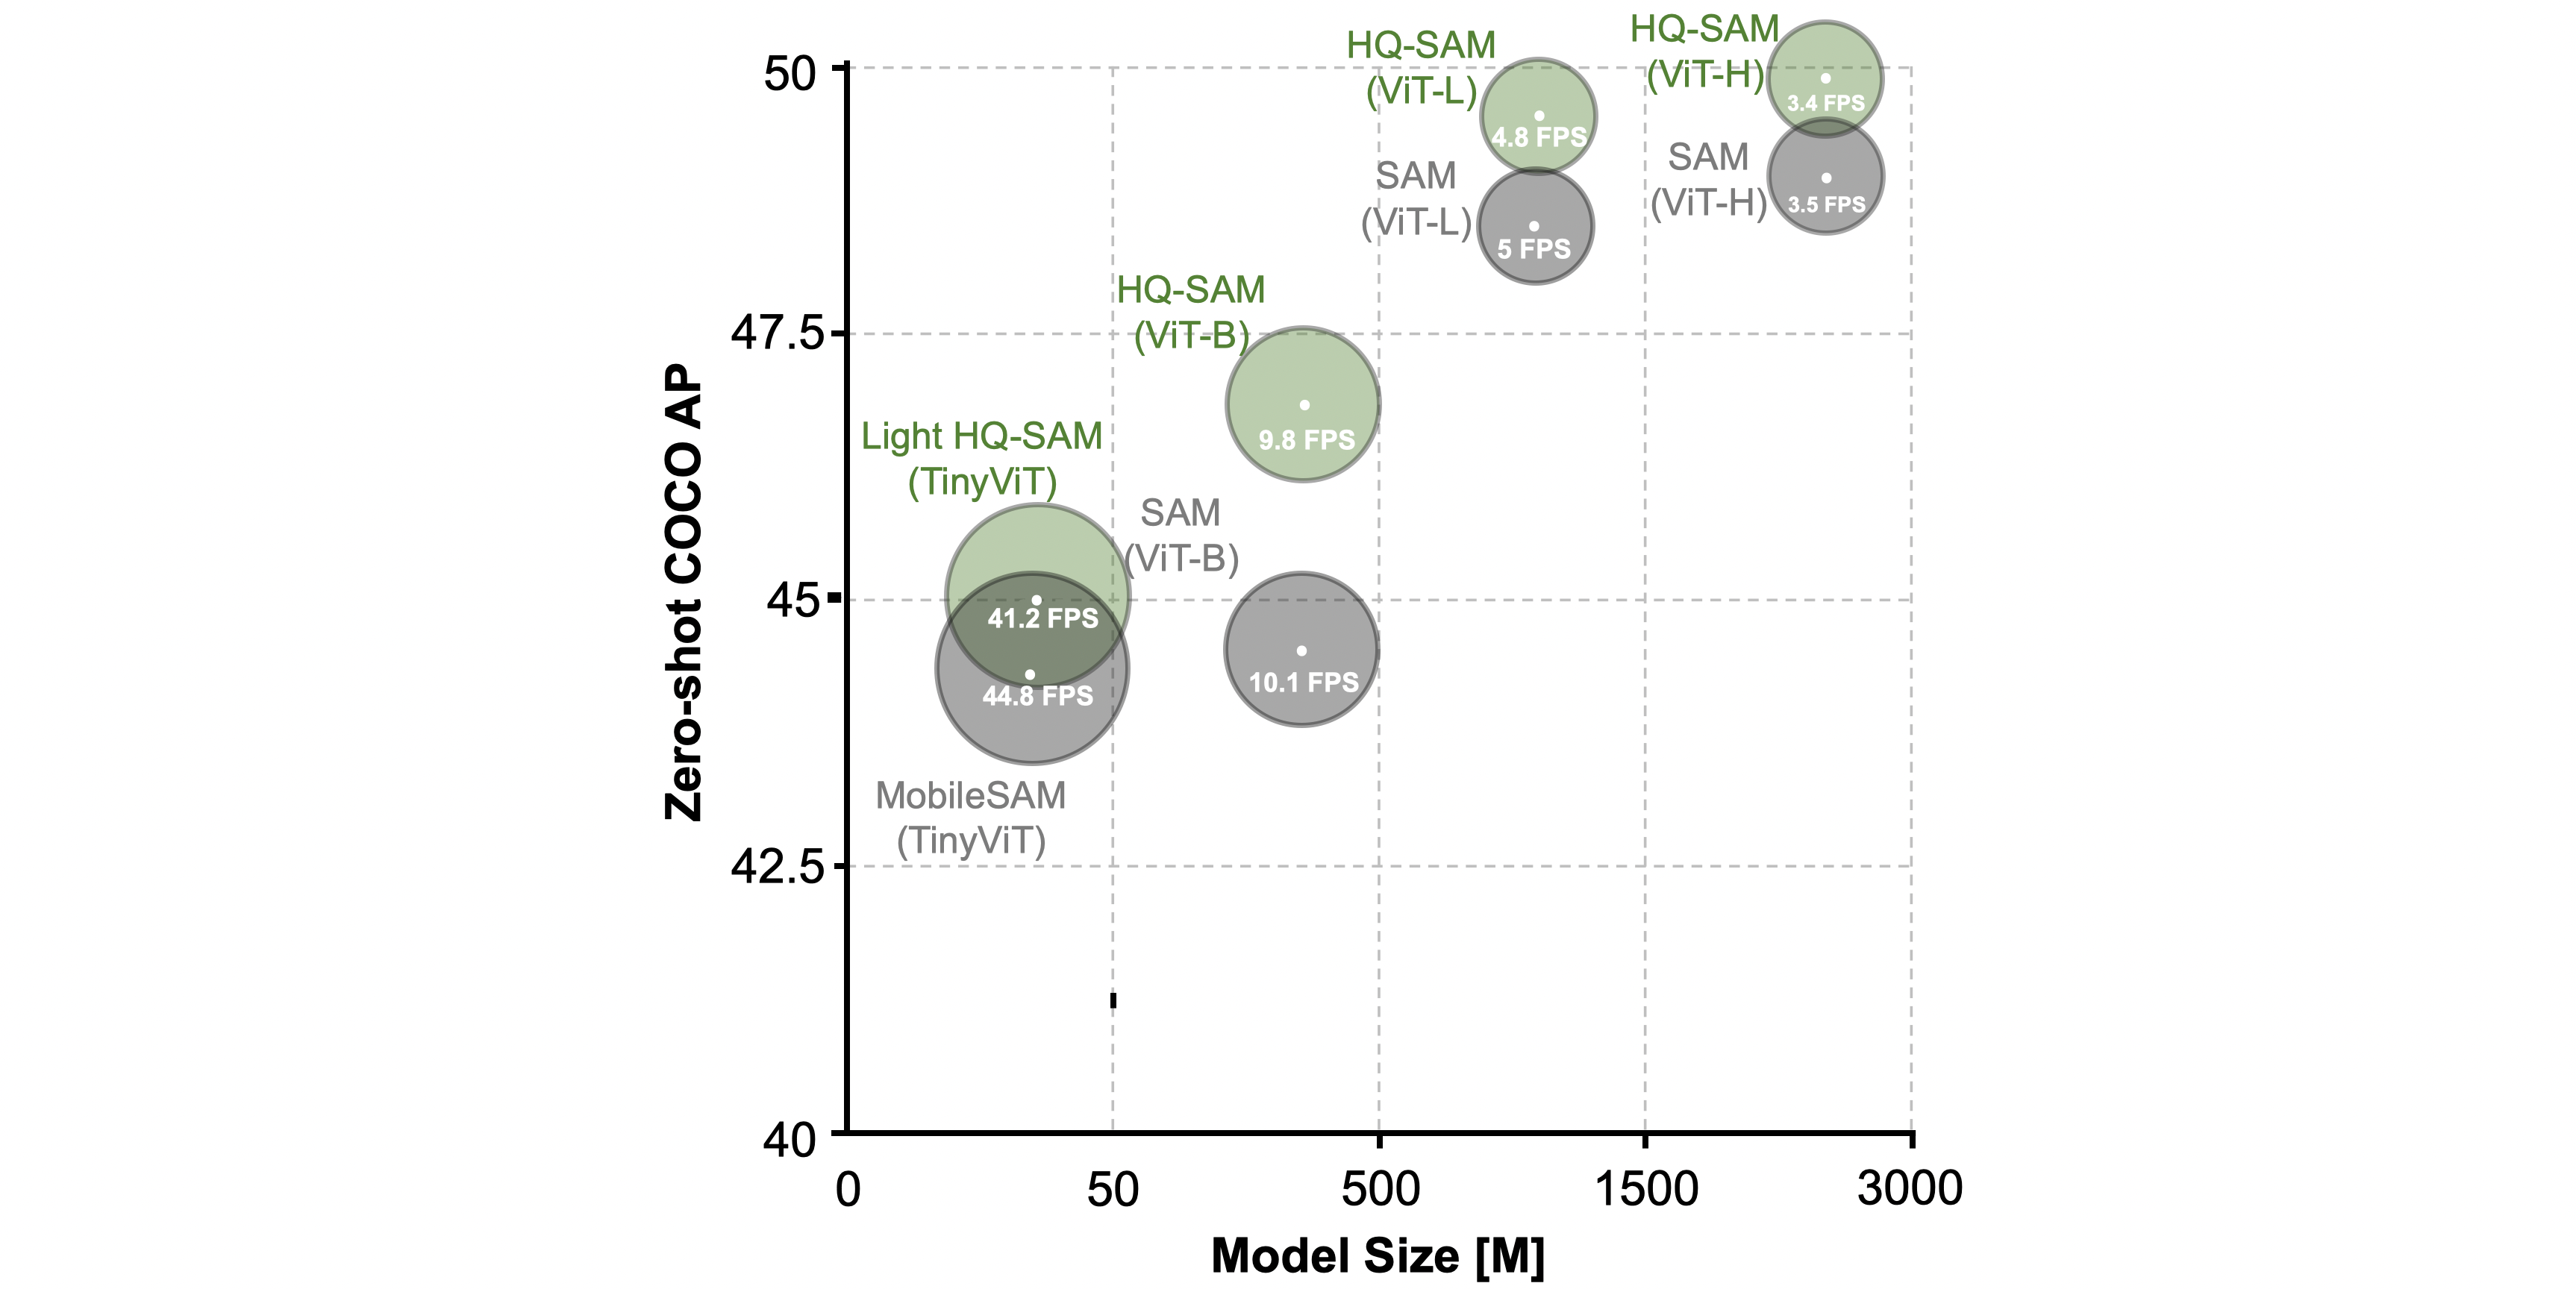
🚀🚀 2023/07/17: We released Light HQ-SAM using TinyViT as backbone, for both fast and high-quality zero-shot segmentation, which reaches 41.2 FPS. Refer to Light HQ-SAM vs. MobileSAM for more details.
🏆🥇 2023/07/14: Grounded HQ-SAM obtains the first place🥇 in the Segmentation in the Wild competition on zero-shot track (hosted in CVPR 2023 workshop), outperforming Grounded SAM. Refer to our SGinW evaluation for more details.
🔥🔥 2023/07/05: We released SAM tuning instuctions and HQSeg-44K data.
2023/07/04: HQ-SAM is adopted in SAM-PT to improve the SAM-based zero-shot video segmentation performance. Also, HQ-SAM is used in Grounded-SAM, Inpaint Anything and HQTrack (2nd in VOTS 2023).
2023/06/28: We released the ONNX export script and colab notebook for exporting and using ONNX model.
2023/06/23: Play with HQ-SAM demo at
2023/06/14: We released the colab demo
2023/06/13: We released the model checkpoints and demo visualization codes.
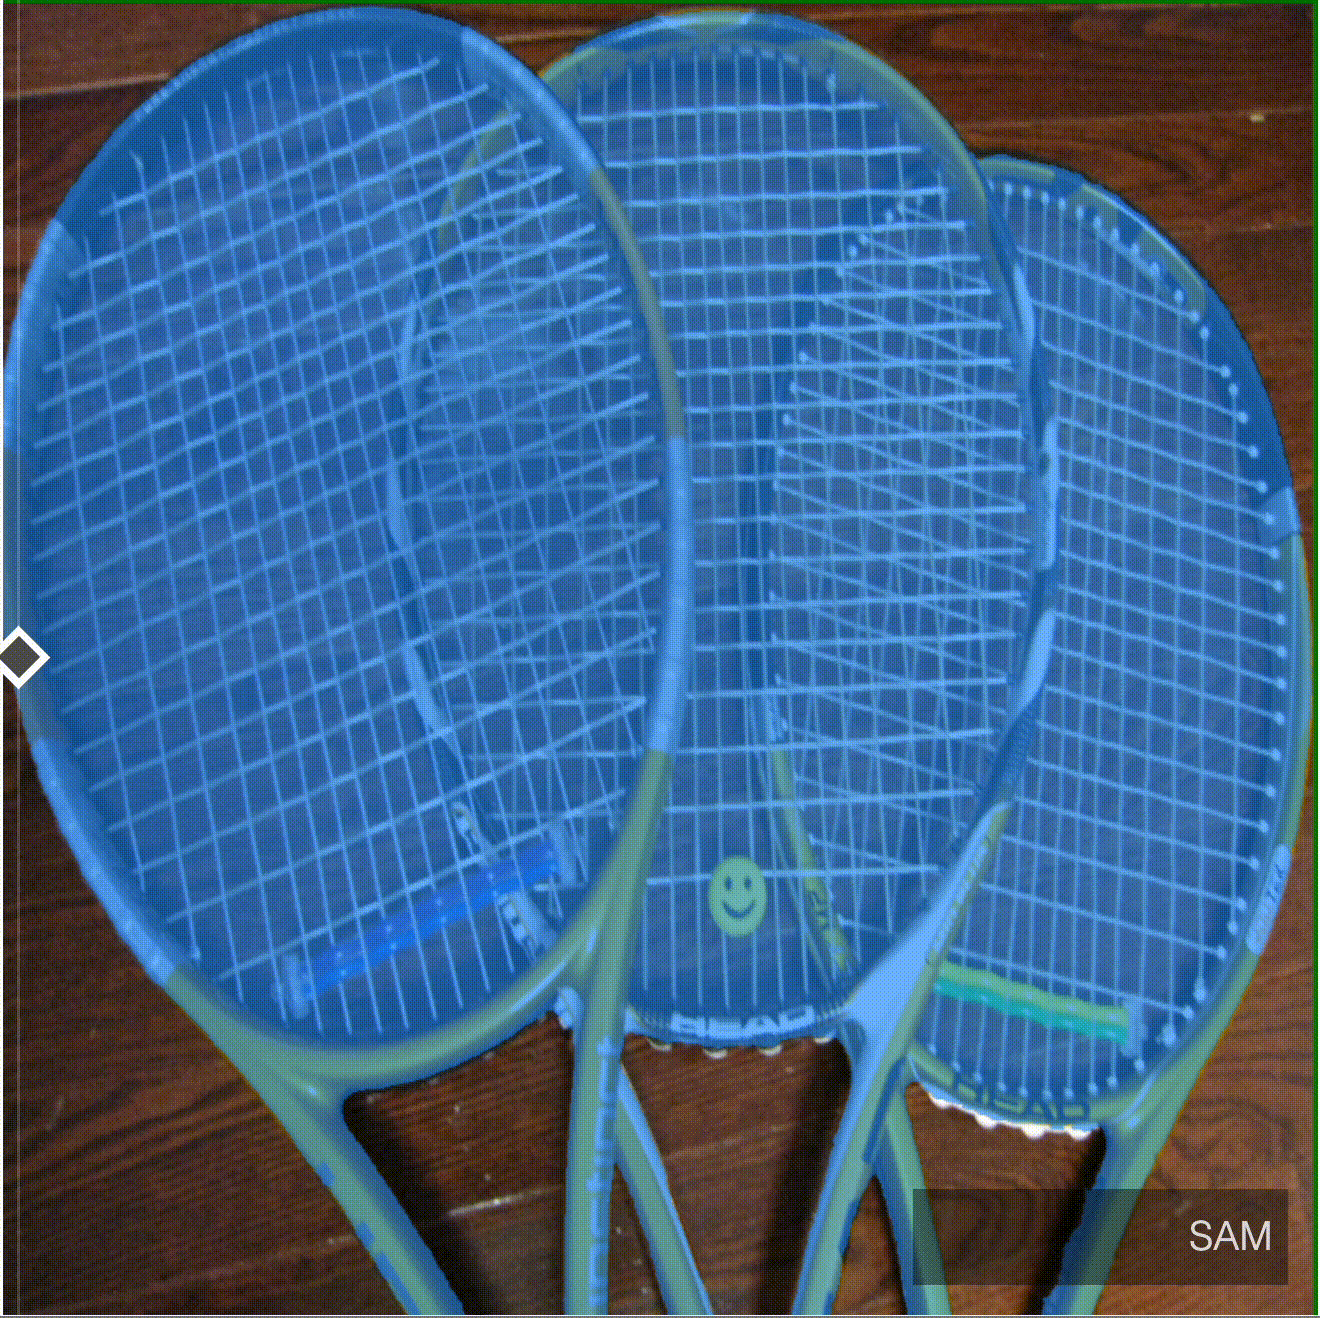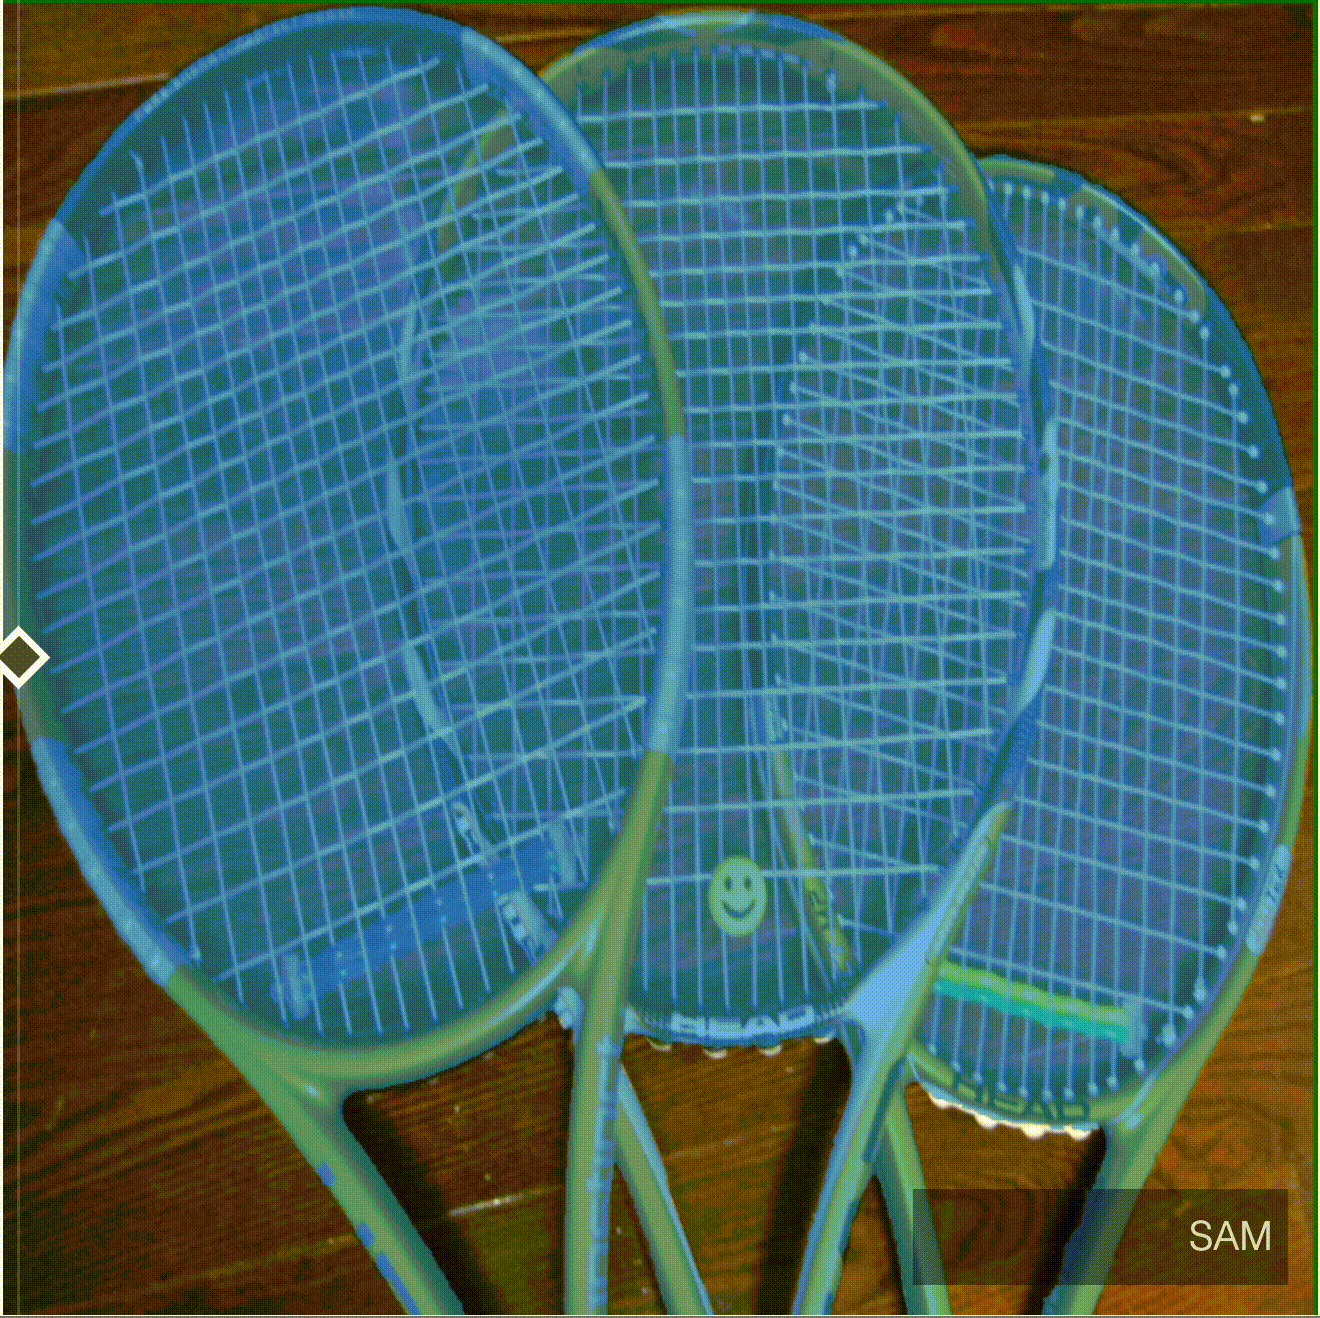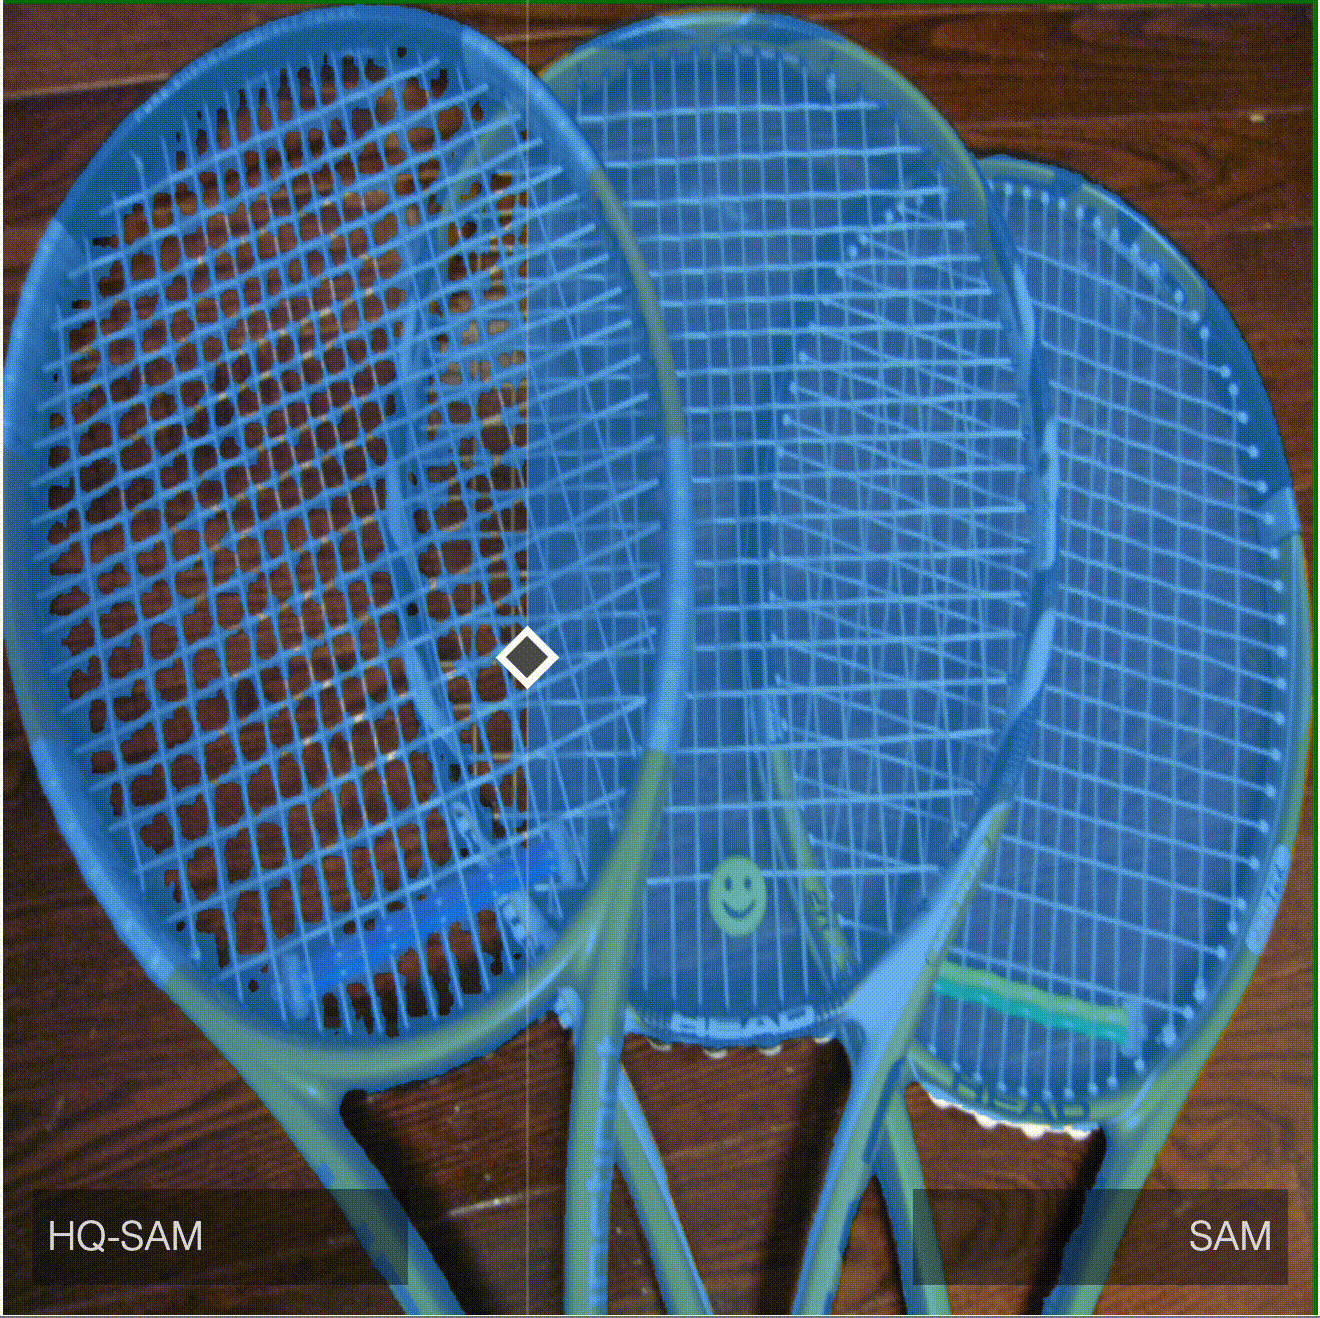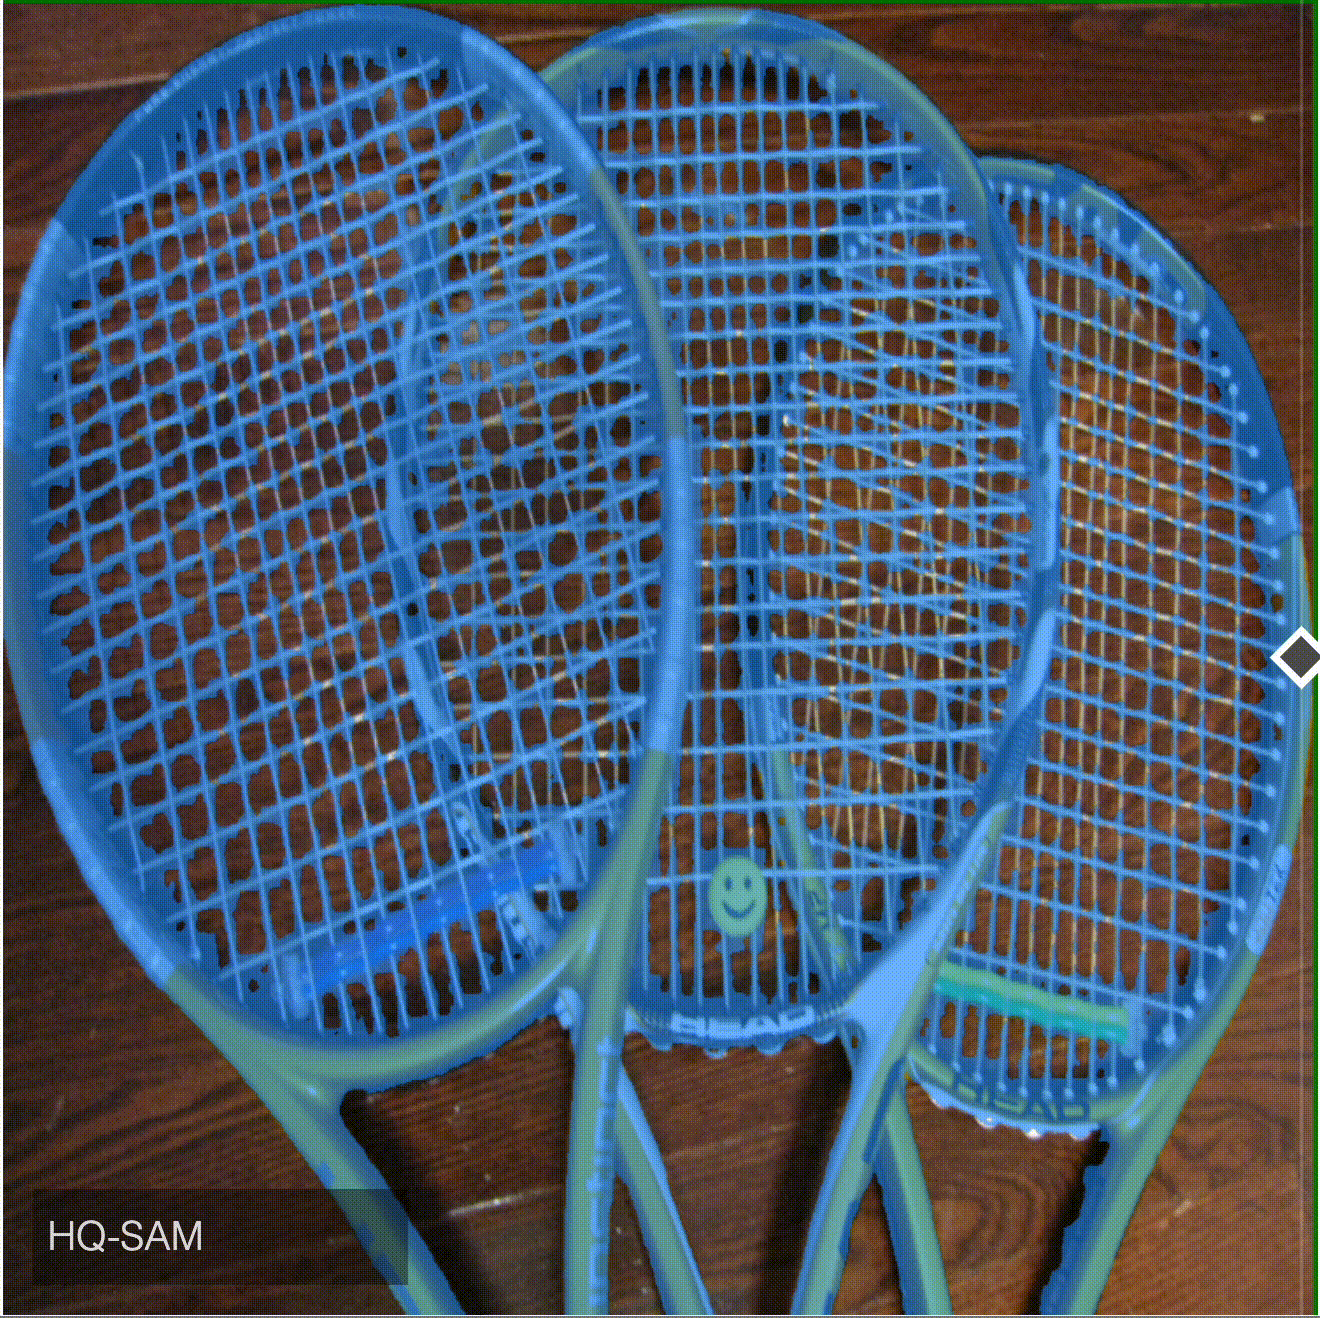
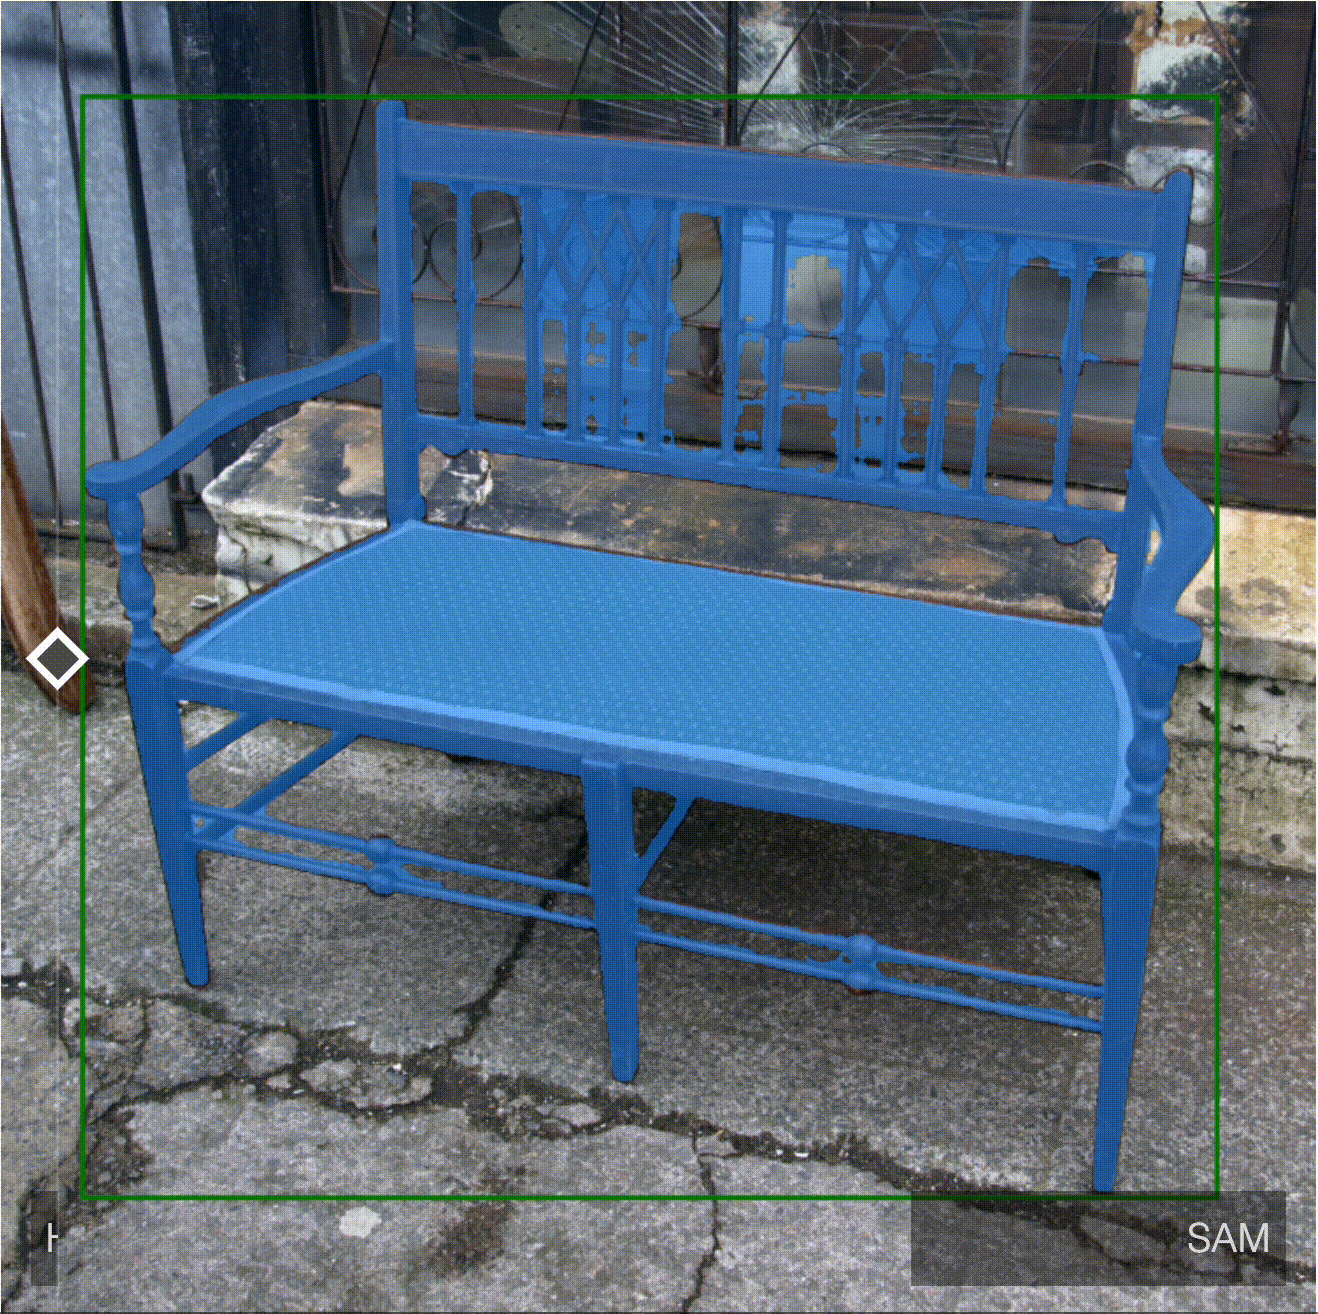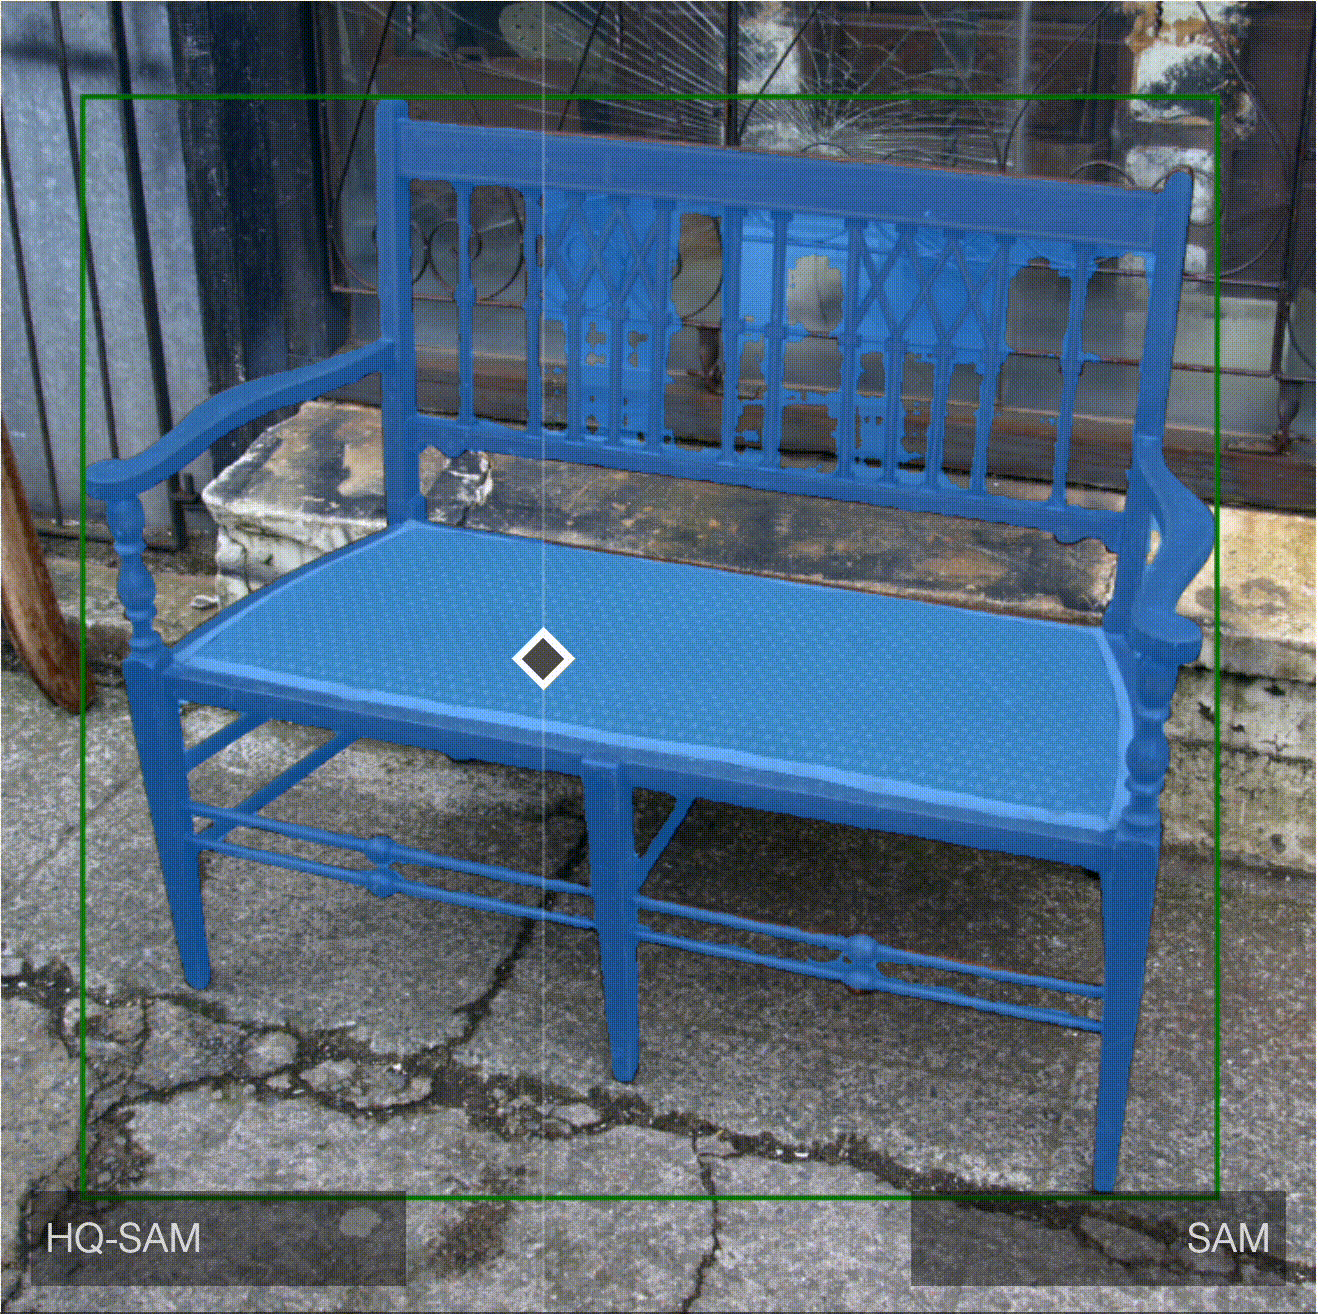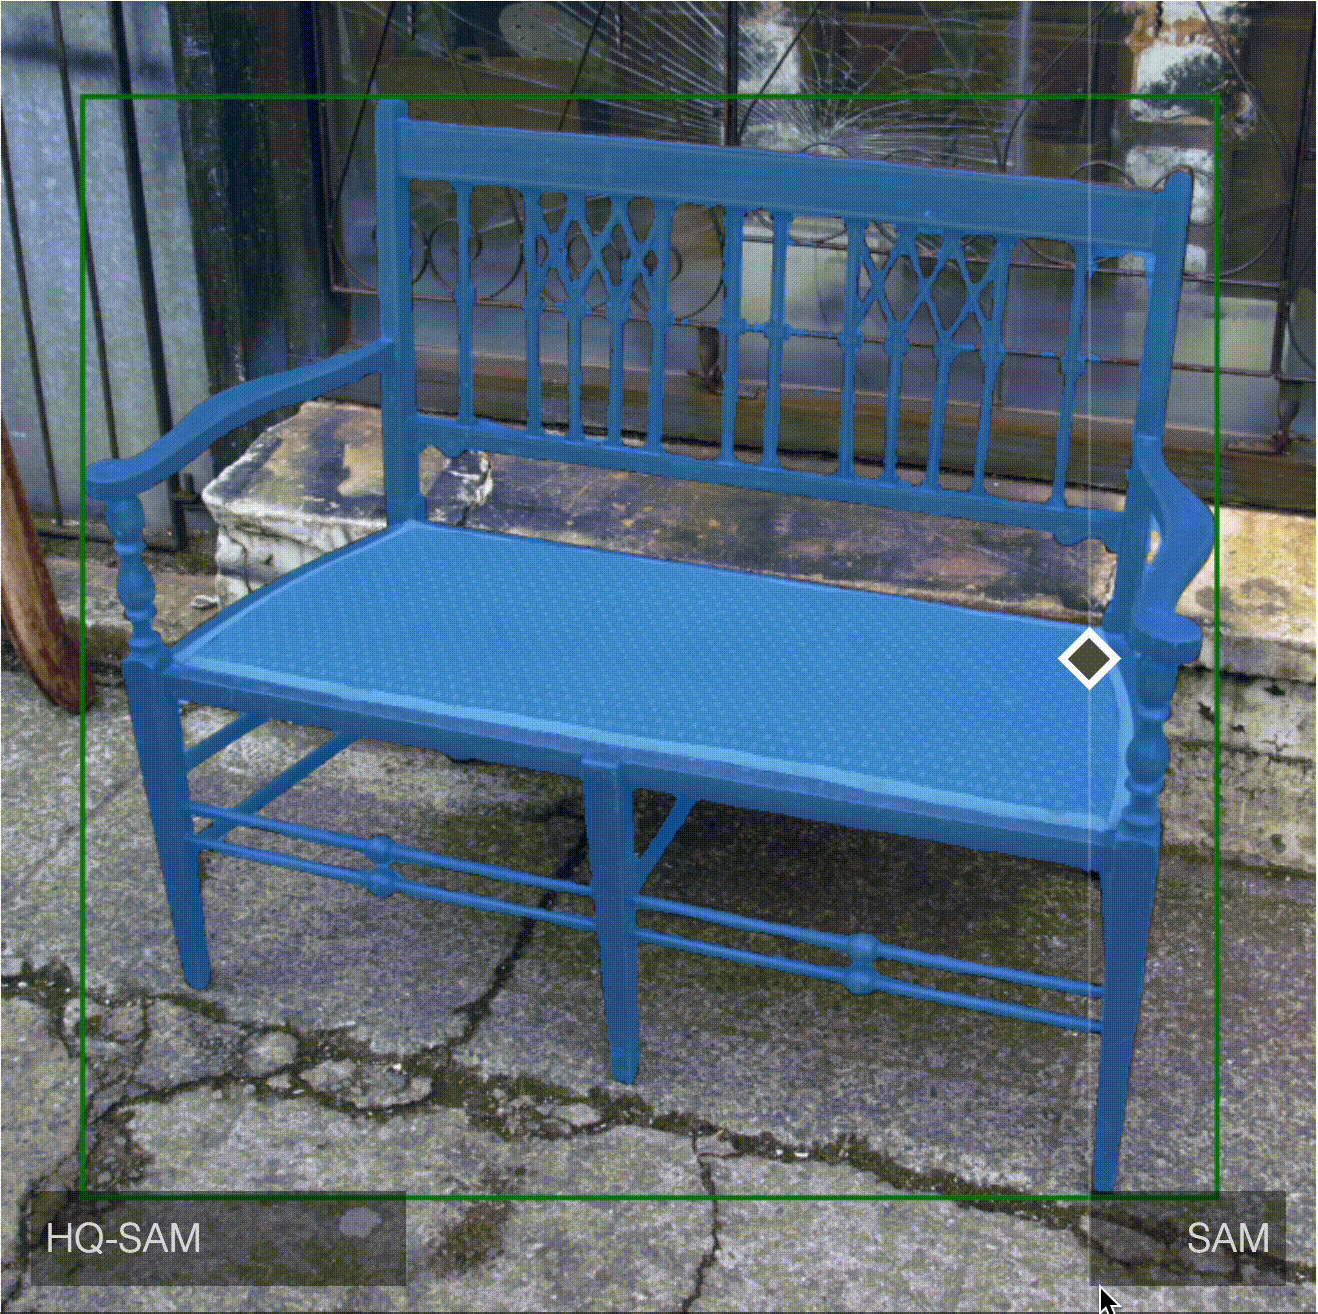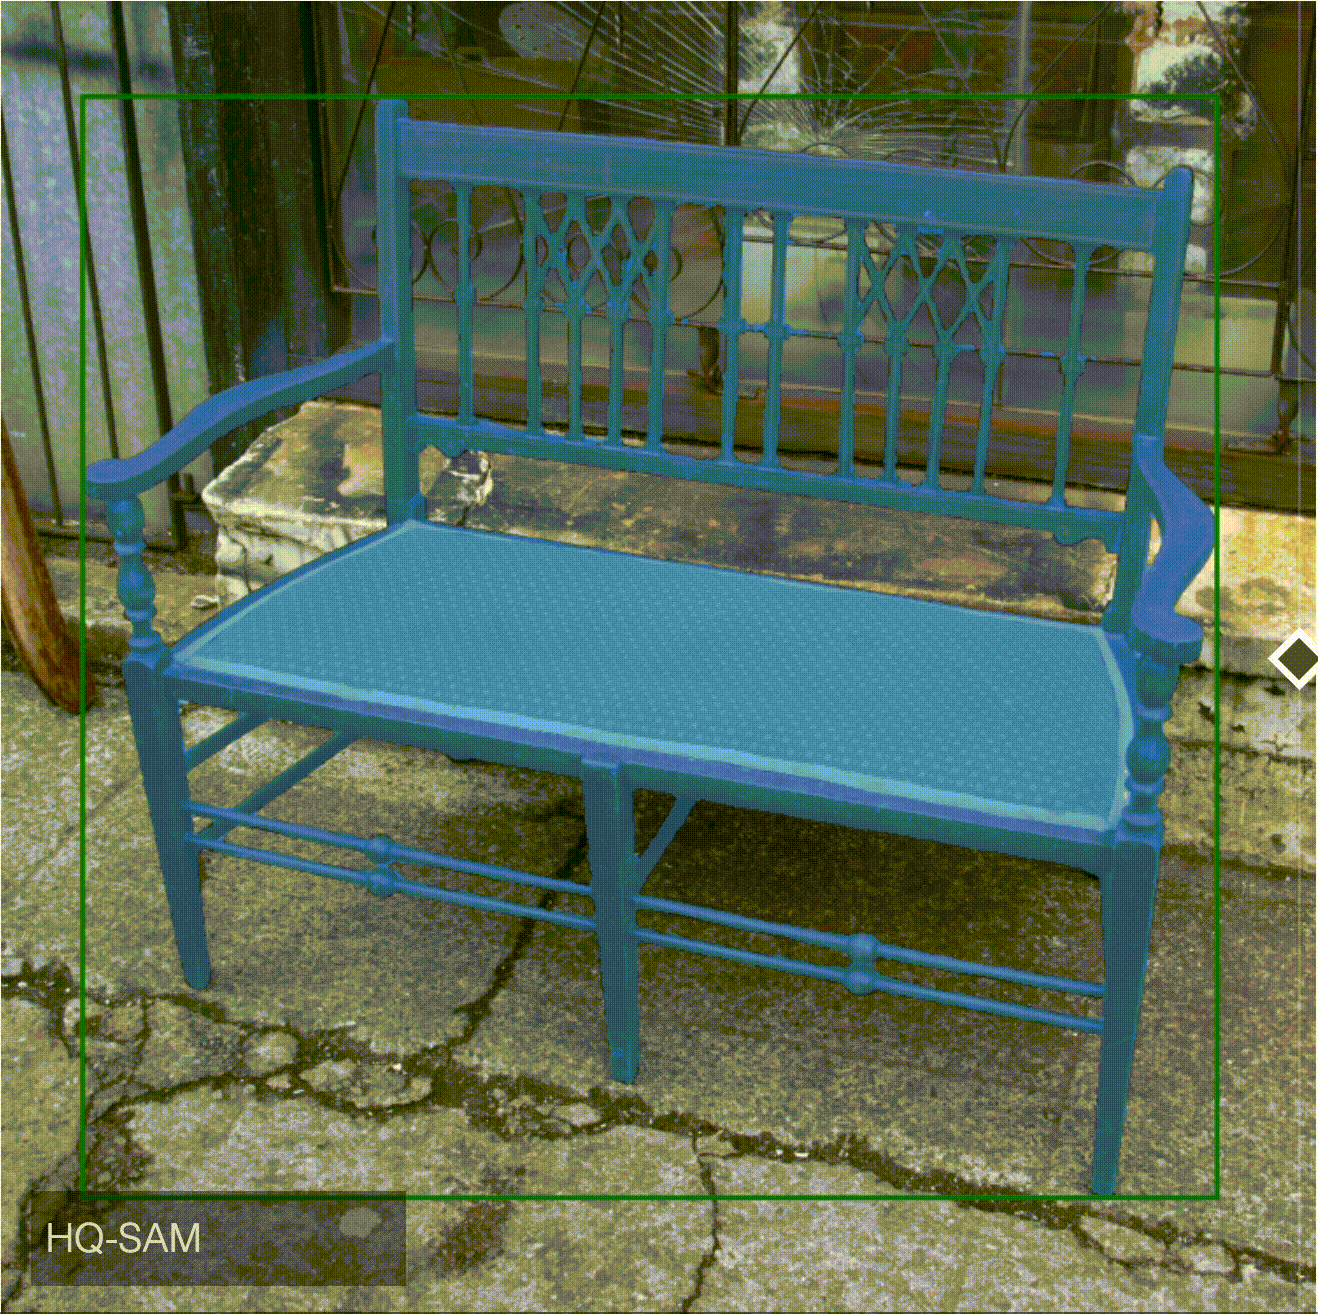
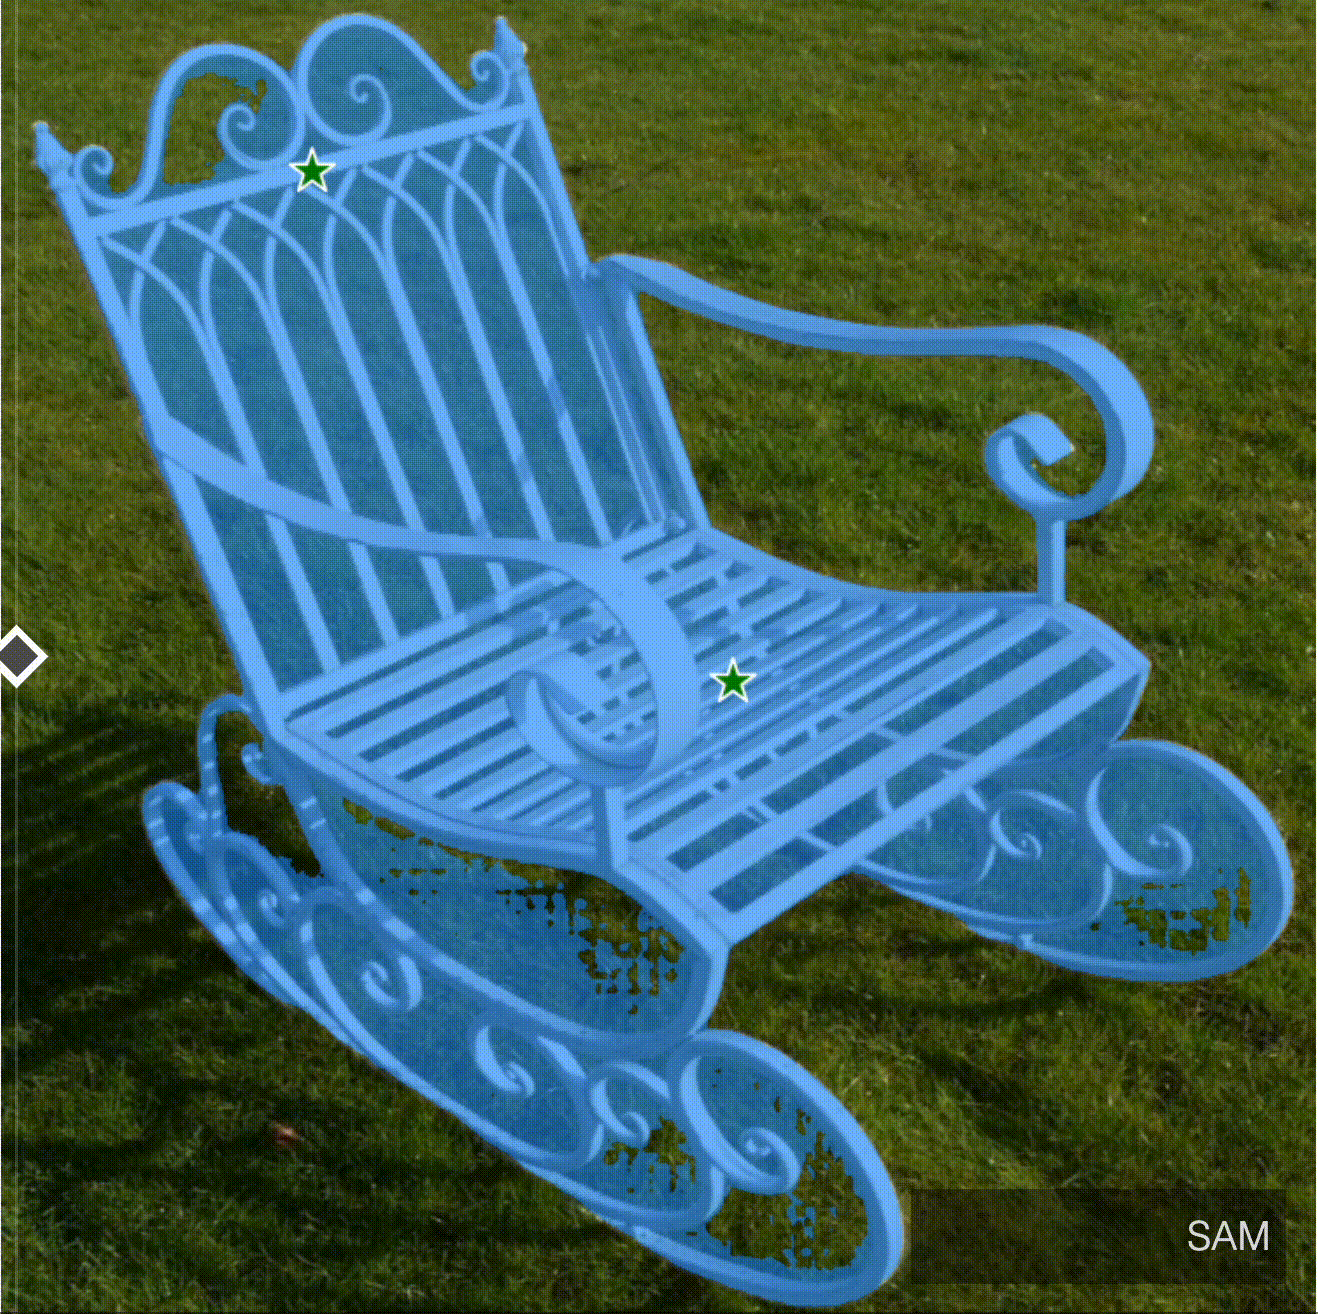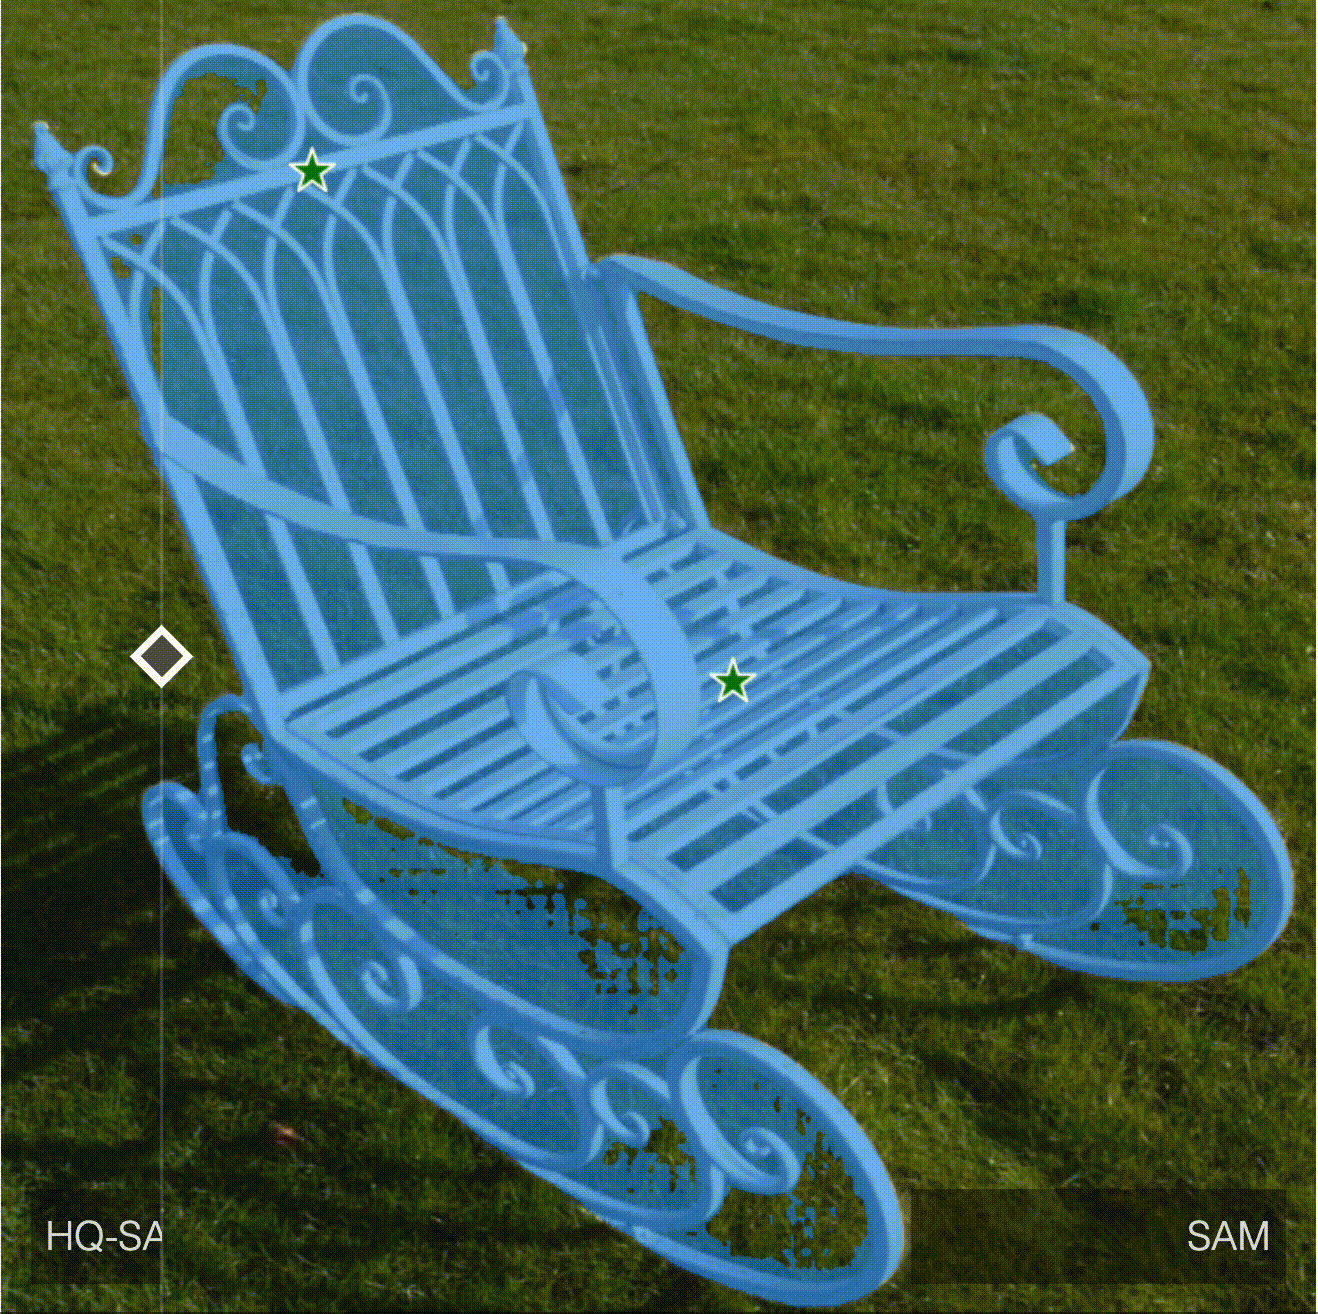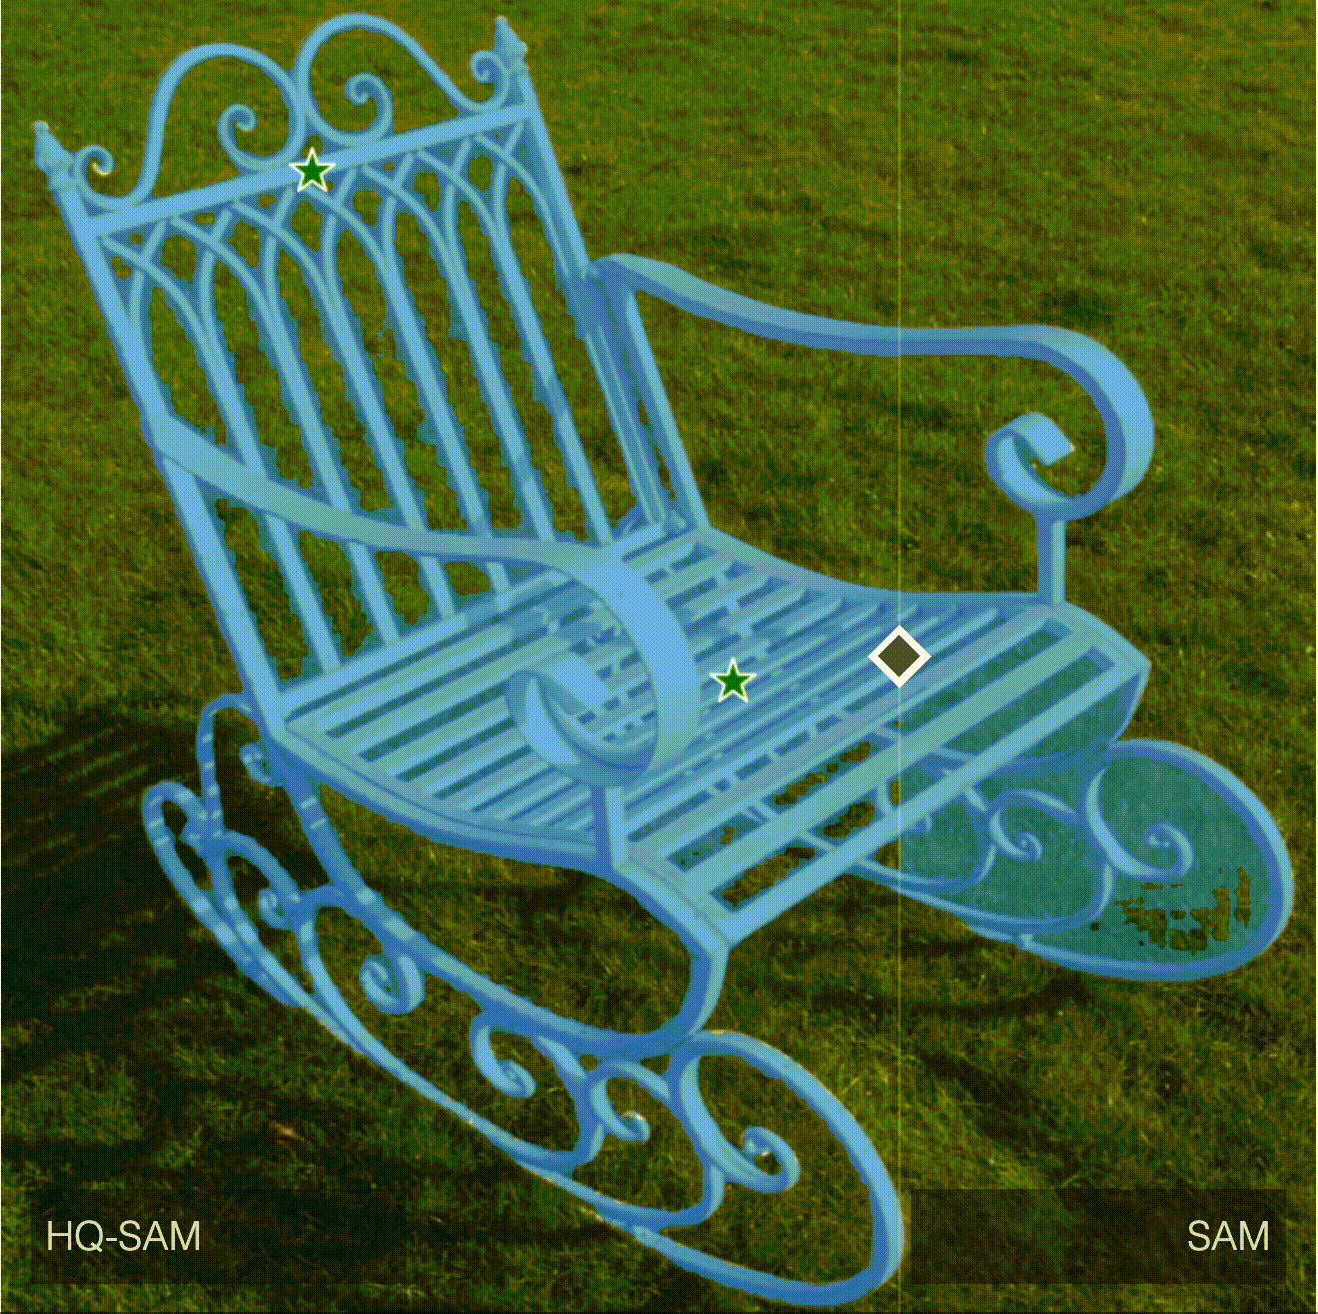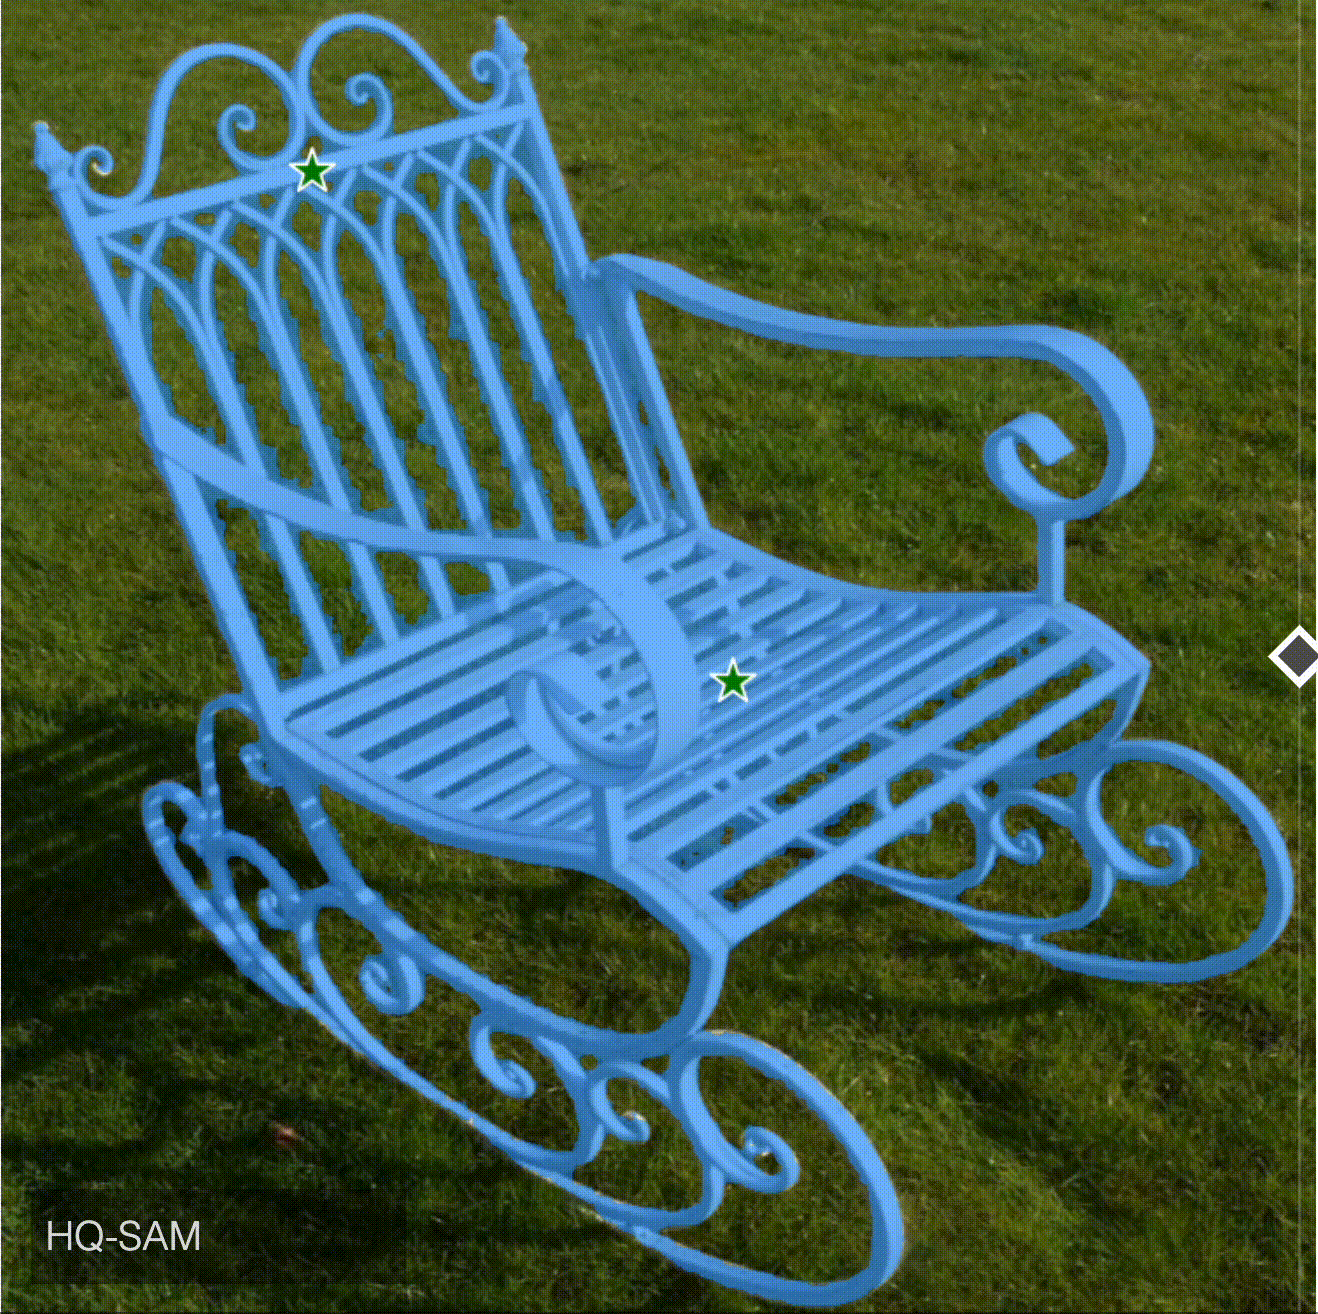
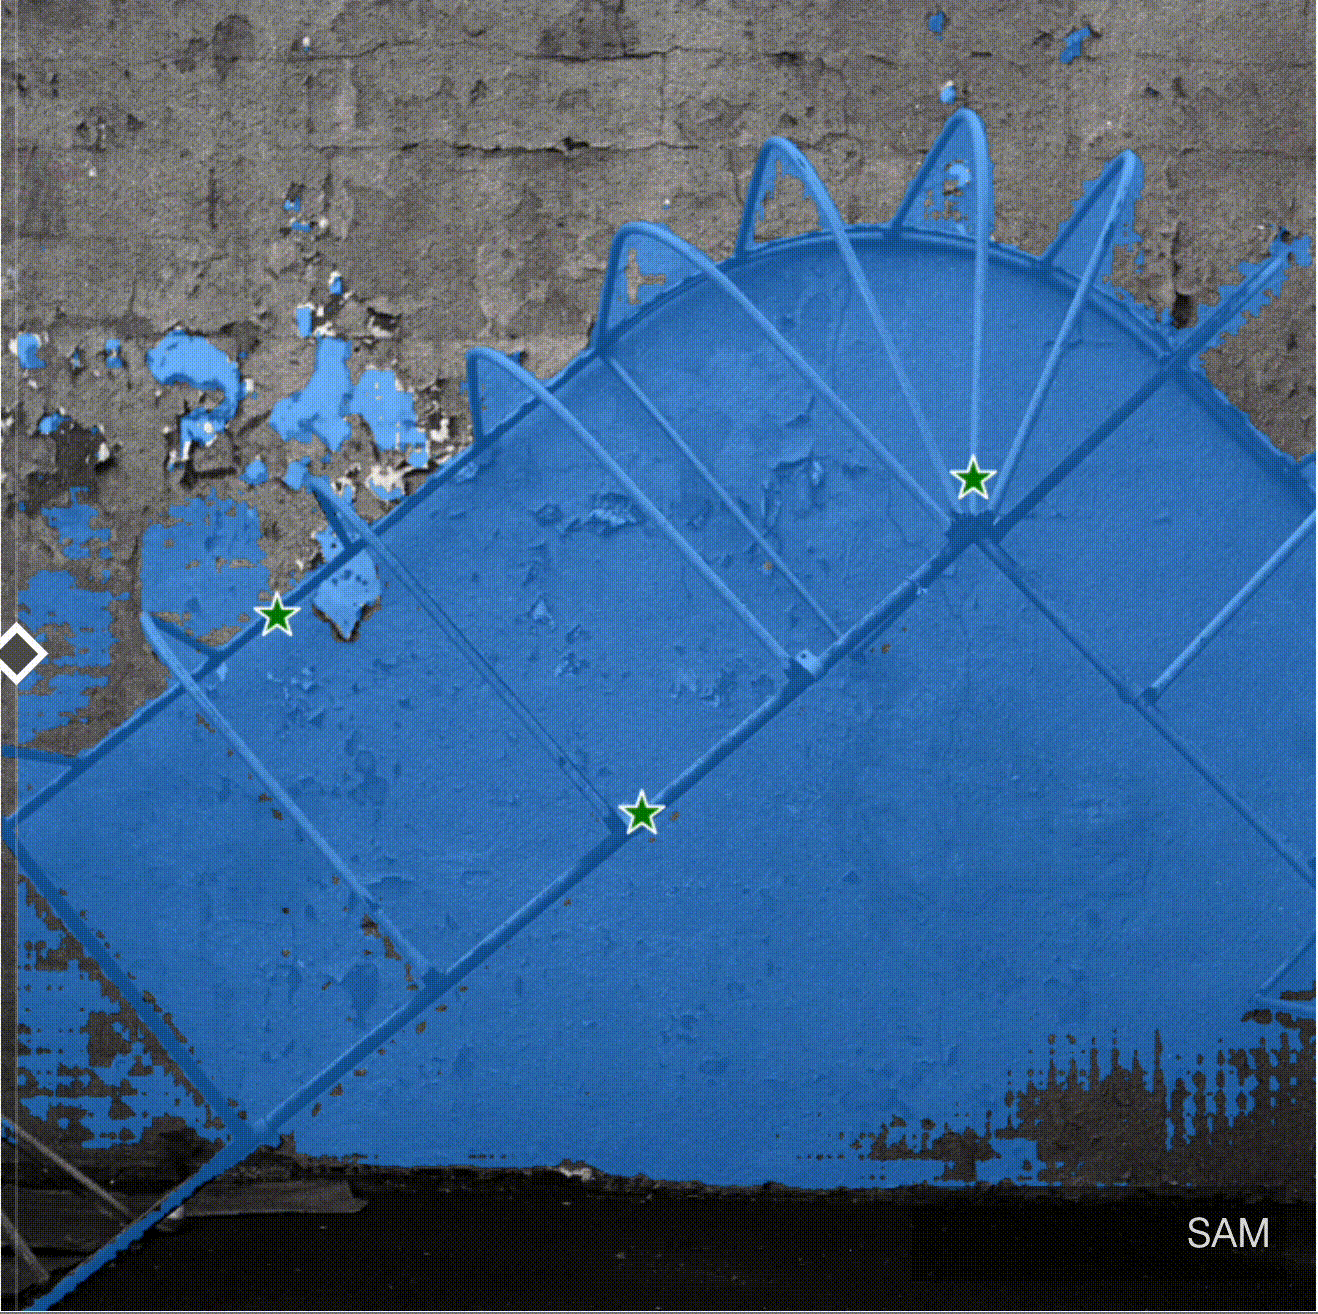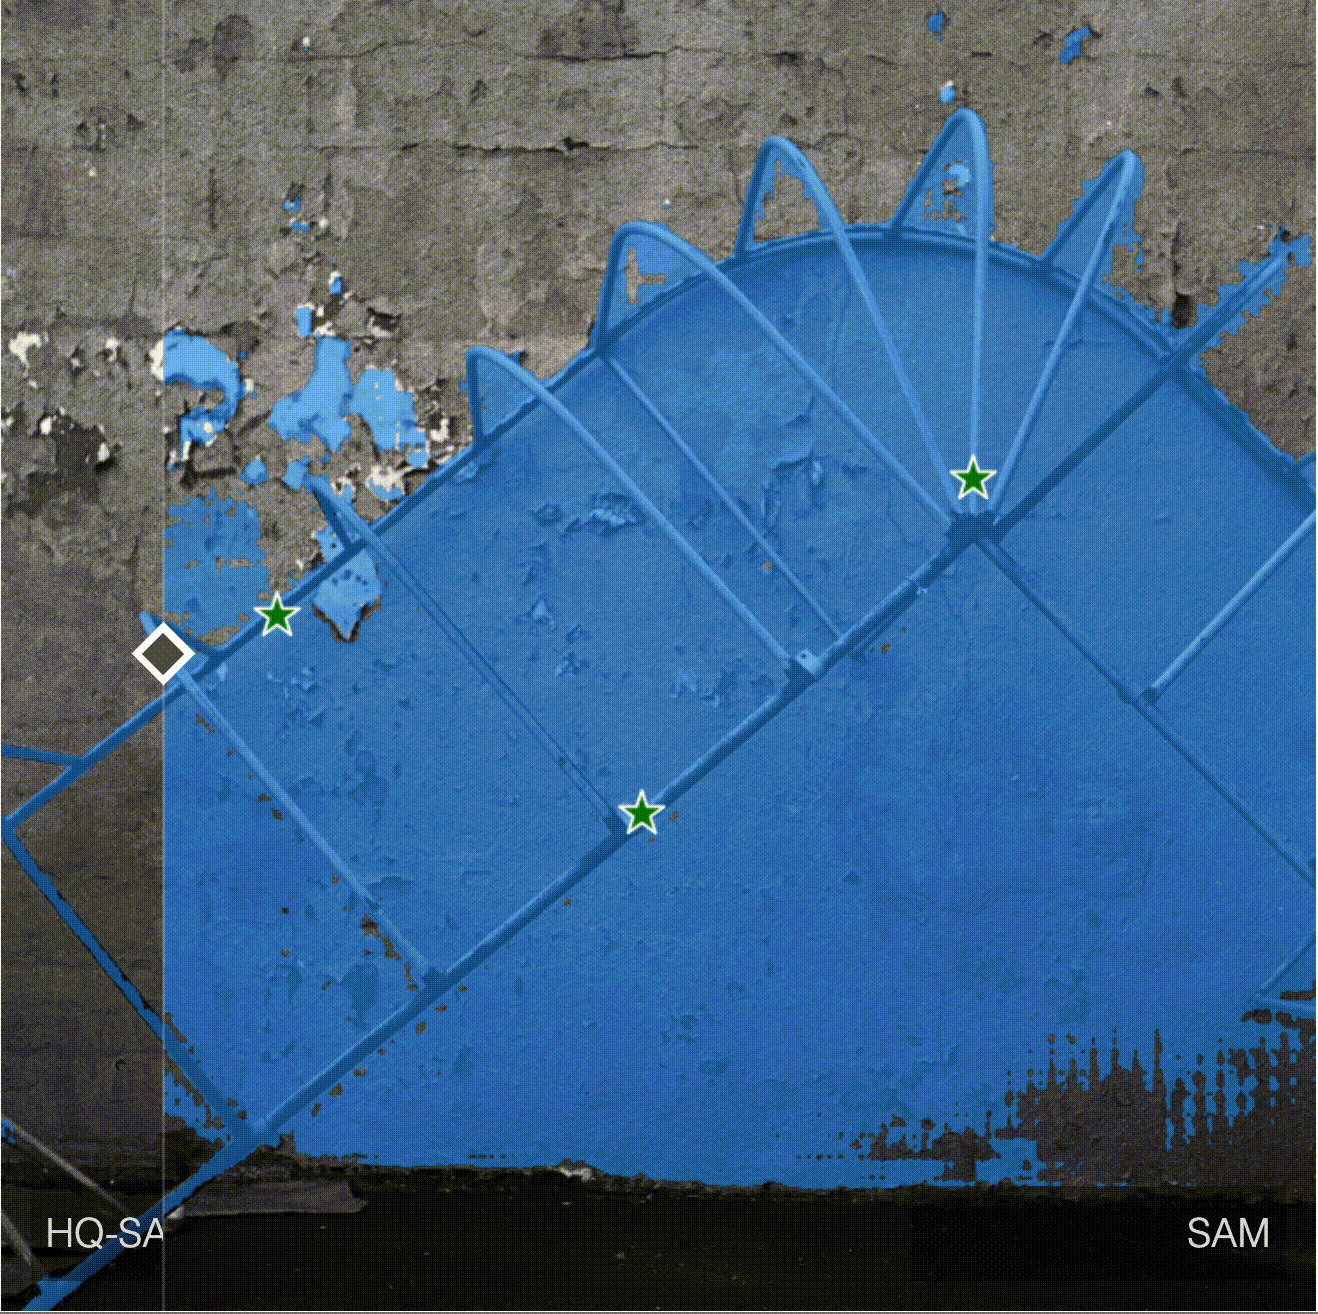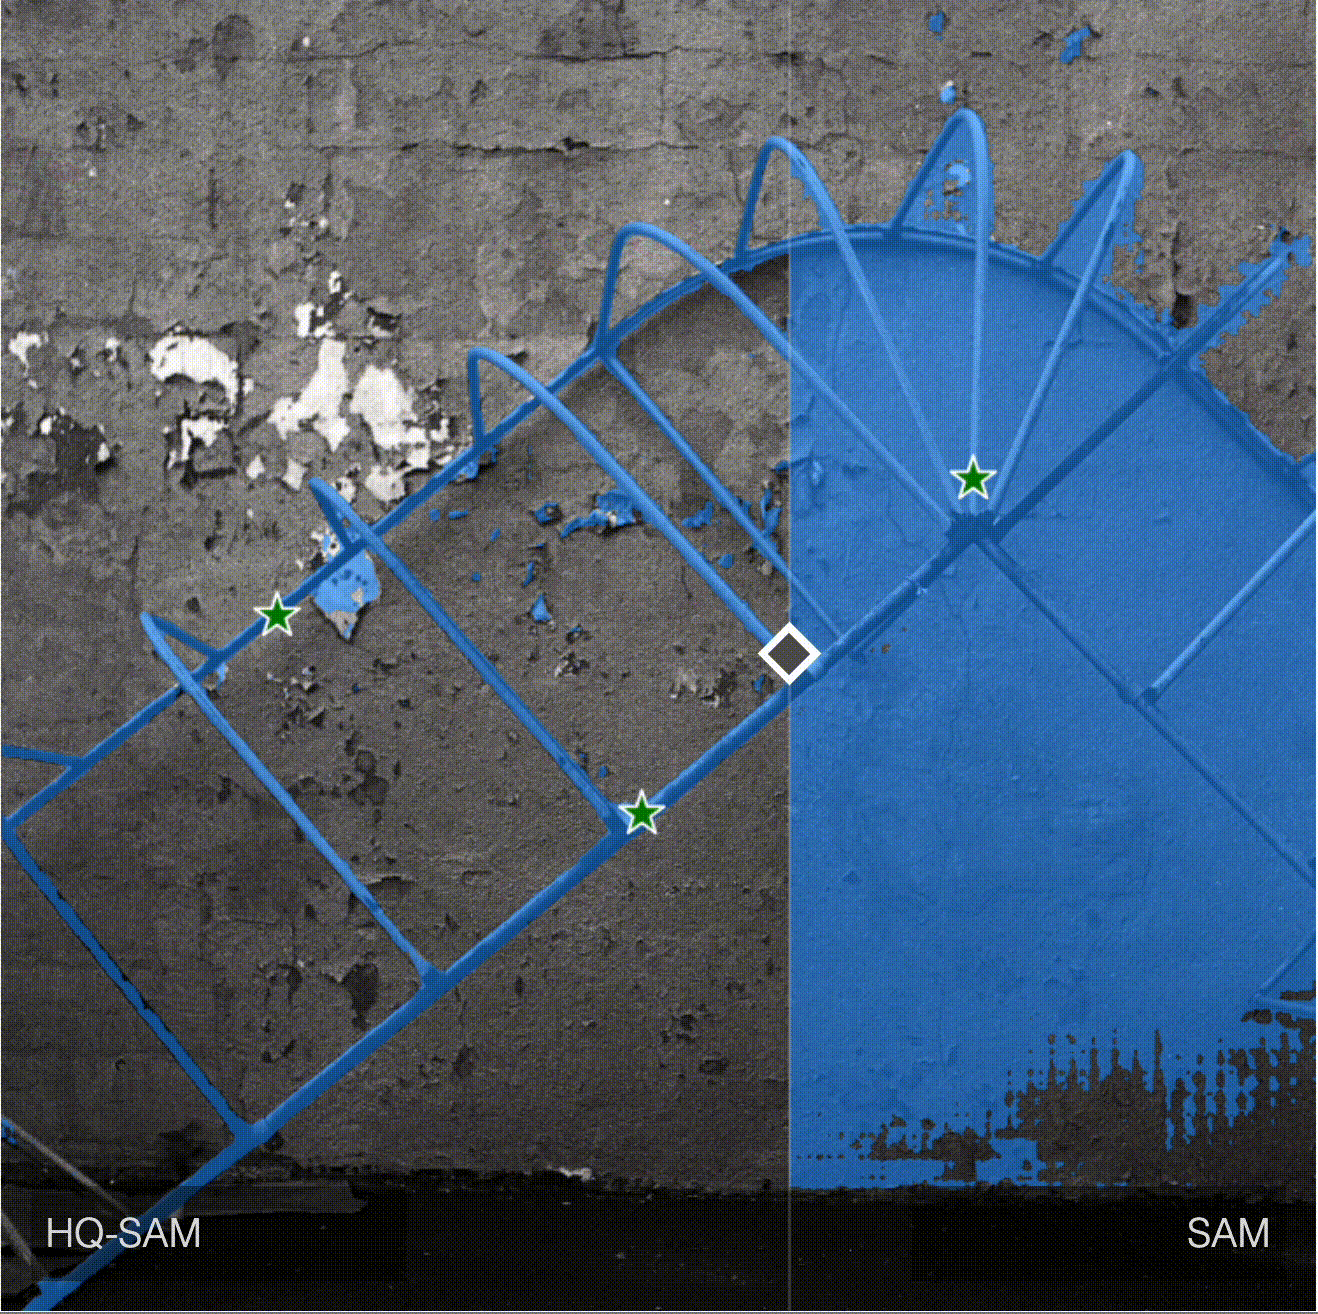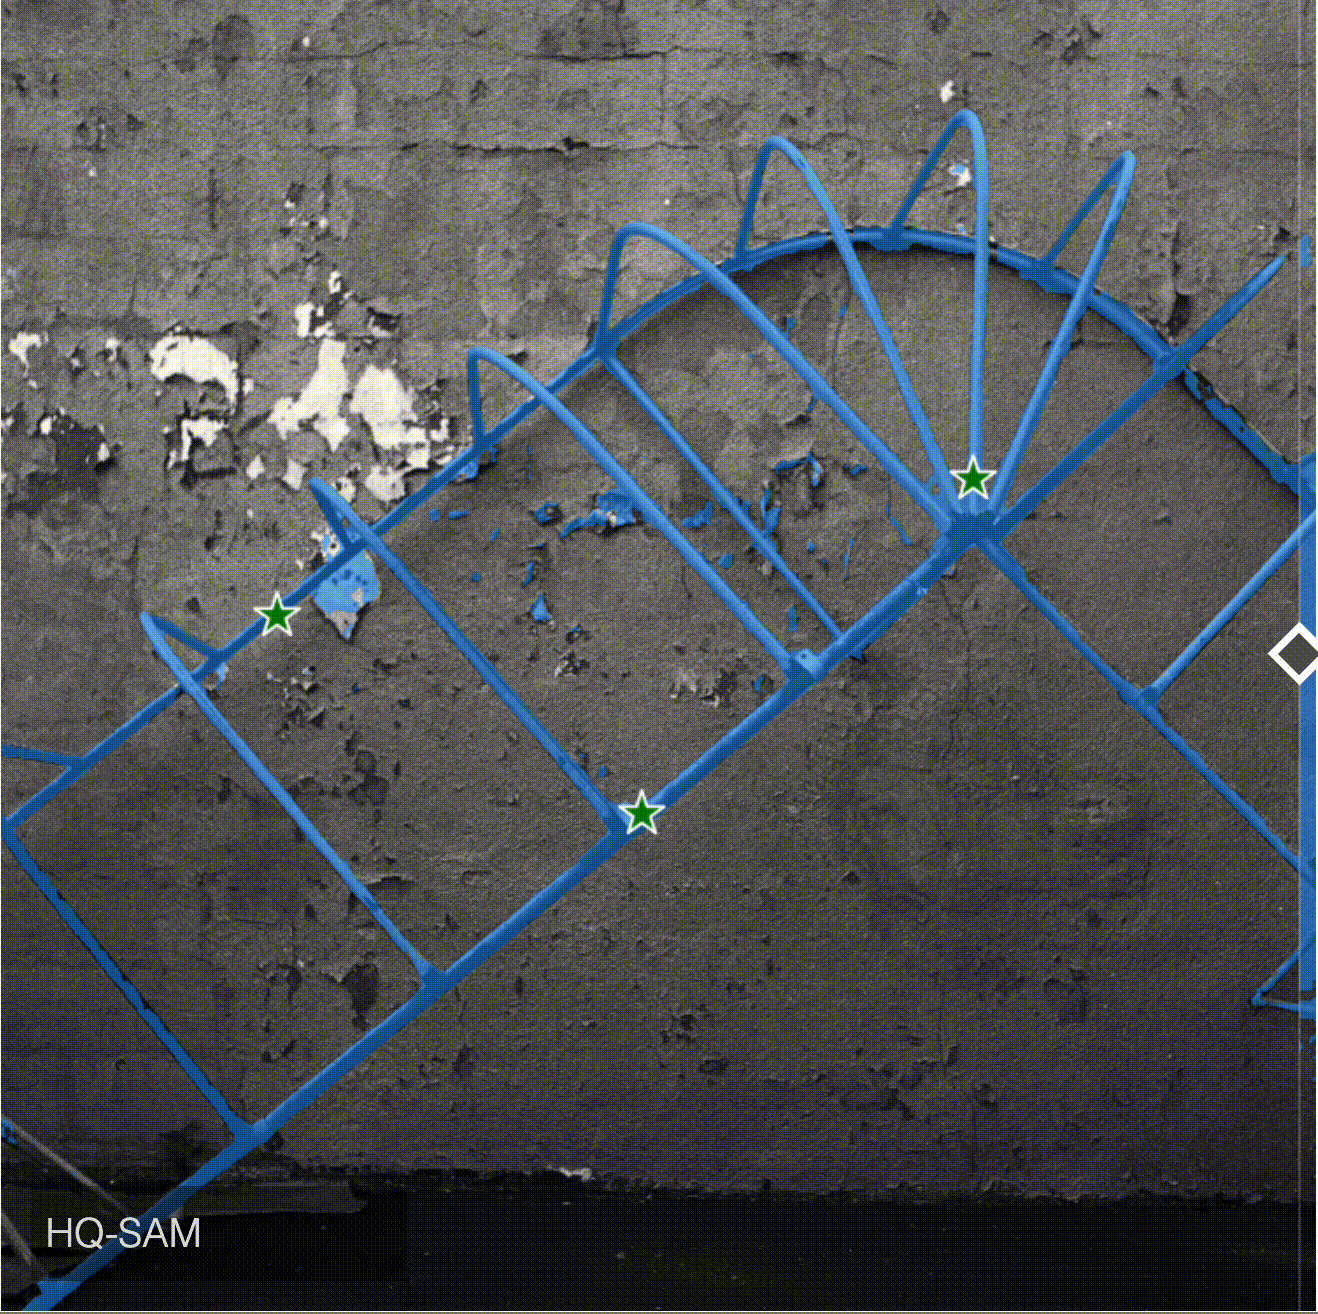
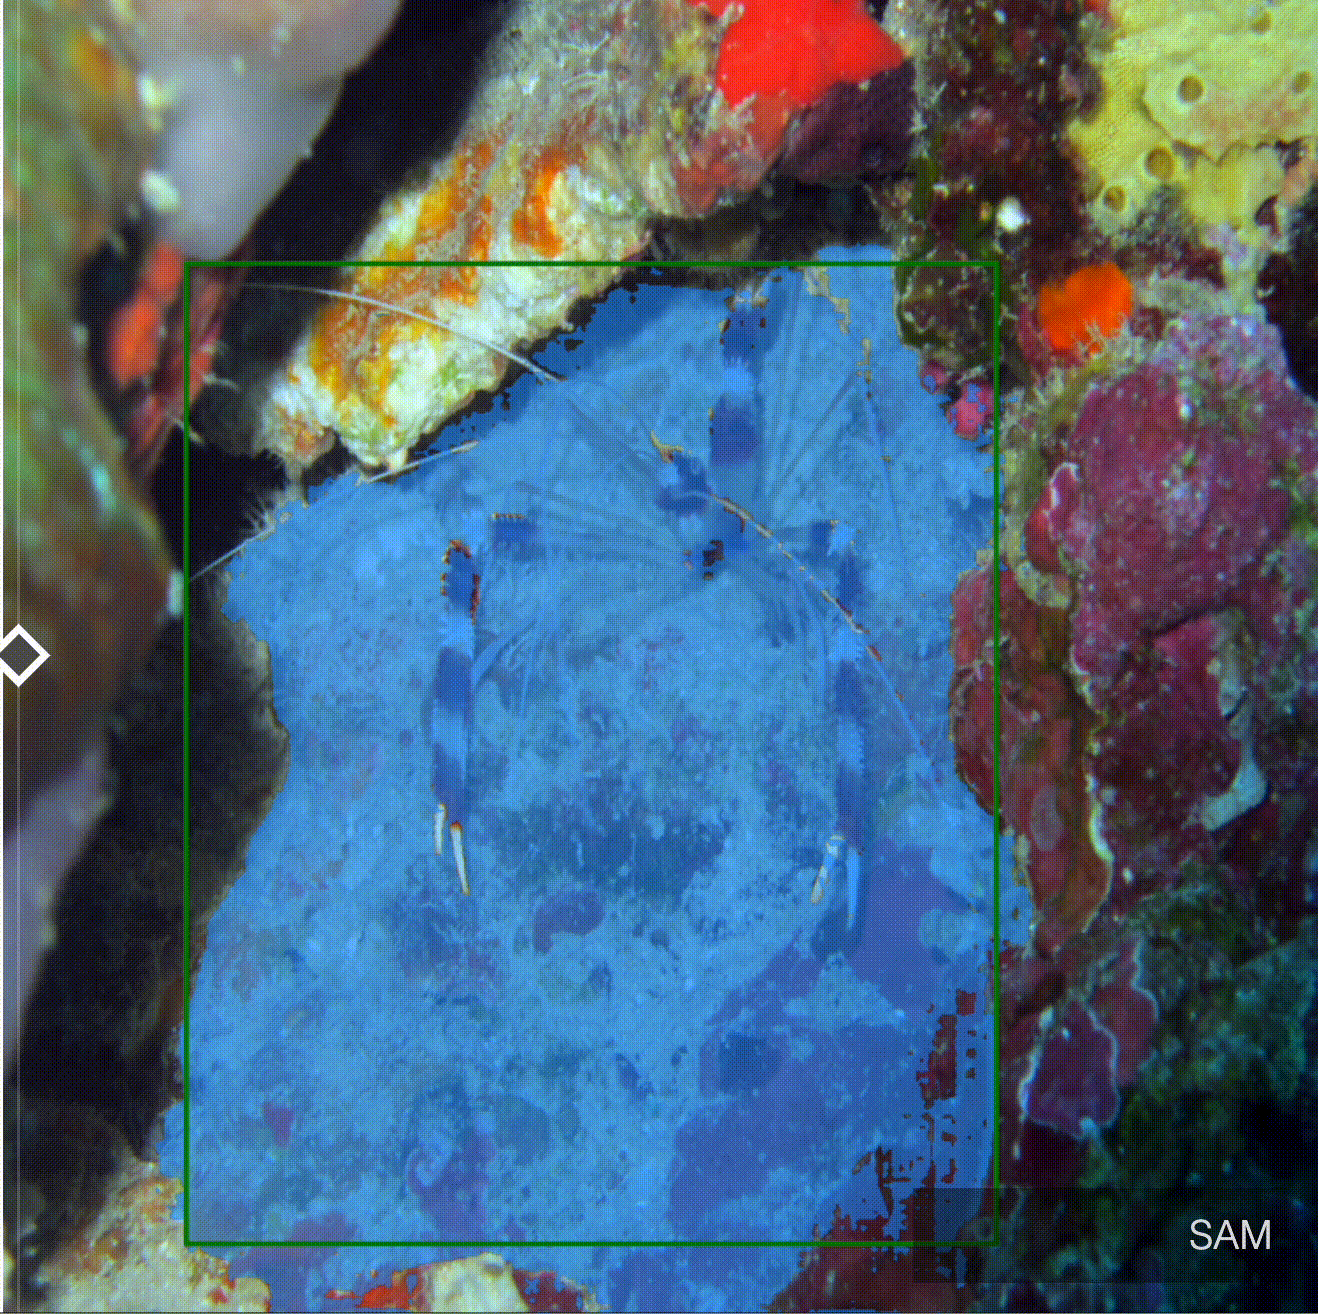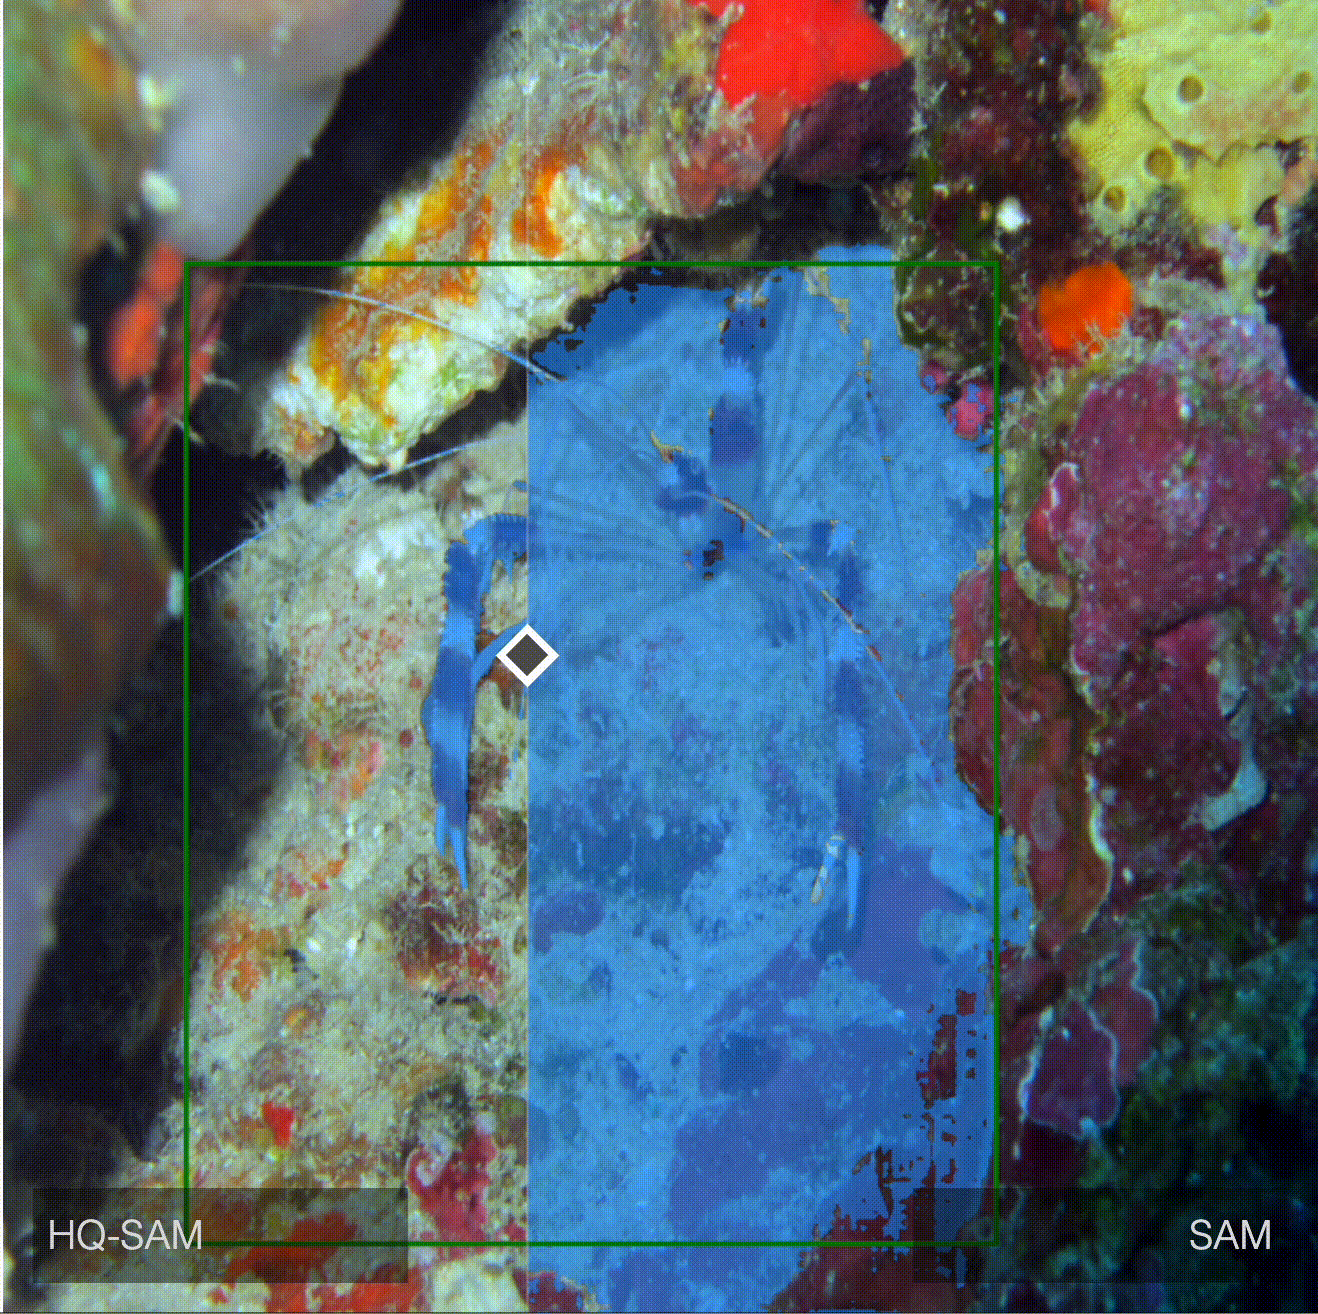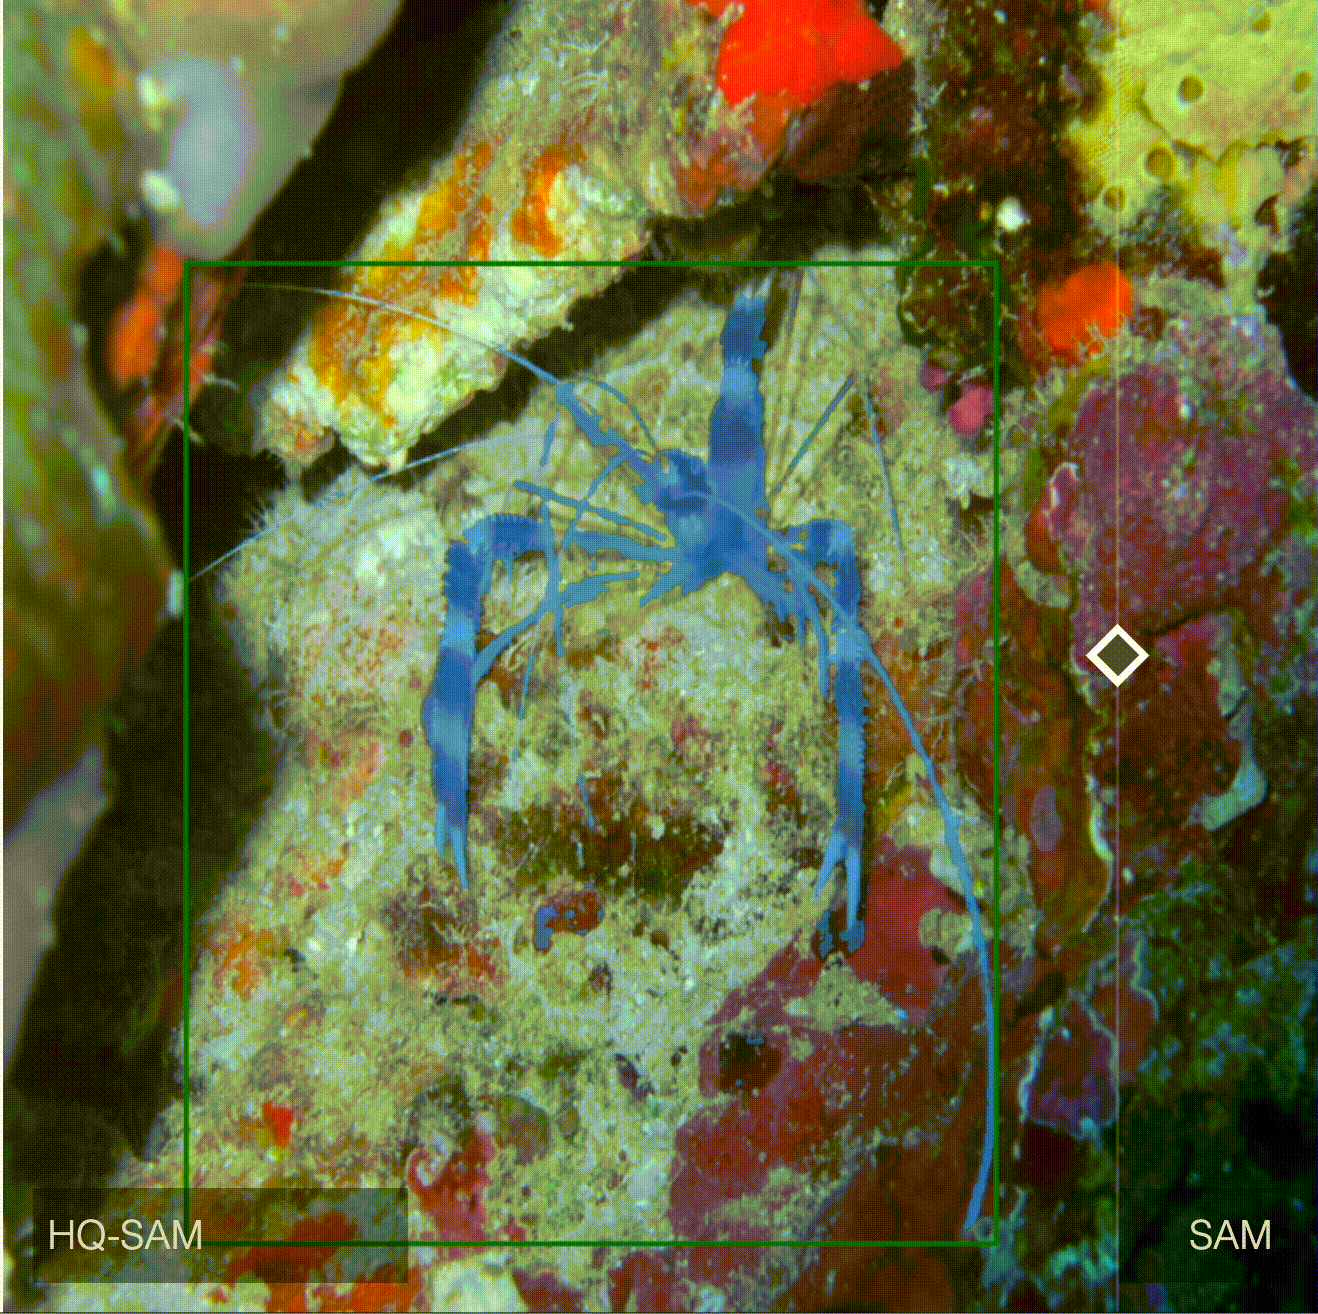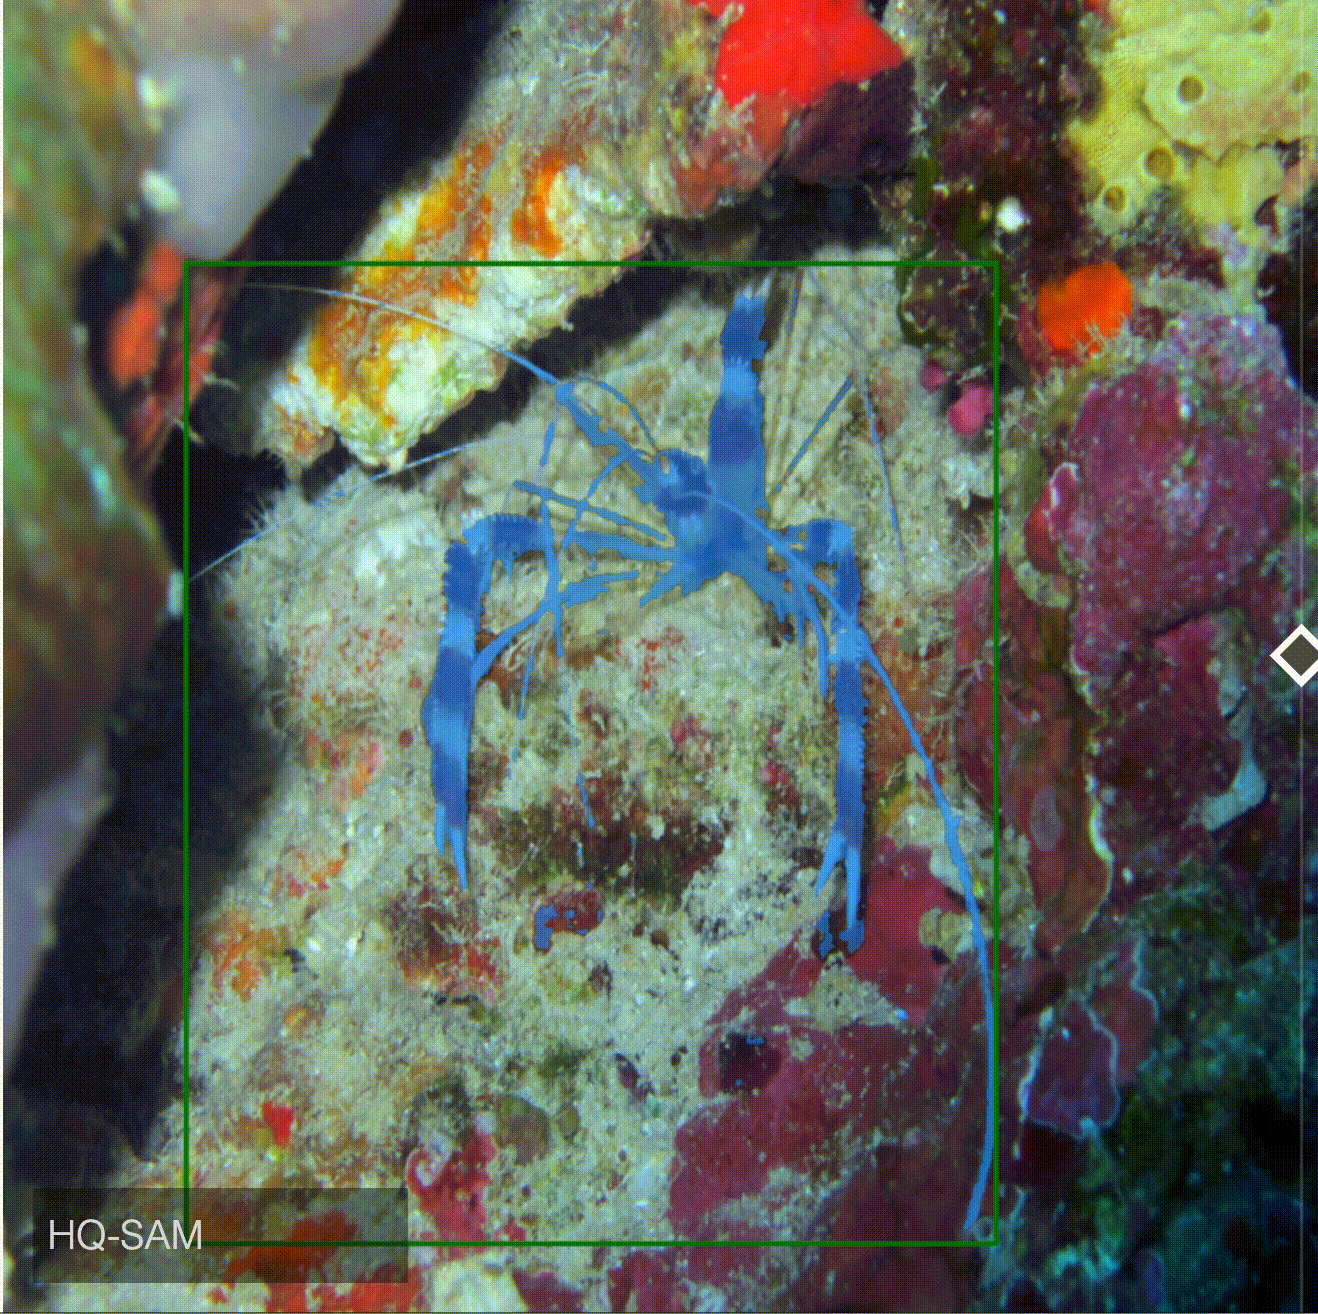
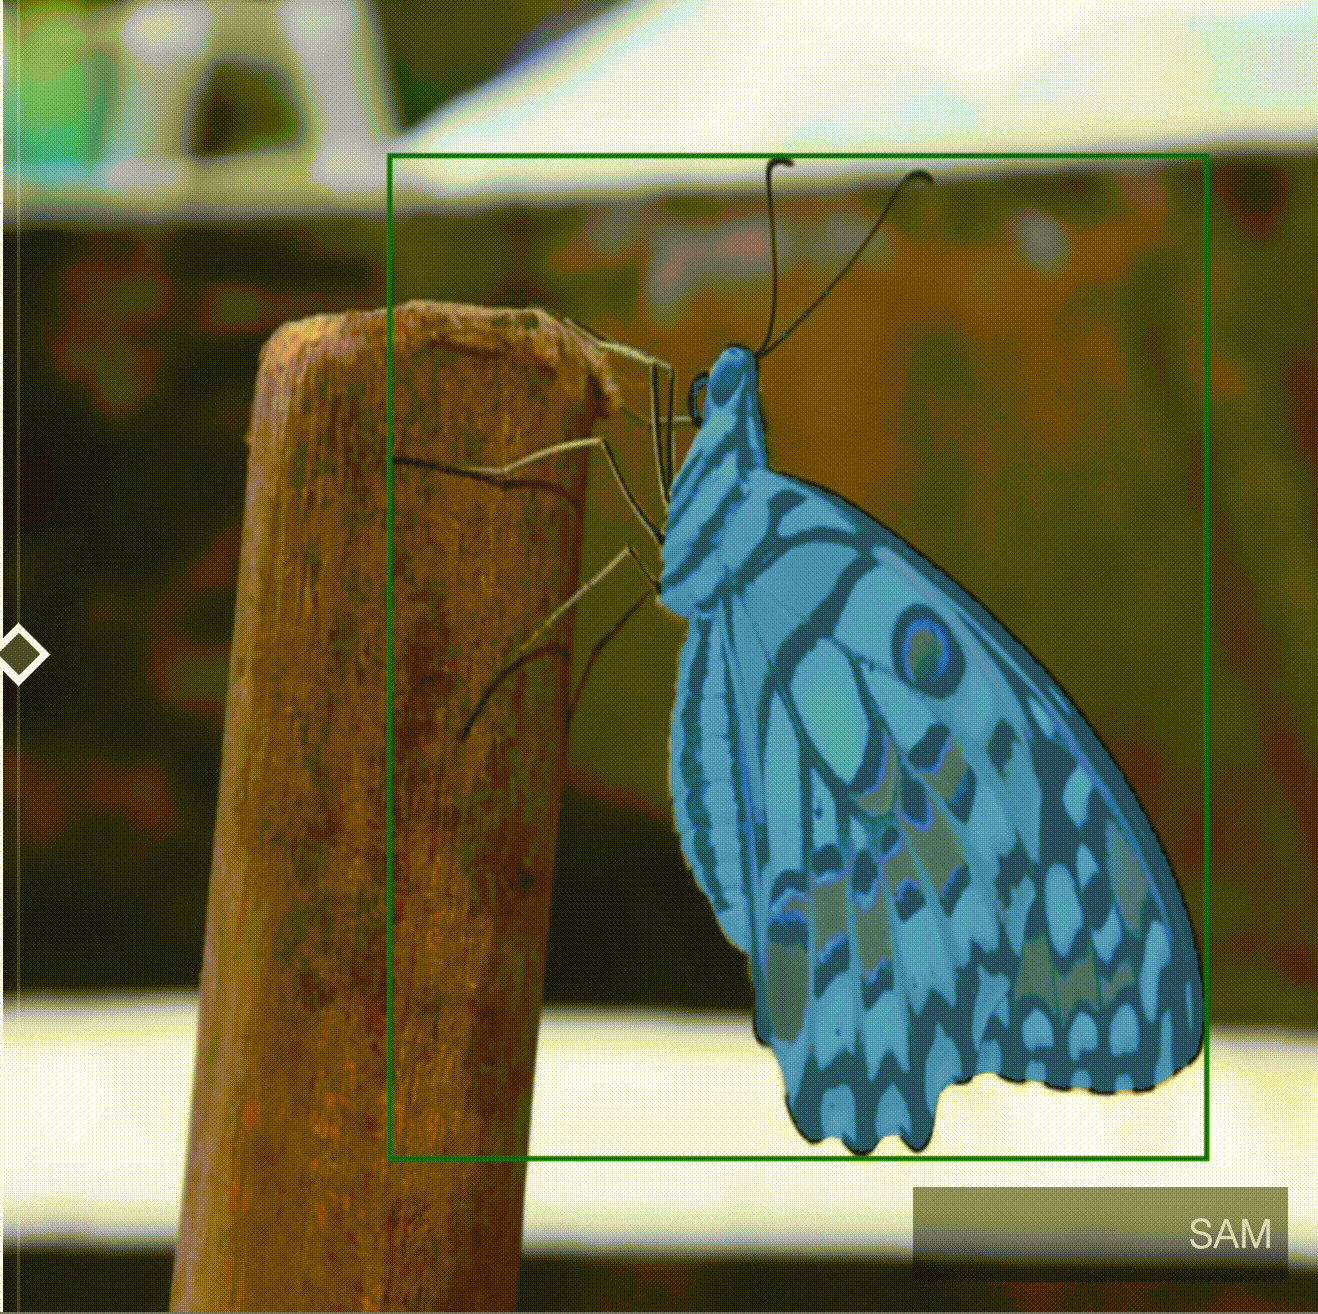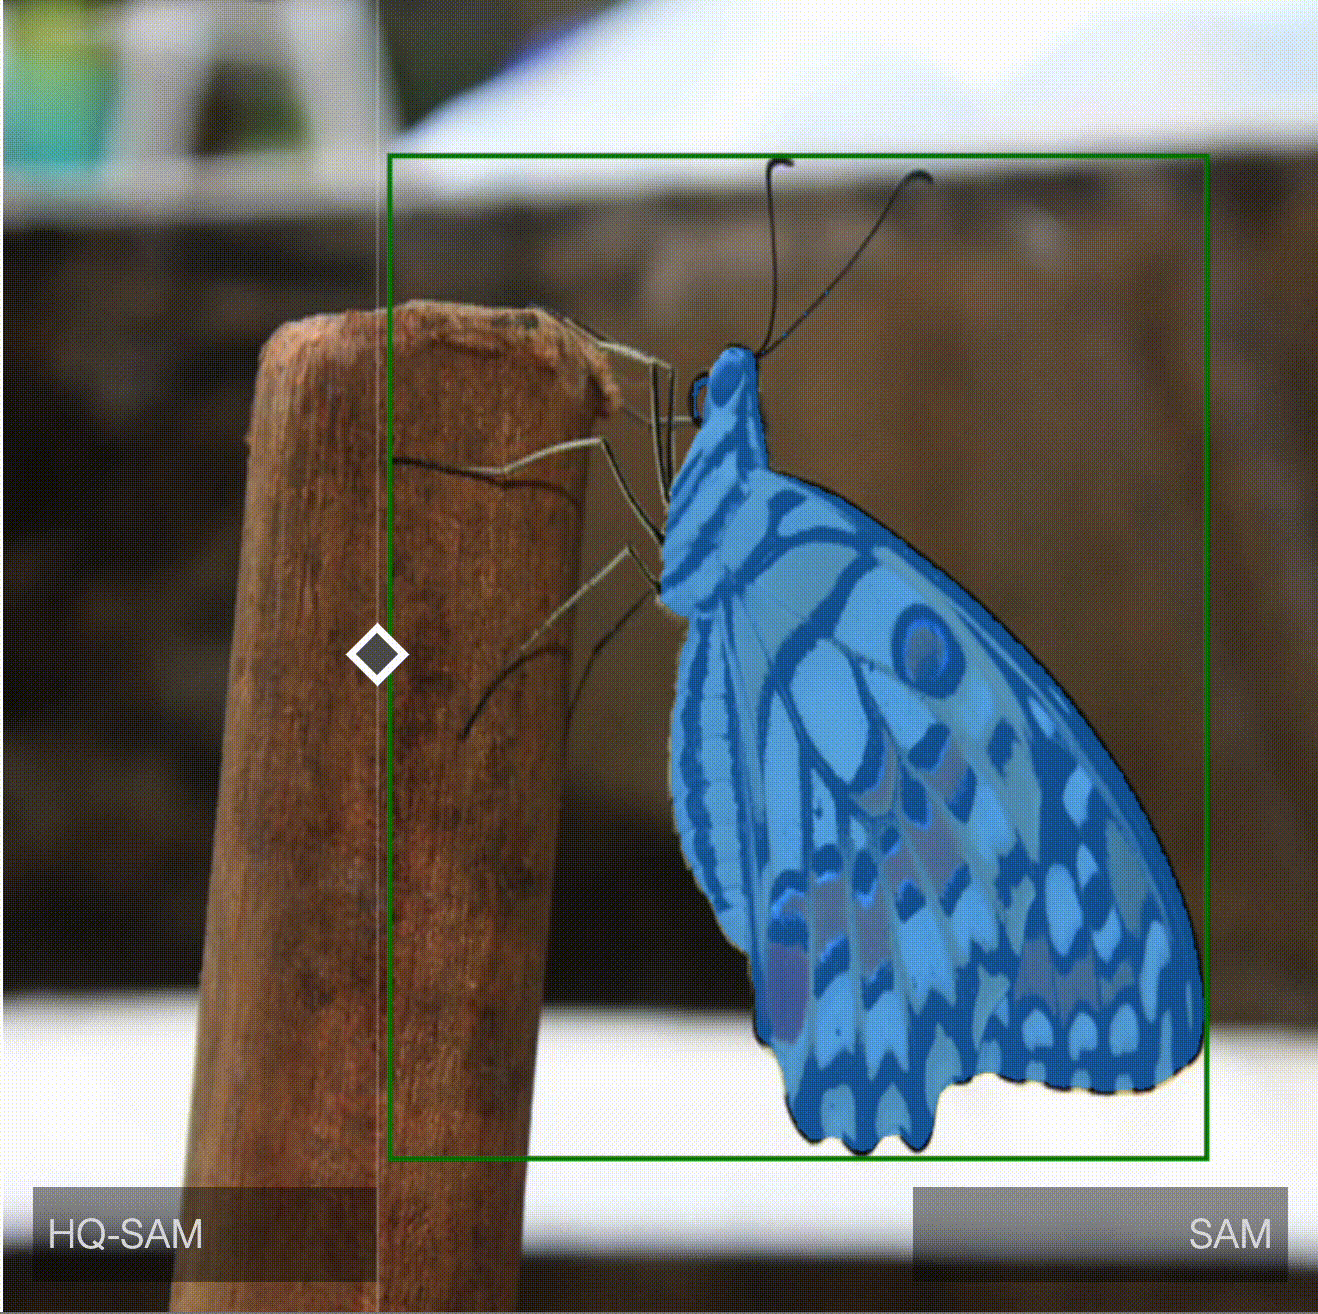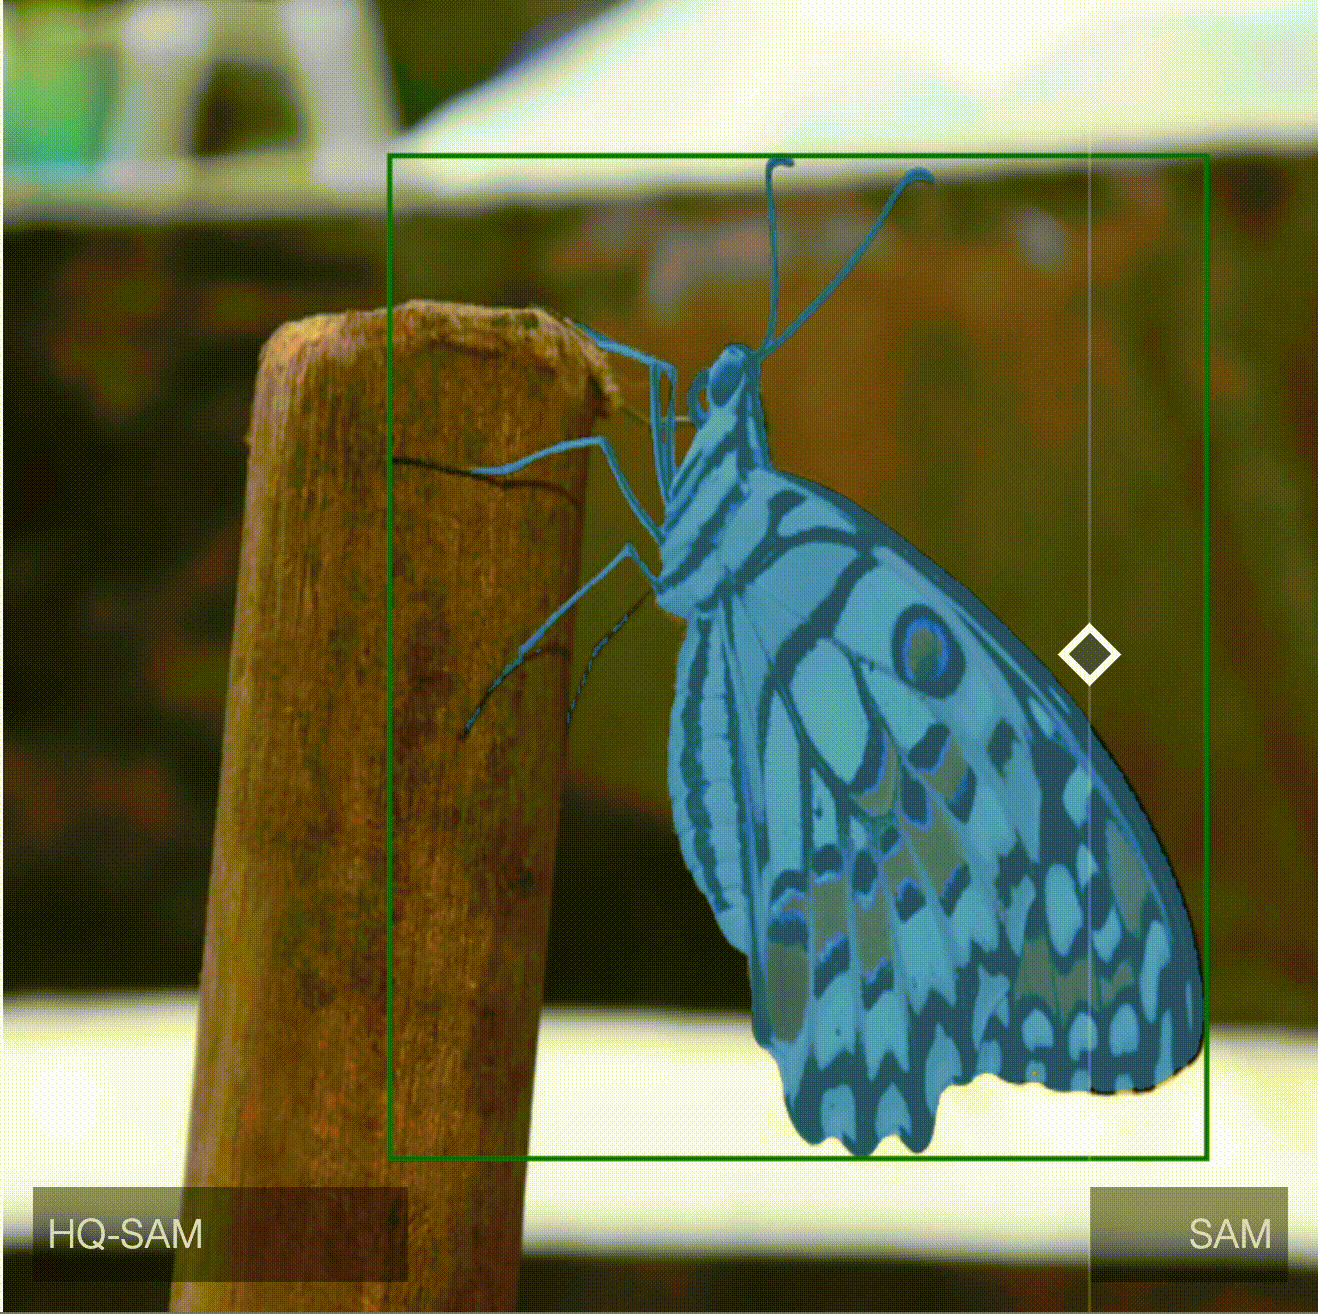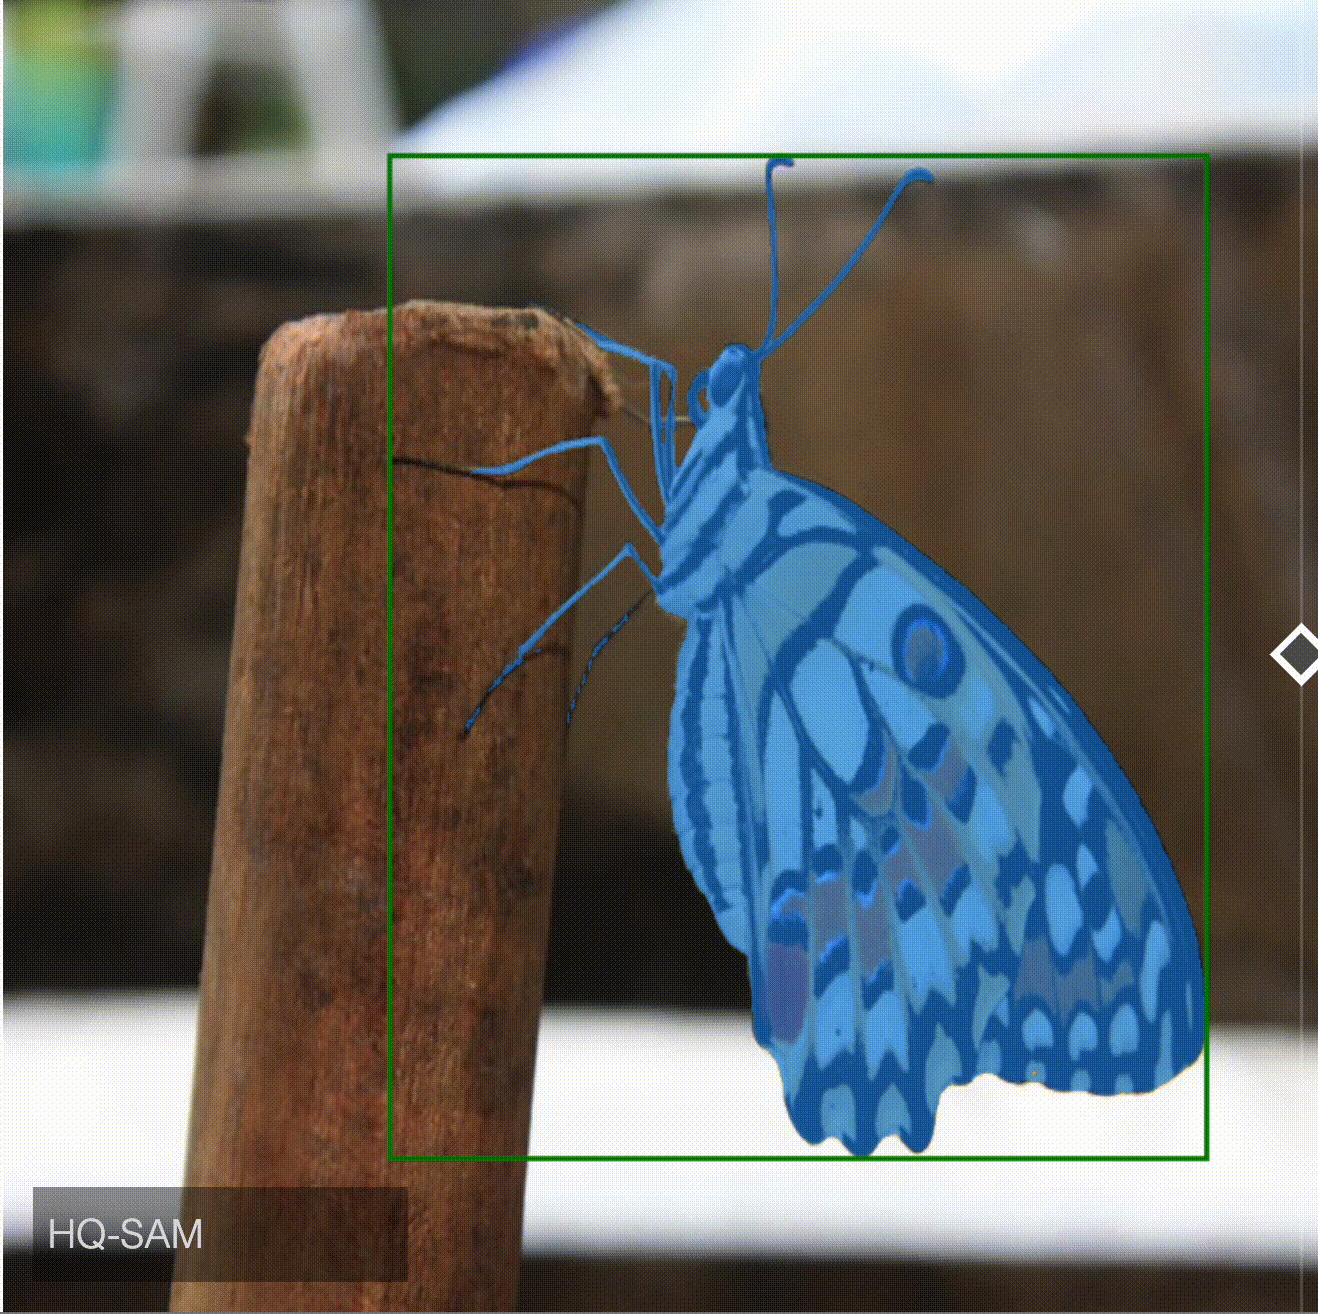
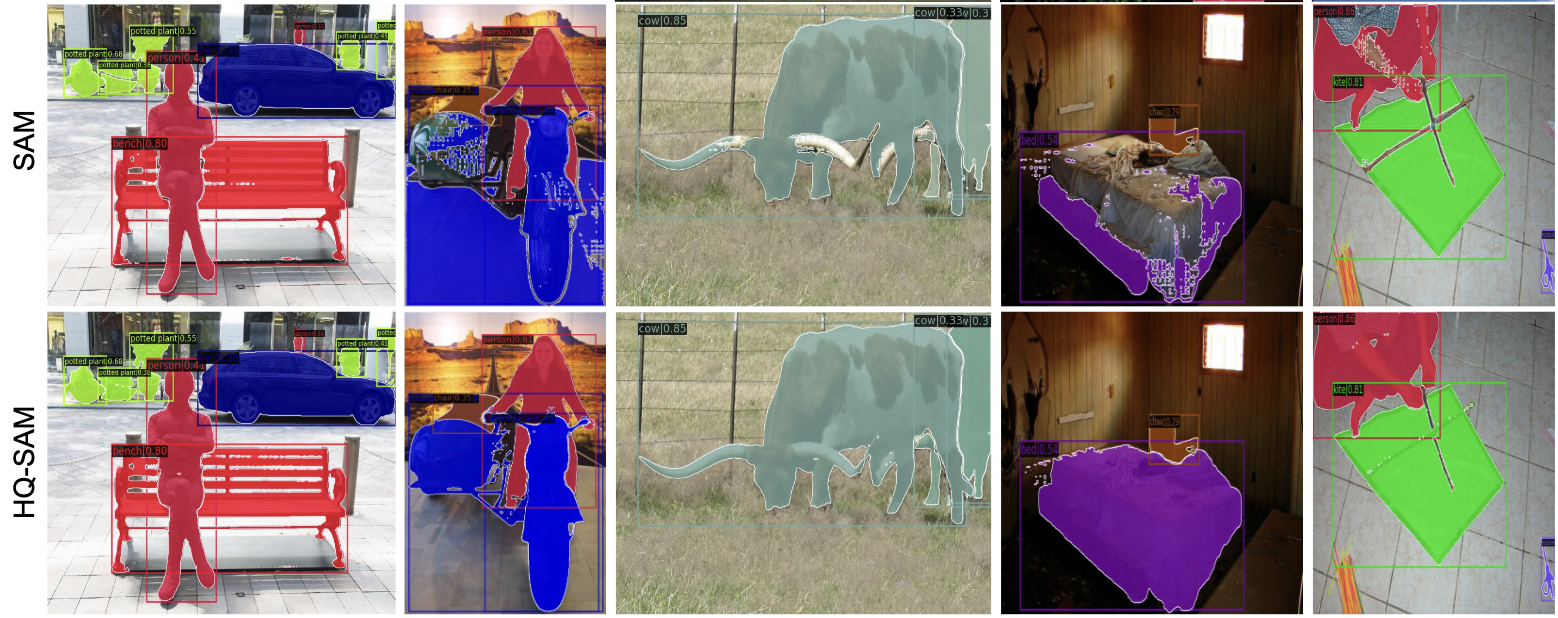
Visual comparison between SAM and HQ-SAM
SAM vs. HQ-SAM
 |
 |
 |
 |
 |
 |
Introduction
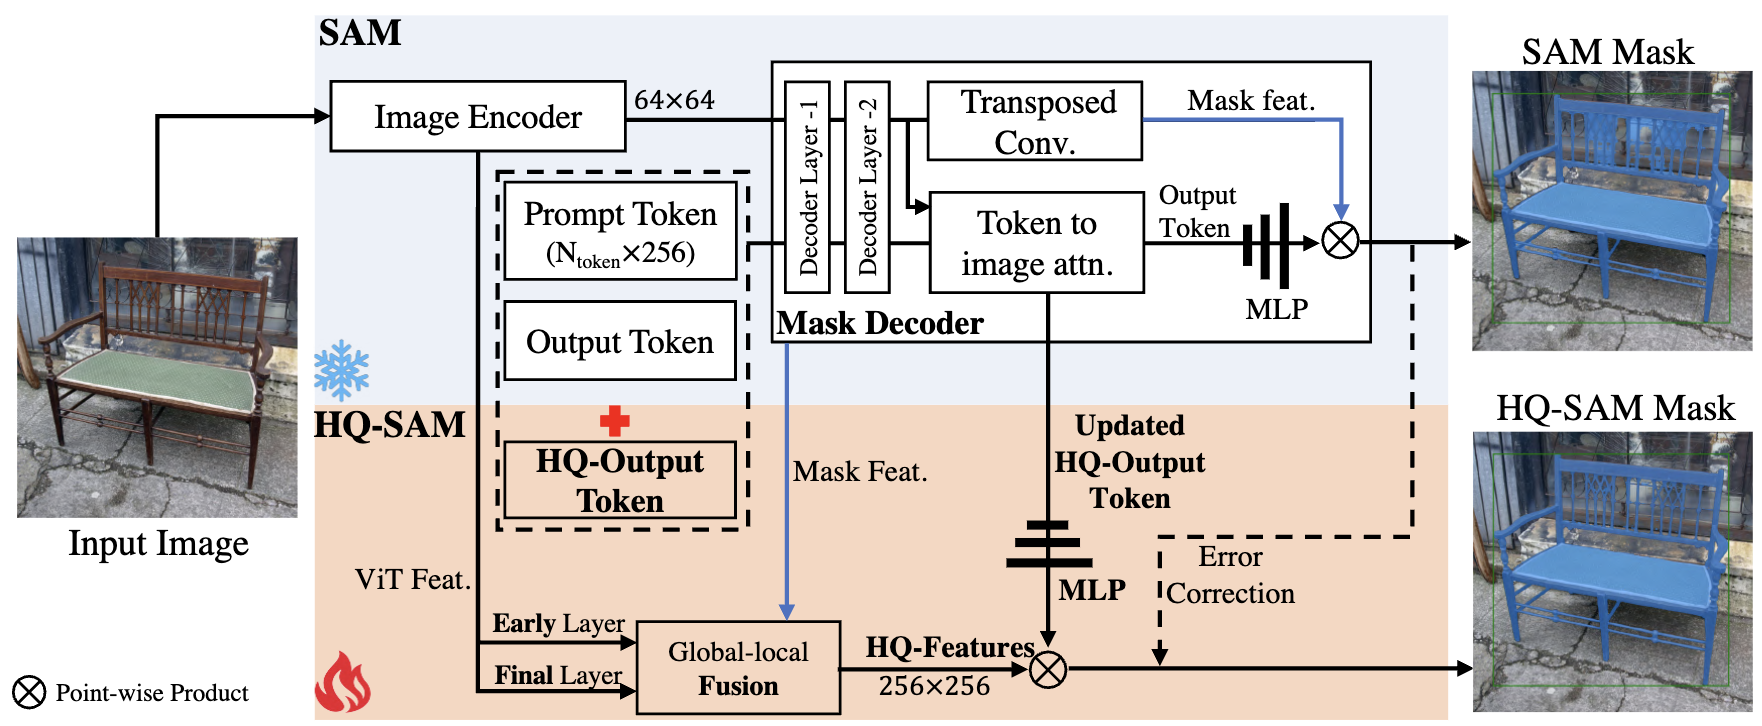
The recent Segment Anything Model (SAM) represents a big leap in scaling up segmentation models, allowing for powerful zero-shot capabilities and flexible prompting. Despite being trained with 1.1 billion masks, SAM's mask prediction quality falls short in many cases, particularly when dealing with objects that have intricate structures. We propose HQ-SAM, equipping SAM with the ability to accurately segment any object, while maintaining SAM's original promptable design, efficiency, and zero-shot generalizability. Our careful design reuses and preserves the pre-trained model weights of SAM, while only introducing minimal additional parameters and computation. We design a learnable High-Quality Output Token, which is injected into SAM's mask decoder and is responsible for predicting the high-quality mask. Instead of only applying it on mask-decoder features, we first fuse them with early and final ViT features for improved mask details. To train our introduced learnable parameters, we compose a dataset of 44K fine-grained masks from several sources. HQ-SAM is only trained on the introduced detaset of 44k masks, which takes only 4 hours on 8 GPUs. We show the efficacy of HQ-SAM in a suite of 9 diverse segmentation datasets across different downstream tasks, where 7 out of them are evaluated in a zero-shot transfer protocol.
Quantitative comparison between SAM and HQ-SAM
Note: For box-prompting-based evaluation, we feed SAM, MobileSAM and our HQ-SAM with the same image/video bounding boxes and adopt the single mask output mode of SAM.
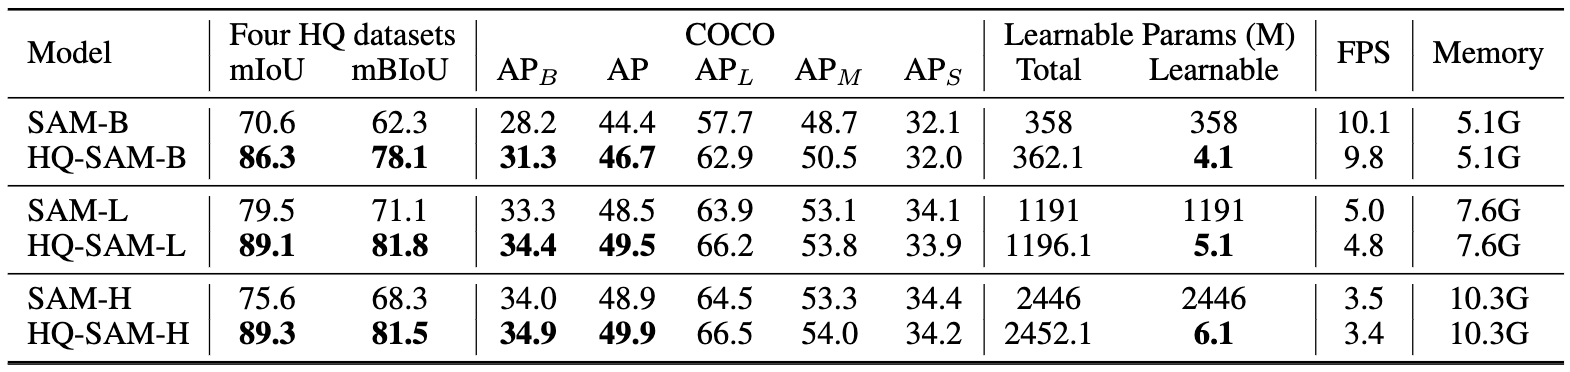
We provide comprehensive performance, model size and speed comparison on SAM variants:
Various ViT backbones on COCO:
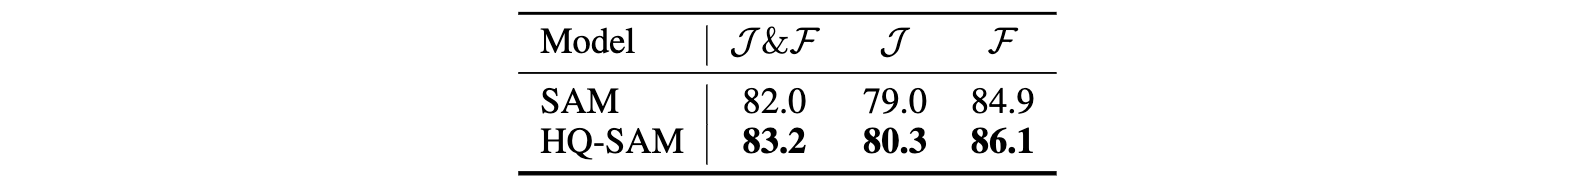
YTVIS and HQ-YTVIS
Note:Using ViT-L backbone. We adopt the SOTA detector Mask2Former trained on the YouTubeVIS 2019 dataset as our video boxes prompt generator while reusing its object association prediction.

DAVIS
Note: Using ViT-L backbone. We adopt the SOTA model XMem as our video boxes prompt generator while reusing its object association prediction.
Interactive segmentation comparison using various points
Note:Using ViT-L backbone. On the high-quality COIFT (zero-shot) and DIS val set.

Installation
The code requires python>=3.8, as well as pytorch>=1.7 and torchvision>=0.8. Please follow the instructions here to install both PyTorch and TorchVision dependencies. Installing both PyTorch and TorchVision with CUDA support is strongly recommended.
Clone the repository locally and install with
git clone https://github.com/SysCV/sam-hq.git
cd sam-hq; pip install -e .
The following optional dependencies are necessary for mask post-processing, saving masks in COCO format, the example notebooks, and exporting the model in ONNX format. jupyter is also required to run the example notebooks.
pip install opencv-python pycocotools matplotlib onnxruntime onnx timm
Example conda environment setup
conda create --name sam_hq python=3.8 -y
conda activate sam_hq
conda install pytorch==1.10.0 torchvision==0.11.0 cudatoolkit=11.1 -c pytorch -c nvidia
pip install opencv-python pycocotools matplotlib onnxruntime onnx timm

# under your working directory
git clone https://github.com/SysCV/sam-hq.git
cd sam-hq
pip install -e .
export PYTHONPATH=$(pwd)
Model Checkpoints
Three HQ-SAM model versions of the model are available with different backbone sizes. These models can be instantiated by running
from segment_anything import sam_model_registry
sam = sam_model_registry["<model_type>"](checkpoint="<path/to/checkpoint>")
Download the provided trained model below and put them into the pretrained_checkpoint folder:
mkdir pretrained_checkpoint
Click the links below to download the checkpoint for the corresponding model type. We also provide alternative model downloading links here or at hugging face.
vit_b: ViT-B HQ-SAM model.vit_l: ViT-L HQ-SAM model.vit_h: ViT-H HQ-SAM model.vit_tiny(Light HQ-SAM for real-time need): ViT-Tiny HQ-SAM model.
Getting Started
First download a model checkpoint. Then the model can be used in just a few lines to get masks from a given prompt:
from segment_anything import SamPredictor, sam_model_registry
sam = sam_model_registry["<model_type>"](checkpoint="<path/to/checkpoint>")
predictor = SamPredictor(sam)
predictor.set_image(<your_image>)
masks, _, _ = predictor.predict(<input_prompts>)
Additionally, see the usage examples in our demo , colab notebook and automatic mask generator notebook.
To obtain HQ-SAM's visual result:
python demo/demo_hqsam.py
To obtain baseline SAM's visual result. Note that you need to download original SAM checkpoint from baseline-SAM-L model and put it into the pretrained_checkpoint folder.
python demo/demo_sam.py
To obtain Light HQ-SAM's visual result:
python demo/demo_hqsam_light.py
HQ-SAM Tuning and HQ-Seg44k Data
We provide detailed training, evaluation, visualization and data downloading instructions in HQ-SAM training. You can also replace our training data to obtain your own SAM in specific application domain (like medical, OCR and remote sensing).
Please change the current folder path to:
cd train
and then refer to detailed readme instruction.
Grounded HQ-SAM vs Grounded SAM on SegInW
Grounded HQ-SAM wins the first place🥇 on SegInW benchmark (consist of 25 public zero-shot in the wild segmentation datasets), and outpuerforming Grounded SAM using the same grounding-dino detector.
| Model Name | Encoder | GroundingDINO | Mean AP | Evaluation Script | Log | Output Json |
|---|---|---|---|---|---|---|
| Grounded SAM | vit-h | swin-b | 48.7 | script | log | result |
| Grounded HQ-SAM | vit-h | swin-b | 49.6 | script | log | result |
Please change the current folder path to:
cd seginw
We provide detailed evaluation instructions and metrics on SegInW in Grounded-HQ-SAM evaluation.
Light HQ-SAM vs MobileSAM on COCO
We propose Light HQ-SAM based on the tiny vit image encoder provided by MobileSAM. We provide quantitative comparison on zero-shot COCO performance, speed and memory below. Try Light HQ-SAM at here.
| Model | Encoder | AP | AP@L | AP@M | AP@S | Model Params (MB) | FPS | Memory (GB) |
|---|---|---|---|---|---|---|---|---|
| MobileSAM | TinyViT | 44.3 | 61.8 | 48.1 | 28.8 | 38.6 | 44.8 | 3.7 |
| Light HQ-SAM | TinyViT | 45.0 | 62.8 | 48.8 | 29.2 | 40.3 | 41.2 | 3.7 |
Note: For the COCO dataset, we use the same SOTA detector FocalNet-DINO trained on the COCO dataset as our and Mobile sam's box prompt generator.
ONNX export
HQ-SAM's lightweight mask decoder can be exported to ONNX format so that it can be run in any environment that supports ONNX runtime. Export the model with
python scripts/export_onnx_model.py --checkpoint <path/to/checkpoint> --model-type <model_type> --output <path/to/output>
See the example notebook for details on how to combine image preprocessing via HQ-SAM's backbone with mask prediction using the ONNX model. It is recommended to use the latest stable version of PyTorch for ONNX export.
Citation
If you find HQ-SAM useful in your research or refer to the provided baseline results, please star ⭐ this repository and consider citing 📝:
@article{sam_hq,
    title={Segment Anything in High Quality},
    author={Ke, Lei and Ye, Mingqiao and Danelljan, Martin and Liu, Yifan and Tai, Yu-Wing and Tang, Chi-Keung and Yu, Fisher},
    journal = {arXiv:2306.01567},
    year = {2023}
}
Acknowledgments
- Thanks SAM, Grounded SAM and MobileSAM for their public code and released models.
1 maintainer

Metadata
1 maintainer
Release files for segment-anything-hq 0.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| segment-anything-hq-0.3.tar.gz | 47.5 kB | Without provenance | Details for segment-anything-hq-0.3.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| segment_anything_hq-0.3-py3-none-any.whl | Python 3 | none | any | Details for segment_anything_hq-0.3-py3-none-any.whl |
Total release size: 100.5 kB
Release files / segment-anything-hq-0.3.tar.gz
| Download URL | segment-anything-hq-0.3.tar.gz |
|---|---|
| Size | 47.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fab190efcd9bcf02a52cc13a628b40745aa5aeb75da1ce9e9b919b13a0206836
|
|
BLAKE2b-256 checksum How to use checksums |
84fd437afe8dd6d3f149f65615a879f3f99803308b89b0f1d9e0704b0052ea79
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.16
|
Release files / segment_anything_hq-0.3-py3-none-any.whl
| Download URL | segment_anything_hq-0.3-py3-none-any.whl |
|---|---|
| Size | 53.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
722d6cb9157074f84d83144401216f0dd2ab1ca972a2d1c491c73b20d689d006
|
|
BLAKE2b-256 checksum How to use checksums |
ea7a08e037dc65a78aa6c3b433771cc18207a93f1b0380f0bda298c98cc5d7ea
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.16
|
Security for segment-anything-hq 0.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














