

Usage |
|
Release |
|
Development |
|
Miscellaneous |
|


Quick Links
Quick Start — Install and run your first experiment
What is SIERRA? — Overview and architecture
Features at a Glance — Supported platforms and capabilities
Why SIERRA? — Motivation and comparison with alternatives
Limitations — What SIERRA is not designed for
Citing — How to cite SIERRA in your research
Troubleshooting — Common issues and how to get help
Contributing — How to contribute to SIERRA
What is SIERRA?
Running large-scale computational experiments is mostly engineering: writing scripts, managing configuration files, wrangling outputs, and rebuilding the same pipeline for every new project.
SIERRA automates this entire workflow.
SIERRA (reSearch pIpEline for Reproducibility, Reusability, and Automation) is a command-line tool and plugin framework that automates the full experimental workflow — generating experiment inputs, executing experiments across heterogeneous computing environments, processing results, and producing analysis artifacts such as plots, videos, and comparative summaries.
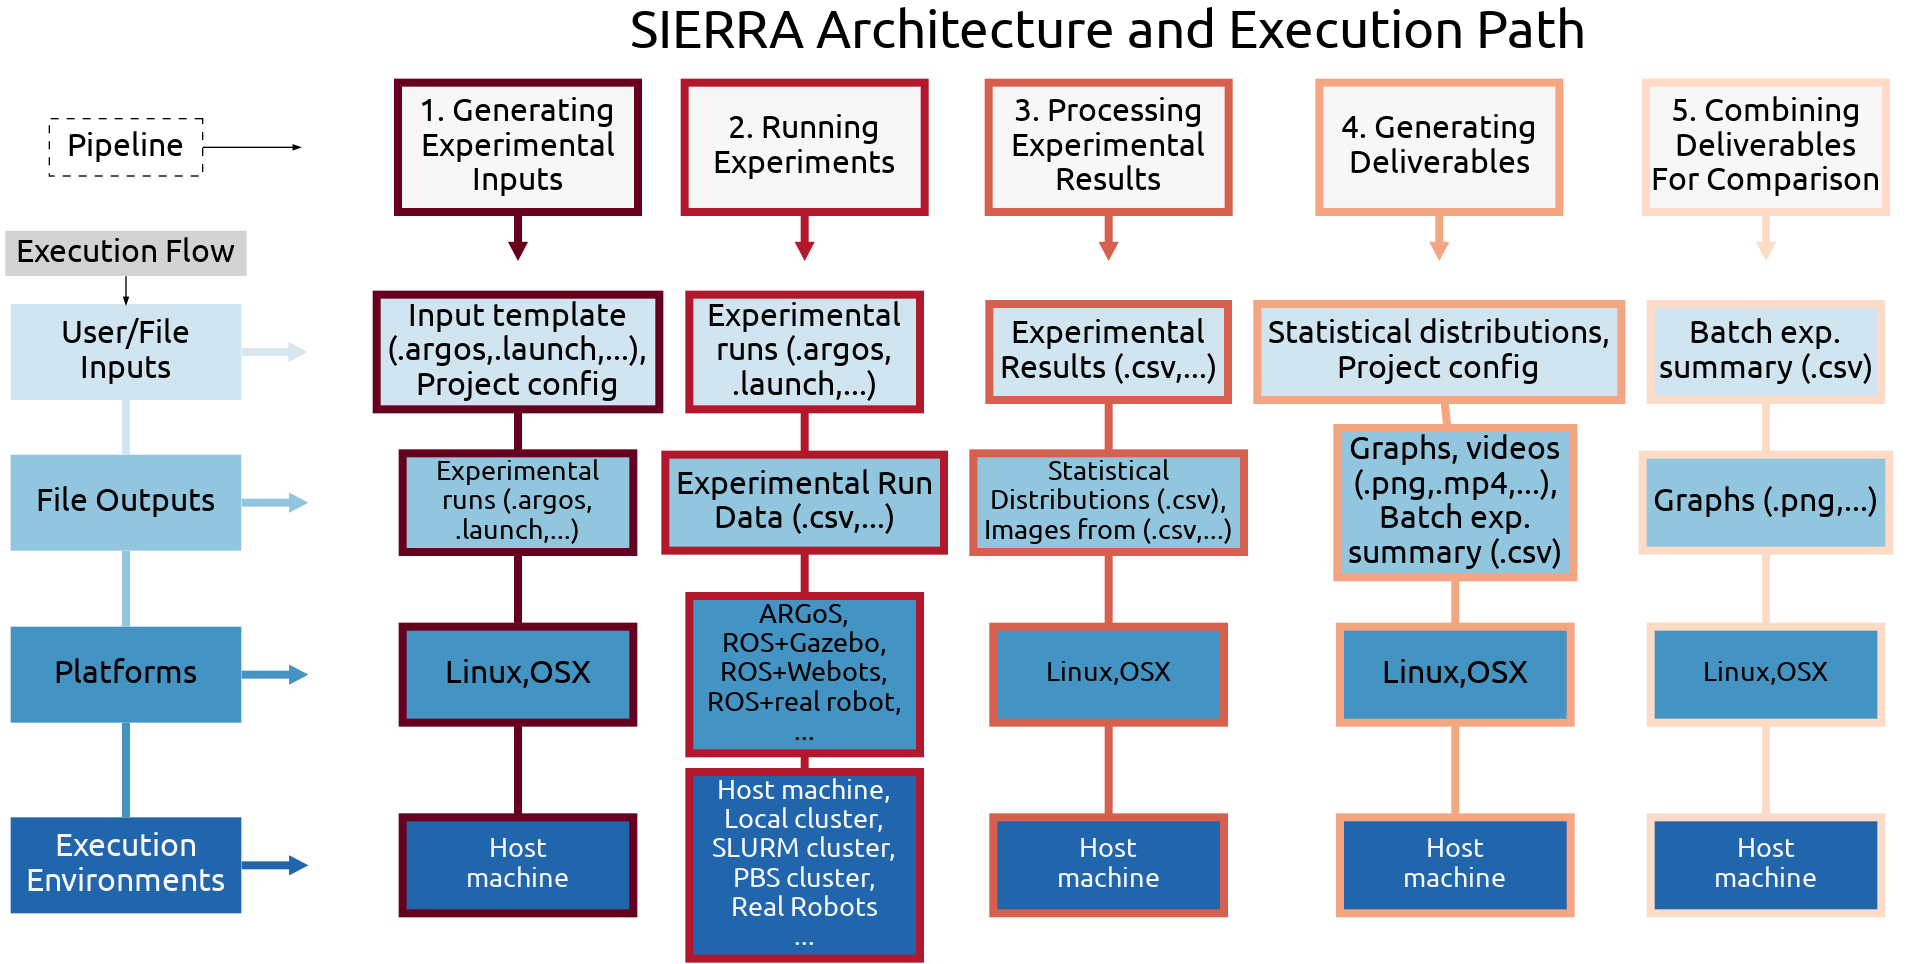
SIERRA architecture, organized by pipeline stage (left to right).
Pipeline Stages
SIERRA organizes experiments into a fixed pipeline:
Input generation — Create experiment configurations from templates
Execution — Run experiments locally, on clusters, etc.
Postprocessing — Parse raw outputs into structured datasets
Product generation — Generate plots, summaries, and derived artifacts
SIERRA is built around three design goals:
Reproducibility — every result is fully described by its path on disk, which encodes the project, controller, scenario, and batch criteria used to produce it. Re-running the same invocation always produces the same layout.
Automation — experiment generation, execution, post-processing, and product generation are handled by the pipeline; no scripting required.
Reusability — the plugin architecture means a project written for one simulator or execution environment requires minimal changes to run on another.
Features at a Glance
All categories below are extensible via plugins.
Feature |
Details |
|---|---|
Supported simulators |
ARGoS, ROS1+Gazebo, ROS1+Robot |
Execution environments |
Local machine, HPC clusters (SLURM, PBS), AWS Batch, Prefect server |
Parameter sweeps |
Numeric, categorical, or mixed combinations |
Output formats |
CSV, Arrow, GraphML, graphs (PNG, HTML), video (mp4) |
Model framework |
Overlay analytical models on empirical results |
Reproducibility |
Fully archived, citable experiment configurations |
Python version |
3.9+ |
Quick Start
Install:
pip3 install sierra-researchMinimal Example
Run a small parameter sweep locally using the built-in sample project.
sierra \
  --sierra-root=$HOME/exp \
  --project=sierra_sample_project \
  --platform=platform.argos \
  --exec-env=hpc.local \
  --template-input-file=exp/argos/template.argos \
  --scenario=LowBlockCount.10x10x1 \
  --batch-criteria population_size.Log8 \
  --n-runs=2 \
  --pipeline 1 2 3 4
This generates all experiment inputs, runs them locally, and processes results into graphs. See the getting started guide for a full walkthrough including expected output.
Why SIERRA?
SIERRA changes the paradigm of running experiments from manual and procedural to declarative and automated. Instead of:
"I need to write a script to run the experiment, another script to
process the data and a 3rd script to generate the graphs I want."
you describe:
"Here is the environment and/or simulator I want to use, the deliverables
I want to generate, and the data I want on them — GO."
SIERRA acts as a backend compiler for research: turning a description of what you want into a fully executed experiment with processed results.
Key advantages:
Deep parameter sweep support — numeric, categorical, or any combination thereof, with no boilerplate. A sweep that would require ~200 lines of brittle, non-reusable bash takes one SIERRA invocation.
Broad platform coverage — mix and match simulators (ARGoS, ROS1+Gazebo), execution environments (local, SLURM, PBS), and output formats with little to no code changes between them.
Maximum reusability — designed so that no copy-pasting is ever needed across projects or platforms.
Rich model framework — run analytical models, generate synthetic data, and overlay it on empirical results automatically on the same figure.
Research-domain focus — built for the scientific workflow, with native concepts for experiments, runs, batch criteria, and replication.
Why SIERRA over Prefect, Dagster, or Airflow?
General-purpose workflow tools like Prefect, Dagster, and Airflow require you to build your own research pipeline from scratch. SIERRA provides a battle-tested pipeline with first-class support for the patterns that matter most in R&D: parameter sweeps, simulator integration, reproducible archiving, and model-vs-empirical comparison.
The trade-off: SIERRA is more opinionated and less feature-complete than those frameworks for general data engineering workloads. For most research use cases, that gap doesn’t matter.
Limitations
SIERRA is purpose-built for the scientific experiment workflow. It is not the right tool if:
You need a general-purpose DAG runner for arbitrary data engineering tasks — use Prefect, Dagster, or Airflow instead.
Your experiments are highly irregular and cannot be expressed as systematic variations on a template.
You need ROS2—ROS1 is supported; ROS2 support is planned.
If you are unsure whether SIERRA fits your use case, check the use cases page or open a discussion thread.
Citing
If you use SIERRA and have found it helpful, please cite the following paper:
@inproceedings{Harwell2022a-SIERRA,
author = {Harwell, John and Lowmanstone, London and Gini, Maria},
title = {SIERRA: A Modular Framework for Research Automation},
year = {2022},
isbn = {9781450392136},
publisher = {International Foundation for Autonomous Agents and Multiagent Systems},
booktitle = {Proceedings of the 21st International Conference on Autonomous Agents and Multiagent Systems},
pages = {1905–1907}
}
To cite a specific version of SIERRA (recommended for reproducibility), use the DOI badge in the Miscellaneous row of the badge table above.
Troubleshooting
If you encounter problems using SIERRA, please open an issue or post in the GitHub Discussions forum. Please include your SIERRA version, OS, and a minimal reproducible example where possible.
Contributing
Contributions of all sizes are welcome — bug fixes, documentation improvements, new plugins, or larger features.
A good first contribution is adding a storage plugin or a simple processor plugin — both are typically under 100 lines and have clear contracts defined in the plugin developer guide.
If you have an idea to discuss before diving in, open a discussion thread at any point. See the contributing guide for the full procedure.
1 maintainer

Release files for sierra-research 1.5.15
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| sierra_research-1.5.15.tar.gz | 11.2 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sierra_research-1.5.15-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 11.5 MB
Release files / sierra_research-1.5.15.tar.gz
| Download URL | sierra_research-1.5.15.tar.gz |
|---|---|
| Size | 11.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ef73a83c0fe2128f2a07b3d49873ee1ca6330136f83354abbbd2029a48ae7ee4
|
|
BLAKE2b-256 checksum How to use checksums |
9d415dba4bfca2a3b5d129dd897ee8fb92f9246ce9f4eb4bb02cfab161348705
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 9, 2026.
Transparency logRelease files / sierra_research-1.5.15-py3-none-any.whl
| Download URL | sierra_research-1.5.15-py3-none-any.whl |
|---|---|
| Size | 345.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5f35fbbf741e9719686026e30674cb9a917bac2598efde6b91bd4701c9d37f38
|
|
BLAKE2b-256 checksum How to use checksums |
9d424db67ef31a50481a63279a2a1077baaa5bc6f04debda75500c3bc29e4c2a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 9, 2026.
Transparency log













