
SMA Finder
SMA Finder is a tool for diagnosing spinal muscular atrophy (SMA) based on Illumina exome, genome, or targeted sequencing data.
It takes a reference sequence (FASTA) and 1 or more alignment files (CRAM or BAM) as input, evaluates reads at the
c.840 position of SMN1 and SMN2 to detect the most common molecular causes of SMA, and then reports whether it found a complete loss of SMN1.
It has been tested and confirmed to be highly accurate on short read data aligned to GRCh37, GRCh38, or T2T using the BWA aligner.
Limitations:
- does not report SMA carrier status or SMN1/SMN2 copy numbers
- does not detect the ~5% of cases caused by SMN1 loss-of-function mutations that do not involve the c.840 position
- requires at least 14 reads to overlap the c.840 position in SMN1 plus SMN2 in order to make a call
- was developed and tested on Illumina short read sequencing data generated from whole blood DNA and aligned using the BWA aligner. Performance on data from other sequencing technologies, sample types, and alignment pipelines is unknown.
Install
python3 -m pip install sma-finder
Example
Example command:
sma_finder --verbose --hg38-reference-fasta /ref/hg38.fa sample1.cram
Command output:
Input args:
    --hg38-reference-fasta: /ref/hg38.fa
    --output-tsv: sample1.sma_finder_results.tsv
    CRAMS or BAMS: sample1.cram
---
Output row #1:
        filename_prefix                     sample1
        file_type                           cram
        genome_version                      hg38
        sample_id                           s1
        sma_status                          has SMA
        confidence_score                    168
        c840_reads_with_smn1_base_C         0
        c840_total_reads                    174
Wrote 1 rows to sample1.sma_finder_results.tsv
Usage
Usage help text:
sma_finder --help

usage: sma_finder.py [-h] [--hg37-reference-fasta HG37_REFERENCE_FASTA]
                     [--hg38-reference-fasta HG38_REFERENCE_FASTA]
                     [--t2t-reference-fasta T2T_REFERENCE_FASTA]
                     [-o OUTPUT_TSV] [-v]
                     cram_or_bam_path [cram_or_bam_path ...]

positional arguments:
  cram_or_bam_path      One or more CRAM or BAM file paths

optional arguments:
  -h, --help            show this help message and exit
  --hg37-reference-fasta HG37_REFERENCE_FASTA
                        HG37 reference genome FASTA path. This should be
                        specified if the input bam or cram is aligned to HG37.
  --hg38-reference-fasta HG38_REFERENCE_FASTA
                        HG38 reference genome FASTA path. This should be
                        specified if the input bam or cram is aligned to HG38.
  --t2t-reference-fasta T2T_REFERENCE_FASTA
                        T2T reference genome FASTA path. This should be
                        specified if the input bam or cram is aligned to the
                        CHM13 telomere-to-telomere benchmark.
  -o OUTPUT_TSV, --output-tsv OUTPUT_TSV
                        Optional output tsv file path
  -v, --verbose         Whether to print extra details during the run
Output
The output .tsv contains one row per input CRAM or BAM file and has the following columns:
| filename_prefix | CRAM or BAM filename prefix. If the input file is /path/sample1.cram this would be "sample1". |
| file_type | "cram" or "bam" |
| genome_version | "hg37", "hg38", or "t2t" |
| sample_id | sample id from the CRAM or BAM file header (parsed from the read group metadata) |
| sma_status | possible values are: "has SMA" "does not have SMA" "not enough coverage at SMN c.840 position" |
| confidence_score | PHRED-scaled integer score measuring the level of confidence that the sma_status is correct. The bigger the score, the higher the confidence. It is calculated in a similar way to the PL field in GATK HaplotypeCaller genotypes. |
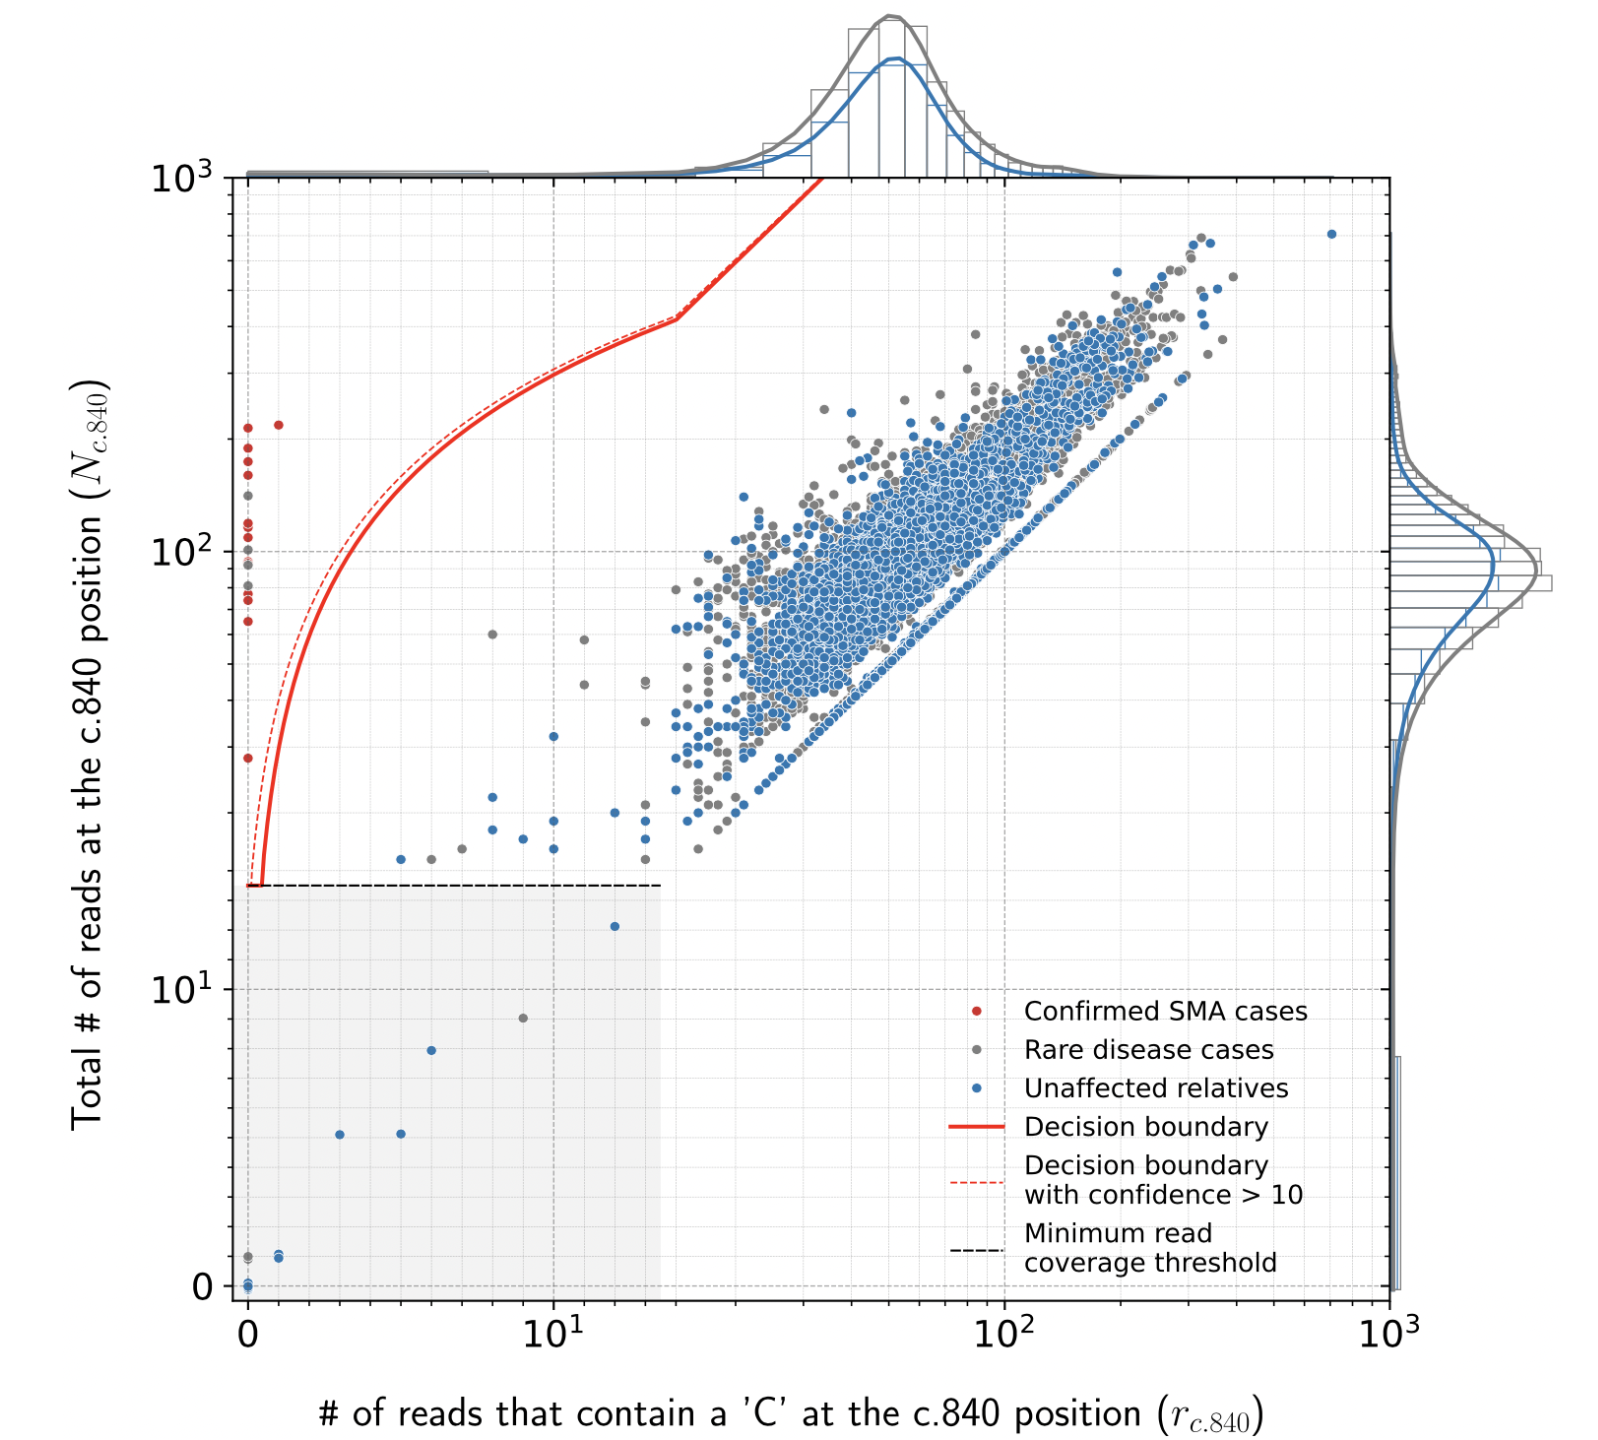
| c840_reads_with_smn1_base_C | number of reads that have a 'C' nucleotide at the c.840 position in SMN1 plus SMN2 |
| c840_total_reads | total number of reads overlapping the c.840 position in SMN1 plus SMN2 |
Combining results from multiple samples
After running SMA Finder on many samples, it often useful to combine the per-sample output tables into a single table. One way to do this is with the following shell command:
combined_table_filename=combined_results.tsv
head -n 1 $(ls *.tsv | head -n 1) > ${combined_table_filename}   # get table header from the 1st table
for i in *.tsv; do
    tail -n +2 $i >> ${combined_table_filename}    # concatenate all tables
done
Plotting combined results
A scatter plot summarizing read counts from many samples can be generated using the plot_SMN1_SMN2_scatter command:
python3 plot_SMN1_SMN2_scatter.py --format svg --format png ${combined_table_filename}
It generates plots like this one which is based on a neuromuscular cohort with 16,626 exomes:
Details
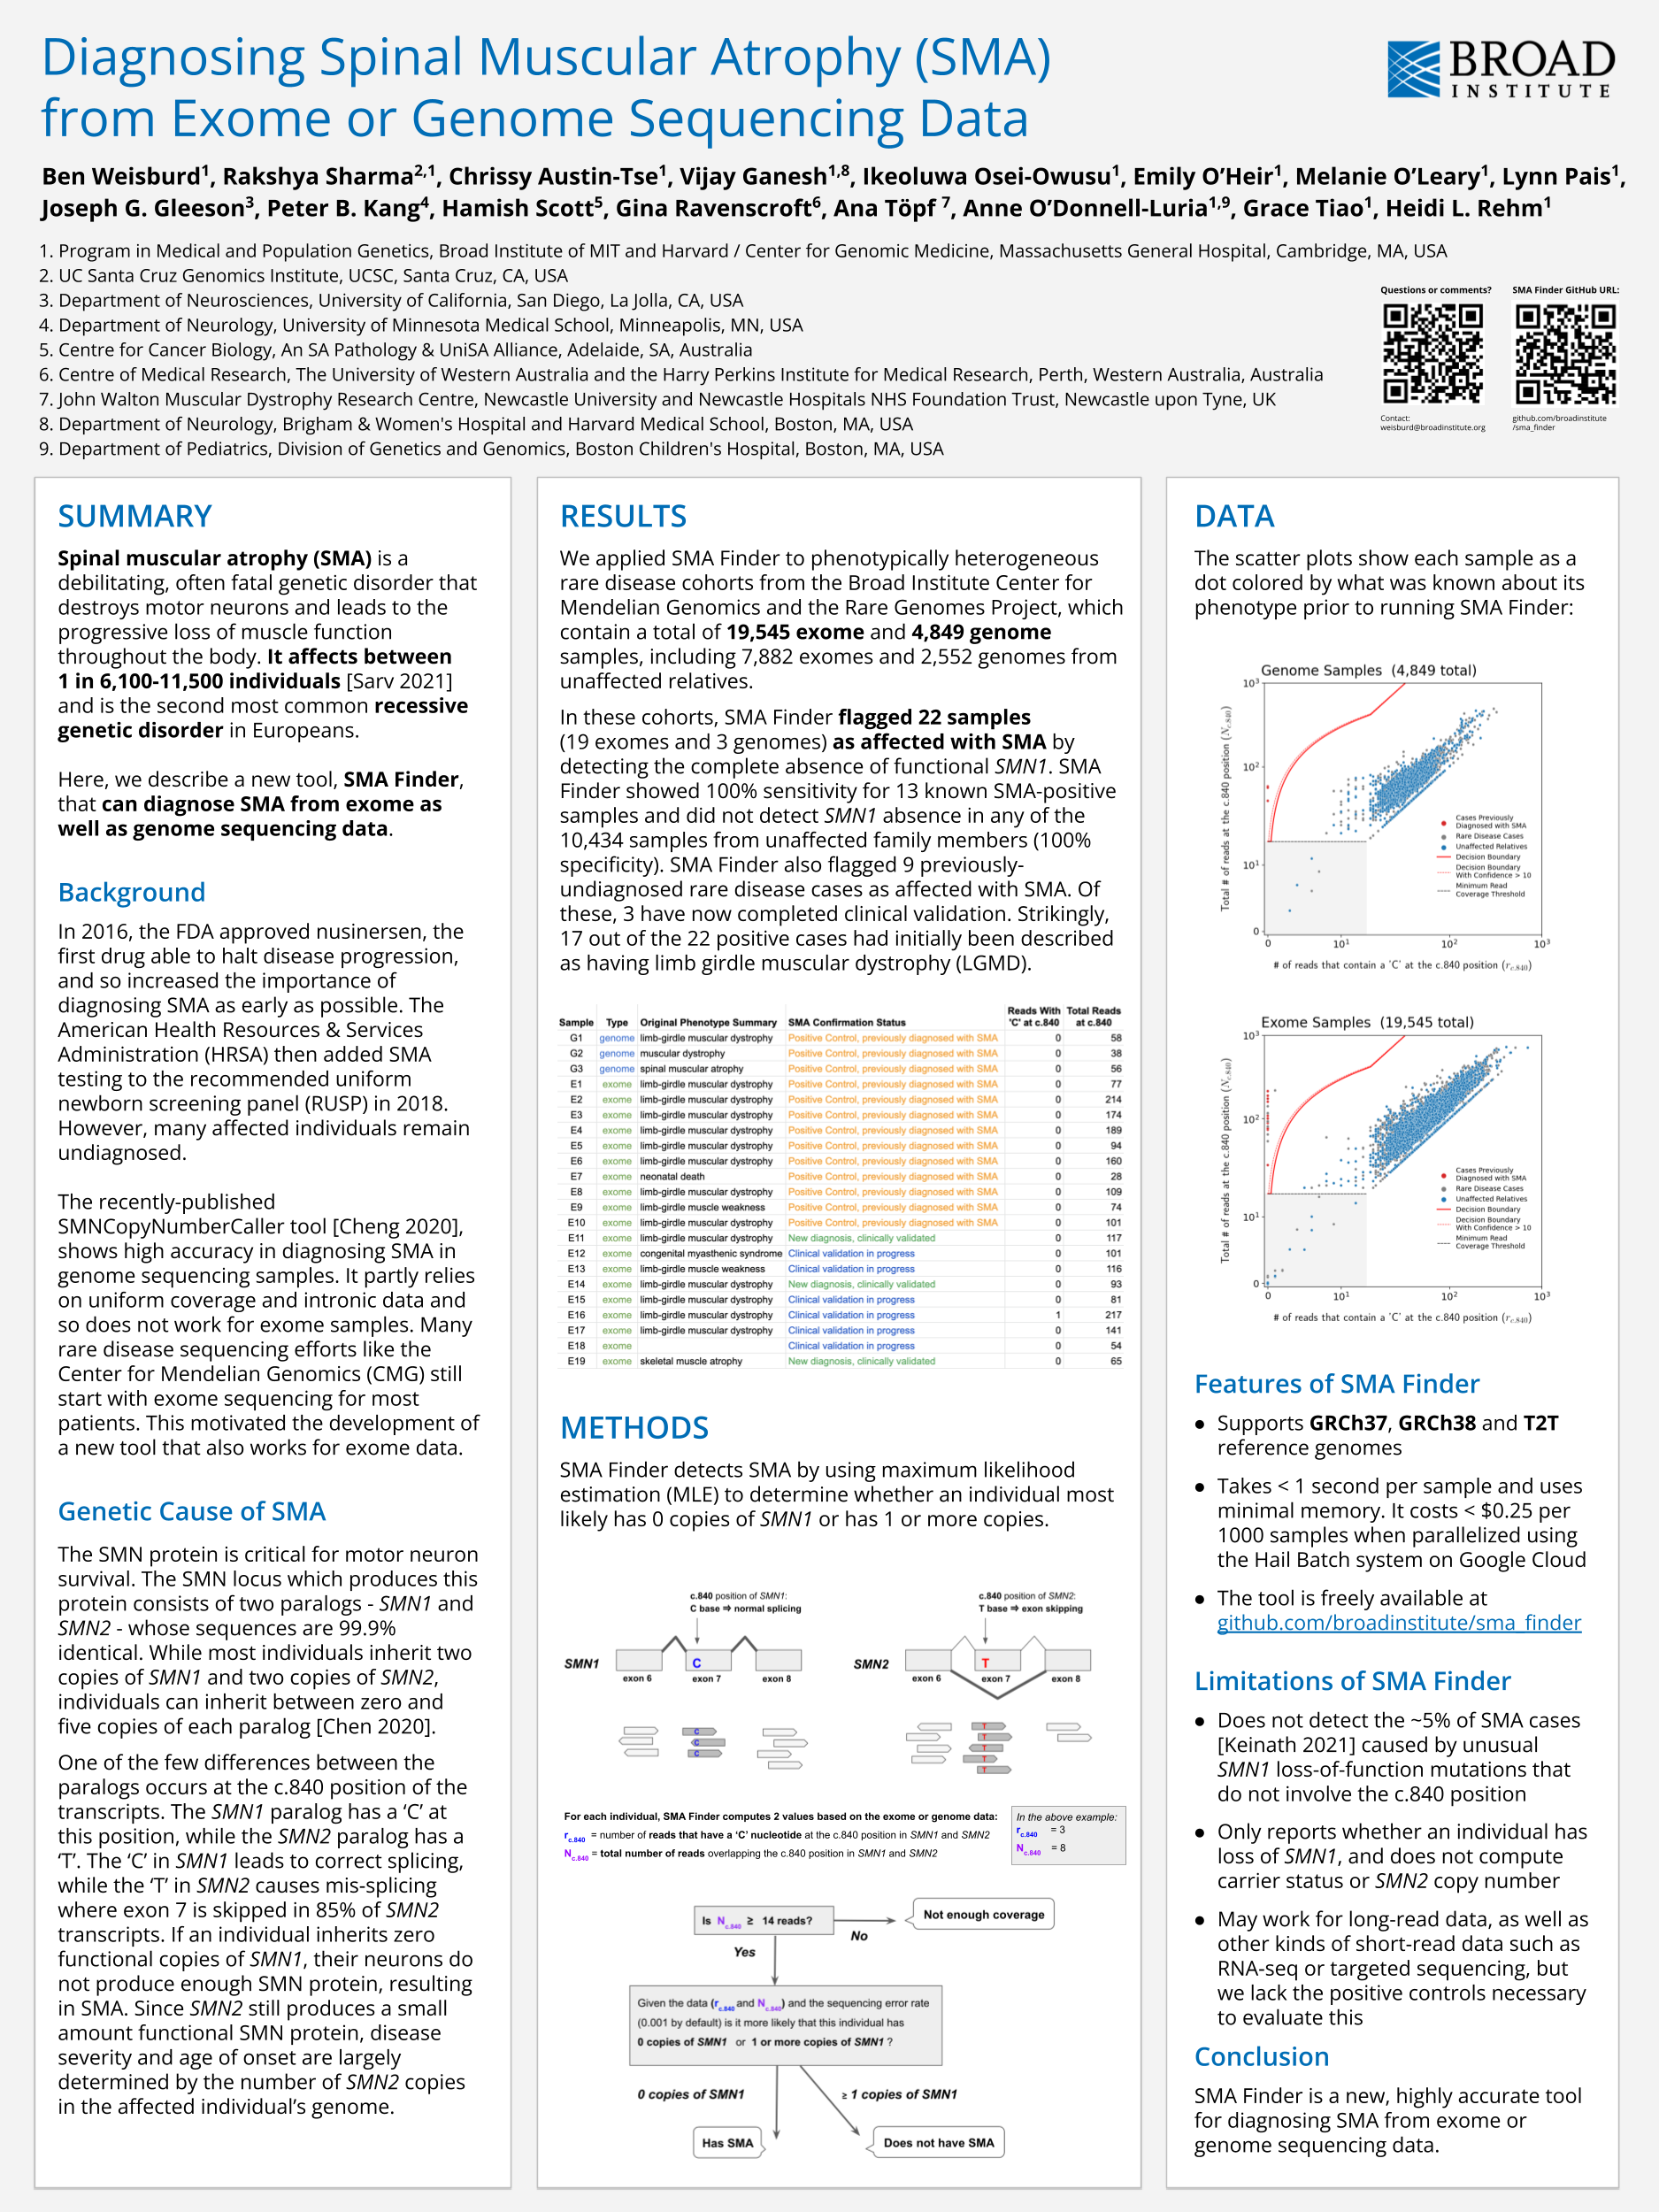
This poster on SMA Finder was presented at the SVAR22 conference:
1 maintainer

Metadata
1 maintainer
Release files for sma-finder 1.4.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| sma_finder-1.4.4.tar.gz | 13.6 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sma_finder-1.4.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 27.7 kB
Release files / sma_finder-1.4.4.tar.gz
| Download URL | sma_finder-1.4.4.tar.gz |
|---|---|
| Size | 13.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e0fdad3e594d1d909fc1f1be91a17464bb64dd0f86096da4b2bb66c4fc92f963
|
|
BLAKE2b-256 checksum How to use checksums |
63594b9cb498a264ca79ffe6ac60a3ef21fc83976e6782c5ae184e7341c8ebb7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.9.17
|
Release files / sma_finder-1.4.4-py3-none-any.whl
| Download URL | sma_finder-1.4.4-py3-none-any.whl |
|---|---|
| Size | 14.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f3f7eb50a71921560194e16c1a8434078a6b9eef5bff8456bb13475b6e05e18f
|
|
BLAKE2b-256 checksum How to use checksums |
630f46dfd349199673b74b45708c838729b7db3a6dee53fcdad8d7b219527dfd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.9.17
|
Security for sma-finder 1.4.4
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














