

This project can ingest both PyTorch and TensorFlow event files but was mostly tested with PyTorch. For a TF-only project, see
tensorboard-aggregator.
Compute statistics (mean, std, min, max, median or any other numpy operation) of multiple TensorBoard run directories. This can be used e.g. when training model ensembles to reduce noise in loss/accuracy/error curves and establish statistical significance of performance improvements or get a better idea of epistemic uncertainty. Results can be saved to disk either as new TensorBoard runs or CSV/JSON/Excel. More file formats are easy to add, PRs welcome.
Example notebooks
| Basic Python API Demo |    |
Demonstrates how to work with local TensorBoard event files. |
| Functorch MLP Ensemble | |
Shows how to aggregate run metrics with TensorBoard Reducer when training model ensembles using functorch. |
| Weights & Biases Integration | |
Trains PyTorch CNN ensemble on MNIST, logs results to WandB, downloads metrics from multiple WandB runs, aggregates using tb-reducer, then re-uploads to WandB as new runs. |
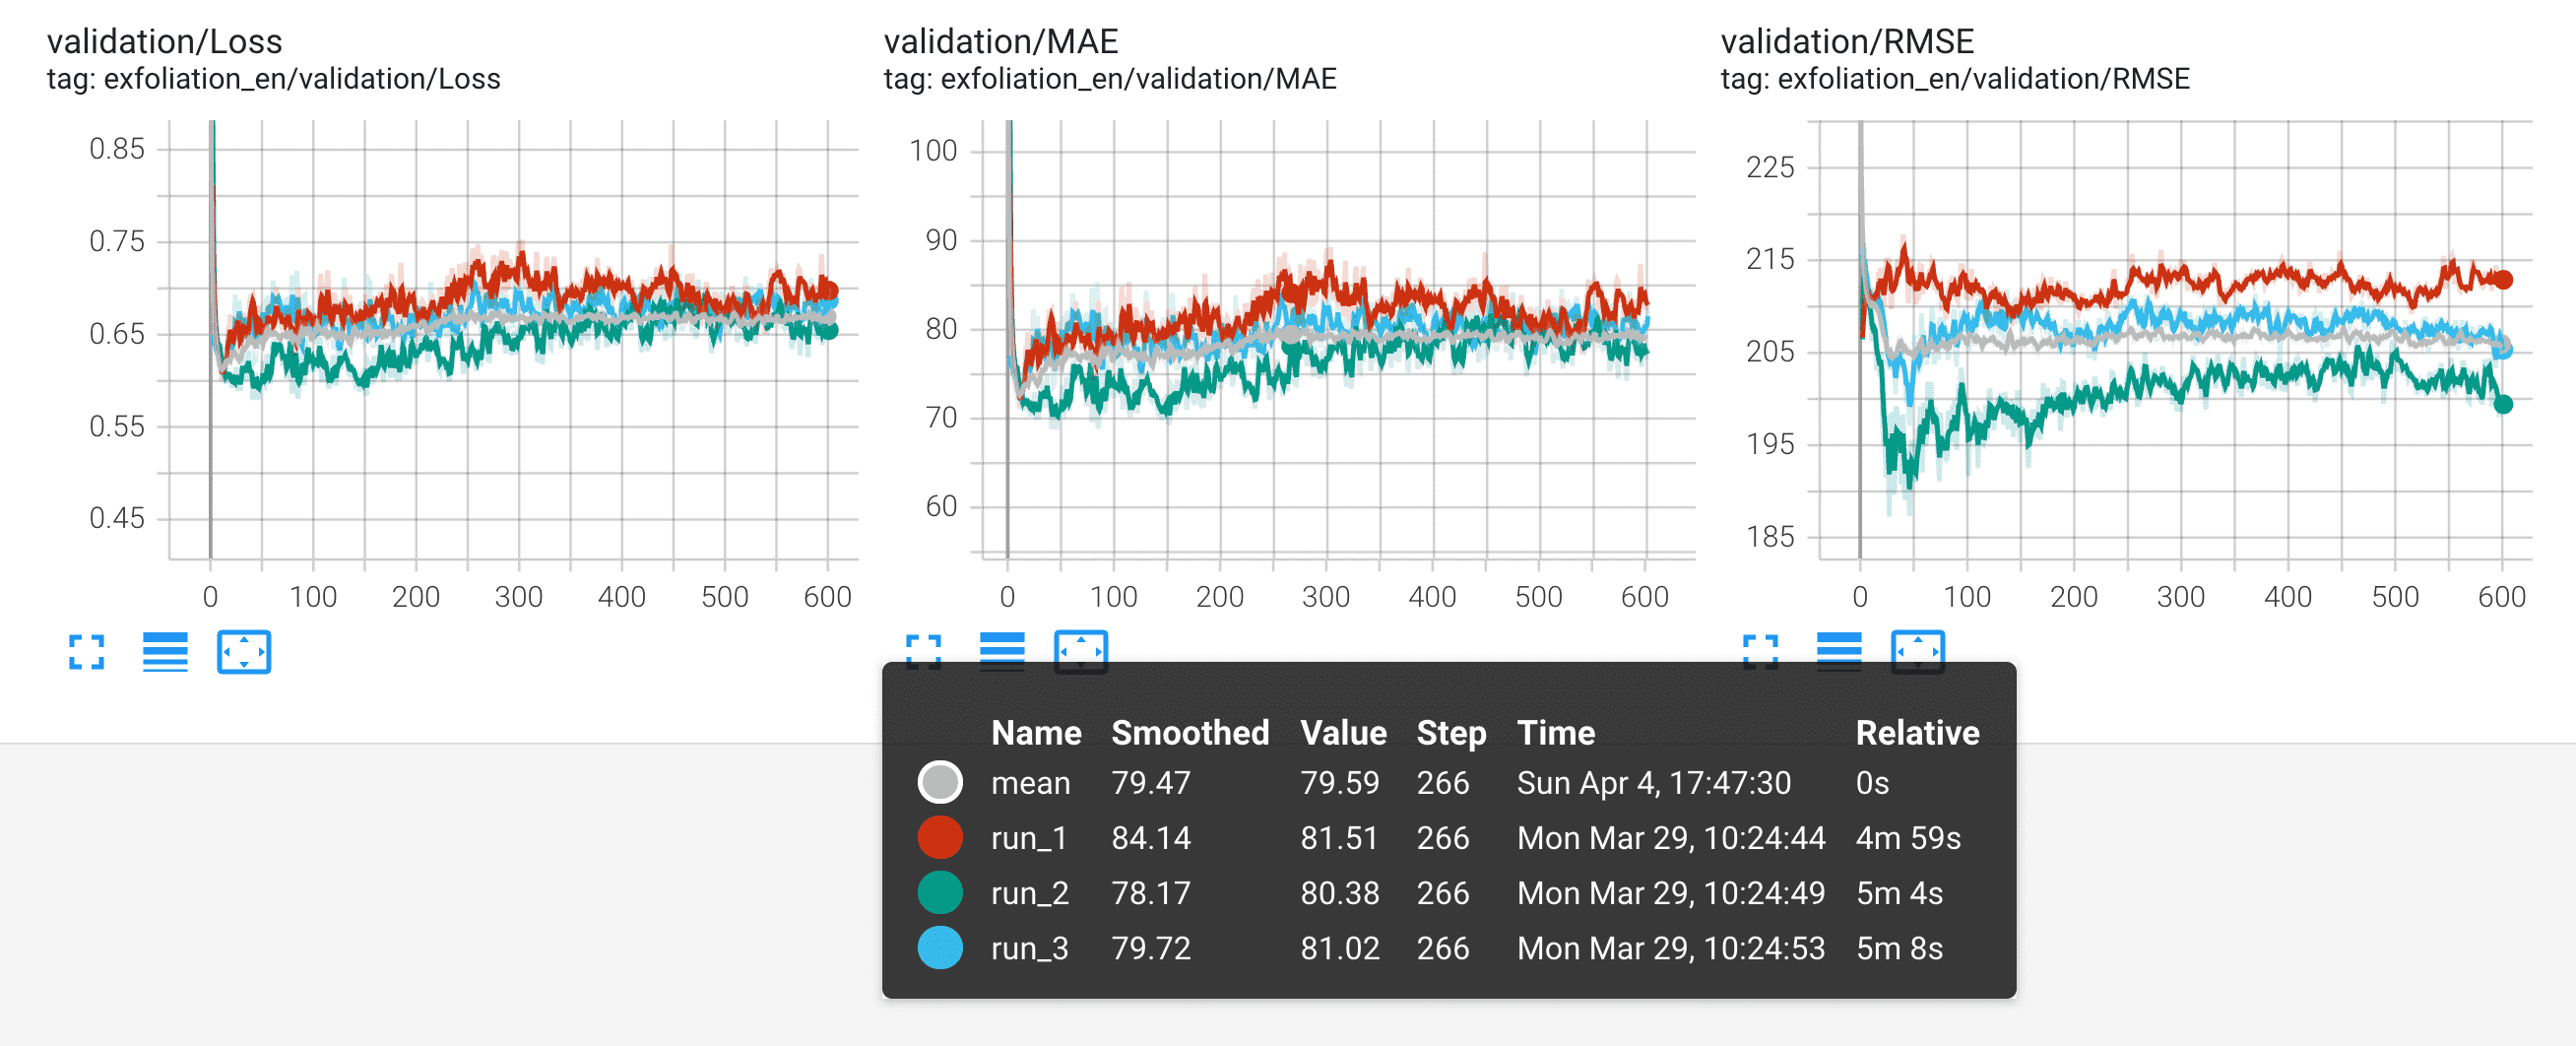
The mean of 3 runs shown in pink here is less noisy and better suited for comparisons between models or different training techniques than individual runs.
Installation
pip install tensorboard-reducer
Excel support requires installing extra dependencies:
pip install 'tensorboard-reducer[excel]'
Usage
CLI
tb-reducer runs/of-your-model* -o output-dir -r mean,std,min,max
All positional CLI arguments are interpreted as input directories and expected to contain TensorBoard event files. These can be specified individually or with wildcards using shell expansion. You can check you're getting the right input directories by running echo runs/of-your-model* before passing them to tb-reducer.
Note: By default, TensorBoard Reducer expects event files to contain identical tags and equal number of steps for all scalars. If you trained one model for 300 epochs and another for 400 and/or recorded different sets of metrics (tags in TensorBoard lingo) for each of them, see CLI flags --lax-steps and --lax-tags to disable this safeguard. The corresponding kwargs in the Python API are strict_tags = True and strict_steps = True on load_tb_events().
In addition, tb-reducer has the following flags:
-o/--outpath(required): File path or directory where to write output to disk. If--outpathis a directory, output will be saved as TensorBoard runs, one new directory created for each reduction suffixed by thenumpyoperation, e.g.'out/path-mean','out/path-max', etc. If--outpathis a file path, it must have'.csv'/'.json'or'.xlsx'(supports compression by using e.g..csv.gz,json.bz2) in which case a single file will be created. CSVs will have a two-level header containing one column for each combination of tag (loss,accuracy, ...) and reduce operation (mean,std, ...). Tag names will be in top-level header, reduce ops in second level. Hint: When saving data as CSV or Excel, usepandas.read_csv("path/to/file.csv", header=[0, 1], index_col=0)andpandas.read_excel("path/to/file.xlsx", header=[0, 1], index_col=0)to load reduction results into a multi-index dataframe.-r/--reduce-ops(optional, default:mean): Comma-separated names of numpy reduction ops (mean,std,min,max, ...). Each reduction is written to a separateoutpathsuffixed by its op name. E.g. ifoutpath='reduced-run', the mean reduction will be written to'reduced-run-mean'.-f/--overwrite(optional, default:False): Whether to overwrite existing output directories/data files (CSV, JSON, Excel). For safety, the overwrite operation will abort with an error if the file/directory to overwrite is not a known data file and does not look like a TensorBoard run directory (i.e. does not start with'events.out').--lax-tags(optional, default:False): Allow different runs have to different sets of tags. In this mode, each tag reduction will run over as many runs as are available for a given tag, even if that's just one. Proceed with caution as not all tags will have the same statistics in downstream analysis.--lax-steps(optional, default:False): Allow tags across different runs to have unequal numbers of steps. In this mode, each reduction will only use as many steps as are available in the shortest run (same behavior aszip(short_list, long_list)which stops whenshort_listis exhausted).--handle-dup-steps(optional, default:None): How to handle duplicate values recorded for the same tag and step in a single run. One of'keep-first','keep-last','mean'.'keep-first/last'will keep the first/last occurrence of duplicate steps while 'mean' computes their mean. Default behavior is to raiseValueErroron duplicate steps.--min-runs-per-step(optional, default:None): Minimum number of runs across which a given step must be recorded to be kept. Steps present across less runs are dropped. Only plays a role iflax_stepsis true. Warning: Be aware that with this setting, you'll be reducing variable number of runs, however many recorded a value for a given step as long as there are at least--min-runs-per-step. In other words, the statistics of a reduction will change mid-run. Say you're plotting the mean of an error curve, the sample size of that mean will drop from, say, 10 down to 4 mid-plot if 4 of your models trained for longer than the rest. Be sure to remember when using this.-v/--version(optional): Get the current version.
Python API
You can also import tensorboard_reducer into a Python script or Jupyter notebook for more complex operations. Here's a simple example that uses all of the main functions load_tb_events, reduce_events, write_data_file and write_tb_events to get you started:
from glob import glob

import tensorboard_reducer as tbr

input_event_dirs = sorted(glob("glob_pattern/of_tb_directories_to_reduce*"))
# where to write reduced TB events, each reduce operation will be in a separate subdirectory
tb_events_output_dir = "path/to/output_dir"
csv_out_path = "path/to/write/reduced-data-as.csv"
# whether to abort or overwrite when csv_out_path already exists
reduce_ops = ("mean", "min", "max", "median", "std", "var")

events_dict = tbr.load_tb_events(input_event_dirs)

# number of recorded tags. e.g. would be 3 if you recorded loss, MAE and R^2
n_scalars = len(events_dict)
n_steps, n_events = list(events_dict.values())[0].shape

print(
    f"Loaded {n_events} TensorBoard runs with {n_scalars} scalars and {n_steps} steps each"
)
print(", ".join(events_dict))

reduced_events = tbr.reduce_events(events_dict, reduce_ops)

for op in reduce_ops:
    print(f"Writing '{op}' reduction to '{tb_events_output_dir}-{op}'")

tbr.write_tb_events(reduced_events, tb_events_output_dir, overwrite=False)

print(f"Writing results to '{csv_out_path}'")

tbr.write_data_file(reduced_events, csv_out_path, overwrite=False)

print("Reduction complete")
1 maintainer

Metadata
1 maintainer
Release files for tensorboard-reducer 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| tensorboard_reducer-0.4.0.tar.gz | 23.9 kB | Without provenance | Details for tensorboard_reducer-0.4.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| tensorboard_reducer-0.4.0-py2.py3-none-any.whl | Python 2, Python 3 | none | any | Details for tensorboard_reducer-0.4.0-py2.py3-none-any.whl |
Total release size: 41.6 kB
Release files / tensorboard_reducer-0.4.0.tar.gz
| Download URL | tensorboard_reducer-0.4.0.tar.gz |
|---|---|
| Size | 23.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
d121874964b86179c3731625580a01ee5f2c18bd7776f1b4c9b040868c57d312
|
|
BLAKE2b-256 checksum How to use checksums |
7fdbf20735876c00f650ad6270b11e3442fb6e900a5aa2c60041de6f60808cf5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.7.3
|
Release files / tensorboard_reducer-0.4.0-py2.py3-none-any.whl
| Download URL | tensorboard_reducer-0.4.0-py2.py3-none-any.whl |
|---|---|
| Size | 17.6 kB |
| Tags | Python 2 Python 3 |
|
SHA-256 checksum How to use checksums |
9e03da29aee2d1395b51ab98d04e2c7002d0bde837f02c95ad31dea811e44ef2
|
|
BLAKE2b-256 checksum How to use checksums |
769e77217f691467fec77d7f262909f2251c01be6d7971641b263c71355542e5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.7.3
|
Security for tensorboard-reducer 0.4.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














