
Twitter Demographer



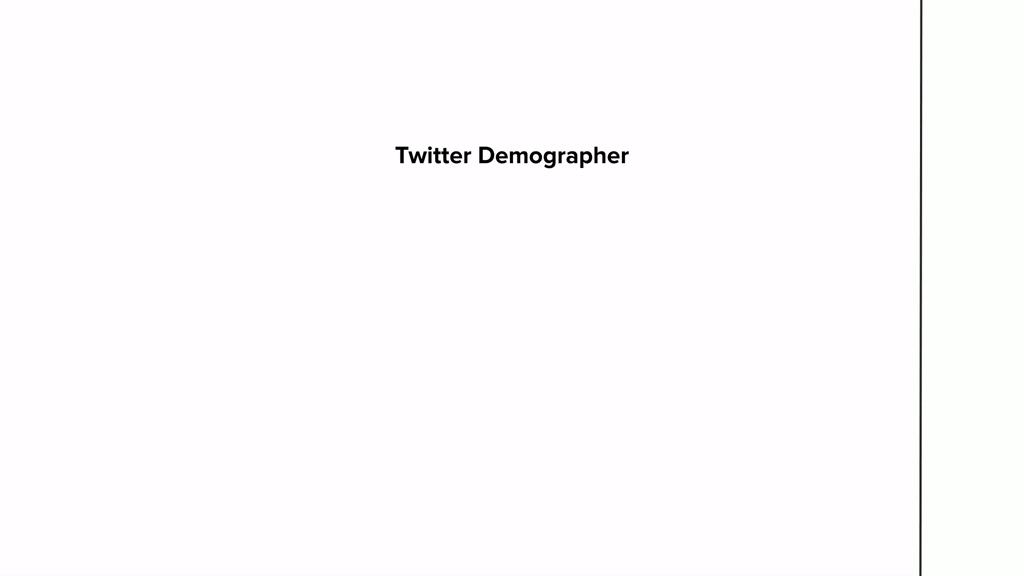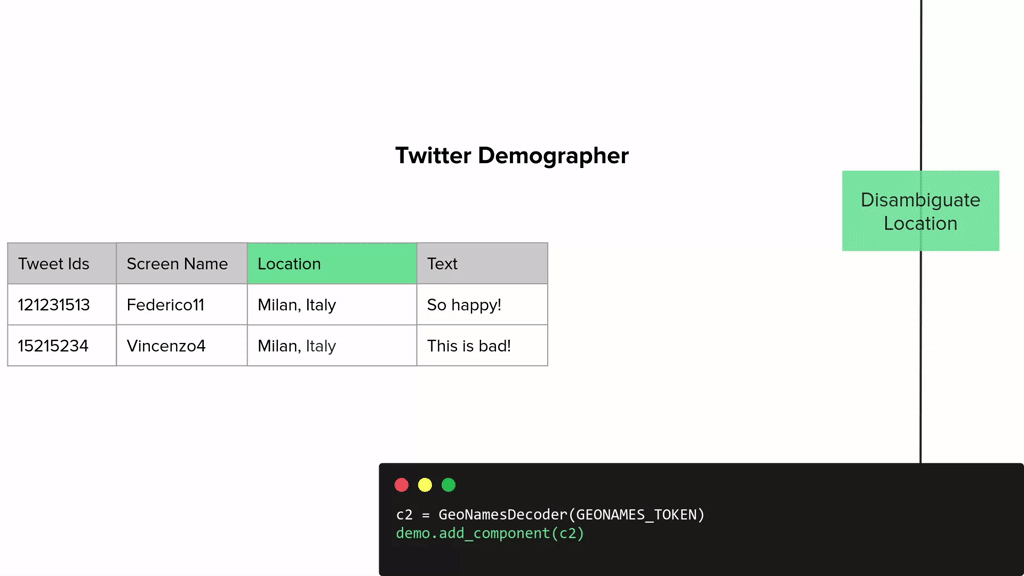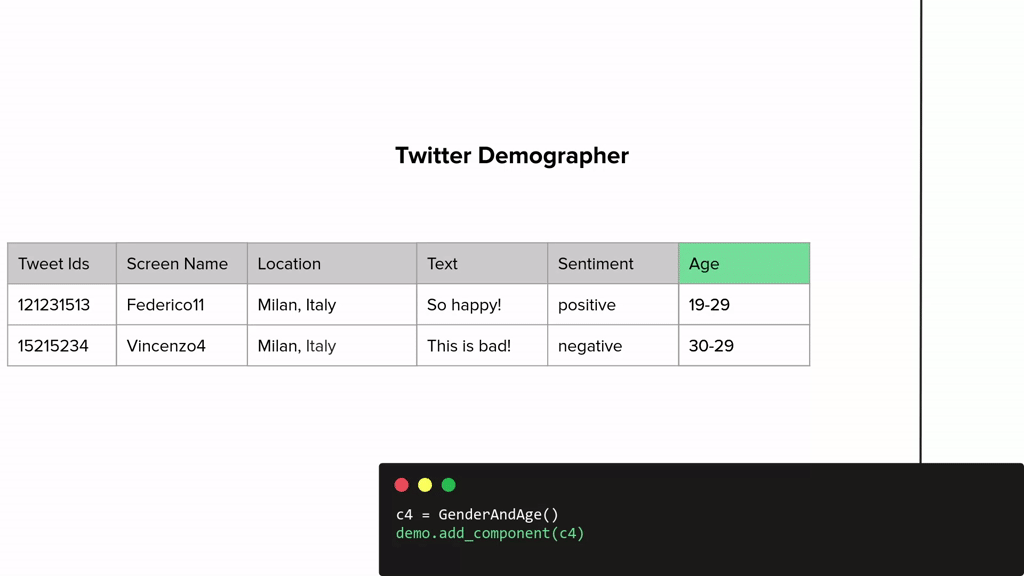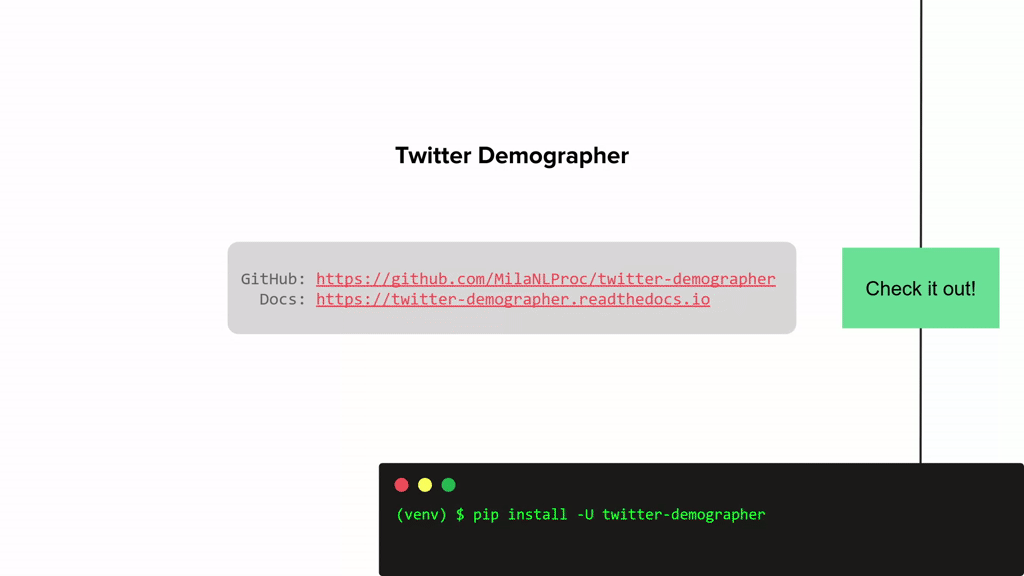
Twitter Demographer provides a simple API to enrich your twitter data with additional variables such as sentiment, user location, gender and age. The tool is completely extensible and you can add your own components to the system.
Free software: MIT license
Documentation: https://twitter-demographer.readthedocs.io.
Note the API is still under development (e.g., we have a lot of logging going on behind the scene) feel free to suggest improvements or submit PRs! We are also working on improving the documentation and adding more examples!
If you find this useful, please remember to cite the following paper:
@article{bianchi2022twitter,
  title={Twitter-Demographer: A Flow-based Tool to Enrich Twitter Data},
  author={Bianchi, Federico and Cutrona, Vincenzo and Hovy, Dirk},
  journal={EMNLP},
  year={2022}
}
Features
From a simple set of tweet ids, Twitter Demographer allows you to rehydrate them and to add additional variables to your dataset.
You are not forced to use a specific component. The design of this tool should be modular enough to allow you to decide what to add and what to remove.
Let’s make an example: you have a set of tweet ids (from english speakers) and you want to:
reconstruct the original tweets
disambiguate the location of the users
predict the sentiment of the tweet.
This can be done with very few lines of code with this library.
from twitter_demographer.twitter_demographer import Demographer
from twitter_demographer.components import Rehydrate
from twitter_demographer.geolocation.nominatim import NominatimDecoder
from twitter_demographer.classification.transformers import HuggingFaceClassifier
import pandas as pd

demo = Demographer()

data = pd.DataFrame({"tweet_ids": ["1477976329710673921", "1467887350084689928", "1467887352647462912", "1290664307370360834", "1465284810696445952"]})

component_one = Rehydrate(BEARER_TOKEN)
component_two = NominatimDecoder()
component_three = HuggingFaceClassifier("cardiffnlp/twitter-roberta-base-sentiment")


demo.add_component(component_one)
demo.add_component(component_two)
demo.add_component(component_three)

print(demo.infer(data))
screen_name created_at ... geo_location_address cardiffnlp/twitter-roberta-base-sentiment
1 ef51346744a099e011ff135f7b223186d4dab4d38bb1d8... 2021-12-06 16:03:10+00:00 ... Milan 1
4 146effc0d60c026197afe2404c4ee35dfb07c7aeb33720... 2021-11-29 11:41:37+00:00 ... Milan 2
2 ef51346744a099e011ff135f7b223186d4dab4d38bb1d8... 2021-12-06 16:03:11+00:00 ... Milan 1
0 241b67c6c698a70b18533ea7d4196e6b8f8eafd39afc6a... 2022-01-03 12:13:11+00:00 ... Zurich 2
3 df94741e2317dc8bfca7506f575ba3bd9a83deabfd9eec... 2020-08-04 15:02:04+00:00 ... Viganello 2Note that you still need to register to both twitter developer and to geonames to use the services.
Privacy Matters
Following the recommendations of the EU’s General Data Protection Regulation, we implement a variety of measures to ensure pseudo-anonymity by design. Using tool provides several built-in measures to remove identifying information and protect user privacy:
removing identifiers
unidirectional hashing
aggregate label swapping.
This does not compromise the value of aggregated analysis but allows for a fairer usage of this data.
Extending
However, the library is also extensible. Say you want to use a custom classifier on some Twitter Data you have. For example, you might want to detect the sentiment of the data using your own classifier.
class YourClassifier(Component):
    def __init__(self, model):
        self.model = model
        super().__init__()

    def inputs(self):
        return ["text"]

    def outputs(self):
        return [f"my_classifier"]

    # not null decorator helps you skip those record that have None in the field
    @not_null("text")
    def infer(self, data):

        return {"my_classifier": model.predict(data["text"])}
Components
Twitter Demographer is based on components that can be concatenated together to build tools. For example, the GeoNamesDecoder to predict the location of a user from a string of text looks like this.
class GeoNamesDecoder(Component):

    def __init__(self, key):
        super().__init__()
        self.key = key

    def outputs(self):
        return ["geo_location_country", "geo_location_address"]

    def inputs(self):
        return ["location"]

    @not_null("location")
    def infer(self, data):
        geo = self.initialize_return_dict()
        for val in data["location"]:
                g = geocoder.geonames(val, key=self.key)
                geo["geo_location_country"].append(g.country)
                geo["geo_location_address"].append(g.address)
        return geo
Current Components
The project and the components are still under development and we are working on introducing novel pipelines to support different use-cases.
You can see the components currently integrated in the system here
Name |
Tool |
|---|---|
Geolocation |
GeoNames, OpenStreetMap |
HateSpeech |
Perspective API |
Classification |
Support for all HuggingFace Classifiers |
Demographics |
M3Inference, FairFace (Coming Soon) |
Topic Modeling |
Contextualized Topic Modeling |
Limitations and Ethical Considerations
Twitter Demographer does not come without limitations. Some of these are related to the precision of the components used; for example, the Geonames decoder can fail the disambiguation - even if it has been adopted by other researchers and services. At the same time, the the topic modeling pipeline can be affected by the number of tweets used to train the model and by other training issues (fixing random seeds can generate suboptimal solutions).
The tool wraps the API from M3 for age and gender prediction. However, those predictions for gender are binary (male or female) and thus give a stereotyped representation of gender. Our intent is not to make normative claims about gender, as this is far from our beliefs. Twitter Demographer allows using other, more flexible tools. The API needs both text and user profile pictures of a tweet to make inferences, for that reason the tool has to include such information in the dataset during the pipeline execution. While this information is public (e.g., user profile pictures), the final dataset contains also inferred information, which may not be publicly available (e.g., gender or age of the user). We cannot completely prevent misuse of this capability but have taken steps to substantially reduce the risk and promote privacy by design.
Inferring user attributes carries the risk of privacy violations. We follow the definitions and recommendations of the European Union’s General Data Protection Regulation for algorithmic pseudo-anonymity. We implement several measures to break a direct mapping between attributes and identifiable users without reducing the generalizability of aggregate findings on the data. Our measures follow the GDPR definition of a “motivated intruder”, i.e., it requires “significant effort” to undo our privacy protection measures. However, given enough determination and resources, a bad actor might still be able to circumvent or reverse-engineer these measures. This is true independent of Twitter Demographer, though, as existing tools could be used more easily to achieve those goals. Using the tool provides practitioners with a reasonable way to protect anonymity.
Credits
This package was created with Cookiecutter and the audreyr/cookiecutter-pypackage project template.
History
0.1.0 (2021-12-16)
First release on PyPI.
1 maintainer

Metadata
1 maintainer
Release files for twitter-demographer 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| twitter_demographer-0.2.1.tar.gz | 26.1 kB | Without provenance | Details for twitter_demographer-0.2.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| twitter_demographer-0.2.1-py2.py3-none-any.whl | Python 2, Python 3 | none | any | Details for twitter_demographer-0.2.1-py2.py3-none-any.whl |
Total release size: 46.7 kB
Release files / twitter_demographer-0.2.1.tar.gz
| Download URL | twitter_demographer-0.2.1.tar.gz |
|---|---|
| Size | 26.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
bd2a08bc56cecf730bddd0a9afe8a03db134f5734a60386b3880570d669d4c3e
|
|
BLAKE2b-256 checksum How to use checksums |
0f20df0d66abcdfedb61423ab5ef8349d8d9bb509e8c370b23d2436f42ccb101
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.9.16
|
Release files / twitter_demographer-0.2.1-py2.py3-none-any.whl
| Download URL | twitter_demographer-0.2.1-py2.py3-none-any.whl |
|---|---|
| Size | 20.6 kB |
| Tags | Python 2 Python 3 |
|
SHA-256 checksum How to use checksums |
e68d7bb21c1b34a623166023b073c39f79073fb7241c36ceb0b03097e587648a
|
|
BLAKE2b-256 checksum How to use checksums |
779fbd6d92a1ba6375c86bf11a418a43939f5a98f09d909567be340bee7d7301
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.9.16
|
Security for twitter-demographer 0.2.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














