
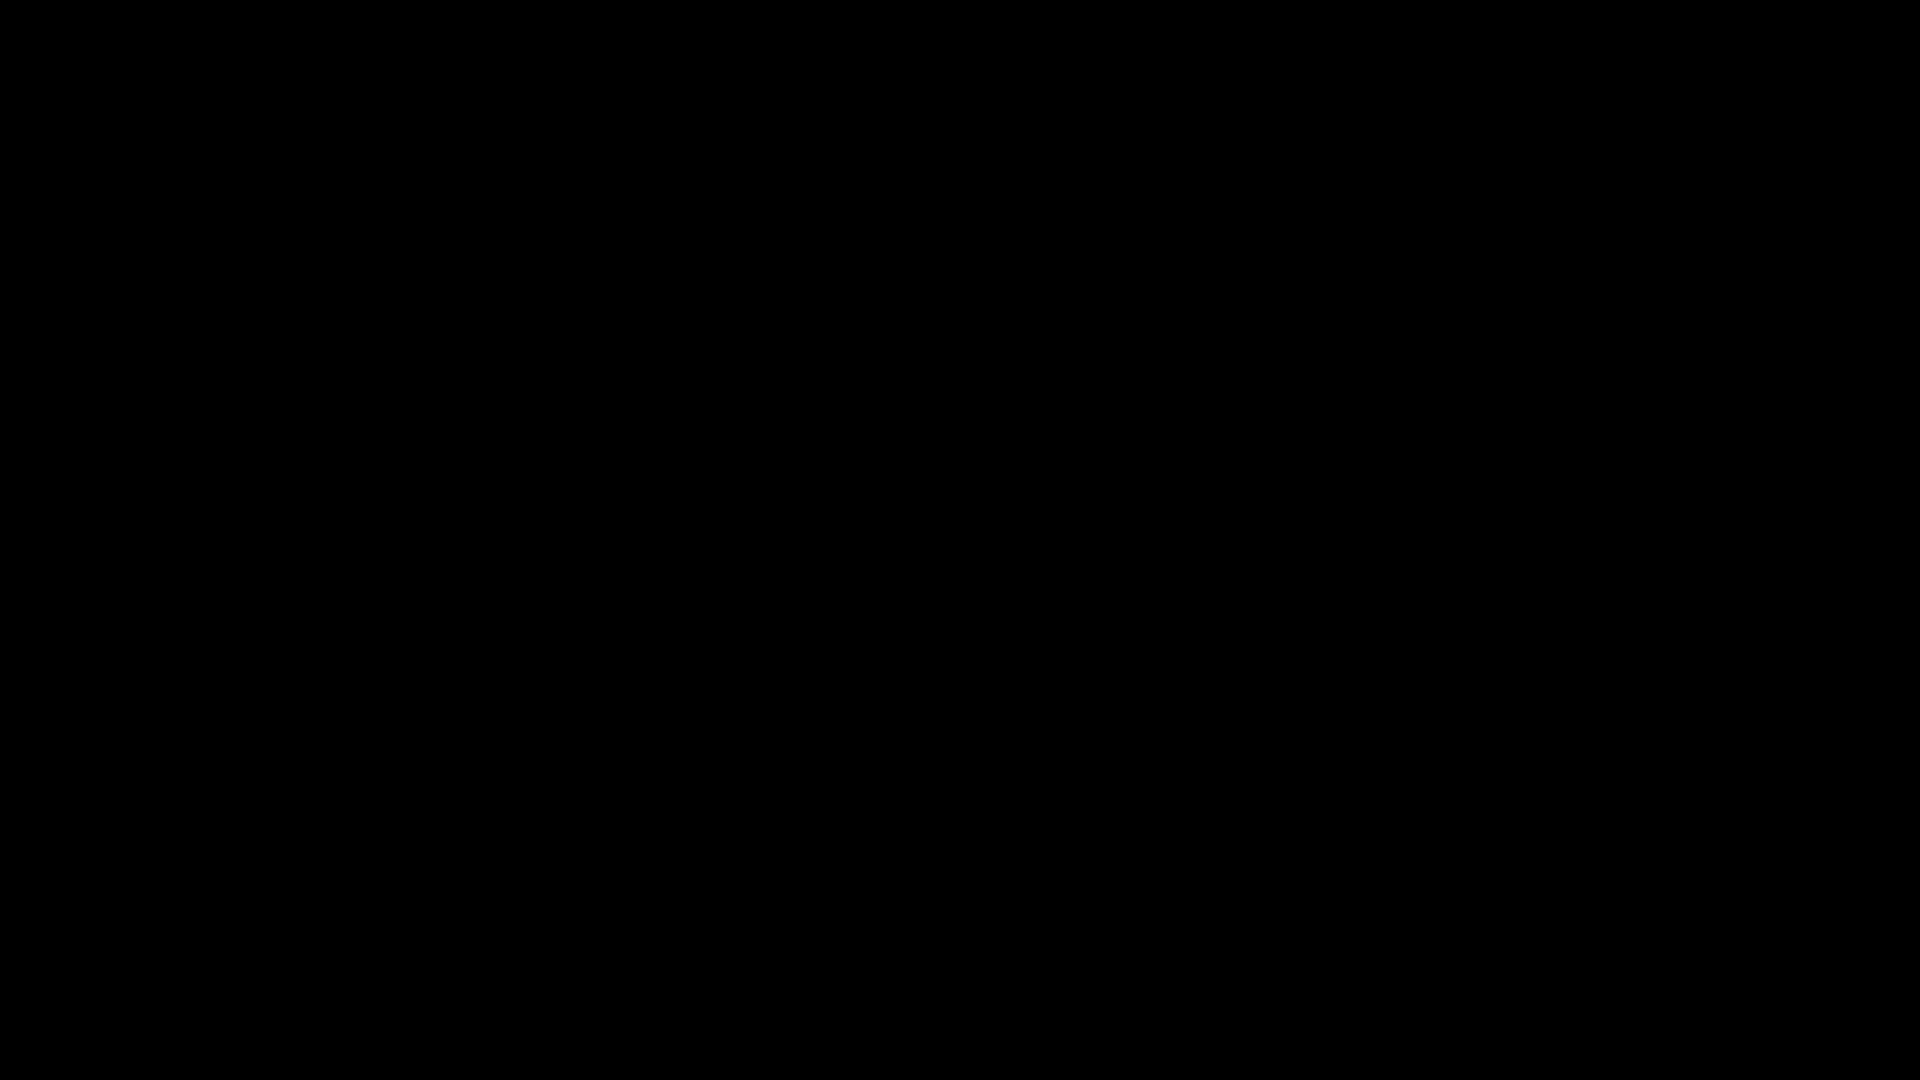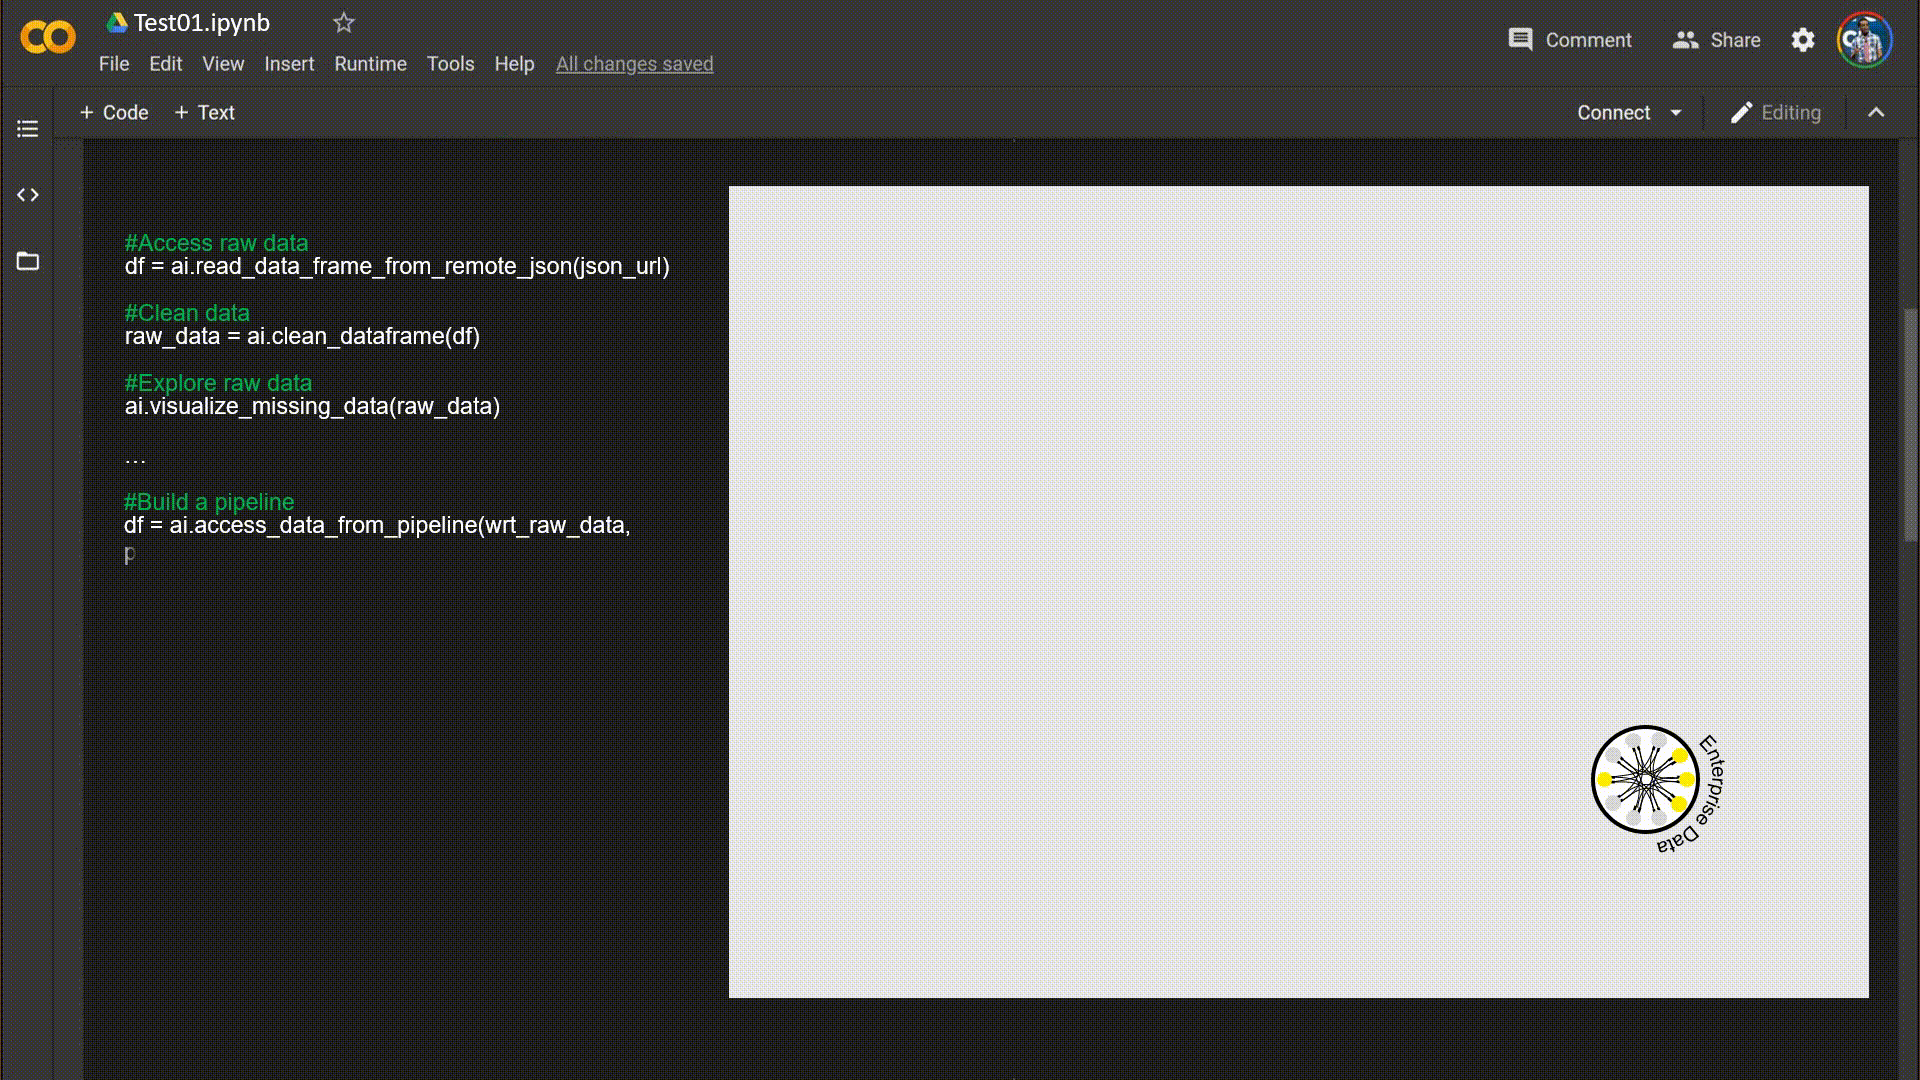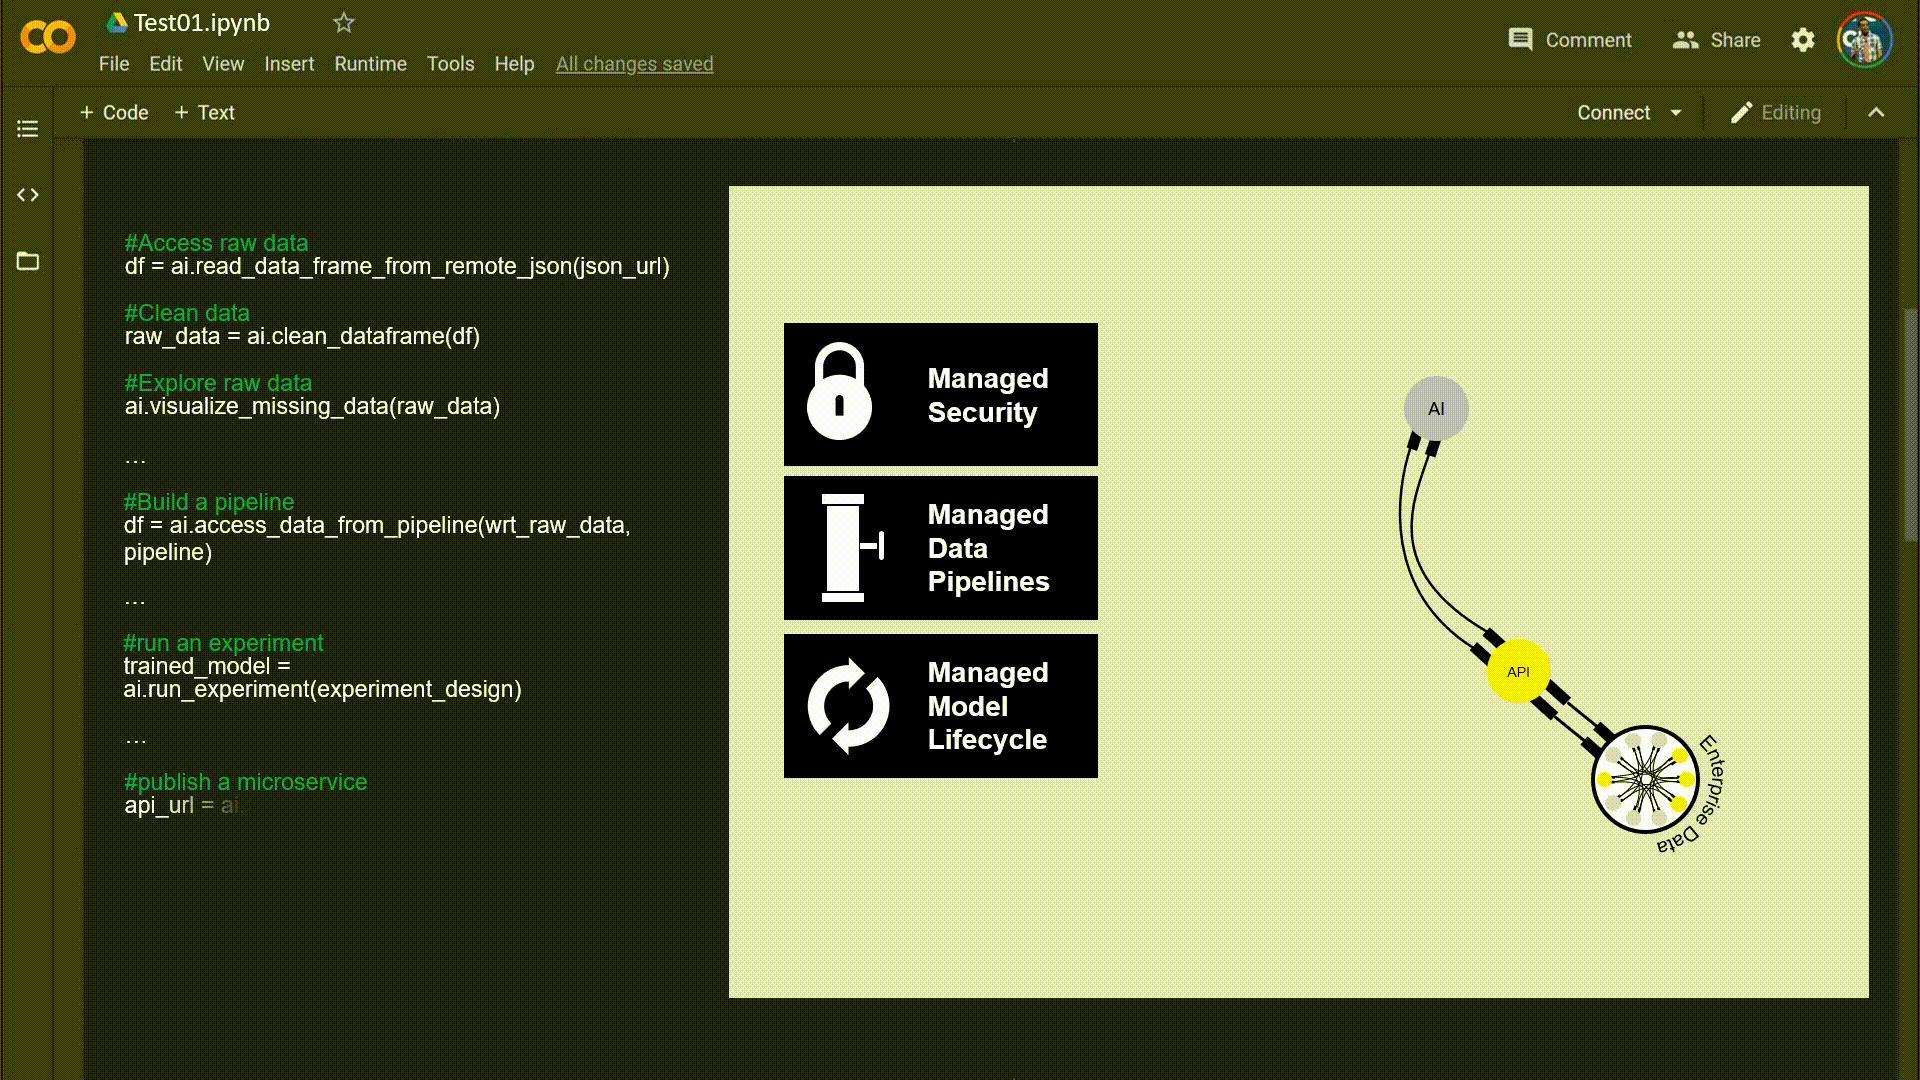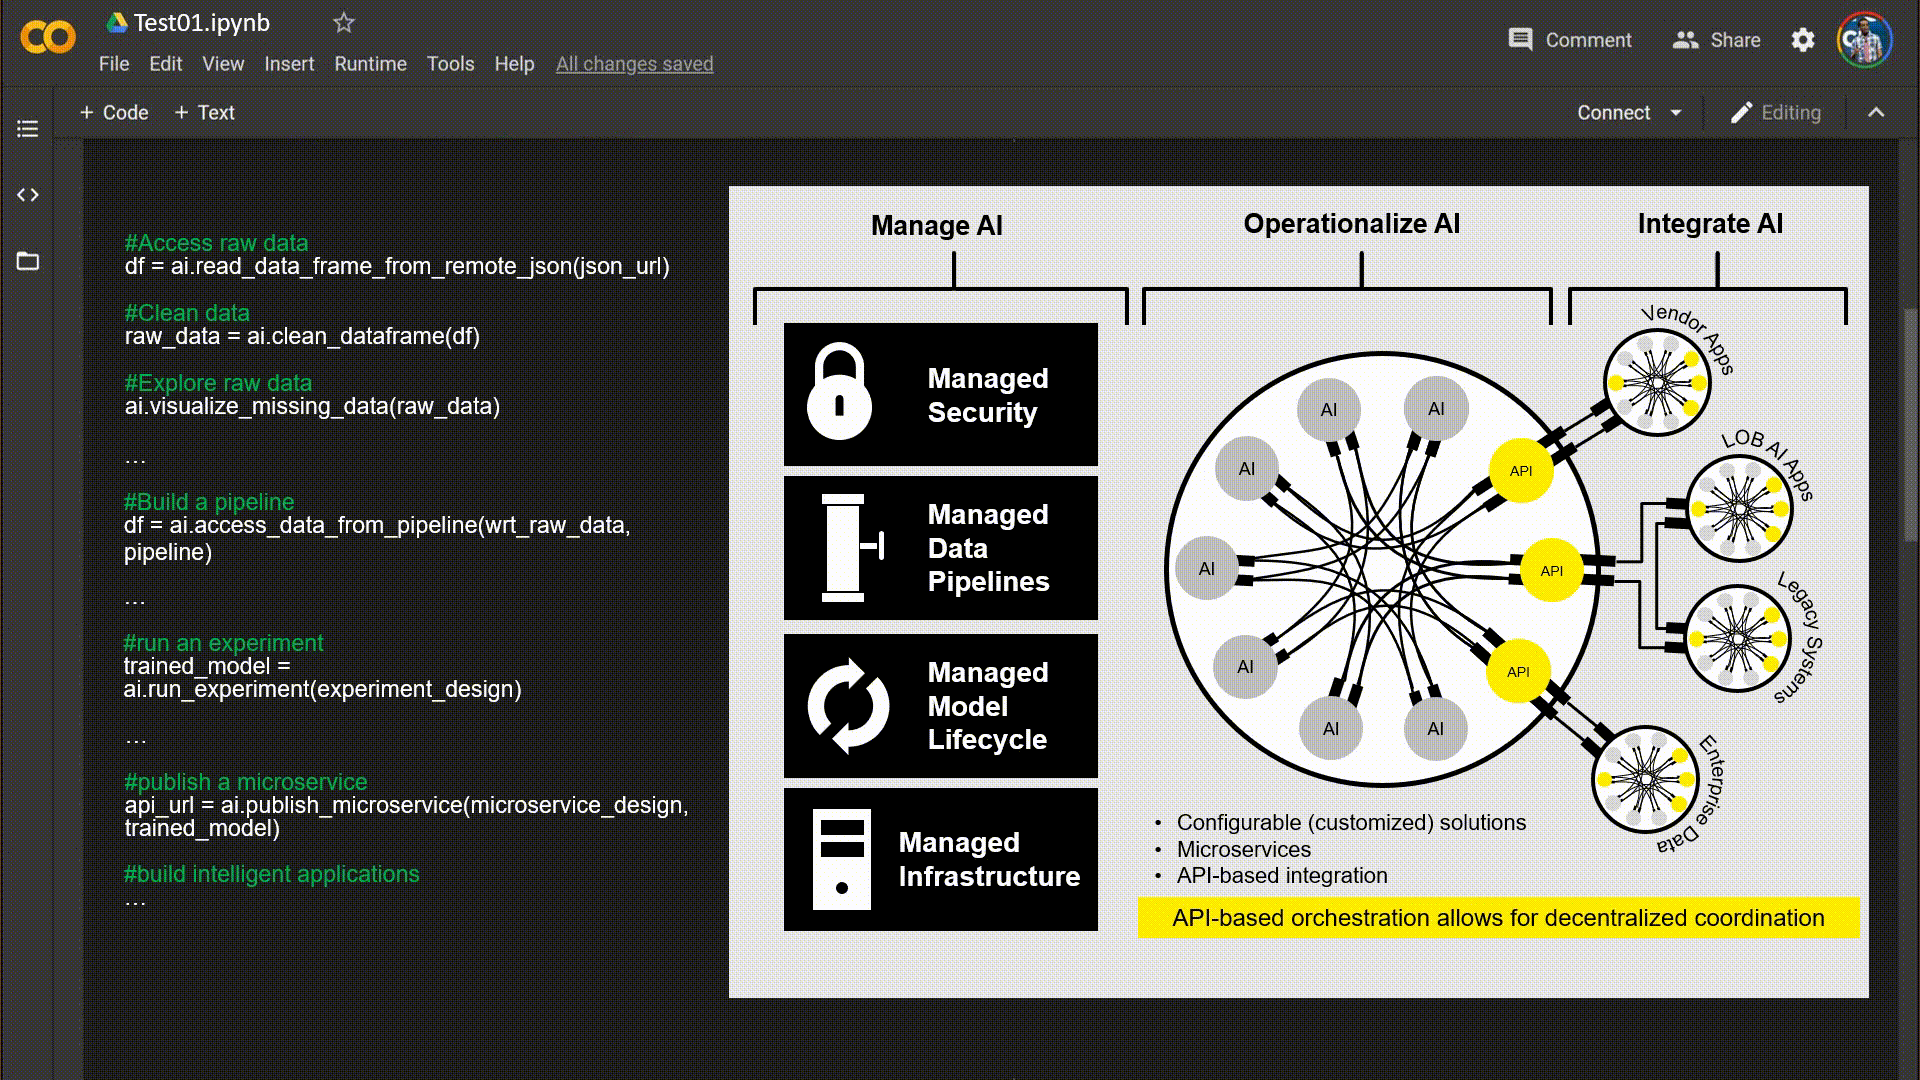
DXC Industrialized AI Starter
DXC Industrialized AI Starter makes it easy for you to deploy your AI algorithms (Industrialize). If you are a data scientist, working on an algorithm that you would like to deploy across the enterprise, DXC's Industrialized AI starter makes it easier for you to:
- Access, clean, and explore raw data
- Build data pipelines
- Run AI experiments
- Publish microservices
Installation
In order to install and use the DXC AI Starter library, please use the below code snippet:
1. pip install DXC-Industrialized-AI-Starter
2. from dxc import ai
Getting Started
Access, Clean, and Explore Raw Data
Use the library to access, clean, and explore your raw data.
#Access raw data
df = ai.read_data_frame_from_remote_json(json_url)
df = ai.read_data_frame_from_remote_csv(csv_url)
df = ai.read_data_frame_from_local_json()
df = ai.read_data_frame_from_local_csv()
df = ai.read_data_frame_from_local_excel_file()

#Clean data: Imputes missing data, removes empty rows and columns, anonymizes text.
raw_data = ai.clean_dataframe(df)

#Explore complete data as a HTML interactive report
report = ai.explore_complete_data(df)
report.to_notebook_iframe()

#Explore raw data:
ai.visualize_missing_data(raw_data) #visualizes relationships between all features in data.
ai.explore_features(raw_data) #creates a visual display of missing data.
ai.plot_distributions(raw_data) #creates a distribution graph for each column.
Click here for details about Acess,clean,explore raw data.
Build Data Pipelines
Pipelines are a standard way to process your data towards modeling and interpreting. By default, the DXC AI Starter library uses the free tier of MongoDB Atlas to store raw data and execute pipelines. In order to get started, you need to first have an MongoDB account which you can signup for free and create a database "connection_string" and specify those details in the data_layer below. The following code connects to MongoDB and stores raw data for processing.
#Insert data into MongoDB:
data_layer = {
    "connection_string": "<your connection_string>",
    "collection_name": "<your collection_name>",
    "database_name": "<your database_name>",
    "data_source":"<Source of your datset>",
    "cleaner":"<whether applied cleaner yes/no >"
}
wrt_raw_data = ai.write_raw_data(data_layer, raw_data, date_fields = [])
Once raw data is stored, you can run pipelines to transform the data. This code instructs the data store on how to refine the output of raw data into something that can be used to train a machine-learning model. Please refer to the syntax of MongDB pipelines for the details of how to write a pipeline. Below is an example of creating and executing a pipeline.
pipeline = [
        {
            '$group':{
                '_id': {
                    "funding_source":"$funding_source",
                    "request_type":"$request_type",
                    "department_name":"$department_name",
                    "replacement_body_style":"$replacement_body_style",
                    "equipment_class":"$equipment_class",
                    "replacement_make":"$replacement_make",
                    "replacement_model":"$replacement_model",
                    "procurement_plan":"$procurement_plan"
                    },
                "avg_est_unit_cost":{"$avg":"$est_unit_cost"},
                "avg_est_unit_cost_error":{"$avg":{ "$subtract": [ "$est_unit_cost", "$actual_unit_cost" ] }}
            }
        }
]

df = ai.access_data_from_pipeline(wrt_raw_data, pipeline) #refined data will be stored in pandas dataframe.
Click here for details about building data pipeline.
Run AI Experiments
Use the DXC AI Starter to build and test algorithms. This code executes an experiment by running run_experiment() on an experiment design.
experiment_design = {
    #model options include ['tpot_regression()', 'tpot_classification()', 'timeseries']
    "model": ai.tpot_regression(),
    "labels": df.avg_est_unit_cost_error,
    "data": df,
    #Tell the model which column is 'output'
    #Also note columns that aren't purely numerical
    #Examples include ['nlp', 'date', 'categorical', 'ignore']
    "meta_data": {
      "avg_est_unit_cost_error": "output",
      "_id.funding_source": "categorical",
      "_id.department_name": "categorical",
      "_id.replacement_body_style": "categorical",
      "_id.replacement_make": "categorical",
      "_id.replacement_model": "categorical",
      "_id.procurement_plan": "categorical"
  }
}

trained_model = ai.run_experiment(experiment_design, verbose = False, max_time_mins = 5, max_eval_time_mins = 0.04, config_dict = None, warm_start = False, export_pipeline = True, scoring = None)
Click here for details about run AI experiments.
Publish Microservice
The DXC AI Starter library makes it easy to publish your models as working microservices. By default, the DXC AI Starter library uses free tier of Algorithmia to publish models as microservices. You must create an Algorithmia account to use. Below is the example for publishing a microservice.
#trained_model is the output of run_experiment() function
microservice_design = {
    "microservice_name": "<Name of your microservice>",
    "microservice_description": "<Brief description about your microservice>",
    "execution_environment_username": "<Algorithmia username>",
    "api_key": "<your api_key>",
    "api_namespace": "<your api namespace>",
    "model_path":"<your model_path>"
}

#publish the micro service and display the url of the api
api_url = ai.publish_microservice(microservice_design, trained_model)
print("api url: " + api_url)
Click here for details about publishing microservice.
Docs
For detailed and complete documentation, please click here
Example notebooks
Here are example notebooks for individual models. These sample notebooks help to understand on how to use each function, what parameters are expected for each function and what will be the output of each function in a model.
Contributing Guide
To know more about the contribution and guidelines please click here
Reporting Issues
If you find any issues, feel free to report them here with clear description of your issue. You can use the existing templates for creating issues.
1 maintainer

Metadata
1 maintainer
Release files for DXC-Industrialized-AI-Starter 3.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| DXC-Industrialized-AI-Starter-3.2.0.tar.gz | 39.9 kB | Without provenance | Details for DXC-Industrialized-AI-Starter-3.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| DXC_Industrialized_AI_Starter-3.2.0-py3-none-any.whl | Python 3 | none | any | Details for DXC_Industrialized_AI_Starter-3.2.0-py3-none-any.whl |
Total release size: 88.1 kB
Release files / DXC-Industrialized-AI-Starter-3.2.0.tar.gz
| Download URL | DXC-Industrialized-AI-Starter-3.2.0.tar.gz |
|---|---|
| Size | 39.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5a4f9cb8b8b4aadfeeaa4e144d6e895619213509d78dc65b5f421542a10a1a9e
|
|
BLAKE2b-256 checksum How to use checksums |
f40b4f7fa3428c36e4db8cd3613198ad1d0f18e484c1810b9648c0eff0948359
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.0 CPython/3.10.4
|
Release files / DXC_Industrialized_AI_Starter-3.2.0-py3-none-any.whl
| Download URL | DXC_Industrialized_AI_Starter-3.2.0-py3-none-any.whl |
|---|---|
| Size | 48.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8e077c94e97b97cc7a39923e277fa7a64085f1038f290d8d1f674fe073681f0f
|
|
BLAKE2b-256 checksum How to use checksums |
3512466604d961db24235f638674168eb7e20db30e474adb0d25a148f6b55cc1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.0 CPython/3.10.4
|
Security for DXC-Industrialized-AI-Starter 3.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














