
aehf — agent evaluation harness framework
A framework-agnostic harness for evaluating tool-using LLM agents: run a suite of cases, judge the transcripts, and get statistically honest pass rates and regression checks — not a single flaky number.
The point of aehf is not just to score agents, but to validate the judge doing the scoring first, then use that trusted judge to make claims you can defend.
Headline finding
On 90 hand-labeled agent transcripts:
| Judge | Raw agreement | Cohen's kappa |
|---|---|---|
| AssertionJudge | 73/90 (81%) | 0.000 |
| LLMJudge (v1) | 87/90 (97%) | 0.894 |
81% agreement sounds like a working instrument. It isn't one. The assertion judge passes every transcript, including all 17 the human failed — so its agreement is just the pass rate of the suite (73/90), and its kappa is 0 by construction: provably no better than chance.
Raw agreement can't tell you that, because it doesn't correct for the agreement you'd get by chance given the base rates. Cohen's kappa does. A judge that prints "pass" forever scores whatever the majority class happens to be, which on a well-built suite is a respectable-looking number. The calibrated LLM judge reaches kappa 0.894 ("almost perfect") on the same 90 transcripts.
This is the whole reason the harness measures kappa before trusting any
downstream number. (Details and caveats: docs/calibration.md.)
Architecture — everything is a protocol
The eval core is decoupled from any provider by three Python Protocols. The
runner, judges, and stats know only the interfaces:
  EvalCase (YAML)
        |
        v
     runner
        |
        v
  Agent.run(case) -> Transcript      <-- Agent protocol
        |                                AnthropicAdapter, OpenAIAdapter, FakeAgent,
        |                                or bring your own
        v
  ToolProvider.execute(name, args)   <-- ToolProvider protocol
        |                                mock / record / replay
        v
  Judge.score(case, transcript)      <-- Judge protocol
        |                                AssertionJudge, LLMJudge
        v
     Verdict
        |
        +----------------+----------------+
        v                v                v
      stats         calibration       regression
  Wilson, McNemar,  kappa vs human   store, diff, CI gate
       n=k
The agent under test is a black box behind Agent; aehf evaluates whatever
implements run(case) -> Transcript. The shipped AnthropicAdapter and
OpenAIAdapter are reference implementations, not the framework.
What's inside
- Runner — async, budget/timeout-enforced, captures agent crashes as failed cases (never harness crashes), bounded concurrency.
- Adapters — Anthropic and OpenAI, each enforcing the same step/token budgets
and mapping provider-specific stop reasons onto one
Terminationenum. - Tools — mock fixtures, plus record/replay for deterministic offline reruns.
- Judges — programmatic assertions and a versioned LLM judge with structured
(forced-tool) verdicts; calibrated against human labels with Cohen's kappa.
Bring your own judge prompt with
--judge-prompt-file, then measure its kappa before trusting it. - Stats — n-sample execution, per-case Wilson confidence intervals, flakiness flags, and McNemar's exact paired test for model/prompt comparison.
- Regression — results store keyed by (git SHA, model, judge version),
aehf diff, a markdown scorecard, and a PR-gate GitHub Action.
Install
pip install aehf                 # core (Anthropic adapter included)
pip install "aehf[openai]"       # + the OpenAI adapter
pip install -e ".[dev]"          # editable, with dev tooling
Set ANTHROPIC_API_KEY or OPENAI_API_KEY (a .env file is loaded
automatically) for anything that runs a live model. The test suite runs green
without a key — CI is free and offline; the two tests that do hit a provider
are marked live and deselected with -m "not live".
Quickstart
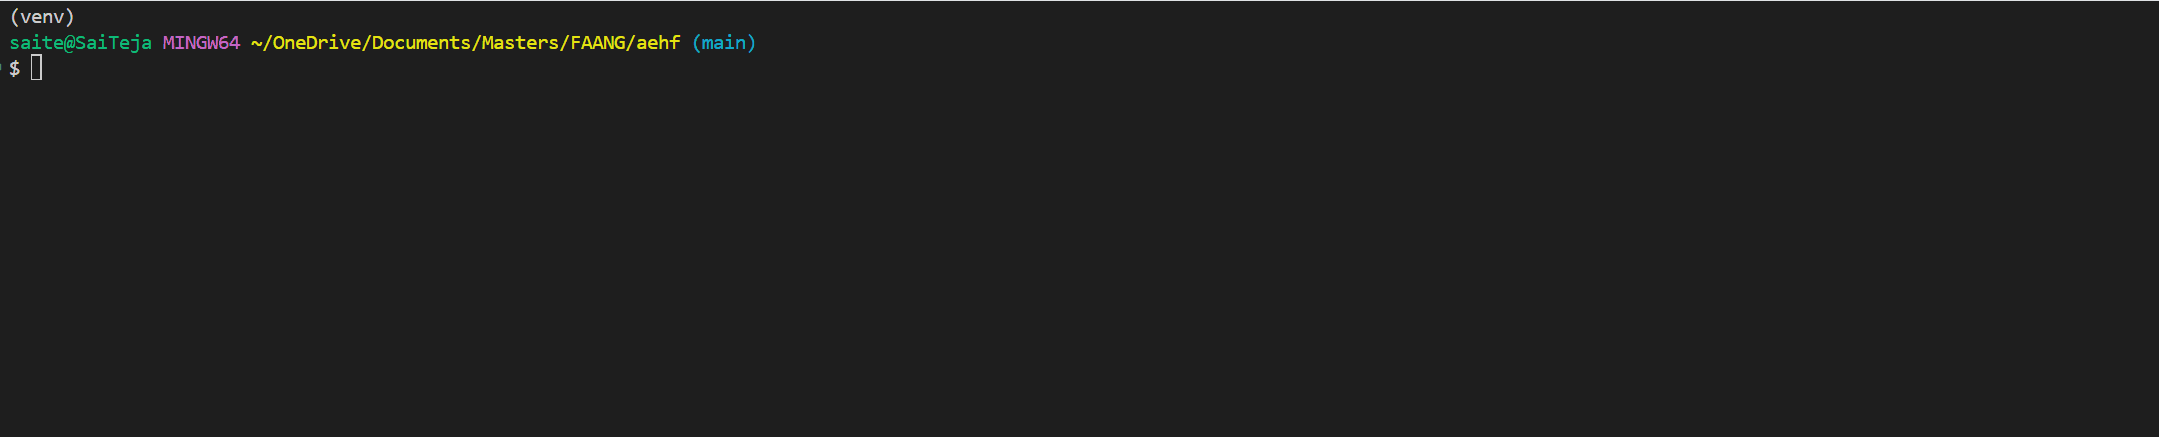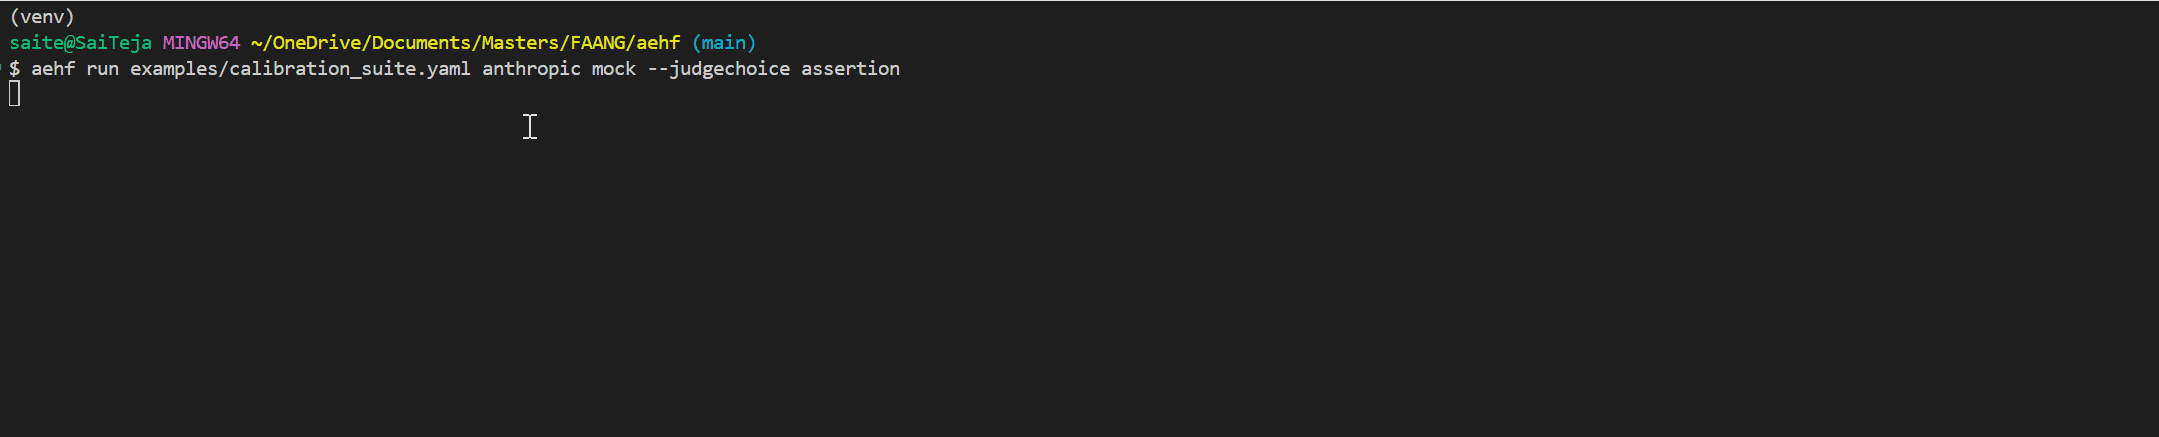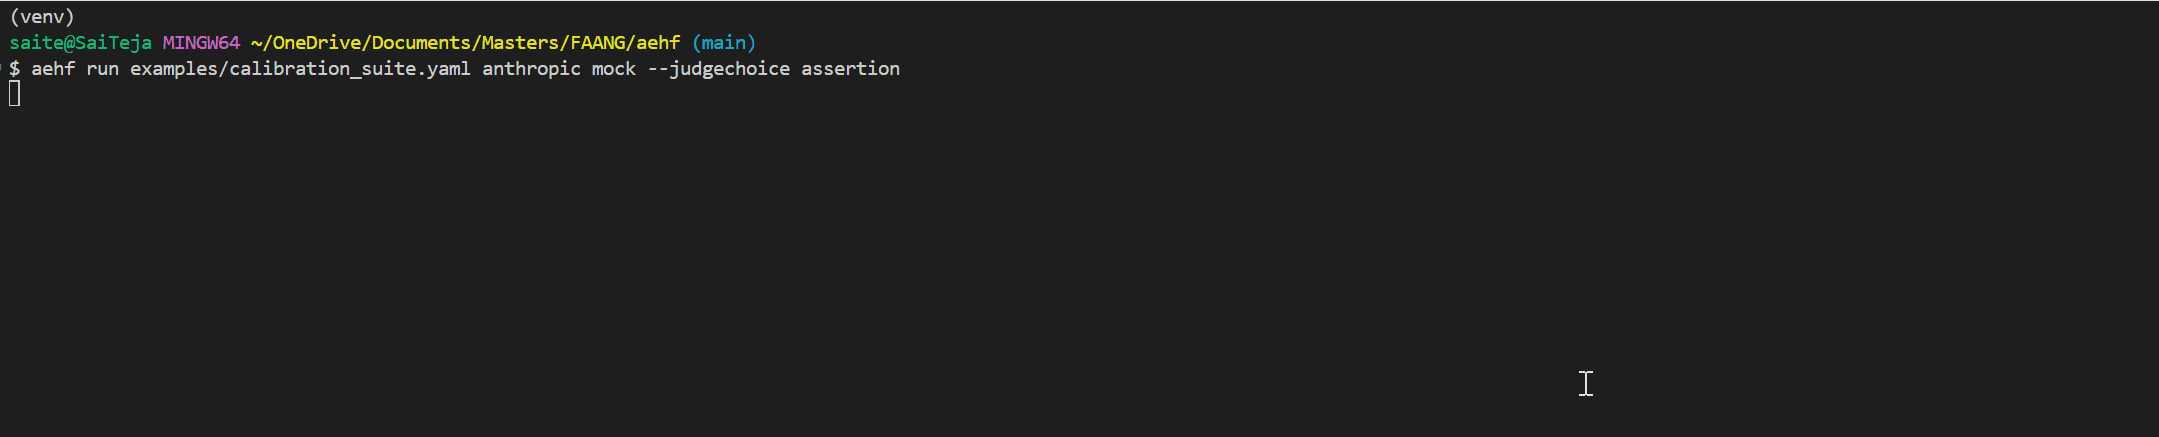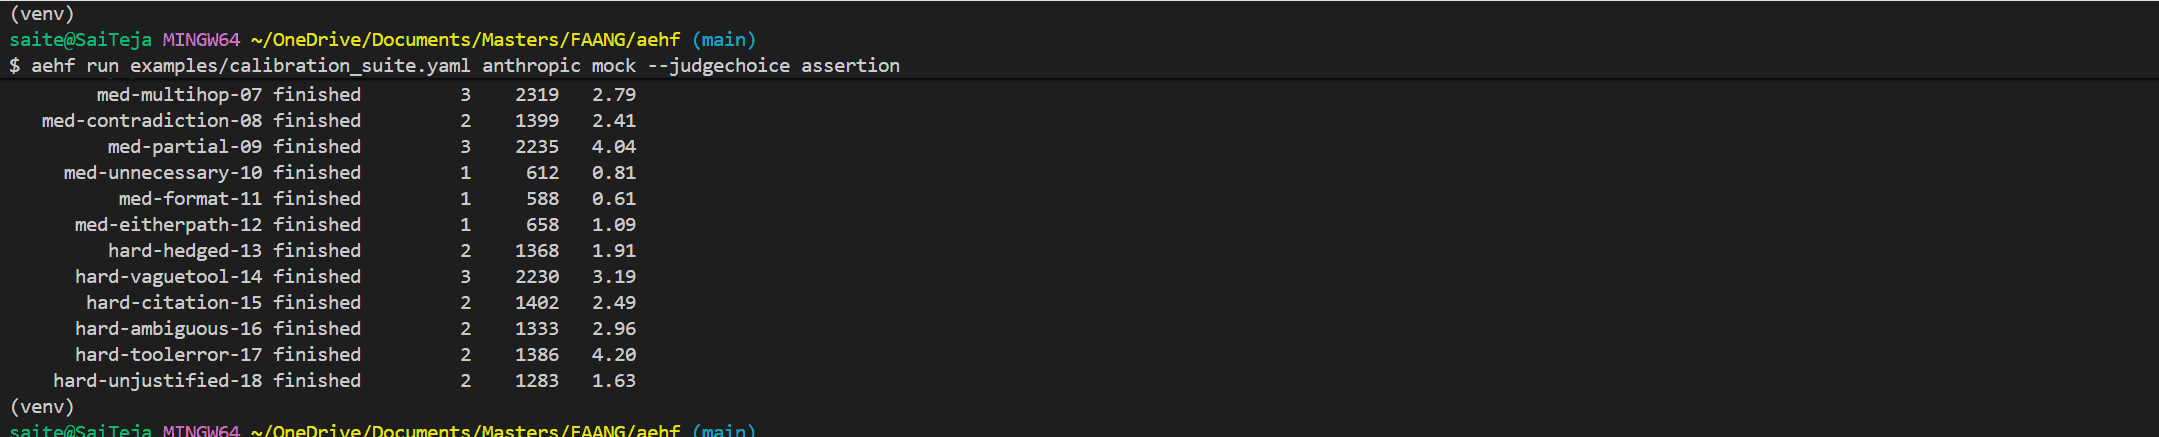
# run a suite with mock tools, assertion judge (no API cost for the judge)
aehf run examples/calibration_suite.yaml anthropic mock --judgechoice assertion

# n-sampled run: per-case pass rate + Wilson CI + flakiness
aehf run examples/calibration_suite.yaml anthropic mock --n-samples 5

# same suite, OpenAI instead (--model is required: the default is Anthropic's)
aehf run examples/calibration_suite.yaml openai mock --model gpt-4o-mini

# calibrate a judge against human labels -> Cohen's kappa + disagreements
aehf calibrate labels/labels_filled.jsonl llm --prompt-version v1

# bring your own judge prompt, then calibrate it before trusting its verdicts
aehf calibrate labels/labels_filled.jsonl llm --judge-prompt-file my_judge.txt

# compare two saved runs with McNemar's test
aehf compare runA.json runB.json

# regression diff between two stored runs (CI gate)
aehf diff <base-sha> <head-sha> --store .aehf
Full command list: run, calibrate, export-labels, label, compare,
diff.
Custom judge prompts
--judge-prompt-file (on both run and calibrate) swaps in your own rubric.
The file must contain the {task}, {rubric}, and {transcript} placeholders —
aehf checks up front and names the missing ones rather than failing mid-suite.
The prompt's identity is its content hash, not its filename: a custom prompt
is stored as file-<stem>-<sha256[:8]>, so editing it produces a new judge
version. That keeps aehf diff honest — it can never compare two runs graded by
different prompts and blame the difference on your agent.
An uncalibrated judge is an unvalidated instrument. Run calibrate with the same
--judge-prompt-file and check its kappa before you trust a number it produces.
Two findings, in one narrative
- Judge calibration — assertions kappa=0.00 -> LLM judge kappa=0.894 (n=90). The instrument is validated.
- Model comparison — using that validated judge, Haiku and Sonnet were
statistically indistinguishable on the suite (15/18 vs 14/18, McNemar
p=1.0). The apparent edge is noise; a single-run comparison would have misled.
(
docs/calibration.md.)
Both come with honest caveats stated in the docs (single annotator; a saturated
suite that can't discriminate the two models). Reporting the null result honestly
is the point — see docs/decision.md for every design choice and rejected
alternative.
Scope (v0.2)
- Ships Anthropic and OpenAI reference adapters behind the same
Agentprotocol — the framework-agnostic claim, demonstrated rather than asserted. The judge is Anthropic-backed; a provider-agnostic judge is the next step. - The CI eval gate compares committed baseline runs (golden-file style),
because replay pins tool results but not the model. See
docs/eval-gate.md. - Tested: 128 offline tests,
mypy --strictclean, ruff clean.
1 maintainer

Metadata
1 maintainer
Release files for aehf 0.2.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| aehf-0.2.2.tar.gz | 78.8 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| aehf-0.2.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 78.9 MB
Release files / aehf-0.2.2.tar.gz
| Download URL | aehf-0.2.2.tar.gz |
|---|---|
| Size | 78.8 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c8c1c53e73551b8cf6091fcda85b95b1124e046499c1853856d074d0f01b2840
|
|
BLAKE2b-256 checksum How to use checksums |
bfcaa21e719fe284f5a5d4e51de6089b9a64e4a1407e879567ada5e2d7979610
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.13.7
|
Release files / aehf-0.2.2-py3-none-any.whl
| Download URL | aehf-0.2.2-py3-none-any.whl |
|---|---|
| Size | 28.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
aabfbfe9d3c27d459d3a8868e5fb00f99782253ad5ea7d9041e9b617fd9705a5
|
|
BLAKE2b-256 checksum How to use checksums |
056977769dedfdb6df7bdcbd9a1a53772bb62128e900888746abd120ae83b325
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.13.7
|














