
autoLRP



Layer-wise Relevance Propagation propagates a logit back to the input space under one constraint: the logit equals the sum of the relevance that reaches the input.
This is a model-agnostic PyTorch implementation. It works at the operation level, so it needs no module rewriting and no module names. It acts on the torch operations the forward pass ran, following the philosophy of autograd, hence autoLRP.
import autolrp


x = autolrp.tensor(model_input)    # wrap the model input
out = model(x)                     # run the model
out[0, pred].lrp()                 # pick the class logit, call .lrp()
relevance_map = x.relevance        # same shape as model_input
pip install autolrp
Examples
A few of the notebooks in examples/showcase. Each wraps
the input, runs the model untouched, and reads .relevance back.
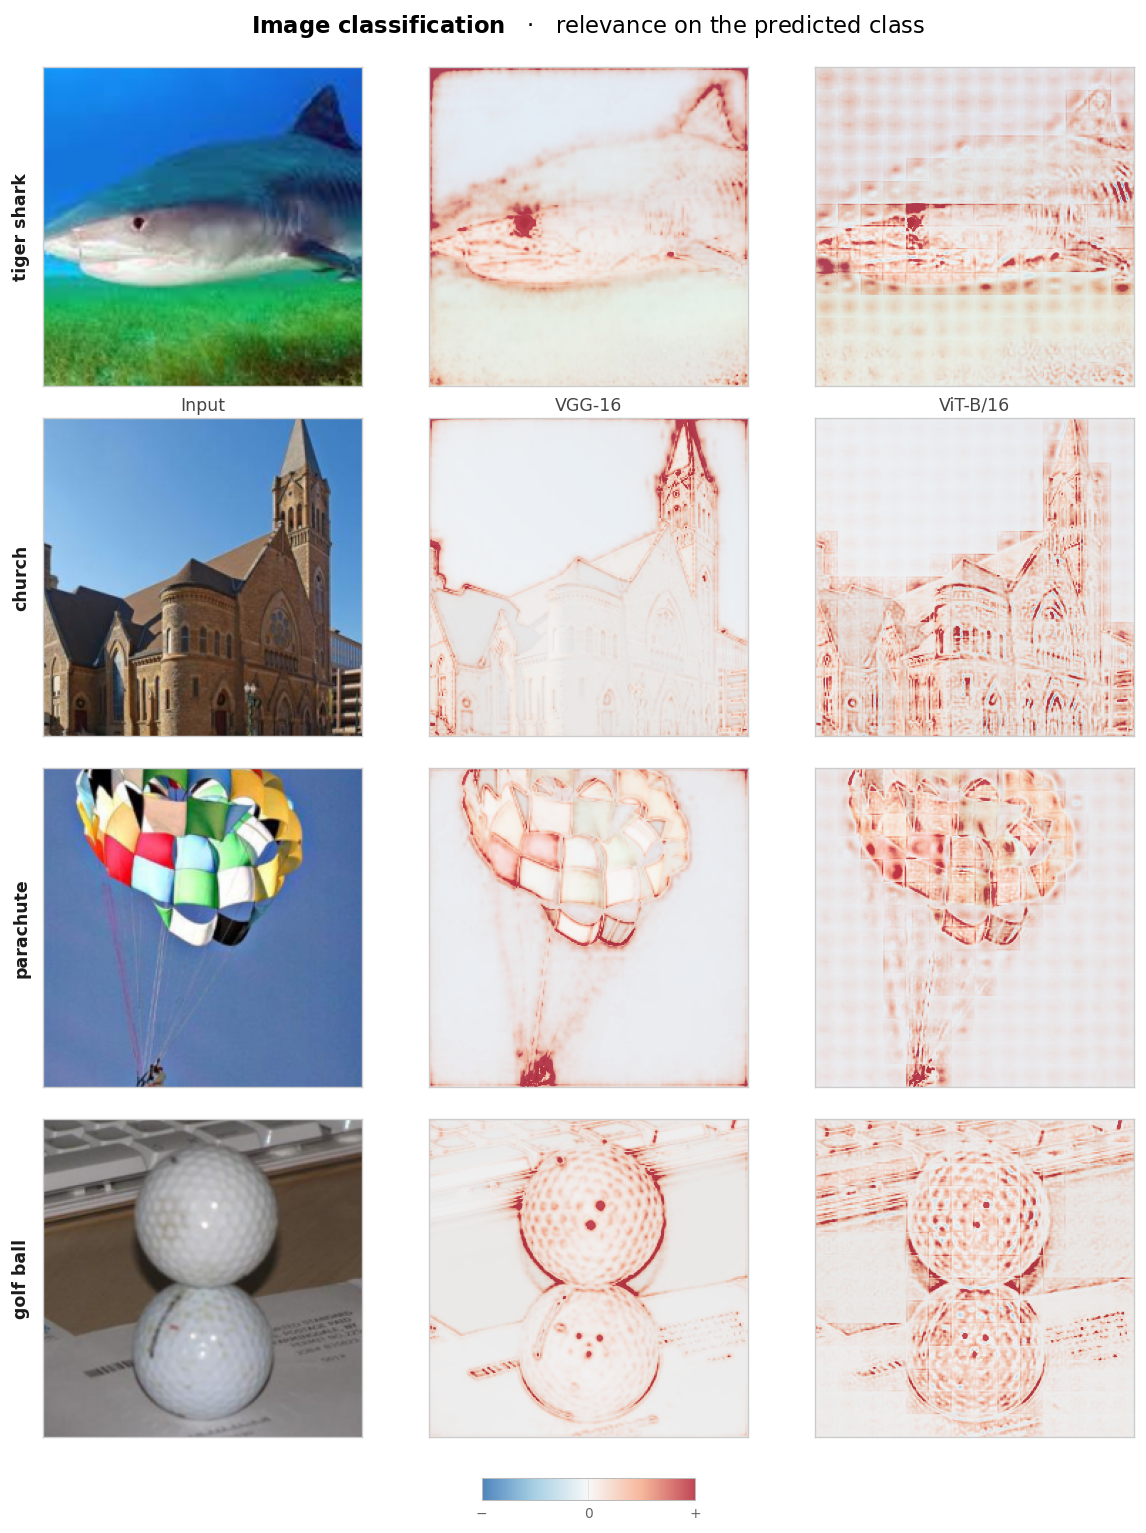
Image classification
Pixels behind the predicted class, across a CNN and a transformer. Notebooks: VGG-16, ViT-B/16
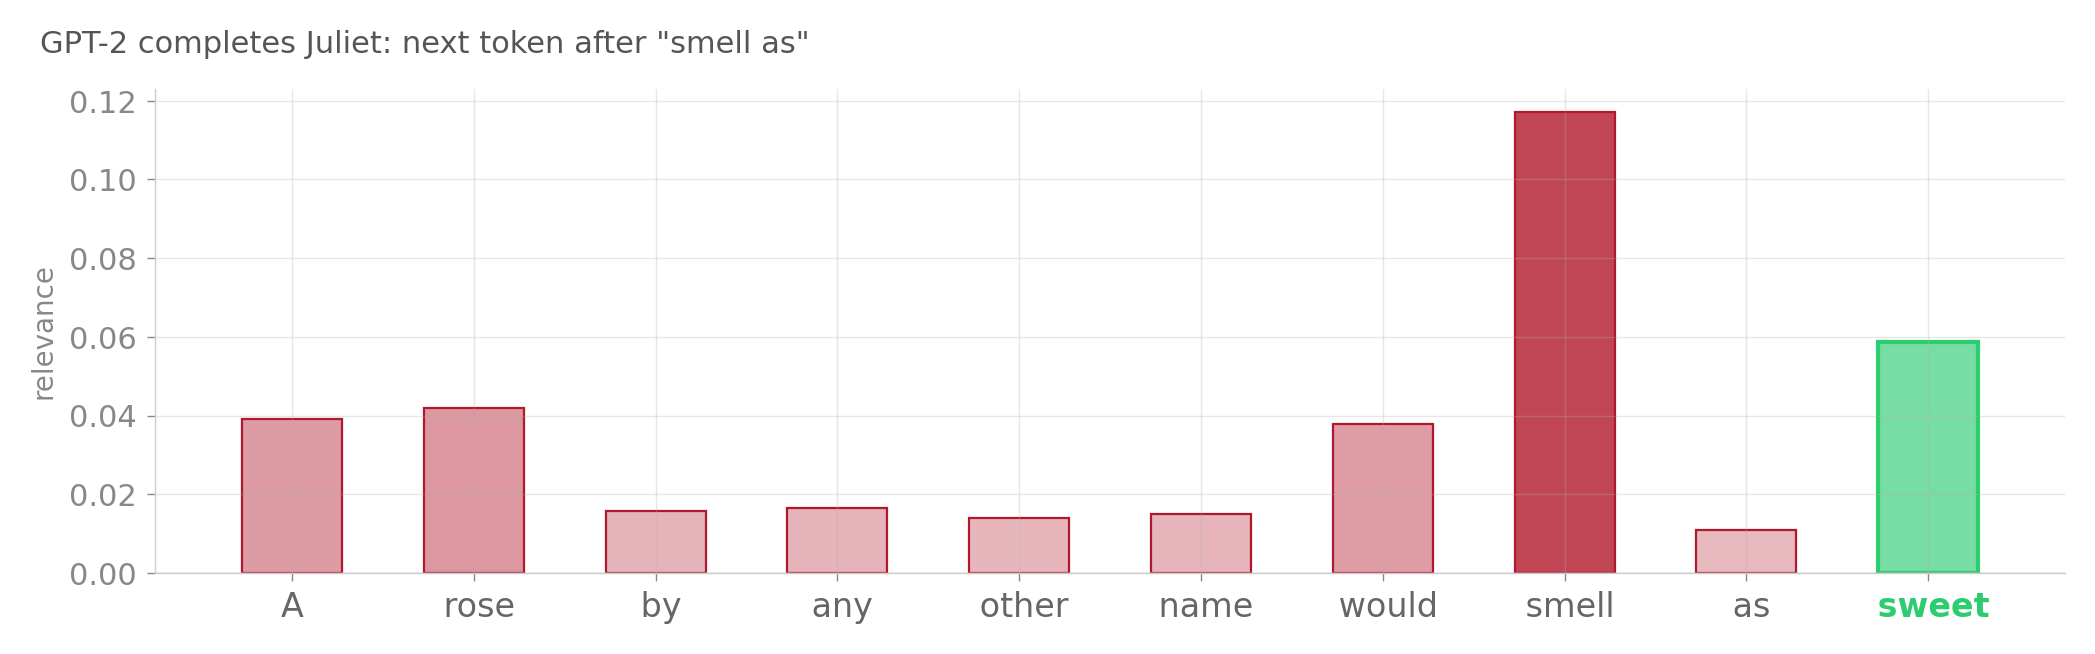
Next-token prediction
GPT-2: context tokens behind the next word.
Sentiment
BERT: words behind the decision.
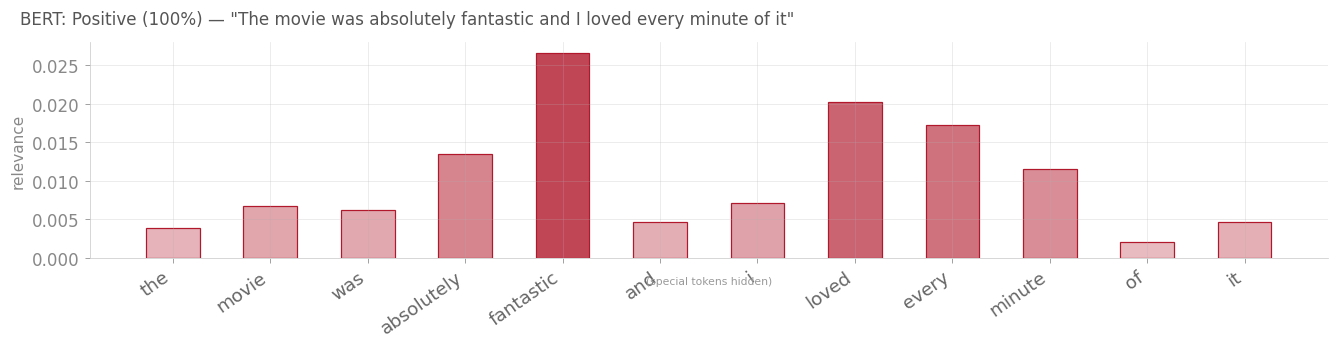
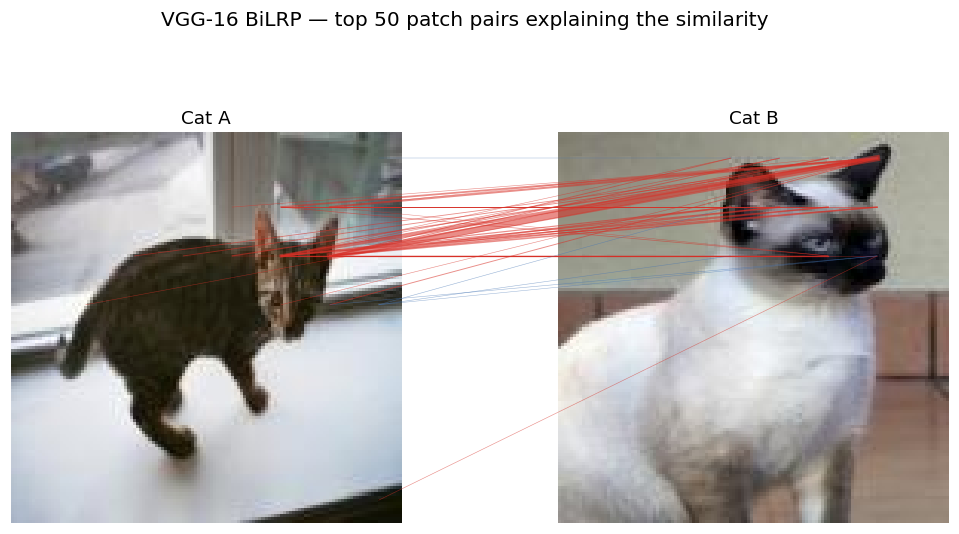
Image similarity (BiLRP)
Attributing a similarity score to the patch pairs that make two images alike. BiLRP, Eberle et al. 2020. Notebook: BiLRP
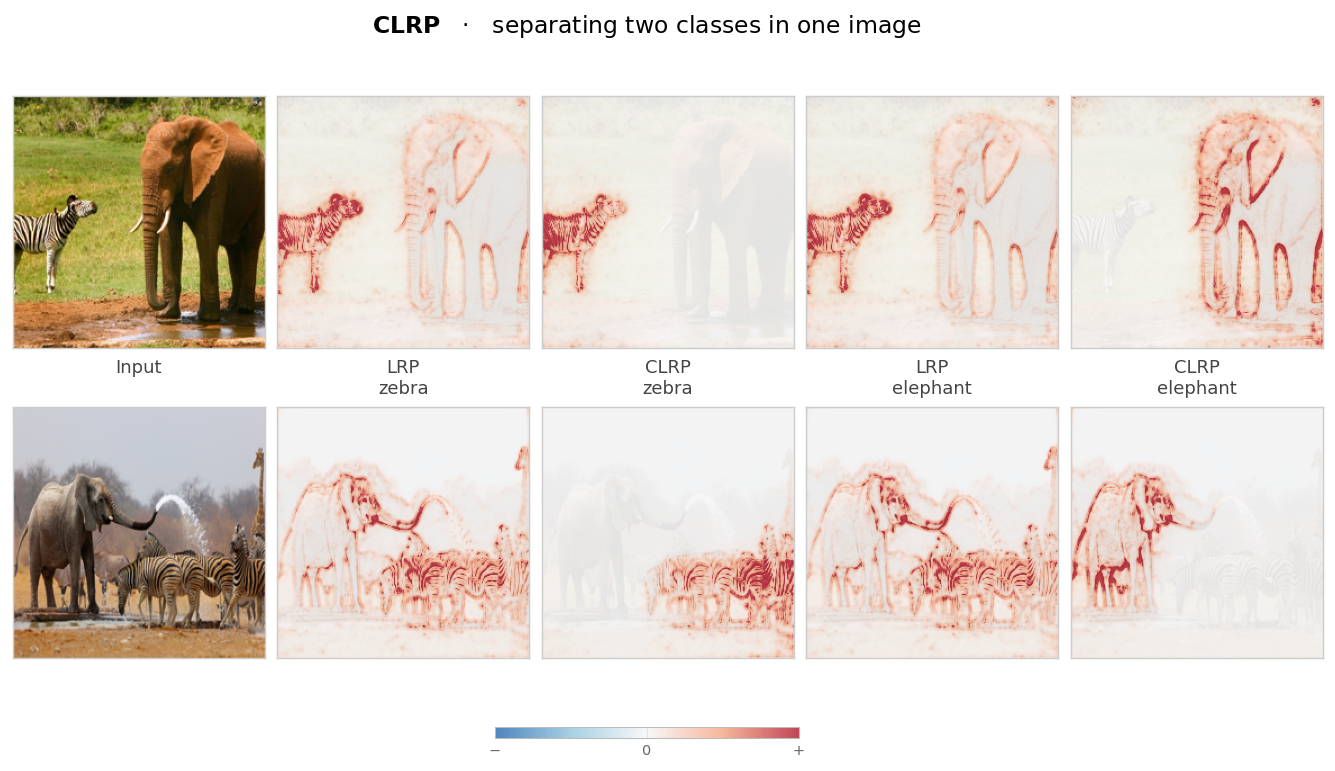
Contrastive attribution (CLRP)
Isolating what is distinctive to each of two classes in one image. CLRP, Gu et al. 2018. Notebook: CLRP
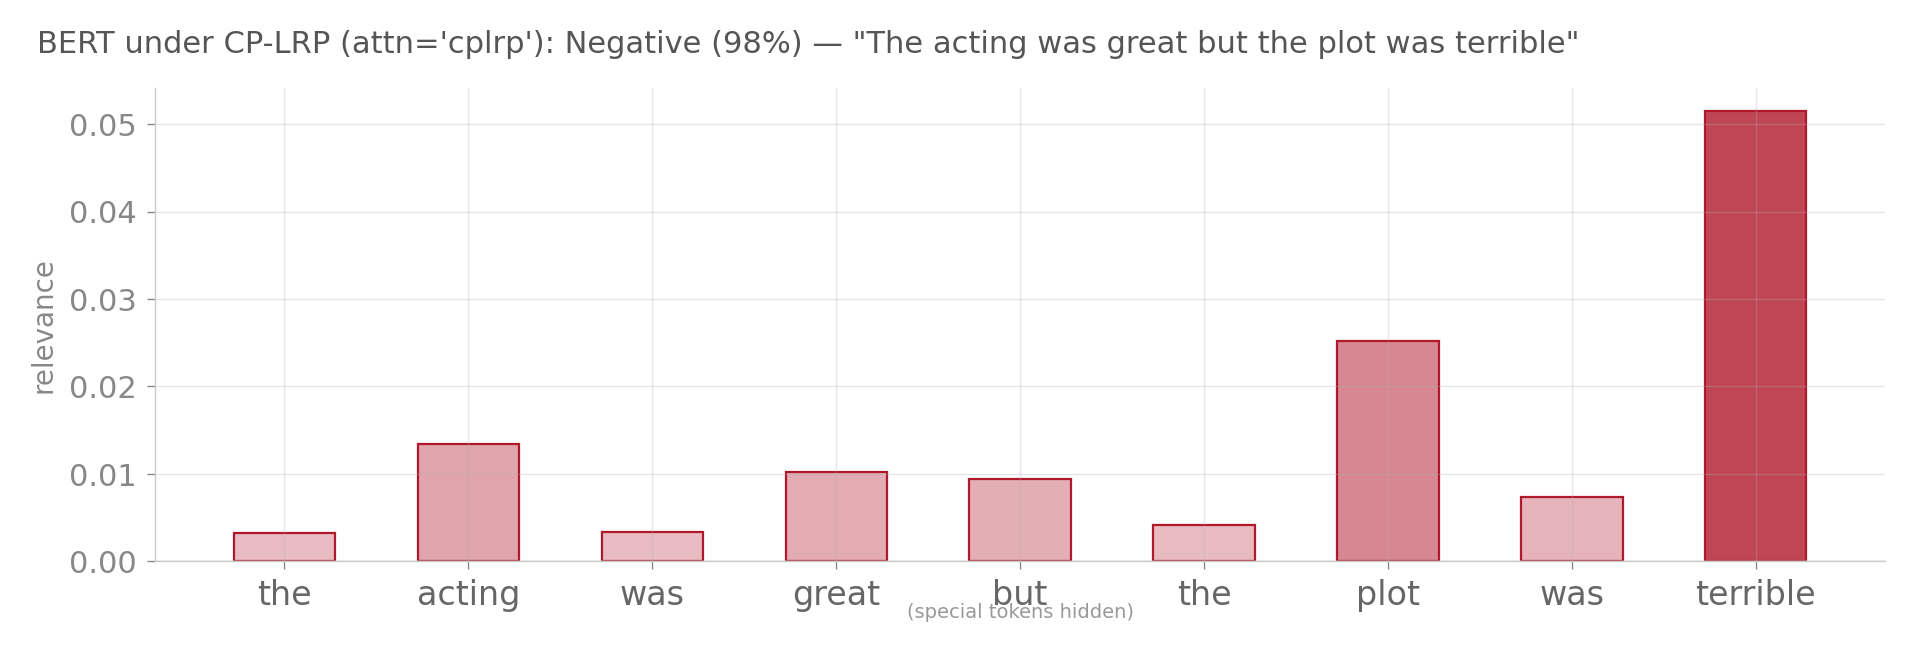
Attention rule variant (CP-LRP)
One preset fragment switches the attention rule (Ali et al. 2022). Notebook: attention presets
out[0, pred].lrp(config=LRPConfig(rule={**BASE, **CPLRP}))
How it works
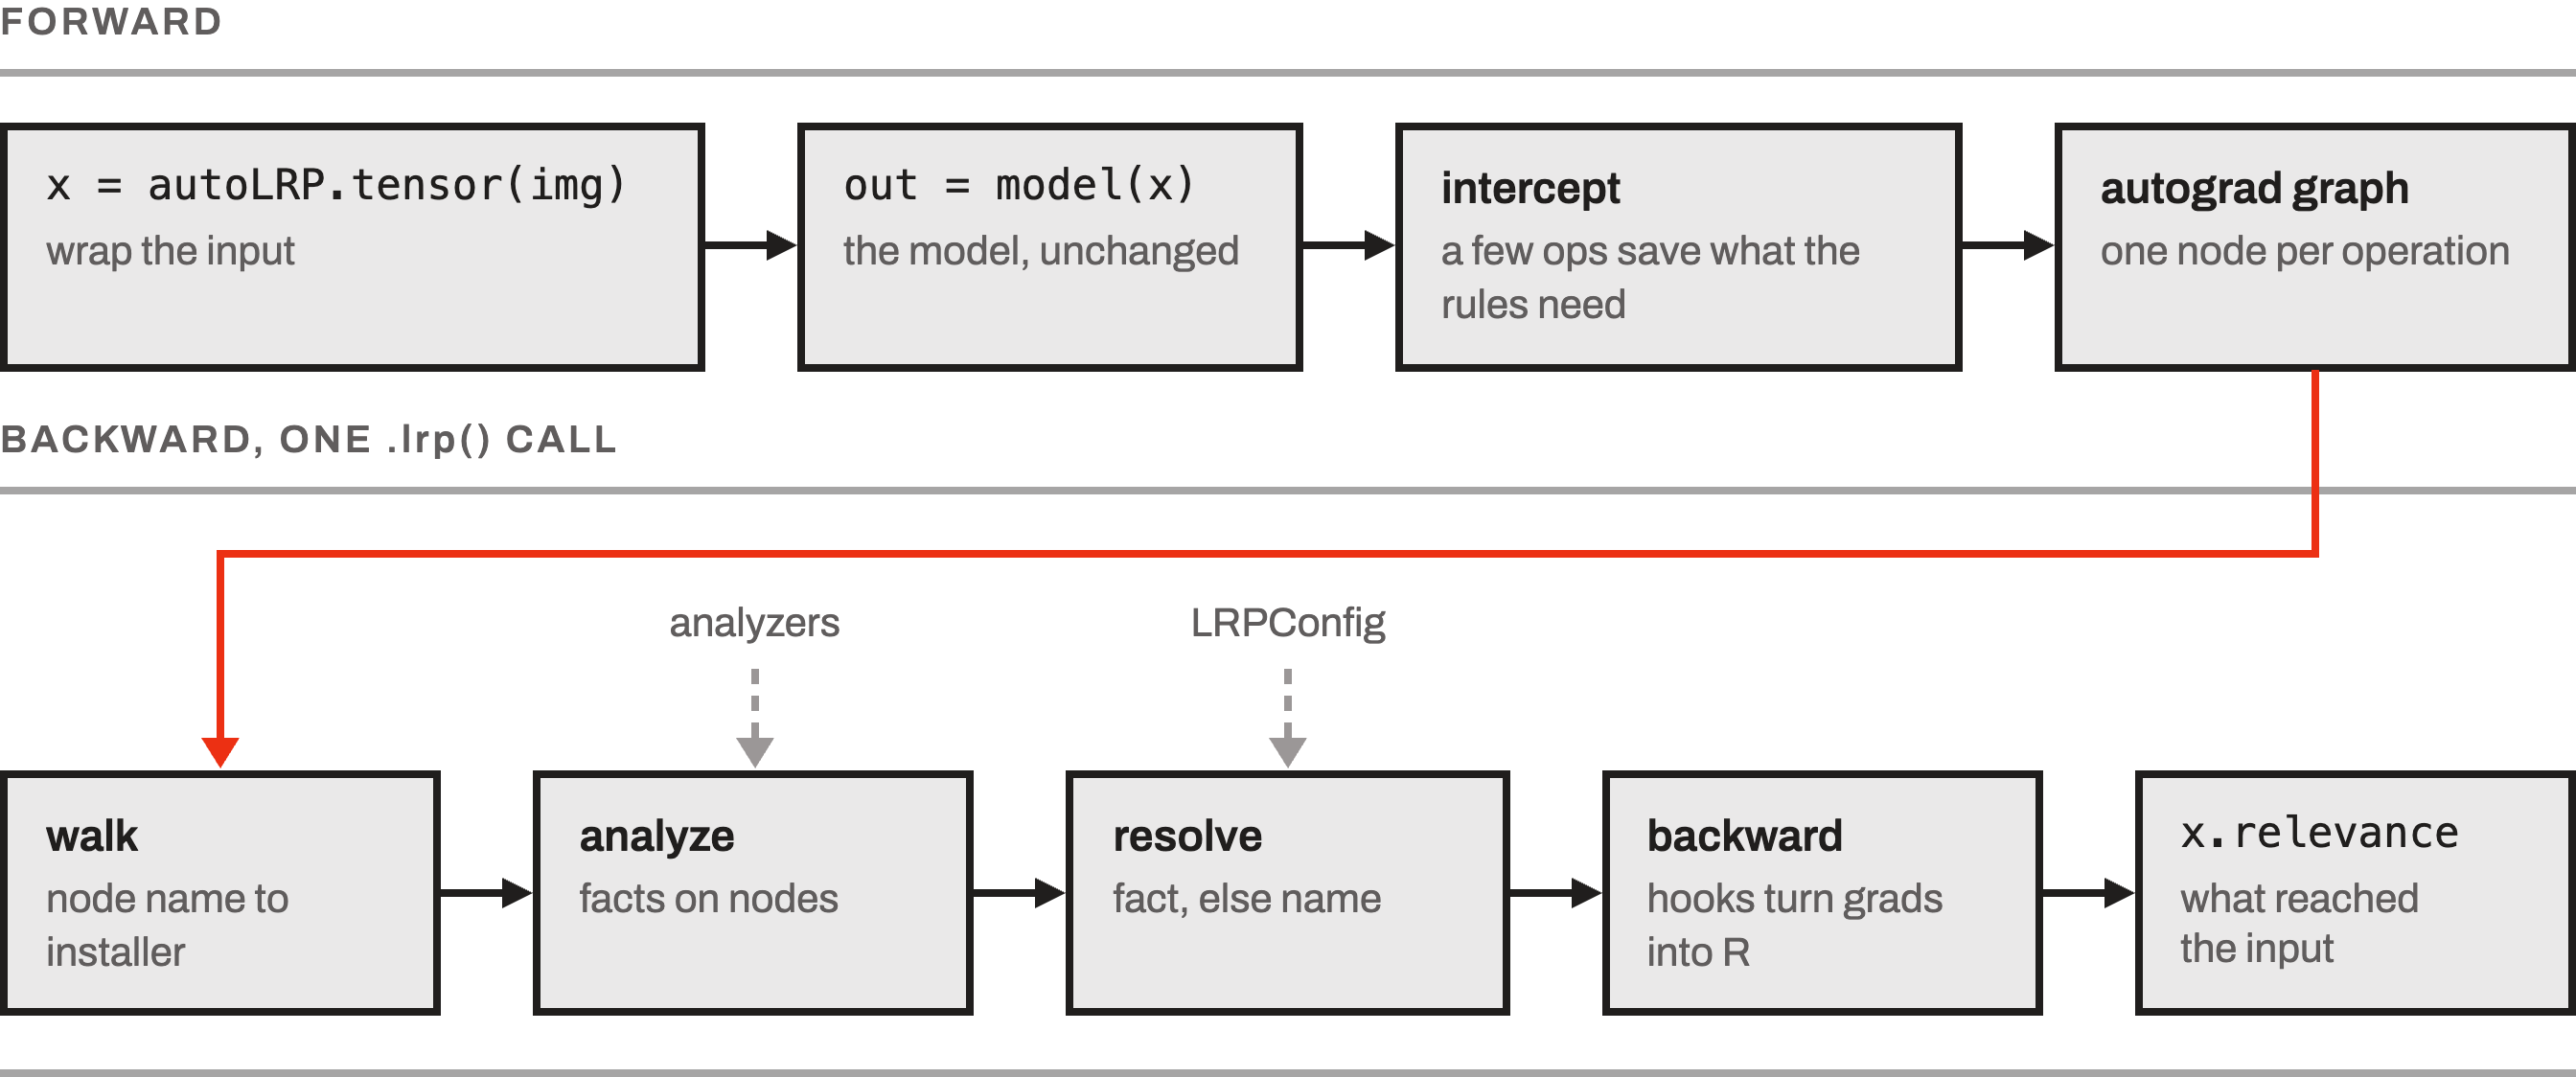
.lrp() never rewrites your model. It works on the autograd graph the forward
pass already built:
- wrap.
autolrp.tensor(x)marks the input. A handful of ops are replaced by versions that save the activations the rules need, and fused attention is written out as ordinary ops. Gradients stay native, so the graph is otherwise unchanged. - walk. After the forward pass, the autograd graph is traversed into an ordered plan of nodes.
- analyze. Analyzers tag nodes with facts, for example which operand of an attention product is the softmax weights.
- resolve. Each node gets one rule, chosen by the config from a fact on the node when it has one, otherwise from the node name.
- backward. One pass back to the wrapped input runs those rules as hooks
that turn the incoming gradient into relevance. What reaches the input is
x.relevance; the model's own.gradis never touched.
Configuration
A node is addressed by its autograd name without the version digit, or by a
fact an analyzer attached to it. BASE is the starting table; override entries
on it, or use a preset:
from autolrp import LRPConfig, BASE, CPLRP, ATTNLRP, UNIFORM, on, ELEMENTWISE_NODES

LRPConfig(rule={**BASE, 'AddmmBackward': 'zplus'})
LRPConfig(rule={**BASE, 'ConvolutionBackward': ('gamma', {'gamma': 0.25})})
LRPConfig(rule={**BASE, **on(ELEMENTWISE_NODES, 'yx')})
LRPConfig.composite()                 # z+ on conv, epsilon elsewhere
LRPConfig(rule={**BASE, **ATTNLRP})
LRPConfig(rule={**BASE, **CPLRP})
LRPConfig(rule={**BASE, **UNIFORM})
print(BASE) lists every key and the rule it runs. The config says exactly
that: a key that is not a node name or a registered fact, a rule the key cannot
run, and a node that no entry addresses are all errors.
LRPConfig(rule={**BASE, 'linear': 'zplus'})
  ValueError: unknown rule key 'linear': not a node name [...]
LRPConfig(rule={**BASE, 'MulBackward': 'zbox'})
  ValueError: rule entry 'MulBackward'='zbox': 'zbox' is not a choice here. Choices: ['proportional']
Citing
If you use autoLRP in your research, please cite it:
@software{alasad2026autolrp,
  author  = {Alasad, Waleed},
  title   = {autoLRP: Layer-wise Relevance Propagation on the PyTorch autograd graph},
  year    = {2026},
  version = {0.2.0},
  url     = {https://github.com/Wa-lead/autoLRP}
}
License
autoLRP is released under the MIT License. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for autoLRP 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| autolrp-0.2.0.tar.gz | 78.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| autolrp-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 136.9 kB
Release files / autolrp-0.2.0.tar.gz
| Download URL | autolrp-0.2.0.tar.gz |
|---|---|
| Size | 78.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c7b1268d8666f69368ccbc04bf736204e81e7d5db0c24444cd099e831752d8b0
|
|
BLAKE2b-256 checksum How to use checksums |
835049dc8fb0816f5a811e089c606988a0ce070628e452f84f5b692318ad35ab
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Release files / autolrp-0.2.0-py3-none-any.whl
| Download URL | autolrp-0.2.0-py3-none-any.whl |
|---|---|
| Size | 58.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
2800190ab3befc8f9a0e6c493ffb3c35968c2427cb6768cf391b42b6fb748921
|
|
BLAKE2b-256 checksum How to use checksums |
f9dd720f5ac56180206e838d2d51434c90d4f29450debf8f06262bbc5919fc8f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|














