
Welcome to Charset Detection for Human 👋 
The Real First Universal Charset Detector


Library that help you read text from unknown charset encoding.
Project motivated bychardet, I'm trying to resolve the issue by taking another approach. All IANA character set names for which the Python core library provides codecs are supported.
>>>>> ❤️ Try Me Online NOW ! Then Adopt Me ❤️ <<<<<
This project offer you a alternative to Universal Charset Encoding Detector, also known as Chardet.
| Feature | Chardet | Charset Normalizer | cChardet |
|---|---|---|---|
Fast |
❌ |
✅ |
✅ ⚡ |
Universal** |
❌ | ✅ | ❌ |
Reliable without distinguishable standards |
❌ | ✅ | ✅ |
Reliable with distinguishable standards |
✅ | ✅ | ✅ |
Free & Open |
✅ | ✅ | ✅ |
Native Python |
✅ | ✅ | ❌ |
Detect spoken language |
❌ | ✅ | N/A |

** : They are clearly using specific code for a specific charset even if covering most of existing one
Your support
Please ⭐ this repository if this project helped you!
✨ Installation
Using PyPi
pip install charset_normalizer
🚀 Basic Usage
CLI
This package come with a CLI
usage: normalizer [-h] [--verbose] [--normalize] [--replace] [--force]
                  file [file ...]
normalizer ./data/sample.1.fr.srt
+----------------------+----------+----------+------------------------------------+-------+-----------+
|       Filename       | Encoding | Language |             Alphabets              | Chaos | Coherence |
+----------------------+----------+----------+------------------------------------+-------+-----------+
| data/sample.1.fr.srt |  cp1252  |  French  | Basic Latin and Latin-1 Supplement | 0.0 % |  84.924 % |
+----------------------+----------+----------+------------------------------------+-------+-----------+
Python
Just print out normalized text
from charset_normalizer import CharsetNormalizerMatches as CnM
print(CnM.from_path('./my_subtitle.srt').best().first())
Normalize any text file
from charset_normalizer import CharsetNormalizerMatches as CnM
try:
    CnM.normalize('./my_subtitle.srt') # should write to disk my_subtitle-***.srt
except IOError as e:
    print('Sadly, we are unable to perform charset normalization.', str(e))
Upgrade your code without effort
from charset_normalizer import detect
Above code will behave the same as chardet.
See wiki for advanced usages. Todo, not yet available.
😇 Why
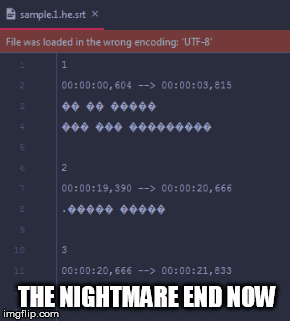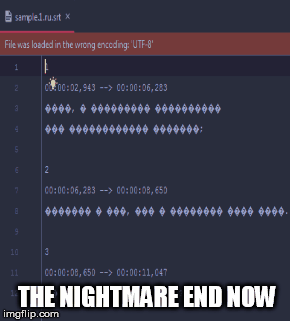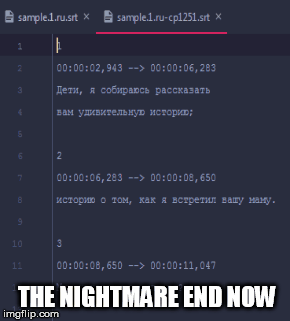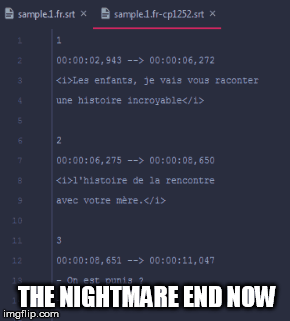
When I started using Chardet, I noticed that this library was wrong most of the time when it's not about Unicode, Gb or Big5. That because some charset are easily identifiable because of there standards and Chardet does a really good job at identifying them.
I don't care about the originating charset encoding, that because two different table can produce two identical file. What I want is to get readable text, the best I can.
In a way, I'm brute forcing text decoding. How cool is that ? 😎
🍰 How
- Discard all charset encoding table that could not fit the binary content.
- Measure chaos, or the mess once opened with a corresponding charset encoding.
- Extract matches with the lowest mess detected.
- Finally, if there is too much match left, we measure coherence.
Wait a minute, what is chaos/mess and coherence according to YOU ?
Chaos : I opened hundred of text files, written by humans, with the wrong encoding table. I observed, then I established some ground rules about what is obvious when it seems like a mess. I know that my interpretation of what is chaotic is very subjective, feel free to contribute in order to improve or rewrite it.
Coherence : For each language there is on earth (the best we can), we have computed letter appearance occurrences ranked. So I thought that those intel are worth something here. So I use those records against decoded text to check if I can detect intelligent design.
⚡ Known limitations
- Not intended to work on non (human) speakable language text content. eg. crypted text.
- When provided trust encoding in headers first. (XML, HTML, HTTP, etc..)
- Language detection is unreliable when text contain more than 1 language that are sharing identical letters.
- Not well tested with tiny content
👤 Contributing
Contributions, issues and feature requests are very much welcome.
Feel free to check issues page if you want to contribute.
📝 License
Copyright © 2019 Ahmed TAHRI @Ousret.
This project is MIT licensed.
Letter appearances frequencies used in this project © 2012 Denny Vrandečić
1 maintainer

Release files for charset-normalizer 1.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| charset_normalizer-1.1.1.tar.gz | 342.8 kB | Details |
Release files / charset_normalizer-1.1.1.tar.gz
| Download URL | charset_normalizer-1.1.1.tar.gz |
|---|---|
| Size | 342.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1537f9cc91b1875ab27dfdd91ec27491d0d003eaedc4b11de704c6a4f292cfd3
|
|
BLAKE2b-256 checksum How to use checksums |
b7c28976bc70a6d8869c91ba93c983cf088f92cb057e5a111b5e0495acf7f2f4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/1.13.0 pkginfo/1.5.0.1 requests/2.22.0 setuptools/41.0.1 requests-toolbelt/0.9.1 tqdm/4.32.2 CPython/3.7.3
|














