
Charset Detection, for Everyone 👋 
The Real First Universal Charset Detector


A library that helps you read text from an unknown charset encoding.
Motivated bychardet, I'm trying to resolve the issue by taking a new approach. All IANA character set names for which the Python core library provides codecs are supported.
>>>>> 👉 Try Me Online Now, Then Adopt Me 👈 <<<<<
This project offers you an alternative to Universal Charset Encoding Detector, also known as Chardet.
| Feature | Chardet | Charset Normalizer | cChardet |
|---|---|---|---|
Fast |
❌ |
✅ |
✅ |
Universal** |
❌ | ✅ | ❌ |
Reliable without distinguishable standards |
❌ | ✅ | ✅ |
Reliable with distinguishable standards |
✅ | ✅ | ✅ |
Free & Open |
✅ | ✅ | ✅ |
License |
LGPL-2.1 | MIT | MPL-1.1 |
Native Python |
✅ | ✅ | ❌ |
Detect spoken language |
❌ | ✅ | N/A |
Supported Encoding |
30 | 🎉 92 | 40 |
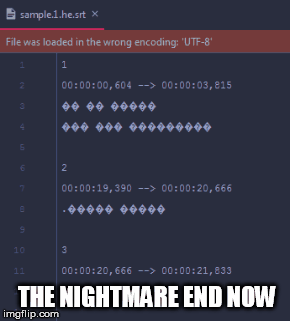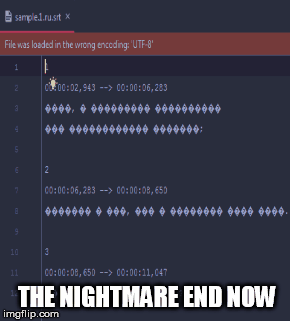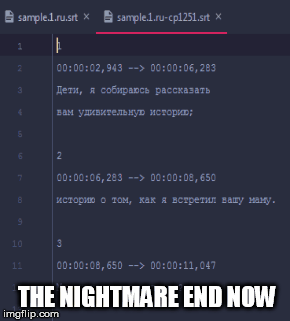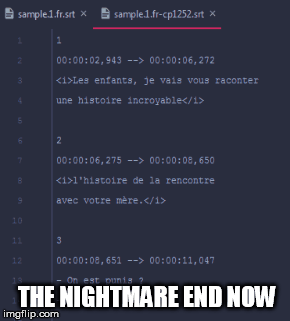
** : They are clearly using specific code for a specific encoding even if covering most of used one
⚡ Performance
This package offer better performance than its counterpart Chardet. Here are some numbers.
| Package | Accuracy | Mean per file (ns) | File per sec (est) |
|---|---|---|---|
| chardet | 93.0 % | 67 ms | 15.38 file/sec |
| charset-normalizer | 95.0 % | 37 ms | 27.77 file/sec |
| Package | 99th percentile | 95th percentile | 50th percentile |
|---|---|---|---|
| chardet | 424 ms | 234 ms | 26 ms |
| charset-normalizer | 335 ms | 186 ms | 17 ms |
Chardet's performance on larger file (1MB+) are very poor. Expect huge difference on large payload.
Stats are generated using 400+ files using default parameters. More details on used files, see GHA workflows.
cchardet is a non-native (cpp binding) faster alternative. If speed is the most important factor, you should try it.
Your support
Please ⭐ this repository if this project helped you!
✨ Installation
Using PyPi for latest stable
pip install charset-normalizer
Or directly from dev-master for latest preview
pip install git+https://github.com/Ousret/charset_normalizer.git
🚀 Basic Usage
CLI
This package comes with a CLI.
usage: normalizer [-h] [-v] [-a] [-n] [-m] [-r] [-f] [-t THRESHOLD]
                  file [file ...]

The Real First Universal Charset Detector. Discover originating encoding used
on text file. Normalize text to unicode.

positional arguments:
  files                 File(s) to be analysed

optional arguments:
  -h, --help            show this help message and exit
  -v, --verbose         Display complementary information about file if any.
                        Stdout will contain logs about the detection process.
  -a, --with-alternative
                        Output complementary possibilities if any. Top-level
                        JSON WILL be a list.
  -n, --normalize       Permit to normalize input file. If not set, program
                        does not write anything.
  -m, --minimal         Only output the charset detected to STDOUT. Disabling
                        JSON output.
  -r, --replace         Replace file when trying to normalize it instead of
                        creating a new one.
  -f, --force           Replace file without asking if you are sure, use this
                        flag with caution.
  -t THRESHOLD, --threshold THRESHOLD
                        Define a custom maximum amount of chaos allowed in
                        decoded content. 0. <= chaos <= 1.
  --version             Show version information and exit.
normalizer ./data/sample.1.fr.srt
🎉 Since version 1.4.0 the CLI produce easily usable stdout result in JSON format.
{
    "path": "/home/default/projects/charset_normalizer/data/sample.1.fr.srt",
    "encoding": "cp1252",
    "encoding_aliases": [
        "1252",
        "windows_1252"
    ],
    "alternative_encodings": [
        "cp1254",
        "cp1256",
        "cp1258",
        "iso8859_14",
        "iso8859_15",
        "iso8859_16",
        "iso8859_3",
        "iso8859_9",
        "latin_1",
        "mbcs"
    ],
    "language": "French",
    "alphabets": [
        "Basic Latin",
        "Latin-1 Supplement"
    ],
    "has_sig_or_bom": false,
    "chaos": 0.149,
    "coherence": 97.152,
    "unicode_path": null,
    "is_preferred": true
}
Python
Just print out normalized text
from charset_normalizer import from_path
print(from_path('./my_subtitle.srt').best())
Normalize any text file
from charset_normalizer import normalize
try:
    normalize('./my_subtitle.srt') # should write to disk my_subtitle-***.srt
except IOError as e:
    print('Sadly, we are unable to perform charset normalization.', str(e))
Upgrade your code without effort
from charset_normalizer import detect
The above code will behave the same as chardet. We ensure that we offer the best (reasonable) BC result possible.
See the docs for advanced usage : readthedocs.io
😇 Why
When I started using Chardet, I noticed that it was not suited to my expectations, and I wanted to propose a reliable alternative using a completely different method. Also! I never back down on a good challenge !
I don't care about the originating charset encoding, because two different tables can produce two identical files. What I want is to get readable text, the best I can.
In a way, I'm brute forcing text decoding. How cool is that ? 😎
Don't confuse package ftfy with charset-normalizer or chardet. ftfy goal is to repair unicode string whereas charset-normalizer to convert raw file in unknown encoding to unicode.
🍰 How
- Discard all charset encoding table that could not fit the binary content.
- Measure chaos, or the mess once opened (by chunks) with a corresponding charset encoding.
- Extract matches with the lowest mess detected.
- Finally, if there is too much match left, we measure coherence.
Wait a minute, what is chaos/mess and coherence according to YOU ?
Chaos : I opened hundred of text files, written by humans, with the wrong encoding table. I observed, then I established some ground rules about what is obvious when it seems like a mess. I know that my interpretation of what is chaotic is very subjective, feel free to contribute in order to improve or rewrite it.
Coherence : For each language there is on earth, we have computed ranked letter appearance occurrences (the best we can). So I thought that intel is worth something here. So I use those records against decoded text to check if I can detect intelligent design.
⚡ Known limitations
- Language detection is unreliable when text contains two or more languages sharing identical letters. (eg. HTML (english tags) + Turkish content (Sharing Latin characters))
- Every charset detector heavily depends on sufficient content. In common cases, do not bother run detection on very tiny content.
👤 Contributing
Contributions, issues and feature requests are very much welcome.
Feel free to check issues page if you want to contribute.
📝 License
Copyright © 2019 Ahmed TAHRI @Ousret.
This project is MIT licensed.
Characters frequencies used in this project © 2012 Denny Vrandečić
1 maintainer

Metadata
1 maintainer
Release files for charset-normalizer 2.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| charset-normalizer-2.0.0.tar.gz | 345.0 kB | Without provenance | Details for charset-normalizer-2.0.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| charset_normalizer-2.0.0-py3-none-any.whl | Python 3 | none | any | Details for charset_normalizer-2.0.0-py3-none-any.whl |
Total release size: 380.4 kB
Release files / charset-normalizer-2.0.0.tar.gz
| Download URL | charset-normalizer-2.0.0.tar.gz |
|---|---|
| Size | 345.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
878bfe99324a9f3191e9a0f555e52ca2e0e1ad14b69802bc3f9a7afc71ffcfa4
|
|
BLAKE2b-256 checksum How to use checksums |
0914f67539d35d38259cb8a03aa0587324dd75f36beb9ce586bcfb04d085dd7a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.4.1 importlib_metadata/4.6.0 pkginfo/1.7.0 requests/2.25.1 requests-toolbelt/0.9.1 tqdm/4.61.1 CPython/3.9.5
|
Release files / charset_normalizer-2.0.0-py3-none-any.whl
| Download URL | charset_normalizer-2.0.0-py3-none-any.whl |
|---|---|
| Size | 35.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
76fd234253352853909a367630ea0040001df0b4f6e9cb655a7bf861e81a6d32
|
|
BLAKE2b-256 checksum How to use checksums |
1c04d23d56e93655f3152a8b6d9377c0558a5d9666b04c7694e4b67c02768dfd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.4.1 importlib_metadata/4.6.0 pkginfo/1.7.0 requests/2.25.1 requests-toolbelt/0.9.1 tqdm/4.61.1 CPython/3.9.5
|
Security for charset-normalizer 2.0.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














