
Welcome to the Friend or Foe repository!
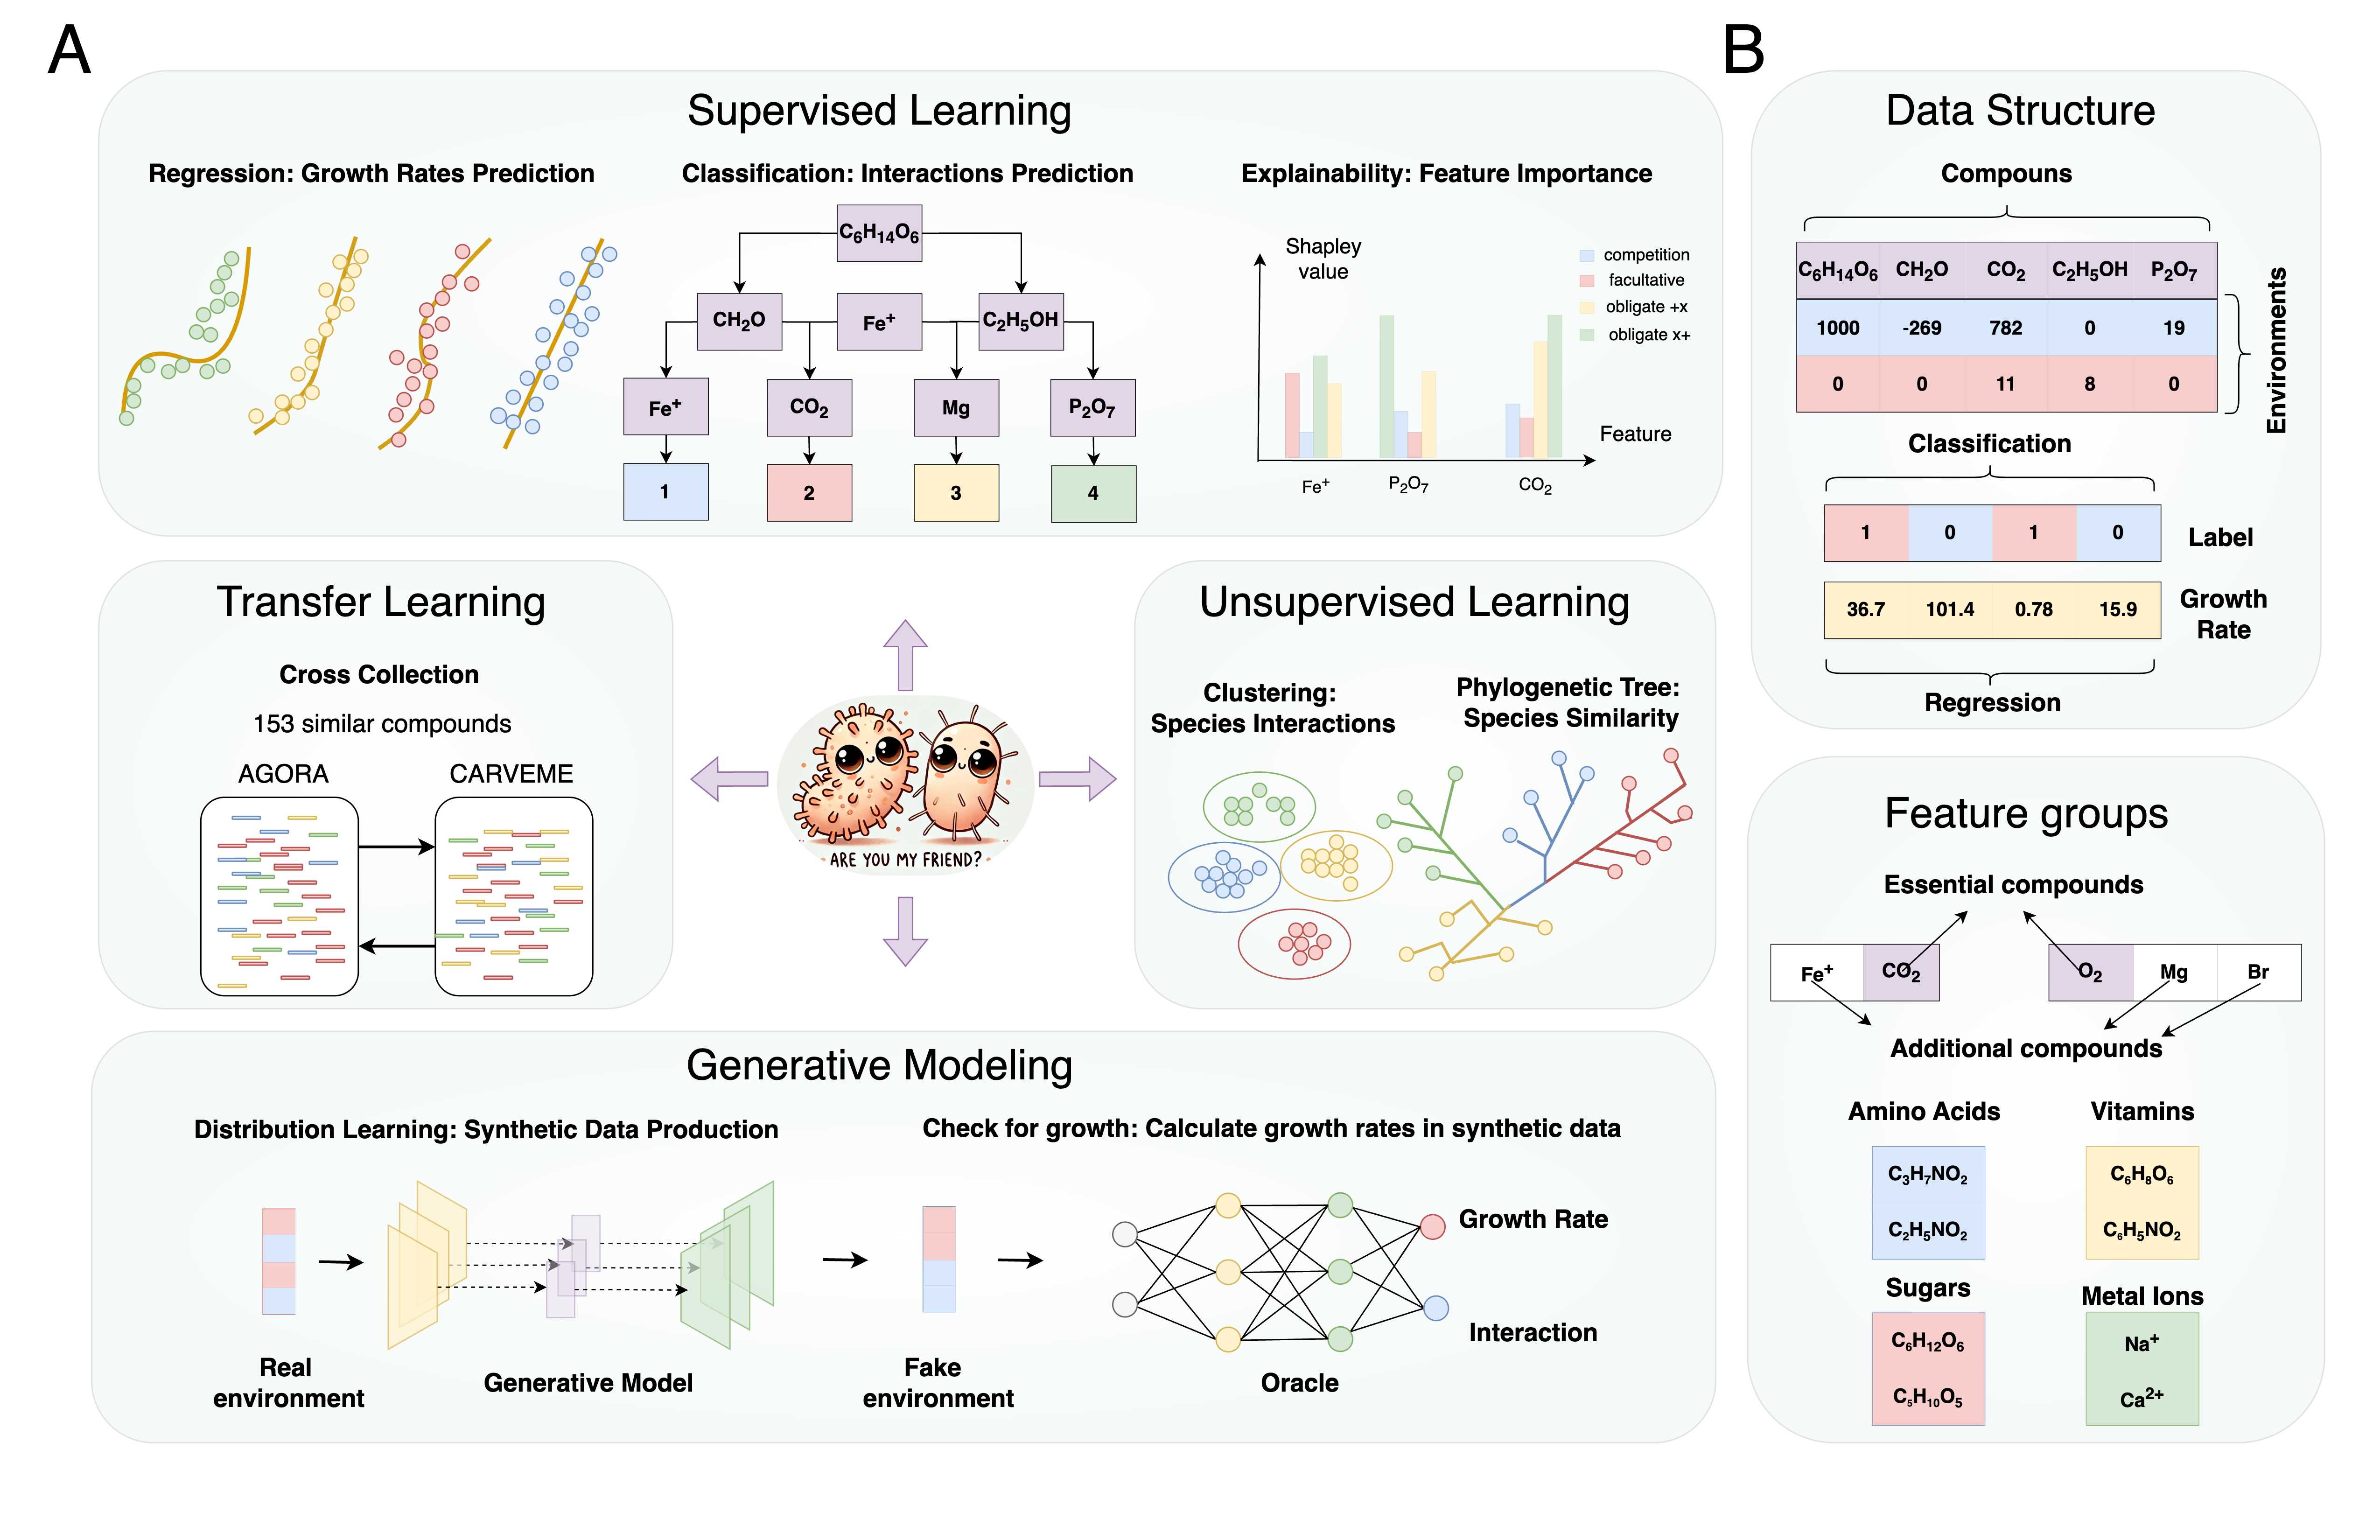
FriendOrFoe is a collection of environmental datasets obtained from metabolic modeling of microbial communities AGORA and CARVEME. FriendOrFoe gathers 64 tabular datasets (16 for AGORA with 100 additional compounds, 16 for AGORA with 50 additional compounds, 16 for CARVEME with 100 additional compounds, 16 for CARVEME with 50 additional compounds), which were constructed by studying more than 10 000 pairs of microbes via Flux Balance Analysis. Our collection could be investigated by four machine learning frameworks. The code underlying the metabolic modeling process is available here. Running Matlab code requires Gurobi Academic License.
Repository structure
- examples: provides notebooks with examples on various tasks
- exp: stores
.jsonfiles with final metrics - models: contains codes, environments and
.jsonfiles for the experiments - friend_or_foe: contains source code
Getting started
Download the package via PyPi manager and install catboost
pip install friend_or_foe
pip install catboost
Basic example of loading through the package and listing all the datasets from the compendium
# import FriendOrFoe loader
from friend_or_foe.data.loader import FriendOrFoeDataLoader

# create FriendOrFoe loader
loader = FriendOrFoeDataLoader(verbose=True)

# print available datasets
datasets = loader.list_available_datasets()
for name in list(datasets.keys()):
    print(f"  --- {name}")
Loading a specific dataset $$\texttt{BC-I}$$ from the AGORA collection
from friend_or_foe.data.loader import FriendOrFoeDataLoader
loader = FriendOrFoeDataLoader()
data = loader.load_dataset('Classification', 'AGORA', '100', 'BC-I')
Training a TabM model
from friend_or_foe.model.base import TabMModel
model = TabMModel(max_epochs=2, patience=1, batch_size=64, k=4, d_block=32)
task_type = 'classification'
model.fit(
    data['X_train'],
    data['y_train'],
    data['X_val'],
    data['y_val'],
    task_type=task_type
)
We also provide an example notebook with basic cli for comprehensive analyses.
Alternatively, you may download the data directly through Hugging Face hub loader. Download the data from our Hugging Face repo: https://huggingface.co/datasets/powidla/Friend-Or-Foe
from huggingface_hub import hf_hub_download
import pandas as pd

REPO_ID = "powidla/Friend-Or-Foe"

# File paths within the repo
X_train_ID = "Classification/AGORA/100/BC-I/X_train_BC-I-100.csv"
X_val_ID = "Classification/AGORA/100/BC-I/X_val_BC-I-100.csv"
X_test_ID = "Classification/AGORA/100/BC-I/X_test_BC-I-100.csv"

y_train_ID = "Classification/AGORA/100/BC-I/y_train_BC-I-100.csv"
y_val_ID = "Classification/AGORA/100/BC-I/y_val_BC-I-100.csv"
y_test_ID = "Classification/AGORA/100/BC-I/y_test_BC-I-100.csv"

# Download and load CSVs as pandas DataFrames
X_train = pd.read_csv(hf_hub_download(repo_id=REPO_ID, filename=X_train_ID, repo_type="dataset"))
X_val = pd.read_csv(hf_hub_download(repo_id=REPO_ID, filename=X_val_ID, repo_type="dataset"))
X_test = pd.read_csv(hf_hub_download(repo_id=REPO_ID, filename=X_test_ID, repo_type="dataset"))

y_train = pd.read_csv(hf_hub_download(repo_id=REPO_ID, filename=y_train_ID, repo_type="dataset"))
y_val = pd.read_csv(hf_hub_download(repo_id=REPO_ID, filename=y_val_ID, repo_type="dataset"))
y_test = pd.read_csv(hf_hub_download(repo_id=REPO_ID, filename=y_test_ID, repo_type="dataset"))
Baseline Demo Notebooks
Quickstart notebook
We provide an end-to-end example on how to predict competitive and cooperative interactions with TabNet.
Examples
The notebooks contain a simple example of using baseline models for predicting microbial interactions.
Reproducing the results
To execute the lines below for Supervised models data path should be organized as follows
FOFdata/<Task>/<Collection>/<Group>/<Dataset>/csv/<name>.csv
For example,
FOFdata/Regression/CARVEME/50/GR-III/csv/X_train_GR-III.csv
Scripts below assume that after creating FOFdata folder the above structure holds.
Supervised models
TabM
To train and test TabM we followed an example. We donwloaded the data into FOFdata folder.
mamba env create -f tabm.yaml
mkdir FOFdata
python main.py
FT-Transformer
To train and test FT-Transformer we followed an example.
mamba env create -f ft.yaml
mkdir FOFdata
python main.py
TabNet
To train and test TabNet we followed instructions from the package.
mamba env create -f tabnet.yaml
mkdir FOFdata
python main.py
GBDTs
We evaluate XGBoost, LightGBM and Catboost as our baselines here.
mamba env create -f gbdts.yaml
mkdir FOFdata
python main.py
Unsupervised models
mamba env create -f uns.yaml
mkdir FOFdata
python main.py
Generative models
TVAE, CTGAN and TabDDPM
To test TVAE, CTGAN and TabDDPM we used synthcity package and adapted officially provided examples. We calculated $\alpha$-Precision and $\beta$-Recall by using eval statistical from synthcity.metrics.
mamba env create -f synthcity.yaml
cd FOFdata
python main.py --tvae
python main.py --ctgan
python main.py --ddpm
TabDiff
To train and test TabDiff we followed the guidelines. The example we used for the AGORA50 dataset is below
git clone https://github.com/MinkaiXu/TabDiff
mamba env create -f tabdiff.yaml
cd data
mkdir GenAGORA50
python process_dataset.py --dataname GenAGORA50
python main.py --dataname GenAGORA50 --mode train --no_wandb --non_learnable_schedule --exp_name GenAGORA50
Alternative way is to skip preprocessing by downloading files from here.
To evaluate and calculate metrics
mamba env create -f synthcity.yaml
cd Info
cp info.json
python main.py --dataname GenAGORA50 --mode test --report --no_wandb
License
FriendOrFoe is under the Apache 2.0 license for code found on the associated GitHub repo and CC-BY-4.0 for the dataset hosted on HuggingFace. The LICENSE file for the repo can be found in the top-level directory.
Citation Information
If you find this repository usefull for your research, please cite the following papers
@article{Solowiej-Wedderburn2025-ar,
  title     = "Competition and cooperation: The plasticity of bacterial
               interactions across environments",
  author    = "Solowiej-Wedderburn, Josephine and Pentz, Jennifer T and Lizana,
               Ludvig and Schroeder, Bjoern O and Lind, Peter A and Libby, Eric",
  journal   = "PLoS Comput. Biol.",
  publisher = "Public Library of Science (PLoS)",
  volume    =  21,
  number    =  7,
  pages     = "e1013213",
  month     =  jul,
  year      =  2025,
  copyright = "http://creativecommons.org/licenses/by/4.0/",
  language  = "en"
}

@misc{cherednichenko2026friendfoe,
      title={Friend or Foe},
      author={Oleksandr Cherednichenko and Josephine Solowiej-Wedderburn and Laura M. Carroll and Eric Libby},
      year={2026},
      eprint={2509.00123},
      archivePrefix={arXiv},
      primaryClass={q-bio.QM},
      url={https://arxiv.org/abs/2509.00123},
}
1 maintainer

Metadata
1 maintainer
Release files for friend-or-foe 0.0.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| friend_or_foe-0.0.4.tar.gz | 54.2 kB | Without provenance | Details for friend_or_foe-0.0.4.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| friend_or_foe-0.0.4-py3-none-any.whl | Python 3 | none | any | Details for friend_or_foe-0.0.4-py3-none-any.whl |
Total release size: 106.2 kB
Release files / friend_or_foe-0.0.4.tar.gz
| Download URL | friend_or_foe-0.0.4.tar.gz |
|---|---|
| Size | 54.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
964e25de668e97a6b474672c6b4974404d203eba0575bb83f03b85c7bcf91cf7
|
|
BLAKE2b-256 checksum How to use checksums |
6a25b32328b8e0eafad65cbe0c6605fc315b278f26a4b3c4b7cca404aebfa38d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.13.2
|
Release files / friend_or_foe-0.0.4-py3-none-any.whl
| Download URL | friend_or_foe-0.0.4-py3-none-any.whl |
|---|---|
| Size | 52.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ddb3cbfc207f7804d206deb30b3b5496ea8cdf0d574f76e78b414775b0f347bd
|
|
BLAKE2b-256 checksum How to use checksums |
a347ea18812bbf62a4471e1f097f7887f5e81659f784cc9f00b7950e1d43953e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.13.2
|
Security for friend-or-foe 0.0.4
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














