
Jupyter Distributed
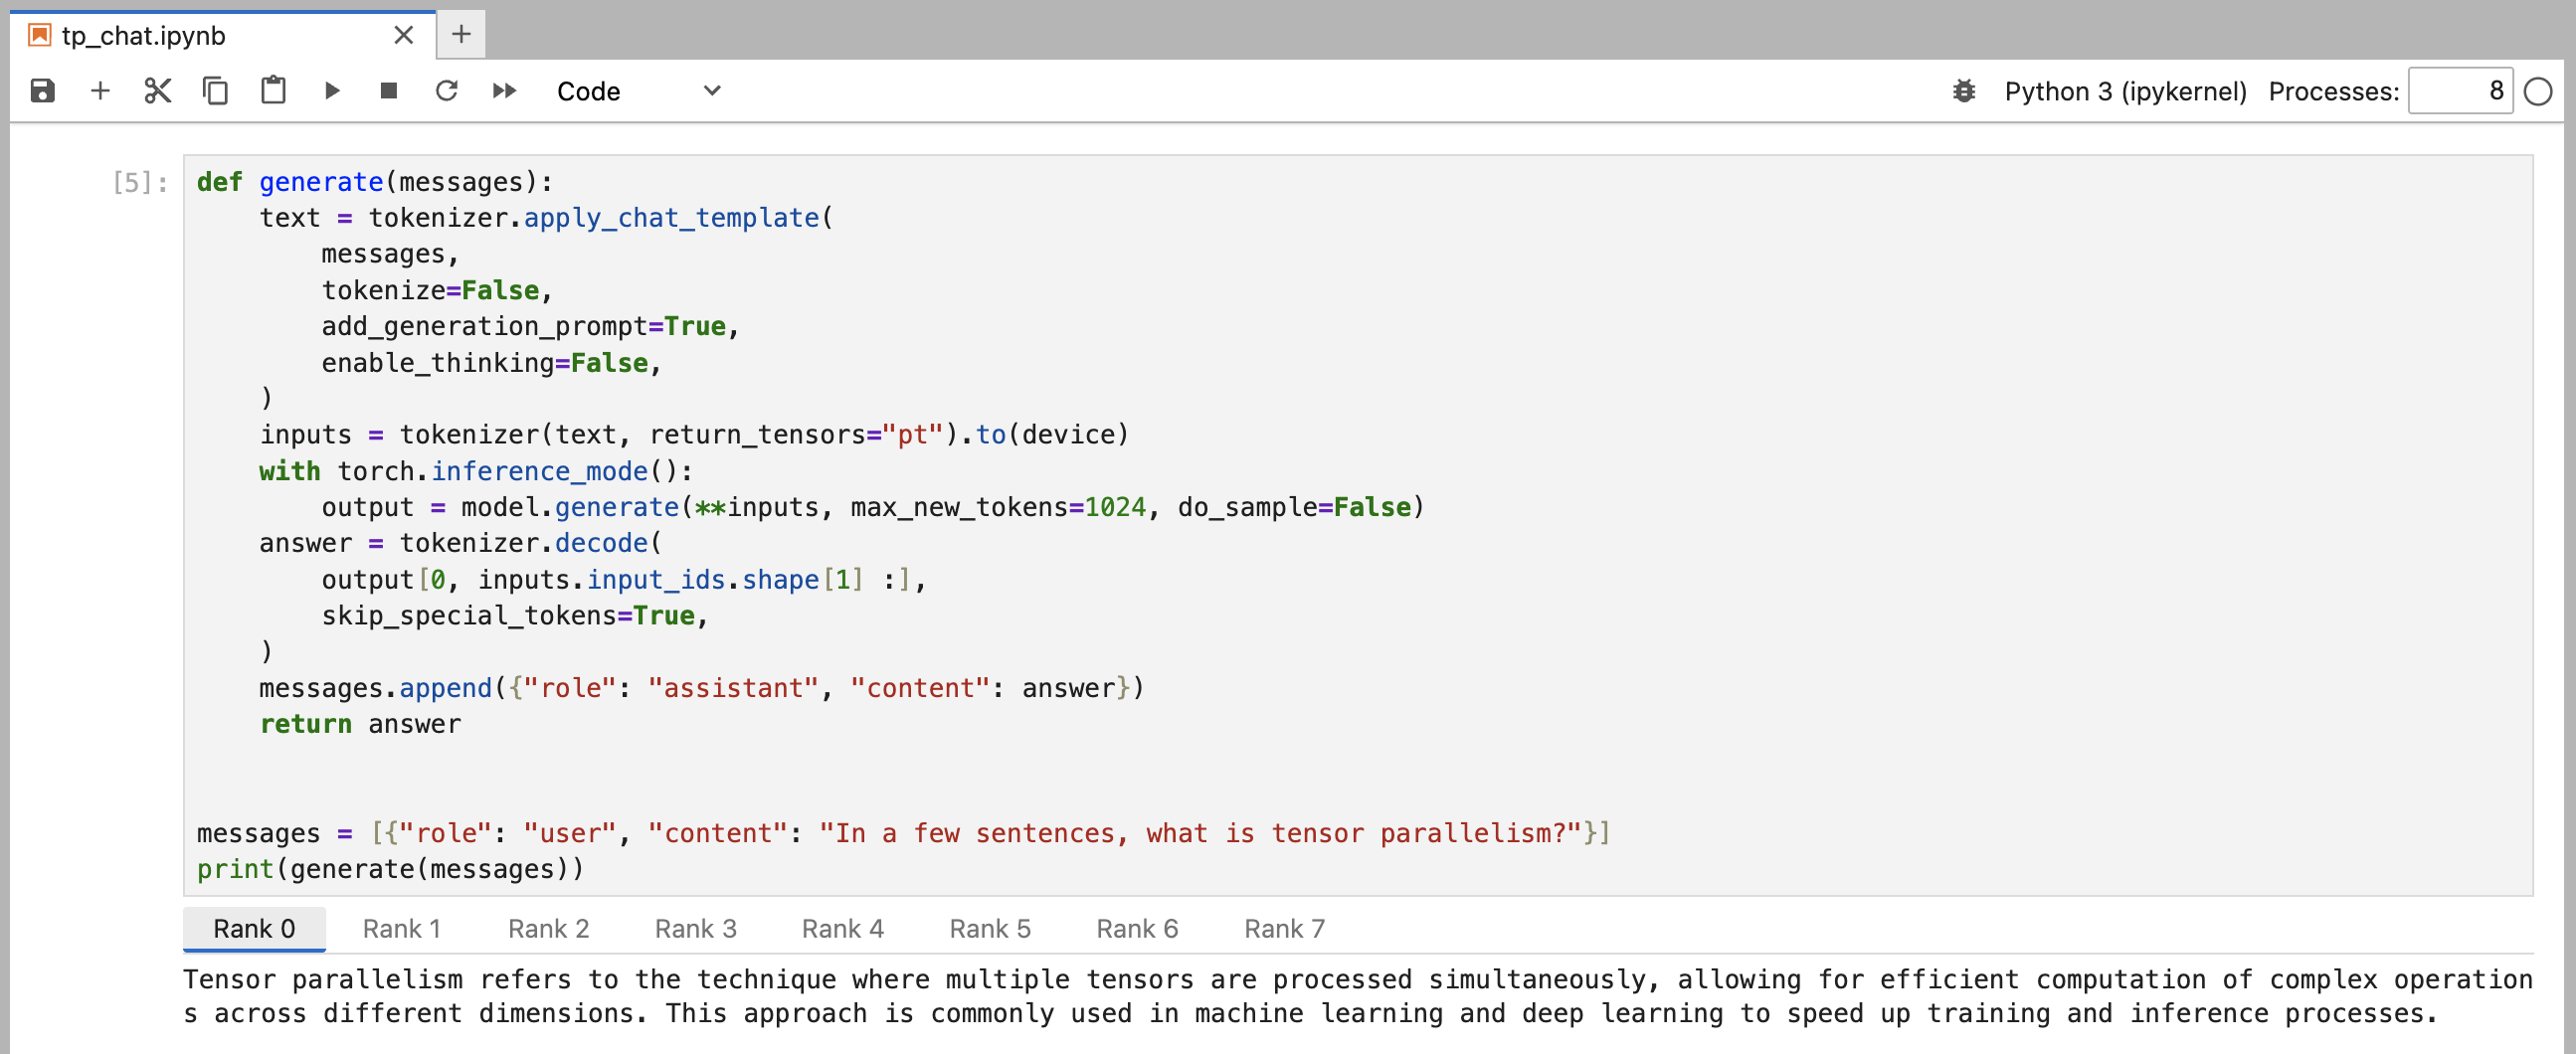
Jupyter Distributed is a notebook extension for running each cell concurrently across multiple persistent kernel processes. It adds a Processes option to JupyterLab and Jupyter Notebook 7 while letting you continue to select and customize your normal Jupyter kernels.
This follows the single program, multiple data (SPMD) model: every process runs the same code but maintains its own independent state. In a notebook, that means one cell can update several parallel interactive sessions whose variables remain available in later cells. The model is general, while naturally supporting distributed training patterns found in ecosystems such as PyTorch and JAX.
Installation
Install Jupyter Distributed into the same environment as JupyterLab or Jupyter Notebook 7:
pip install jupyter-distributed
jupyter lab
Use jupyter notebook instead of jupyter lab to launch Notebook 7. The
Jupyter Server and frontend extensions are enabled automatically. Restart the
server after installing or upgrading the package.
Using it
- Open or create a notebook and select its normal kernel, such as Python 3.
- Enter the number of parallel processes in the Processes field in the notebook toolbar.
- Confirm the restart. Every subsequent cell is executed concurrently by that many persistent processes.
- Select a rank tab to inspect its output.
When a notebook kernel first connects, Jupyter Distributed restarts it once behind the same managed execution path used for multiple processes. At the default of one process, outputs display normally without rank navigation.
Changing the process count stops the current kernel processes, starts a new group at the requested size, and clears all in-memory state.
Run a cell on only one zero-based rank by starting it with %%rank N. The
wrapper can contain ordinary code or another cell magic:
%%rank 1
activation.max().item()
%%rank 0
%%ai
Explain the model defined in this notebook.
Only the selected rank runs the cell body or changes state. This is useful for
rank-local inspection and for operations such as %%ai that should run once
rather than independently on every process.
Outputs stream while a cell is running. Standard streams, rich display data,
display updates, output clearing, exceptions, and terminal-style progress
updates are kept separate for each rank. Comm-based interactive outputs such as
ipywidgets and tqdm.notebook also remain independent: each rank owns its
widget state and interactions are routed back to that rank. Widget state is
restored when the browser reconnects to a still-running kernel.
Debugging Python in JupyterLab
The standard JupyterLab debugger works with distributed IPython kernels. A notebook breakpoint is installed in every process. Continue, pause, step over, step in, and step out apply to all paused processes together, while stack frames and variables are inspected for the selected rank thread.
While paused, use the Rank section in the debugger sidebar to choose which
process supplies the Calls and Variables views. JupyterLab's existing debug
console follows the same selected rank. Open it with Debugger: Evaluate Code
from the Command Palette and run expressions with Shift+Enter.
This is the first-stage debugging interface: ranks appear as threads in
JupyterLab's existing debugger panel rather than in dedicated rank tabs.
Python's built-in breakpoint() also works in notebook cells and imported
libraries once the JupyterLab debugger is active. Without an attached debugger,
it prints a warning instead of starting competing pdb sessions.
Notebook 7 supports distributed execution and rank-aware output, but the debugger integration is currently available only in JupyterLab.
Notebook agents with MCP
Install the optional MCP support:
pip install "jupyter-distributed[mcp]"
This lets an MCP-compatible agent work with the open notebook and its live kernel. The agent can inspect the selected cell, safely change the live process count, edit and run cells, read every rank's output, and select a rank in the JupyterLab debugger.
Starting JupyterLab also starts an MCP server at
http://localhost:3001/mcp. It uses the Streamable HTTP transport, listens on
localhost by default, and does not require an authentication token. Register
that endpoint with your agent harness. For example:
codex mcp add jupyter --url http://localhost:3001/mcp
claude mcp add --transport http jupyter http://localhost:3001/mcp
For OpenCode, Pi, or another MCP-compatible agent, register the same URL as a Streamable HTTP server. Then open a notebook in JupyterLab and ask the agent to work with it.
For a Jupyter server on a remote machine, forward both the web and MCP ports in the same SSH connection:
ssh -L 8888:localhost:8888 -L 3001:localhost:3001 <host>
Keep the MCP port bound to localhost; the SSH tunnel makes it available to the local agent without exposing it on the remote network.
Computation model
Jupyter Distributed follows the single program, multiple data (SPMD) model:
- Every process receives the same cell source.
- Each process has its own interpreter and independent variables.
- Process state persists across cells.
- A cell is considered complete when every process has completed, failed, or been interrupted.
- Standard interrupt, restart, and shutdown actions apply to the whole group.
For example, set Processes to 2 and run:
import os
import random

rank = int(os.environ["RANK"])
value = random.randint(0, 9)
rank * 10 + value
The output contains two rank views with independently generated values. Both
rank and value remain available in later cells on their respective process.
For complete distributed-model examples, see the demo notebooks.
What it does not do
Jupyter Distributed provides local process lifecycle, SPMD cell execution, and rank-aware output. It does not:
- choose or configure a distributed-computing framework;
- initialize collectives, shard data or models, or assign devices;
- schedule work across multiple machines, clusters, Slurm, or Kubernetes;
- provide elastic process resizing;
- support Notebook 6 or the legacy classic Notebook frontend;
- support interactive stdin prompts in distributed mode.
The selected runtime remains responsible for communication between processes. The execution protocol is designed to support any kernelspec, but the current implementation has only been tested with Python kernels.
PyTorch and JAX Distributed
Jupyter Distributed is framework agnostic, but PyTorch and JAX distributed workloads are flagship use cases.
PyTorch
To make torch.distributed convenient, each process receives these variables
at every process count, including one:
torchrun-compatible environment variables:
RANKLOCAL_RANKWORLD_SIZELOCAL_WORLD_SIZEMASTER_ADDRMASTER_PORT
Jupyter Distributed selects a local rendezvous address and available port, but does not initialize a process group. A notebook uses the ordinary PyTorch API:
import torch.distributed as dist

if not dist.is_initialized():
    dist.init_process_group("gloo")

dist.get_rank(), dist.get_world_size()
For NCCL, select the appropriate CUDA device from LOCAL_RANK before
initializing the process group. The defaults may be overridden in an earlier
cell before init_process_group() reads them:
import os

os.environ["MASTER_PORT"] = "29501"
PyTorch's process-group timeout applies to outstanding collective operations, not idle time between notebook cells, so normal interactive pauses do not require a longer timeout.
JAX
JAX processes additionally receive these variables at every process count:
JAX_COORDINATOR_ADDRESSJAX_PROCESS_IDJAX_NUM_PROCESSES
JAX reads these values directly, so initialization is parallel to the PyTorch example:
import jax

jax.distributed.initialize()

jax.process_index(), jax.process_count()
Device visibility and any framework-specific distributed configuration remain the notebook's responsibility.
Demos
- FSDP training with Transformers
- Tensor-parallel chat with Transformers
- Distributed debugging with PyTorch
The demos require their own model/runtime dependencies and suitable hardware. They are examples of integrating existing distributed libraries rather than features implemented by Jupyter Distributed itself.
License
Licensed under the MIT License.
1 maintainer

Metadata
1 maintainer
Release files for jupyter-distributed 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| jupyter_distributed-0.1.1.tar.gz | 418.1 kB | Without provenance | Details for jupyter_distributed-0.1.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| jupyter_distributed-0.1.1-py3-none-any.whl | Python 3 | none | any | Details for jupyter_distributed-0.1.1-py3-none-any.whl |
Total release size: 506.6 kB
Release files / jupyter_distributed-0.1.1.tar.gz
| Download URL | jupyter_distributed-0.1.1.tar.gz |
|---|---|
| Size | 418.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
876f6d046aadf7a10067d8298f39597d310e4e1168395620d374abdde4ac0266
|
|
BLAKE2b-256 checksum How to use checksums |
5b36835523a0a2afa03dd54b10063e32296375bd70bf7effab2a69ff8b30b741
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.9 {"installer":{"name":"uv","version":"0.12.9","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / jupyter_distributed-0.1.1-py3-none-any.whl
| Download URL | jupyter_distributed-0.1.1-py3-none-any.whl |
|---|---|
| Size | 88.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ad04e07dde4250cc5063641f797421186924b9665866889a5d1d4e102e46c626
|
|
BLAKE2b-256 checksum How to use checksums |
8e96e511b381a876c854ffe666c6174a8ea13b73c82cfe8a04b980ac0a861f07
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.9 {"installer":{"name":"uv","version":"0.12.9","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Security for jupyter-distributed 0.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














