


A multi-threaded explainability framework using Shapley values for LLM-based outputs.
Getting Started
Install the llmshap package (with all optional dependencies):
pip install "llmshap[all]"
Install in editable mode with all optional dependencies (after cloning the repository):
pip install -e ".[all]"
Documentation is available at llmSHAP Docs and a hands-on tutorial can be found here.
Example Usage
from llmSHAP import DataHandler, BasicPromptCodec, ShapleyAttribution
from llmSHAP.llm import OpenAIInterface

data = "In what city is the Eiffel Tower?"
handler = DataHandler(data, permanent_keys={0,3,4})
result = ShapleyAttribution(model=OpenAIInterface(model_name="gpt-4o-mini"),
                            data_handler=handler,
                            prompt_codec=BasicPromptCodec(system="Answer the question briefly."),
                            use_cache=True,
                            num_threads=16,
                            ).attribution()

print("\n\n### OUTPUT ###")
print(result.output)

print("\n\n### ATTRIBUTION ###")
print(result.attribution)

print("\n\n### HEATMAP ###")
print(result.render())
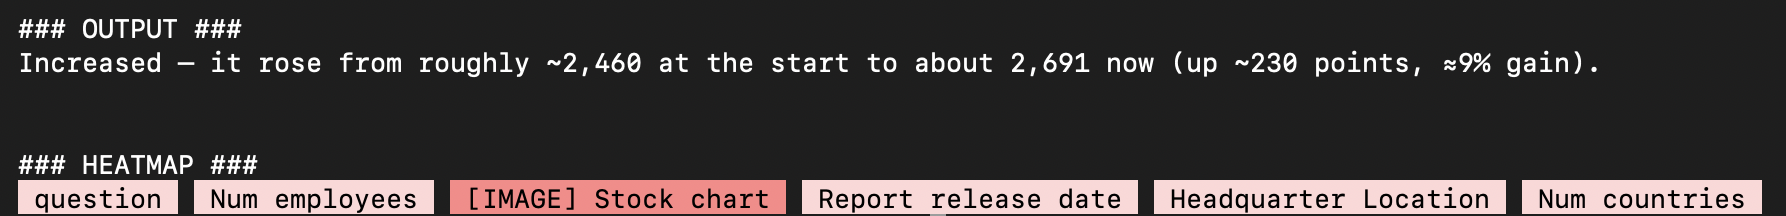
Multimodal Example with Image:
The following example shows llmSHAP with images.
from llmSHAP import DataHandler, BasicPromptCodec, ShapleyAttribution, Image
from llmSHAP.llm import OpenAIInterface

data = {
    "question": "Has our stockprice increased or decreased since the beginning?",
    "Num employees"        : "The company has about 450 employees.",
    "[IMAGE] Stock chart"  : Image(image_path="./docs/_static/demo-stock-price.png"),
    "Report release date"  : "Quarterly reports are released on the 15th.",
    "Headquarter Location" : "The headquarters is located in a mid-sized city.",
    "Num countries"        : "It has offices in three countries."
}

result = ShapleyAttribution(model=OpenAIInterface(model_name="gpt-5-mini", reasoning="low"),
                            data_handler=DataHandler(data, permanent_keys={"question"}),
                            prompt_codec=BasicPromptCodec(system="Answer the question briefly."),
                            use_cache=True,
                            num_threads=35,
                            ).attribution()

print("\n\n### OUTPUT ###")
print(result.output)

print("\n\n### HEATMAP ###")
print(result.render(abs_values=True, render_labels=True))
Embedding-Based Output Scoring
EmbeddingCosineSimilarity measures semantic similarity between outputs using embeddings.
It supports two backends:
- API — any OpenAI-compatible embeddings endpoint via
api_url_endpoint. - Local — a
sentence-transformersmodel downloaded on first use.
For the local backend, install the embeddings extra:
pip install "llmshap[embeddings]"
The example below uses the OpenAI API backend, which is already included in [all].
from llmSHAP import DataHandler, BasicPromptCodec, ShapleyAttribution, EmbeddingCosineSimilarity
from llmSHAP.llm import OpenAIInterface

data = "In what city is the Eiffel Tower?"
handler = DataHandler(data)
result = ShapleyAttribution(model=OpenAIInterface(model_name="gpt-4o-mini"),
                            data_handler=handler,
                            prompt_codec=BasicPromptCodec(system="Answer the question briefly."),
                            use_cache=True,
                            num_threads=16,
                            value_function=EmbeddingCosineSimilarity(
                                model_name = "text-embedding-3-small",
                                api_url_endpoint = "https://api.openai.com/v1")
                            ).attribution()

print("\n\n### OUTPUT ###")
print(result.output)

print("\n\n### HEATMAP ###")
print(result.render(abs_values=True, render_labels=True))
Example data
You can pass either a string or a dictionary:
from llmSHAP import DataHandler

# String input
data = "The quick brown fox jumps over the lazy dog"
handler = DataHandler(data)

# Dictionary input
data = {"a": "The", "b": "quick", "c": "brown", "d": "fox"}
handler = DataHandler(data)
To exclude certain keys from the computations, use permanent_keys:
from llmSHAP import DataHandler

data = {"a": "The", "b": "quick", "c": "brown", "d": "fox"}
handler = DataHandler(data, permanent_keys={"a", "d"})

# Get data with index 1 WITHOUT the permanent features.
print(handler.get_data({1}, exclude_permanent_keys=True, mask=False))
# Output: {'b': 'quick'}

# Get data with index 1 AND the permanent features.
print(handler.get_data({1}, exclude_permanent_keys=False, mask=False))
# Output: {'a': 'The', 'b': 'quick', 'd': 'fox'}
Comparison with TokenSHAP
| Capability | llmSHAP | TokenSHAP |
|---|---|---|
| Threaded | ✅ (optional num_threads) |
❌ |
| Modular architecture | ✅ | ❌ |
| Heuristics | SlidingWindow • Monte Carlo • Counterfactual | Monte Carlo |
| Caching across coalitions | ✅ | ❌ |
| Sentence-/chunk-level attribution | ✅ | ✅ |
| Permanent context pinning (always-included features) | ✅ | ❌ |
| Pluggable similarity metric | ✅ TF-IDF, embeddings | ✅ TF-IDF, embeddings |
| Docs & tutorial | ✅ Docs + tutorial | ✅ README only |
| Unit tests & CI | ✅ Pytest + GitHub Actions | ❌ |
| Image attribution | ✅ | ✅ PixelSHAP |
| In-image attribution | ❌ | ✅ PixelSHAP |
Stars ⭐️

1 maintainer

Metadata
1 maintainer
Release files for llmSHAP 1.5.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| llmshap-1.5.2.tar.gz | 20.6 kB | Without provenance | Details for llmshap-1.5.2.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| llmshap-1.5.2-py3-none-any.whl | Python 3 | none | any | Details for llmshap-1.5.2-py3-none-any.whl |
Total release size: 43.1 kB
Release files / llmshap-1.5.2.tar.gz
| Download URL | llmshap-1.5.2.tar.gz |
|---|---|
| Size | 20.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
80c65dc4d6dffec99389ee38c48ba641ce7750df9a6791adce1bfa98e7ed6e73
|
|
BLAKE2b-256 checksum How to use checksums |
8b64ab71bbae95e48ebd3c999aec2a10c02b195f41990486d8908b4591aa69aa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.11.5
|
Release files / llmshap-1.5.2-py3-none-any.whl
| Download URL | llmshap-1.5.2-py3-none-any.whl |
|---|---|
| Size | 22.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
4dddc3d823f4faa271344177eb42e0f953e67fc34c3be1b5a24da22c202e609e
|
|
BLAKE2b-256 checksum How to use checksums |
842e8bc5a376c97500d1718909ae55f66fe047f42902da336f4a6508a21b64f6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.11.5
|
Security for llmSHAP 1.5.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














