
main_content_extractor
Description
This library is designed for extracting only the main content from HTML.
It was developed for obtaining information related to LLM and for data input to LangChain and LlamaIndex.
Since this library contains element information and hierarchy information of HTML, it is useful when utilizing them.
For example, it can be helpful in obtaining a list of links or headers from the main content.
While trafilatura is an excellent library for main content extraction, it has issues such as missing necessary data or inability to output HTML.
To address these problems, this library exists.
The sequence of main content extraction is as follows:
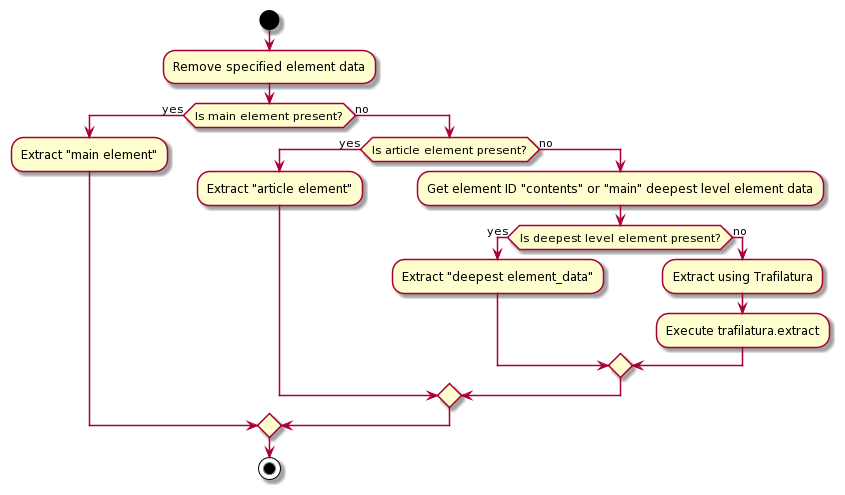
In addition to HTML format, output in Text format and Markdown format is also supported. This is to make it easier to output data in a format that is more convenient for LLM.
The extraction of main content uses trafilatura.
Since trafilatura cannot output in HTML format, it is output in XML format containing HTML information and then converted to HTML.
The conversion from XML to HTML is irreversible and does not perfectly match the original data.
Installation
pip install MainContentExtractor
HowToUse
import requests
from main_content_extractor import MainContentExtractor

# Get HTML using requests
url = "https://developer.mozilla.org/ja/docs/Web"
response = requests.get(url)
response.encoding = 'utf-8'
content = response.text

# Get HTML with main content extracted from HTML
extracted_html = MainContentExtractor.extract(content)

# Get HTML with main content extracted from Markdown
extracted_markdown = MainContentExtractor.extract(content, output_format="markdown")
1 maintainer

Metadata
1 maintainer
Release files for MainContentExtractor 0.0.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| MainContentExtractor-0.0.4.tar.gz | 5.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| MainContentExtractor-0.0.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 10.8 kB
Release files / MainContentExtractor-0.0.4.tar.gz
| Download URL | MainContentExtractor-0.0.4.tar.gz |
|---|---|
| Size | 5.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
697acc05909fb2f786d9cf7d4ff5bfbf14e4c3359c3a6eadc7ed4403fc2e66e5
|
|
BLAKE2b-256 checksum How to use checksums |
01de634b620e845f48bf27cbe66816e60f0fdb12414f77c8916af60aec508b0d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.11.5
|
Release files / MainContentExtractor-0.0.4-py3-none-any.whl
| Download URL | MainContentExtractor-0.0.4-py3-none-any.whl |
|---|---|
| Size | 5.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
77684179436e28eb2e19be26657cb2bbd7c1f9213a2c3ee163a8f9dfbca64107
|
|
BLAKE2b-256 checksum How to use checksums |
766232c33101b179d373d753d7c892b19f2ec22978b6c3c36d17a4a61d2169b6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.11.5
|














