


Flexible metadata store for MLOps, built for research and production teams that run a lot of experiments.
Neptune is a lightweight solution designed for:
- Experiment tracking: log, display, organize, and compare ML experiments in a single place.
- Model registry: version, store, manage, and query trained models and model-building metadata.
- Monitoring ML runs live: record and monitor model training, evaluation, or production runs live.
Getting started
Step 1: Sign up for a free account
Step 2: Install the Neptune client library
pip install neptune-client
Step 3: Connect Neptune to your code
import neptune.new as neptune

run = neptune.init(project="common/quickstarts", api_token="ANONYMOUS")

run["parameters"] = {
    "batch_size": 64,
    "dropout": 0.2,
    "optim": {"learning_rate": 0.001, "optimizer": "Adam"},
}

for epoch in range(100):
    run["train/accuracy"].log(epoch * 0.6)
    run["train/loss"].log(epoch * 0.4)

run["f1_score"] = 0.66
Learn more in the documentation or check our video tutorials to find your specific use case.
Features
Log and display
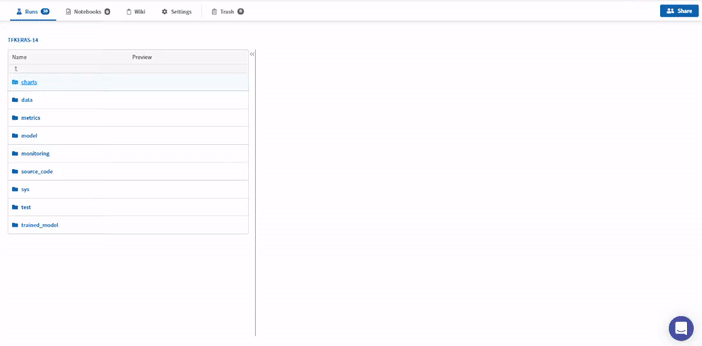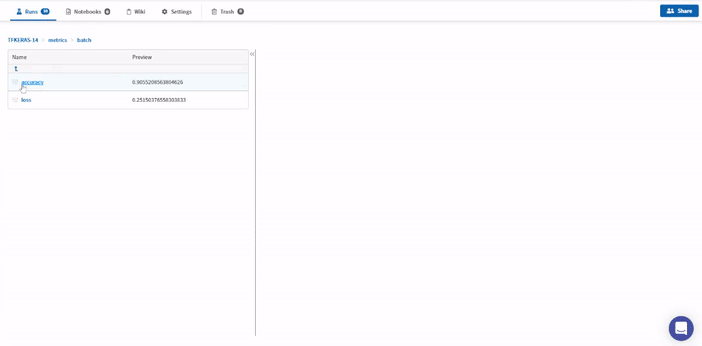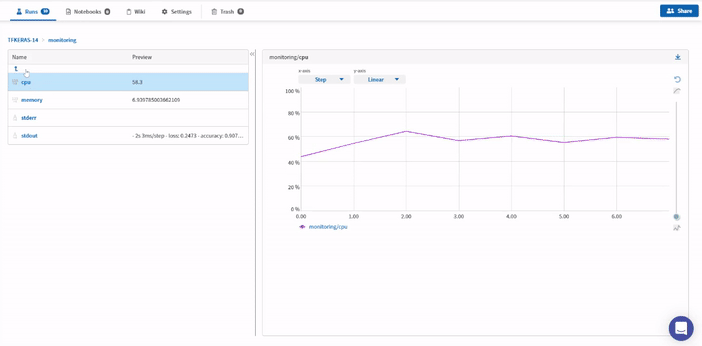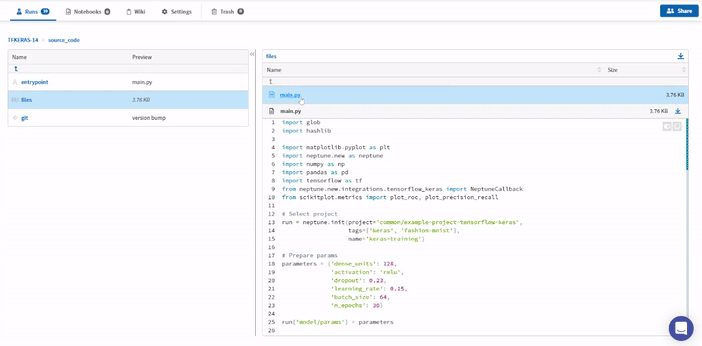
Neptune supports log and display for many different types of metadata generated during the ML model lifecycle:
- metrics and learning curves
- parameters, tags, and properties
- code, Git info, files, and Jupyter notebooks
- hardware consumption (CPU, GPU, memory)
- images, interactive charts, and HTML objects
- audio and video files
- tables and CSV files
- and more
Compare
You can compare model-building runs you log to Neptune using various comparison views:
- Charts: where you can compare learning curves for metrics or losses
- Images: where you can compare images across runs
- Parallel coordinates: where you can see parameters and metrics displayed on a parallel coordinates plot
- Side-by-side: which shows you the difference between runs in a table format
- Artifacts: where you can compare datasets, models, and other artifacts that you version in Neptune
- Notebooks: which shows you the difference between notebooks (or checkpoints of the same notebook) logged to the project
Filter and organize
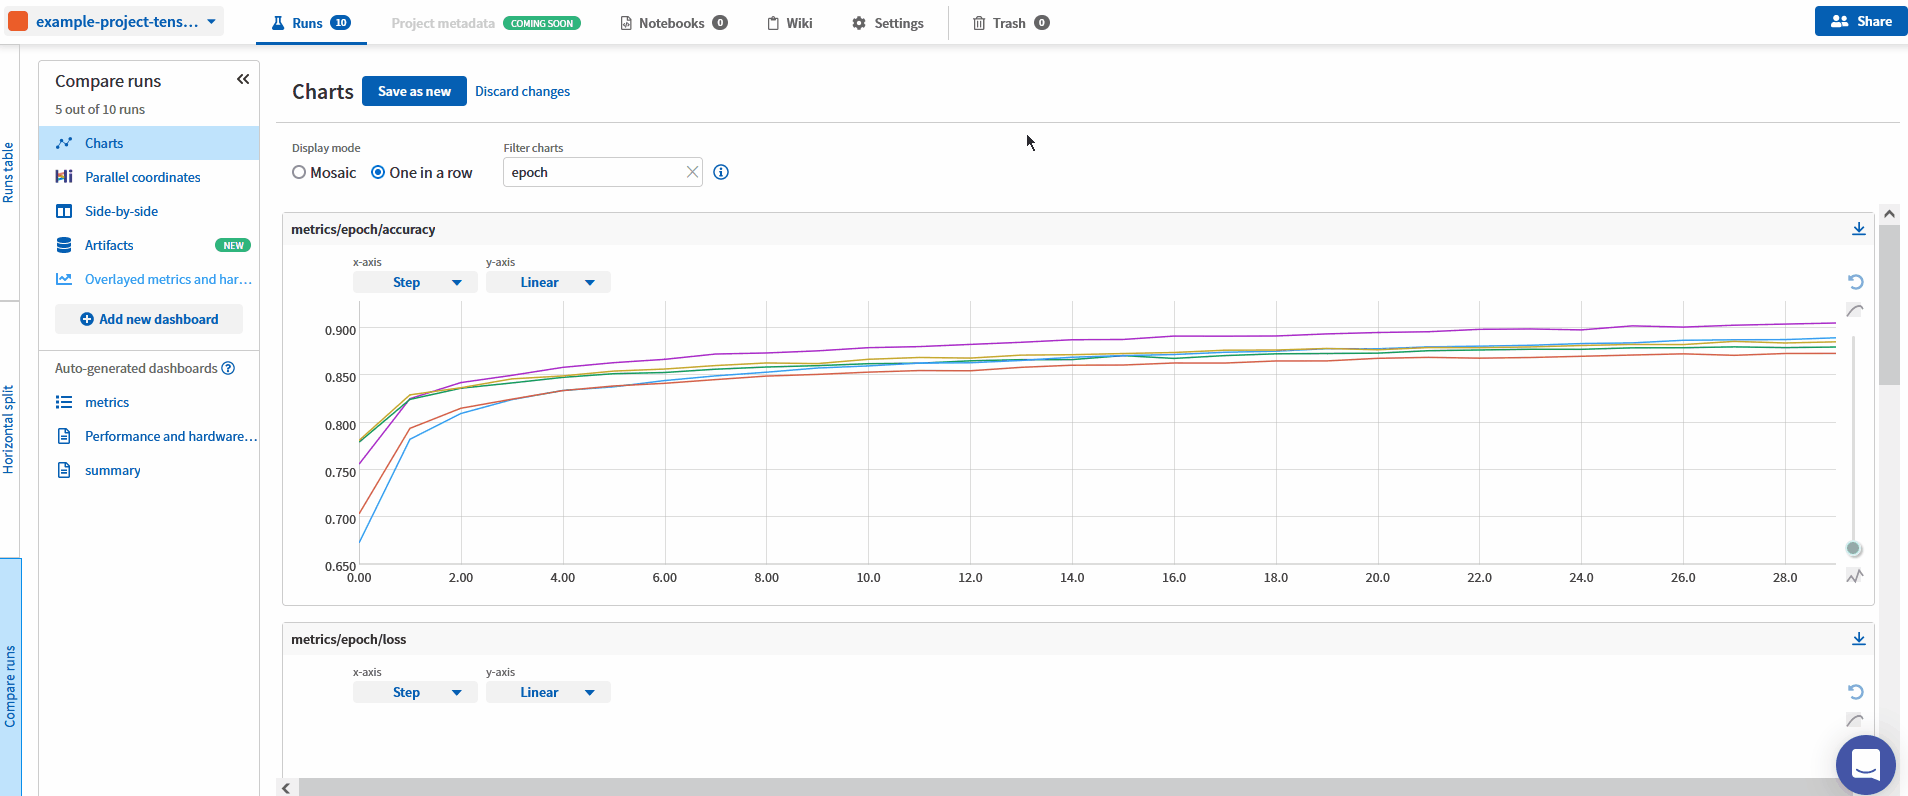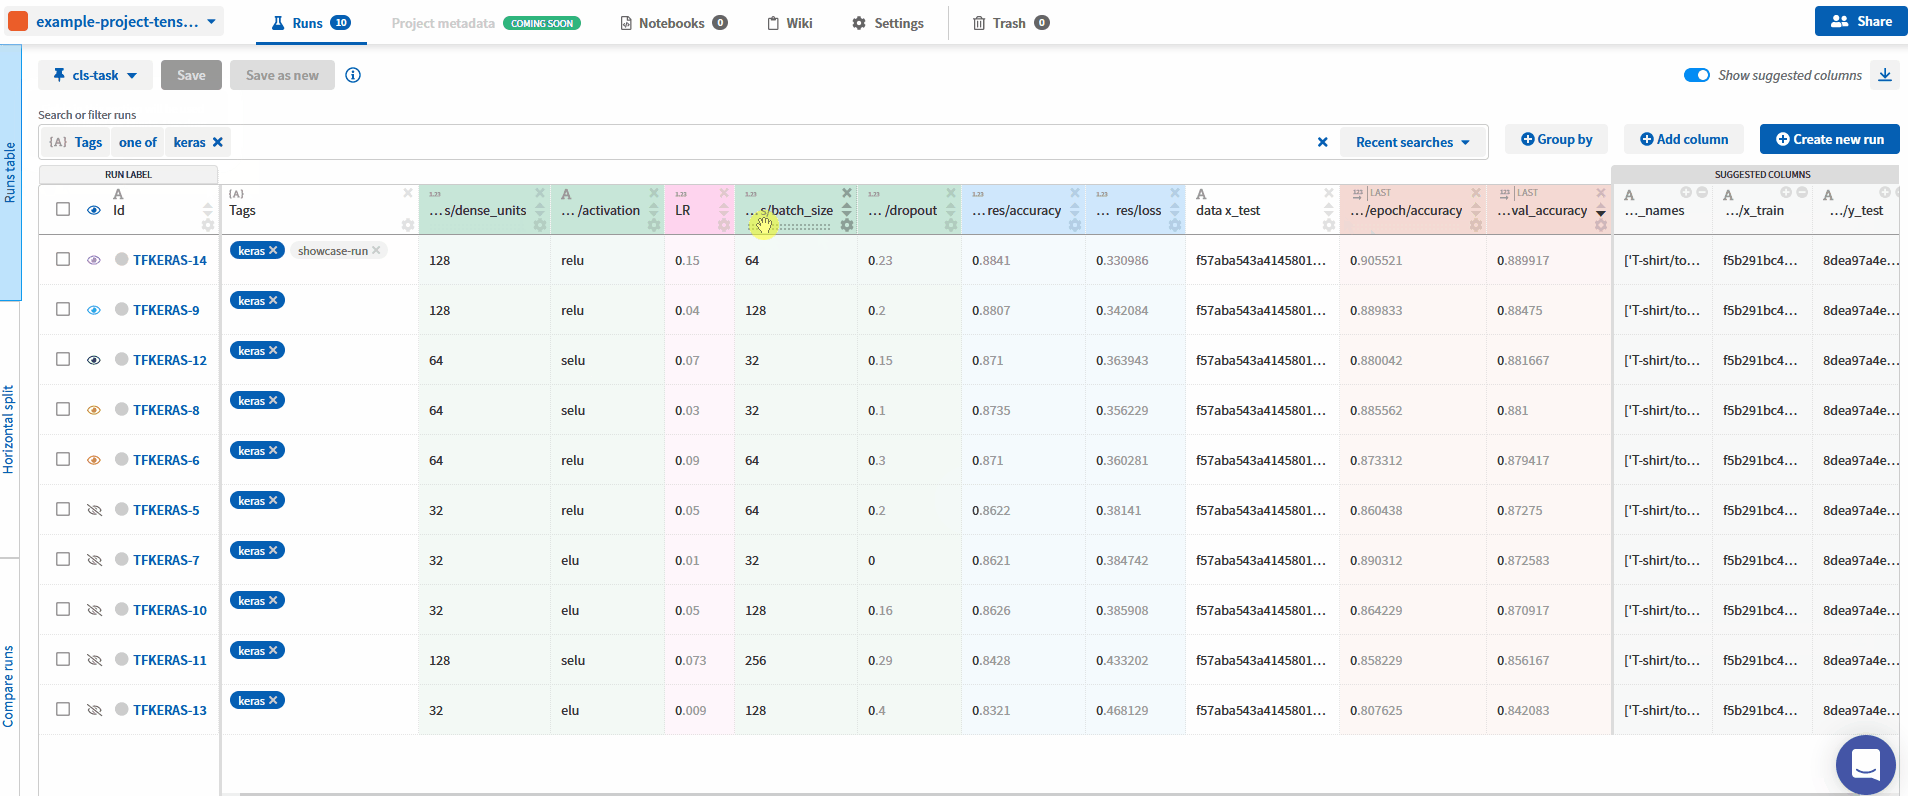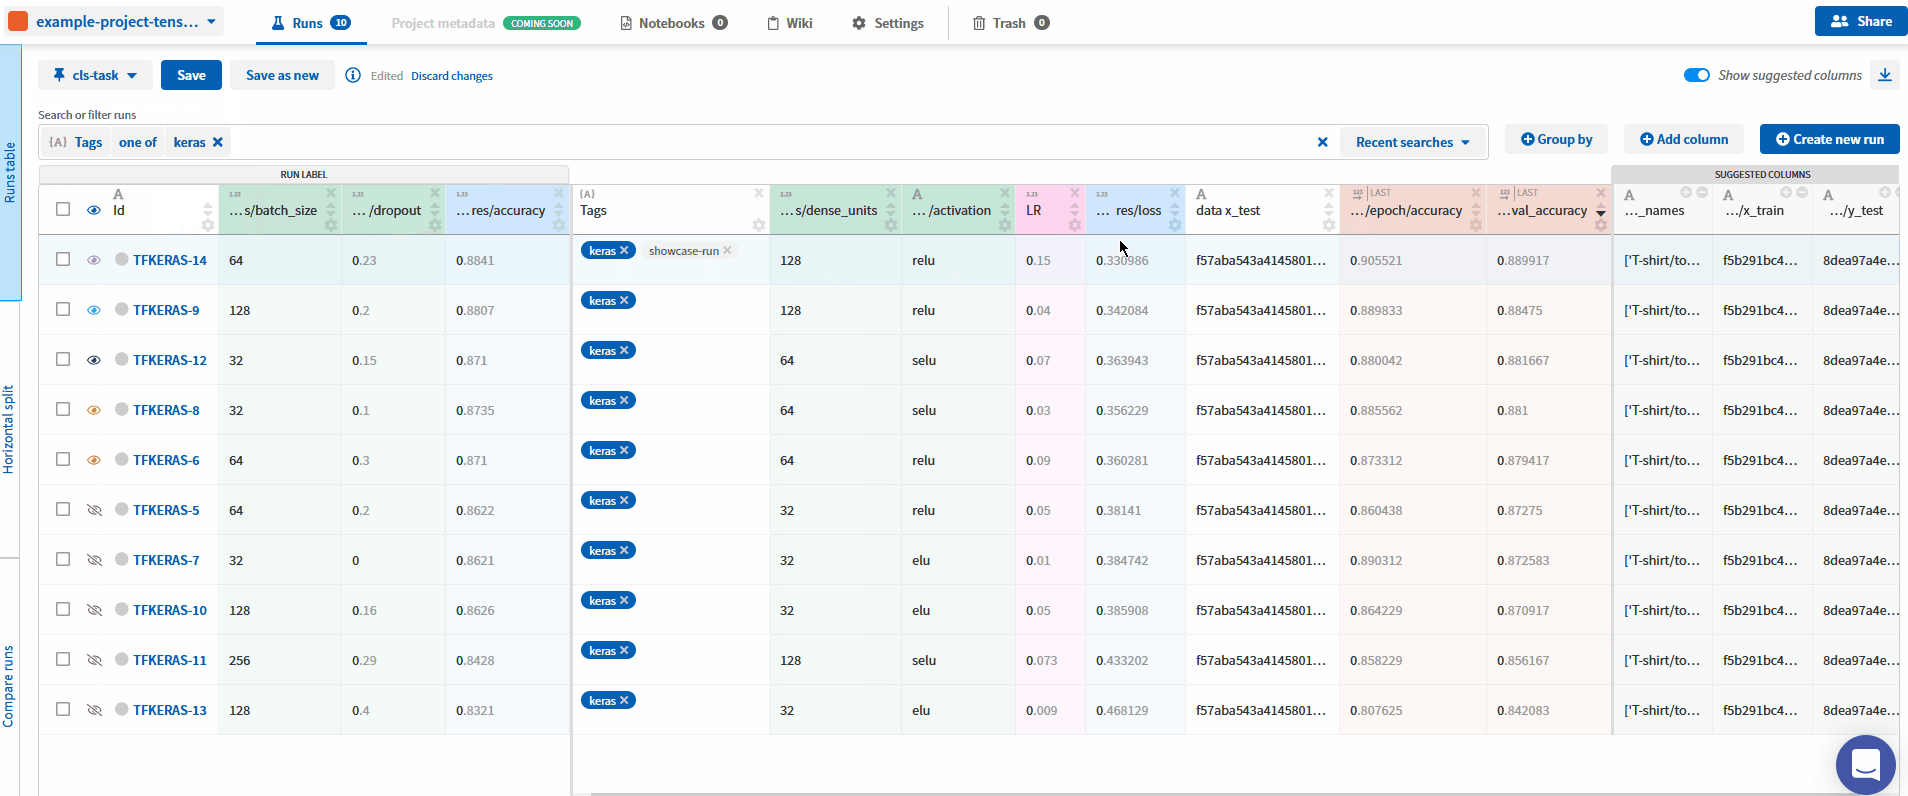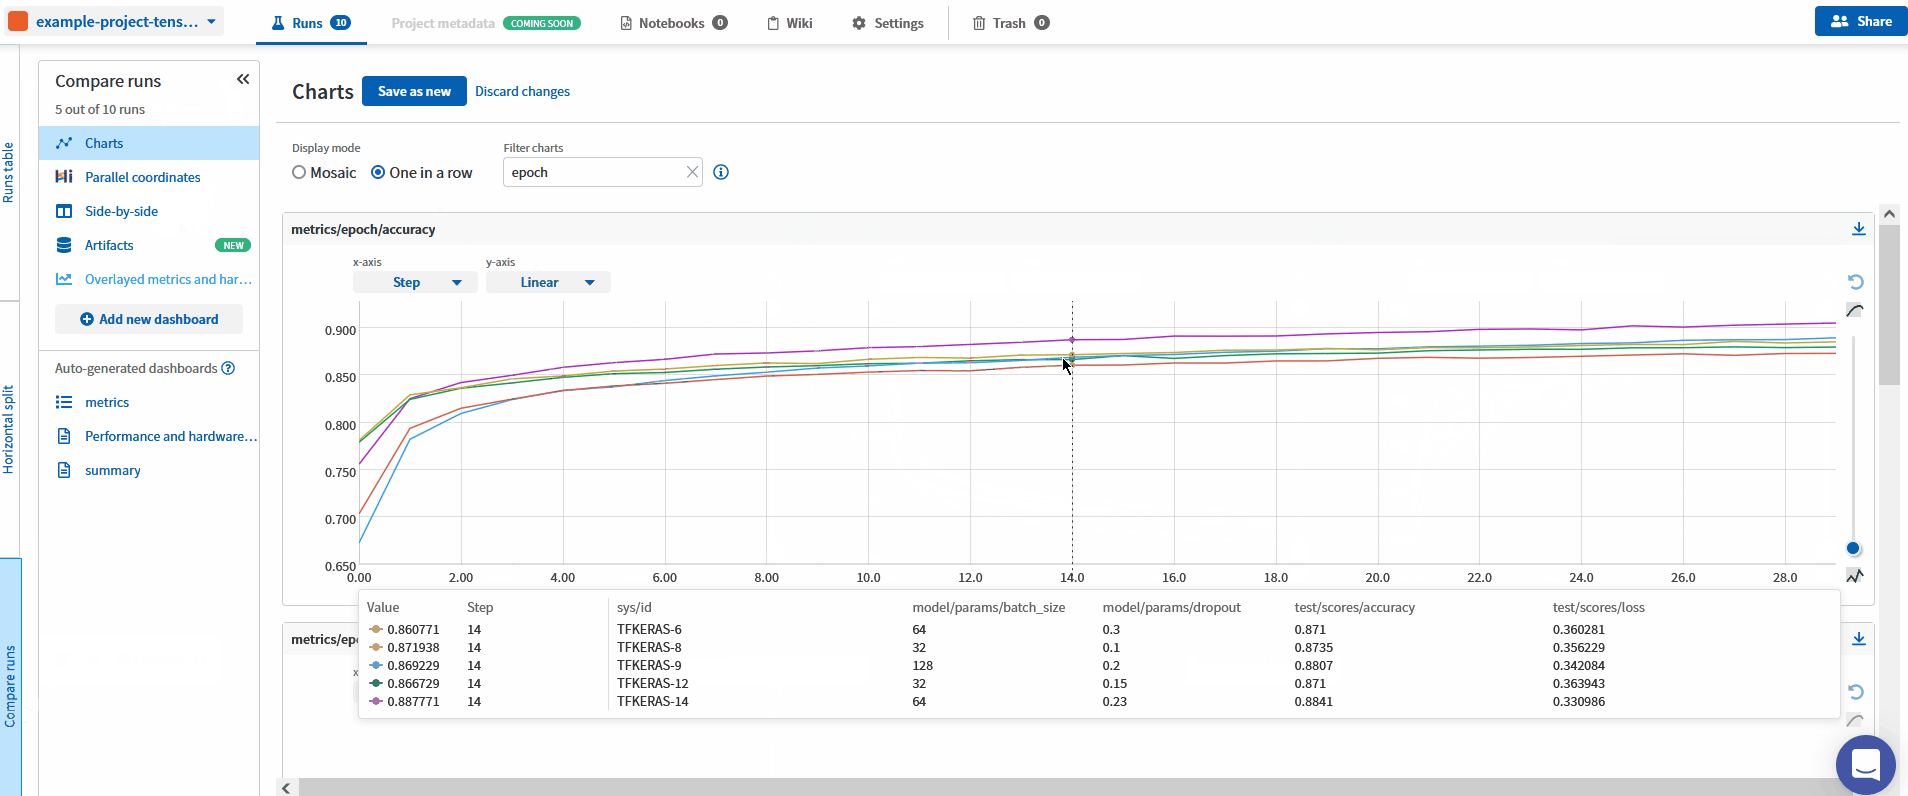
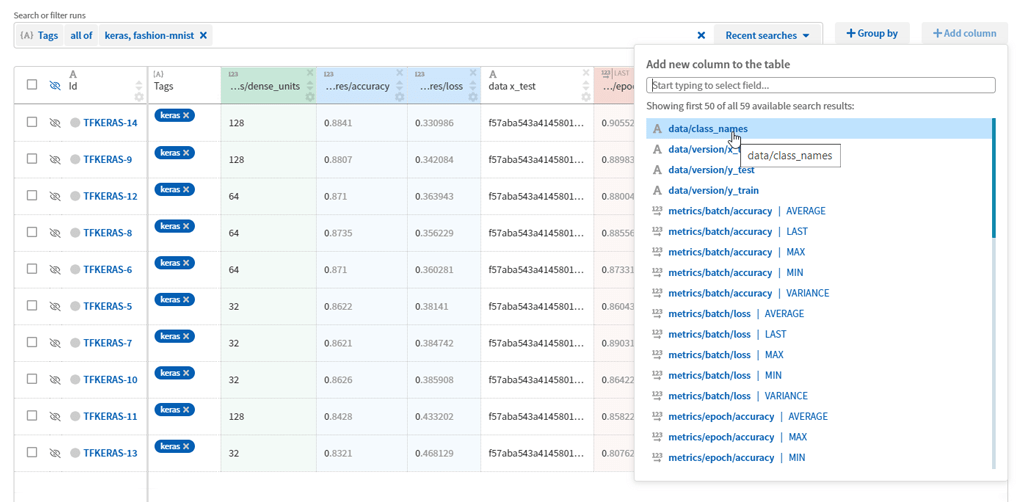
Filter, sort, and group model training runs using highly configurable dashboards.
Collaborate
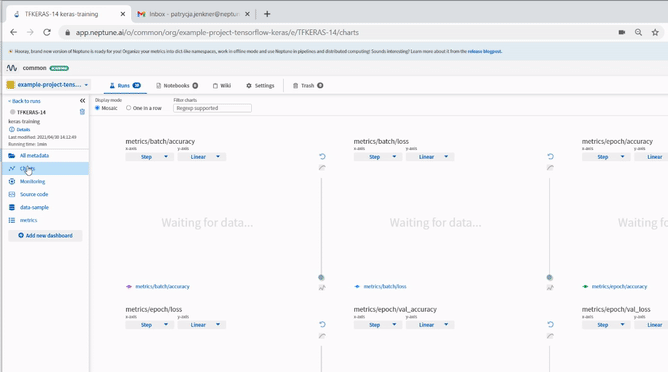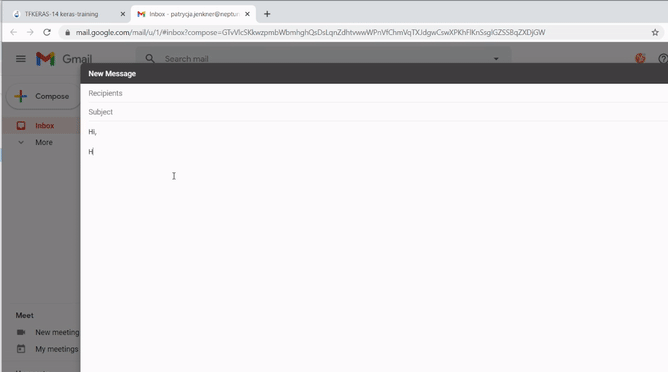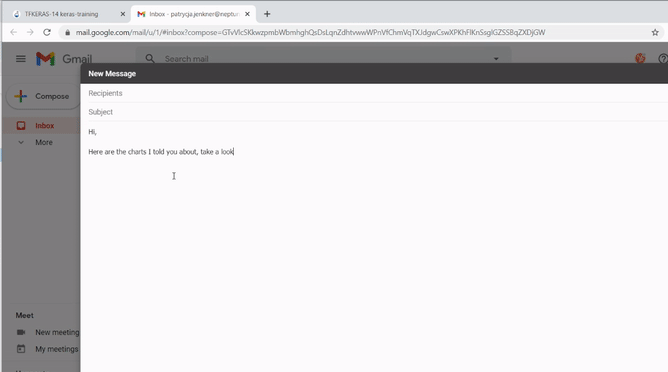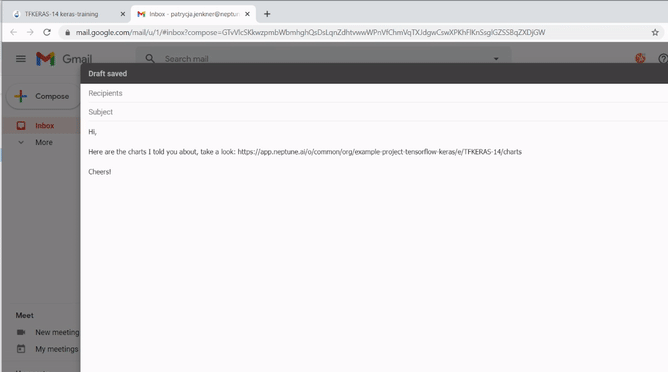
Improve team management and collaboration by grouping all experiments into projects and workspaces and quickly sharing any result or visualization within the team.
Integrate with your favourite ML libraries
Neptune comes with 25+ integrations with Python libraries popular in machine learning, deep learning and reinforcement learning. Available integrations:
- PyTorch and PyTorch Lightning
- TensorFlow / Keras and TensorBoard
- Scikit-learn, LightGBM, and XGBoost
- Optuna, Scikit-Optimize, and Keras Tuner
- Bokeh, Altair, Plotly, and Matplotlib
- and more
PyTorch Lightning
Example:
from pytorch_lightning import Trainer
from pytorch_lightning.loggers import NeptuneLogger

# Create NeptuneLogger
neptune_logger = NeptuneLogger(
    api_key="ANONYMOUS",  # replace with your own
    project="common/pytorch-lightning-integration",  # "WORKSPACE_NAME/PROJECT_NAME"
    tags=["training", "resnet"],  # optional
)

# Pass it to the Trainer
trainer = Trainer(max_epochs=10, logger=neptune_logger)

# Run training
trainer.fit(my_model, my_dataloader)


TensorFow/Keras
Example:
import tensorflow as tf
import neptune.new as neptune
from neptune.new.integrations.tensorflow_keras import NeptuneCallback

run = neptune.init(project="common/tf-keras-integration", api_token="ANONYMOUS")

mnist = tf.keras.datasets.mnist
(x_train, y_train), (x_test, y_test) = mnist.load_data()
x_train, x_test = x_train / 255.0, x_test / 255.0

model = tf.keras.models.Sequential(
    [
        tf.keras.layers.Flatten(),
        tf.keras.layers.Dense(256, activation=tf.keras.activations.relu),
        tf.keras.layers.Dropout(0.5),
        tf.keras.layers.Dense(10, activation=tf.keras.activations.softmax),
    ]
)

optimizer = tf.keras.optimizers.SGD(
    learning_rate=0.005,
    momentum=0.4,
)

model.compile(
    optimizer=optimizer, loss="sparse_categorical_crossentropy", metrics=["accuracy"]
)

neptune_cbk = NeptuneCallback(run=run, base_namespace="metrics")
model.fit(x_train, y_train, epochs=5, batch_size=64, callbacks=[neptune_cbk])


Scikit-learn
Example:
from sklearn.datasets import load_digits
from sklearn.ensemble import GradientBoostingClassifier
from sklearn.model_selection import train_test_split
import neptune.new as neptune
import neptune.new.integrations.sklearn as npt_utils

run = neptune.init(
    project="common/sklearn-integration",
    api_token="ANONYMOUS",
    name="classification-example",
    tags=["GradientBoostingClassifier", "classification"],
)

parameters = {
    "n_estimators": 120,
    "learning_rate": 0.12,
    "min_samples_split": 3,
    "min_samples_leaf": 2,
}

gbc = GradientBoostingClassifier(**parameters)

X, y = load_digits(return_X_y=True)
X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.20, random_state=28743
)

gbc.fit(X_train, y_train)

run["cls_summary"] = npt_utils.create_classifier_summary(
    gbc, X_train, X_test, y_train, y_test
)


fastai
Example:
import fastai
from neptune.new.integrations.fastai import NeptuneCallback
from fastai.vision.all import *
import neptune.new as neptune

run = neptune.init(
    project="common/fastai-integration", api_token="ANONYMOUS", tags="basic"
)

path = untar_data(URLs.MNIST_TINY)
dls = ImageDataLoaders.from_csv(path)

# Log all training phases of the learner
learn = cnn_learner(
    dls, resnet18, cbs=[NeptuneCallback(run=run, base_namespace="experiment")]
)
learn.fit_one_cycle(2)
learn.fit_one_cycle(1)

run.stop()


Optuna
Example:
import lightgbm as lgb
import neptune.new as neptune
import neptune.new.integrations.optuna as optuna_utils
import optuna
from sklearn.datasets import load_breast_cancer
from sklearn.metrics import roc_auc_score
from sklearn.model_selection import train_test_split

def objective(trial):
    data, target = load_breast_cancer(return_X_y=True)
    train_x, test_x, train_y, test_y = train_test_split(data, target, test_size=0.25)
    dtrain = lgb.Dataset(train_x, label=train_y)

    param = {
        "verbose": -1,
        "objective": "binary",
        "metric": "binary_logloss",
        "num_leaves": trial.suggest_int("num_leaves", 2, 256),
        "feature_fraction": trial.suggest_uniform("feature_fraction", 0.2, 1.0),
        "bagging_fraction": trial.suggest_uniform("bagging_fraction", 0.2, 1.0),
        "min_child_samples": trial.suggest_int("min_child_samples", 3, 100),
    }

    gbm = lgb.train(param, dtrain)
    preds = gbm.predict(test_x)
    accuracy = roc_auc_score(test_y, preds)

    return accuracy


# Create a Neptune run
run = neptune.init(
    api_token="ANONYMOUS", project="common/optuna-integration"
)  # you can pass your credentials here

# Create a NeptuneCallback for Optuna
neptune_callback = optuna_utils.NeptuneCallback(run)

# Pass NeptuneCallback to Optuna Study .optimize()
study = optuna.create_study(direction="maximize")
study.optimize(objective, n_trials=20, callbacks=[neptune_callback])

# Stop logging to the run
run.stop()


Neptune.ai is trusted by great companies
Read how various customers use Neptune to improve their workflow.
Support
If you get stuck or simply want to talk to us about something, here are your options:
- Check our FAQ page.
- Chat! In the app, click the blue message icon in the bottom-right corner and send a message. A real person will talk to you ASAP (typically very ASAP).
- You can just shoot us an email at support@neptune.ai.
People behind Neptune
Created with ❤️ by the Neptune.ai team:
Piotr, Jakub, Paulina, Kamil, Magdalena, Małgorzata, Piotr, Aleksandra, Marcin, Hubert, Adam, Jakub, Paweł, Patrycja, Grzegorz, Paweł, Marcin, Jakub, Prince, Rafał, Dominika, Karolina, Parth, Rafał, Stephen, Sabine, Martyna, Artur, Franciszek, Aleksiej, Kshiteej, Tomek, Tymoteusz, Piotr, Chaz, Michał, Siddhant, Karolina, Michał, and you?
2 maintainers


Metadata
2 maintainers
Release files for neptune-client 0.16.5
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| neptune-client-0.16.5.tar.gz | 320.6 kB | Without provenance | Details for neptune-client-0.16.5.tar.gz |
Release files / neptune-client-0.16.5.tar.gz
| Download URL | neptune-client-0.16.5.tar.gz |
|---|---|
| Size | 320.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c738288c7a1ab5313dfc86dcd910e03fbce1c31b094d9f92c7540ddf44ed02ef
|
|
BLAKE2b-256 checksum How to use checksums |
84b16b608330b6d3250f3b709cc5a3b19b17fc65ea4e4ca0503dacc4db0ffc7c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.1 CPython/3.8.13
|
Security for neptune-client 0.16.5
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














