
Ormophine
The most simple Python ORM. Read like Python, run like SQL.



No models to define. No DSL to learn. No boilerplate to write.
Philosophy
Most Python ORMs were built for enterprise complexity — layers of abstractions, session lifecycles, model definitions, and migration pipelines. They're powerful, but they make simple things hard.
Ormophine is built on a different premise:
90% of database work is simple CRUD. The ORM for that work should be simple too.
Ormophine gives you one thing no other ORM does: you write plain Python, and it becomes SQL. No new syntax. No function wrappers. No lambda queries. If you know Python, you already know Ormophine.
# This is Python. But it's also a SQL query.
rows = users.get_row(
    which_columns = [
      (users.firstname + " " + users.lastname).If(users.firstname != None).Else(users.lastname),
      users.age
      ],
    where = (users.age >= 18) & users.name.lower().startswith('a'),
    order_by = users.age
)
That's it. Read it like Python, it runs like SQL. Under the hood, Ormophine translates your expressions into optimized, parameterized SQL — you never see a ? or a %s.
Documentation & AI Assistance
📖 Full Documentation Comprehensive guides, API references, and examples are available at: 👉 https://ormophine.readthedocs.io/en/latest/index.html
🤖 AI-Powered Assistance
To help you write queries and debug your code, Ormophine ships with AI reference files (Sqlite.AI.Refrence.txt, MySQL.AI.Refrence.txt, PostgreSQL.AI.Refrence.txt).
You can find these files in the root directory of the installed package. Simply attach the appropriate file to ChatGPT, Claude, or Gemini, ask your question, and the AI will respond using the exact API and behavior of your Ormophine version. It's like having an Ormophine expert on standby!
🌟 For the First Time in the Python Community
Ormophine introduces several query-expression paradigms that have never existed before in mainstream Python ORMs (SQLAlchemy, Peewee, Tortoise, PonyORM, or Django ORM).
Instead of forcing developers to learn a secondary Domain Specific Language (DSL), function wrappers (func., fn., F()), or verbose SQL construct helpers, Ormophine makes Python expressions directly executable as SQL queries:
1. ✂️ Native Python String Slicing in SQL (col[start:stop])
For the first time, you can slice database columns using standard Python 0-based indexing and negative offsets:
# Slices directly into SQL SUBSTR() / SUBSTRING() across SQLite, MySQL, & PostgreSQL
users.code[:3]          # First 3 characters
users.lastname[5:-2]    # From index 5, skipping last 2 characters
users.phone[-4:]        # Last 4 digits
In other ORMs, achieving this requires manual 1-based indexing math, func.length() calculations, and backend-specific substring wrappers.
2. 🔀 Pythonic One-Line Conditionals (.If().Else())
Ormophine mirrors Python's native value if condition else alternative syntax directly on column expressions:
# Clean, readable, and fully composable
status_label = users.name.If(users.is_active == 1).Else('Inactive')

rows = users.get_row([status_label], where=users.age >= 18)
Unlike rigid CASE WHEN constructs in other ORMs, Ormophine conditionals return first-class query expressions that can be further chained with slicing, string methods, or mathematical operations.
3. 🔗 Native String Methods Directly on Column Expressions
You can call Python string methods directly on columns or computed expressions without wrapping them in external SQL function helpers:
# Native Python methods chained seamlessly
where = (users.email.lower().endswith('@company.com')) & (users.bio.strip().contains('developer'))
Supported methods include .lower(), .upper(), .strip(), .lstrip(), .rstrip(), .startswith(), .endswith(), .contains(), and .replace().
4. 🧩 Composable Zero-DSL Query Expressions
You can freely compose string concatenation, arithmetic, slicing, conditionals, and logical operators in one fluent expression without ever dropping into a framework DSL:
# Full expression composition: concatenation -> strip -> slice -> conditional
display_tag = ((users.first_name + " " + users.last_name).strip()[:10]).If(users.is_vip == True).Else('Standard')

rows = users.get_row([display_tag], where=(users.age + 5 >= 25) & (users.status == 'active'))
5. 🛡️ Automatic Transparent Parameterization
Every literal value, string, or number passed within these Python expressions is automatically converted into parameterized query arguments (? or %s). You write natural Python without thinking about escaping or SQL injection vulnerabilities.
Simplicity in Action — Side by Side
The best way to understand Ormophine's advantage is to see the same everyday tasks written in different ORMs. Notice what's missing in the Ormophine column: no models, no sessions, no .execute(), no func. wrappers, no lambdas.
Connecting to the Database
SQLAlchemy:
from sqlalchemy import create_engine
engine = create_engine('sqlite:///my_db.db')
PonyORM:
from pony.orm import Database
db = Database()
db.bind(provider='sqlite', filename='my_db.db', create_db=True)
Peewee:
from peewee import SqliteDatabase
db = SqliteDatabase('my_db.db')
Ormophine:
from Ormophine.Sqlite import Driver

db = Driver('my_db.db')
Accessing Tables
SQLAlchemy: Requires manual reflection or pre-defined models
from sqlalchemy import Table, MetaData
metadata = MetaData()
users = Table('users', metadata, autoload_with=engine)
PonyORM: Requires defining entities and generating mappings
from pony.orm import Required
class User(db.Entity):
    name = Required(str)
    age = Required(int)
db.generate_mapping(create_tables=True)
Peewee: Requires defining models and explicitly linking them to the database
from peewee import Model, CharField, IntegerField
class User(Model):
    name = CharField()
    age = IntegerField()
    class Meta:
        database = db
Ormophine:
# No models. No definitions. Tables appear as attributes automatically.
users = db.users
Your database already knows its schema. Why should you redeclare it in Python?
Inserting Data
SQLAlchemy: Requires explicit connection context and commit
with engine.connect() as conn:
    conn.execute(users.insert().values(
        name='Alice',
        email='alice@example.com',
        age=30
    ))
    conn.commit()
PonyORM: Requires explicit db_session context
from pony.orm import db_session
with db_session:
    User(name='Alice', email='alice@example.com', age=30)
Peewee: Requires calling .execute() on the query construct
User.insert(
    name='Alice',
    email='alice@example.com',
    age=30
).execute()
Ormophine:
# Auto-committed. Column objects as keys — readable and safe.
name, email, age = users.name, users.email, users.age # For simplicity

users.insert({
    name:  'Alice',
    email: 'alice@example.com',
    age:   30
})
A dictionary. Column on the left, value on the right. You can read it at a glance.
Fetching Data with Complex Conditions
Let's try to fetch rows where the lowercased name starts with 'ab', AND a specific slice of the lastname equals 'connor', ordered by age.
SQLAlchemy: Verbose function calls and manual string manipulation for slicing
from sqlalchemy import select, func
stmt = select(users.c.name, users.c.age).where(
    func.lower(users.c.name).like('ab%'),
    func.substr(users.c.lastname, 6, func.length(users.c.lastname) - 7) == 'connor'
).order_by(users.c.age)
with engine.connect() as conn:
    results = conn.execute(stmt).fetchall()
PonyORM: Requires lambda functions and lacks intuitive slicing
from pony.orm import db_session, select
with db_session:
    query = select(u for u in User if u.name.lower().startswith('ab'))
    # String slicing like [5:-2] is not natively supported in PonyORM queries
    query = query.order_by(lambda u: u.age)
    results = [(u.name, u.age) for u in query]
Peewee: Uses SQL function wrappers and lacks native Python slicing
from peewee import fn
# Peewee lacks native string slicing in ORM queries
query = User.select(User.name, User.age).where(
    fn.LOWER(User.name).startswith('ab')
    # User.lastname[5:-2] == 'connor' is not possible natively
).order_by(User.age)
results = list(query.dicts())
Ormophine:
# Pure Python. Slicing, string methods — they just work.
rows = users.get_row(
    [users.name, users.age],
    where=(users.name.lower().startswith('ab')) & (users.lastname[5:-2] == 'connor'),
    order_by=users.age
)
users.name.lower().startswith('ab') — that's Python. users.lastname[5:-2] — that's Python. Ormophine translates them into the correct SQL functions automatically. You never have to think about how to express your logic in SQL.
Atomic / Batch Transactions
Performing multiple write operations in a single, atomic transaction is crucial for data integrity and speed. Let's insert 2 users, update 1, and delete 1.
SQLAlchemy: Requires explicit connection block and manual execution for each statement
with engine.begin() as conn:
    conn.execute(users.insert().values(name='Dave', email='dave@example.com', age=40))
    conn.execute(users.insert().values(name='Eve', email='eve@example.com', age=28))
    conn.execute(users.update().where(users.c.name == 'Alice').values(age=31))
    conn.execute(users.delete().where(users.c.name == 'Bob'))
PonyORM: Requires db_session context and imperative object manipulation for updates/deletes
from pony.orm import db_session
with db_session:
    User(name='Dave', email='dave@example.com', age=40)
    User(name='Eve', email='eve@example.com', age=28)
    alice = User.get(name='Alice')
    if alice: alice.age = 31
    bob = User.get(name='Bob')
    if bob: bob.delete()
Peewee: Requires atomic context and explicit .execute() on every query construct
with db.atomic():
    User.insert(name='Dave', email='dave@example.com', age=40).execute()
    User.insert(name='Eve', email='dave@example.com', age=28).execute()
    User.update(age=31).where(User.name == 'Alice').execute()
    User.delete().where(User.name == 'Bob').execute()
Ormophine:
# Queue your operations. Run once. All or nothing.
batch = users.batch()
batch.insert({users.name: 'Dave', users.email: 'dave@example.com', users.age: 40})
batch.insert({users.name: 'Eve', users.email: 'eve@example.com', users.age: 28})
batch.update({users.age: 31}, where=users.name == 'Alice')
batch.delete_row(where=users.name == 'Bob')
batch.run() # Executes all and commits in one transaction
No context managers. No .execute() on every line. Just stack your operations and run.
Writing Conditional Values in a Query
Ormophine lets a column expression follow Python's one-line conditional idea:
the value before .If() is returned when the condition is true, and the value
passed to .Else() is returned otherwise.
SQLAlchemy: Uses an explicit SQL expression helper rather than a column method
from sqlalchemy import case

display_name = case(
  (users.c.is_active == 1, users.c.name),
  else_='inactive'
)
stmt = select(display_name)
PonyORM: Usually expresses the branching in Python after loading entities
with db_session:
  rows = [(u.name if u.is_active else 'inactive') for u in User.select()]
Peewee:
Uses a framework-specific Case expression
from peewee import Case

display_name = Case(
  User.is_active,
  ((1, User.name),),
  'inactive'
)
rows = User.select(display_name)
Ormophine:
rows = users.get_row(
  [(users.name).If(users.is_active == 1).Else('inactive')],
  where=users.name.lstrip().startswith('A')
)
The conditional remains a composable query expression: it can be selected,
used in where, passed to update, nested, or chained with string methods.
For a function-style spelling, use Builtins.IIf(condition, then_value, else_value).
Chained Joins
Joins use the same fluent query expression style. Start from a table, add each
join with its ON condition, and finish with .get_row().
SQLAlchemy:
stmt = (
  select(users.c.name, orders.c.amount)
  .select_from(users)
  .join(orders, orders.c.user_id == users.c.id)
  .join(banlist, banlist.c.user_id == users.c.id)
  .where(banlist.c.id > 20)
)
rows = connection.execute(stmt).fetchall()
PonyORM:
with db_session:
  rows = select(
    (u.name, o.amount)
    for u in User
    for o in Order
    if o.user_id == u.id and u.id > 20
  )[:]
Peewee:
query = (
  User
  .select(User.name, Order.amount)
  .join(Order, on=(Order.user_id == User.id))
  .switch(User)
  .join(Banlist, on=(Banlist.user_id == User.id))
  .where(Banlist.id > 20)
)
rows = list(query.dicts())
Ormophine:
rows = (
  users
  .left_join(orders, orders.user_id == users.id)
  .inner_join(banlist, banlist.user_id == users.id)
  .get_row(
    [users.name, orders.amount],
    where=banlist.id > 20
  )
)
The join builder supports inner_join, left_join, and right_join, can be
extended with additional joins, and automatically aliases repeated tables.
SQLite does not support native RIGHT JOIN; use an equivalent left_join
with the table order reversed.
What Makes Ormophine Simple
Ormophine's simplicity isn't about having fewer features — it's about expressing more with less syntax. Every design decision follows one rule:
If it reads like Python, it's right. If you have to look up how to write it, it's wrong.
Columns Are Python Variables
Other ORMs give you column objects that you must wrap in helper functions. Ormophine columns behave like native Python values:
# String methods — just call them
users.name.lower()
users.name.upper()
users.name.strip()
users.name.startswith('A')
users.name.endswith('.com')

# Slicing — just like Python strings and lists
users.code[:3]        # first 3 characters
users.lastname[5:-2]  # from index 5, drop last 2

# Arithmetic — just like Python numbers
users.price * users.qty - users.discount

# Concatenation — the + operator works naturally
users.first_name + ' ' + users.last_name
# Or you can add more complexity
users.first_name.lower().strip() + ' ' + ((users.last_name[:-3]).If (users.last_name.endswith('kov')).Else (users.last_name))

# Logic — combine with & and |
(users.age >= 18) & (users.status == 'active')
All of these are translated to the correct SQL under the hood. All values are automatically parameterized — SQL injection is prevented by design.
No Models, No Boilerplate
You don't define classes. You don't declare fields. You don't bind tables to a metadata registry. You connect, and everything is there:
db = Driver('my.db')

users  = db.users     # it just exists
orders = db.orders    # this too

# Columns appear as attributes
users.name    # column object
users.age     # column object
users.email   # column object
One API, Three Databases
Switching databases is a one-line import change. The API stays identical:
# SQLite
from Ormophine.Sqlite import Driver
db = Driver('my.db')

# MySQL
from Ormophine.Mysql import Driver
db = Driver(host='localhost', port=3306, username='root', password='pass', db_name='my_db')

# PostgreSQL
from Ormophine.Postgresql import Driver
db = Driver(host='localhost', port=5432, username='postgres', password='pass', db_name='my_db')
Same .insert(), same .get_row(), same .update(), same .batch(). Learn once, use anywhere.
Quick Examples
Connect and access tables
from Ormophine.Sqlite import Driver

db = Driver('company.db')

# Tables and columns are discovered automatically — no models needed
users   = db.users
orders  = db.orders
Insert
users.insert({
    users.name:  'Alice',
    users.email: 'alice@example.com',
    users.age:   30
})
Select with conditions
name, email, age , phone= users.name, users.email, users.age, users.phone

rows = users.get_row(
    which_columns = [
      name,
     ("email: " + email).If(email != None).Else(("phone: " + phone).If(phone != None).Else('No information'))
     ],
    where   = (age >= 18) & name.startswith('A'),
    order_by = age
)
Update
users.update(
    update = {users.age: users.age + 1},
    where  = users.status == 'active'
)
Bulk insert
users.bulk_insert(
    columns   = [users.name, users.age],
    data_list = [['Bob', 25], ['Carol', 32], ['Dave', 28]]
)
Joins
result = (
  users
  .inner_join(orders, orders.user_id == users.id)
  .get_row(
    [users.name, orders.amount, orders.date],
    where=orders.amount > 100,
    order_by=orders.date
  )
)
Why Ormophine?
- Zero Learning Curve — if you know Python, you know Ormophine. Columns are variables, methods are methods, slicing is slicing, operators are operators. There is no DSL, no special syntax, nothing to look up.
- Reads Like English —
users.name.lower().startswith('a')says exactly what it does. Compare that tofunc.lower(users.c.name).like('a%'). - Fast & Thread-Safe — built on a dedicated writer queue (SQLite) and robust connection pooling (MySQL/PostgreSQL); parallel reads, serialized writes.
- Multi-Database — one unified API across SQLite, MySQL, and PostgreSQL. Switch databases by changing your import.
⚡ Benchmark Results
Ormophine is simple — but it's not slow. We benchmarked it against popular Python ORMs (SQLAlchemy, PonyORM, and Peewee) across SQLite, PostgreSQL, and MySQL — measuring throughput instead of raw execution time.
Methodology
We evaluate two distinct scenarios to measure both transactional overhead and bulk efficiency:
-
Single Operations: Measures how many CRUD queries per second each ORM can execute when a COMMIT is issued immediately after every single insert, update, and delete. This tests the ORM's baseline overhead and connection management for isolated transactions.
-
Batch Operations: Measures how many CUD (Create, Update, Delete) queries per second each ORM can execute when all statements are executed first, and a single COMMIT is issued at the end. This tests the ORM's efficiency in bulk transactional processing.
Metric — Queries Per Second (QPS): each test run executes a fixed number of queries per operation; throughput is computed as QPS = queries / elapsed_seconds for every run, and the mean across all repeats is reported. QPS is a normalized metric, so results remain directly comparable across chunk sizes and database backends — and it reads naturally: how many queries can each ORM execute in one second?
How to read the charts: every chart shows Mean Throughput in Queries Per Second (QPS) — a taller bar is better. Below each chart, the percentage indicates how much faster Ormophine is compared to that ORM.
Note on Variance & Equivalence: Due to natural system fluctuations, each test run can have a variance of up to ±10%. Therefore, throughput differences of less than 5% are considered statistically insignificant (margin of error). In the charts below, differences under 5% are displayed in gray and marked as "≈ Equal", rather than claiming a marginal advantage.
You can access the benchmark Jupyter notebooks in the project repository at Ormophine/{Sqlite, Postgresql, Mysql}/Benchmark to run the tests on your own hardware.
You can also use this Google Colab notebooks:
Sqlite: https://colab.research.google.com/drive/1KK3sr8H_Crd29fmnq3VmpmE88aLNT3Yr?usp=sharing
MySQL: https://colab.research.google.com/drive/1ndwmN0C9UTZHTNmLh8-fT9rEg-DSrzHQ?usp=sharing
PostgeSQL: https://colab.research.google.com/drive/1XYrC30vUciS1YgY6M5MBoxwO9YTltzkD?usp=sharing
Sqlite Results
Single Operations Test
(Executed 10,000 queries total — 200 repeats × 50 chunk size — for each CRUD operation per ORM)
|
Inserts: 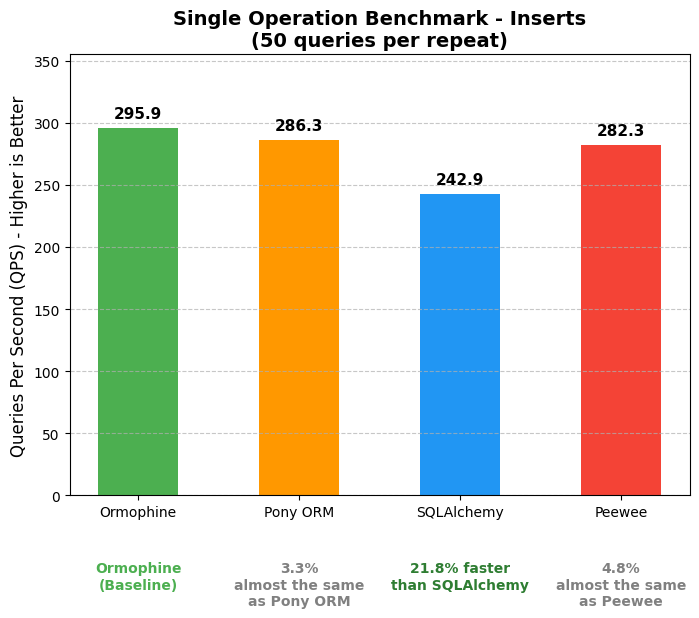
|
Updates: 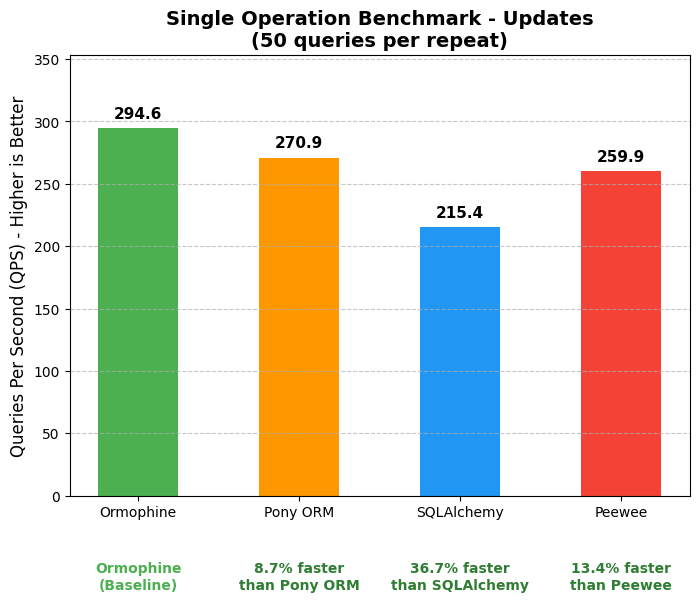
|
|
Reads: 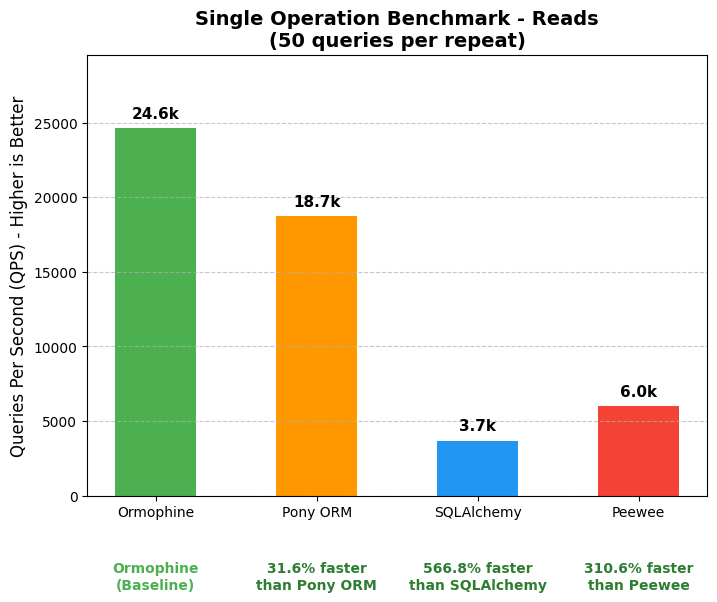
|
Deletes: 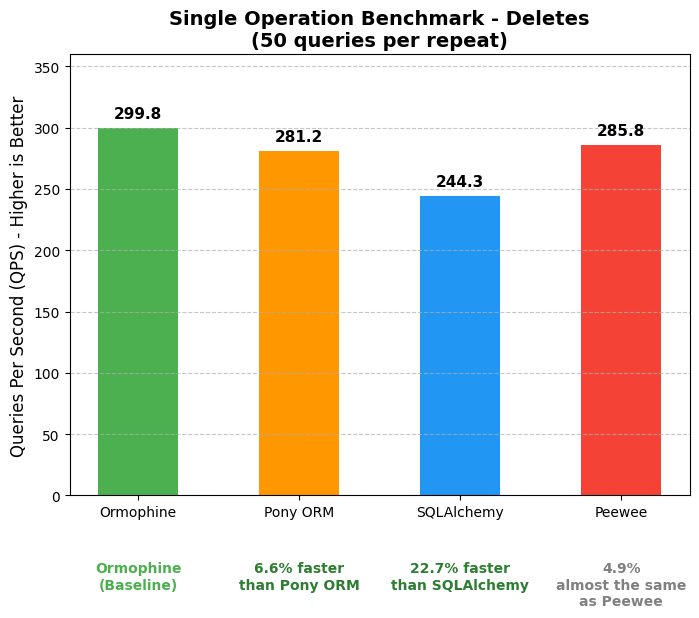
|
Batch Operation Test
(Executed 500 queries total — 5 repeats × 100 statements per chunk — for each CUD operation per ORM)
|
Inserts: 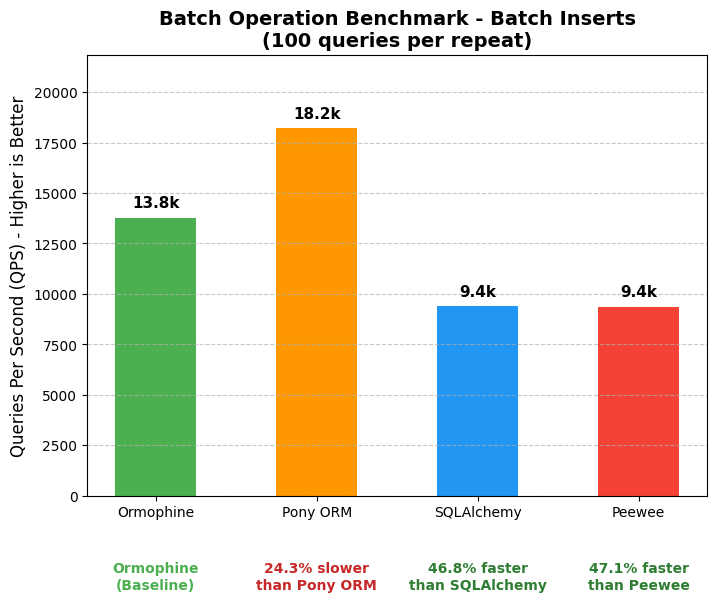
|
Updates: 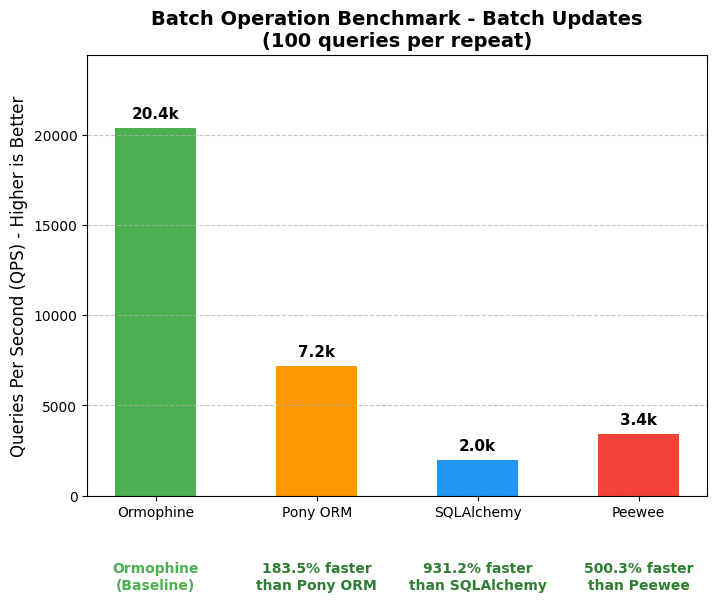
|
Deletes: 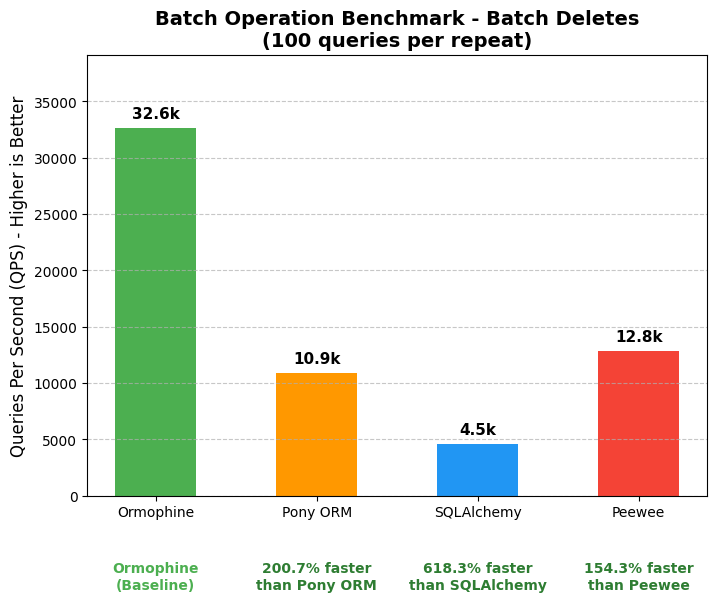
|
PostgreSQL Results
Single Operations Test
(Executed 10,000 queries total — 200 repeats × 50 chunk size — for each CRUD operation per ORM)
|
Inserts: 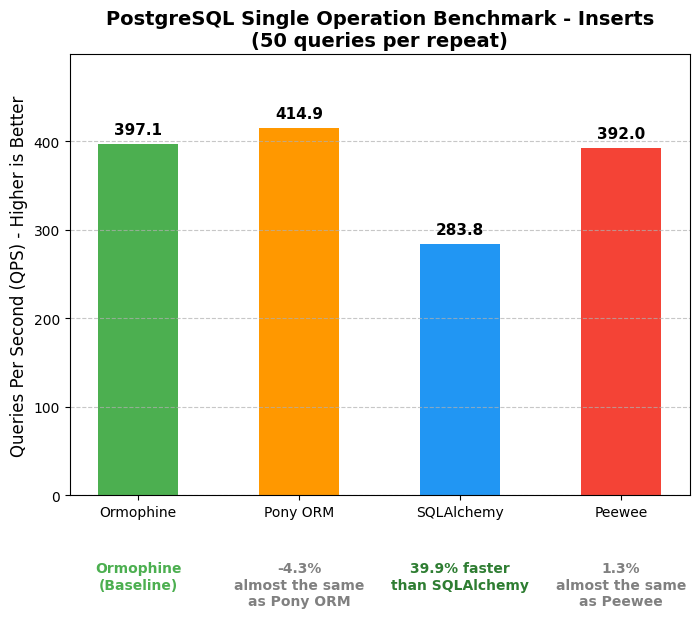
|
Updates: 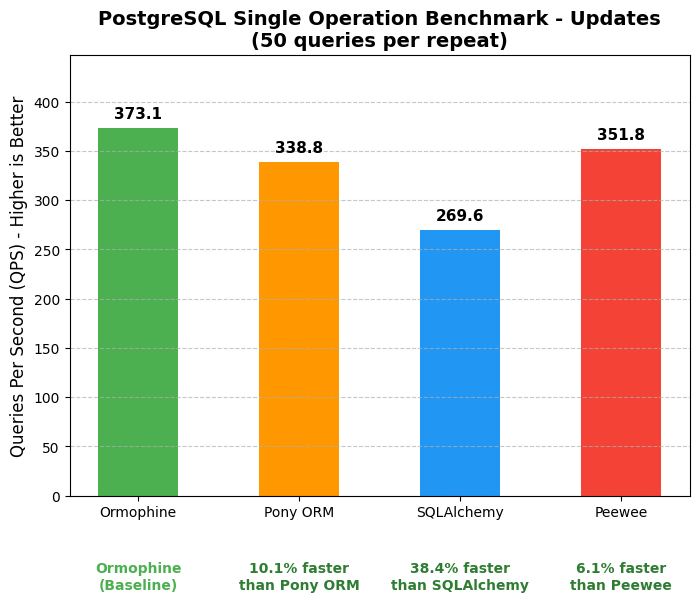
|
|
Reads: 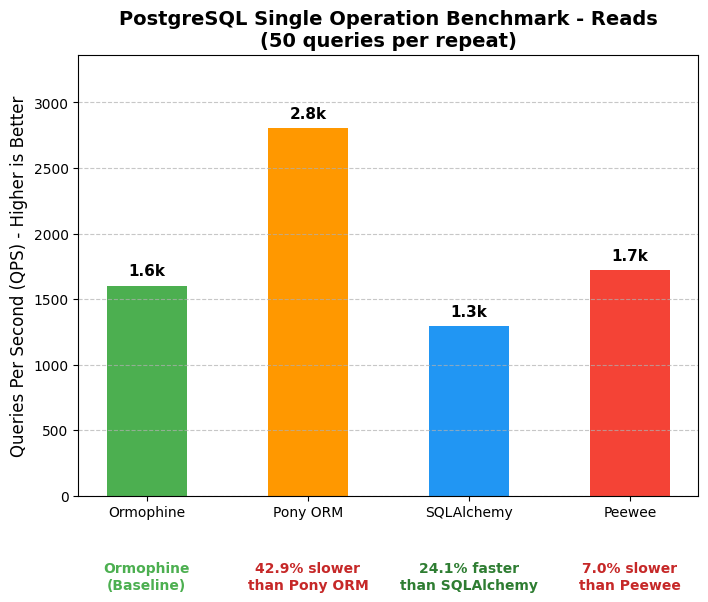
|
Deletes: 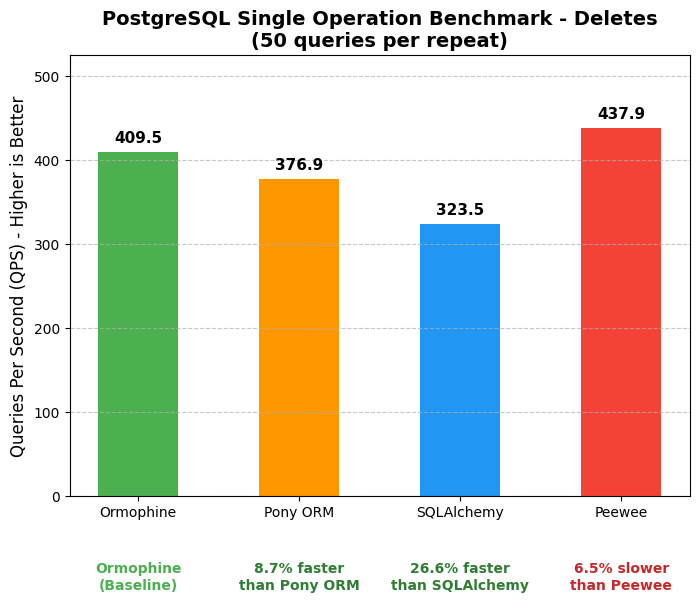
|
Batch Operation Test
(Executed 500 queries total — 5 repeats × 100 statements per chunk — for each CUD operation per ORM)
|
Inserts: 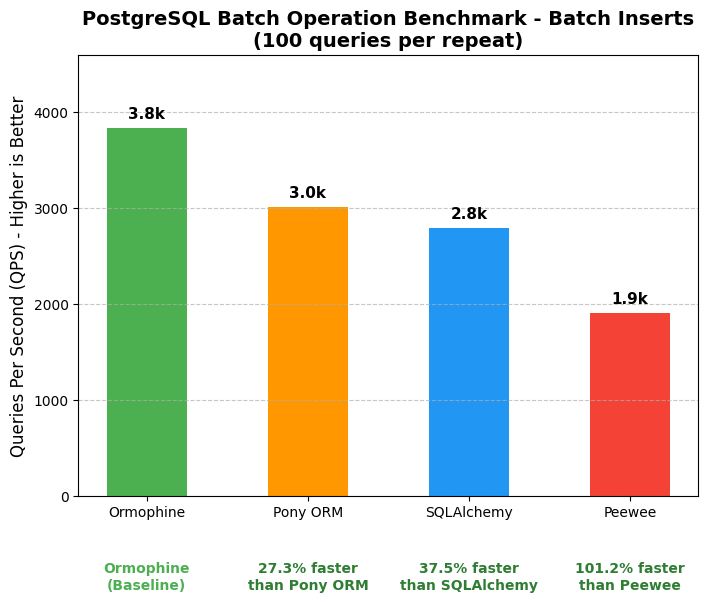
|
Updates: 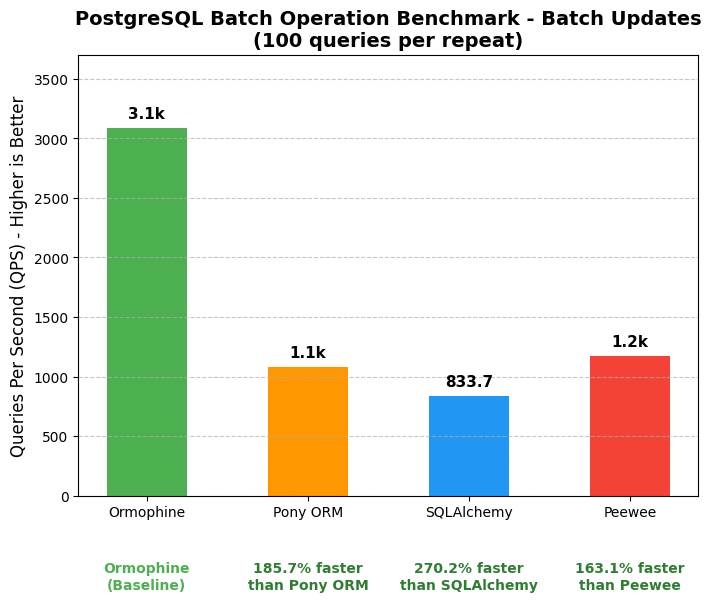
|
Deletes: 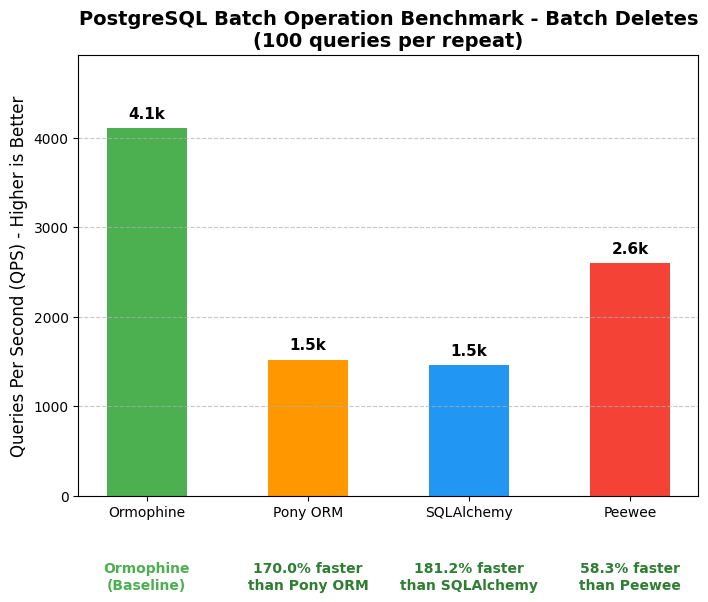
|
MySQL Results
Single Operations Test
(Executed 10,000 queries total — 200 repeats × 50 chunk size — for each CRUD operation per ORM)
|
Inserts: 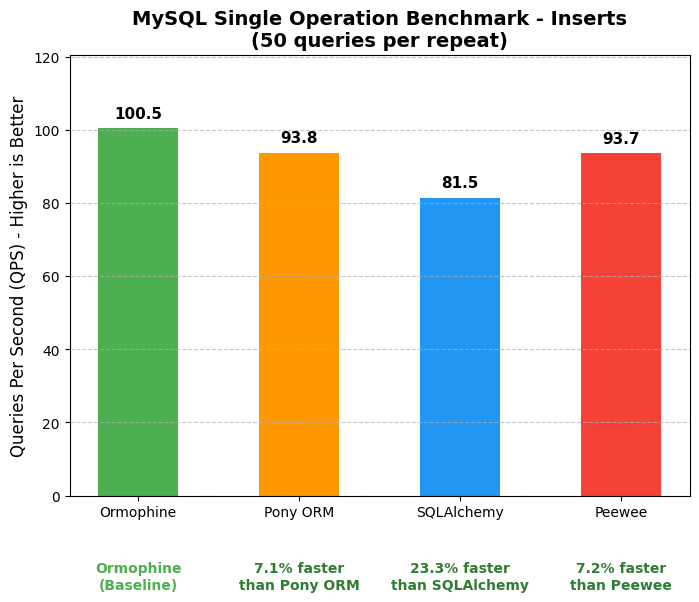
|
Updates: 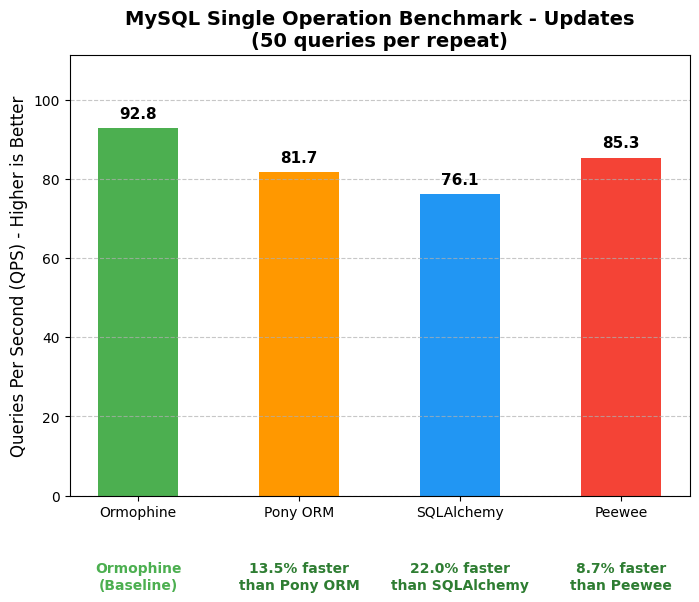
|
|
Reads: 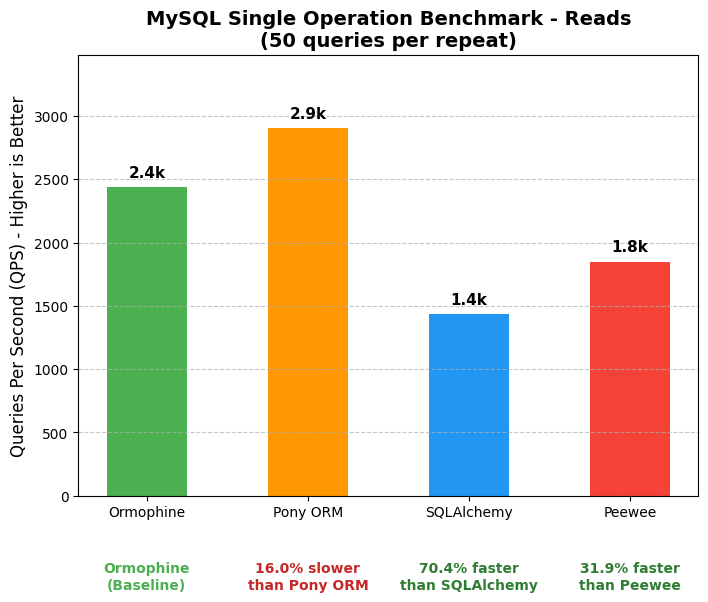
|
Deletes: 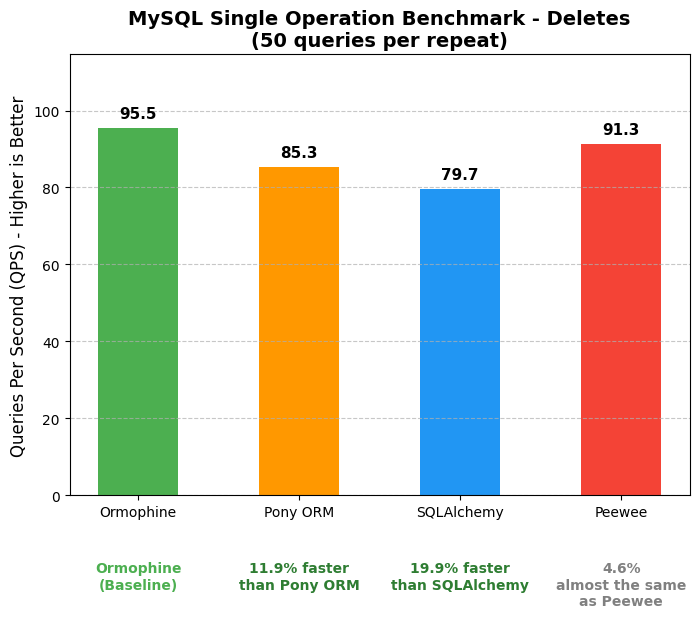
|
Batch Operation Test
(Executed 500 queries total — 5 repeats × 100 statements per chunk — for each CUD operation per ORM)
|
Inserts: 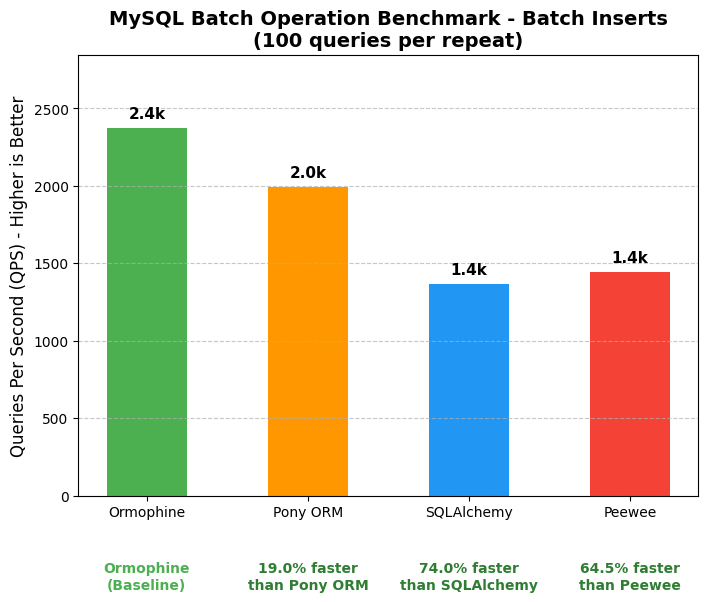
|
Updates: 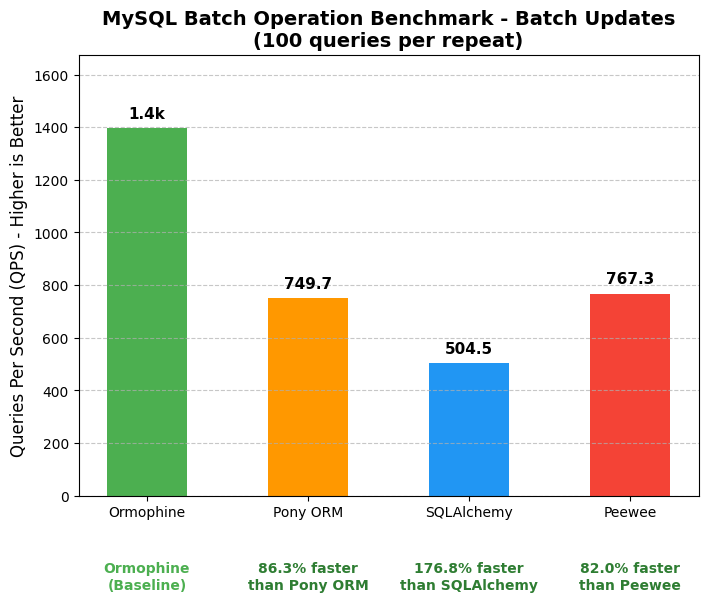
|
Deletes: 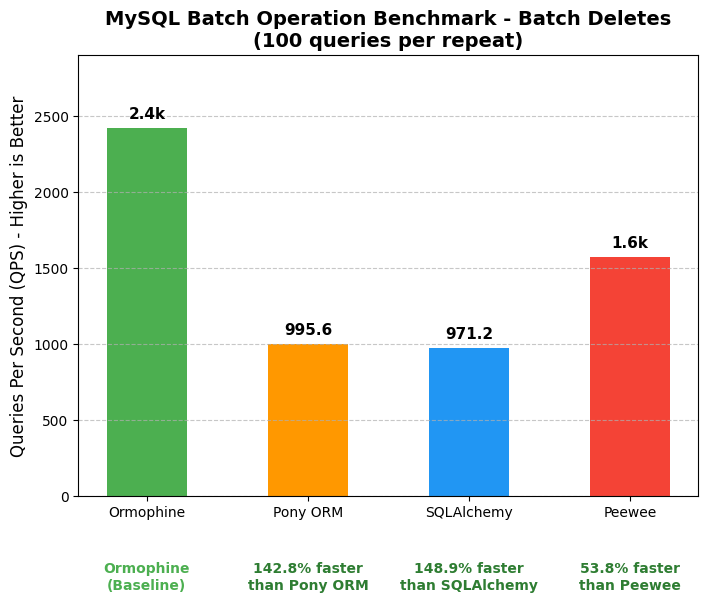
|
🎯 Scope & Limitations (What Ormophine is NOT)
Ormophine is deliberately designed to be minimalist, intuitive, and blisteringly fast for standard CRUD workloads. By keeping the core lightweight, we intentionally avoid the baggage of enterprise ORM patterns.
To help you decide if Ormophine is right for your project, here is a transparent overview of what Ormophine does not cover:
1. No Declarative Model Classes or Active Record Objects
Ormophine dynamically reflects your database schema at runtime (db.users.name).
- Queries return clean Python primitives and tuples, not heavyweight model instances.
- There is no static class boilerplate (
class User(Model): ...). - Note: Because tables and columns are resolved dynamically at runtime, IDE auto-completion / static type hints (like Mypy) for column names are not available.
2. No Relationship Mapping (Lazy / Eager Loading)
- Ormophine does not provide automated relational navigation properties (e.g.,
user.ordersor automated backreferences). - Multi-table operations are performed explicitly using clean, chained join builders (
.inner_join(),.left_join(),.right_join()).
3. No Unit of Work / Identity Map / Dirty Tracking
- There is no background session tracking modified object attributes (e.g.,
user.email = "new"; db.commit()). - All updates, inserts, and deletes are explicit via
.update(),.insert(), or transactional.batch()scripts.
4. No Schema Migration Engine (Not an Alembic / Django Migrations Replacement)
- Ormophine provides simple, imperative DDL helpers (
create_table,add_column,delete_column,rename_table,create_index). - It does not track migration versions, generate automatic schema diffs, or provide rollback migration histories. For complex enterprise schema evolution, use an external migration tool.
5. Synchronous Only (No async / await Support)
- Ormophine's drivers use optimized multi-threading (dedicated writer queues in SQLite, robust connection pooling in MySQL/PostgreSQL), but all API calls are synchronous (blocking I/O).
- There is currently no
asyncio/awaitsyntax support for ASGI frameworks.
6. Complex SQL Constructs Outside Standard CRUD
Ormophine covers common queries, slicing, arithmetic, string manipulation, conditionals, and standard joins. However, advanced SQL constructs are not natively built into the high-level query builder:
GROUP BY&HAVING: Not exposed inget_row()arguments (aggregates evaluate across target datasets).- Window Functions: (
ROW_NUMBER(),RANK(),OVER (PARTITION BY ...)are omitted). - Set Operations: (
UNION,UNION ALL,INTERSECT,EXCEPT). - Arbitrary CTEs / Nested Derived Tables: (
WITH ...queries). - Need these? You can always drop down to raw SQL at any time using
db.custom_execute_with_fetch(...).
7. Non-Supported Database Engines
- Ormophine exclusively supports SQLite, MySQL, and PostgreSQL.
- Oracle, Microsoft SQL Server (MSSQL), CockroachDB, and NoSQL engines are not supported.
💡 Rule of Thumb: When to Use Ormophine?
| Use Ormophine If... | Use SQLAlchemy / Django ORM If... |
|---|---|
| ✅ You want clean, zero-boilerplate Python CRUD. | ❌ You need a full Unit of Work / Identity Map architecture. |
✅ You want to query columns using natural Python syntax (.lower(), slicing [2:5], conditionals .If().Else()). |
❌ You need automated schema migrations with history rollbacks (Alembic). |
| ✅ You want lightweight, fast, auto-committed operations without managing sessions. | ❌ You need async I/O (asyncio / asyncpg / aiosqlite). |
| ✅ You already have an existing database or prefer simple schema definition. | ❌ You rely heavily on complex Window functions, CTEs, or ORM-managed relationship graphs (user.profile.posts). |
Installation
pip install Ormophine
Project Status & Roadmap
Ormophine is intentionally lightweight. We don't aim to match the feature count of enterprise ORMs — we aim to make simple CRUD as simple as it can possibly be.
⚠️ Work in Progress
Ormophine is currently in active development. While it is highly functional and fast, it is not yet as feature-complete as legacy ORMs like SQLAlchemy or Django ORM.
Our philosophy is to keep the core simple and fast. In future releases, we plan to simulate even more Python string and list methods to make the query syntax even closer to pure Python.
Current Roadmap
- SQLite backend with full ORM
- MySQL backend with connection pooling
- PostgreSQL backend with connection pooling
- Operator overloading and slicing (
[]) for columns - String methods simulation (
lower,upper,strip,startswith, etc.) - Batch / bulk operations
- AI Reference files for LLM assistance
- Expanding simulated Python methods (
.replace(),.find(), etc.) - Benchmark suite publication
- Video Tutorials
- Further performance optimizations and extended simulated methods
Video Tutorials
🎥 Coming Soon! We are preparing a comprehensive video series to help you get started with Ormophine, from basic connections to advanced concurrent read/write pooling and schema management.
Stay tuned—links will be posted here soon.
Contributing
The codebase is currently in active development. Contributions, bug reports, and feature requests are very welcome! Please feel free to open an issue or submit a pull request.
License
Ormophine is released under the MIT License, a permissive open-source license commonly used by Python libraries. You may use, copy, modify, merge, publish, distribute, sublicense, and sell the software, subject to including the original copyright and license notices in copies or substantial portions of the software.
The software is provided "as is", without warranty. See the full license text for the complete terms.
1 maintainer

Release files for Ormophine 0.12.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ormophine-0.12.6.tar.gz | 448.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ormophine-0.12.6-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 893.7 kB
Release files / ormophine-0.12.6.tar.gz
| Download URL | ormophine-0.12.6.tar.gz |
|---|---|
| Size | 448.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c6b49010b2c4842f038ef7cabeb3fdf9e0666a649240d30a7b5435c4d36f89a3
|
|
BLAKE2b-256 checksum How to use checksums |
f4762b540a6ed35ce6266aa614350762f52973331e9ed90360e06b98d8becd46
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency logRelease files / ormophine-0.12.6-py3-none-any.whl
| Download URL | ormophine-0.12.6-py3-none-any.whl |
|---|---|
| Size | 445.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1302b29a4c260835dae62b9fbf09fefef4749cf9c6d253d3a13a21e0ef0651ed
|
|
BLAKE2b-256 checksum How to use checksums |
c4ce55acaa5cd5a75b623d8cad312feabcc20b4787e4b09b74b5f5bcb42ab00c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency log













