
LLM as Function, Prompt as Code, Context-Centric



Update Notes (0.8.4)
PyRepl terminal isolation: PyRepl worker processes now isolate fd 0/1/2 from host terminals, capture direct fd writes and subprocess stdout/stderr into tool output, and drop late child-process output so it cannot corrupt TUI hosts or contaminate later snippets. See CHANGELOG for details.
Documentation
Design Philosophy
| Principle | Meaning |
|---|---|
| LLM is Function | An LLM call is indistinguishable from a Python function call: signature, type hints, return value |
| Prompt as Code | DocString is the system prompt. Code and prompt are never separated |
| Context-Centric | Each LLM request is compiled from invocation config, transcript/history, and internal runtime patches |
Quick Start
Installation
pip install SimpleLLMFunc
Build a General Agent in 30 Lines
That's it — a coding agent with persistent REPL, file tools, self-reflection memory, context compaction, and parallel fork:
from SimpleLLMFunc import llm_chat, OpenAICompatible, tui
from SimpleLLMFunc.builtin import PyRepl, FileToolset

llm = OpenAICompatible.load_from_json_file("provider.json")["openrouter"]["gpt-5.4"]
repl = PyRepl()
file_tools = FileToolset("./sandbox").toolset

@tui
@llm_chat(
    llm_interface=llm,
    toolkit=[*repl.toolset, *file_tools],
    stream=True,
    self_reference_key="agent_main",
)
async def agent(message: str, history=None):
    """You are a practical local coding agent.

    ## Rules
    - Read files before editing. Prefer small, local edits.
    - Use execute_code for Python. Use file tools for read/grep/sed.
    - When a milestone is done, compact your context via:
      runtime.selfref.context.compact(...)
    - For parallel subtasks, spawn forks via:
      runtime.selfref.fork.spawn(...)
      then gather with runtime.selfref.fork.gather_all(...)
    """

if __name__ == "__main__":
    agent()  # launches an interactive TUI
Run it:
python agent.py
The agent gets a terminal UI with streaming markdown, tool-call panels, and fork lifecycle visualization — no extra code needed.
See examples/tui_general_agent_example.py for the full production version with environment blocks, workspace config, and debug logging.
A Simpler Start — LLM as a Typed Function
If you just need an LLM-powered function with type-safe returns:
import asyncio
from SimpleLLMFunc import llm_function, OpenAICompatible

llm = OpenAICompatible.load_from_json_file("provider.json")["your_provider"]["model"]

@llm_function(llm_interface=llm)
async def classify_sentiment(text: str) -> str:
    """
    Analyze the sentiment of the given text.

    Args:
        text: Text to analyze

    Returns:
        One of: 'positive', 'negative', or 'neutral'
    """
    pass  # Prompt as Code!

async def main():
    result = await classify_sentiment("This product is amazing!")
    print(f"Sentiment: {result}")

asyncio.run(main())
Initial Configuration
- Copy configuration template:
cp env_template .env
-
Configure API keys in
.env. Optionally setLOG_DIR,LANGFUSE_BASE_URL,LANGFUSE_SECRET_KEY,LANGFUSE_PUBLIC_KEY. -
Check
examples/provider_template.jsonfor multi-provider configuration.
Architecture
SimpleLLMFunc is organized in five layers, each with a strict boundary:
┌──────────────────────────────────────────────────────────────────────────┐
│  L1. Decorator Layer          @llm_function / @llm_chat / @tool         │
│      Python call → InvocationSpec + PromptContract + TranscriptSeed     │
├──────────────────────────────────────────────────────────────────────────┤
│  L2. Compile Boundary          compile_pipeline.py (single entry)       │
│      Mutations applied → system prompt assembled → LLM messages rendered│
├──────────────────────────────────────────────────────────────────────────┤
│  L3. ReAct Runtime             react_loop.py (event-only core)          │
│      LLM call → tool batch → mutation collection → loop                 │
├──────────────────────────────────────────────────────────────────────────┤
│  L4. Interface Layer           OpenAICompatible / OpenAIResponsesAPI    │
│      Provider adapters, key pool, token-bucket rate limiting            │
├──────────────────────────────────────────────────────────────────────────┤
│  L5. Infrastructure            hooks / logger / observability / type    │
│      Event stream, Langfuse spans, structured logging, multimodal types │
└──────────────────────────────────────────────────────────────────────────┘
Core Data Flow: Mutation-Driven Context Evolution
The central rule: context changes are applied through compile-time mutation application, not by letting tools or selfref directly rewrite the live context.
     ┌──────────┐   ┌──────────────────────┐
     │ LLM Call │──►│AssistantMessageMutation│
     └──────────┘   └──────────┬───────────┘
     ┌──────────┐   ┌──────────────────────┐│
     │Tool Exec │──►│  ToolResultMutation   ││
     └──────────┘   └──────────┬───────────┘│
     ┌──────────┐   ┌──────────────────────┐│   ┌───────────────┐
     │SelfRef   │──►│ ExperienceRemember /  ││──►│compile_context│──► Compiled Context
     │ Hooks    │   │ ContextSummary        ││   │ apply_mutations│   (LLM-visible)
     └──────────┘   └──────────────────────┘│   └───────────────┘
     ┌──────────┐   ┌──────────────────────┐│
     │Abort     │──►│Truncated / Cancelled  ││
     └──────────┘   └──────────────────────┘│
                                         all mutations
9 mutation types cover every context change: assistant messages, tool results, multimodal outputs, full replacement, compaction, experience remember/forget, truncation, and cancellation.
SelfRef: Meta Context Editing
SelfRef enables an agent to read and edit its own context at runtime, while respecting the mutation boundary:
| Operation | What it does | Mutation produced |
|---|---|---|
| Remember | Add durable experience that survives across turns | ExperienceRememberMutation |
| Forget | Remove experience by ID | ExperienceForgetMutation |
| Compact | Replace working transcript with a structured summary | ContextSummaryMutation |
| Fork | Spawn a child agent with inherited context snapshot | (sub-agent runs independently) |
All changes take effect at the next compile boundary — SelfRef cannot bypass compile to modify live context directly.
Project Map
SimpleLLMFunc/
├── llm_decorator/             # L1: Decorator layer
│   ├── llm_function_decorator.py  # @llm_function — stateless LLM → typed result
│   ├── llm_chat_decorator.py      # @llm_chat public facade / LLMChat callable
│   ├── chat_call_context.py       # Bound args/template/runtime call context
│   ├── chat_selfref.py            # SelfRef binding/finalization helpers
│   ├── chat_toolkit.py            # Runtime toolkit and fork toolkit helpers
│   ├── chat_types.py              # Shared decorator constants/types
│   ├── invocation_spec.py         # InvocationSpec / PromptContract / TranscriptSeed
│   ├── invocation_builder.py      # Spec builders for function/chat modes
│   ├── prompt_contract.py         # Prompt templates + XML Schema generation
│   ├── signature.py               # Signature binding + trace_id + log context
│   └── utils/tools.py             # Tool processing + spec collection
│
├── base/                      # L2+L3: Compile boundary + ReAct runtime
│   ├── compile_pipeline.py        # Single compile entry: reduce + convert
│   ├── context_compile.py         # Mutation apply engine
│   ├── llm_input_render.py        # Ephemeral system prompt rendering
│   ├── react_loop.py              # ReAct main loop (event-only)
│   ├── llm_call.py                # Single LLM call execution
│   ├── tool_scheduler.py          # Concurrent tool scheduling
│   ├── post_process.py            # Response → typed result (XML → Pydantic)
│   ├── types/                     # Core type contracts (all dataclasses)
│   │   ├── source.py              # CompileSource / DataFromAgentConfig / DataFromSelfRef
│   │   ├── context.py             # ContextState / CompiledContext
│   │   ├── compile.py             # ReducedTurnContext / CompiledTurnContext
│   │   ├── mutation.py            # ContextMutation (9 variant union type)
│   │   ├── react.py               # ReactLoopState
│   │   ├── llm.py                 # SingleLLMCallResult
│   │   └── scheduler.py           # ToolSchedulerResult
│   ├── messages/                  # Message building / extraction / validation
│   ├── tool_call/                 # Tool call extraction / execution / streaming / validation
│   └── type_resolve/              # Type description + XML round-trip
│
├── tool/                      # @tool decorator + Tool base class
├── builtin/                   # Built-in tools
│   ├── pyrepl.py                  # PyRepl public facade
│   ├── pyrepl_execution.py        # execute/reset orchestration
│   ├── pyrepl_worker_client.py    # subprocess + queue lifecycle
│   ├── pyrepl_worker_mixin.py     # facade-compatible worker wrappers
│   ├── pyrepl_primitive_host.py   # runtime primitive host / backend bridge
│   ├── pyrepl_tools.py            # execute_code/reset_repl tool factory
│   ├── pyrepl_audit.py            # audit log writer
│   ├── pyrepl_input_bridge.py     # process-wide input bridge
│   ├── pyrepl_input_mixin.py      # PyRepl input submission API
│   └── file_tools.py              # Workspace-scoped file tools
│
├── runtime/                   # Runtime primitive system
│   ├── primitives.py              # PrimitiveRegistry / PrimitivePack / @primitive()
│   ├── worker_proxy.py            # WorkerRuntimeProxy (runtime.selfref.*)
│   └── selfref/
│       ├── state.py               # SelfReference public facade
│       ├── store.py               # Durable history/source store
│       ├── active_turn.py         # Active memory/fork/toolkit/template contextvars
│       ├── mutations.py           # Pending compaction/context mutation queues
│       ├── memory_api.py          # self_reference.memory[...] proxy/handle
│       ├── context_memory.py      # Context memory, experiences, compaction, direct edits
│       ├── agent_binding.py       # Bound recursive agent callable state
│       ├── fork_manager.py        # Fork/spawn/gather lifecycle
│       ├── fork_utils.py          # Fork helper functions/constants
│       ├── session.py             # SelfRefSession (invocation-scoped plugin)
│       ├── context_ops.py         # Context parse / build / canonicalize
│       └── primitives.py          # selfref runtime primitives
│
├── hooks/                     # Event stream system
│   ├── events.py                  # 14 ReActEvent subtypes
│   ├── stream.py                  # ReactOutput / ResponseYield / EventYield
│   ├── event_bus.py               # Event ingress + origin metadata
│   └── event_emitter.py           # Tool custom event emitter
│
├── interface/                 # L4: LLM interface layer
│   ├── llm_interface.py           # Abstract base class
│   ├── openai_compatible.py       # OpenAI Compatible adapter
│   ├── openai_responses_compatible.py  # Responses API adapter
│   ├── key_pool.py                # API key rotation pool
│   └── token_bucket.py            # Token-bucket rate limiting
│
├── logger/                    # Structured logging + trace_id
├── observability/             # Langfuse integration
├── type/                      # Multimodal types (Text / ImgUrl / ImgPath)
└── utils/tui/                 # Textual TUI integration
Detailed Guide
@llm_function — Stateless Typed LLM Calls
Returns Pydantic models, primitives, dicts, or lists directly:
from typing import List
from pydantic import BaseModel, Field

class ProductReview(BaseModel):
    rating: int = Field(..., description="Product rating, 1-5")
    pros: List[str] = Field(..., description="Advantages")
    cons: List[str] = Field(..., description="Disadvantages")
    summary: str = Field(..., description="Review summary")

@llm_function(llm_interface=llm)
async def analyze_review(product_name: str, review_text: str) -> ProductReview:
    """You are a professional product review expert.
    Analyze the review and generate a structured report.

    Args:
        product_name: Product name
        review_text: User review content

    Returns:
        A structured ProductReview object
    """
    pass

result = await analyze_review("XYZ Headphones", "Great sound but unstable connection...")
print(result.rating)   # 4
print(result.pros)     # ["Great sound quality", ...]
@llm_chat — Conversational Agents
Multi-turn history, streaming, tool calls, SelfRef integration:
@llm_chat(llm_interface=llm, toolkit=[search_tool, calculator], stream=True)
async def agent(user_message: str, history=None):
    """An intelligent assistant that can search and calculate."""
    pass

async for response, updated_history in agent("Hello", []):
    print(response)
@tui — Terminal UI for @llm_chat
Out-of-the-box Textual TUI with streaming markdown, tool-call panels, token stats, and fork visualization:
from SimpleLLMFunc import llm_chat, tui

@tui(custom_event_hook=[...])
@llm_chat(llm_interface=llm, stream=True)
async def agent(message: str, history=None):
    """Your agent prompt"""

if __name__ == "__main__":
    agent()  # launches TUI
See examples/tui_chat_example.py for a full example. Each EventYield carries origin metadata for fork-aware event routing.
@tool — Register Functions as LLM Tools
from SimpleLLMFunc.tool import tool
from SimpleLLMFunc.type import ImgPath

@tool(name="generate_chart", description="Generate a chart from data")
async def generate_chart(data: str, chart_type: str = "bar") -> ImgPath:
    """Generate charts based on provided data.

    Args:
        data: CSV format data
        chart_type: Chart type, default is bar chart

    Returns:
        Generated chart file path
    """
    chart_path = "./generated_chart.png"
    # ... chart generation logic
    return ImgPath(chart_path)
Tools can be stacked with @llm_function on the same function.
Tools can also return multiple images with optional text, for example tuple[str, list[ImgPath | ImgUrl]]. PyRepl's execute_code uses this path when code outputs images through display(Image(...)) or an image-rich last expression.
Multimodal Support
from SimpleLLMFunc.type import UserChatMessage, ImgPath, ImgUrl, Text

@llm_function(llm_interface=llm)
async def analyze_image(
    description: Text,        # Text description
    web_image: ImgUrl,        # Web image URL or data: URL
    local_image: ImgPath      # Local image path, encoded as a data URL
) -> str:
    """Analyze images based on the description"""
    pass

result = await analyze_image(
    description=Text("Describe the differences between these images"),
    web_image=ImgUrl("https://example.com/image.jpg"),
    local_image=ImgPath("./reference.jpg")
)

@llm_chat(llm_interface=llm)
async def vision_agent(message: UserChatMessage, history=None):
    """Answer questions about the user's multimodal message."""
    pass

async for output in vision_agent(
    UserChatMessage.multimodal(
        "What is in this image?",
        ImgUrl("https://example.com/cat.jpg", detail="high"),
    ),
    history=[],
):
    ...
llm_function keeps the normal Python-function style: declare image parameters as ImgUrl / ImgPath / lists of those types. llm_chat accepts an explicit OpenAI-compatible UserChatMessage, so an Agent can receive text and image content in one user message.
Tool-Call Limit Default
Both @llm_function and @llm_chat default to max_tool_calls=None (unbounded). Pass an explicit integer like max_tool_calls=8 for safety caps:
@llm_chat(llm_interface=llm, stream=True, max_tool_calls=12)
async def cautious_agent(message: str, history=None):
    """Agent with an explicit safety cap."""
    pass
Decorator Parameters
@llm_function(
    llm_interface=llm_interface,
    toolkit=[tool1, tool2],
    retry_on_exception=True,
    timeout=60
)
async def my_function(param: str) -> str:
    """Supports {language} {style} analysis"""
    pass

result = await my_function(
    "input",
    _template_params={"language": "English", "style": "Professional"},
)
_template_params is passed at call time and only used to format the DocString via str.format. It is removed before signature binding and is not part of the LLM input.
LLM Provider Interface
Supported providers:
- OpenAI (GPT-4, etc.)
- Deepseek
- Anthropic Claude
- Volc Engine Ark
- Baidu Qianfan
- Local LLM (Ollama, vLLM, etc.)
- Any OpenAI API-compatible service
- OpenAI Responses API via
OpenAIResponsesCompatible
from SimpleLLMFunc import APIKeyPool, OpenAICompatible, OpenAIResponsesCompatible

# From JSON config
provider = OpenAICompatible.load_from_json_file("provider.json")
llm = provider["deepseek"]["v3-turbo"]

# Direct creation
llm = OpenAICompatible(
    api_key_pool=APIKeyPool(["sk-xxx"], provider_id="deepseek-chat"),
    base_url="https://api.deepseek.com/v1",
    model_name="deepseek-chat",
)

# Responses API
responses_llm = OpenAIResponsesCompatible(
    api_key_pool=APIKeyPool(["sk-xxx"], provider_id="openrouter-gpt-5.4"),
    base_url="https://openrouter.ai/api/v1",
    model_name="gpt-5.4",
)
For Responses API, write normal docstrings and chat history. The adapter maps system prompt to instructions and forwards reasoning={...}.
provider.json
{
    "deepseek": [{
        "model_name": "deepseek-v3.2",
        "api_keys": ["sk-key-1", "sk-key-2"],
        "base_url": "https://api.deepseek.com/v1",
        "max_retries": 5,
        "retry_delay": 1.0,
        "rate_limit_capacity": 10,
        "rate_limit_refill_rate": 1.0
    }]
}
Logging and Observability
| Feature | Description |
|---|---|
| Trace ID tracking | Auto-generated trace_id per call, linking all related logs |
| Structured logging | Multiple levels (DEBUG–CRITICAL), colored console output |
| Context propagation | Async-safe contextvars, trace_id auto-associated |
| File persistence | Auto-rotation and archiving |
| Langfuse integration | Visualize LLM call chains, nested spans per tool/LLM call |
from SimpleLLMFunc.logger import app_log, push_error, log_context

app_log("Starting request", trace_id="request_123")

with log_context(trace_id="task_456", function_name="analyze_text"):
    app_log("Analysis started")     # inherits trace_id
    push_error("Analysis failed")   # inherits trace_id
Built-in Tools
PyRepl — persistent IPython subprocess with variable persistence, execution timeout, event-emitter streaming, and primitive pack support:
from SimpleLLMFunc.builtin import PyRepl
repl = PyRepl(working_directory="./workspace")
tools = repl.toolset  # [execute_code, reset_repl, list_variables]
FileToolset — workspace-scoped file tools with stale-write protection:
from SimpleLLMFunc.builtin import FileToolset
file_tools = FileToolset("./workspace").toolset  # [read_file, read_image, grep, sed, echo_into]
API Key Management and Traffic Control
- Multiple API keys with min-heap load balancing
- Token-bucket algorithm for rate limiting
- Per-model configuration in
provider.json
Async Native
All decorators return async functions. Use await or asyncio.run():
# Concurrent LLM calls
results = await asyncio.gather(*[classify_text(t) for t in texts])
Common Use Cases
Data Processing
@llm_function(llm_interface=llm)
async def extract_entities(text: str) -> Dict[str, List[str]]:
    """Extract named entities from text"""
    pass

entities = await extract_entities("John works at Apple in Beijing")
# {"person": ["John"], "location": ["Beijing"], "organization": ["Apple"]}
General-Purpose Agent
@llm_chat(llm_interface=llm, toolkit=[*repl.toolset, *file_tools], stream=True, self_reference_key="main")
async def agent(message: str, history=None):
    """A coding agent with REPL, file tools, and self-reflection"""
    pass
Batch Processing
results = await asyncio.gather(*[classify_text(t) for t in texts])
Multimodal
@llm_function(llm_interface=llm)
async def analyze_images(local_img: ImgPath, web_img: ImgUrl) -> str:
    """Compare and analyze two images"""
    pass
Running Examples
pip install SimpleLLMFunc
cp env_template .env
# Edit .env with your API keys

python examples/tui_general_agent_example.py    # Full coding agent with TUI
python examples/llm_function_pydantic_example.py # Structured output
python examples/event_stream_chatbot.py          # Chat + event stream
python examples/parallel_toolcall_example.py     # Concurrent tool calls
python examples/pyrepl_example.py                # Persistent REPL
python examples/pyrepl_seaborn_multimodal_images.py # PyRepl image outputs
python examples/response_api_example.py          # Responses API
Export Agent Skills
simplellmfunc-skill usage ~/.config/opencode/skills
simplellmfunc-skill developer ~/.config/opencode/skills
Use --force to overwrite.
Configuration
Priority (high → low): program config → environment variables → .env file.
# .env
LOG_DIR=./logs
LOG_LEVEL=INFO
LANGFUSE_BASE_URL=https://cloud.langfuse.com
LANGFUSE_PUBLIC_KEY=pk_xxx
LANGFUSE_SECRET_KEY=sk_xxx
LANGFUSE_EXPORT_ALL_SPANS=true
Contributing
- Bug reports: GitHub Issues
- Feature suggestions welcome
- Documentation improvements welcome
- Example code welcome
More Resources
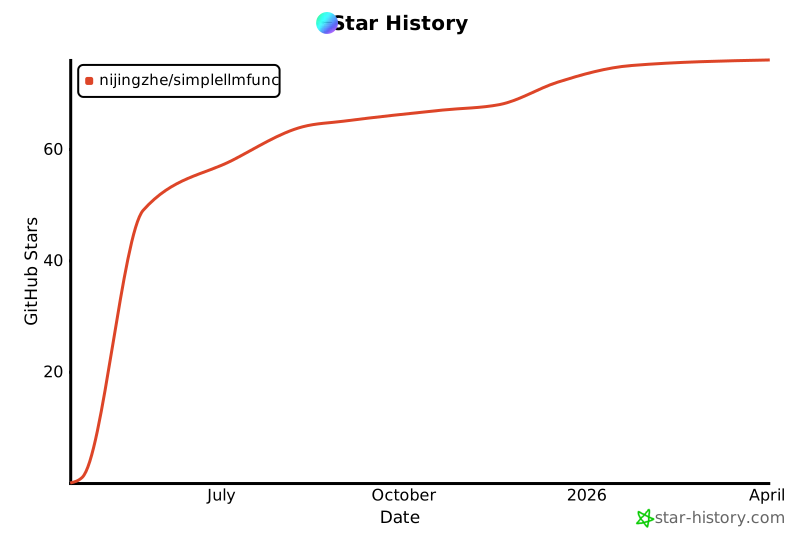
Star History
Citation
@software{ni2025simplellmfunc,
  author = {Jingzhe Ni},
  month = {February},
  title = {{SimpleLLMFunc: A New Approach to Build LLM Applications}},
  url = {https://github.com/NiJingzhe/SimpleLLMFunc},
  version = {0.8.4},
  year = {2026}
}
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for SimpleLLMFunc 0.8.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| simplellmfunc-0.8.4.tar.gz | 347.5 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| simplellmfunc-0.8.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 792.9 kB
Release files / simplellmfunc-0.8.4.tar.gz
| Download URL | simplellmfunc-0.8.4.tar.gz |
|---|---|
| Size | 347.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f19eee269cb5a3028dac269db0bddba3a1a234db51c3ad22385fa238d19f2995
|
|
BLAKE2b-256 checksum How to use checksums |
f5c59de00f7b3202660374686332ac07ec03cc0de631e02fcb5f4138d4217a94
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/2.3.2 CPython/3.14.4 Darwin/25.5.0
|
Release files / simplellmfunc-0.8.4-py3-none-any.whl
| Download URL | simplellmfunc-0.8.4-py3-none-any.whl |
|---|---|
| Size | 445.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ab1d4dc84bcea82a78d7de0c8d415c7cd4ffde6634c7b368371c312f4c390559
|
|
BLAKE2b-256 checksum How to use checksums |
c40d8f48d053d96728655dd05a56a954999721a65a9b7387aa55047865b8e7e7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/2.3.2 CPython/3.14.4 Darwin/25.5.0
|
Security for SimpleLLMFunc 0.8.4
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














