
tableschema-spss-py


Generate and load SPSS files based on Table Schema descriptors.
Features
- implements
tableschema.Storageinterface
Contents
Getting Started
Installation
The package use semantic versioning. It means that major versions could include breaking changes. It's highly recommended to specify package version range in your setup/requirements file e.g. package>=1.0,<2.0.
pip install tableschema-spss
Examples
Code examples in this readme requires Python 3.3+ interpreter. You could see even more example in examples directory.
For this example your schema should be compatible with SPSS storage - https://github.com/frictionlessdata/tableschema-spss-py#creating-sav-files
from tableschema import Table

# Load and save table to SPSS
table = Table('data.csv', schema='schema.json')
table.save('data', storage='spss', base_path='dir/path')
Documentation
The whole public API of this package is described here and follows semantic versioning rules. Everyting outside of this readme are private API and could be changed without any notification on any new version.
Storage
Package implements Tabular Storage interface (see full documentation on the link):
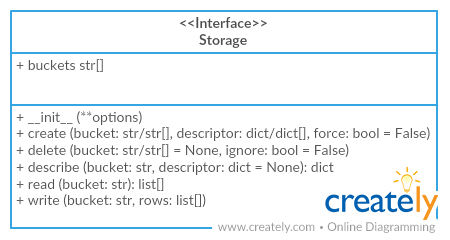
This driver provides an additional API:
Storage(base_path=None)
base_path (str)- a valid directory path where .sav files can be created and read. If no base_path is provided, the Storage object methods will accept file paths rather than bucket names.
storage.buckets
List all .sav and .zsav files at base path. Bucket list is only maintained if Storage has a valid base path, otherwise will return None.
(str[]/None)- returns bucket list or None
With a base path
We can get storage with a specified base path this way:
from tableschema_spss import Storage

storage_base_path = 'path/to/storage/dir'
storage = Storage(storage_base_path)
We can then interact with storage buckets ('buckets' are SPSS .sav/.zsav files in this context):
storage.buckets  # list buckets in storage
storage.create('bucket', descriptor)
storage.delete('bucket')  # deletes named bucket
storage.delete()  # deletes all buckets in storage
storage.describe('bucket') # return tableschema descriptor
storage.iter('bucket') # yields rows
storage.read('bucket') # return rows
storage.write('bucket', rows)
Without a base path
We can also create storage without a base path this way:
from tableschema_spss import Storage

storage = Storage()  # no base path argument
Then we can specify SPSS files directly by passing their file path (instead of bucket names):
storage.create('data/my-bucket.sav', descriptor)
storage.delete('data/my-bucket.sav')  # deletes named file
storage.describe('data/my-bucket.sav') # return tableschema descriptor
storage.iter('data/my-bucket.sav') # yields rows
storage.read('data/my-bucket.sav') # return rows
storage.write('data/my-bucket.sav', rows)
Note that storage without base paths does not maintain an internal list of buckets, so calling storage.buckets will return None.
Reading .sav files
When reading SPSS data, SPSS date formats, DATE, JDATE, EDATE, SDATE, ADATE, DATETIME, and TIME are transformed into Python date, datetime, and time objects, where appropriate.
Other SPSS date formats, WKDAY, MONTH, MOYR, WKYR, QYR, and DTIME are not supported for native transformation and will be returned as strings.
Creating .sav files
When creating SPSS files from Table Schemas, date, datetime, and time field types must have a format property defined with the following patterns:
date:%Y-%m-%ddatetime:%Y-%m-%d %H:%M:%Stime:%H:%M:%S.%f
Table Schema descriptors passed to storage.create() should include a custom spss:format property, defining the SPSS type format the data is expected to represent. E.g.:
{
    "fields": [
        {
            "name": "person_id",
            "type": "integer",
            "spss:format": "F8"
        },
        {
            "name": "name",
            "type": "string",
            "spss:format": "A10"
        },
        {
            "type": "number",
            "name": "salary",
            "title": "Current Salary",
            "spss:format": "DOLLAR8"
        },
        {
           "type": "date",
           "name": "bdate",
           "title": "Date of Birth",
           "format": "%Y-%m-%d",
           "spss:format": "ADATE10"
        }
    ]
}
Contributing
The project follows the Open Knowledge International coding standards.
Recommended way to get started is to create and activate a project virtual environment. To install package and development dependencies into active environment:
$ make install
To run tests with linting and coverage:
$ make test
For linting pylama configured in pylama.ini is used. On this stage it's already
installed into your environment and could be used separately with more fine-grained control
as described in documentation - https://pylama.readthedocs.io/en/latest/.
For example to sort results by error type:
$ pylama --sort <path>
For testing tox configured in tox.ini is used.
It's already installed into your environment and could be used separately with more fine-grained control as described in documentation - https://testrun.org/tox/latest/.
For example to check subset of tests against Python 2 environment with increased verbosity.
All positional arguments and options after -- will be passed to py.test:
tox -e py27 -- -v tests/<path>
Under the hood tox uses pytest configured in pytest.ini, coverage
and mock packages. This packages are available only in tox envionments.
Changelog
Here described only breaking and the most important changes. The full changelog and documentation for all released versions could be found in nicely formatted commit history.
v1.0
- Initial driver release


Release files for tableschema-spss 1.0.14
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| tableschema-spss-1.0.14.tar.gz | 13.9 kB | Without provenance | Details for tableschema-spss-1.0.14.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| tableschema_spss-1.0.14-py2.py3-none-any.whl | Python 3, Python 2 | none | any | Details for tableschema_spss-1.0.14-py2.py3-none-any.whl |
Total release size: 23.9 kB
Release files / tableschema-spss-1.0.14.tar.gz
| Download URL | tableschema-spss-1.0.14.tar.gz |
|---|---|
| Size | 13.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b9c1d4c8b1dc9fc445961212ad4c1673ecc9aab861bc85e57eb2888f9cb573ea
|
|
BLAKE2b-256 checksum How to use checksums |
c47cd5466108f55b2a92c86dc3e32888c4087c4642682a47752f5adee7a4c934
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/2.0.0 pkginfo/1.5.0.1 requests/2.22.0 setuptools/41.6.0 requests-toolbelt/0.9.1 tqdm/4.37.0 CPython/3.8.0
|
Release files / tableschema_spss-1.0.14-py2.py3-none-any.whl
| Download URL | tableschema_spss-1.0.14-py2.py3-none-any.whl |
|---|---|
| Size | 10.0 kB |
| Tags | Python 2 Python 3 |
|
SHA-256 checksum How to use checksums |
7decca6399925dafd641a90138658a81e03d78958a53d8e82e963c8360a950d9
|
|
BLAKE2b-256 checksum How to use checksums |
0918a177547c2228ebe4038dc2548fa7d5e20f4fef10073dd9024efdd483ae7d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/2.0.0 pkginfo/1.5.0.1 requests/2.22.0 setuptools/41.6.0 requests-toolbelt/0.9.1 tqdm/4.37.0 CPython/3.8.0
|
Security for tableschema-spss 1.0.14
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














