
TrorYong ASR Model
TrorYongASR, is an Automatic Speech Recognition Model implemented by KrorngAI.
TrorYong (ត្រយ៉ង) is Khmer word for giant ibis, the bird that symbolises Cambodia.
Support My Work
While this work comes truly from the heart, each project represents a significant investment of time -- from deep-dive research and code preparation to the final narrative and editing process. I am incredibly passionate about sharing this knowledge, but maintaining this level of quality is a major undertaking. If you find my work helpful and are in a position to do so, please consider supporting my work with a donation. You can click here to donate or scan the QR code below. Your generosity acts as a huge encouragement and helps ensure that I can continue creating in-depth, valuable content for you.
Installation
You can easily install tror-yong-asr using pip command as the following:
pip install tror-yong-asr
To use TrorYongASR, there are few dependencies: transformers, safetensors, and torchaudio.
Usage
Get started with the code below
from transformers import AutoProcessor
from tror_yong_asr import TrorYongASRModel, transcribe, translate, identify_language


model_id = "KrorngAI/TrorYongASR2-small"
processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)
model = TrorYongASRModel.from_pretrained(model_id)

result1 = identify_language('/path/to/audio_file.mp3', model, processor)
print(result1)

result2 = transcribe('/path/to/audio_file.mp3', model, processor, max_tokens=64)
print(result2)

result3 = translate('/path/to/audio_file.mp3', model, processor, max_tokens=64)
print(result3)
TrorYongASR has 2 pre-trained weights that support Khmer and English:
- Tiny version with
model_id=KrorngAI/TrorYongASR2-tiny - Small version with
model_id=KrorngAI/TrorYongASR2-small
Evaluation
Dataset
The evaluation assesses transcription capability on two datasets: 1) google/fleurs for Khmer and 2) openslr/librispeech_asr for English.
All results are from the test split of each dataset.
| Dataset | Language | Testing samples | Description |
|---|---|---|---|
| google/fleurs | Khmer | 765 | Multi-lingual dataset with Khmer language samples |
| librispeech_asr.clean | English | 2611 | Clean speech dataset for English transcription |
Audio longer than 30 seconds are excluded from the evaluation (that is why google/fleurs has 765 samples instead of 771 and librispeech_asr.clean has 2611 instead of 2620).
Metrics
For transcription task, 3 metrics below are used
- Token Error Rate (TER): Proportion of incorrectly predicted tokens
- Character Error Rate (CER): Proportion of characters that are incorrect
- Word Error Rate (WER): Proportion of words that are incorrect
TER measures model's capability in predicting the next token given the audio input and the current sequence of tokens. This metric is weaker than WER and CER because it doesn't account for insertions, deletions, substitutions, and autoregression as comprehensively.
Results
| Model | Metric | Khmer (fleurs) |
English (librispeech_asr.clean) |
|---|---|---|---|
| Tiny | WER | 57.07% | 20.35% |
| CER | 43.95% | 12.42% | |
| TER | 49% | 11% | |
| Small | WER | 36.70% | 10.12% |
| CER | 29.26% | 6.05% | |
| TER | 38% | 5% |
Both configurations performance well on English language. However, Khmer language remains a challenge.
Note: To compute CER and WER, whitespaces are added between words in Khmer text (Khmer text does not have word boundaries like English text). To do so, khmercut PyPI package is used to tokenize Khmer text into words, and then the words are joined back together with whitespaces.
It is due to no-boundary Khmer words that Token Error Rate is utilized as one of the metrics.
Comparison with TrorYongASR1 and Whisper:
| Size | Model | Parameters | Khmer (fleurs) |
English (librispeech_asr.clean) |
|---|---|---|---|---|
| Tiny | TrorYongASR2 | 29M | 57.07% | 20.35% |
| TrorYongASR1 | 29M | 75.88% | 54.33% | |
| Whisper | 39M | 100.6% | 7.6% | |
| Small | TrorYongASR2 | 136M | 36.70% | 10.12% |
| TrorYongASR1 | 135M | 50.46% | 21.75% | |
| Whisper | 244M | 104.4% | 3.4% |
Key Observations:
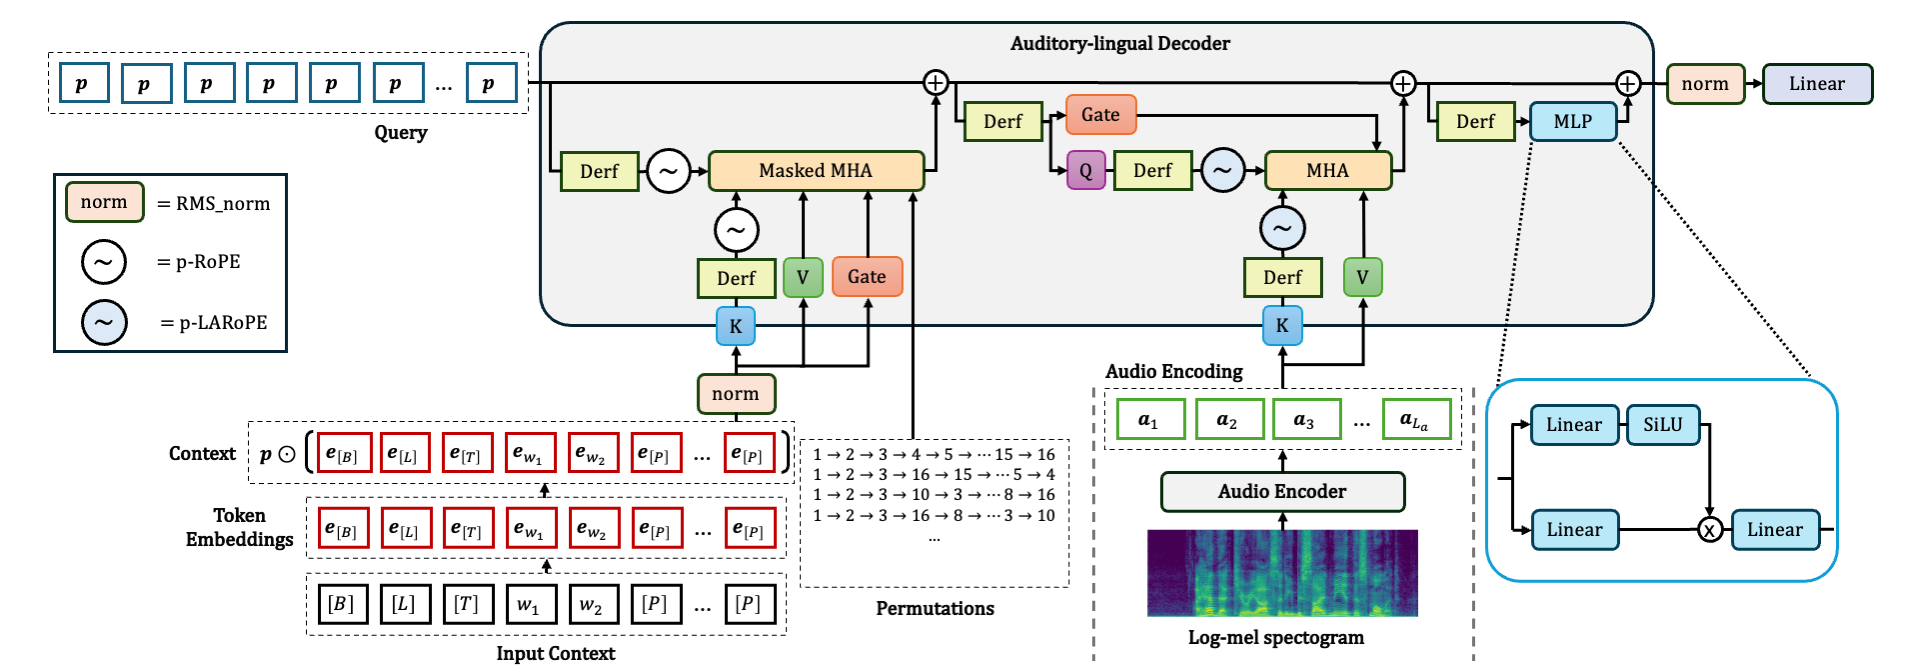
- As mentioned above, TrorYongASR2 clearly outperforms TrorYongASR1 and requires just a small increase in the number of parameters (the increase comes from additional length predictor and gate projection layers)
- Whisper has the highest number of parameters for comparable configuration (39M vs 29M for
tiny, and 244M vs 136M forsmall) - Whisper shows significantly lower word error rates on English (7.6% for
tiny, 3.4% forsmall) - TrorYongASR2 performs best on Khmer dataset (57.07% for
tiny, and 36.70% forsmall)
Note: WER data of Whisper is taken directly from their paper.
Note on Translation Task: According to KrorngAI, the 2 translation datasets above are built using the API of TranslateKH which, in turn, uses an AI model for the translation (Khmer to English and vice-versa). Without any means to check the correctness of the translation over 209 hours of audio, TrorYongASR2 is not evaluated on any translation datasets. It can be assumed that the translation performance of TrorYongASR2 is upper bounded by the AI model used in the backend of TranslateKH.
Fine-tuning
You can follow this notebook below to learn to fine-tune TrorYongASR2.

Citation
BibTeX:
@online{khun2026,
  author = {Khun, Kimang},
  title = {TrorYongASR2: {Permuted} {Language} {Modeling} with
    {Monotonic} {Alignment,} {Gated} {Attention,} and
    {Normalization-free} {Design}},
  date = {2026-10-19},
  url = {https://kimang18.github.io/krorngai-blog/TrorYongASR2/},
  langid = {en}
}
1 maintainer

Metadata
1 maintainer
Release files for tror-yong-asr 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| tror_yong_asr-0.2.1.tar.gz | 31.9 kB | Without provenance | Details for tror_yong_asr-0.2.1.tar.gz |
Release files / tror_yong_asr-0.2.1.tar.gz
| Download URL | tror_yong_asr-0.2.1.tar.gz |
|---|---|
| Size | 31.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f1f3d7aa9e9751c88fc9b6df1d6cfd07fe26f9b78b84c12b946b991eff0e87e9
|
|
BLAKE2b-256 checksum How to use checksums |
946a73a549a7ecadf1a83e39141880bc052337711b2c37902a90415d3edfce6c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.10
|
Security for tror-yong-asr 0.2.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














