
ParsBench


ParsBench provides toolkits for benchmarking Large Language Models (LLMs) based on the Persian language. It includes various tasks for evaluating LLMs on different topics, benchmarking tools to compare multiple models and rank them, and an easy, fully customizable API for developers to create custom models, tasks, scores, and benchmarks.
Key Features
- Variety of Tasks: Evaluate LLMs across various topics.
- Benchmarking Tools: Compare and rank multiple models.
- Customizable API: Create custom models, tasks, scores, and benchmarks with ease.
Evaluating your AI app (new)
Building a Persian chatbot or agent with the OpenAI SDK, OpenAI Agents SDK, LangGraph, Pydantic AI, Agno, or CrewAI? ParsBench now evaluates your app, not just models — tool-call matching across Jalali/Gregorian calendars, digit scripts and rial/toman amounts, Persian judge rubrics, a Persian user simulator, and pytest/CI integration:
from parsbench.appeval import AppEvaluator, Golden, ToolCall
evaluator = AppEvaluator(goldens=[
Golden(input="بلیط تهران-مشهد برای ۵ مهر میخوام",
tools=[ToolCall("search_flights", date="2026-09-27")],
contains=["250 هزار تومان"])])
print(evaluator.evaluate(my_bot))
See runnable examples for every major framework in examples/.
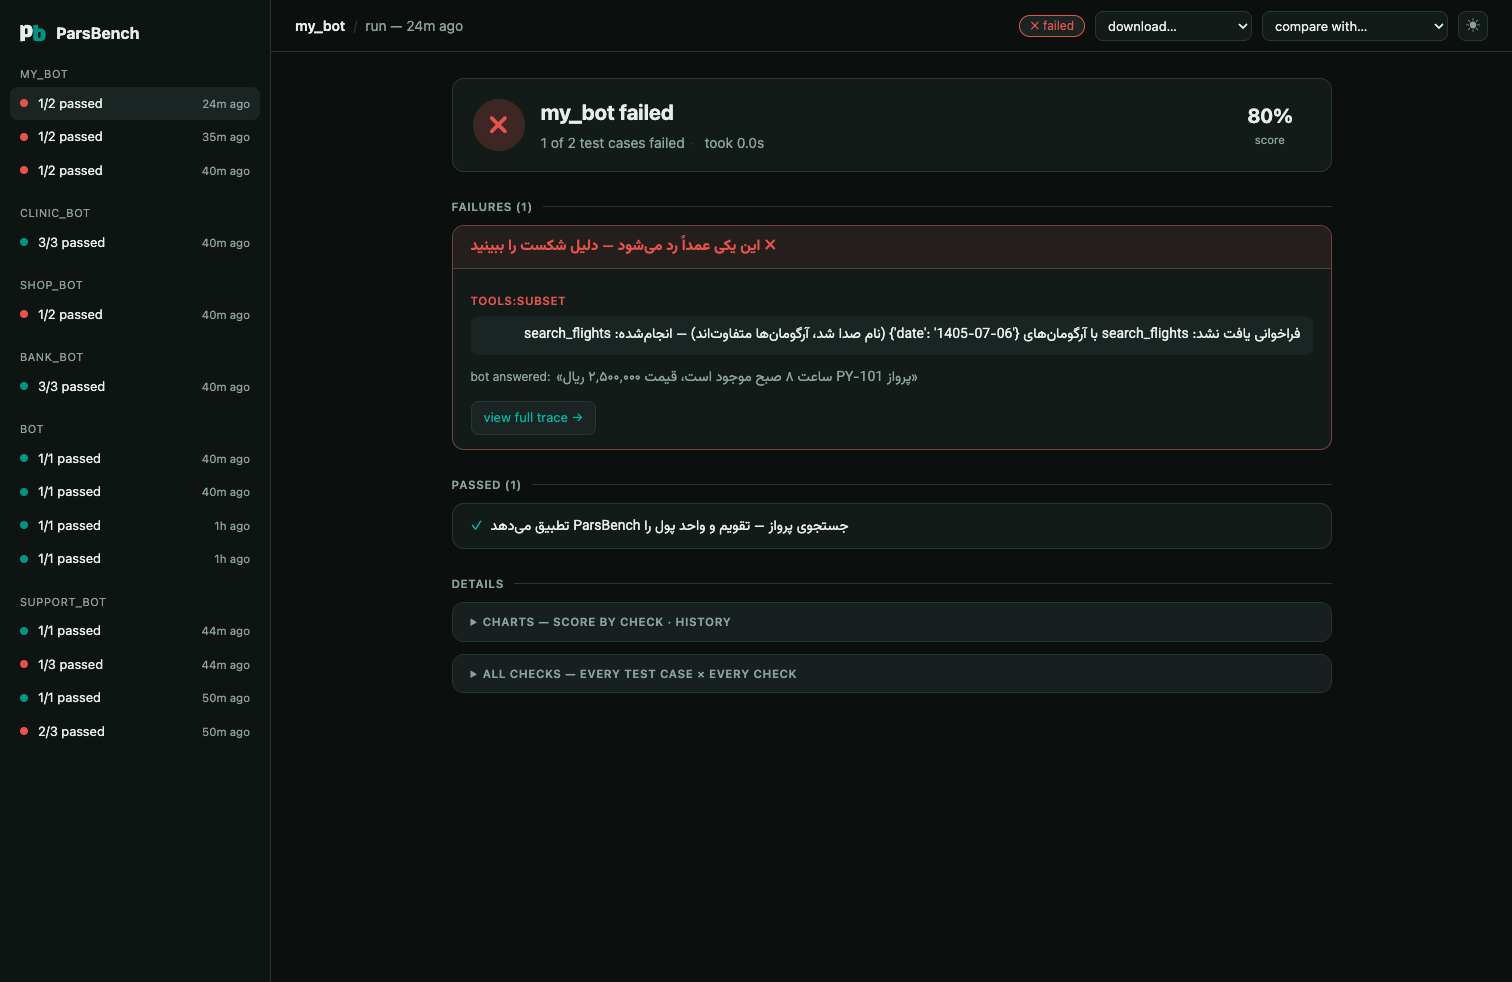
- See your runs —
parsbench viewopens a local viewer: live progress, traces, simulation replays, diffs, exports, and charts. No extra dependencies, nothing to configure.
Motivation
I was trying to fine-tune an open-source LLM for the Persian language. I needed some evaluation to test the performance and utility of my LLM. It leads me to research and find this paper. It's great work that they prepared some datasets and evaluation methods to test on ChatGPT. They even shared their code in this repository.
So, I thought that I should build a handy framework that includes various tasks and datasets for evaluating LLMs based on the Persian language. I used some parts of their work (Datasets, Metrics, Basic prompt templates) in this library.
Installation
Requires Python ≥ 3.12. ParsBench 0.2.x targets current library versions (transformers 5, datasets 5, numpy 2), which need Python 3.12+. If you're on Python 3.10/3.11, pin the previous release:
pip install "parsbench==0.1.7".
Install ParsBench using pip:
pip install parsbench
The Persian Math task additionally needs the Math Equivalence package, installed manually:
pip install git+https://github.com/hendrycks/math.git
Usage
Evaluating a PreTrained Model
Load the pre-trained model and tokenizer from the HuggingFace and then, evaluate the model using the PersianMath task:
from transformers import AutoModelForCausalLM, AutoTokenizer

from parsbench.models import PreTrainedTransformerModel
from parsbench.tasks import PersianMath

model = AutoModelForCausalLM.from_pretrained(
    "Qwen/Qwen2-72B-Instruct",
    torch_dtype="auto",
    device_map="auto"
)
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-72B-Instruct")

tf_model = PreTrainedTransformerModel(model=model, tokenizer=tokenizer)

with PersianMath() as task:
    results = task.evaluate(tf_model)
Benchmarking Multiple Models with Multiple Tasks
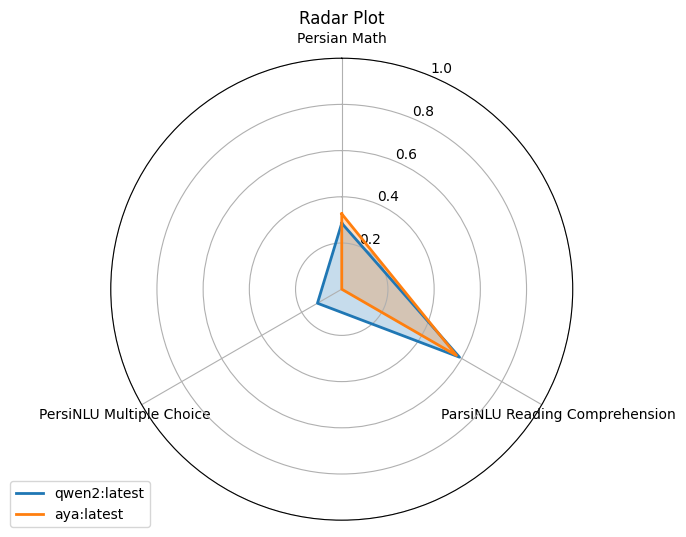
For example, we run our local models using Ollama:
ollama run qwen2
ollama run aya
Then we benchmark those models using the ParsBench.
from parsbench.benchmarks import CustomBenchmark
from parsbench.models import OpenAIModel
from parsbench.tasks import ParsiNLUMultipleChoice, PersianMath, ParsiNLUReadingComprehension

qwen2_model = OpenAIModel(
    api_base_url="http://localhost:11434/v1/",
    api_secret_key="ollama",
    model="qwen2:latest",
)
aya_model = OpenAIModel(
    api_base_url="http://localhost:11434/v1/",
    api_secret_key="ollama",
    model="aya:latest",
)

benchmark = CustomBenchmark(
    models=[qwen2_model, aya_model],
    tasks=[
        ParsiNLUMultipleChoice,
        ParsiNLUReadingComprehension,
        PersianMath,
    ],
)
result = benchmark.run(
    prompt_lang="fa",
    prompt_shots=[0, 3],
    n_first=100,
    sort_by_score=True,
)
result.show_radar_plot()
Available Tasks
| Task Name | Score Name | Dataset |
|---|---|---|
| ParsiNLU Sentiment Analysis | Exact Match (F1) | ParsiNLU |
| ParsiNLU Entailment | Exact Match (F1) | ParsiNLU |
| ParsiNLU Machine Translation En -> Fa | Bleu | ParsiNLU |
| ParsiNLU Machine Translation Fa -> En | Bleu | ParsiNLU |
| ParsiNLU Multiple Choice | Exact Match (Accuracy) | ParsiNLU |
| ParsiNLU Reading Comprehension | Common Tokens (F1) | ParsiNLU |
| Persian NER | NER Exact Match (F1) | PersianNER |
| Persian Math | Math Equivalence (Accuracy) | Source |
| ConjNLI Entailment | Exact Match (F1) | Source |
| Persian MMLU (Khayyam Challenge) | Exact Match (Accuracy) | Khayyam Challenge |
| FarsTail Entailment | Exact Match (F1) | FarsTail |
| Persian News Summary | Rouge | PNSummary |
| XL-Sum | Rouge | XLSum |
You can import the class of above tasks from parsbench.tasks and use it for evaluating your model.
Example Notebooks

Sponsors
Here are the names of companies/people who helped us to keep maintaining this project. If you want to donate this project, see this page.
- AvalAI: They gave us free OpenAI API credit several times in their "AvalAward" program. It helped us for doing R&D and benchmarking GPT models.
- Basalam: They voluntarily helped us to run the benchmarks on open-weight models and build the ParsBench Leaderboard.
Contributing
Contributions are welcome! Please refer to the contribution guidelines for more information on how to contribute.
Citation
If you use ParsBench in your research, please cite it as follows:
@software{parsbench2025,
  author = {Shahriar Shariati Motlagh},
  title = {ParsBench: A Toolkit for Benchmarking Persian Language Models},
  url = {https://github.com/ParsBench/ParsBench},
  year = {2025},
}
Or in text format:
Shariati Motlagh, S. (2025). ParsBench: A Toolkit for Benchmarking Persian Language Models. GitHub repository: https://github.com/ParsBench/ParsBench
License
ParsBench is distributed under the Apache-2.0 license.
Contact Information
For support or questions, please contact: shahriarshm81@gmail.com Feel free to let me know if there are any additional details or changes you'd like to make!
1 maintainer

Metadata
1 maintainer
Release files for parsbench 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| parsbench-0.3.0.tar.gz | 215.5 kB | Without provenance | Details for parsbench-0.3.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| parsbench-0.3.0-py3-none-any.whl | Python 3 | none | any | Details for parsbench-0.3.0-py3-none-any.whl |
Total release size: 469.5 kB
Release files / parsbench-0.3.0.tar.gz
| Download URL | parsbench-0.3.0.tar.gz |
|---|---|
| Size | 215.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ab08045e0378d30a2bfa411cae8ab6824717b278edd88d84e7632fdf66ea9ecc
|
|
BLAKE2b-256 checksum How to use checksums |
76c9cd60660ee5cec9e6b0f6a1078fdfbea12f5bf0189bea3d9cac4b3e4aeb86
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/1.6.1 CPython/3.11.4 Darwin/25.5.0
|
Release files / parsbench-0.3.0-py3-none-any.whl
| Download URL | parsbench-0.3.0-py3-none-any.whl |
|---|---|
| Size | 254.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ec6c874fe938c9c07b6d363fbbe89340473fd964c4dbf0f9057f9a531de30bed
|
|
BLAKE2b-256 checksum How to use checksums |
003bc9e4a0cda10c9b14ea378a083e1e14295cfad39332e3b75729695e83e787
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/1.6.1 CPython/3.11.4 Darwin/25.5.0
|
Security for parsbench 0.3.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














