


PDF scientific paper translation and bilingual comparison library.
- Online Service: Beta version launched Immersive Translate - BabelDOC Free usage quota is available; please refer to the FAQ section on the page for details.
- Self-deployment: PDFMathTranslate-next support for BabelDOC, available for self-deployment + WebUI with more translation services.
- Provides a simple command line interface.
- Provides a Python API.
- Mainly designed to be embedded into other programs, but can also be used directly for simple translation tasks.
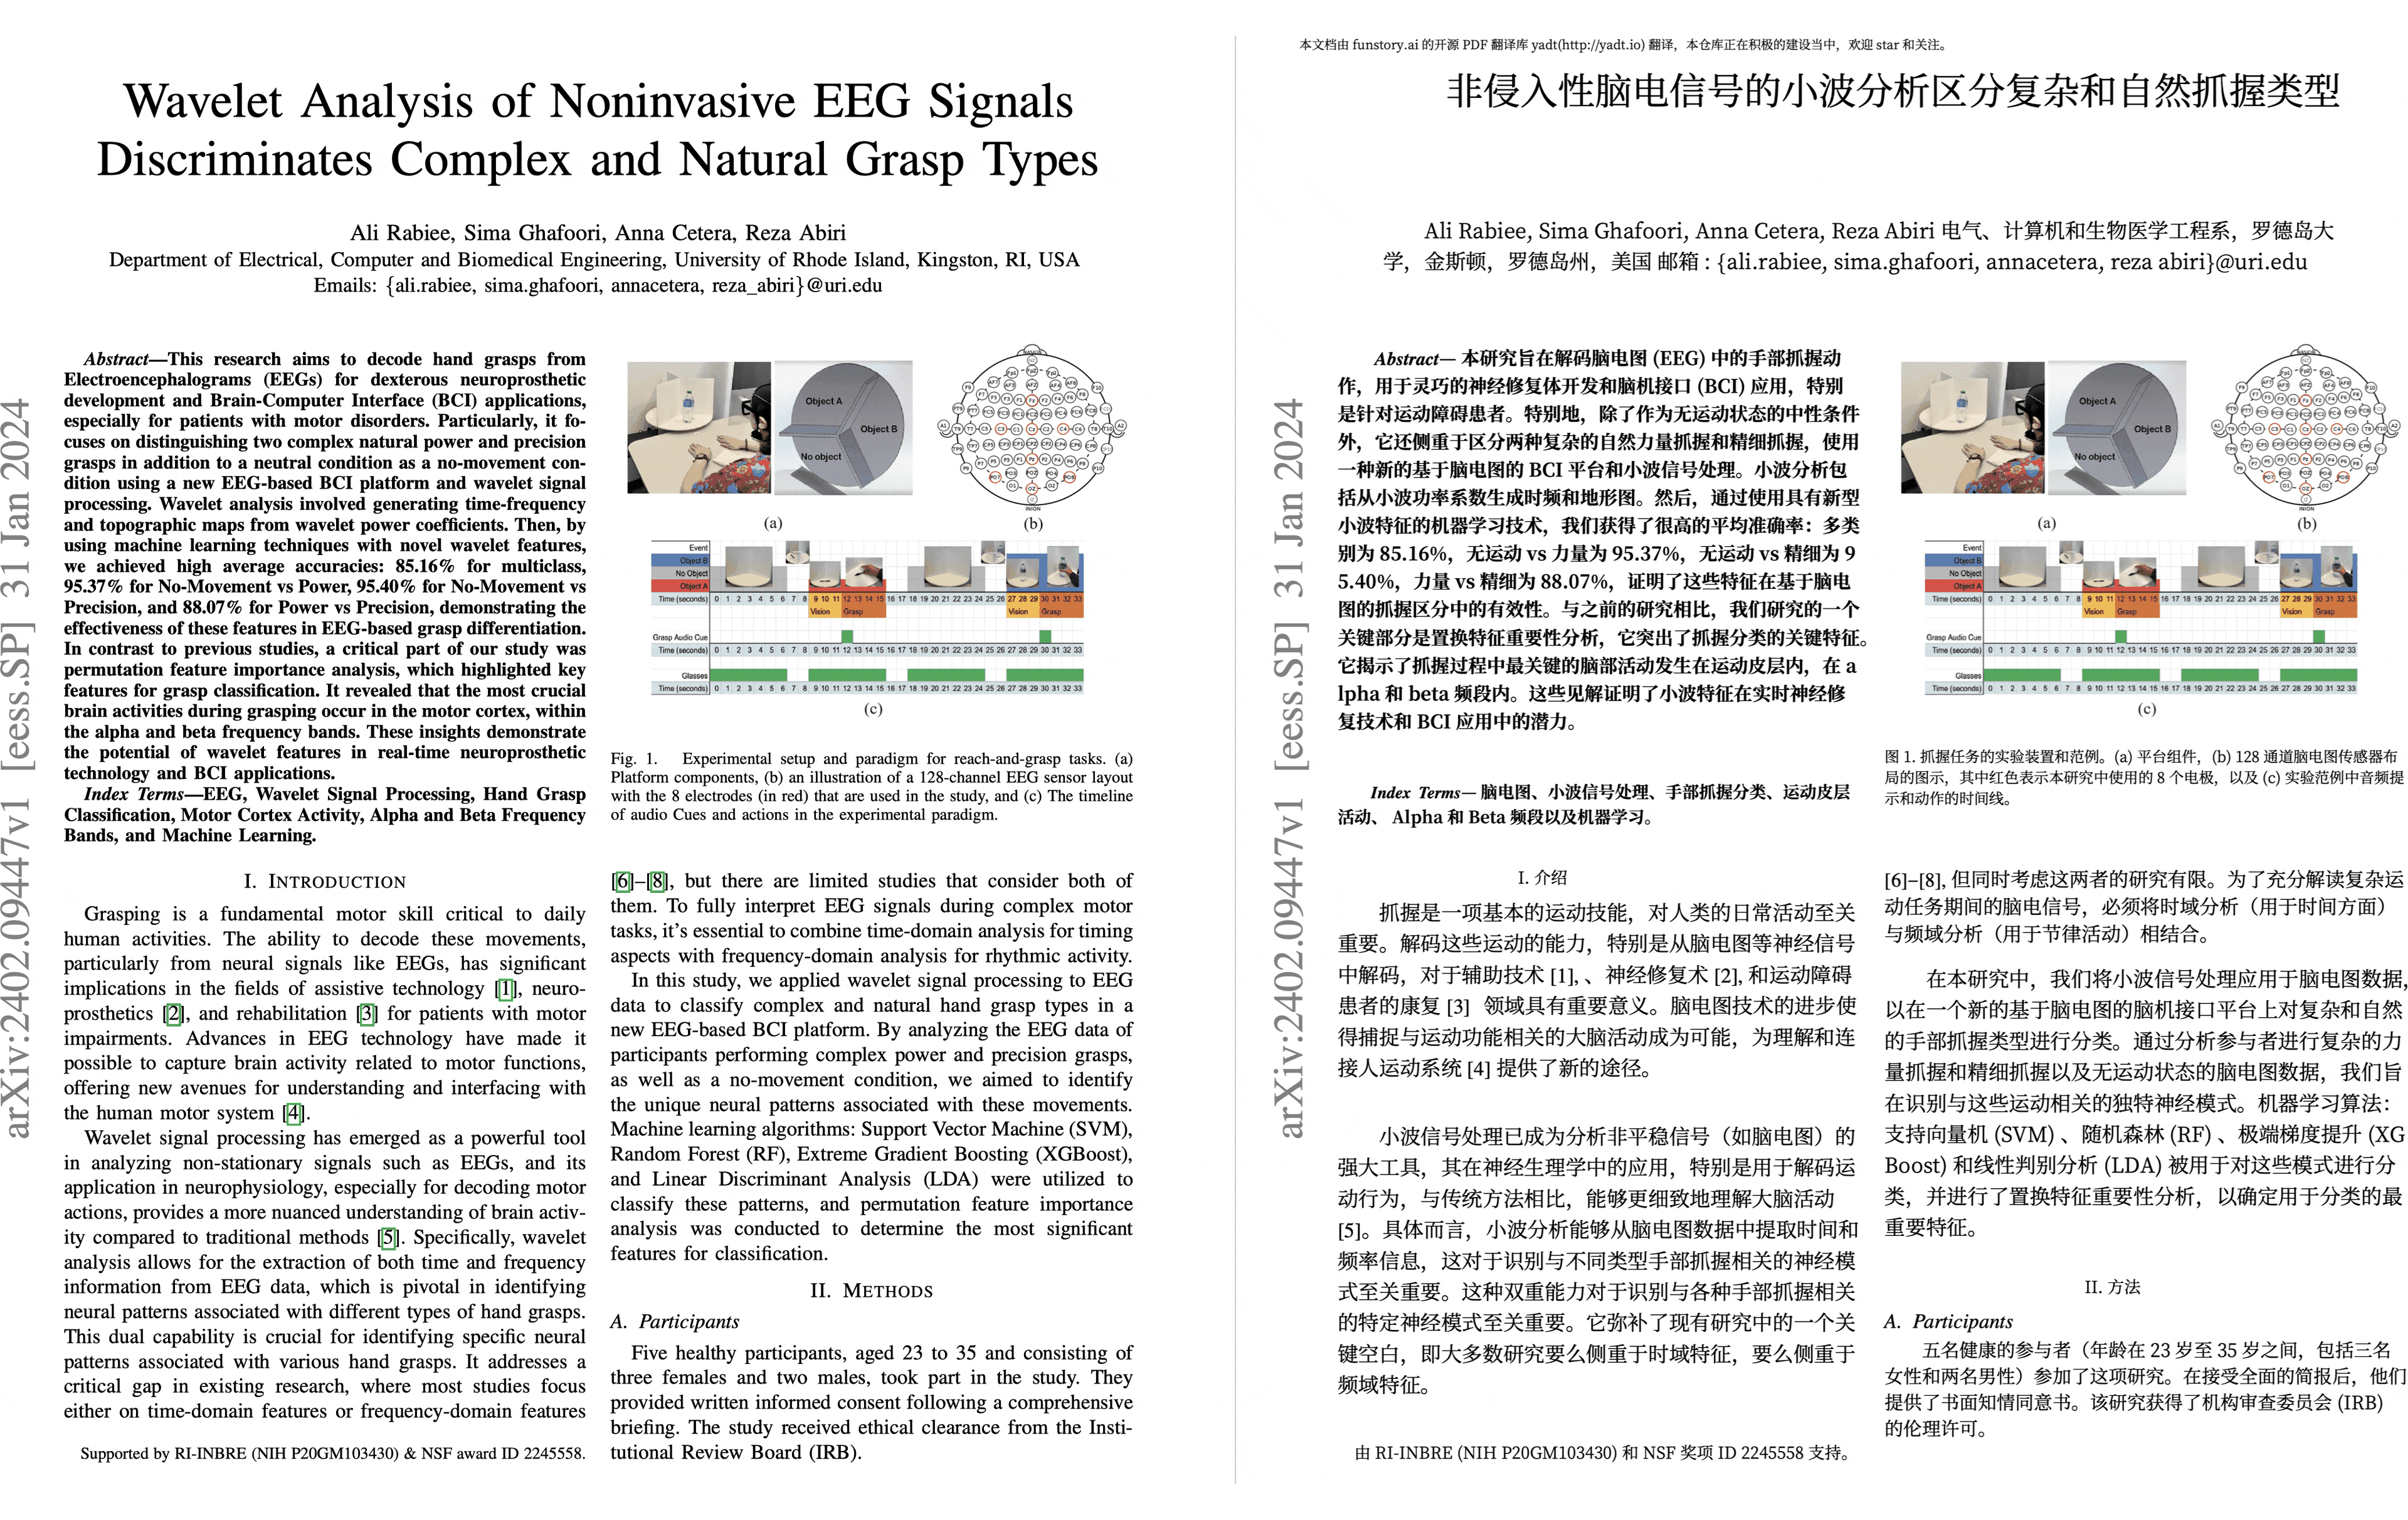
Preview
We are hiring
Getting Started
Install from PyPI
We recommend using the Tool feature of uv to install BabelDOC.
-
First, you need to refer to uv installation to install uv and set up the
PATHenvironment variable as prompted. -
Use the following command to install BabelDOC:
uv tool install --python 3.12 BabelDOC

babeldoc --help
- Use the
babeldoccommand. For example:
babeldoc --openai --openai-model "gpt-4o-mini" --openai-base-url "https://api.openai.com/v1" --openai-api-key "your-api-key-here"  --files example.pdf

# multiple files
babeldoc --openai --openai-model "gpt-4o-mini" --openai-base-url "https://api.openai.com/v1" --openai-api-key "your-api-key-here"  --files example1.pdf --files example2.pdf
Install from Source
We still recommend using uv to manage virtual environments.
-
First, you need to refer to uv installation to install uv and set up the
PATHenvironment variable as prompted. -
Use the following command to install BabelDOC:
# clone the project
git clone https://github.com/funstory-ai/BabelDOC

# enter the project directory
cd BabelDOC

# install dependencies and run babeldoc
uv run babeldoc --help
- Use the
uv run babeldoccommand. For example:
uv run babeldoc --files example.pdf --openai --openai-model "gpt-4o-mini" --openai-base-url "https://api.openai.com/v1" --openai-api-key "your-api-key-here"

# multiple files
uv run babeldoc --files example.pdf --files example2.pdf --openai --openai-model "gpt-4o-mini" --openai-base-url "https://api.openai.com/v1" --openai-api-key "your-api-key-here"
Advanced Options
Language Options
--lang-in,-li: Source language code (default: en)--lang-out,-lo: Target language code (default: zh)
PDF Processing Options
-
--files: One or more file paths to input PDF documents. -
--pages,-p: Specify pages to translate (e.g., "1,2,1-,-3,3-5"). If not set, translate all pages -
--split-short-lines: Force split short lines into different paragraphs (may cause poor typesetting & bugs) -
--short-line-split-factor: Split threshold factor (default: 0.8). The actual threshold is the median length of all lines on the current page * this factor -
--skip-clean: Skip PDF cleaning step -
--dual-translate-first: Put translated pages first in dual PDF mode (default: original pages first) -
--disable-rich-text-translate: Disable rich text translation (may help improve compatibility with some PDFs) -
--enhance-compatibility: Enable all compatibility enhancement options (equivalent to --skip-clean --dual-translate-first --disable-rich-text-translate) -
--use-alternating-pages-dual: Use alternating pages mode for dual PDF. When enabled, original and translated pages are arranged in alternate order. When disabled (default), original and translated pages are shown side by side on the same page. -
--watermark-output-mode: [DEPRECATED] Watermarks are no longer added; this option still controls output file names and count. -
--max-pages-per-part: Maximum number of pages per part for split translation. If not set, no splitting will be performed. -
--no-watermark: [DEPRECATED] Watermarks are no longer added; this option still affects output file names and count. -
--translate-table-text: Translate table text (experimental, default: False) -
--formular-font-pattern: Font pattern to identify formula text (default: None) -
--formular-char-pattern: Character pattern to identify formula text (default: None) -
--show-char-box: Show character bounding boxes (debug only, default: False) -
--skip-scanned-detection: Skip scanned document detection (default: False). When using split translation, only the first part performs detection if not skipped. -
--ocr-workaround: Use OCR workaround (default: False). Only suitable for documents with black text on white background. When enabled, white rectangular blocks will be added below the translation to cover the original text content, and all text will be forced to black color. -
--auto-enable-ocr-workaround: Enable automatic OCR workaround (default: False). If a document is detected as heavily scanned, this will attempt to enable OCR processing and skip further scan detection. See "Important Interaction Note" below for crucial details on how this interacts with--ocr-workaroundand--skip-scanned-detection. -
--primary-font-family: Override primary font family for translated text. Choices: 'serif' for serif fonts, 'sans-serif' for sans-serif fonts, 'script' for script/italic fonts. If not specified, uses automatic font selection based on original text properties. -
--only-include-translated-page: Only include translated pages in the output PDF. This option is only effective when--pagesis used. (default: False) -
--merge-alternating-line-numbers: Enable post-processing to merge alternating line-number layouts (keep the number paragraph as an independent paragraph b; merge adjacent text paragraphs a and c across it whenlayout_idandxobj_idmatch, digits are ASCII and spaces only). Default: off. -
--skip-form-render: Skip form rendering (default: False). When enabled, PDF forms will not be rendered in the output. -
--skip-curve-render: Skip curve rendering (default: False). When enabled, PDF curves will not be rendered in the output. -
--only-parse-generate-pdf: Only parse PDF and generate output PDF without translation (default: False). This skips all translation-related processing including layout analysis, paragraph finding, style processing, and translation itself. Useful for testing PDF parsing and reconstruction functionality. -
--remove-non-formula-lines: Remove non-formula lines from paragraph areas (default: False). This removes decorative lines that are not part of formulas, while protecting lines in figure/table areas. Useful for cleaning up documents with decorative elements that interfere with text flow. -
--non-formula-line-iou-threshold: IoU threshold for detecting paragraph overlap when removing non-formula lines (default: 0.9). Higher values are more conservative and will remove fewer lines. -
--figure-table-protection-threshold: IoU threshold for protecting lines in figure/table areas when removing non-formula lines (default: 0.9). Higher values provide more protection for structural elements in figures and tables. -
--rpc-doclayout: RPC service host address for document layout analysis (default: None) -
--working-dir: Working directory for translation. If not set, use temp directory. -
--no-auto-extract-glossary: Disable automatic term extraction. If this flag is present, the step is skipped. Defaults to enabled. -
--save-auto-extracted-glossary: Save automatically extracted glossary to the specified file. If not set, the glossary will not be saved.
Translation Service Options
--qps: QPS (Queries Per Second) limit for translation service (default: 4)--ignore-cache: Ignore translation cache and force retranslation--no-dual: Do not output bilingual PDF files--no-mono: Do not output monolingual PDF files--min-text-length: Minimum text length to translate (default: 5)--openai: Use OpenAI for translation (default: False)--custom-system-prompt: Custom system prompt for translation.--add-formula-placehold-hint: Add formula placeholder hint for translation. (Currently not recommended, it may affect translation quality, default: False)--disable-same-text-fallback: Disable fallback translation when LLM output matches input text. (default: False)--pool-max-workers: Maximum number of worker threads for internal task processing pools. If not specified, defaults to QPS value. This parameter directly sets the worker count, replacing previous QPS-based dynamic calculations.--no-auto-extract-glossary: Disable automatic term extraction. If this flag is present, the step is skipped. Defaults to enabled.
OpenAI Specific Options
--openai-model: OpenAI model to use (default: gpt-4o-mini)--openai-base-url: Base URL for OpenAI API--openai-api-key: API key for OpenAI service--enable-json-mode-if-requested: Enable JSON mode for OpenAI requests (default: False)--term-pool-max-workers: Maximum number of worker threads dedicated to automatic term extraction. If not specified, this defaults to the value of--pool-max-workers, which itself defaults to the QPS value when unset.
Glossary Options
--glossary-files: Comma-separated paths to glossary CSV files.- Each CSV file should have the columns:
source,target, and an optionaltgt_lng. - The
sourcecolumn contains the term in the original language. - The
targetcolumn contains the term in the target language. - The
tgt_lngcolumn (optional) specifies the target language for that specific entry (e.g., "zh-CN", "en-US").- If
tgt_lngis provided for an entry, that entry will only be loaded and used if its (normalized)tgt_lngmatches the (normalized) overall target language specified by--lang-out. Normalization involves lowercasing and replacing hyphens (-) with underscores (_). - If
tgt_lngis omitted for an entry, that entry is considered applicable for any--lang-out.
- If
- The name of each glossary (used in LLM prompts) is derived from its filename (without the .csv extension).
- During translation, the system will check the input text against the loaded glossaries. If terms from a glossary are found in the current text segment, that glossary (with the relevant terms) will be included in the prompt to the language model, along with an instruction to adhere to it.
- Each CSV file should have the columns:
Output Control
--output,-o: Output directory for translated files. If not set, use current working directory.--debug: Enable debug logging level and export detailed intermediate results in~/.cache/babeldoc/working.--report-interval: Progress report interval in seconds (default: 0.1).
General Options
--warmup: Only download and verify required assets then exit (default: False)
Offline Assets Management
--generate-offline-assets: Generate an offline assets package in the specified directory. This creates a zip file containing all required models and fonts.--restore-offline-assets: Restore an offline assets package from the specified file. This extracts models and fonts from a previously generated package.
Configuration File
--config,-c: Configuration file path. Use the TOML format.
Example Configuration:
[babeldoc]
# Basic settings
debug = true
lang-in = "en-US"
lang-out = "zh-CN"
qps = 10
output = "/path/to/output/dir"

# PDF processing options
split-short-lines = false
short-line-split-factor = 0.8
skip-clean = false
dual-translate-first = false
disable-rich-text-translate = false
use-alternating-pages-dual = false
watermark-output-mode = "watermarked"  # DEPRECATED: No watermark is added; this still controls output file names and count.
max-pages-per-part = 50  # Automatically split the document for translation and merge it back.
only_include_translated_page = false # Only include translated pages in the output PDF. Effective only when `pages` is used.
# no-watermark = false  # DEPRECATED: No watermark is added; this still affects output file names and count.
skip-scanned-detection = false  # Skip scanned document detection for faster processing
auto_extract_glossary = true # Set to false to disable automatic term extraction
formular_font_pattern = "" # Font pattern for formula text
formular_char_pattern = "" # Character pattern for formula text
show_char_box = false # Show character bounding boxes (debug)
ocr_workaround = false # Use OCR workaround for scanned PDFs
rpc_doclayout = "" # RPC service host for document layout analysis
working_dir = "" # Working directory for translation
auto_enable_ocr_workaround = false # Enable automatic OCR workaround for scanned PDFs. See docs for interaction with ocr_workaround and skip_scanned_detection.
skip_form_render = false # Skip form rendering (default: False)
skip_curve_render = false # Skip curve rendering (default: False)
only_parse_generate_pdf = false # Only parse PDF and generate output PDF without translation (default: False)
remove_non_formula_lines = false # Remove non-formula lines from paragraph areas (default: False)
non_formula_line_iou_threshold = 0.2 # IoU threshold for paragraph overlap detection (default: 0.2)
figure_table_protection_threshold = 0.3 # IoU threshold for figure/table protection (default: 0.3)

# Translation service
openai = true
openai-model = "gpt-4o-mini"
openai-base-url = "https://api.openai.com/v1"
openai-api-key = "your-api-key-here"
enable-json-mode-if-requested = false  # Enable JSON mode when requested (default: false)
disable_same_text_fallback = false # Disable fallback translation when LLM output matches input text (default: false)
pool-max-workers = 8  # Maximum worker threads for task processing (defaults to QPS value if not set)

# Glossary Options (Optional)
# glossary-files = "/path/to/glossary1.csv,/path/to/glossary2.csv"

# Output control
no-dual = false
no-mono = false
min-text-length = 5
report-interval = 0.5

# Offline assets management
# Uncomment one of these options as needed:
# generate-offline-assets = "/path/to/output/dir"
# restore-offline-assets = "/path/to/offline_assets_package.zip"
Python API
The current recommended way to call BabelDOC in Python is to call the high_level.do_translate_async_stream function of pdf2zh next.
Background
There are a lot projects and teams working on to make document editing and translating easier like:
There are also some solutions to solve specific parts of the problem like:
- layoutreader: the read order of the text block in a pdf
- Surya: the structure of the pdf
This project hopes to promote a standard pipeline and interface to solve the problem.
In fact, there are two main stages of a PDF parser or translator:
- Parsing: A stage of parsing means to get the structure of the pdf such as text blocks, images, tables, etc.
- Rendering: A stage of rendering means to render the structure into a new pdf or other format.
For a service like mathpix, it will parse the pdf into a structure may be in a XML format, and then render them using a single column reader order as layoutreader does. The bad news is that the original structure lost.
Some people will use Adobe PDF Parser because it will generate a Word document and it keeps the original structure. But it is somewhat expensive. And you know, a pdf or word document is not a good format for reading in mobile devices.
We offer an intermediate representation of the results from parser and can be rendered into a new pdf or other format. The pipeline is also a plugin-based system which everybody can add their new model, ocr, renderer, etc.
Roadmap
- Add line support
- Add table support
- Add cross-page/cross-column paragraph support
- More advanced typesetting features
- Outline support
- ...
Our first 1.0 version goal is to finish a translation from PDF Reference, Version 1.7 to the following language version:
- Simplified Chinese
- Traditional Chinese
- Japanese
- Spanish
And meet the following requirements:
- layout error less than 1%
- content loss less than 1%
Version Number Explanation
This project uses a combination of Semantic Versioning and Pride Versioning. The version number format is: "0.MAJOR.MINOR".
-
MAJOR: Incremented by 1 when API incompatible changes are made or when proud improvements are implemented.
-
MINOR: Incremented by 1 when any API compatible changes are made.
Known Issues
- Parsing errors in the author and reference sections; they get merged into one paragraph after translation.
- Lines are not supported.
- Does not support drop caps.
- Large pages will be skipped.
How to Contribute
BabelDOC is currently developed in a maintainer-led mode. Bug reports, reproducible PDFs, documentation fixes, and small compatibility fixes are welcome. For changes to parsing, rendering, translation, or service integration behavior, please open an issue for discussion before submitting a pull request.
Everyone interacting in BabelDOC and its sub-projects' codebases, issue trackers, chat rooms, and mailing lists is expected to follow the BabelDOC Code of Conduct.
Immersive Translation sponsors monthly Pro membership redemption codes for active contributors to this project, see details at: CONTRIBUTOR_REWARD.md
Acknowledgements
BabelDOC is still at an early stage of development, and many parts are not as polished as we would like yet. We sincerely appreciate every bug report, criticism, suggestion, reproducible PDF, downstream integration experience, and contribution from people working on BabelDOC and related upstream/downstream projects. We will keep iterating on BabelDOC, fixing bugs, and making it better step by step.
Star History

1 maintainer

Metadata
1 maintainer
Release files for BabelDOC 0.7.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| babeldoc-0.7.1.tar.gz | 13.8 MB | With provenance | Details for babeldoc-0.7.1.tar.gz |
Built distributions (wheels)
| File | Actions Reset | |||
|---|---|---|---|---|
| babeldoc-0.7.1-cp310-abi3-win_amd64.whl | CPython 3.10 | abi3 | Windows x86-64 | Details for babeldoc-0.7.1-cp310-abi3-win_amd64.whl |
| babeldoc-0.7.1-cp310-abi3-manylinux_2_28_x86_64.whl | CPython 3.10 | abi3 | Linux glibc 2.28+ x86-64 | Details for babeldoc-0.7.1-cp310-abi3-manylinux_2_28_x86_64.whl |
| babeldoc-0.7.1-cp310-abi3-manylinux_2_28_aarch64.whl | CPython 3.10 | abi3 | Linux glibc 2.28+ ARM64 | Details for babeldoc-0.7.1-cp310-abi3-manylinux_2_28_aarch64.whl |
| babeldoc-0.7.1-cp310-abi3-macosx_11_0_arm64.whl | CPython 3.10 | abi3 | macOS 11.0+ ARM64 | Details for babeldoc-0.7.1-cp310-abi3-macosx_11_0_arm64.whl |
| babeldoc-0.7.1-cp310-abi3-macosx_10_12_x86_64.whl | CPython 3.10 | abi3 | macOS 10.12+ x86-64 | Details for babeldoc-0.7.1-cp310-abi3-macosx_10_12_x86_64.whl |
Total release size: 72.7 MB
Release files / babeldoc-0.7.1.tar.gz
| Download URL | babeldoc-0.7.1.tar.gz |
|---|---|
| Size | 13.8 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
05a27d19e0b02e6afb4ca2946fa6fe7b431658d534628de33afd10d93d888b34
|
|
BLAKE2b-256 checksum How to use checksums |
9c47e8f94cbc6703b801f4c43d33322e2fff81ac11f00427f5169d8a6f136a49
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 7, 2026.
Transparency logRelease files / babeldoc-0.7.1-cp310-abi3-win_amd64.whl
| Download URL | babeldoc-0.7.1-cp310-abi3-win_amd64.whl |
|---|---|
| Size | 11.5 MB |
| Tags | CPython 3.10 Windows x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
ed0fff589afde6751fa2c25077bd59676fbebb5c285af5f552f3f2ac747dcff9
|
|
BLAKE2b-256 checksum How to use checksums |
bb6f703d97a7d99fd8ead98a7242fffb0dfe28816ac5d458c04446475d42690d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 7, 2026.
Transparency logRelease files / babeldoc-0.7.1-cp310-abi3-manylinux_2_28_x86_64.whl
| Download URL | babeldoc-0.7.1-cp310-abi3-manylinux_2_28_x86_64.whl |
|---|---|
| Size | 12.1 MB |
| Tags | CPython 3.10 Linux glibc 2.28+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
8ffe2efe4d6e2f4a38cd400e41dd9839664b7932aade95275defcf0d023cdbb4
|
|
BLAKE2b-256 checksum How to use checksums |
9141139e3e8500701df81700441bbb09de2a205e74eaa2402c9e53727ba8ac9c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 7, 2026.
Transparency logRelease files / babeldoc-0.7.1-cp310-abi3-manylinux_2_28_aarch64.whl
| Download URL | babeldoc-0.7.1-cp310-abi3-manylinux_2_28_aarch64.whl |
|---|---|
| Size | 12.0 MB |
| Tags | CPython 3.10 Linux glibc 2.28+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
03f56873873494d96bea9154eeeb457238e45c1404421eb1dcea5b630afbb290
|
|
BLAKE2b-256 checksum How to use checksums |
109a46a9601c87ee08ecf47bd480489400d56a904452deb6d1a46124b4329834
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 7, 2026.
Transparency logRelease files / babeldoc-0.7.1-cp310-abi3-macosx_11_0_arm64.whl
| Download URL | babeldoc-0.7.1-cp310-abi3-macosx_11_0_arm64.whl |
|---|---|
| Size | 11.5 MB |
| Tags | CPython 3.10 abi3 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
55d9b630e60f61704a7c032ab05a7f8a181e45f6ca2e2f5590b0071d2d11bfc9
|
|
BLAKE2b-256 checksum How to use checksums |
70226da7b20ed1682566345633dab572b09a4b8fc6110cbb6c304ee0acb9c14f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 7, 2026.
Transparency logRelease files / babeldoc-0.7.1-cp310-abi3-macosx_10_12_x86_64.whl
| Download URL | babeldoc-0.7.1-cp310-abi3-macosx_10_12_x86_64.whl |
|---|---|
| Size | 11.8 MB |
| Tags | CPython 3.10 abi3 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
76ebe8f9da7ac638b61226d0f6edae22bc7e1565bfe3e40fb9b4f28b44280a7c
|
|
BLAKE2b-256 checksum How to use checksums |
e95adb17b130574379036a4c2c5a05c10c79e8d1f4f0c438d6b2e70c4680482a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 7, 2026.
Transparency logSecurity for BabelDOC 0.7.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 6 files in this release have been uploaded with provenance metadata.
Attestation for babeldoc-0.7.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 7, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














