
OpenPyTEA is an open-source Python toolkit for performing techno-economic assessment (TEA) of chemical and energy systems. It was created to address a persistent gap in the TEA workflow: while process simulators model mass and energy balances, researchers often lack an equally transparent and flexible way to evaluate the economic feasibility of their designs. Commercial tools remain black-box tools, and many academic TEA implementations are process-specific, undocumented, or difficult to reproduce.
OpenPyTEA provides a fully open, modular, and traceable framework that brings TEA into the Python ecosystem. By integrating equipment cost estimation, capital and operating expenditure modeling, cash-flow analysis, cost breakdowns, sensitivity evaluation, and Monte Carlo uncertainty propagation, the toolkit enables users to perform end-to-end TEA with clarity and reproducibility.
Beyond its functionality, OpenPyTEA is designed as a community-driven TEA platform. Users can contribute new equipment cost correlations, improve economic models, report issues, and expand the toolkit’s capabilities over time. This collaborative approach helps build a shared, transparent, and continually improving TEA resource—similar to the open-source progress seen in the LCA community.
Whether used for early-stage process design, technology screening, or teaching, OpenPyTEA makes TEA more accessible, consistent, and aligned with FAIR research principles (Findable, Accessible, Interoperable, and Reusable).
For a full walkthrough of the features and usage of OpenPyTEA, refer to the walkthrough.ipynb notebook:
https://github.com/pbtamarona/OpenPyTEA/blob/main/walkthrough.ipynb
For the full documentation of the package, visit the ReadTheDocs page:
https://openpytea.readthedocs.io
For some case-study examples, please check the examples folder:
https://github.com/pbtamarona/OpenPyTEA/tree/main/examples
🎓 Workshop
We are hosting a one-day workshop on open-science techno-economic assessment using OpenPyTEA!
Open-Science Techno-Economic Assessment with OpenPyTEA: From Process Design to Economic Insights
The workshop covers the full workflow from process design and simulation to economic evaluation, combining lectures, a hands-on session with OpenPyTEA, and an industry talk by Shell. It closes with a community discussion on establishing shared TEA standards, bringing together students, researchers, engineers, and policymakers across chemical, energy, and sustainability sciences.
- 📅 Date: November 6, 2026 | 09:30 – 18:00
- 📍 Location: Process & Energy, TU Delft, Delft, The Netherlands
- 📝 Registration: aanmelder.nl/openpytea2026
- ⏰ Deadline: $${\color{red}\textbf{Registration closes on October 15, 2026}}$$
Lunch, snacks, coffee, and drinks will be provided!
✨ Key Features
- Modular architecture: clean separation of cost correlations, equipment objects, plant economics, and uncertainty analysis.
- Transparent and reproducible: all algorithms, equations, and assumptions are openly available for full traceability.
- Cost breakdown visualization: built-in functions to plot stacked bar charts of equipment costs, fixed capital, operating costs, and levelized cost of production (LCOP).
- Cash flow diagrams: visualize a project's cumulative cash flow over time, including its maximum investment and pay-back point, with support for overlaying multiple plants.
- Built-in uncertainty tools: automatic generation of sensitivity plots and Monte Carlo simulations, covering process quantities (consumption and production rates) as well as prices and financial assumptions.
- Parameter dependencies: declare how quantities depend on one another — cooling water scaling with production, a byproduct's yield tracking the main product, capital cost scaling with capacity — and every analysis honours the same graph.
- Workflow using JSON configuration files: standardized input/output structure via
io.pyfor reproducible analyses and multi-scenario evaluation. - Flexible analysis and visualization: separation of data processing (
analysis.py) and plotting (plotting.py) allows users to apply custom visualization tools. - Interoperable and extensible: easy integration with process simulators, optimization frameworks, and LCA tools.
- Education-friendly: ideal for teaching TEA and process design without reliance on proprietary software.
- Community-driven: users can contribute new correlations, improve models, request features, and shape the evolution of the platform.
📦 Installation
1. Install from PyPI (recommended)
pip install openpytea
2. Install from GitHub (development version)
pip install git+https://github.com/pbtamarona/OpenPyTEA
or with uv:
uv add git+https://github.com/pbtamarona/OpenPyTEA
OpenPyTEA requires Python ≥ 3.10.
The main dependencies include:
matplotlibnumpypandasscienceplotsscipytqdmjinja2
⚙️ Package (Repository) Structure
src/openpytea/
├── equipment.py            # Equipment-level costing and inflation correction
├── plant.py                # Plant-level TEA: CAPEX, OPEX, cash flows, financial metrics
├── analysis.py             # Sensitivity and uncertainty analysis (sensitivity plots, Monte Carlo)
├── plotting.py             # Visualization functions (plots and figures)
├── io.py                   # JSON-based workflow: load inputs and export results
├── helpers.py              # Helper functions for data handling and common operations
└── data/                   # Cost correlations database and CEPCI data
examples/                   # Example notebooks and case studies
walkthrough.ipynb           # Walkthrough of the package
pyproject.toml
README.md
🏗️ Software Architecture
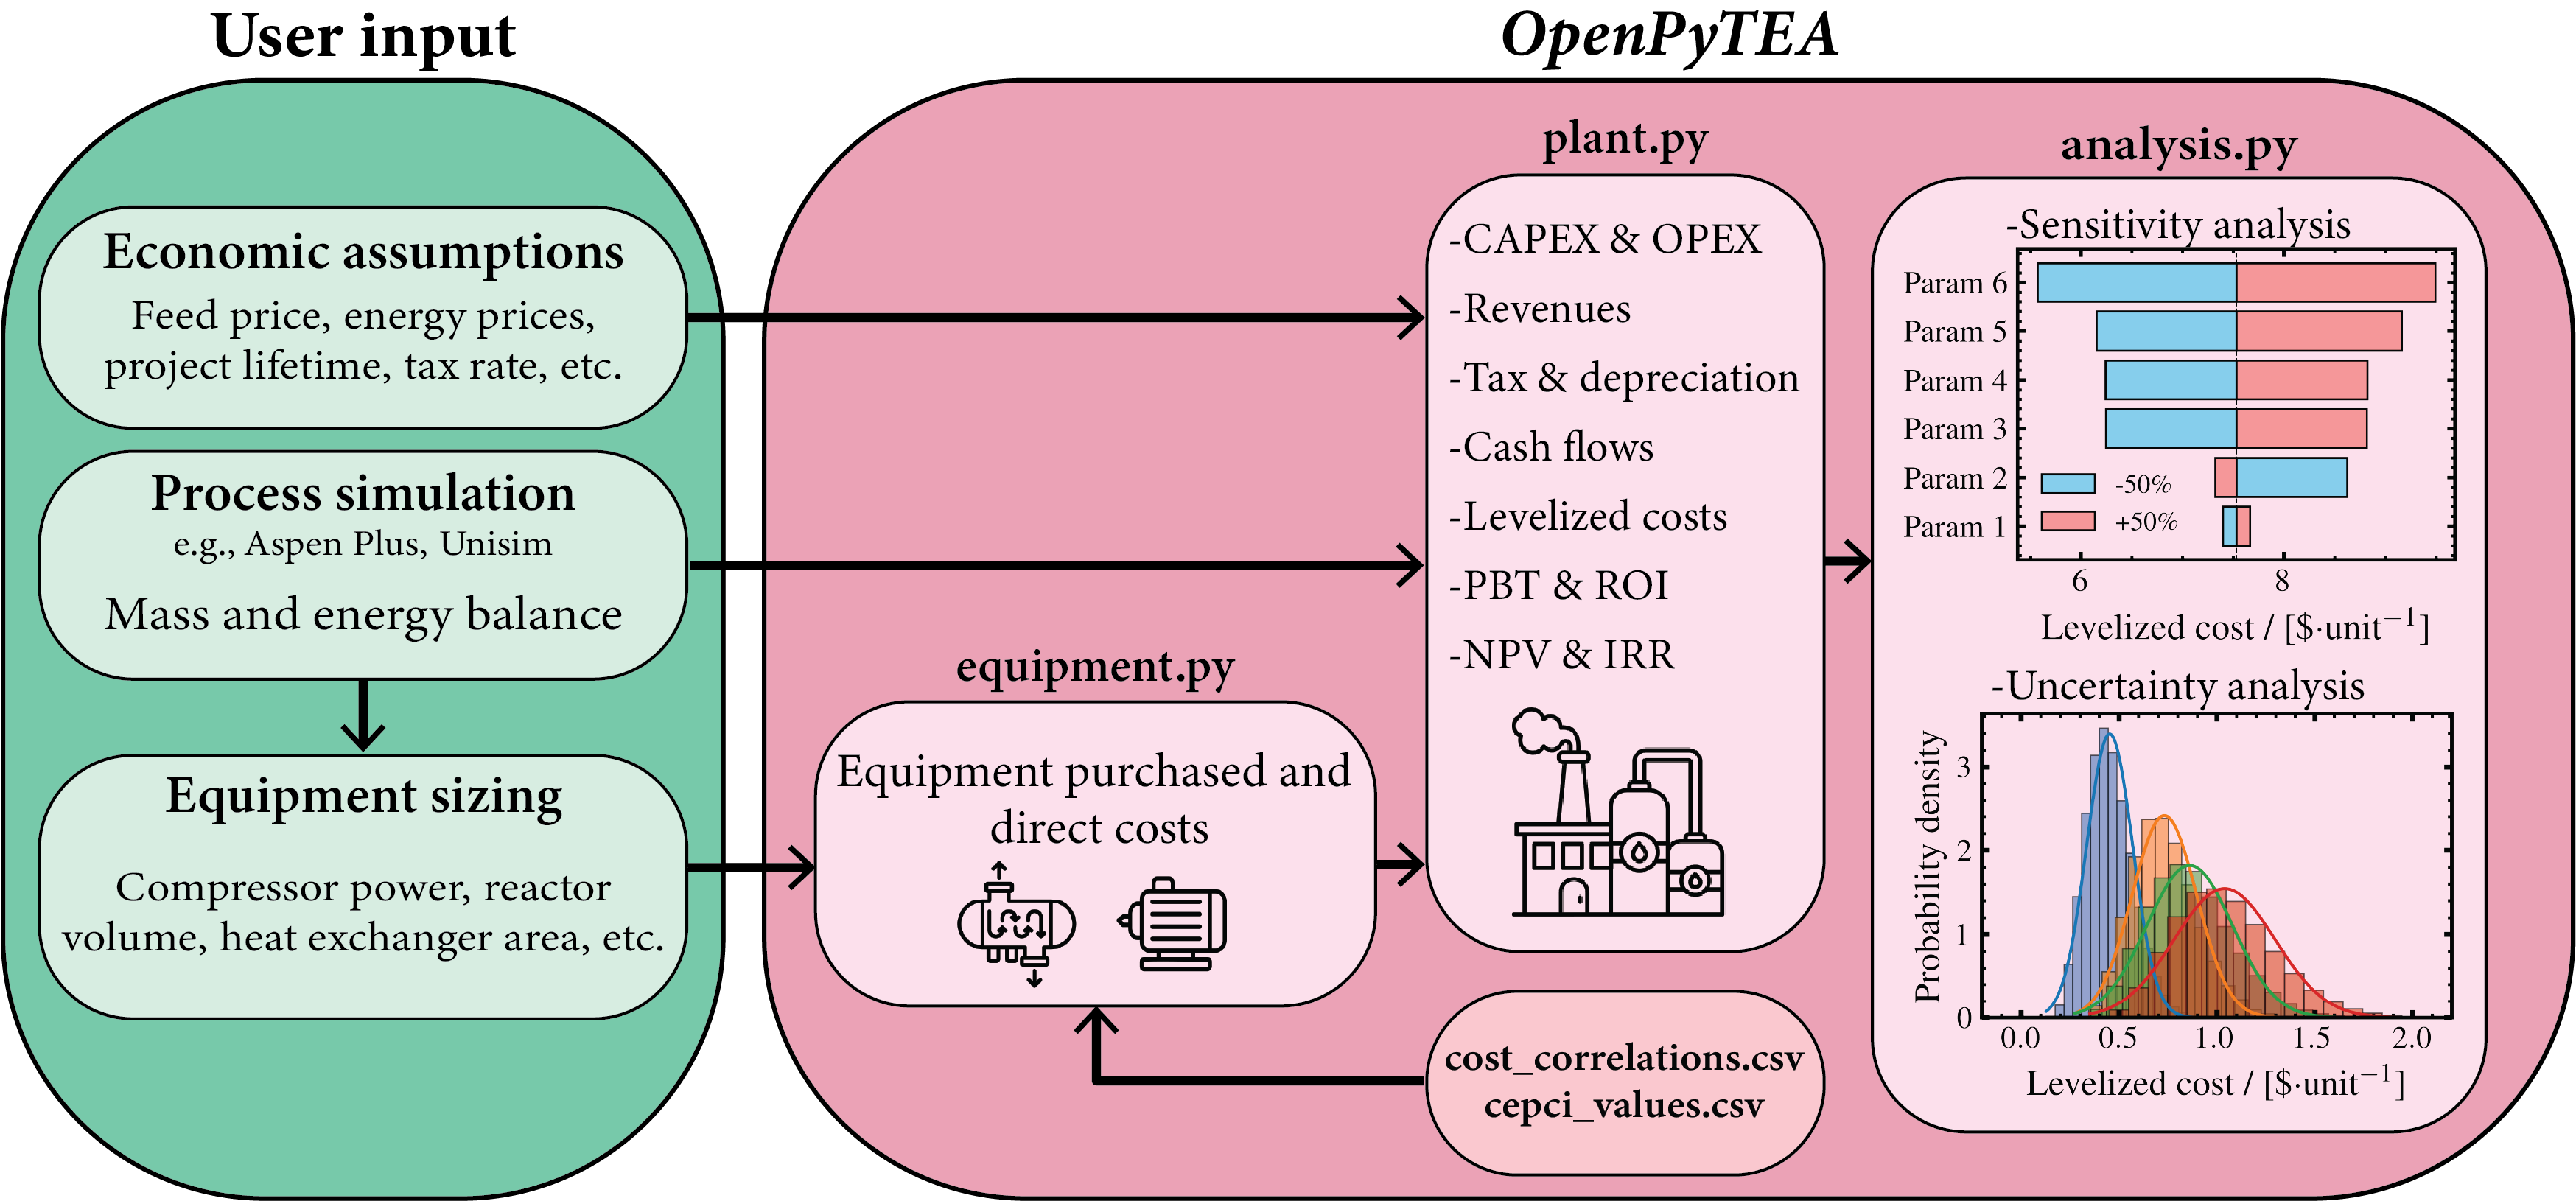
Software architecture and data flow of OpenPyTEA, illustrating the progression from user input to TEA output. Users provide economic assumptions, process simulation results, and equipment-sizing parameters. Equipment-sizing information is linked with cost correlations and CEPCI values stored in CSV databases to calculate inflation-adjusted purchased and direct costs. Equipment objects are aggregated into a Plant object, where CAPEX, OPEX, and financial performance metrics are evaluated. The analysis.py module subsequently operates on Plant objects to perform sensitivity and uncertainty analyses.
🖥️ Graphical User Interface
Note: The GUI is still in development and may not yet offer all the features of the Python package.
An optional graphical interface provides the full TEA workflow — equipment costing, plant configuration, results, sensitivity/tornado analysis, Monte Carlo, and multi-plant comparison — without writing Python code. It can be installed as a standalone desktop app — installers for Windows (.exe/.msi) and macOS (.dmg) are available on the Releases page, with no Python or Node.js required — or run from source as a FastAPI + React application.
The GUI's source, installer build, setup instructions, and architecture documentation live on the standalone-package branch:
git fetch origin
git checkout standalone-package
🧠 Core Concepts
1. Equipment-level costing
Each process unit (e.g., compressor, heat exchanger, reactor) is represented by an Equipment object:
from openpytea.equipment import Equipment

compressor = Equipment(
    name='COMP',
    param=5000,  # kW
    process_type='Fluids',
    category='Compressors, fans, & Blowers',
    type='Compressor, centrifugal',
    material='Carbon steel'
)

print(compressor.direct_cost)
Each equipment item retrieves its cost correlation from the internal database in data/cost_correlations.csv and adjusts the cost to the desired year using the Chemical Engineering Plant Cost Index (CEPCI).
Assemblies such as a PSA skid (vessels plus adsorbent layers) can be built from individually priced sub-components with CompositeEquipment; the composite then behaves like any other equipment item in a plant:
from openpytea.equipment import CompositeEquipment

psa = CompositeEquipment(
    name='PSA',
    process_type='Fluids',
    components=[vessel, zeolite, carbon],   # ordinary Equipment objects
)
print(psa.direct_cost)
psa.breakdown()                             # one row per sub-component
2. Plant-level techno-economic assessment
Multiple equipment objects can be grouped into a Plant instance for full TEA
from openpytea.plant import Plant

ammonia_plant = Plant({
    'plant_name': 'Ammonia Production Plant',
    'country': 'Netherlands',
    'process_type': 'Fluids',
    'equipment': [compressor],
    'interest_rate': 0.09,
    'plant_utilization': 0.95,
    'project_lifetime': 20,  # in years
    'plant_products': {  # Here we define the product(s) of the plant
        'ammonia': {
            'production': 125_000,  # Daily production in kg/day
        }
    },
    'variable_opex_inputs': {
        'electricity': {
            'consumption': 110,  # Daily consumption, in MWh
            'price': 75  # US$/MWh
        },
        'hydrogen': {
            'consumption': 22_000,  # Daily consumption, in kg/day
            'price': 2  # US$/kg
        },
    },
})

ammonia_plant.calculate_cash_flow(print_results=True)
ammonia_plant.calculate_levelized_cost()
Main outputs include:
- Capital expenditures (CAPEX): inside/outside battery limits, engineering, contingency, and location factors
- Operating expenditures (OPEX): variable and operating expenditures, including utilities, maintenance, labor, and overhead costs
- Financial metrics: Net Present Value (NPV), Internal Rate of Return (IRR), Return on Investment (ROI), Payback Time (PBT), and Levelized Cost of Product (LCOP)
3. CAPEX and OPEX breakdown plots
Following a data + plot pattern used throughout the package, OpenPyTEA includes convenience functions for visualizing the economic structure of one or more plants as stacked bar charts:
direct_costs_data()+plot_stacked_bar(): direct equipment costs (per equipment item;expand_composites=Truesplits composite equipment into its components).fixed_capital_data()+plot_stacked_bar(): fixed capital components (ISBL, OSBL, design & engineering, contingency).variable_opex_data()+plot_stacked_bar(): variable operating costs by input mass and energy stream.fixed_opex_data()+plot_stacked_bar(): fixed operating expenses, including labor, supervision, maintenance, overhead, R&D, and more.levelized_cost_data()+plot_stacked_bar(): levelized cost of production (LCOP), broken down into discounted CAPEX, OPEX, and side-product revenue.
from openpytea.analysis import direct_costs_data, levelized_cost_data
from openpytea.plotting import plot_stacked_bar

direct_costs = direct_costs_data(ammonia_plant)
fig, ax = plot_stacked_bar(direct_costs)

lcop = levelized_cost_data(ammonia_plant)
fig, ax = plot_stacked_bar(lcop)
Each *_data() function also accepts a list of plants, in which case plot_stacked_bar draws one bar per plant side-by-side for direct comparison. Separating data preparation (analysis.py) from plotting (plotting.py) means you can also feed the returned dictionaries into your own custom visualization code.
4. Cash flow diagram
cash_flow_data() and plot_cash_flow() visualize a project's cumulative cash flow over time: the dip into debt during construction, the point of maximum investment, the break-even (pay-back) point, and the eventual climb into profit.
from openpytea.analysis import cash_flow_data
from openpytea.plotting import plot_cash_flow

cash_flow = cash_flow_data(ammonia_plant)
fig, ax = plot_cash_flow(cash_flow)
As with the cost breakdowns, passing a list of plants overlays their cumulative cash flow curves — each with its own shaded debt region and break-even line — for direct comparison. The returned dictionary also carries the underlying figures (max_investment, max_investment_year, breakeven_year/payback_time) for use outside the plot, e.g. in reports.
5. Sensitivity and uncertainty analysis
OpenPyTEA provides integrated tools for visual sensitivity and probabilistic analysis of cost and performance drivers.
One-Way Sensitivity Line Plot
from openpytea.analysis import sensitivity_data
from openpytea.plotting import plot_sensitivity

results = sensitivity_data(
    ammonia_plant,
    parameter="electricity",
    plus_minus_value=0.5,
)
fig, ax = plot_sensitivity(results)
The plants input may also be a list of Plant objects to generate comparison plots.
Besides prices and financial assumptions, parameter also accepts a process quantity — "electricity.consumption" or "ammonia.production" — to sweep the physical side of the plant.
Tornado Plot (One-at-a-Time Sensitivity)
from openpytea.analysis import tornado_data
from openpytea.plotting import plot_tornado

results = tornado_data(ammonia_plant, plus_minus_value=0.5)
fig, ax = plot_tornado(results)
Pass include_process_params=True to rank consumption and production quantities alongside the prices and financial assumptions.
Monte Carlo Simulation
from openpytea.analysis import monte_carlo
from openpytea.plotting import plot_monte_carlo

results = monte_carlo(ammonia_plant, num_samples=1_000_000)
fig, ax = plot_monte_carlo(results)
Outputs include probability distributions and confidence intervals for LCOP, NPV, ROI, and payback time—supporting uncertainty-informed decision-making. With plot_multiple_monte_carlo, OpenPyTEA can also visualize Monte Carlo results for multiple plants to enable uncertainty comparisons. plot_monte_carlo_inputs shows the sampled inputs themselves, split into process and economic figures, to confirm each distribution came out as intended.
Uncertainty is configured per item: price_uncertainty on any variable_opex_inputs or plant_products entry, consumption_uncertainty/production_uncertainty for the quantities, and project_uncertainties for the project-level scalars.
Parameter Dependencies
ammonia_plant.update_configuration({
    "variable_opex_inputs": {
        "hydrogen": {
            "consumption_dependency": {
                "depends_on": {"production:ammonia": 0.176},  # kg H2 per kg NH3
            },
        },
    },
})
Rather than varying independently, a quantity can be defined as a linear function of one or more others — dependent = Σ wᵢ · parentᵢ + offset. Here the hydrogen feed follows ammonia production instead of drifting away from it. Process and economic parameters can drive each other in either direction (a byproduct's yield tracking the main product, fixed_capital_factor scaling with capacity), chains and multi-parent nodes resolve automatically, and cycles raise an error. A dependent may carry its own additive noise on top of the implied mean.
Because dependencies live on the Plant, all three analyses honour them: Monte Carlo samples through the graph, while sensitivity_data and tornado_data propagate each perturbation through it and refuse to vary a parameter that a dependency already determines. See the Analysis user guide in the documentation for the full configuration format.
6. Workflow using JSON config files and command-line interface
OpenPyTEA supports a workflow using structured JSON input files via the io.py module. This enables standardized, reproducible, and scalable TEA studies.
Key functionalities include:
run_equipment(): evaluate equipment costs from JSON inputrun_plant(): construct and evaluate a plant configurationrun_tea(): execute full TEA, including cost breakdowns, sensitivity, and uncertainty analysisrun_openpytea(): single-file counterpart torun_tea()— runs the same pipeline from one combined JSON file (equipment+plant+analysisblocks), intended for CLI use
This workflow is demonstrated in case_study_1_with_JSON.ipynb in the example folder.
Installing OpenPyTEA also installs an openpytea command-line tool, so the same combined-file workflow can be run without writing any Python:
openpytea run project/config.json --output-dir outputs/tea_results
openpytea equipment, openpytea plant, and openpytea tea (the three-file variant of run_tea()) are also available — run openpytea --help for the full command list. See the JSON Workflow guide for details.
📘 Example Workflows
Example notebooks are available in the examples/ folder, including:
- Comparison of hydrogen production pathwways
- Hydrogen liquefaction precooling system
- Geothermal-based heating and power generation
Run any example via:
jupyter notebook examples/case_study_1.ipynb
Each notebook demonstrates:
- Input definition and equipment configuration
- Cash-flow and investment evaluation
- Sensitivity and uncertainty analysis
- Visualization of key economic indicators
🧑🏫 Educational Use
OpenPyTEA is suitable for chemical and process engineering education. Students can perform full TEA using their simulation outputs—estimating capital, operating, and profitability metrics—without commercial software. All algorithms are visible and modifiable, eliminating the “black-box” nature of most TEA tools.
🛠️ Contributing
We welcome community contributions! You can help by:
- Adding or updating equipment cost correlations
- Improving the documentation or creating tutorials
- Extending the visualization or uncertainty modules
To contribute:
- Fork the repository.
- Create a new branch:
git checkout -b feature-new-equipment
- Commit your changes and open a Pull Request.
Please follow PEP8 coding conventions and include a short description of your updates.
📖 Publication
OpenPyTEA is described in the following peer-reviewed paper published in SoftwareX:
Tamarona, P.B., Vlugt, T.J.H., & Ramdin, M. (2026). OpenPyTEA: An open-source python toolkit for techno-economic assessment of chemical process plants and energy systems with economic sensitivity and uncertainty evaluation. SoftwareX, 35, 102816. https://doi.org/10.1016/j.softx.2026.102816
If you use OpenPyTEA in your research, please cite this paper (see Citation below).
📚 Citation
If you use OpenPyTEA in your research, please cite the following paper:
Tamarona, P.B., Vlugt, T.J.H., & Ramdin, M. (2026). OpenPyTEA: An open-source python toolkit for techno-economic assessment of chemical process plants and energy systems with economic sensitivity and uncertainty evaluation. SoftwareX, 35, 102816. https://doi.org/10.1016/j.softx.2026.102816
BibTeX:
@article{TAMARONA2026102816,
title = {OpenPyTEA: An open-source python toolkit for techno-economic assessment of chemical process plants and energy systems with economic sensitivity and uncertainty evaluation},
journal = {SoftwareX},
volume = {35},
pages = {102816},
year = {2026},
issn = {2352-7110},
doi = {https://doi.org/10.1016/j.softx.2026.102816},
url = {https://www.sciencedirect.com/science/article/pii/S2352711026003080},
author = {P.B. Tamarona and T.J.H. Vlugt and M. Ramdin},
keywords = {Techno-economic assessment, Process design, Process plant, Power plant, Chemical engineering},
` ` `
📄 License
OpenPyTEA is released under the MIT License.
You are free to use, modify, and distribute the code with proper attribution.
📬 Contact
Panji B. Tamarona
Repository: https://github.com/pbtamarona/OpenPyTEA
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file openpytea-3.0.0.tar.gz.
File metadata
- Download URL: openpytea-3.0.0.tar.gz
- Upload date:
- Size: 131.3 kB
- Tags: Source
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
145646c1c8e454d314d1636cbba48c8a9afa583346f27475eac9b1f29f3d5940
|
|
| MD5 |
1c054829e8b23b894c117219a0717c14
|
|
| BLAKE2b-256 |
1c21eafe45ffc9883441744f077dbc9361b24bf1492b6bf020a112caaefbe23a
|
File details
Details for the file openpytea-3.0.0-py3-none-any.whl.
File metadata
- Download URL: openpytea-3.0.0-py3-none-any.whl
- Upload date:
- Size: 117.6 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? No
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
9ca0dedbfda4e50346633fa97888bff24c718d2161c8924052cd7ecd0e0d6e7c
|
|
| MD5 |
5a93e03f8097e07cd5ad12626600c035
|
|
| BLAKE2b-256 |
46d1efc02362a7b910b5de76b1f4c154fe3073f491b20b1a7e9fd9eb73bb18c0
|














