
PyIBS: Inverse Binomial Sampling in Python


PyIBS is one of the open-source tools for fitting models to data developed by the Machine and Human Intelligence Group at the University of Helsinki. It works with PyBADS for point estimates and PyVBMC for posterior and model-evidence estimates.
What is it?
PyIBS estimates the log-likelihood of a model that you can simulate but whose likelihood you cannot compute. It implements inverse binomial sampling (IBS) for data with discrete responses [1]. For each trial, IBS simulates responses until one matches the observed response, then uses the number of draws to estimate that trial's log-likelihood. Without a likelihood threshold or time limit, the estimate is exactly unbiased. PyIBS also estimates its variance, which measures the noise introduced by simulation. The reference implementation is ibslike.m in MATLAB IBS.
Use the estimates with a method that handles noisy objectives: PyBADS for maximum-likelihood or maximum-a-posteriori estimation, or PyVBMC for posterior and model-evidence estimation. PyIBS can return the estimate and its estimated standard deviation in the format both methods accept.
What's new in PyIBS 1.5
- Rebuilt and checked against MATLAB IBS. The sampling code follows
ibslike.m0.96 and has been compared with it line by line. The catalogue of deliberate differences explains the choices made for the Python implementation. - Validated against exact likelihoods. Tests on 16 models with exact log-likelihoods detected no bias. The validation record lists the models and settings tested, and the limits of the variance estimates.
- Ready for PyBADS and PyVBMC.
additional_output="std"returns a tuple of Python floats: the estimate and its estimated standard deviation. PyBADS 1.5 and PyVBMC 1.5 accept this format for noisy targets. PyIBS warns when the standard deviation is 0, which both methods refuse, and links to guidance in the FAQ. - Reproducible runs.
IBS(..., random_seed=...)seeds a random number generator that the simulator receives through itsrngparameter. Set the sampling schedule explicitly to avoid a decision based on timing; see Quick start. - Fixes. PyIBS 0.1.0's default
max_iterwas 15, which biased estimates for improbable responses. It also failed on responses with several columns. Version 1.5 fixes these and other defects. - Faster. In timings of the example model, PyIBS 0.1.0 took 1.3 to 2.1 times as long per estimate with a fast simulator, and up to 3.8 times as long when a fixed cost per simulator call dominated the runtime.
- Requirements. PyIBS requires Python 3.10 or later. Its only runtime dependencies are NumPy 2.0 or later and SciPy 1.13 or later.
- Documentation and examples. The documentation site includes three example notebooks covering basic use, PyBADS, and PyVBMC, plus a FAQ. The PyIBS skill helps coding agents find the relevant documentation (see Documentation).
Results differ from PyIBS 0.1.0 even with a fixed seed, and IBS rejects some settings that the earlier version accepted. Before upgrading an existing analysis, read "Upgrading from 0.1.0" in the changelog, which also lists the changes in detail.
Documentation
Read the full documentation for tutorials, practical guidance, and the API reference.
Its FAQ collects questions and answers on when to use IBS, installing PyIBS, writing the simulator, fitting with PyBADS and PyVBMC, choosing the number of repeats and the likelihood threshold, and calls that go wrong.
To use the PyIBS skill, give the file to your coding agent or copy the skills/pyibs folder into its skill directory. To update a copied skill, copy the folder again from the PyIBS version you use.
When should I use PyIBS?
Use PyIBS when you can simulate a model's responses but cannot compute its likelihood. The responses must be discrete, such as choices, categories, or counts, and the simulator must be able to draw each trial's response given its context: its stimulus and, when relevant, earlier stimuli and responses [1, Section 2.2]. IBS then supplies the noisy log-likelihood and uncertainty estimates needed for maximum-likelihood or maximum-a-posteriori fitting with PyBADS, posterior and model-evidence estimation with PyVBMC, and model comparison.
- Use a tractable likelihood when available. The IBS paper recommends a closed form or an analytical or numerical approximation whenever one is practical. IBS estimates can help check its implementation, and the accuracy of an approximation [1, Section 6.4].
- Amortized simulation-based inference is often better when fitting one model to many datasets with cheap simulations. A neural network trained once on simulations can share that training cost across datasets. In neural posterior estimation, it then estimates the posterior for each new dataset almost immediately [3].
- IBS remains the method of choice when trial contexts are numerous and richly structured. An amortized estimator must learn the model's behaviour across the contexts it may encounter; IBS only simulates the contexts present in the data. For example, a model of human board-game play chooses each move from the current board position, which may occur only once in the dataset [1, Section 5.4; 2].
- IBS also helps when guarantees for each dataset matter. An amortized estimator can be accurate on some datasets and unreliable on others, so each dataset needs its own diagnostics [3]. IBS needs no training, and its log-likelihood and variance estimates are unbiased for any dataset whose observed responses all have positive probability.
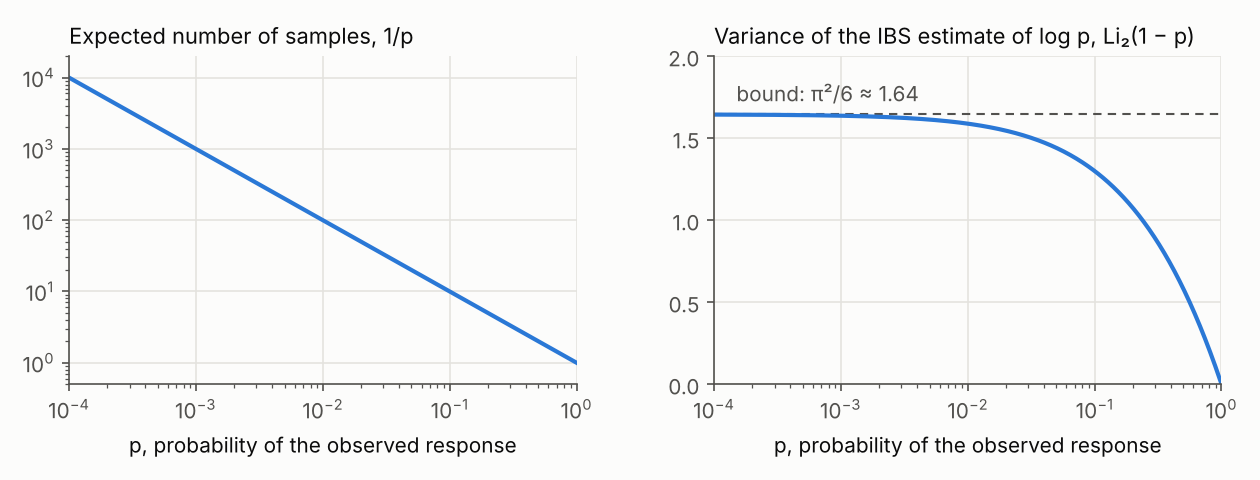
- Account for the cost of improbable responses. A trial whose observed response has model probability p takes 1/p samples on average. A lapse component that gives every possible response positive probability limits this cost. The likelihood threshold can save work at poor parameter vectors, at the cost of bias [1, Sections 2.2 and 6.4, Appendix C.1]. Continuous responses require binning or an approximate matching rule [1, Section 6.3]; see the FAQ.
The FAQ discusses IBS and amortized simulation-based inference in more detail.
Installation
Install PyIBS from PyPI or conda-forge. It requires Python 3.10 or later, NumPy 2.0 or later, and SciPy 1.13 or later.
-
Install or upgrade with pip:
python -m pip install --upgrade pyibsOr use Conda:
conda install --channel=conda-forge "pyibs>=1.5"The minimum version in the Conda command prevents it from silently selecting PyIBS 0.1.0 in an environment with NumPy 1.x or Python 3.10: on conda-forge, PyIBS 1.5 requires Python 3.11 or newer.
-
(Optional) To fit models with PyIBS's estimates, as the example notebooks do, install PyBADS and PyVBMC, and Jupyter Notebook to run the notebooks:
python -m pip install --upgrade "pybads>=1.5.1" "pyvbmc>=1.5" notebookThe notebooks are included with PyIBS. Find their installation folder with:
python -c "import os, pyibs.examples; print(os.path.dirname(pyibs.examples.__file__))"
Run pyibs.check_for_updates() to check for a newer release. To install from source, follow the instructions for developers and contributors.
Quick start
To estimate a model's log-likelihood:
- Write a simulator that draws one response for each requested trial.
- Supply the observed responses and each trial's design, such as its stimulus.
- Create an
IBSobject and call it with a parameter vector. For fitting, wrap this call as the target of an optimizer or inference method. - Check the estimates and the fit.
This complete example generates 600 trials from the included orientation-discrimination model and compares an IBS estimate with its exact negative log-likelihood:
import numpy as np

from pyibs import IBS
from pyibs.examples.psycho_model import psycho_generator, psycho_neg_logl

# The parameters are (log(sigma), bias, lapse).
rng = np.random.default_rng(20261009)
S = 3 * rng.standard_normal(600)  # the orientation of each trial's stimulus
theta = np.array([0.0, 0.2, 0.03])
R = psycho_generator(theta, S, rng)  # the responses, 1 or -1

ibs = IBS(psycho_generator, R, S, vectorized=True, random_seed=1)
neg_logl, sd = ibs(theta, num_reps=100, additional_output="std")
exact = psycho_neg_logl(theta, S, R)
print(f"IBS: {neg_logl:.1f} +/- {sd:.1f}; exact: {exact:.1f}")
To use your own model, pass these inputs to IBS:
sample_from_model: a simulator called assample_from_model(params, design_rows). If it has anrngparameter that accepts a keyword, PyIBS also passes its random number generator asrng=rng. Return an independent simulated response for each requested row; a trial may be requested several times in one call.response_matrix: the observed responses, one row per trial.design_matrix(optional): the design of each trial, one row per trial. The simulator receives the rows requested by IBS. When no design is supplied, it receives the trials' 0-based indices instead.
ibs(params) returns the negative log-likelihood estimate, averaging 10 independent IBS repeats by default. Set num_reps to change this number. With additional_output="std", the call also returns an estimated standard deviation, which measures variation between IBS calls at the same parameters; it is not uncertainty in the parameters. With "full", it returns an EstimateResult containing per-trial estimates and the cost of the call. The IBS reference describes all settings, including the likelihood threshold neg_logl_threshold.
Choose the sampling schedule for your simulator. The code above sets vectorized=True, which requests batches of responses, because psycho_generator returns many responses cheaply in one call. By default (vectorized=None), IBS times your simulator once and, if simulating is slow, requests one response per trial and call, which wastes no samples; see Should I set vectorized?
The fitting snippets below are templates. Supply a starting parameter vector x0, hard bounds lb and ub, and plausible bounds plb and pub; PyVBMC also needs a prior. Example 2 and Example 3 define these inputs for the orientation-discrimination model.
For PyBADS, which minimizes its target, return the negative log-likelihood and its estimated standard deviation:
from pybads import BADS

def target(theta):
    return ibs(theta, num_reps=100, additional_output="std")

bads = BADS(
    target, x0, lb, ub, plb, pub,
    options={"specify_target_noise": True, "random_seed": 2},
)
result = bads.optimize()
For PyVBMC, return the log-likelihood (return_positive=True) and its estimated standard deviation. When you supply prior, PyVBMC adds the log prior itself:
from pyvbmc import VBMC

def log_likelihood(theta):
    return ibs(
        theta, num_reps=100, additional_output="std", return_positive=True
    )

vbmc = VBMC(
    log_likelihood, x0, lb, ub, plb, pub,
    prior=prior, options={"specify_target_noise": True}, seed=2,
)
vp, results = vbmc.optimize()
Choose num_reps for a standard deviation of about 1 near the optimum. PyBADS works best with noise of 1 or less there; PyVBMC works best with about 1, and not much more than 3, in the region containing most posterior mass. For this model, 100 repeats give an SD of about 1.1 on 600 trials.
For reproducible runs, seed both PyIBS and the fitting method, and have the simulator draw from the rng it receives. Set vectorized explicitly and leave the timing-dependent settings max_time and acceleration_threshold at their defaults. The examples above use separate seeds for IBS and the fit; the FAQ explains when a seed reproduces a run.
Next steps
The example notebooks form a short tutorial: basic use and checks of the uncertainty estimates, maximum-likelihood fitting with PyBADS, and posterior and model-evidence estimation with PyVBMC. Read their saved outputs on the documentation site, or run the notebooks installed in pyibs/examples.
The FAQ explains how to write a simulator, choose num_reps and the likelihood threshold, and troubleshoot a failed call.
How does it work?
Suppose a trial's observed response has probability p under the model. IBS does not need to know p: it simulates responses until one matches, taking K draws, and estimates log p as
-(1 + 1/2 + 1/3 + ... + 1/(K - 1)).
The estimate is 0 when K = 1. For every p > 0, it is exactly unbiased and has the least variance among unbiased estimators based on this sampling procedure. Its variance is bounded by π²/6 even as p approaches 0 [1, Sections 2.4 and 4.3]. The same count K gives an estimate of that variance, ψ₁(1) − ψ₁(K), where ψ₁ is the trigamma function [1, Section 4.3]. Its expectation is the variance itself, Li₂(1 − p) (Fig 1), so the variance estimate is unbiased too.
Summing over trials and averaging independent repeats often makes the estimated standard deviation useful for normal confidence intervals [1, Section 4.6], though not always: if every response matches on its first draw, the variance estimate is 0 even though repeated IBS calls can vary.
Fig 1: the cost and variance of IBS. A trial with matching probability p takes 1/p samples on average (left). The variance of its log p estimate, Li₂(1 − p), stays below π²/6 even as p approaches 0 (right) [1, Sections 4.2 and 4.3].
The data's log-likelihood is the sum of the trial log-likelihoods. IBS therefore adds their estimates and variance estimates. An IBS call averages num_reps independent repeats, reducing the variance by that factor. Each simulator call samples all trials that still need a match. With vectorized=True, it requests several samples per trial, a number that grows after every call.
The optional likelihood threshold, neg_logl_threshold, stops a repeat once its accumulating negative log-likelihood estimate exceeds the threshold. That repeat contributes the threshold value to the negative log-likelihood estimate. This saves simulation at poor parameters but biases the estimate [1, Appendix C.1]. A finite max_time also biases estimates; use neither limit when unbiasedness is essential.
See the IBS paper for more details (van Opheusden, Acerbi and Ma, 2020).
Troubleshooting and contact
PyIBS is under active development. Its estimates have been checked against exact likelihoods across models and settings, but you should also check the simulator, estimates, and fits for your own model.
Many questions are answered in the FAQ. Its Troubleshooting section covers the errors a call can raise, how to make a run reproducible, and how to check that the estimates are right for your model.
If the FAQ does not help, or for unexpected behavior or bugs:
- Ask in the lab's Discussions forum, including questions about your model-fitting application.
- Open a GitHub issue.
- Email the project lead at luigi.acerbi@helsinki.fi with 'PyIBS' in the subject.
References and citation
-
van Opheusden, B.*, Acerbi, L.* & Ma, W. J. (2020). Unbiased and efficient log-likelihood estimation with inverse binomial sampling. PLOS Computational Biology 16(12): e1008483. (* equal contribution) https://doi.org/10.1371/journal.pcbi.1008483
-
van Opheusden, B., Kuperwajs, I., Galbiati, G., Bnaya, Z., Li, Y. & Ma, W. J. (2023). Expertise increases planning depth in human gameplay. Nature 618: 1000-1005. https://doi.org/10.1038/s41586-023-06124-2
-
Li, C., Vehtari, A., Bürkner, P.-C., Radev, S. T., Acerbi, L. & Schmitt, M. (2026). Amortized Bayesian workflow. Transactions on Machine Learning Research. https://openreview.net/forum?id=osV7adJlKD
Please cite reference 1 when using PyIBS. For example:
We estimated the log-likelihood of our models with inverse binomial sampling (IBS; van Opheusden, Acerbi and Ma, 2020), implemented in PyIBS. IBS simulates responses until each observed response is matched, giving unbiased log-likelihood and variance estimates when sampling is allowed to complete.
To support the project and keep in touch:
- Star ⭐ the PyIBS repository on GitHub;
- Follow Luigi Acerbi on X or Bluesky for updates about IBS/PyIBS and other projects;
- Tell us about your model-fitting problem and your experience with PyIBS (positive or negative) in the lab's Discussions forum.
Explore PyBADS, PyVBMC, and the lab's other model-fitting tools for ways to fit models using these estimates.
BibTeX
@article{vanopheusden2020unbiased,
  title={Unbiased and efficient log-likelihood estimation with inverse binomial sampling},
  author={van Opheusden, Bas and Acerbi, Luigi and Ma, Wei Ji},
  journal={PLOS Computational Biology},
  volume={16},
  number={12},
  pages={e1008483},
  year={2020},
  publisher={Public Library of Science},
  doi={10.1371/journal.pcbi.1008483}
}
License
PyIBS is released under the terms of the BSD 3-Clause License.
Acknowledgments
PyIBS is developed by members (past and current) of the Machine and Human Intelligence Group at the University of Helsinki and ELLIS Institute Finland. We thank Julia Maria Perathoner for her work on PyIBS 0.1.0, an earlier Python port of IBS. Development of PyIBS 1.5 was assisted by coding agents, including Anthropic's Claude. Work on the PyIBS package is supported by the Research Council of Finland (grants 356498 and 358980 to Luigi Acerbi) and its Flagship programme: Finnish Center for Artificial Intelligence FCAI.


Release files for PyIBS 1.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| pyibs-1.5.0.tar.gz | 244.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pyibs-1.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 478.3 kB
Release files / pyibs-1.5.0.tar.gz
| Download URL | pyibs-1.5.0.tar.gz |
|---|---|
| Size | 244.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c86b1cfbf691a45d90426befcc0e78c475cb87939040d47e7ee9697ce5b7dc10
|
|
BLAKE2b-256 checksum How to use checksums |
58a41093fd98e0b227d870c14393a9e58fe60aa37fc76c4b6611e682ba691d17
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency logRelease files / pyibs-1.5.0-py3-none-any.whl
| Download URL | pyibs-1.5.0-py3-none-any.whl |
|---|---|
| Size | 234.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3bb26bff54460687ee2778ade6f2ab3b4d89110a7b895dd3143686b041834765
|
|
BLAKE2b-256 checksum How to use checksums |
a10c6cadccf50206ec76e2fd7082fee07695434748dcf40685fab05906790640
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency log













