
SafeAI — Agent Authority Security for the Software Supply Chain


Enjoying SafeAI? A ⭐ on GitHub helps more security teams find it.
Know what your AI agent can do before you deploy it.
SafeAI statically maps agent capabilities, tools, MCP integrations, and authority changes, then turns material changes into explainable CI/CD security decisions and portable evidence. Technically, SafeAI is a Static AI Capability & Risk Analyzer: it scans AI application source code for security risks, capability exposure, and governance gaps. It is offline and source-private by default — it never executes agents or calls LLMs, and network activity occurs only through explicitly enabled integration commands (currently only --pr-comment-post). It integrates into CI/CD pipelines.
Three pillars — DISCOVER / COMPARE / GOVERN:
| Pillar | Question | What SafeAI does |
|---|---|---|
| DISCOVER | What can the agent access? | Builds an evidence-backed model of agent authority: tools, MCP servers, filesystem, shell, databases, APIs, destinations, memory, delegation, autonomy, approval controls |
| COMPARE | What changed? | Diffs authority against the approved baseline: new tools, read → write widening, new destinations, removed approval gates |
| GOVERN | Should that change be allowed? | Deterministic CI/CD decisions — pass, review-required, block, accepted-exception — with evidence, never an opaque score |
SafeAI is not a runtime guardrail and does not certify an agent as safe. It provides source-first, evidence-backed visibility into agent authority and meaningful changes before deployment.
🌐 safeai-analyzer.ikaruscareer.com — project landing page
Know Your Agent (KYA)
SafeAI now turns static scan results into a private, historical inventory of AI agents and their findings.
Why SafeAI?
Traditional application security tools (SAST, SCA, IaC scanning) are not designed for AI agent systems. AI applications introduce new risk surfaces:
- Prompt injection — untrusted input flows into model prompts
- Agent tool misuse — agents with filesystem, shell, or database access
- Capability sprawl — frameworks expose capabilities without visibility
- MCP exposure — Model Context Protocol endpoints and tools
- Governance gaps — missing authentication, permissions, audit trails
SafeAI fills this gap by analyzing frameworks, agents, tools, capabilities, and MCP integrations at rest—before deployment.
SafeAI analyzes AI applications without executing them, helping developers discover capabilities, identify potential risks, and improve governance early in the software lifecycle.
Designed to be lightweight, explainable, and community-driven, SafeAI aims to become an open foundation for AI capability and risk analysis.
SafeAI sits before runtime guardrails and red-teaming tools in the security lifecycle. It scans agent source code at commit time — detecting framework-specific capabilities, MCP misconfigurations, and prompt injection patterns — before you ever deploy an agent to staging. It does not replace runtime tools (Microsoft AGT), evaluation frameworks (LangSmith, DeepEval), or red-teaming scanners (Promptfoo, Garak). It complements them: find the risk in code first, then validate at runtime.
Example: authority-change report
SafeAI's most important security event is not simply that a finding exists. It is that an agent's effective authority materially changes.
Agent: customer-support-agent            Baseline: release v2.4.0 (approved)

AUTHORITY CHANGE (material)
+ tool:        crm_update
+ capability:  database write
+ destination: production CRM
+ access:      read → write
- human approval gate (GOV_APPROVAL_MISSING)

Policy decision: BLOCK
Reason: production write authority was added without an approved
        exception or required approval control.
Evidence: source files · tool definition · baseline manifest ·
          current manifest · policy profile · SafeAI version ·
          ruleset version · commit SHA
The reviewer learns what the agent can now do that it could not do before — and the decision cites evidence, not a score.
Agent Authority Model
SafeAI builds an analytical model — not an observation of runtime permissions — of what an agent is empowered to do:
Agent
  → Tool / MCP Server / Skill / Workflow Node
    → Capability
      → Access Mode (none < read < write < mutate < execute)
        → Data / Destination / Resource
          → Authority
Every authority statement carries a class: declared (config says so), detected (code shows it), inferred (heuristic, confidence-labelled), repository/IaC-observed (in-repo infrastructure grants), or unknown. Runtime-granted authority (live IAM, deployed network policy, runtime identity) is explicitly unknown to the static scanner — unknown is an evidence state, not evidence of safety, and SafeAI never converts it into a pass.
What decisions mean. pass means no configured deterministic gate
triggered — never "the agent is safe." unknown means unattributable
evidence — never "no risk detected." Organizations can govern unknown
authority explicitly (authority.unknown policy, --unknown-authority),
but the default leaves it visible and unfailed.
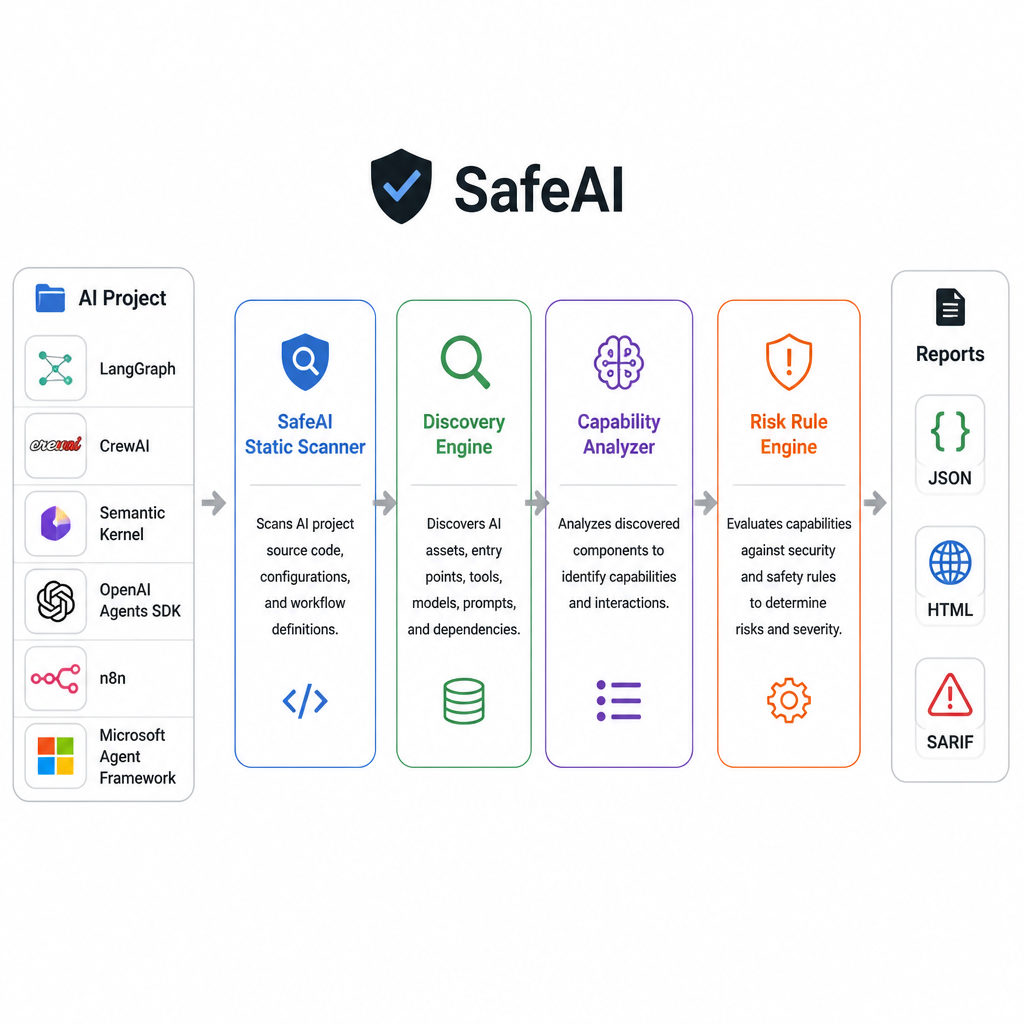
Key Features
| Feature | Description |
|---|---|
| Framework Detection | Detects and parses 19 AI agent frameworks (AST + config + regex, no mutual exclusion) |
| Tool Identity & Access Modes | Capabilities attributed to named tools (agent / MCP server / skill / tool / workflow node) on an access scale none < read < write < mutate < execute; inferred modes are flagged, never overstated |
| Capability Discovery | Maps 19 capability categories (shell, filesystem, network, database, memory, MCP, ...) with evidence, confidence, and provenance |
| Capability Escalation Detection | Per-tool authority diffs between scans (new shell, read→write widening, new MCP server, removed approval gate, ...) — 14 rules, including gating-aware subsumption |
| AI Risk Analysis | Categorizes findings into 7 risk categories with weighted trust scoring (0–100) |
| Prompt Risk Analysis | Detects injection patterns, delimiter issues, system leak, role override |
| Governance Signal Detection | Detects missing operational controls: timeout, retry, approval, audit, rate limiting, circuit breaker, backpressure, health check (8 GOV_* rules) |
| Component-Level Analysis | Skills, prompt files, tool definitions, model configurations, workflow templates |
| Data-Flow Analysis | Tracks untrusted input propagation into sensitive sinks (prompts, tool calls, shell, file writes, HTTP, database); placeholder-aware confidence |
| Control Mappings | OWASP LLM / Agentic + NIST AI RMF mapping layer for framework-based filtering and grouping |
| Deep Claude Code Analysis | Structural analysis of .claude/settings.json, permissions, slash commands, subagents, hooks, .mcp.json |
| MCP Analysis | Discovers MCP servers, clients, tools, resources, and validates configuration |
| Data Leakage Detection | Flags hardcoded secrets, tokens, and API keys (redacted in all outputs) |
| KYA Shared Registry | Append-only SQLite registry of scan-derived agent records, shared org-wide; list/show/history/diff/export/components |
| Baseline & Escalation Gating | --fail-on-new for new/regressed findings, --fail-on-escalation for authority changes, --pr-comment PR summaries |
| Policy-as-Code & Suppressions | allow/warn/require_review/deny policy with selectors; required-reason suppressions |
| Assurance Boundary | Every scan states exactly what it did and could not verify — never a fixed disclaimer |
| Security Scorecard | Deterministic 0–10 score with per-category breakdown and pass/warn/fail outcome; informational unless you opt into --scorecard-fail-under gating — evidence and policy decide, the score does not |
| CI/CD Integration | SARIF 2.1.0 output, exit codes, GitHub Actions Marketplace action and workflow included |
| Community Scan | Governed private-pilot workflow for scanning public third-party agent frameworks with responsible disclosure (community-scans/) — private by default, human-reviewed before any publication |
| Multi-Format Reports | Terminal, JSON, SARIF 2.1.0, HTML, canonical KYA manifest, PR comment, Security Scorecard |
| Cross-File Analysis | Import graph, symbol resolution, and project graph |
| Confidence-Arbitrated Parsing | Multiple parsers per file, merged with provenance |
How It Works
Source Code
    │
    ▼
File Collection — Python, YAML, JSON, .prompt, and .claude configs;
                 prunes VCS, caches, oversized files, and SafeAI's own artifacts
    │
    ▼
Framework Detection — 16 parsers (AST + config + regex), all run on all files;
                     import graph and dependency manifests
    │
    ▼
Static Analysis — semantic docs, component extraction, capability / prompt /
                 data-leakage / MCP / Claude Code analyzers
    │
    ▼
Capability Mapping — per-tool identity (agent, MCP server, skill, tool,
                    workflow node) + access modes (read < write < mutate < execute)
    │
    ▼
Risk Rules — rule engine with severity, confidence, provenance, stable fingerprints
    │
    ▼
Trust Score — deterministic 0–100 score across 7 weighted risk categories
    │
    ▼
KYA Pipeline — finding normalization, suppressions, baseline (new/regressed),
              policy-as-code, capability escalation diff
    │
    ▼
Registry & Reports — shared SQLite registry; terminal, JSON, SARIF 2.1.0, HTML,
                     canonical manifest, PR comment
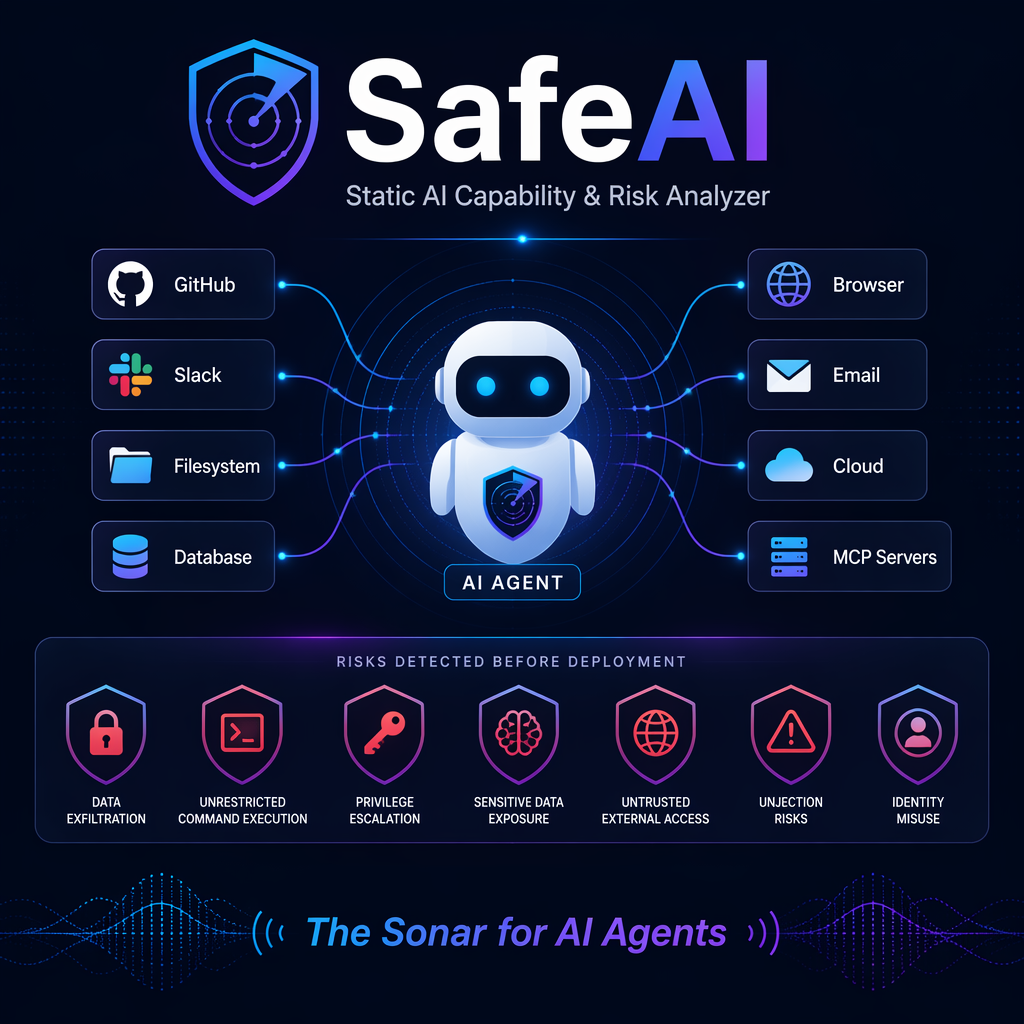
Supported Frameworks
| Framework | Detection | Discovery | Capability Analysis | Risk Analysis | Status |
|---|---|---|---|---|---|
| LangGraph | ✔ | Partial | Partial | Partial | Partial |
| CrewAI | ✔ | Partial | Partial | Partial | Partial |
| LangChain | ✔ | Partial | Partial | Partial | Partial |
| Semantic Kernel | ✔ | Partial | Partial | Partial | Partial |
| OpenAI Agents SDK | ✔ | Partial | Partial | Partial | Partial |
| Microsoft Agent Framework | ✔ | Partial | Minimal | Minimal | Experimental |
| Azure AI Foundry | ✔ | Minimal | Minimal | Minimal | Experimental |
| Bedrock Agent | ✔ | Minimal | Minimal | Minimal | Experimental |
| Claude Code | ✔ (deep) | Deep | Partial | Partial | Partial |
| Google ADK | ✔ | Partial | Minimal | Minimal | Experimental |
| Mastra | ✔ | Partial | Minimal | Minimal | Experimental |
| Haystack | ✔ | Partial | Minimal | Minimal | Experimental |
| LlamaIndex | ✔ | Partial | Minimal | Minimal | Experimental |
| Dify | ✔ | Minimal | Minimal | Minimal | Experimental |
| n8n | ✔ | Partial | Minimal | Minimal | Experimental |
| Cursor (.cursorrules) | ✔ | Minimal | Minimal | Minimal | Experimental |
| Windsurf (.windsurfrules) | ✔ | Minimal | Minimal | Minimal | Experimental |
| OpenClaw config | ✔ | Minimal | Minimal | Minimal | Experimental |
| GitHub Copilot instructions | ✔ | Minimal | Minimal | Minimal | Experimental |
Framework Support Details
- LangGraph — detects
StateGraph,add_edge,bind_tools, nodes, models - CrewAI — detects
Agent,Task, tools, models - AutoGen — detects
AssistantAgent,UserProxyAgent,register_for_llm,register_function, models - LangChain — detects
AgentExecutor,Chain,Tool,PromptTemplate, models - Semantic Kernel — detects
Kernel.invoke, plugins, functions, skills, memory - OpenAI Agents SDK — detects
Agent, tools, handoffs, MCP references - Microsoft Agent Framework — detects
AgentClient, tools, workflows, Azure models - Azure AI Foundry — detects YAML configurations with Azure resources
- Bedrock Agent — detects JSON configurations with Bedrock resources
- Claude Code — structural analysis of
.claude/settings.json, permission grants,.mcp.json, slash commands, subagent definitions, and lifecycle hooks - Google ADK — detects ADK agent, workflow, tool, and model patterns
- Mastra — detects Mastra agents, workflows, tools, and model references
- Haystack — detects Haystack pipelines, agents, tools, and retrievers
- LlamaIndex — detects agents, tools, indexes, and model references
- Dify — detects Dify workflow and agent configuration files
- n8n — detects n8n workflow exports, nodes, and connections
- Cursor (.cursorrules) — detects declared tools/permissions and capability-relevant keywords (shell, filesystem, HTTP, database) in the IDE's rules config, JSON, YAML, or free text
- Windsurf (.windsurfrules) — detects declared tools, models, and capability-relevant keywords in JSON, YAML, or free-text rules
- OpenClaw config — detects JSON/YAML files under
.openclaw/and.openclaw.yaml, including declared tools, models, and MCP servers - GitHub Copilot instructions — detects repository instruction Markdown,
YAML frontmatter, and
.copilot/*.ymltool or permission grants
Maturity is on the scale defined in docs/reference/FRAMEWORK_SUPPORT.md:
Partial = reliable detection and discovery with capability/risk analysis over
common patterns; Experimental = detection and basic artifact discovery with
limited framework-specific analysis. No framework is rated fully Supported
yet — SafeAI is in early preview and deliberately does not overclaim coverage.
Framework Test Coverage (v1.8.0)
Representative test fixtures and validation tests for framework detection:
| Framework | Test | Fixture | Contributor |
|---|---|---|---|
| LangGraph | test_langgraph_framework.py |
fixtures/langgraph/representative/graph.py |
@adnqcr7-code [#63] |
| LlamaIndex | test_llamaindex_framework.py |
fixtures/llamaindex/representative/agent.py |
@adnqcr7-code [#61] |
| CrewAI | test_crewai_framework.py |
fixtures/crewai/representative/crew.py |
@adnqcr7-code [#62] |
| Claude Code | test_claude_code_deep.py |
fixtures/claude_code/compatibility/ |
@adnqcr7-code [#59] |
| OpenClaw config | test_config_adapters.py |
fixtures/openclaw/representative/.openclaw/config.json |
@YaoSong808 [#159] |
| GitHub Copilot instructions | test_config_adapters.py |
fixtures/copilot/representative/.github/copilot-instructions.md |
@YaoSong808 [#159] |
Supported Capabilities
SafeAI fingerprints capabilities at the framework object level and via fallback regex patterns. Each capability includes evidence, confidence score, resolved definition, and provenance.
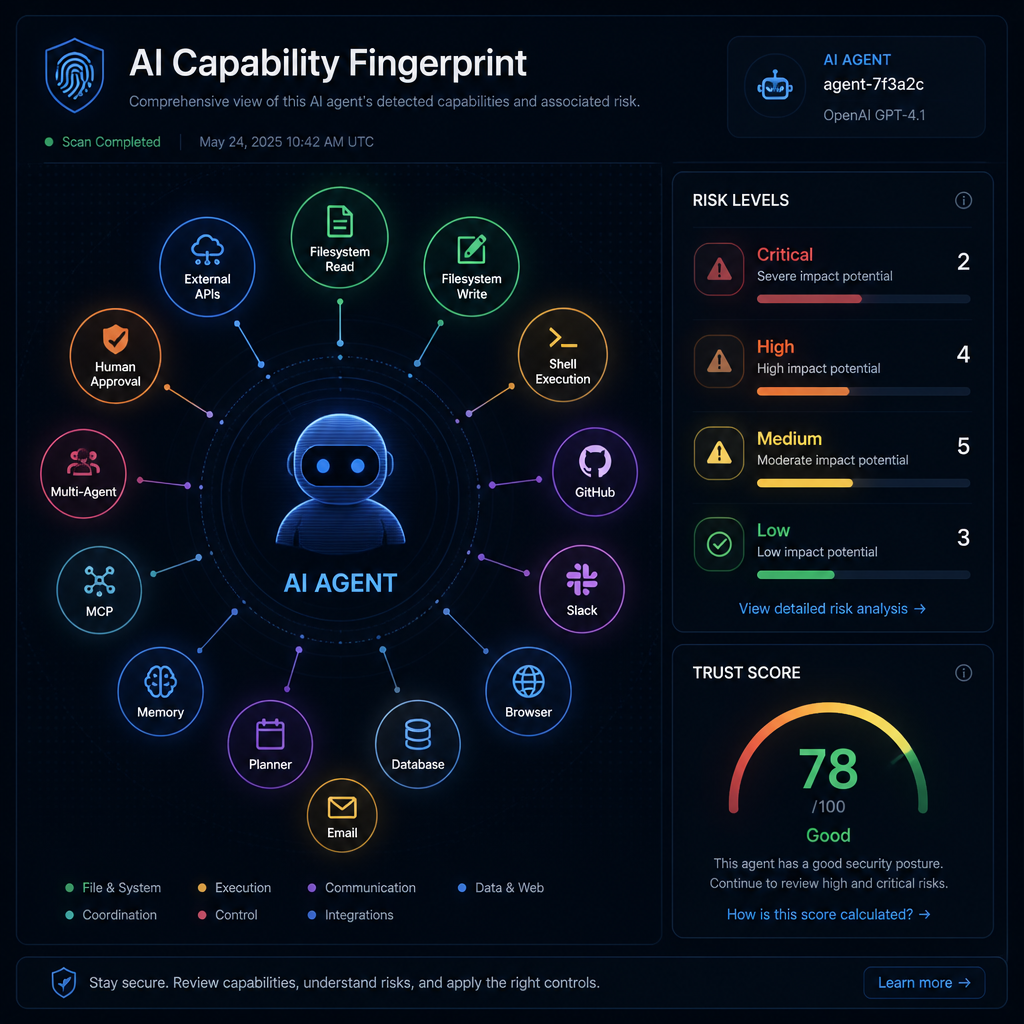
| Capability | Category | Risk Impact |
|---|---|---|
| Shell Execution | Shell | Command injection, host compromise |
| Filesystem Access | Filesystem | Data exfiltration, file tampering |
| Browser Automation | Browser | UI-based attacks, credential theft |
| Planning / Orchestration | Planner | Autonomous decision chain risk |
| Agent Delegation | Delegation | Unchecked sub-agent authority |
| Memory / Checkpoint | Memory | Data retention across sessions |
| RAG / Retrieval | RAG | Document exfiltration, prompt injection via documents |
| GitHub Integration | GitHub | Repository access, secret leakage |
| Slack Integration | Slack | Channel monitoring, message injection |
| Email Integration | Phishing, data exfiltration | |
| Database Access | Databases | SQL injection, data breach |
| Cloud Services | Cloud | Cloud resource abuse, cost escalation |
| External APIs | External APIs | Third-party data exfiltration |
| MCP Services | MCP | Exposed endpoints, unauthorized tool access |
| Human Approval | Human Approval | Approval bypass risk |
| Multi-Agent | Multi-Agent | Delegation-based privilege escalation |
| Container | Container | Container orchestration abuse (Docker, Kubernetes) |
| Collaboration | Collaboration | Cross-system coordination risk |
| Untrusted Input | Untrusted Input | Injection surface into agent pipelines |
Note: A capability is detected wherever the evidence lives — through a framework adapter, a direct pattern detector (for example Docker, Kubernetes, S3, Slack, Jira, browser automation, GCP), or MCP configuration analysis. Capabilities that only MCP configuration exposes today (e.g. email, human approval gates) are still flagged — the tool is reported with an unattributed identity rather than a guessed owner.
Know Your Agent (KYA) — Shared Registry
Every scan automatically builds a private "Know Your Agent" registry of
scan-derived agent records — no server, no account, no network call, no
source upload. Scans from every project accumulate in one shared SQLite
database (SAFEAI_REGISTRY env var or ~/.safeai/registry.db), so
safeai registry list shows the whole organization's agents from any folder.
safeai scan .                              # scan + accumulate into the shared registry
safeai scan . --manifest safeai-manifest.json   # also write the canonical KYA manifest
safeai scan . --html report.html                # interactive HTML report (risk gauge, escalations)
safeai registry list                       # agents/workflows from every scanned project
safeai registry list --format html > registry.html   # shareable HTML inventory
safeai registry show <agent-id>            # latest KYA record
safeai registry history <agent-id>         # all scans for an agent
safeai registry diff <agent-id> --from previous --to latest
safeai registry export --output inventory.json
safeai registry import inventory.json --dry-run
safeai registry import inventory.json       # atomic, idempotent merge
safeai registry export --format json --output inventory.json
safeai registry export --format html --output inventory.html
What you get on the first run:
- A static scan ran successfully.
- The shared registry was initialized (
SAFEAI_REGISTRYor~/.safeai/registry.db). - One or more KYA agent records were created with stable identities.
- Findings carry confidence, provenance, remediation, and stable fingerprints.
- No source code or secrets are uploaded or stored in output artifacts.
KYA records static evidence, not runtime truth. It answers "what does the source/configuration say this agent can do?" — never "what is this agent doing in production?" See docs/reference/REGISTRY.md, docs/reference/KYA_MANIFEST.md, and docs/reference/LIMITATIONS.md.
CI note: registry persistence is auto-disabled for bare CI jobs (the CI
env var). Use --registry "$RUNNER_TEMP/registry.db", set SAFEAI_REGISTRY
to a shared path, or use --no-registry for ephemeral scans.
Installation
Requirements
- Python 3.11, 3.12, or 3.13
- PyYAML (for YAML configuration parsing)
Install from PyPI (recommended)
pip install SafeAI-Static-Analyzer
Unpinned on purpose — this always resolves to the latest stable
release (see releases).
Verify the download with docs/reference/VERIFICATION.md.
Install from source
git clone https://github.com/ikaruscareer/SafeAI.git
cd SafeAI
pip install -e .
Install development dependencies
pip install -e ".[dev]"
Privacy & Telemetry
SafeAI collects no data by default. Usage telemetry is opt-in, anonymous, and fully documented in PRIVACY.md. If you do nothing, nothing is ever sent. See PRIVACY.md for the complete data contract, what is never collected, and how to disable telemetry.
CLI Usage
python -m safeai scan <directory> [options]
python -m safeai registry <subcommand> [options]
Options
| Option | Default | Description |
|---|---|---|
directory |
required | Path to scan |
--sarif |
report.sarif |
SARIF output path (empty string to skip) |
--json |
— | JSON output path |
--html |
— | HTML report output path |
--manifest |
— | Canonical KYA manifest output path (safeai-manifest.json) |
--digest-file |
— | With --manifest: write <canonical-sha256> <manifest-basename> to this path. The digest is the one safeai manifest verify reports, not a raw file hash, so it is not sha256sum -c compatible |
--baseline |
— | Prior manifest/report for new/existing comparison |
--fail-on-new |
off | With --baseline: fail only on new/regressed findings |
--policy |
.safeai/policy.yml |
Policy-as-code YAML file |
--suppressions |
.safeai/suppressions.yml |
Suppressions YAML file |
--registry |
shared (SAFEAI_REGISTRY/~/.safeai/registry.db) |
Registry database path |
--no-registry |
off | Skip registry persistence |
--strict-registry |
off | Fail the scan if registry persistence fails |
--pr-comment |
— | Write a reviewer-facing Markdown summary of capability escalations to this path (never posted anywhere) |
--pr-comment-stdout |
off | Print the PR comment Markdown to stdout |
--fail-on-escalation |
— | Fail if a capability escalation at or above critical, high, or medium is detected (requires --baseline) |
--scorecard / --scorecard-md |
— | Write the SafeAI Security Scorecard as Markdown to this path |
--scorecard-json |
— | Write the SafeAI Security Scorecard as JSON (conforms to safeai/scorecard-schema.json) |
--scorecard-summary |
— | Append the Security Scorecard to the GitHub Actions step summary ($GITHUB_STEP_SUMMARY) |
--scorecard-fail-under |
— | Fail the scan if the Security Scorecard score is below this value (0–10) |
--rules |
built-in | Custom rules directory |
--fail-on |
critical |
Exit code threshold: critical, high, medium |
--verbose |
— | Enable verbose output |
Exit Codes
| Code | Condition |
|---|---|
| 0 | No findings at or above threshold; policy outcome not deny |
| 1 | Finding at or above threshold, or policy outcome deny |
| 2 | Operational error (e.g. --strict-registry persistence failure) |
Suppressed findings never trigger exit code 1. With --fail-on-new, only
findings classified new or regressed against the baseline are gated.
Common 1.4 Workflows
# canonical manifest + baseline seed
python -m safeai scan . --manifest safeai-manifest.json

# CI/PR scan: fail only for new or regressed findings
python -m safeai scan . --baseline safeai-manifest.json --fail-on-new --fail-on high

# CI/PR scan: fail on capability escalations and render a PR comment
python -m safeai scan . --baseline safeai-manifest.json \
  --fail-on-escalation high --pr-comment comment.md

# inspect the shared KYA registry
python -m safeai registry list
python -m safeai registry show <agent-id>
python -m safeai registry history <agent-id>
python -m safeai registry diff <agent-id> --from previous --to latest
python -m safeai registry export --format json --output safeai-kya-inventory.json
Example Output
See docs/guides/REPORTING_GUIDE.md for a complete guide to interpreting each output format (HTML, JSON, SARIF, PR comments, scorecard, registry) and triaging findings.
Terminal
SafeAI Scan Summary
Files: 12
Frameworks: langgraph, crewai
MCP assets: 2
Overall AI Risk Score: 73
critical: 1
high: 3
medium: 5
Findings:
[critical] app.py:10 - Untrusted input interpolated into prompt
[high] app.py:22 - Capability detected: shell_execution
[high] mcp.json:1 - MCP configuration does not define authentication
Example: LangGraph agent with MCP
{
  "Framework": "LangGraph",
  "Capabilities": ["Planner", "Memory", "Filesystem", "MCP"],
  "Risk Score": 73,
  "Findings": 9,
  "Critical": 1,
  "High": 3
}
CI/CD Integration
SafeAI ships a GitHub Actions Marketplace action and supports all major CI platforms.
# GitHub Actions — minimal workflow
name: safeai-scan
on: [push, pull_request]
permissions:
  contents: read
jobs:
  scan:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-python@v5
        with: { python-version: '3.12' }
      - uses: ikaruscareer/SafeAI@v2
        with: { path: '.', fail-on: critical }
      - uses: github/codeql-action/upload-sarif@v3
        if: always()
        with: { sarif_file: ${{ steps.safeai.outputs.sarif-path }} }
See CI/CD Integration Guide for GitHub Actions, GitLab CI, Azure DevOps, and escalation-gating examples.
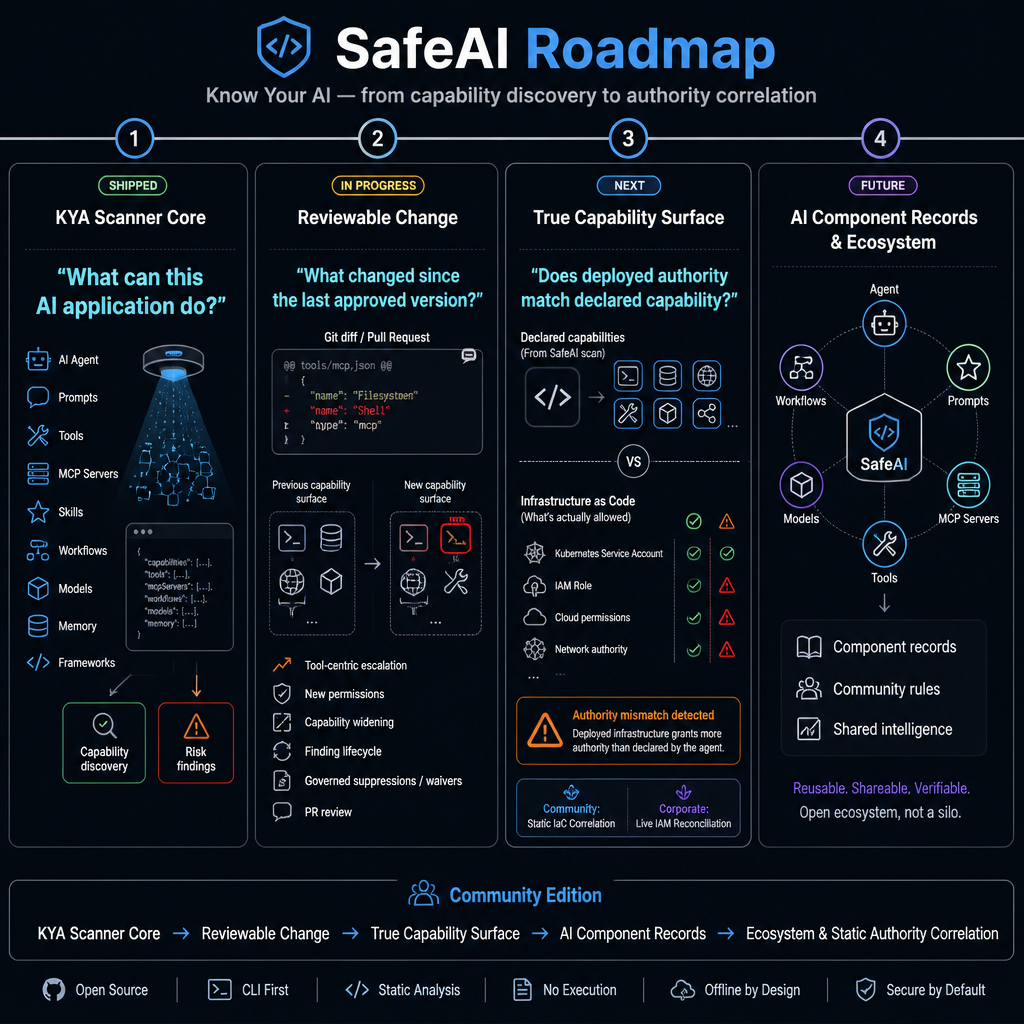
Roadmap
See ROADMAP.md for the detailed roadmap.
- Completed in 1.3: KYA manifest, baseline/new-regressed gating, suppressions, policy-as-code, local SQLite registry, registry CLI.
- Completed in 1.4 (beta): tool-centric capability model (tool identity
- access modes), 14 capability escalation rules, capability diff v2, deep Claude Code analysis, PR comment + CI context, assurance boundary, registry schema v2, shared org-wide registry default.
- Completed in 1.5: environment/credential dependency inventory and
dependency-to-capability correlation, first stable release
(
1.5.0, classifier5 - Production/Stable), and a GitHub Actions Marketplace action (action.ymlcomposite action plus a validatedscripts/safeai-action.pydriver andaction-test.ymlCI workflow). - Completed in 1.9.0: component version/hash in registry,
safeai init, governance signal detection (8GOV_*rules including circuit breaker, backpressure, health check), control mappings (OWASP LLM/Agentic + NIST AI RMF), AutoGen + LangGraph adapter completion, heuristic data-flow analysis with placeholder-aware confidence, browser automation rule split. - Next focus: adapter depth improvements, richer dataflow/context precision, and optional enterprise-scale workflows.
Community Contributors
SafeAI is built by and for the AI security community. Thank you to all contributors who have helped make AI safer:
| Contributor | Key Contributions |
|---|---|
| @i-safonoff | .cursorrules framework adapter, rule_coverage_summary(), RULES_REFERENCE.md, dataflow casing fix |
| @ARAVIND281 | Claude Code permission evaluation order, interprocedural data-flow tracking |
| @Solarthis | MCP tool description injection detection |
| @Aming9303 | safeai registry components CLI, safeai init command, GitHub Actions example |
| @adnqcr7-code | Framework detection tests (LangGraph, CrewAI, LlamaIndex, n8n, Claude Code), CI/SARIF docs |
| @hadbiaghiles | AutoGen framework documentation |
| @D05TL3 | GitHub Actions scanning example |
| @mikemikimike | Adapter negative detection tests |
| @burakeyler | --digest-file manifest digest sidecar (PR #148) |
| @YaoSong808 | OpenClaw and GitHub Copilot config-file adapters (PR #159) |
| @mah | Claude Code deep analysis documentation |
| @asarakhatun17-lgtm | Supported frameworks consistency fix |
| @yugaaank | Capability detectors (Docker, Kubernetes, Redis, S3, GCP, Slack, Jira, browser) |
| @Teachmeplaycode | Benchmark corpus expansion, static subprocess precision gap documentation (PR #174) |
| @nikitajos7 | Policy profile display in terminal and HTML reports (PR #175) |
See CONTRIBUTING.md for how to get involved.
Documentation
| Document | Description |
|---|---|
| Roadmap | Future plans and feature requests |
| Contributing | How to get involved |
| Security | Vulnerability reporting and response |
| Privacy | Telemetry and data handling |
| Release Notes | Changelog for all versions |
| Governance & Editions | Community vs Corporate boundary and non-negotiables |
| DCO | Contribution sign-off (Developer Certificate of Origin) |
| Upgrade Guide | v1.x → v2.0.0 migration |
| CI/CD Integration | GitHub Actions, GitLab CI, Azure DevOps examples |
License
SafeAI is released under the Apache 2.0 License.
1 maintainer

Release files for SafeAI-Static-Analyzer 2.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| safeai_static_analyzer-2.4.0.tar.gz | 386.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| safeai_static_analyzer-2.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 701.6 kB
Release files / safeai_static_analyzer-2.4.0.tar.gz
| Download URL | safeai_static_analyzer-2.4.0.tar.gz |
|---|---|
| Size | 386.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b7b1b607cea76ad6ae988c6653a4f6cb2e9b72f4e81c38a98ba8186f38f988c1
|
|
BLAKE2b-256 checksum How to use checksums |
e1b05b53aa86d92ba843034e5978f35d76c677a323080419dd0b3b8787a00d0b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 22, 2026.
Transparency logRelease files / safeai_static_analyzer-2.4.0-py3-none-any.whl
| Download URL | safeai_static_analyzer-2.4.0-py3-none-any.whl |
|---|---|
| Size | 315.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
52c6eff32ec8e3885816a9b01c35ca788dc7fddb66b4b867b1b7177b4b919ebf
|
|
BLAKE2b-256 checksum How to use checksums |
2e3408c76c27593416671ce4de9fab83945131b683f358c4e1a2b00033f52d87
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 22, 2026.
Transparency log













