

43 compression methods — quantizers, token-eviction caches, cross-layer merging — in MLX





veloxquant.dev — Quickstart · All 43 methods · Playground · Contributing
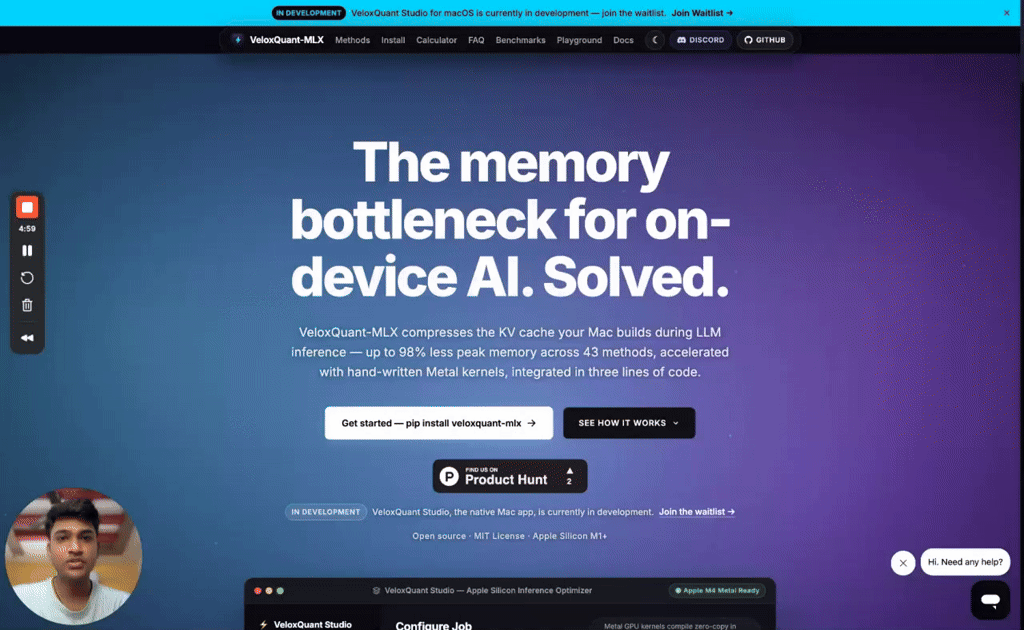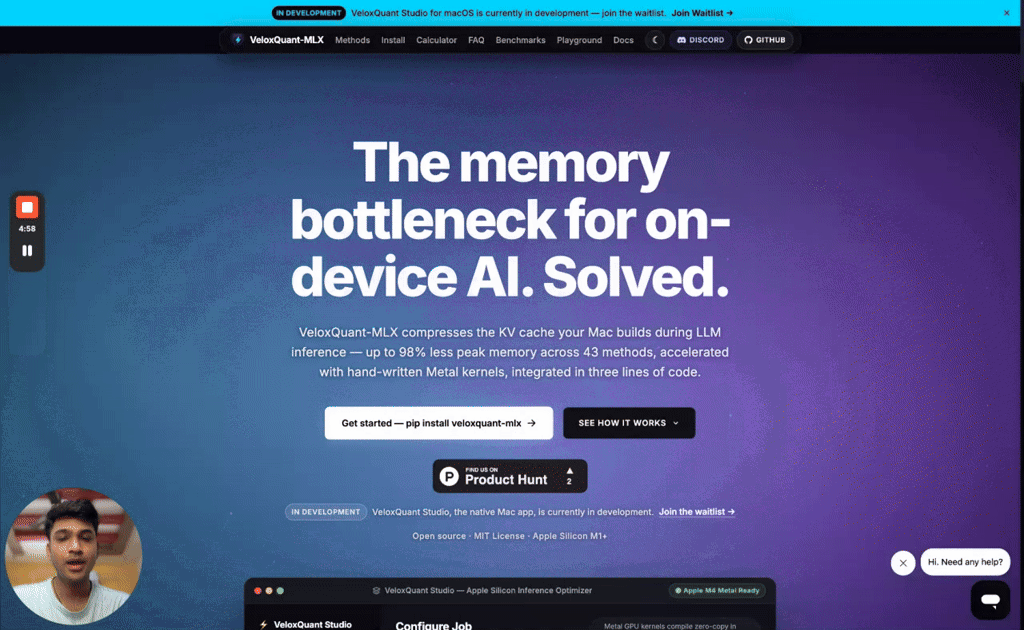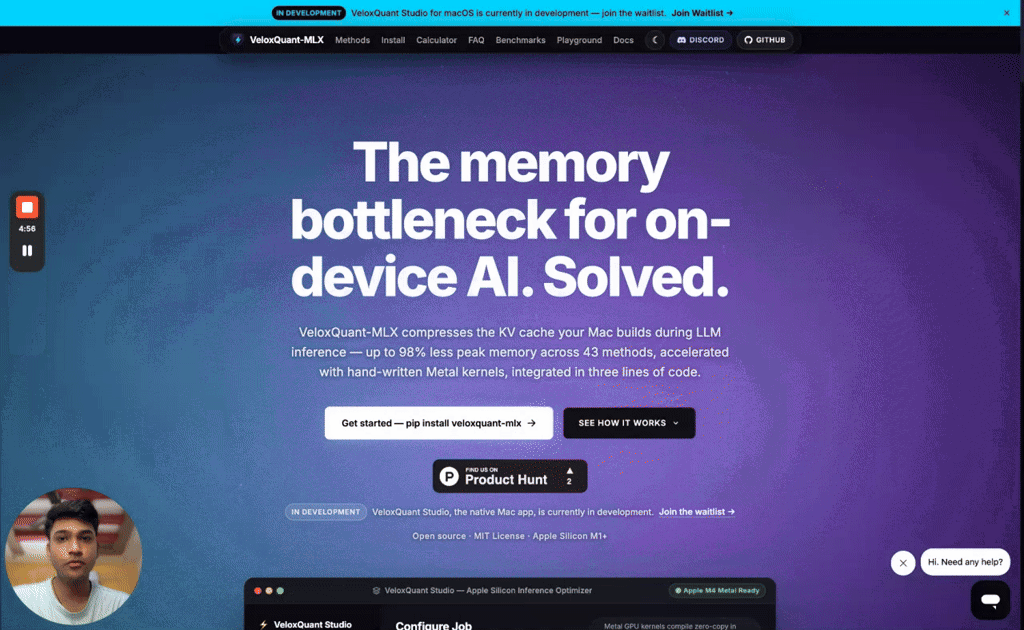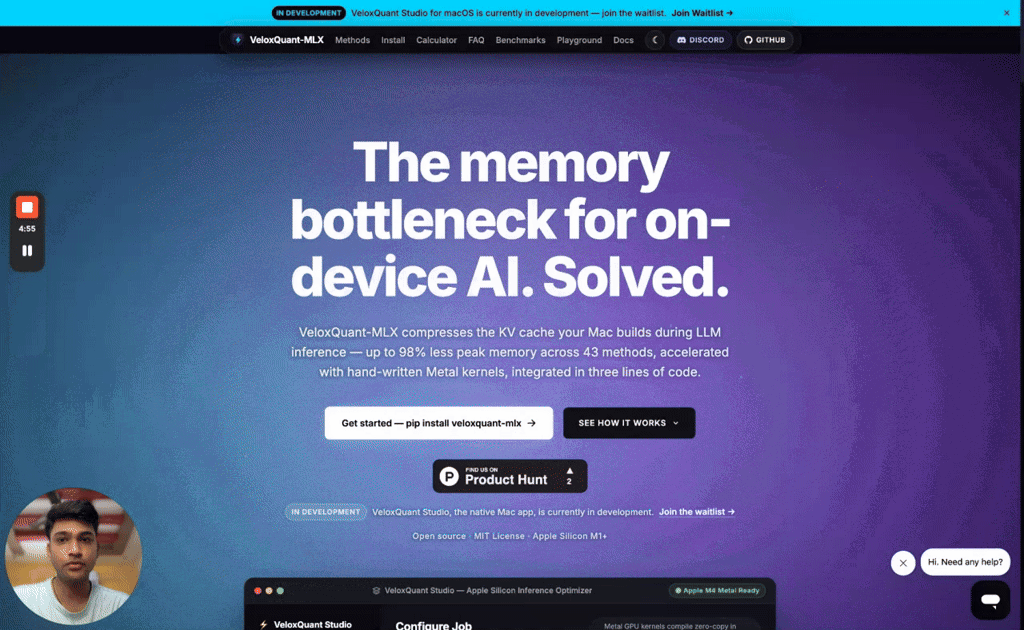
VeloxQuant-MLX shrinks the KV cache of any mlx_lm model on Apple Silicon, up to 16× smaller with near-lossless quality, in three lines of code. If you run models locally and keep hitting a context-length or memory wall, you swap in a compressed cache and change nothing else about the model.
Inside are 43 compression methods, each adapted from a published paper, spanning zero-calibration 1-bit quantizers, token-eviction caches, and cross-layer merging. All of them share the same 3-line API, so switching means changing method="...". The hot path runs on hand-written Metal kernels (up to 14.7× faster quantize), and it's validated on 12 production models (Llama, Mistral, Qwen, Phi, Gemma 3/4, Falcon) plus vision-language models via mlx-vlm.
Compression ratios are bit-width accounting, not measured RSS. Most methods still store fp16 internally on the default serving path, so Activity Monitor won't drop by the same factor; eviction/merging methods (marked 🔻RSS below) do reduce resident memory today. Details: #27.
Numbers
| Metric | Value | Notes |
|---|---|---|
| Max key cache compression | 16× | VecInfer-1bit, head_dim=128 |
| Metal kernel speedup | 13× | quantize_vq at S=2048 (range 6.9–14.7×) |
| Peak memory reduction | 98% | 729 MB → 12 MB, Falcon3-7B shape |
| RVQ-1bit compression | 7.5× | Near-zero throughput cost |
| FP16 throughput retained | 100% | Qwen2.5-7B at 16× compression |
| Production models validated | 12 | Llama, Mistral, Qwen, Phi, Gemma 3/4, Falcon |
Full metric table, including RaBitQ / CommVQ / KIVI / SpectralQuant figures and methodology: BENCHMARK_RESULTS.md.
Table of contents
Installation · Quickstart · Method library · Metal kernels · Benchmarks · Architecture · CLI · Development · Governance · Ecosystem · Docs · Support
Installation
pip install VeloxQuant-MLX
Requirements: Apple Silicon M1+, Python ≥ 3.11, MLX ≥ 0.18, NumPy ≥ 1.26.
Source install, conda/miniforge, Metal troubleshooting, and verifying the install are covered in the installation guide.
Quickstart
Python — RVQ 1-bit, 7.5× compression, no calibration (recommended default):
import mlx_lm
from veloxquant_mlx import KVCacheBuilder, KVCacheConfig

model, tokenizer = mlx_lm.load("mlx-community/Mistral-7B-Instruct-v0.3-4bit")

config = KVCacheConfig(method="turboquant_rvq", bit_width_inlier=1, seed=42)
caches = KVCacheBuilder.for_model(model, config)
model.make_cache = lambda *_a, **_k: caches

response = mlx_lm.generate(model, tokenizer, prompt="Explain relativity simply.", max_tokens=200)
No Python — the control panel:
veloxquant panel # local web UI at http://127.0.0.1:7860
Pick a model and a method, press Start Server, and point any OpenAI-compatible
client (Claude Code, Cursor, the OpenAI SDK) at the URL it gives you. It drives
veloxquant serve, usable directly too — see docs/control-panel.md.
Next: the 5-minute quickstart · mixed-precision guide · mlx_lm integration
Method library
Every one of the 43 methods drops in the same way: set method="<id>" in
KVCacheConfig. The algorithm overview
has the full comparison table, a decision tree, per-model recommendations, and
for each method its mechanism, config, evidence, and limitations.
If you want a starting point:
- No calibration, best default →
turboquant_rvqb=1 (7.5×, 0.92 cosine) - Max compression, Qwen2.5/Gemma →
vecinfer1-bit (16×, Metal-accelerated) - Best quality at moderate compression →
spectralb=3 (5.33×, ~5s calibration) - Heterogeneous layers (sensitivity ratio >2×) → RateQuant on top of RVQ
- Max context length, fixed RAM →
rabitqkeys + MSE-b4 values (6× full KV) - RoPE-compatible exact VQ →
comm_vq(ICML 2025, 64× key compression) - Hard cap on token count, fixed RAM →
h2oorsnapkv(eviction, reduces resident memory)
The 43 methods fall into three families:
- Quantization (22) — compress every token. Default
turboquant_rvq; also VecInfer, SpectralQuant, RateQuant, RaBitQ, QJL, PolarQuant, CommVQ, KIVI, SVDq, KVQuant-NUQ, GEAR, and more. - Low-rank & cross-layer (6) — compress across dimensions or depth. PALU, XQuant, MiniCache, xKV, AdaKV, KVTC.
- Token eviction & merging (15, 🔻RSS) — drop or merge low-value tokens; these reduce resident memory today. SnapKV, StreamingLLM, H2O, TOVA, PyramidKV, SqueezeAttention, ChunkKV, Keyformer, KVzip, and more.
Every method links to its own page, with mechanism, config, evidence, and limitations, on the algorithm overview.
Every "-adapted" method is an adaptation, not a 1:1 port: the cache sees only per-layer K/V, never the model's real attention maps, so attention-based signals use a key-as-query proxy.
Metal kernels
VecInfer's quantize_vq was the slowest step in the pipeline, so it now runs on the
GPU. It's JIT-compiled by mx.fast.metal_kernel on first call, with the same Python
API — no code changes needed to benefit.
| Metric | Pure MLX | Metal kernel | Delta |
|---|---|---|---|
| Quantize latency (S=8192) | 228 ms | 15.6 ms | 14.7× faster |
| Peak memory (Falcon3-7B shape) | 729 MB | 12 MB | 98% reduction |
The memory win comes from what never gets written out: the pure-MLX version
materializes an [N, n_centroids, sub_dim] diff tensor, while the kernel keeps the
argmin accumulator in thread-local GPU registers.
A second set of kernels forms a fully GPU-resident RaBitQ pipeline — 1-bit packed keys scored via XOR+popcount, 4-bit codebook values, fused into one dispatch (1.78× vs dequantize+SDPA at S_kv=8192).
Caveat: kernels pay ~50–200 µs launch overhead per call. On tiny models (SmolLM2-135M, ~60 launches/token) that can exceed the savings. Built for 7B+ at realistic context lengths.
How they were built: blogs/metal-kernels.md · Usage and debugging: docs — Metal GPU kernels
Benchmark results

End-to-end
mlx_lm.generate · 200-token prompt · 120-token generation · Apple M-series unified memory
10-model study, VecInfer vs RVQ (v0.5.0) — compression and throughput, tok/s:
| Model | fp16 | RVQ-1bit (7.5×) | VecInfer-1bit (16×) |
|---|---|---|---|
| Llama-3.2-3B | 47.6 | 46.2 | 40.2 |
| Llama-3.1-8B | 20.5 | 20.6 | 19.6 |
| Mistral-7B | 23.6 | 22.8 | 9.8 |
| Qwen2.5-7B | 21.0 | 20.7 | 21.5 ⬆ exceeds fp16 at 16× |
| Qwen3-8B | 20.3 | 19.6 | 2.4 |
| Falcon3-7B | 17.3 | 21.7 | 17.0 |
RVQ-1bit is the safe default: within 5% of fp16 on most 7–8B models, zero calibration. VecInfer-1bit wins on memory (always 16×) and on throughput for strong-GQA models (Qwen2.5, Gemma), but degrades badly on others — see the full table before choosing it.
All 10 models, compression ratios, historical snapshots, and methodology: BENCHMARK_RESULTS.md.
Architecture
Every method runs the same three-step pipeline: rotate the K/V tensors into a friendlier basis, quantize them (optionally with a residual pass for extra precision), then pack the bits. That is why swapping method="..." just works. Every quantizer plugs into the same KVCacheConfig → KVCacheBuilder → mlx_lm-compatible cache path regardless of what it does internally.
The wiring underneath is conventional object-oriented plumbing, plus some custom data structures for the bit-packing. Pipeline diagrams (TurboQuantRVQ, VecInfer) and the design-pattern breakdown are in docs — Core concepts.
CLI
# Which method should I use on my Mac?
python -m veloxquant_mlx recommend \
    --chip M4 --ram-gb 16 --model-class 7B --goal everyday

# Hardware-aware config for a specific workload shape
python -m veloxquant_mlx auto-config \
    --head-dim 128 --seq-len 32000 --n-layers 32 --batch-size 4 --json

# Synthetic benchmark — single config
python -m veloxquant_mlx benchmark \
    --method turboquant_rvq --head_dim 128 --bits 2 --seq_len 1000

# Precompute rotation matrices, JL matrices, codebooks
python -m veloxquant_mlx precompute \
    --head_dim 128 --bits 1 2 3 4 --jl_dim 128 --seed 42 --output_dir ./artifacts/
recommend is accounting-aware: it reports the key compression ratio and flags
when resident RAM savings are unlikely, rather than quoting a ratio that won't show
up in RSS. Goals: everyday, max_key_accounting, max_context, best_quality,
constant_memory. Add --json for machine-readable output. Also in the browser via
the Compression Lab.
Full CLI reference, including loading precomputed artifacts to skip runtime computation: docs — CLI.
Development
# Full test suite (includes Metal parity tests)
pytest veloxquant_mlx/tests/ -v

# 2-bit improvement validation — fast synthetic run
python benchmark_scripts/test_2bit_improvements.py

# Generate optimization-journey figure
python scripts/plot_optimization_journey.py
Contributions welcome. Open an issue first for anything beyond a small bugfix. See CONTRIBUTING.md for guidelines and CHANGELOG.md for release history.
Project & governance
These policies already governed the project. This section makes them reachable from the README rather than only from the file tree.
| Security policy | SECURITY.md — private disclosure by email, acknowledgement within 72 hours, confirmed issues resolved within 14 days, reporters credited in release notes |
| Governance | GOVERNANCE.md — decision-making, contribution path, and how co-maintainers are added |
| Code of conduct | CODE_OF_CONDUCT.md |
| Contributing | CONTRIBUTING.md — open an issue before anything beyond a small bugfix |
| Citations & provenance | CITATIONS.md — every method traced to its paper, with deviations documented |
| Release process | Automated via python-semantic-release; every release is gated on the full test suite. See CHANGELOG.md |
Maintainership: I maintain this project (rajveer43) with one other active contributor — a key-person risk worth weighing if you're evaluating it for production. GOVERNANCE.md covers how co-maintainers are added.
Lint and the non-Metal unit suite run on CI for every push; the full suite, including Metal parity tests that need Apple Silicon, gates each release.
Documentation & blog posts
Full docs, including per-method pages, guides, and API reference: https://veloxquant.dev/
Deep-dive writeups live in blogs/ and are published on the docs site:
overview ·
10-model study ·
hands-on tutorial ·
KIVI ·
Metal kernels ·
results ·
TensorOps research
Ecosystem
This repo is the Python engine. Client SDKs in other languages talk to a running
veloxquant serve instance (hardware detection, KV-cache estimation, and
OpenAI-compatible local inference), so you can drive it from whatever stack you
already have.
| Language | Package | Install | Source |
|---|---|---|---|
| TypeScript / JS | @veloxquant/sdk |
npm i @veloxquant/sdk |
veloxquant-sdk |
| Rust | veloxquant |
cargo add veloxquant |
veloxquant-rs |
| Go | veloxquant-go |
go get github.com/rajveer43/veloxquant-go |
veloxquant-go |
| Kotlin / JVM | JitPack | com.github.rajveer43:veloxquant-kotlin |
veloxquant-kotlin |
| Swift | SPM | .package(url: "...veloxquant-swift", from: "0.1.0-alpha") |
veloxquant-swift |
There's also a VS Code extension (source) that recommends compression settings and opens the compression lab without leaving the editor.
The Rust crate ships as
veloxquantplus focused sub-crates (veloxquant-core,-memory,-system,-runtime,-openai,-monitor) if you want a narrower dependency. Kotlin and Swift are at0.1.0-alpha.
Beyond compression: cross-model KV transfer
One capability in this repo is not a compression method and is deliberately
not counted in the 43: cross-model KV cache transfer
(veloxquant_mlx.transfer). Instead of shrinking one model's cache, it maps a
source model's already-prefilled KV into a target model's format, so the
receiver can skip prefill when you swap between two models in the same family.
Cache size is unchanged; what you save is prefill compute.
It lives in its own subsystem rather than behind method="..." because it needs
two models, an offline per-pair fit, and a multi-GB artifact, none of which the
single-model cache contract can express. Adapted from
Cross-Model KV Cache Transfer (NVIDIA, arXiv:2608.03893).
The paper's retention and speedup figures are its own, measured on
datacenter-scale pairs, and are not reproduced here. Read the
docs page
for the caveats before relying on it.
References
43 methods, each adapted from a published paper with documented deviations — 39 from peer-reviewed venues, 2 from preprints as stated exceptions. Full bibliography and per-method provenance: CITATIONS.md.
Headline references: TurboQuant (ICLR 2026), VecInfer (2024), RaBitQ (SIGMOD 2024), CommVQ (ICML 2025), KVzip (NeurIPS 2025), KVTC (ICLR 2026), CurDKV (NeurIPS 2025). Built on Apple MLX.
Support
VeloxQuant-MLX is free and MIT-licensed. There is no commercial offering and no revenue behind it. Funding is not required to use it and never gates a feature; it buys maintenance time.
- Stars, issue reports, and PRs are the most useful contribution. They tell me what breaks on hardware I do not have.
- Want to help fund it? Buy me a chai ☕ or tip on Ko-fi 💜.
- Found a vulnerability? Do not open a public issue; follow SECURITY.md instead.
- Citing this work: DOI 10.5281/zenodo.20647294, with per-method attributions in CITATIONS.md.
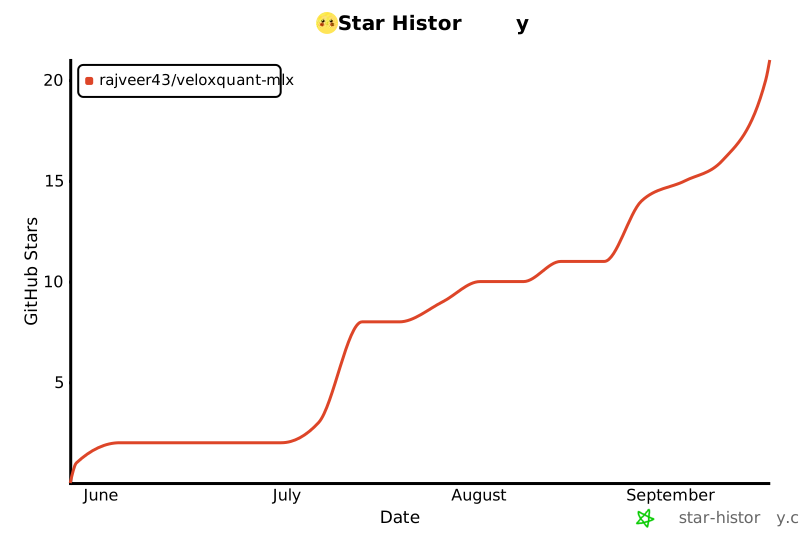
Star History
License
MIT — see LICENSE.
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file veloxquant_mlx-0.83.20.tar.gz.
File metadata
- Download URL: veloxquant_mlx-0.83.20.tar.gz
- Upload date:
- Size: 1.0 MB
- Tags: Source
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
8e3e1b97cc8cc3ad9f48131cc1603020b7b35bf17b0272ab296d878e61d7a4df
|
|
| MD5 |
dfc96e4fc1ca7b2c21c6dfc7dac42faf
|
|
| BLAKE2b-256 |
affc3b3276923e035896979bc96df45cbfd2a043b6904641c2f676e7e575d1b9
|
Provenance
The following attestation bundles were made for veloxquant_mlx-0.83.20.tar.gz:
Publisher:
release.yml on rajveer43/VeloxQuant-MLX
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
veloxquant_mlx-0.83.20.tar.gz -
Subject digest:
8e3e1b97cc8cc3ad9f48131cc1603020b7b35bf17b0272ab296d878e61d7a4df - Sigstore transparency entry: 2849381347
- Sigstore integration time:
-
Permalink:
rajveer43/VeloxQuant-MLX@d842ee73857ad6cd895aa7f36c2000aa177a6c99 -
Branch / Tag:
refs/heads/master - Owner: https://github.com/rajveer43
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@d842ee73857ad6cd895aa7f36c2000aa177a6c99 -
Trigger Event:
push
-
Statement type:
File details
Details for the file veloxquant_mlx-0.83.20-py3-none-any.whl.
File metadata
- Download URL: veloxquant_mlx-0.83.20-py3-none-any.whl
- Upload date:
- Size: 1.3 MB
- Tags: Python 3
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
843fda25c4f6965cbab71f81f96ddb384b51aaf32fcc3b8215b452436044e90d
|
|
| MD5 |
8d8f3a880a52e66022c6992a7f6331e1
|
|
| BLAKE2b-256 |
257c6f05304be31f76fd164c320a81783143b4398781f19372bcf0f29adfcdc7
|
Provenance
The following attestation bundles were made for veloxquant_mlx-0.83.20-py3-none-any.whl:
Publisher:
release.yml on rajveer43/VeloxQuant-MLX
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
veloxquant_mlx-0.83.20-py3-none-any.whl -
Subject digest:
843fda25c4f6965cbab71f81f96ddb384b51aaf32fcc3b8215b452436044e90d - Sigstore transparency entry: 2849381380
- Sigstore integration time:
-
Permalink:
rajveer43/VeloxQuant-MLX@d842ee73857ad6cd895aa7f36c2000aa177a6c99 -
Branch / Tag:
refs/heads/master - Owner: https://github.com/rajveer43
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@d842ee73857ad6cd895aa7f36c2000aa177a6c99 -
Trigger Event:
push
-
Statement type:














