
🐝 abcopt
Canonical Artificial Bee Colony (ABC) optimization for Python, with a scikit-learn compatible hyperparameter search.


abcopt implements the Artificial Bee Colony algorithm of Derviş Karaboğa (2005) step for step as in the reference implementation published by the ABC research group at Erciyes University, and wraps it in ABCSearchCV, a drop-in alternative to GridSearchCV and RandomizedSearchCV.
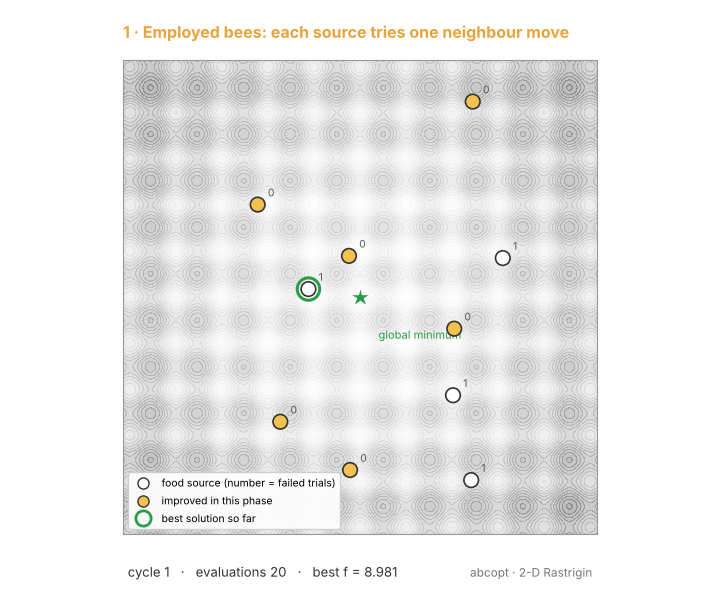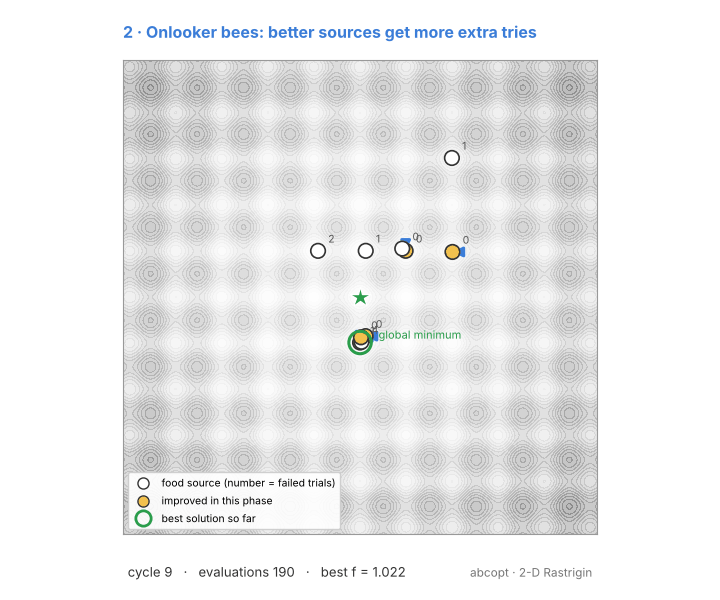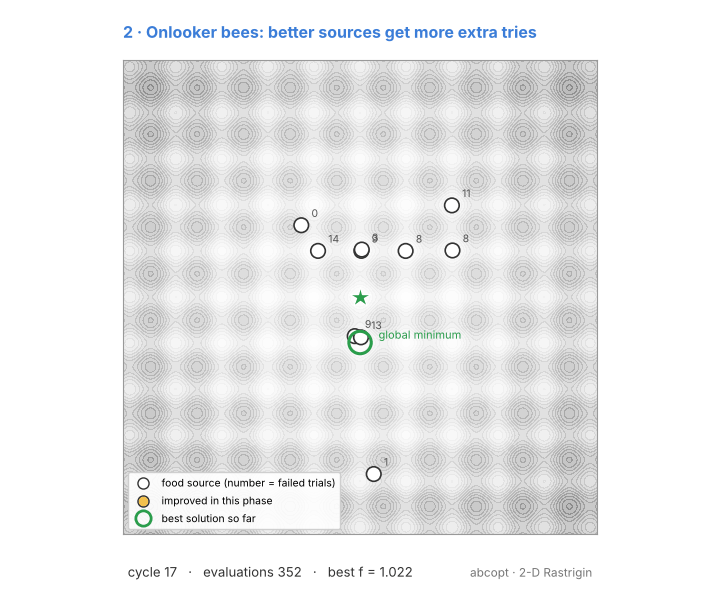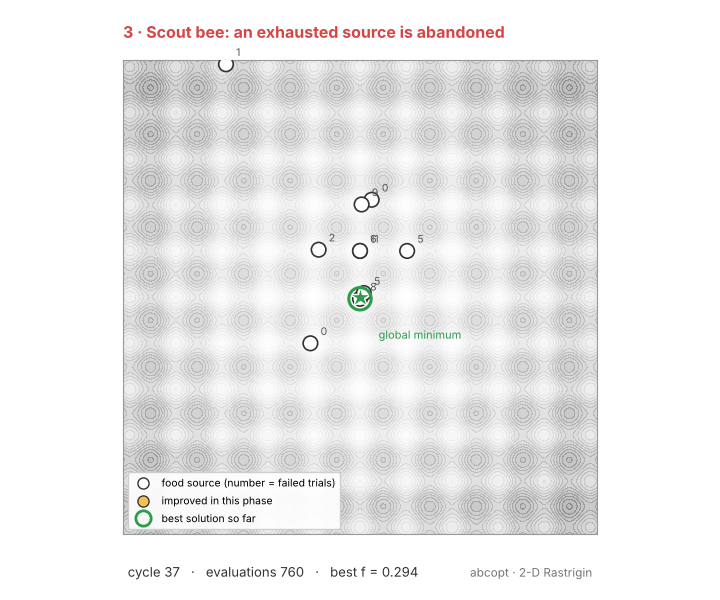
A real CanonicalABCSolver run on the 2-D Rastrigin function (many local minima, one global minimum ★).
Employed bees move one dimension at a time, onlookers revisit the best sources, and a scout restarts an exhausted source at a random spot.
Numbers are failed-trial counters. Generated by docs/make_animation.py.
Highlights
- Verified canonical ABC. A test runs abcopt and the Erciyes University reference code on the same random-number stream and checks that both evaluate identical points and return identical results.
- scikit-learn native.
ABCSearchCVprovidesfit,predict,predict_proba,score,best_params_,best_estimator_and acv_results_table in the same format asGridSearchCV. - Mixed search spaces. Continuous (optionally log-scaled), integer and categorical hyperparameters.
- No wasted runs. Configurations that ABC proposes twice are served from a cache, which roughly halves tuning time on discrete spaces without changing the search.
- Reproducible and predictable. Fixed evaluation budget (
max_evals) andrandom_statefor identical runs. - Lightweight. Depends only on
numpyandscikit-learn.
Contents: Installation · Quick start · How ABC works · Benchmark · API reference · Notes and limitations · Examples · Citation
Installation
pip install abcopt
Requires Python 3.9+, NumPy and scikit-learn.
Quick start
Tune a scikit-learn model
from sklearn.datasets import load_breast_cancer
from sklearn.ensemble import HistGradientBoostingClassifier
from abcopt import ABCSearchCV

X, y = load_breast_cancer(return_X_y=True)

param_space = {
    "learning_rate":    {"type": "float", "range": (0.01, 0.3), "log": True},
    "max_iter":         {"type": "int",   "range": (50, 300)},
    "max_leaf_nodes":   {"type": "int",   "range": (8, 64)},
    "l2_regularization": {"type": "float", "range": (1e-6, 1.0), "log": True},
}

search = ABCSearchCV(
    HistGradientBoostingClassifier(random_state=0),
    param_space,
    cv=5,
    scoring="accuracy",
    max_evals=60,       # candidates evaluated by ABC
    random_state=0,
)
search.fit(X, y)

print(search.best_score_, search.best_params_)
search.predict(X[:5])   # best_estimator_, refit on all data
Any scikit-learn compatible estimator works, including XGBoost and LightGBM.
Minimize a function
import numpy as np
from abcopt import CanonicalABCSolver

def rastrigin(x):
    return 10 * len(x) + np.sum(x**2 - 10 * np.cos(2 * np.pi * x))

solver = CanonicalABCSolver(rastrigin, n_params=5, lb=[-5.12] * 5, ub=[5.12] * 5,
                            max_evals=20_000, random_state=0)
best_x, best_f, history = solver.solve()
Inspect the search
import pandas as pd
import matplotlib.pyplot as plt

results = pd.DataFrame(search.cv_results_)          # one row per unique configuration
results.sort_values("rank_test_score").head()

evals, best = zip(*search.history_)                  # best CV score after each ABC cycle
plt.plot(evals, best); plt.xlabel("candidates evaluated"); plt.ylabel("best CV score")
How ABC works
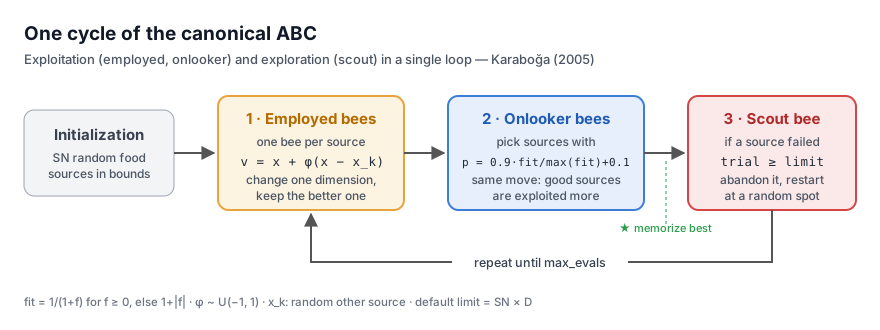
ABC models the foraging behaviour of a honey bee colony. Each food source is a candidate solution and its nectar amount is the solution's fitness. Three kinds of bees share the work:
| Phase | What happens | Why |
|---|---|---|
| Employed bees | Each source changes one random dimension relative to a random other source, v_ij = x_ij + φ·(x_ij − x_kj), φ ∈ [−1, 1], and keeps the better of old and new. |
Local search around every source |
| Onlooker bees | Sources are visited in turn; source i gets an extra try with probability p_i = 0.9 · fit_i / max(fit) + 0.1, until pop_size tries have been made. |
More effort on promising regions |
| Scout bee | Once per cycle, the source with the most failed tries is replaced by a random one if its counter has reached limit. |
Escapes local minima |
Fitness is derived from cost as 1 / (1 + f) for f ≥ 0 and 1 + |f| otherwise. The best solution found so far is always kept.
Benchmark
abcopt was compared with Random Search and Optuna TPE under identical evaluation budgets (notebook).
Black-box functions (D = 10, mean over 10 seeds, lower is better):
| Function | ABC @ 1k | TPE @ 1k | ABC @ 10k | TPE @ 2k | Random @ 10k |
|---|---|---|---|---|---|
| Sphere | 1.5 | 0.27 | 4e-11 | 0.22 | 12.3 |
| Rosenbrock | 1.3e3 | 88.5 | 0.51 | 114 | 1.1e4 |
| Rastrigin | 29.9 | 59.7 | 0.09 | 47.3 | 71.2 |
| Ackley | 12.8 | 5.58 | 0.0003 | 5.8 | 16.7 |
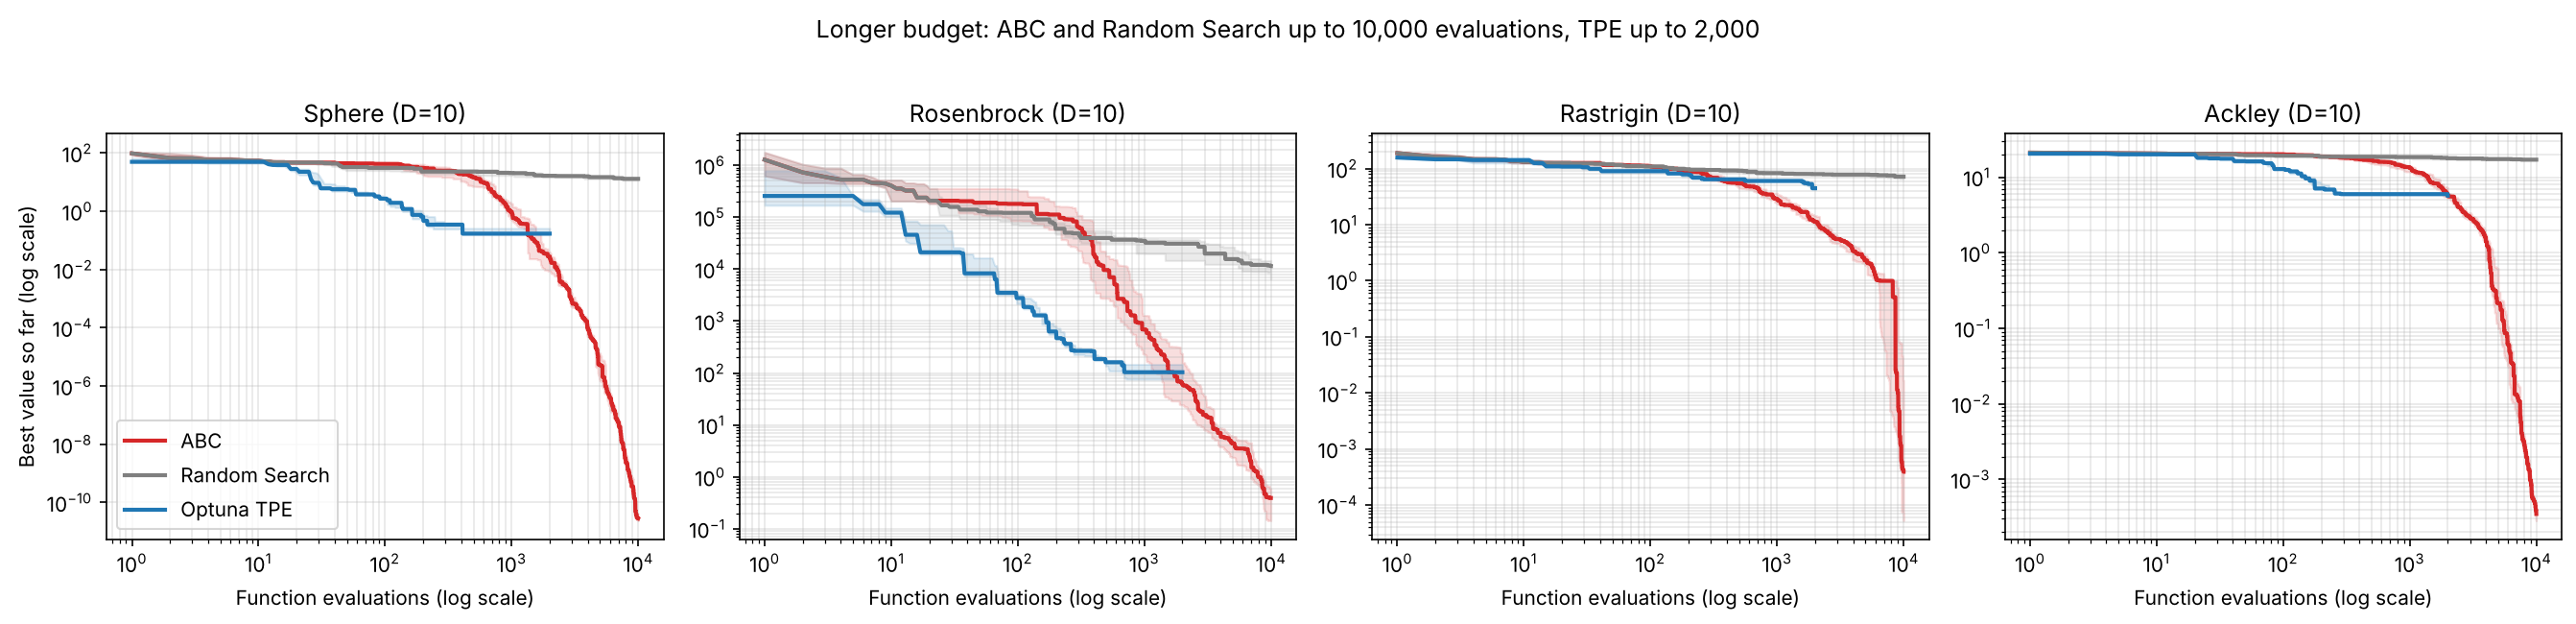
- With a short budget TPE is usually ahead; ABC beats Random Search everywhere and wins on the highly multimodal Rastrigin.
- With a larger budget ABC converges close to the global optimum on all four functions, while TPE stalls.
- ABC's own overhead is negligible: about 0.02 s versus 24 s for TPE over 2,000 evaluations.
- For hyperparameter tuning with about 50 candidates, the three methods end within noise of each other on test accuracy.
When to use which: TPE for very small budgets of expensive evaluations (for example deep-learning tuning); ABC when evaluations are cheap enough to afford thousands, when the landscape is rugged, or when you want a dependency-light scikit-learn drop-in.
API reference
CanonicalABCSolver
CanonicalABCSolver(objective_func, n_params, lb, ub,
                   pop_size=20, max_evals=1000, limit=None, random_state=None)
| Parameter | Description |
|---|---|
objective_func |
Callable taking a 1-D np.ndarray and returning a scalar cost to minimize. NaN is treated as the worst cost. |
n_params |
Number of dimensions |
lb, ub |
Lower and upper bound of each dimension |
pop_size |
Number of food sources (SN), equal to the number of employed and of onlooker bees. The colony size in the reference code is 2 × pop_size. |
max_evals |
Budget of objective evaluations |
limit |
A source is abandoned once its failed-trial counter reaches limit. Default: pop_size × n_params. |
random_state |
Seed or np.random.Generator |
solve() returns (best_params, best_cost, history), where history lists (evaluations_used, best_cost_so_far) after initialization and after every cycle.
ABCSearchCV
ABCSearchCV(estimator, param_space, cv=3, scoring="accuracy", pop_size=20, max_evals=200,
            limit=None, random_state=None, n_jobs=None, error_score=np.nan,
            refit=True, cache=True, verbose=False)
Search space (param_space), one entry per hyperparameter:
| Kind | Specification |
|---|---|
| Continuous | {"type": "float", "range": (0.01, 0.3)} |
| Continuous, log scale | {"type": "float", "range": (1e-4, 1e-1), "log": True} |
| Integer (both ends inclusive) | {"type": "int", "range": (2, 12)} |
| Categorical | {"type": "categorical", "choices": ["gini", "entropy"]} |
Parameters
| Parameter | Description |
|---|---|
cv, scoring, n_jobs, refit |
As in GridSearchCV. Higher scores are better; use neg_* scorers for errors. |
pop_size, max_evals, limit, random_state |
Passed to CanonicalABCSolver. max_evals counts every candidate ABC proposes. |
error_score |
Score for candidates that fail to fit (a RuntimeWarning is issued); "raise" stops the search. |
cache |
Reuse the score of a configuration ABC has already evaluated instead of cross-validating it again. Saves time; the search is unchanged. |
fit(X, y=None, groups=None, **fit_params): groups is passed to group-aware splitters and fit_params (for example sample_weight) to the estimator.
Attributes after fit
| Attribute | Content |
|---|---|
best_params_, best_score_, best_index_ |
Best configuration, its mean CV score and its row in cv_results_ |
best_estimator_, refit_time_ |
Best configuration refit on all data (refit=True) |
cv_results_ |
One row per unique configuration, in GridSearchCV format |
results_ |
Every candidate in proposal order with params, score and cached |
history_ |
(evaluations_used, best_score_so_far) after each cycle |
n_evals_, n_unique_evals_, n_splits_ |
Candidates evaluated, distinct configurations (cross-validation runs), CV folds |
Methods: predict, predict_proba, predict_log_proba, decision_function, transform, score and classes_, whenever the underlying estimator supports them.
Notes and limitations
- Budget semantics. As in the reference implementation, the budget is a number of objective evaluations, not of cycles. With
ABCSearchCV, cached repeats still count towardsmax_evals. - Integer and categorical parameters are searched as continuous values and rounded. Categorical choices become equal-width intervals of one dimension, so neighbouring choices are treated as "close"; this works well for a handful of choices.
- Sequential by design. Bees are evaluated one after another, exactly as in the reference algorithm; parallelism comes from
n_jobsinside each cross-validation. - Minimization.
CanonicalABCSolverminimizes; to maximize, return the negative value.
Examples
| Example | Content |
|---|---|
| Benchmark | ABC vs Random Search vs Optuna TPE on test functions and two tuning tasks |
| Federated learning on MedMNIST | ABC tunes FedAvg's learning rate and momentum on non-IID PathMNIST (5 clients, Dirichlet α = 0.5); test accuracy rises from 78.05% to 85.28%. Run with abcopt 0.1. |
| Animation | Records every phase of a solver run and renders the GIF above |
Development
git clone https://github.com/yusufkorkmazyigit/abc-optimizer-lib.git
cd abc-optimizer-lib
pip install -e ".[test]"
pytest
The test suite includes the reference-equivalence test (tests/test_reference_equivalence.py) and runs on Python 3.9, 3.11 and 3.12 for every push. Release notes are in CHANGELOG.md. Issues and pull requests are welcome.
Citation
If abcopt helps your work, please cite the original algorithm and this software:
@techreport{karaboga2005abc,
  author      = {Karaboğa, Derviş},
  title       = {An Idea Based on Honey Bee Swarm for Numerical Optimization},
  institution = {Erciyes University, Engineering Faculty, Computer Engineering Department},
  number      = {TR06},
  year        = {2005}
}

@software{korkmazyigit_abcopt,
  author  = {Korkmazyiğit, Yusuf},
  title   = {abcopt: Canonical Artificial Bee Colony optimization for Python},
  url     = {https://github.com/yusufkorkmazyigit/abc-optimizer-lib},
  version = {0.2.2},
  year    = {2026}
}
License
MIT. See LICENSE. The reference port used in the tests is MIT licensed by its authors.
Developed by Yusuf Korkmazyiğit, Computer Engineering, Erciyes University.
1 maintainer

Metadata
1 maintainer
Release files for abcopt 0.2.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| abcopt-0.2.2.tar.gz | 23.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| abcopt-0.2.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 38.7 kB
Release files / abcopt-0.2.2.tar.gz
| Download URL | abcopt-0.2.2.tar.gz |
|---|---|
| Size | 23.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
92f5dbe3898b1cd65094bbd43bc1b567936c9f6a5e0e05a2a1eb68ee30c2239c
|
|
BLAKE2b-256 checksum How to use checksums |
6673b78fef9a412bbe9fe004ad5657430d3e0b1ab030c28c66d3ce19a5bc104e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 13, 2026.
Transparency logRelease files / abcopt-0.2.2-py3-none-any.whl
| Download URL | abcopt-0.2.2-py3-none-any.whl |
|---|---|
| Size | 15.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5b8abed1b9d2b62b46b6676e0c7552c82254b654ddae84dd49e7a9290996c90f
|
|
BLAKE2b-256 checksum How to use checksums |
f9f32bb4132adfd721bc6b6f8d14c9f44795e2d1997fbf11bd995a638c4acd81
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 13, 2026.
Transparency log













