
acroforge
Turn flat PDFs into real, fillable AcroForms. Permissive (Apache-2.0), deterministic, zero-copyleft.


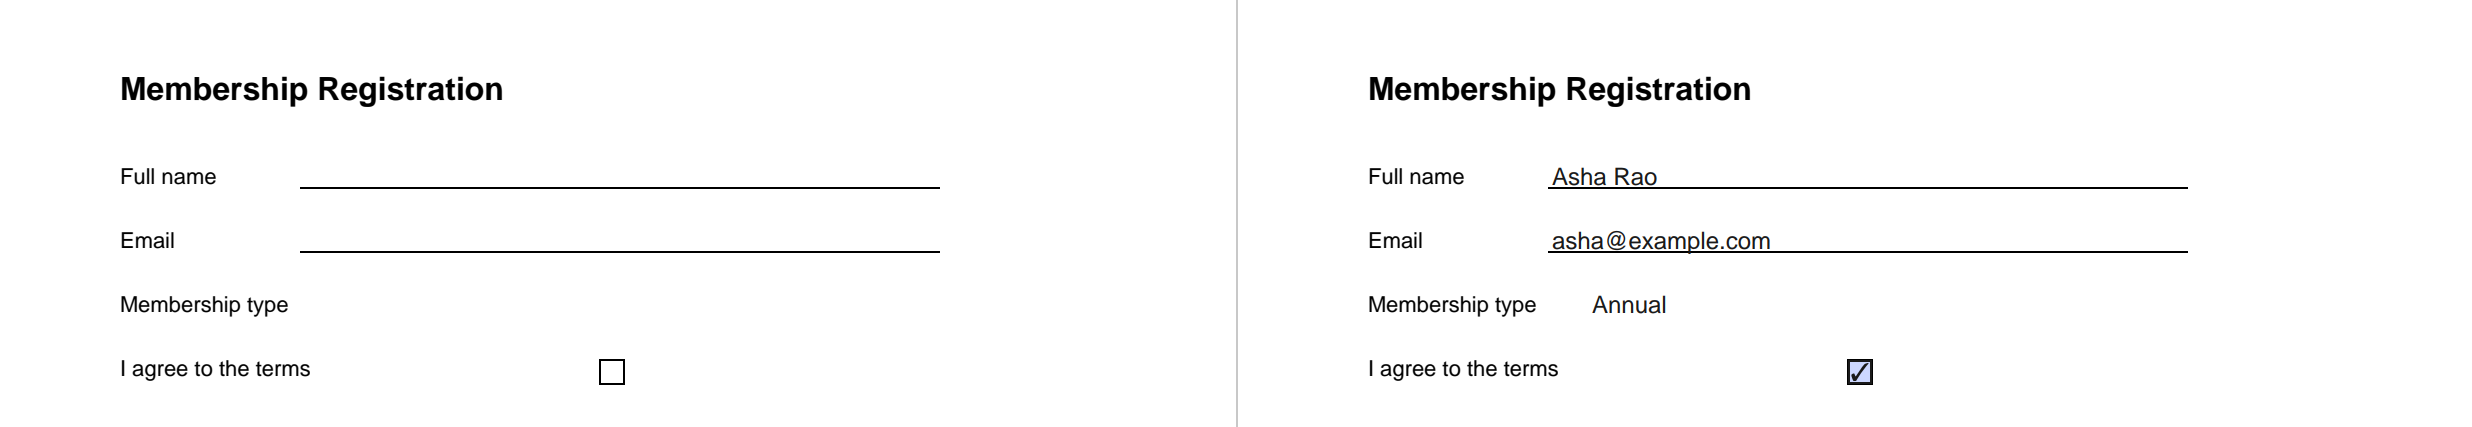
Left: a flat PDF - just printed lines and an empty box. Right: the same PDF after acroforge - real, fillable form fields, filled and rendered correctly. No Adobe, no cloud, no AGPL.
What it does
acroforge takes any PDF - vector or scanned - and injects real AcroForm fields at positions you specify. The result is a standards-compliant fillable PDF that renders correctly in Chrome's pdfium and Firefox's pdf.js.
Four operations:
| Operation | What it does |
|---|---|
build |
Inject interactive AcroForm fields into a flat PDF |
fill |
Set field values by name on a fillable PDF |
remove |
Delete specific fields by name (raises if a name is missing) |
flatten |
Bake field appearances into page content; remove interactive fields |
All accept and return plain bytes, making them easy to compose in any pipeline.
Tested on real-world forms
The deterministic core (build / fill / flatten / read_fields) is validated against 125 real public PDF forms - IRS and other government forms (VA, OPM, GSA), CMS / Medicare and hospital healthcare forms, federal- and state-court legal forms, and SBA / USPTO / vendor business forms. It reads every one of them, and fills, flattens, and round-trips every fillable one (over 11,000 real fields) without a single crash. Every field type renders correctly in Chrome's pdfium and Firefox's pdf.js, golden-image tested in CI.
The detect() layer below is separate and clearly labeled best-effort.
Install
pip install acroforge
Or from source:
git clone https://github.com/san64777/acroforge
cd acroforge
pip install -e .   # or: uv pip install -e .
Python usage
import io
from reportlab.pdfgen import canvas  # any PDF source works
import acroforge as af
from acroforge import FieldSpec, FieldType

# --- Step 0: obtain a flat PDF (bytes) any way you like ---
buf = io.BytesIO()
c = canvas.Canvas(buf, pagesize=(612, 792))
c.drawString(72, 720, "Name:")
c.drawString(72, 680, "Agree to terms:")
c.save()
flat_pdf: bytes = buf.getvalue()

# --- Step 1: describe the fields you want ---
fields = [
    FieldSpec(
        type=FieldType.TEXT,
        page=0,
        rect=(200, 700, 450, 730),  # (x0, y0, x1, y1) in PDF points
        name="full_name",
    ),
    FieldSpec(
        type=FieldType.CHECKBOX,
        page=0,
        rect=(200, 660, 220, 680),
        name="agree",
        export_value="Yes",
    ),
]

# --- Step 2: inject the fields ---
fillable: bytes = af.build(flat_pdf, fields)

# --- Step 3: fill values ---
filled: bytes = af.fill(fillable, {"full_name": "Jane Doe", "agree": True})

# --- Step 4: flatten (optional - locks the form) ---
final: bytes = af.flatten(filled)

# Write to disk
with open("output.pdf", "wb") as f:
    f.write(final)
CLI usage
# 1. Inject fields described in a JSON manifest
acroforge build in.pdf manifest.json fillable.pdf

# 2. Fill fields from a JSON object {name: value}
acroforge fill fillable.pdf data.json filled.pdf

# 3. Flatten (bake and lock)
acroforge flatten filled.pdf final.pdf
Example manifest.json:
[
  {
    "type": "text",
    "page": 0,
    "rect": [200, 700, 450, 730],
    "name": "full_name"
  },
  {
    "type": "checkbox",
    "page": 0,
    "rect": [200, 660, 220, 680],
    "name": "agree",
    "export_value": "Yes"
  },
  {
    "type": "radio",
    "page": 0,
    "rect": [200, 620, 220, 640],
    "name": "plan",
    "options": ["basic", "pro", "enterprise"],
    "export_value": "pro"
  }
]
Example data.json:
{"full_name": "Jane Doe", "agree": true, "plan": "pro"}
Field types
| Type | FieldType |
Notes |
|---|---|---|
| Single-line text | FieldType.TEXT |
Optional maxlen to cap character count |
| Multi-cell comb | FieldType.COMB |
maxlen sets the number of cells (e.g. SSN = 9) |
| Checkbox | FieldType.CHECKBOX |
export_value is the on-state value (default "Yes") |
| Radio button | FieldType.RADIO |
One FieldSpec per button; share name, set export_value per button |
| Signature | FieldType.SIGNATURE |
Placeholder widget - renders a blank sig box |
| Dropdown / list box | FieldType.CHOICE |
options lists the choices; list_box, multi_select, editable flags (see note) |
FieldSpec reference
class FieldSpec(BaseModel):
    type: FieldType
    page: int                                    # 0-indexed
    rect: tuple[float, float, float, float]      # (x0, y0, x1, y1) in PDF points
    name: str                                    # AcroForm field name
    options: list[str] | list[tuple[str, str]] | None = None  # choice options (str or (export, label))
    maxlen: int | None = None                    # TEXT cap / COMB cell count
    export_value: str | None = None              # radio/checkbox on-value
    list_box: bool = False                       # CHOICE: False=dropdown, True=list box
    multi_select: bool = False                   # CHOICE list box: allow multiple selections
    editable: bool = False                       # CHOICE combo: accept free-typed text
    confidence: float = 1.0                      # 1.0 = explicit; <1.0 = best-effort guess
Dropdowns and list boxes (FieldType.CHOICE)
# dropdown (combo box)
FieldSpec(type=FieldType.CHOICE, page=0, rect=(200, 620, 360, 640),
          name="state", options=["CA", "NY", "TX"])

# (export, label) pairs: store "CA", display "California"
FieldSpec(type=FieldType.CHOICE, page=0, rect=(200, 580, 360, 600),
          name="st", options=[("CA", "California"), ("NY", "New York")])

# scrolling list box, multi-select
FieldSpec(type=FieldType.CHOICE, page=0, rect=(200, 500, 360, 570),
          name="langs", options=["en", "fr", "de"], list_box=True, multi_select=True)
All four variants - dropdown, single-select list box, editable dropdown, and
multi-select list box - are cross-viewer verified: the selected value renders in
both pdfium and pdf.js. read_fields recovers a choice field's structure (its
options and the list_box / multi_select / editable flags); it does not
recover the current selection, since a FieldSpec describes the field, not its
filled value.
Detection (best-effort)
In addition to the deterministic engine, acroforge ships an optional, best-effort detector that guesses where fields belong on a flat vector PDF by reading its vector geometry and nearby text labels. It handles both common form archetypes:
- Underline forms - write-on rules become text fields.
- Table/grid forms - bordered table cells become text fields (label-aware: the field is placed in the writable area below the label, multi-column cells are split, and section-header rows are skipped).
- Checkboxes - both vector squares and font glyphs (☐ / ☑ / ☒).
import acroforge as af

pdf = open("form.pdf", "rb").read()

# Inspect candidate fields (a FormManifest); every field has confidence < 1.0
manifest = af.detect(pdf)
for f in manifest.fields:
    print(f.type, f.name, f.rect, f.confidence)

# Or go straight to a fillable PDF (detect() then build())
fillable: bytes = af.make_fillable(pdf)
CLI:
# Print the detected manifest as JSON (review it!)
acroforge detect form.pdf

# Detect and write a fillable PDF in one step
acroforge make-fillable form.pdf fillable.pdf
Read this before relying on it:
- Heuristic. Detection guesses from vector shapes and text proximity. It will miss fields and invent spurious ones.
- Vector-only. It reads the PDF's vector content stream. Scanned (image-only)
PDFs are refused with
ScannedPDFError- there is no OCR. - Confidence-scored. Every detected
FieldSpeccarriesconfidence < 1.0to flag it as a guess. Explicitly authored specs useconfidence = 1.0. - Meant to be reviewed. Treat the output of
detect()/make-fillableas a draft manifest to inspect and correct, not a finished form. - No accuracy claims. We make no promise about detection precision or recall on any form. Quality varies wildly by document.
- No AI. There are no models, no inference, no network calls - just deterministic geometry heuristics over the PDF's own vectors.
Reading existing fields
read_fields(pdf) ingests the AcroForm fields already present in a fillable PDF as FieldSpecs (real registered fields, so confidence = 1.0). It is the inverse of build, so the two round-trip:
import acroforge as af

specs = af.read_fields(open("fillable.pdf", "rb").read())   # -> list[FieldSpec]
for s in specs:
    print(s.type.value, s.name, s.rect)

# copy one form's field layout onto another PDF
af.build(other_pdf, af.read_fields(template_pdf))
(One FieldSpec per widget, with coordinates, type, name, and checkbox/radio on-states recovered. Dropdowns are reported as text. Pushbuttons are skipped.)
Removing fields
remove(pdf, names) deletes specific fields by the name read_fields reports, so the two compose. Handy when make_fillable over-detects, or to strip a field before sending a form:
specs = af.read_fields(pdf)
junk = [s.name for s in specs if s.type == af.FieldType.SIGNATURE]
clean = af.remove(pdf, junk)        # raises ValueError if any name is missing
Naming a radio group removes the whole group; removing the last field leaves an empty, re-usable /AcroForm.
Serializing a manifest
detect() returns a FormManifest and read_fields() returns list[FieldSpec] - both pydantic models, so store / send-to-a-UI / round-trip them with pydantic's built-ins (no extra API to learn):
data = manifest.model_dump_json()                  # -> JSON string
manifest = FormManifest.model_validate_json(data)  # -> back to a FormManifest
af.build(pdf, manifest.fields)                      # build from the (edited) specs
(export, label) option pairs round-trip as [export, label] arrays and back to tuples; generate a TypeScript type from FormManifest.model_json_schema().
Scope and honest limits
The reliable part is the deterministic build / fill / flatten engine. You
supply field positions via FieldSpecs - acroforge injects, fills, and flattens them
reliably at exactly the coordinates you give it, on any PDF (vector or scanned).
detect() / make_fillable() are the best-effort layer described above: use them
to bootstrap a manifest, then review and hand off the corrected specs to the engine.
XFA / dynamic forms: some PDFs (many government forms) carry a dynamic XFA layer over the standard AcroForm. acroforge operates on the AcroForm layer - which is what most viewers render - and drops the XFA layer on output. Flattened output is unambiguous everywhere; for interactive output, an XFA-first viewer (some Adobe configurations) may prefer the dropped layer, so flatten the result if you need cross-Adobe fidelity.
There is no AI in this package, and no copyrighted form templates are bundled - bring your own PDFs.
Engine and dependencies
Runtime dependencies are strictly permissive:
| Package | License | Role |
|---|---|---|
reportlab |
BSD | Field widget rendering |
pypdf |
BSD-3-Clause | PDF read / merge / flatten |
pdfplumber |
MIT | PDF geometry utilities |
PyPDFForm |
MIT | Fill helpers |
pydantic |
MIT | FieldSpec / FormManifest validation |
Optional extras:
[fallback]- addspikepdf(MPL-2.0) as a fallback PDF writer; not required for the default engine path.[harness]- addspypdfium2+Pillowfor cross-viewer visual regression tests.
No GPL, AGPL, LGPL, or SSPL in the runtime tree. CI enforces this on every push via pip-licenses --fail-on='GPL;AGPL;LGPL;SSPL'.
License
Apache-2.0. See LICENSE.
No copyrighted form templates are included or bundled. Bring your own PDFs.
1 maintainer

Release files for acroforge 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| acroforge-0.4.0.tar.gz | 782.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| acroforge-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 818.9 kB
Release files / acroforge-0.4.0.tar.gz
| Download URL | acroforge-0.4.0.tar.gz |
|---|---|
| Size | 782.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
aa87313de4c3e7ff33a62fb3fb72a4b19c7d61e5f03bf850dc6bd363cf14ed49
|
|
BLAKE2b-256 checksum How to use checksums |
09e5b754d125f6b4c0b70e1434fbb225981a43b4db79a9bdc0472c5490aeeb58
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 8, 2026.
Transparency logRelease files / acroforge-0.4.0-py3-none-any.whl
| Download URL | acroforge-0.4.0-py3-none-any.whl |
|---|---|
| Size | 36.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d883ee8ac891d05f6f471f73c6c9b24a4a8ca4b21049a86d6dcfca00924b7c90
|
|
BLAKE2b-256 checksum How to use checksums |
47924082bb5149cc40393a0dd764c08fde7f77d29c3b0e058db62b0251b6937a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 8, 2026.
Transparency log













