


Overview
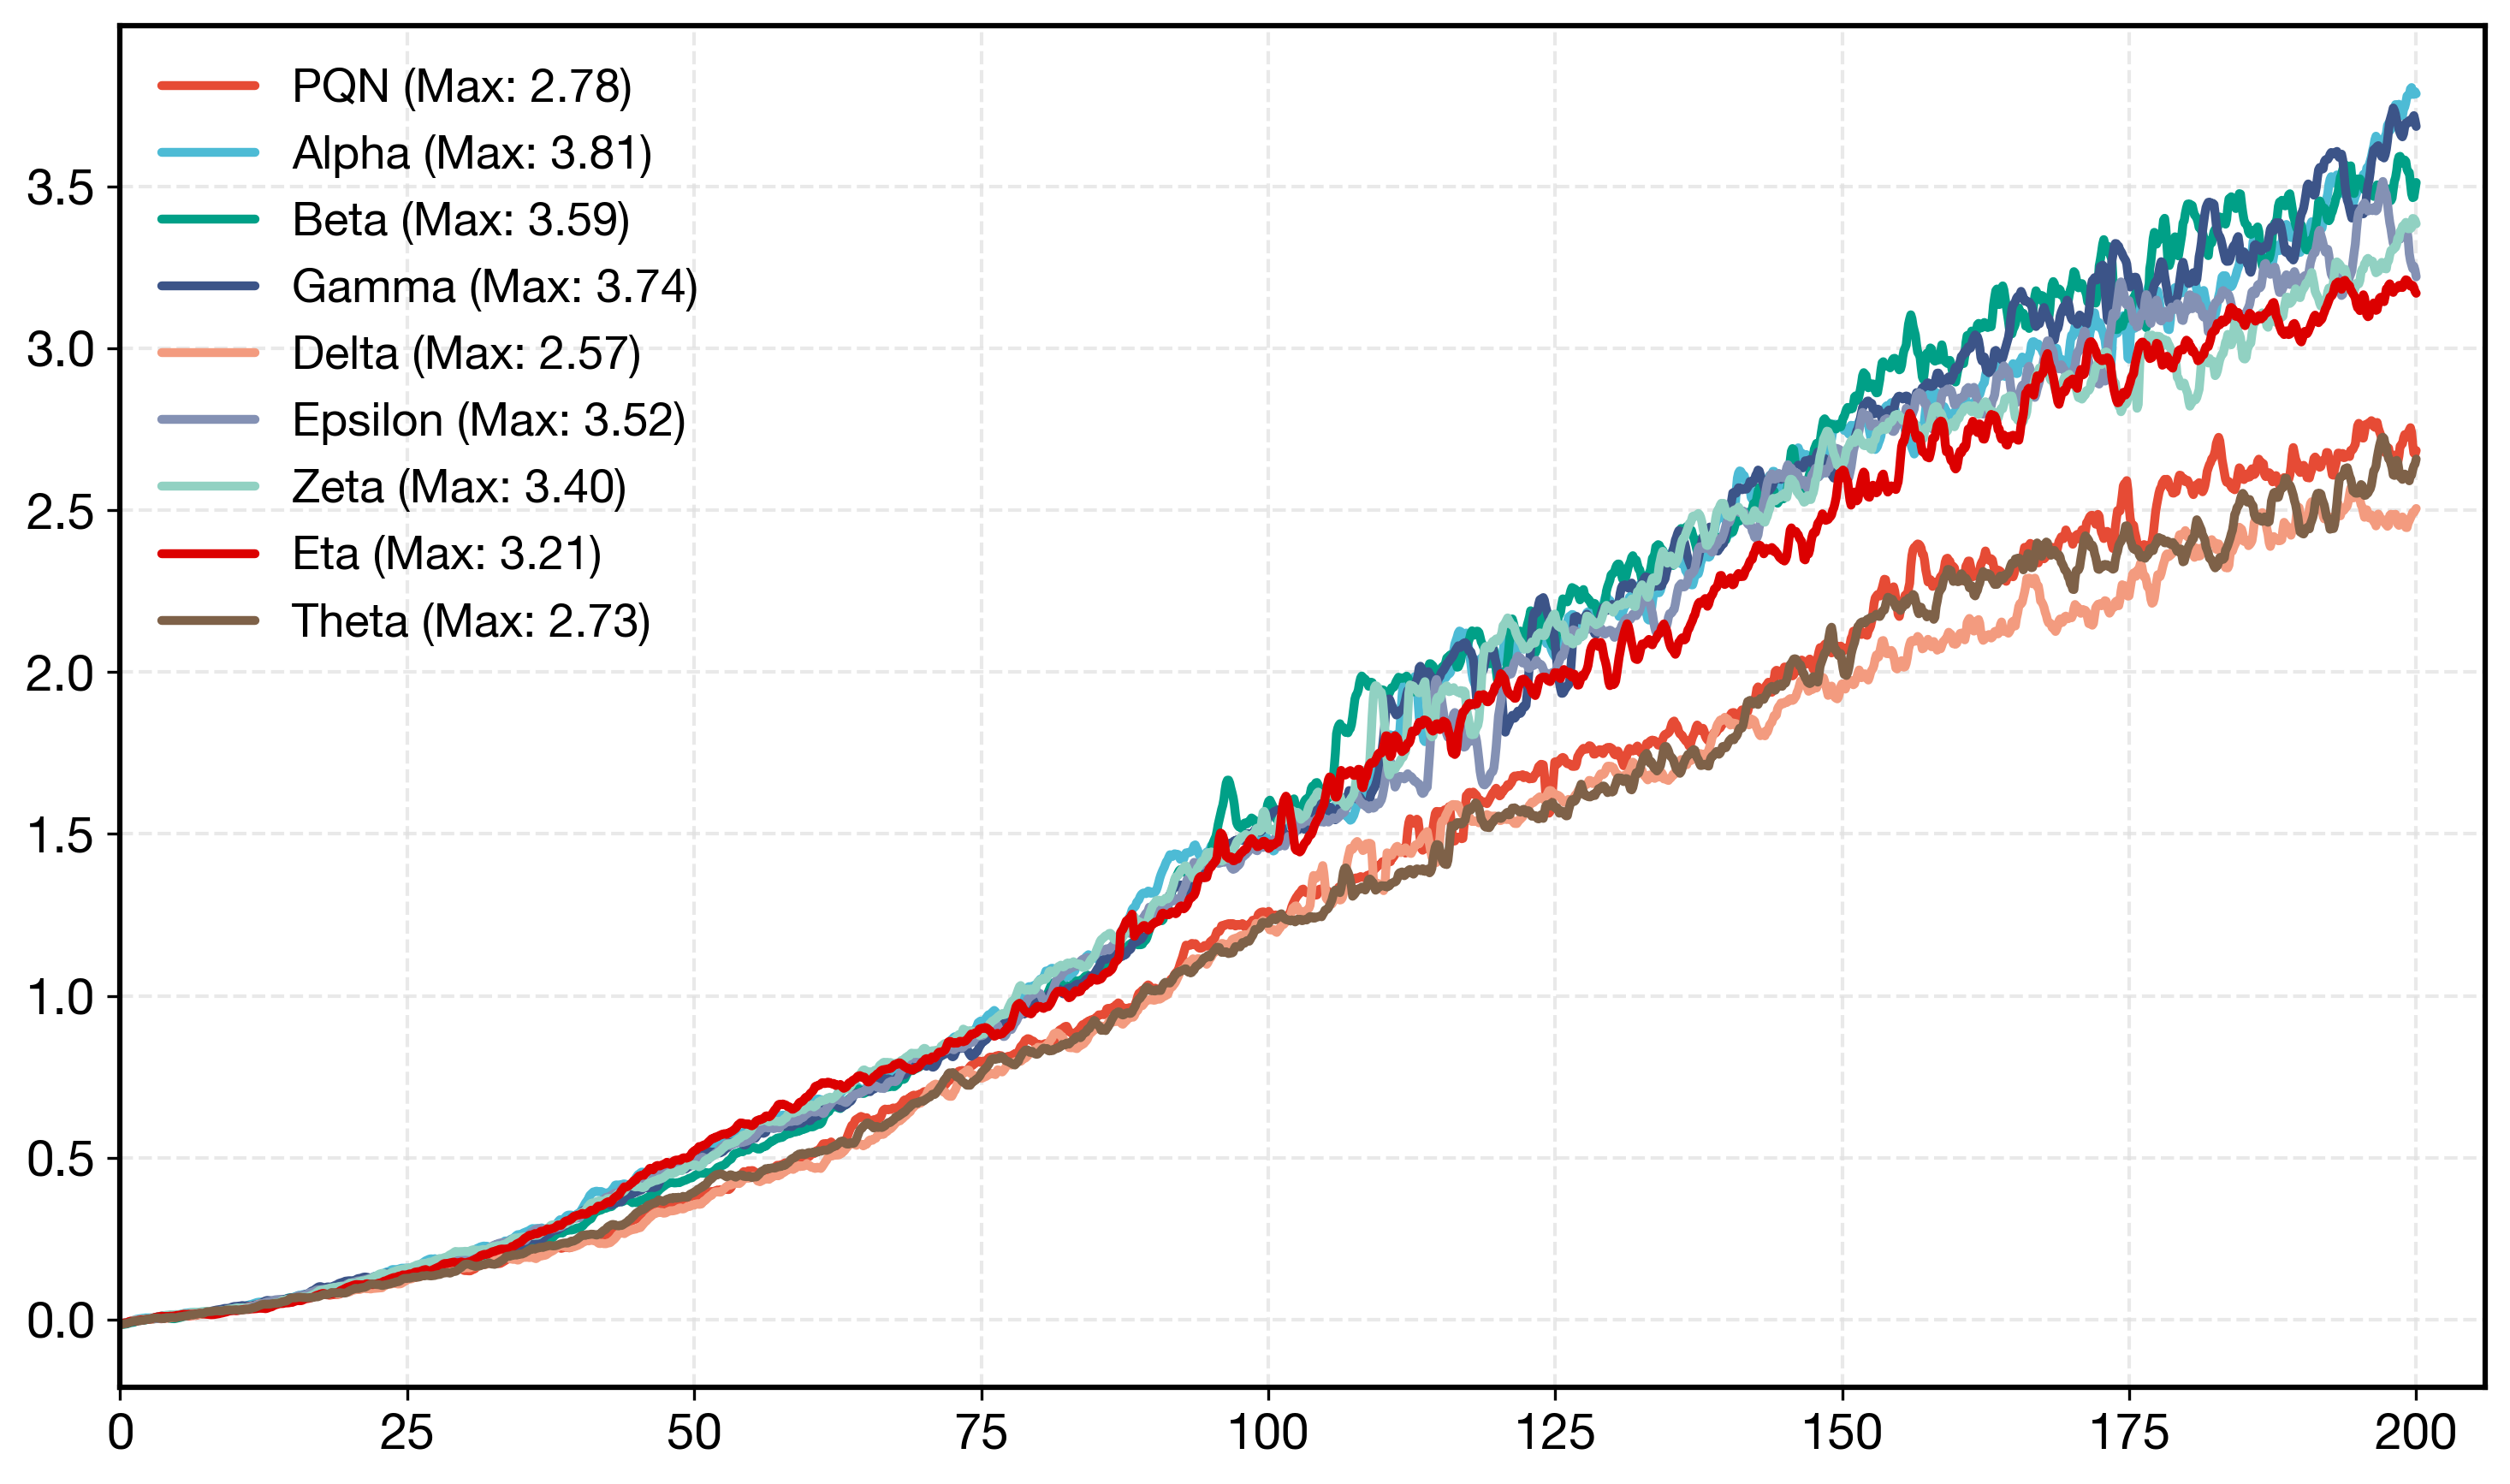
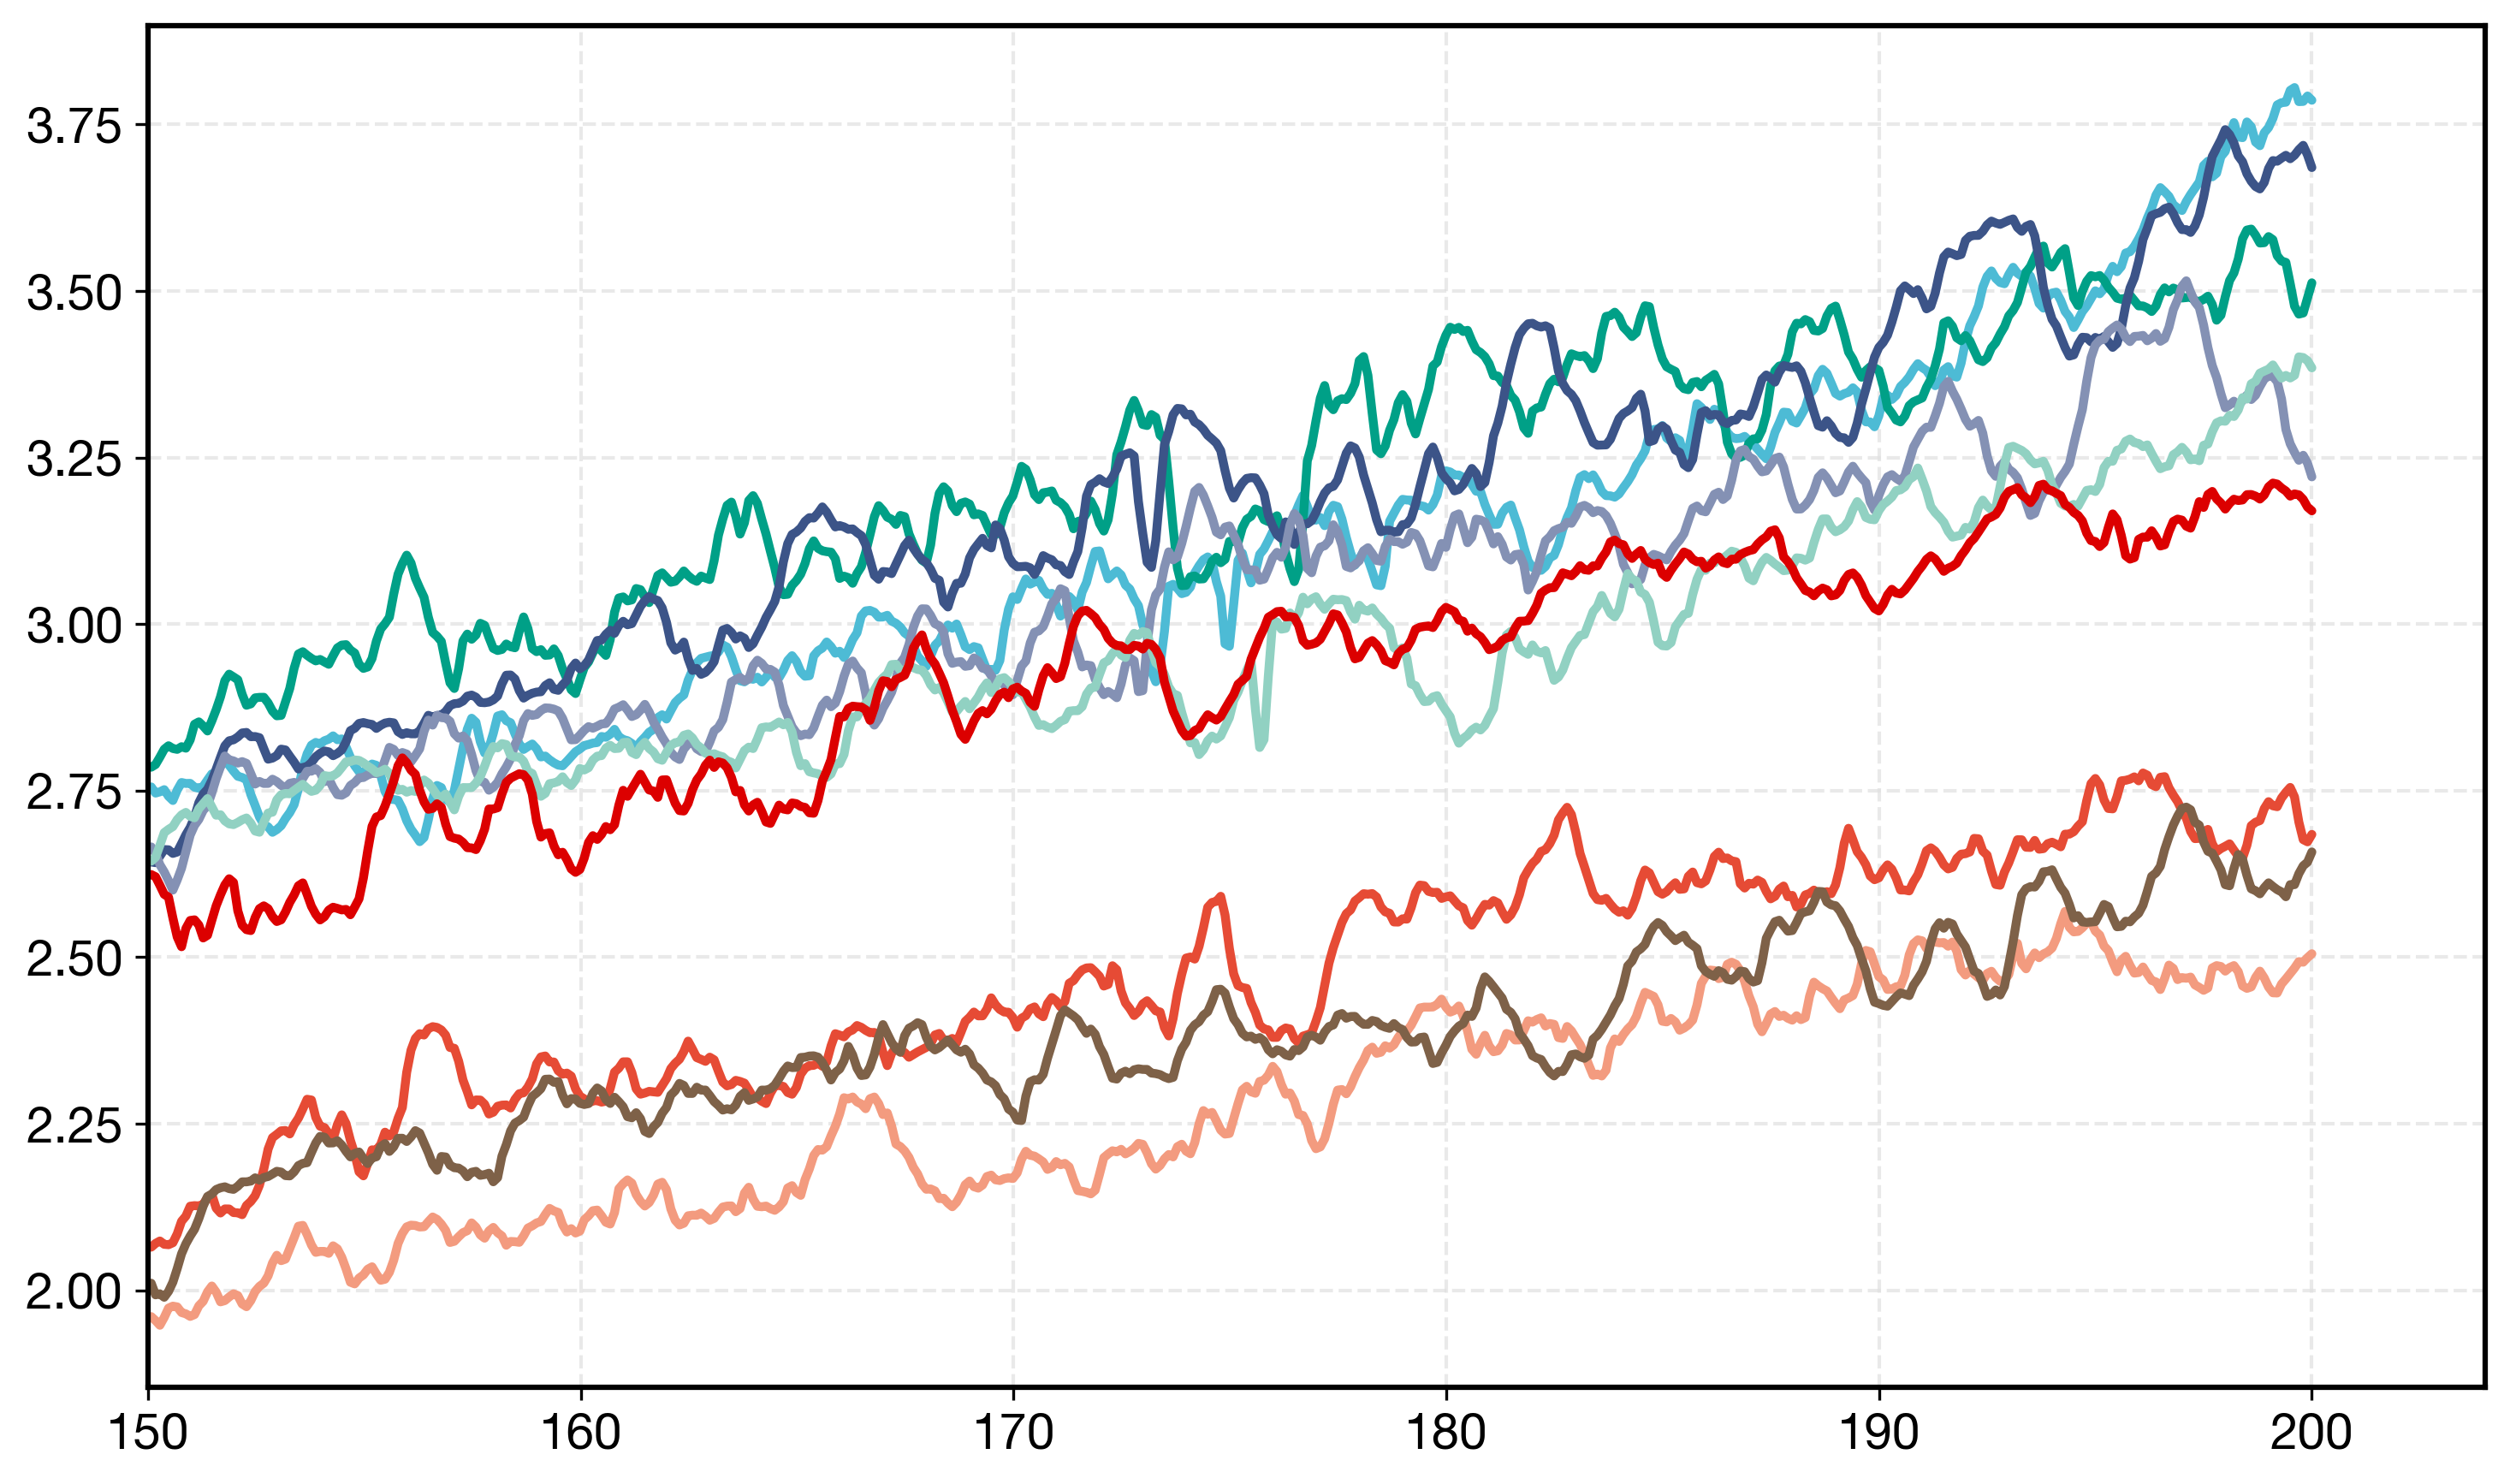
Aftab (Persian: آفتاب, meaning "sun" or "sun rays") is a benchmarking framework for evaluating CNN-based encoders in PQN across Atari games. It provides standardized training, evaluation, and reproducibility tools for deep reinforcement learning research.
See how the Aftab architecture compares to standard PQN baselines in these video demonstrations.
This research was done without receiving any funds; therefore, if you found our work useful, please consider sponsoring on GitHub 💛.
Encoder Experiments
| IQM HNS |
|---|
|
| IQM HNS (Last 50M Frames) |
|
Hadamax Experiments
| IQM HNS |
|---|
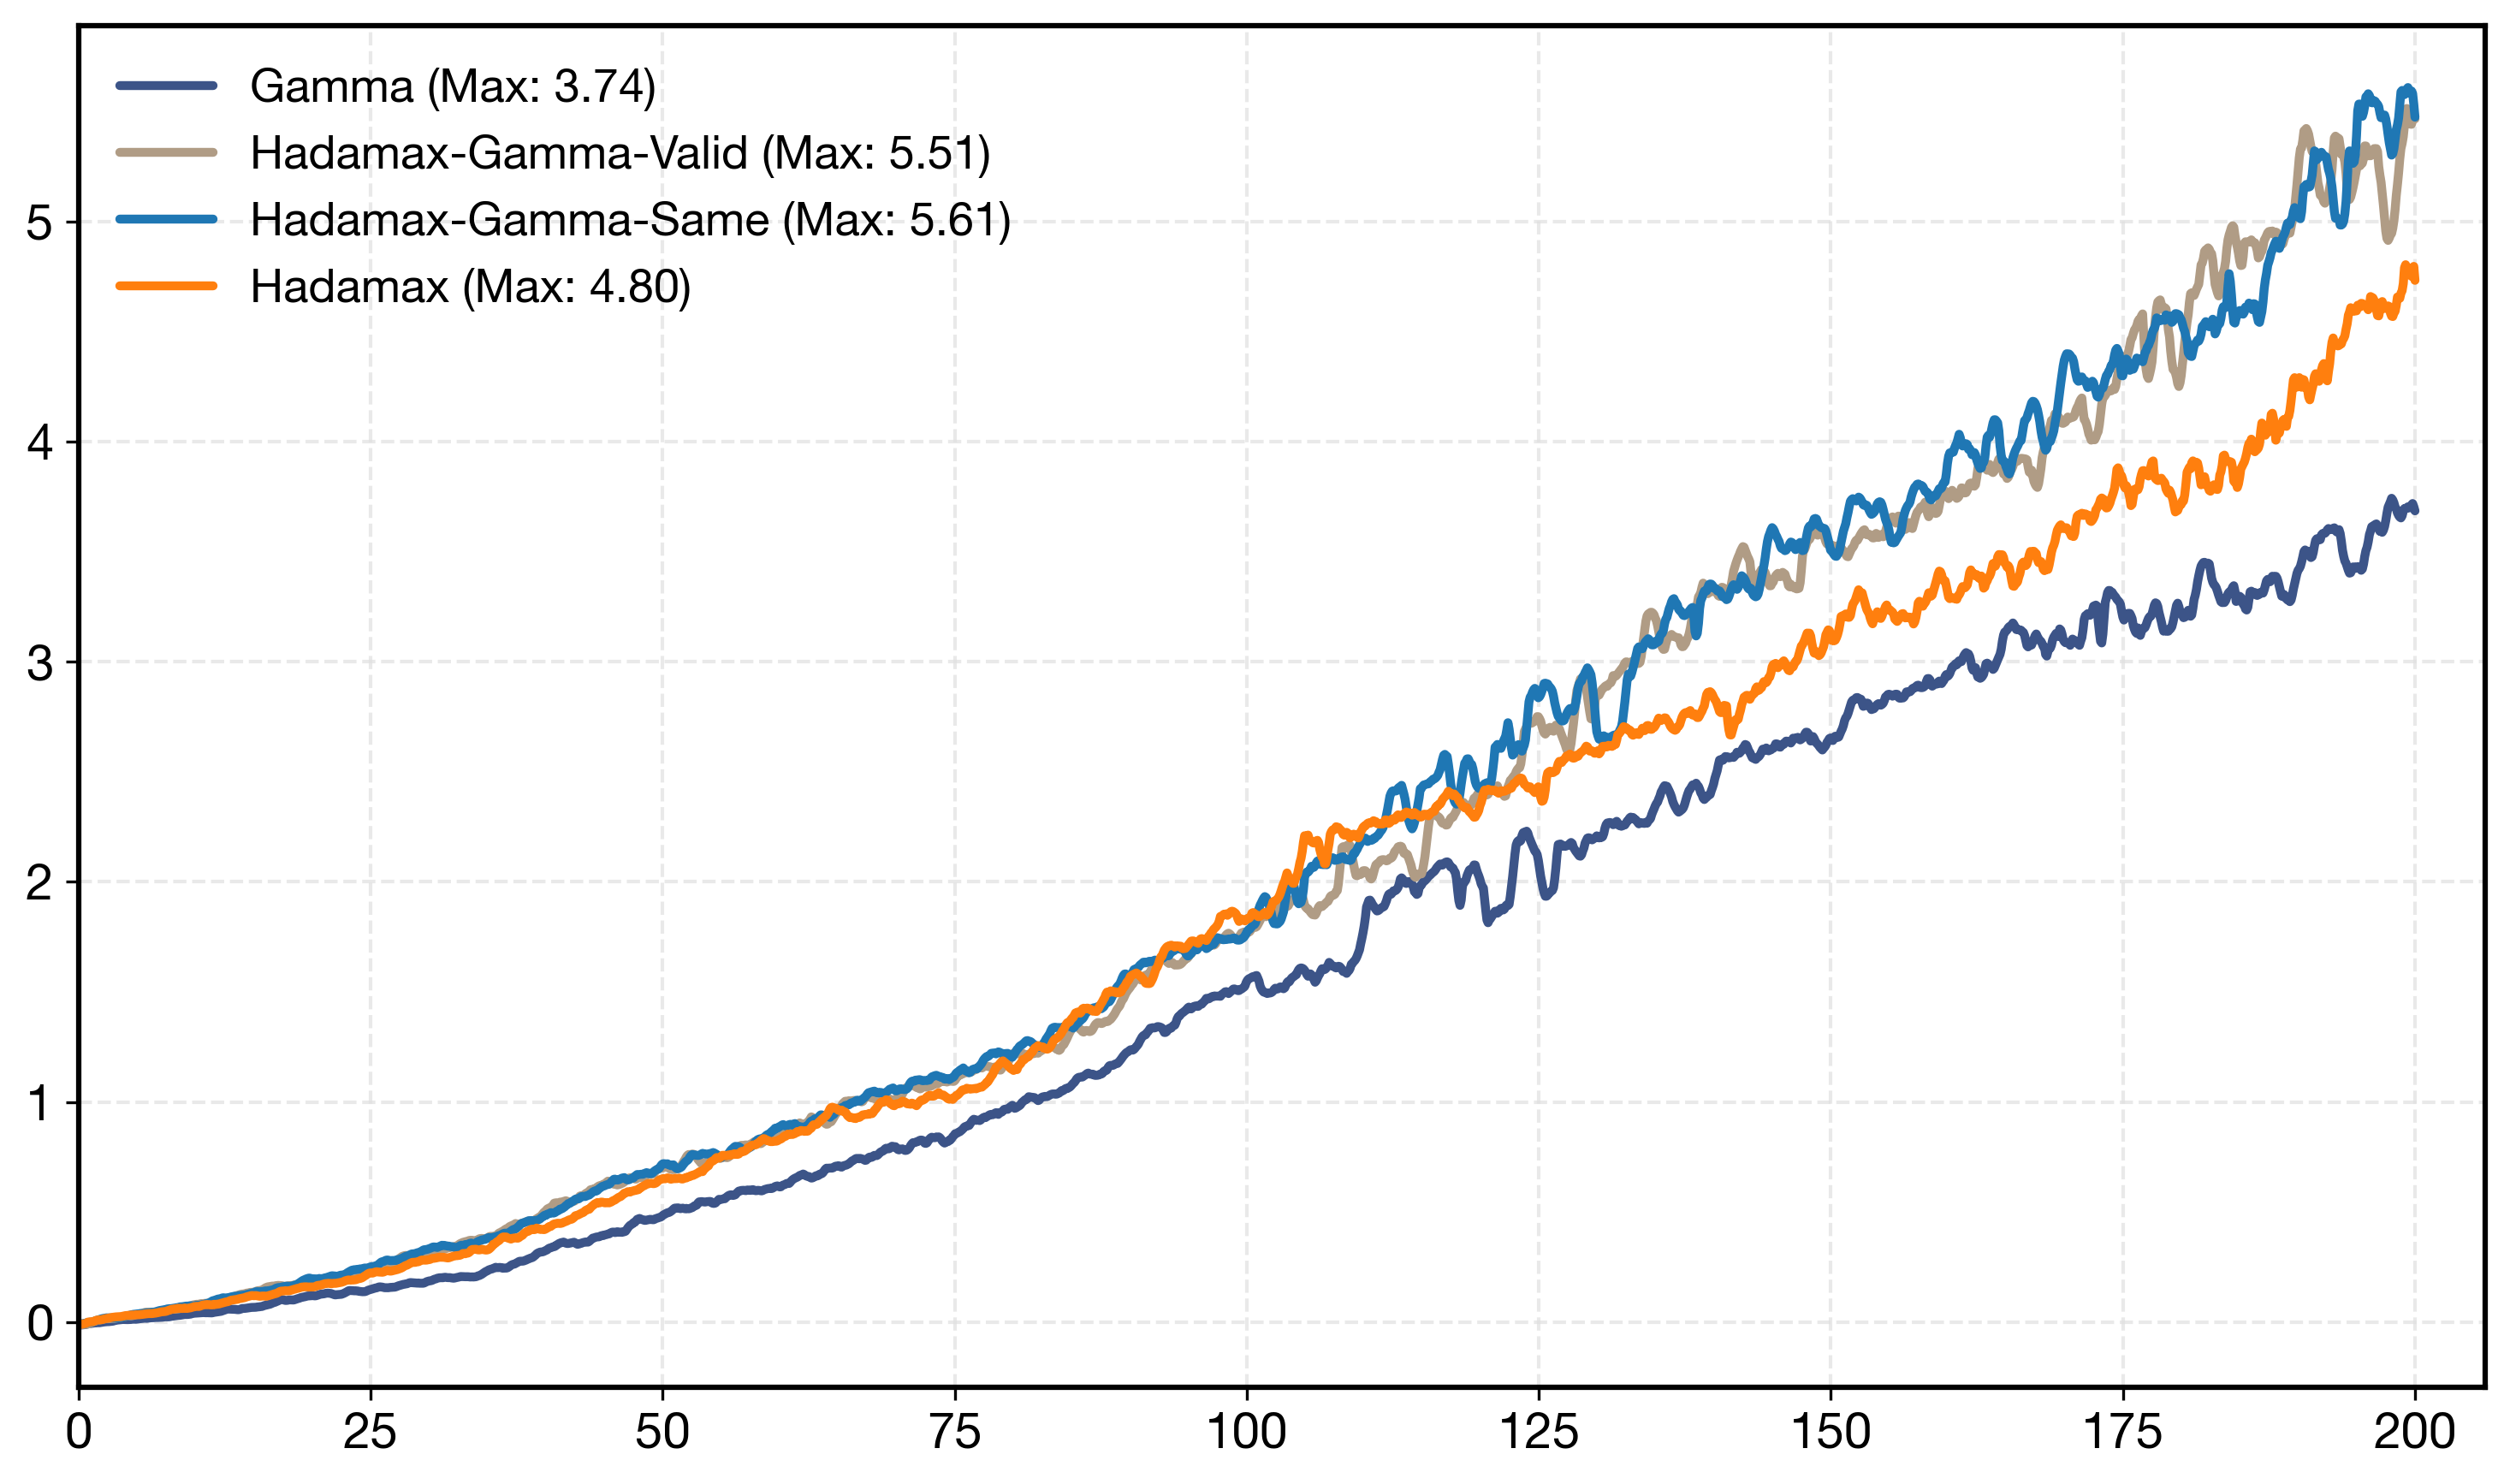
|
| IQM HNS (Last 50M Frames) |
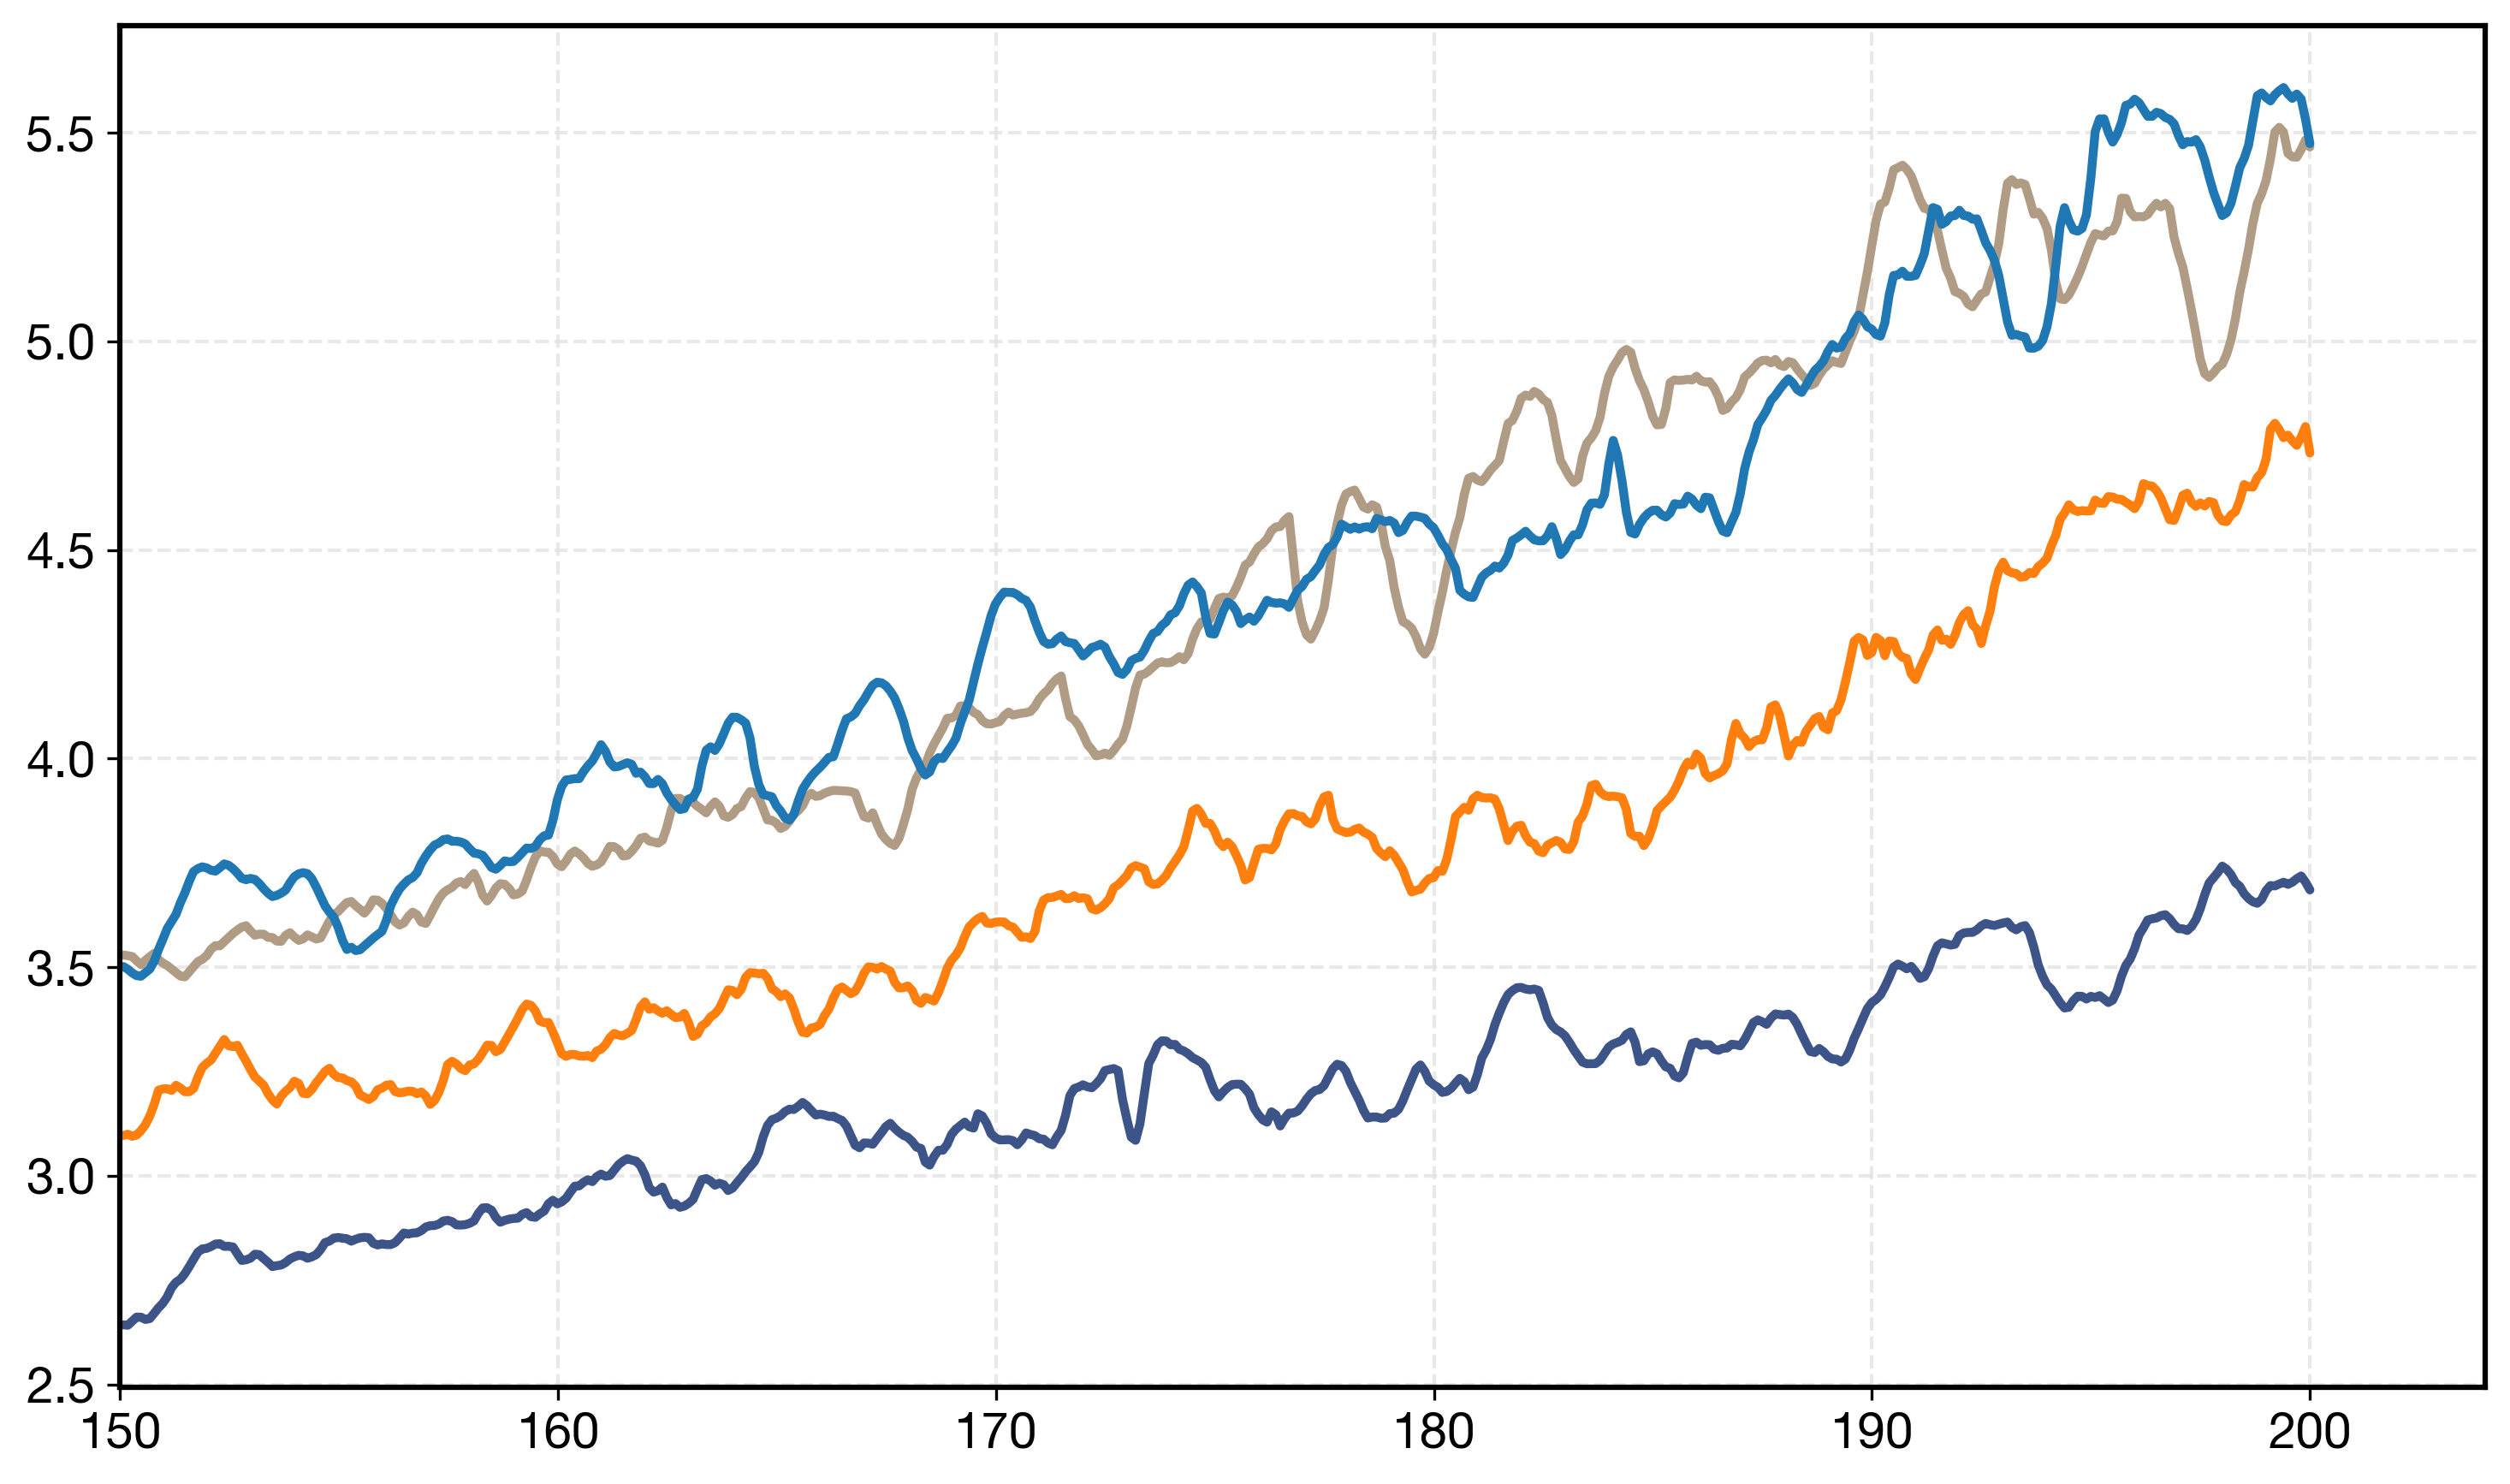
|
References:
Q-Values Experiments
| IQM HNS |
|---|
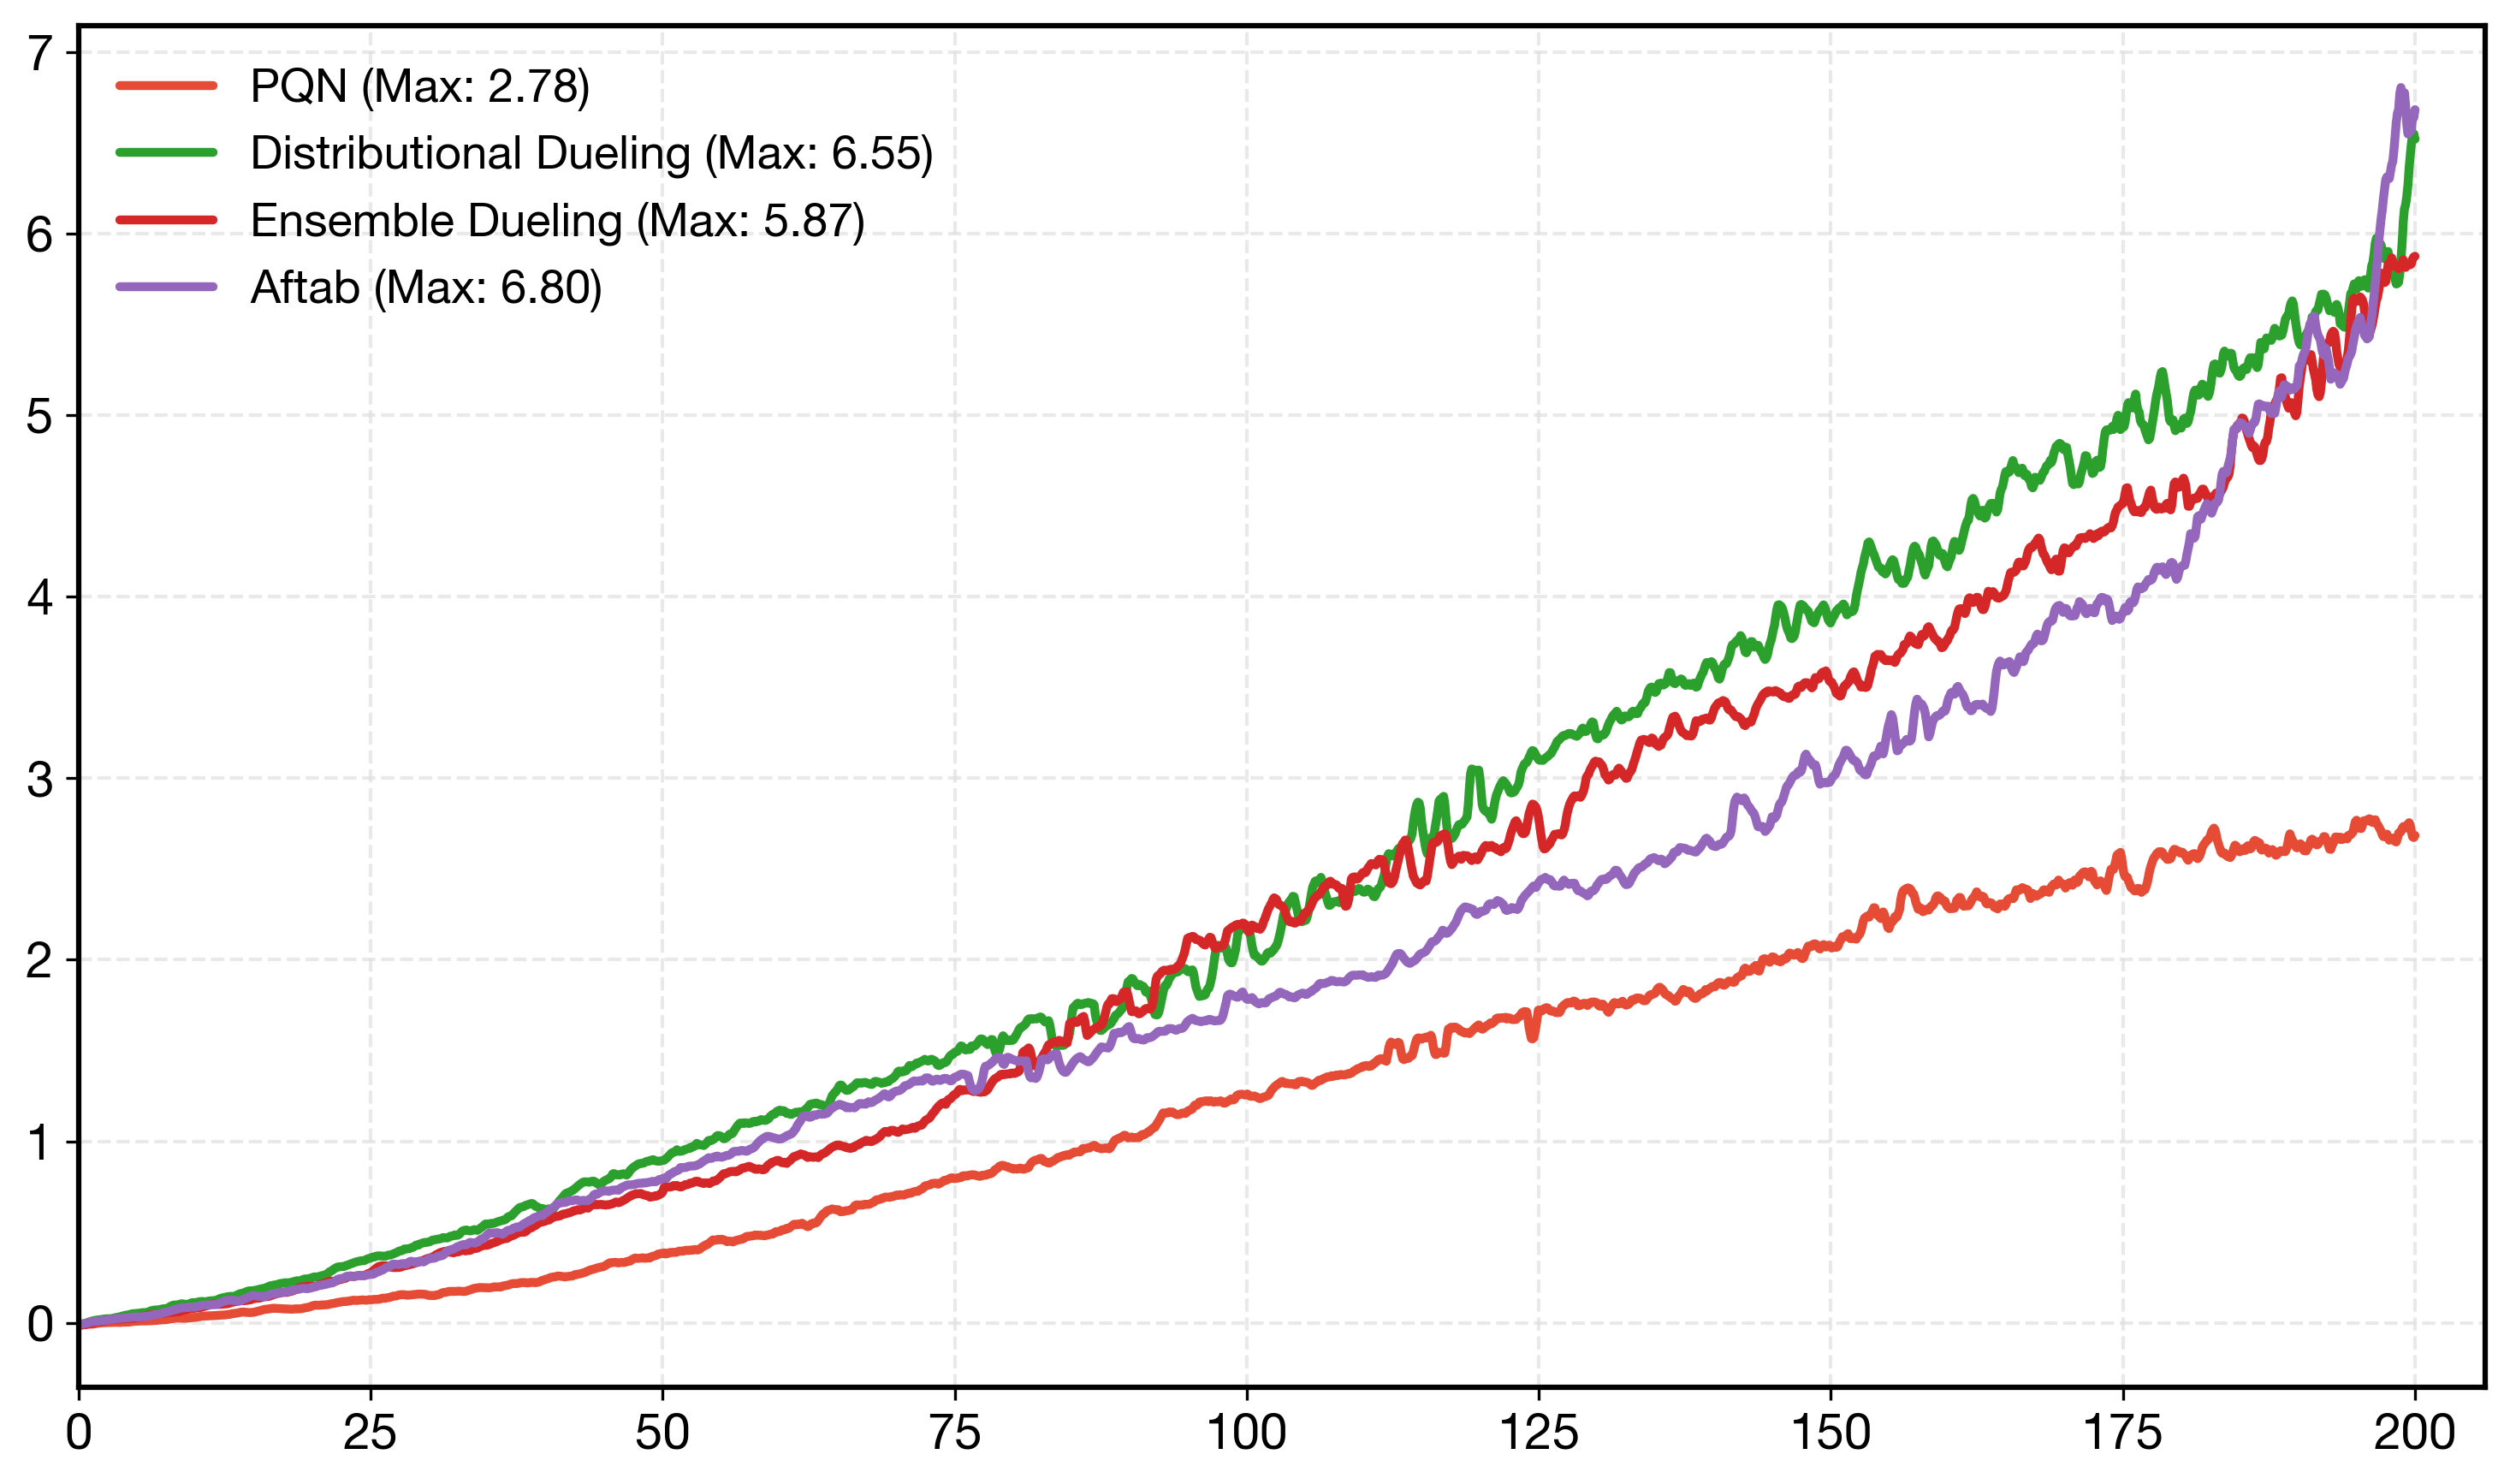
|
| IQM HNS (Last 50M Frames) |
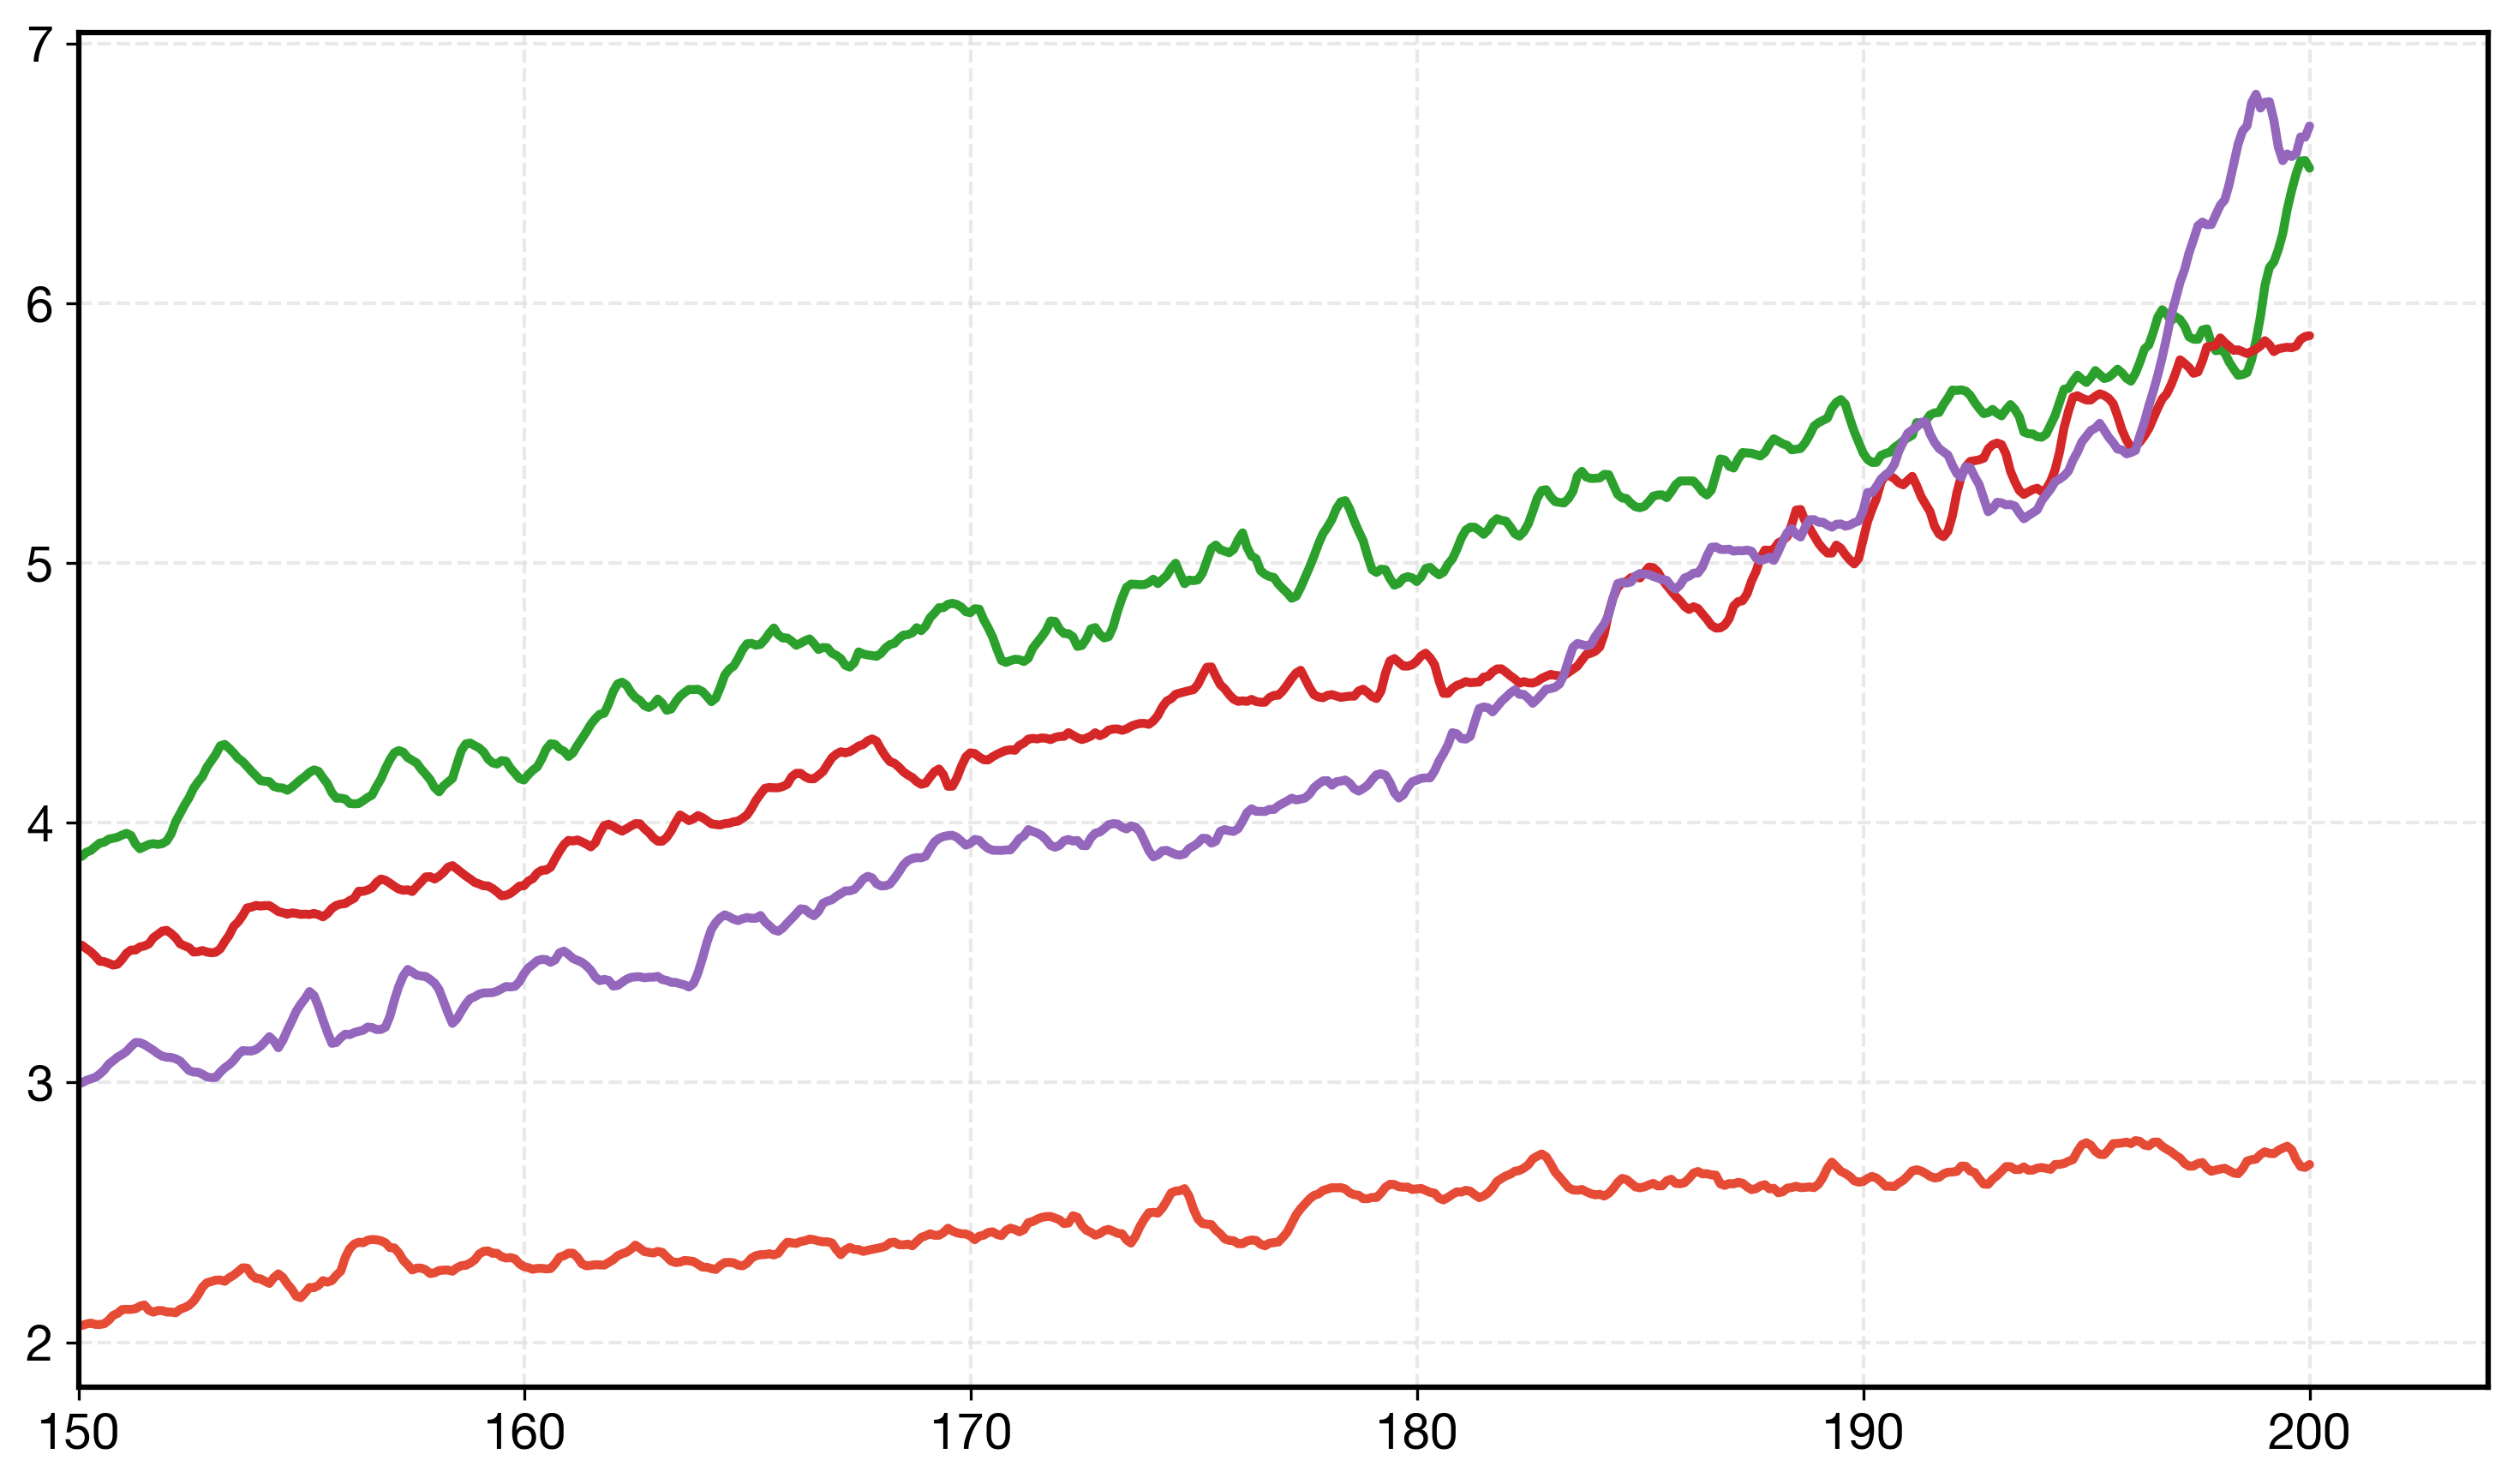
|
References:
- Stop Regressing
- Deep Exploration via Bootstrapped DQN
- Improving Regression Performance with Distributional Losses
Procgen (Overfitting Prevention) Experiments
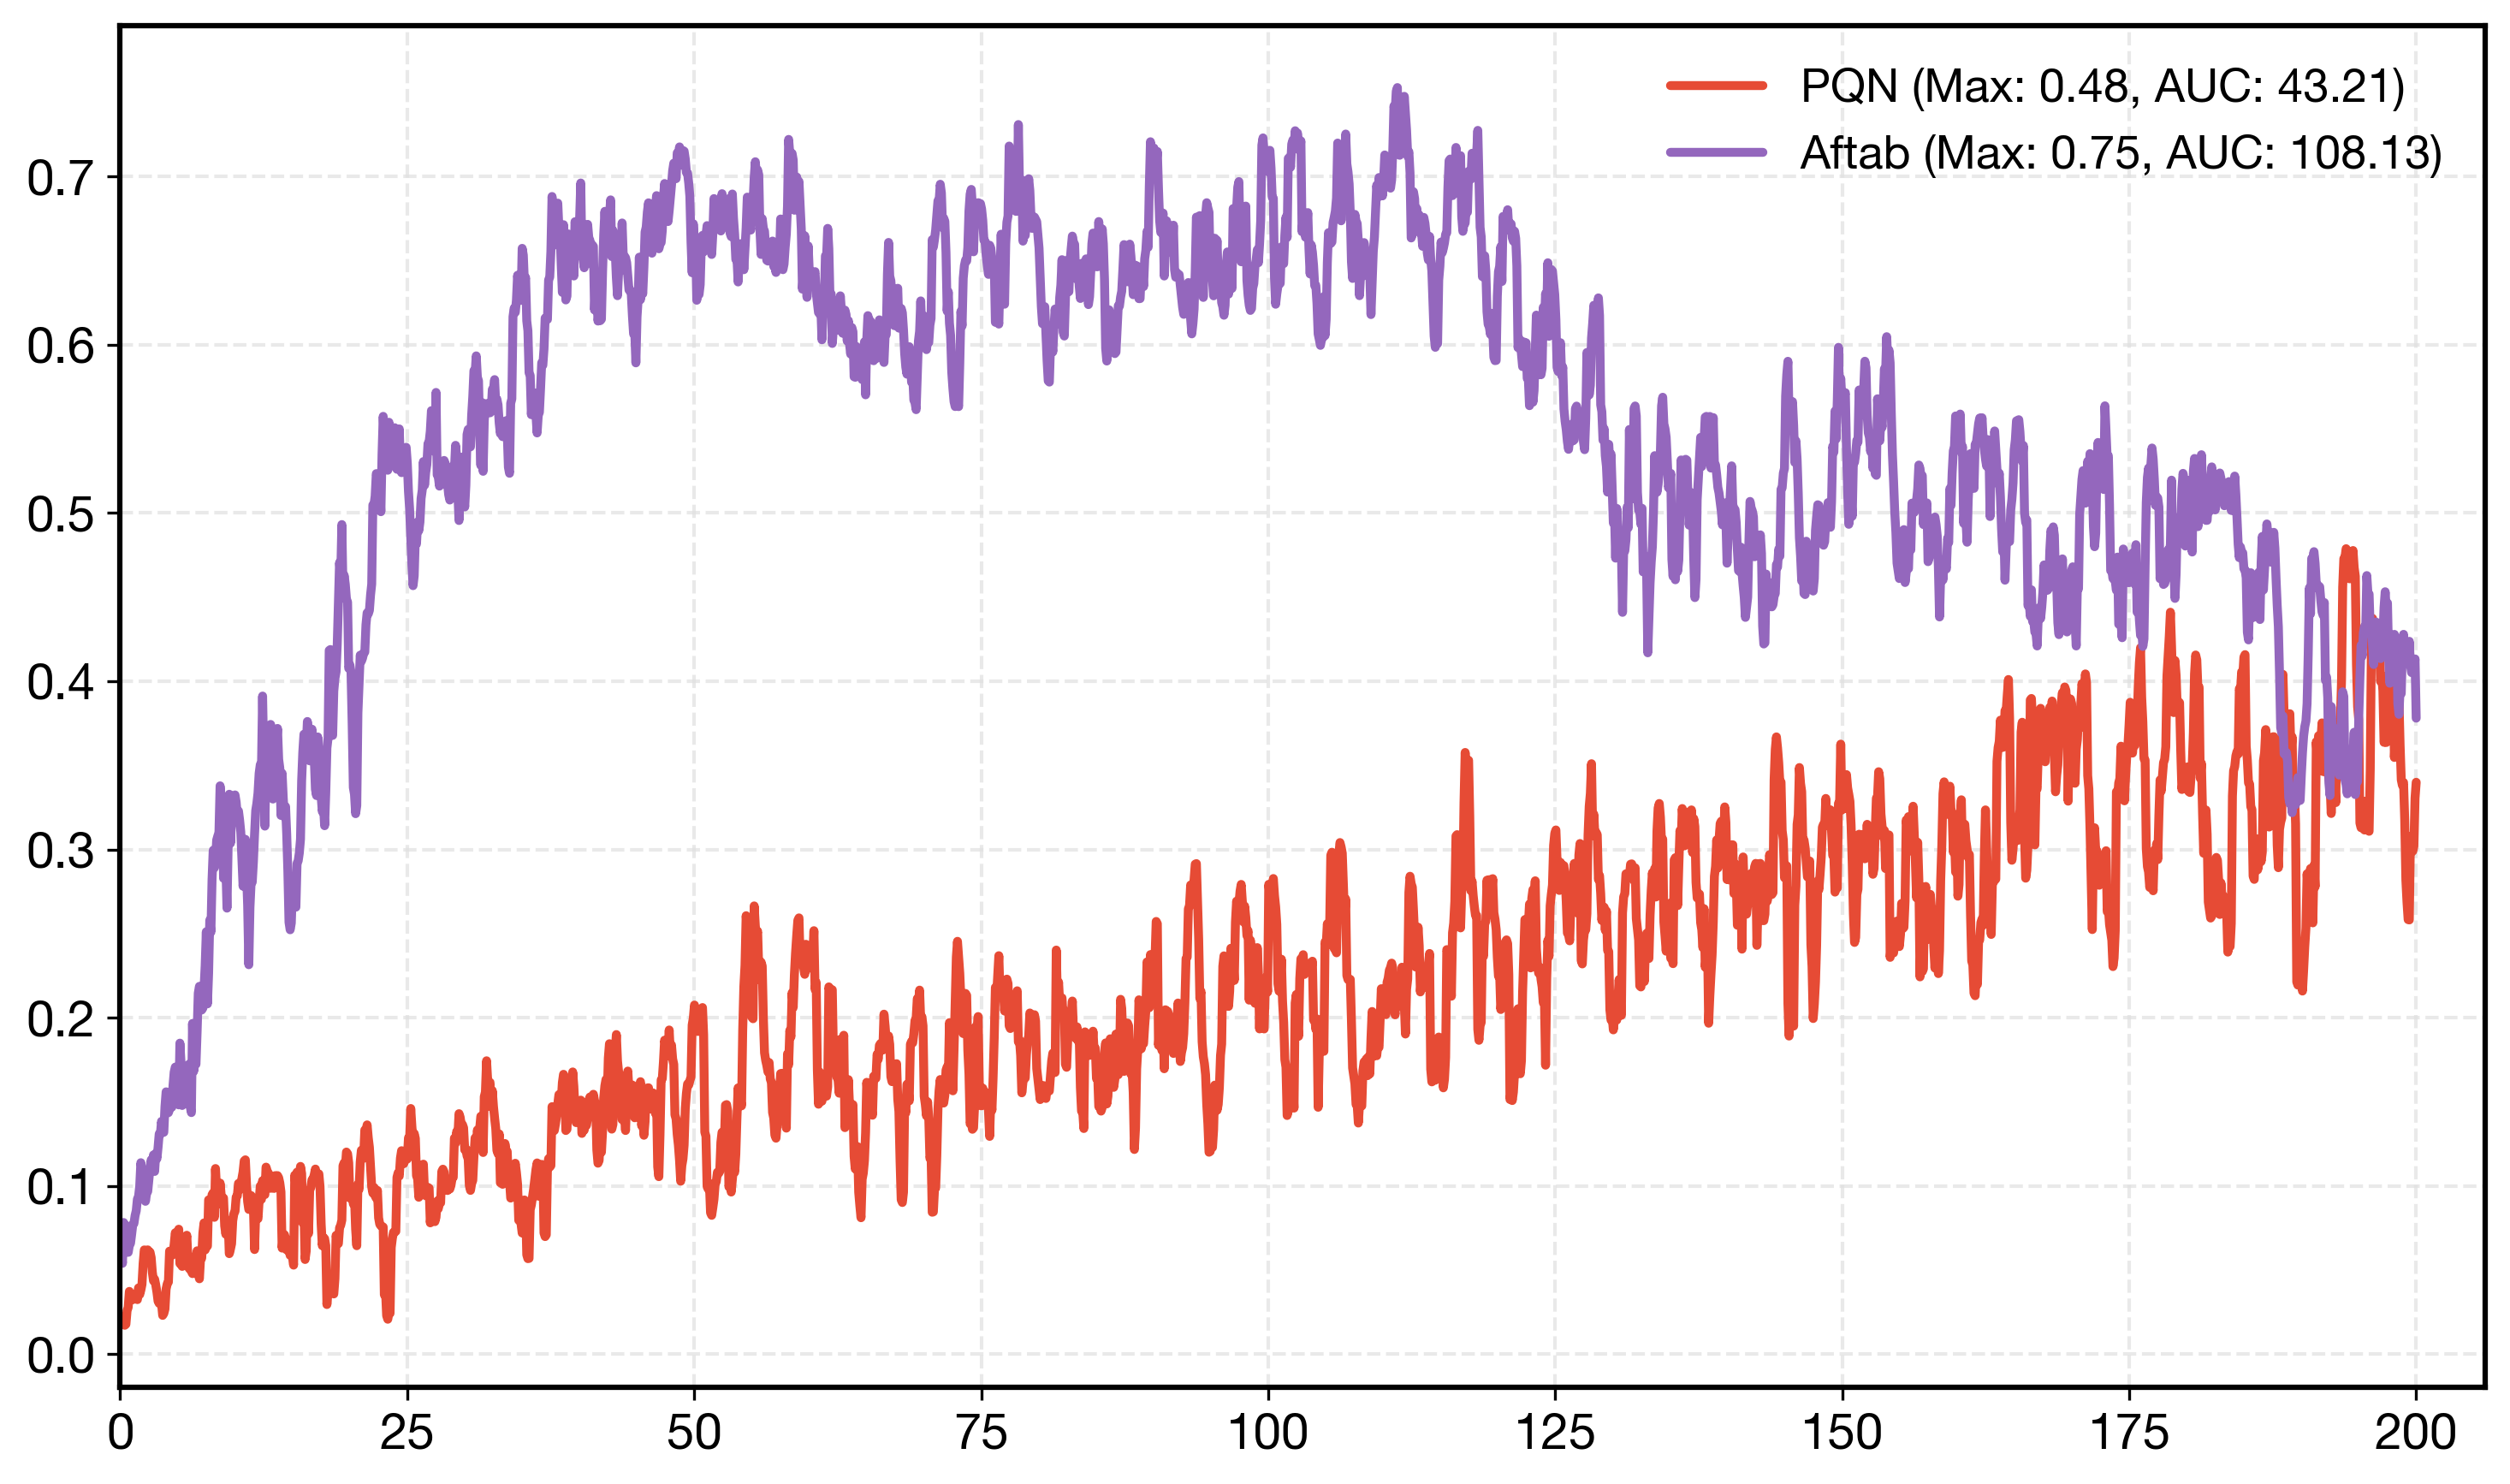
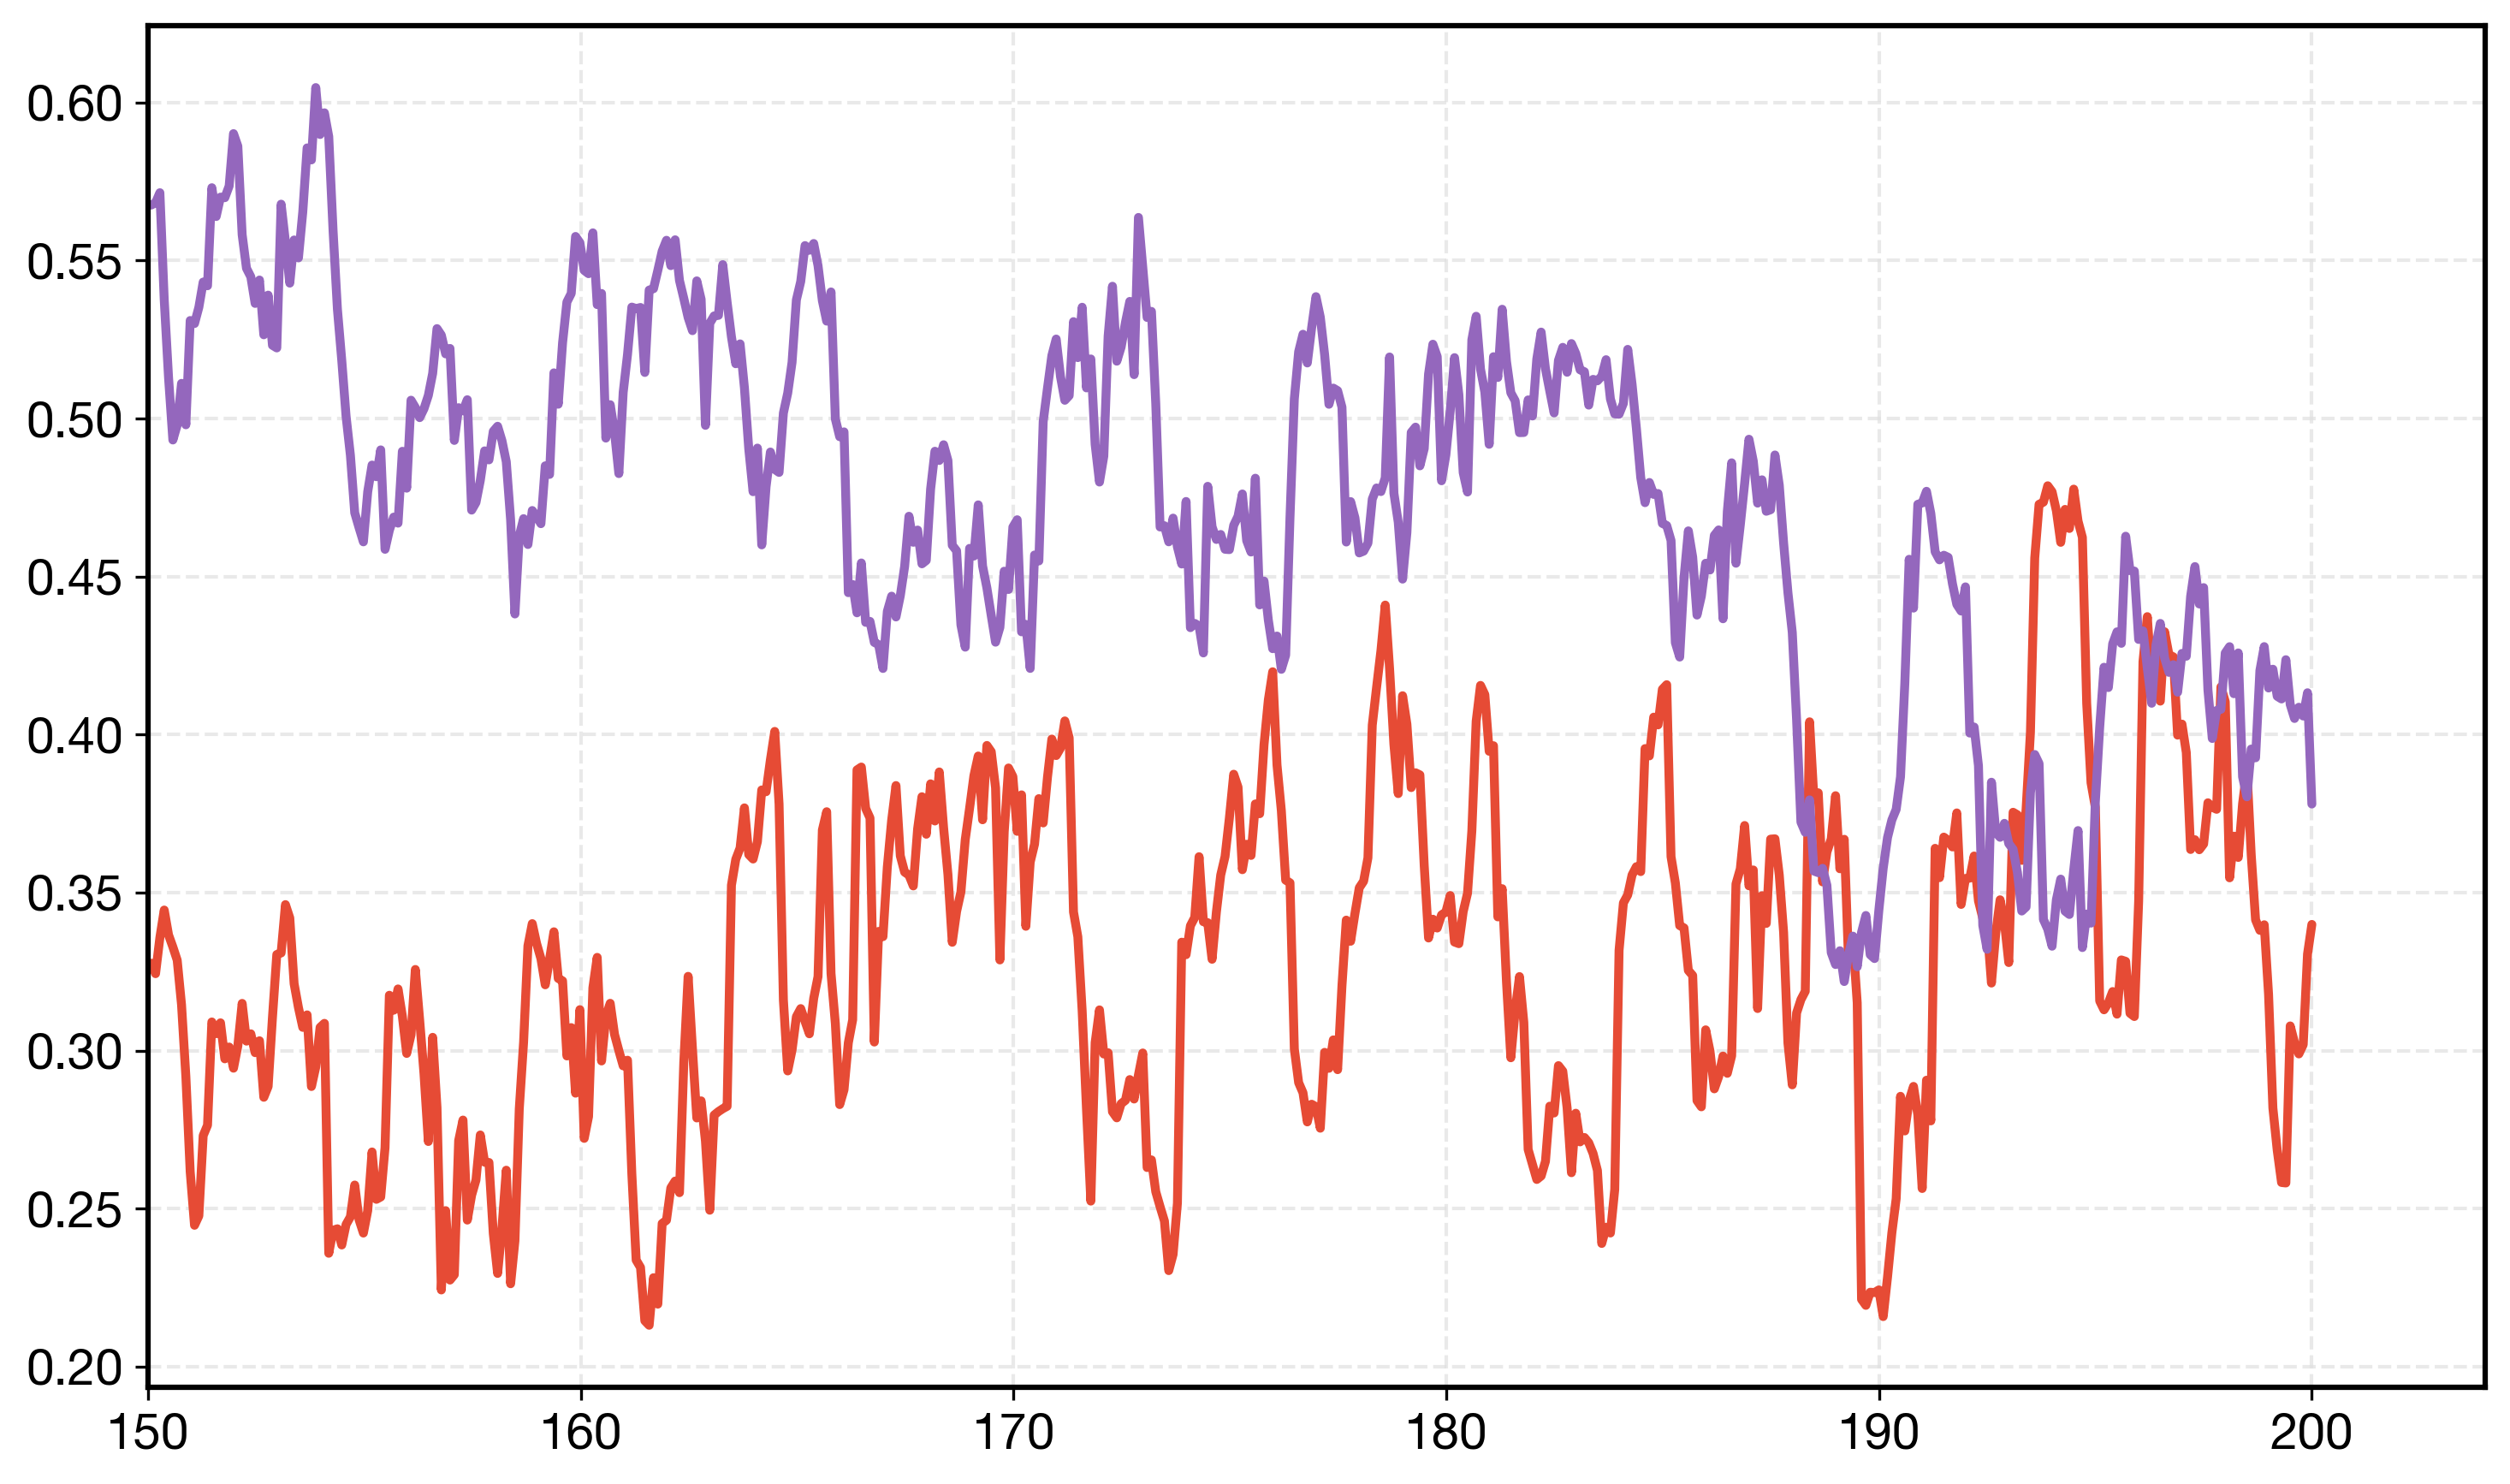
Since there are no public benchmarks comparing human-normalized-scores of Procgen environments, we created PNS (Procgen Normalized Score) that is a minimal min-max normalization of scores across seeds.
| IQM PNS |
|---|
|
| IQM PNS (Last 50M Frames) |
|
Installation
Install via pip:
pip install aftab
Alternatively, you can clone the repository and install in editable mode.
git clone https://github.com/tahashieenavaz/aftab.git aftab_source
pip install -e aftab_source
We highly recommend using Micromamba for creating virtual environments with instructions detailed here.
Training Agents
Currently JAX API is under development and is planned to be finished by the end of 2026. Contributions are highly encouraged.
from aftab import Aftab
from aftab import aftab_environments

seeds = [1, 2, 3, 4]

for environment in aftab_environments:
    agent = Aftab(encoder="gamma", frames="pilot")
    for seed in seeds:
        agent.train(environment=environment, seed=seed)
        agent.log()
Custom Encoder Injection
You can define your own encoder as a PyTorch module and pass it to the agent:
import torch
from aftab import Aftab

class CustomImageEncoder(torch.nn.Module):
    pass

agent = Aftab(encoder=CustomImageEncoder)
Results
All experimental results are organized by experiment category. Each section contains:
- Tables: numerical results (HNS/PHS and raw scores)
- Charts: IQM normalized scores and training curves
Encoder Experiments
Tables
Charts
Hadamax Experiments
Tables
Charts
Q-Value Experiments
Tables
Charts
Procgen Experiments
Tables
Charts
Model Complexity
Base Variants
| Variant | Encoder Parameters | Regression Head Parameters | Total Parameters | Encoder FLOPs | Regression Head FLOPs | Total FLOPs |
|---|---|---|---|---|---|---|
| PQN | 78,304 | 1,686,500 | 1,764,804 | 7.734 | 1.610 | 9.347 |
| Alpha | 174,752 | 1,782,948 | 1,957,700 | 27.541 | 1.610 | 29.151 |
| Beta | 89,008 | 1,782,948 | 1,871,956 | 61.515 | 1.610 | 63.126 |
| Gamma | 117,168 | 1,725,364 | 1,842,532 | 22.901 | 1.610 | 24.512 |
| Delta | 78,552 | 1,850,588 | 1,929,140 | 6.143 | 1.774 | 7.917 |
| Epsilon | 80,112 | 2,179,828 | 2,259,940 | 13.252 | 2.101 | 15.354 |
| Zeta | 77,232 | 2,537,396 | 2,614,628 | 25.362 | 2.462 | 27.824 |
| Eta | 78,400 | 23,739,460 | 23,817,860 | 28.422 | 23.663 | 52.085 |
| Theta | 76,288 | 1,127,428 | 1,203,716 | 9.065 | 1.053 | 10.118 |
Note: The Eta variant has significantly more parameters than other variants, primarily due to the encoder producing a large number of features.
Hadamax Variants
| Variant | Encoder Parameters | Regression Head Parameters | Total Parameters | Encoder FLOPs | Regression Head FLOPs | Total FLOPs |
|---|---|---|---|---|---|---|
| Hadamax | 156,608 | 3,968,516 | 4,125,124 | 159.014 | 3.969 | 162.984 |
| Gamma-Hadamax-Valid | 234,336 | 1,609,220 | 1,843,556 | 122.001 | 1.610 | 123.611 |
| Gamma-Hadamax-Same | 234,336 | 3,280,388 | 3,514,724 | 129.300 | 3.281 | 132.581 |
Hyperparameters
The following tables reflect the defaults defined by Aftab. The
experiment_name argument is required and has no default.
Training and Environment
Hyperparameter (Aftab argument) |
Default |
|---|---|
Encoder (encoder) |
Gamma-Hadamax-Valid |
Network (network) |
Distributional Bootstrapped (Ensemble) Dueling |
Total frames (frames) |
200,000,000 |
Frame skip (frame_skip) |
4 |
Frame stack (frame_stack) |
4 |
No-op maximum (noop) |
30 |
Learning rate (lr) |
$2.5 \times 10^{-4}$ |
Training environments (train_environments) |
128 |
Test environments (test_environments) |
8 |
Steps per update (steps_per_update) |
32 |
| Batch size (derived) | 4,096 |
Mini-batches (mini_batches) |
32 |
| Mini-batch size (derived) | 128 |
| Discount factor ($\gamma$) | 0.99 |
Return $\lambda$ (return_lambda) |
0.65 |
Epochs (epochs) |
2 |
Gradient norm (gradient_norm) |
10.0 |
Embedding dimension (embedding_dimension) |
512 |
Training episodic life (train_episodic_life) |
True |
Test episodic life (test_episodic_life) |
False |
Training reward clipping (train_reward_clip) |
True |
Test reward clipping (test_reward_clip) |
True |
| Epsilon Schedule | Linear |
| Epsilon Annealing Ratio | 10% |
Optimizer
Hyperparameter (Aftab argument) |
Default |
|---|---|
Optimizer (optimizer) |
Rectified Adam ("radam") |
Epsilon (optimizer_epsilon) |
$1 \times 10^{-5}$ |
Weight decay (optimizer_weight_decay) |
0.0 |
$\beta_1$ (optimizer_first_beta) |
0.9 |
$\beta_2$ (optimizer_second_beta) |
0.999 |
Distributional and Bootstrapped (Ensemble) Q-Values
Hyperparameter (Aftab argument) |
Default |
|---|---|
Distributional bins (distributional_bins) |
51 |
Distributional minimum (distributional_min_value) |
-10.0 |
Distributional maximum (distributional_max_value) |
10.0 |
Distributional sigma (distributional_sigma) |
None (derived from the sigma ratio) |
Distributional sigma ratio (distributional_sigma_ratio) |
0.75 |
Distributional value clip (distributional_value_clip) |
0.0 |
Bootstrap heads (bootstrap_heads) |
10 |
Bootstrap probability (bootstrap_probability) |
1.0 |
Procgen Overrides
| Hyperparameter | Default | Procgen |
|---|---|---|
| Training environments | 128 | 64 (procgen_train_environments) |
| Steps per update | 32 | 256 (procgen_steps_per_update) |
| Batch size | 4,096 | 16,384 |
| Mini-batch size | 128 | 512 |
For Procgen environments, Aftab automatically applies the two overrides above; other defaults remain unchanged.
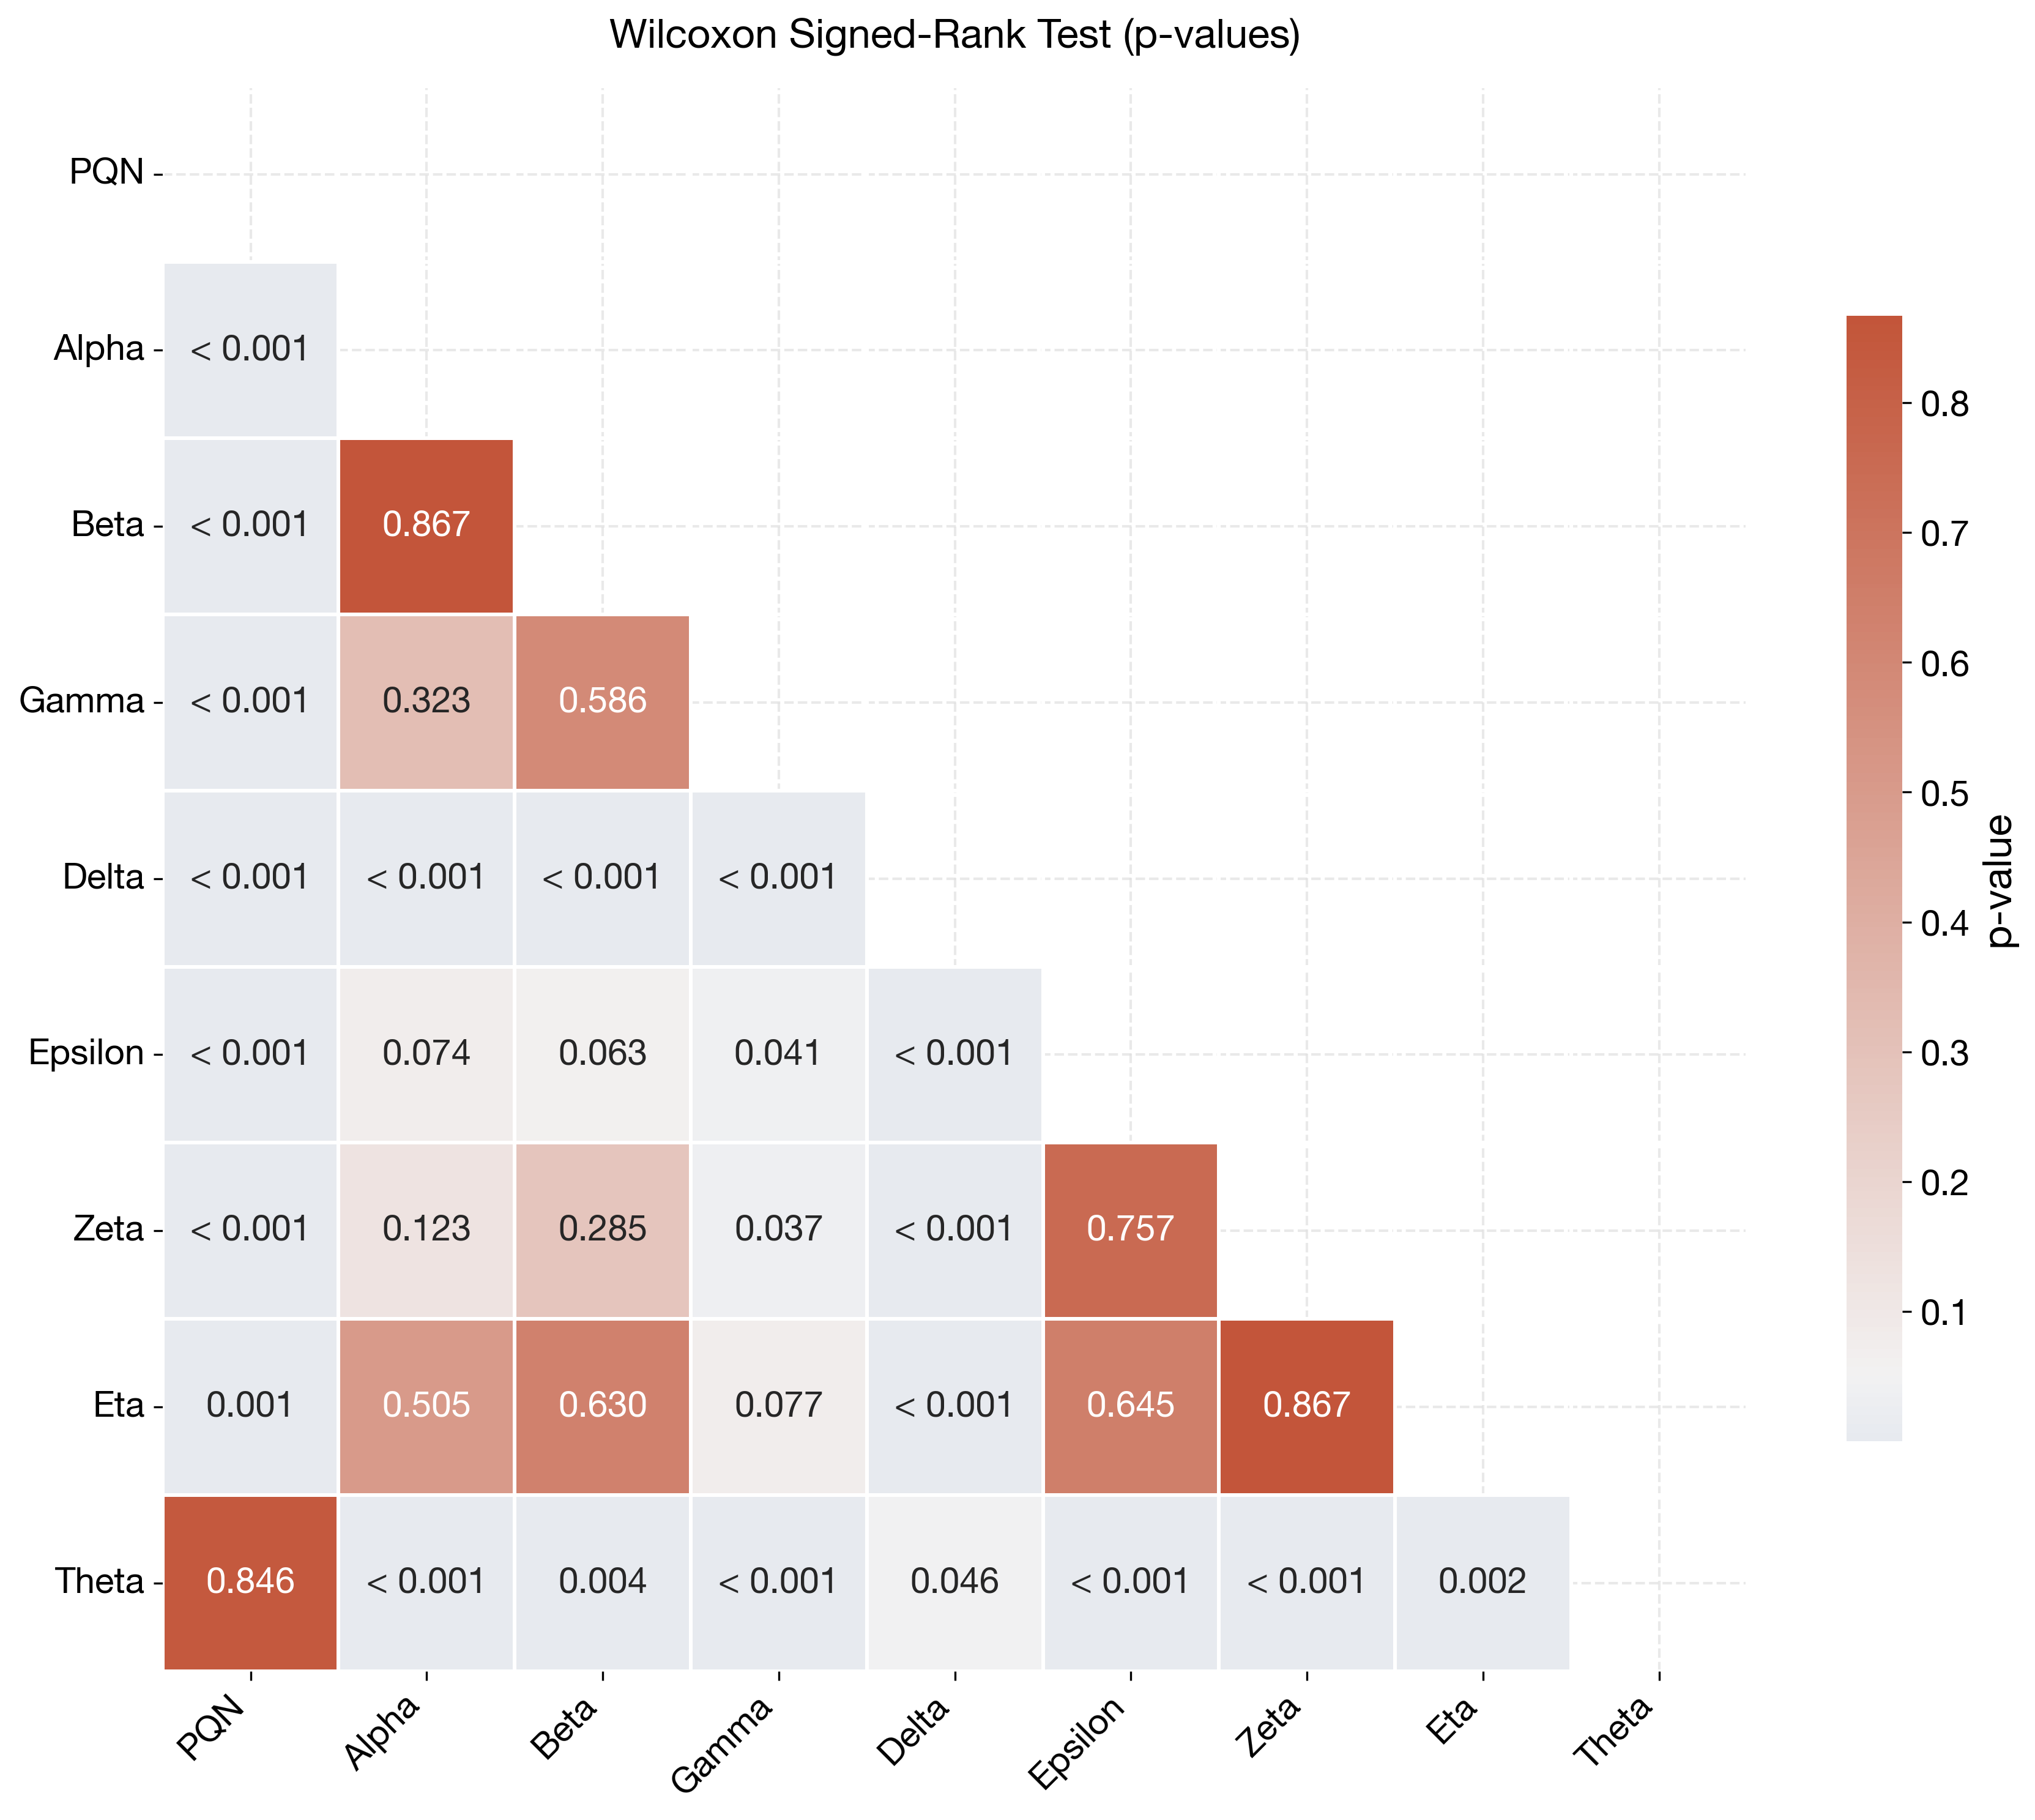
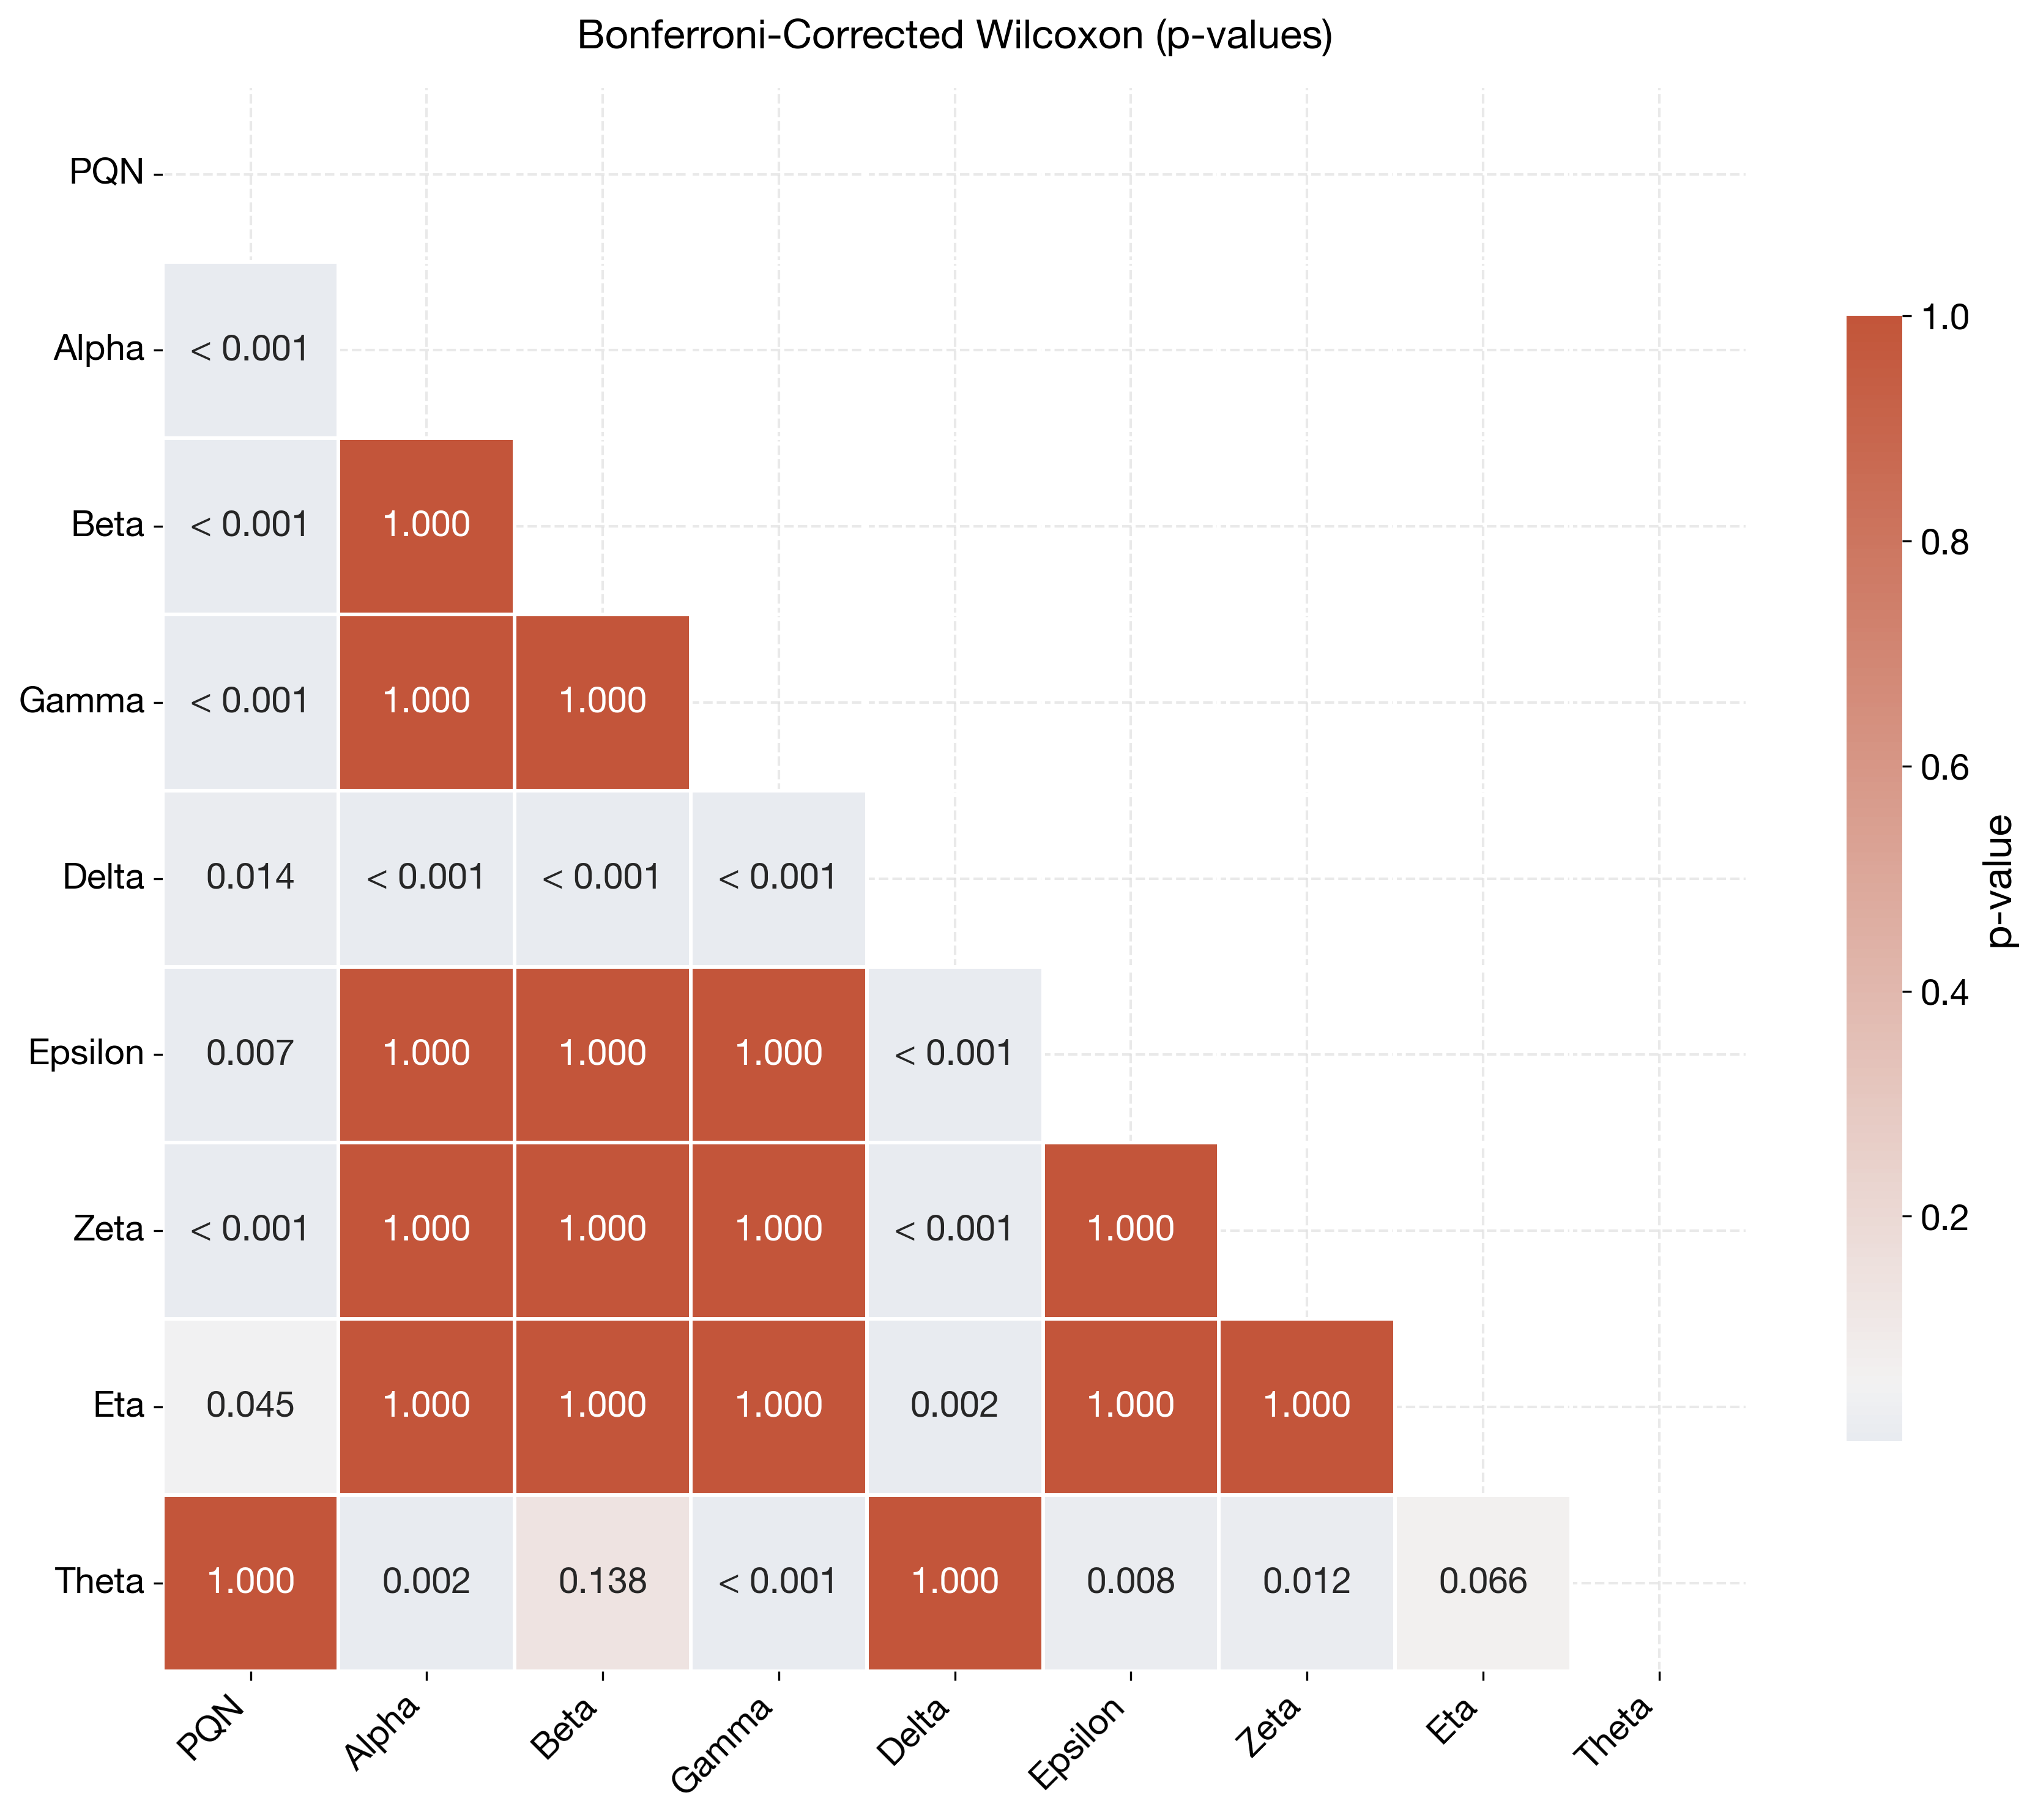
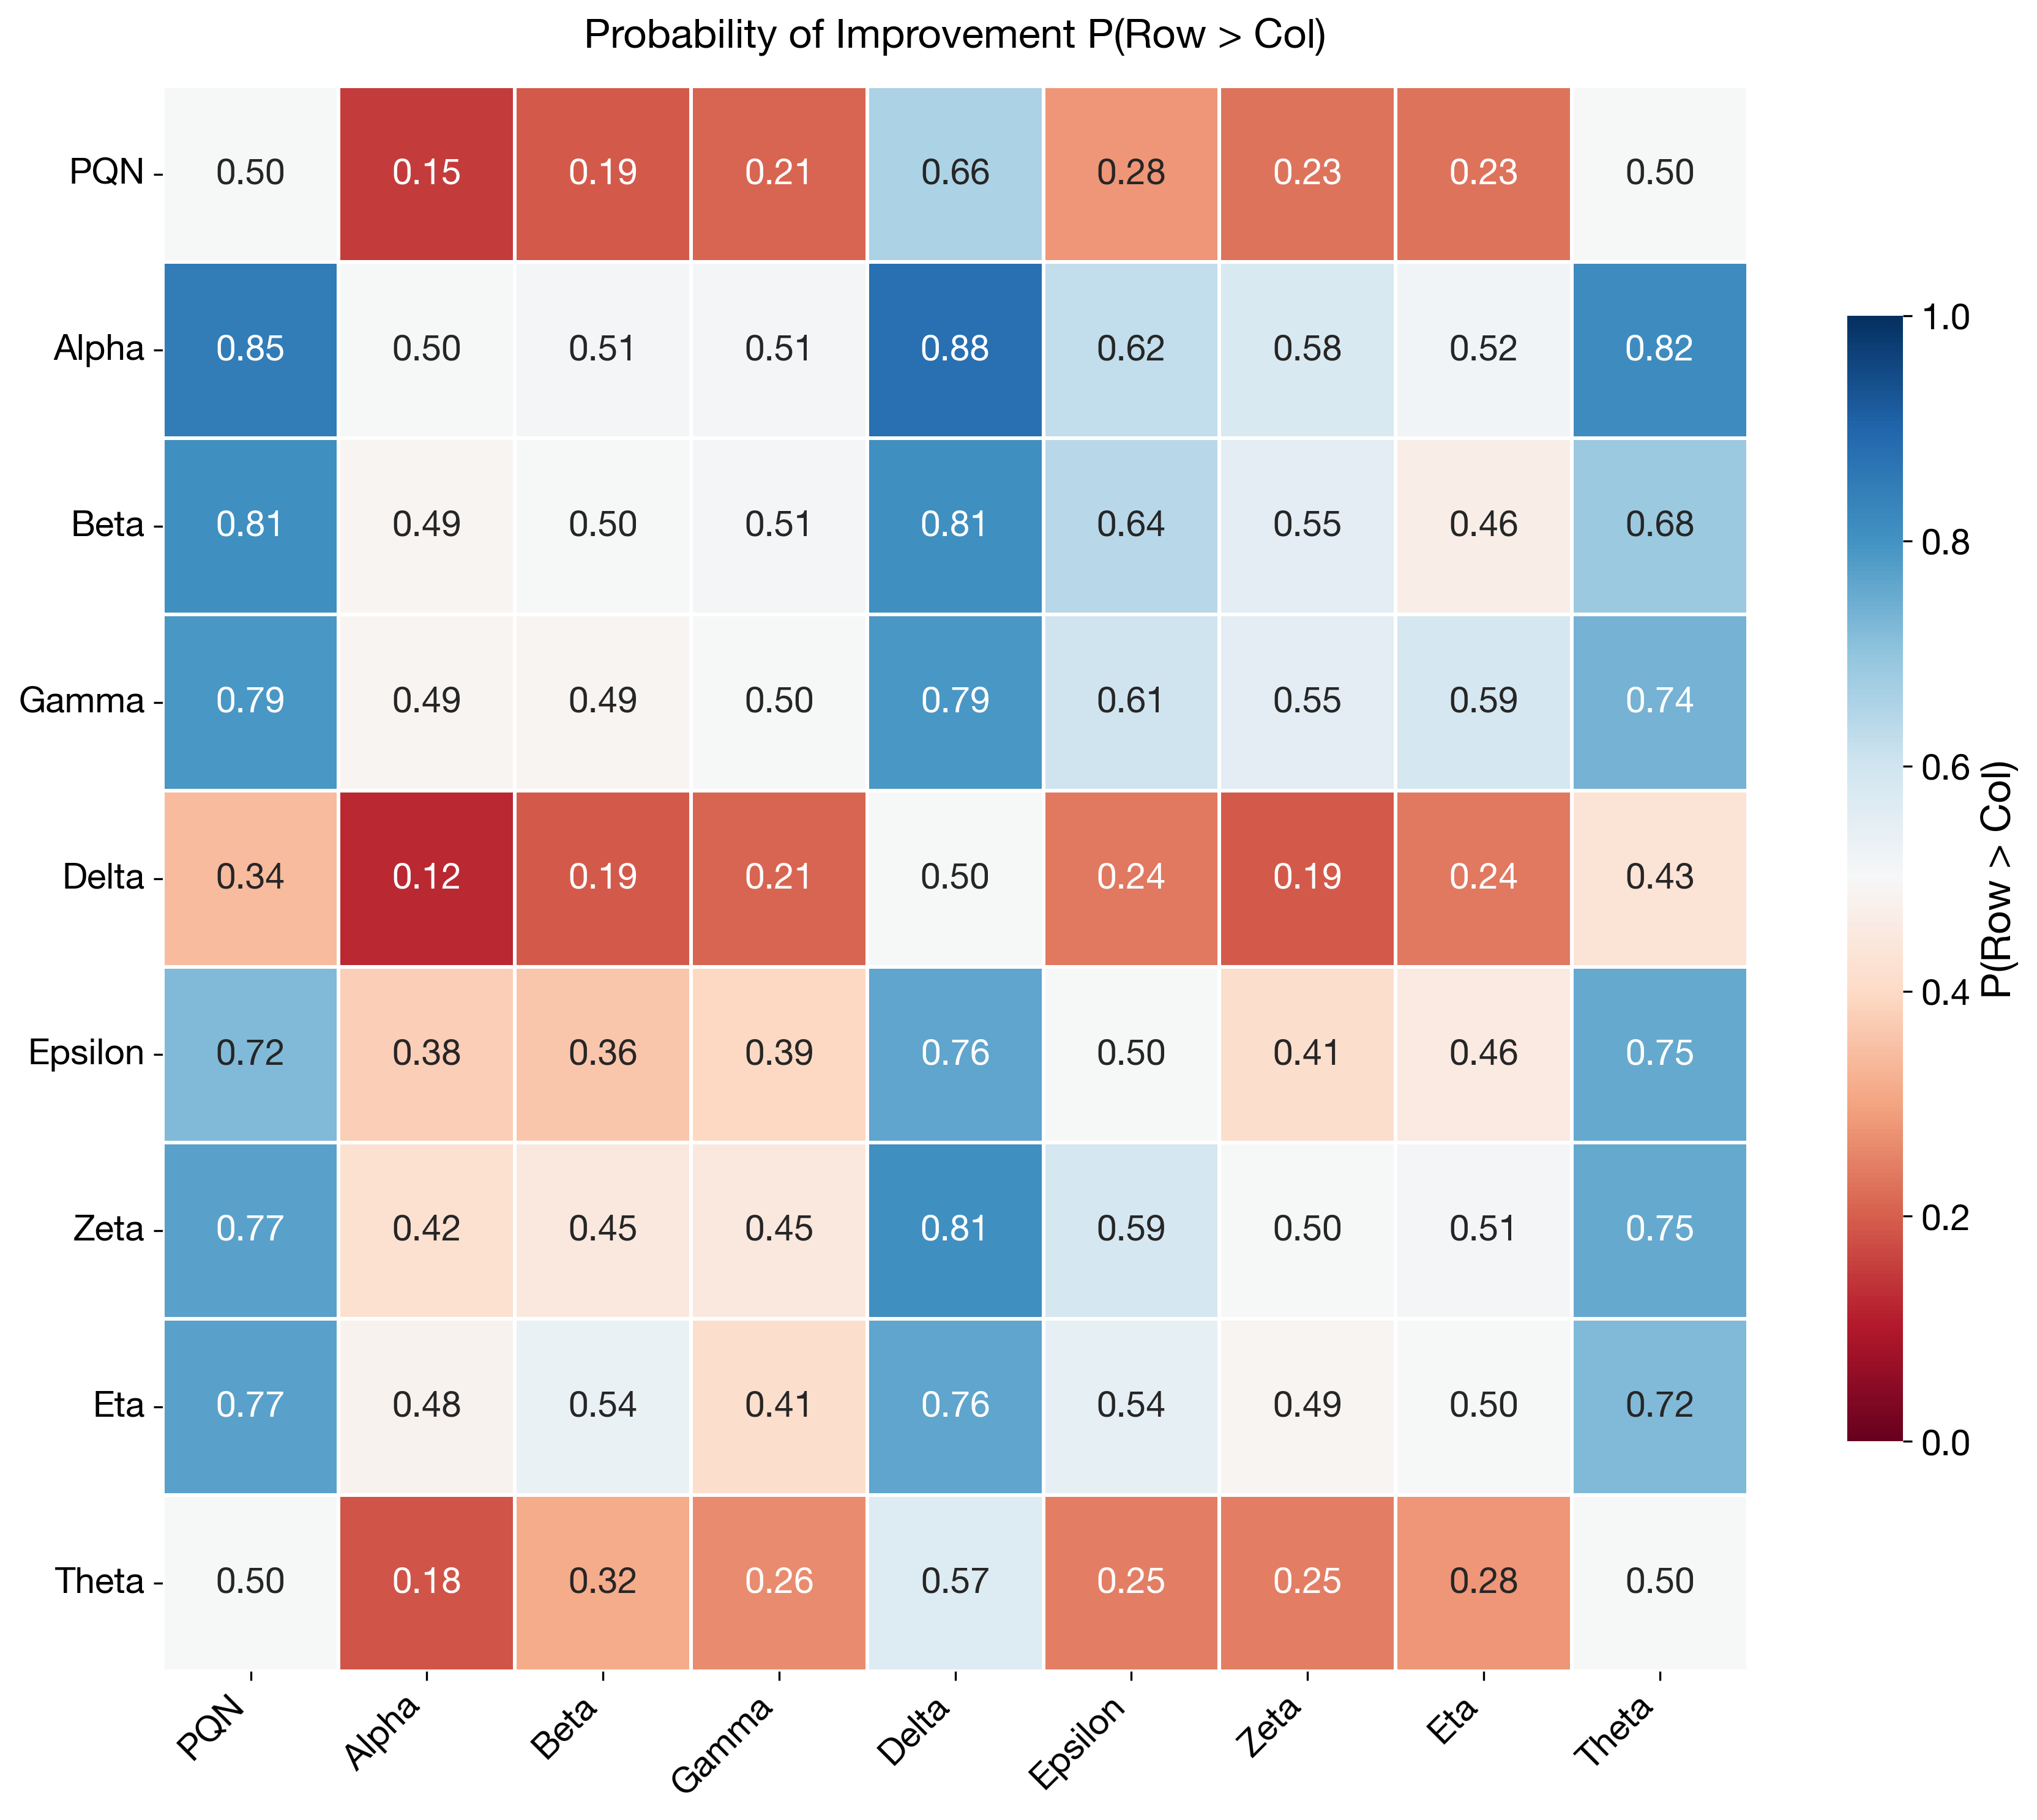
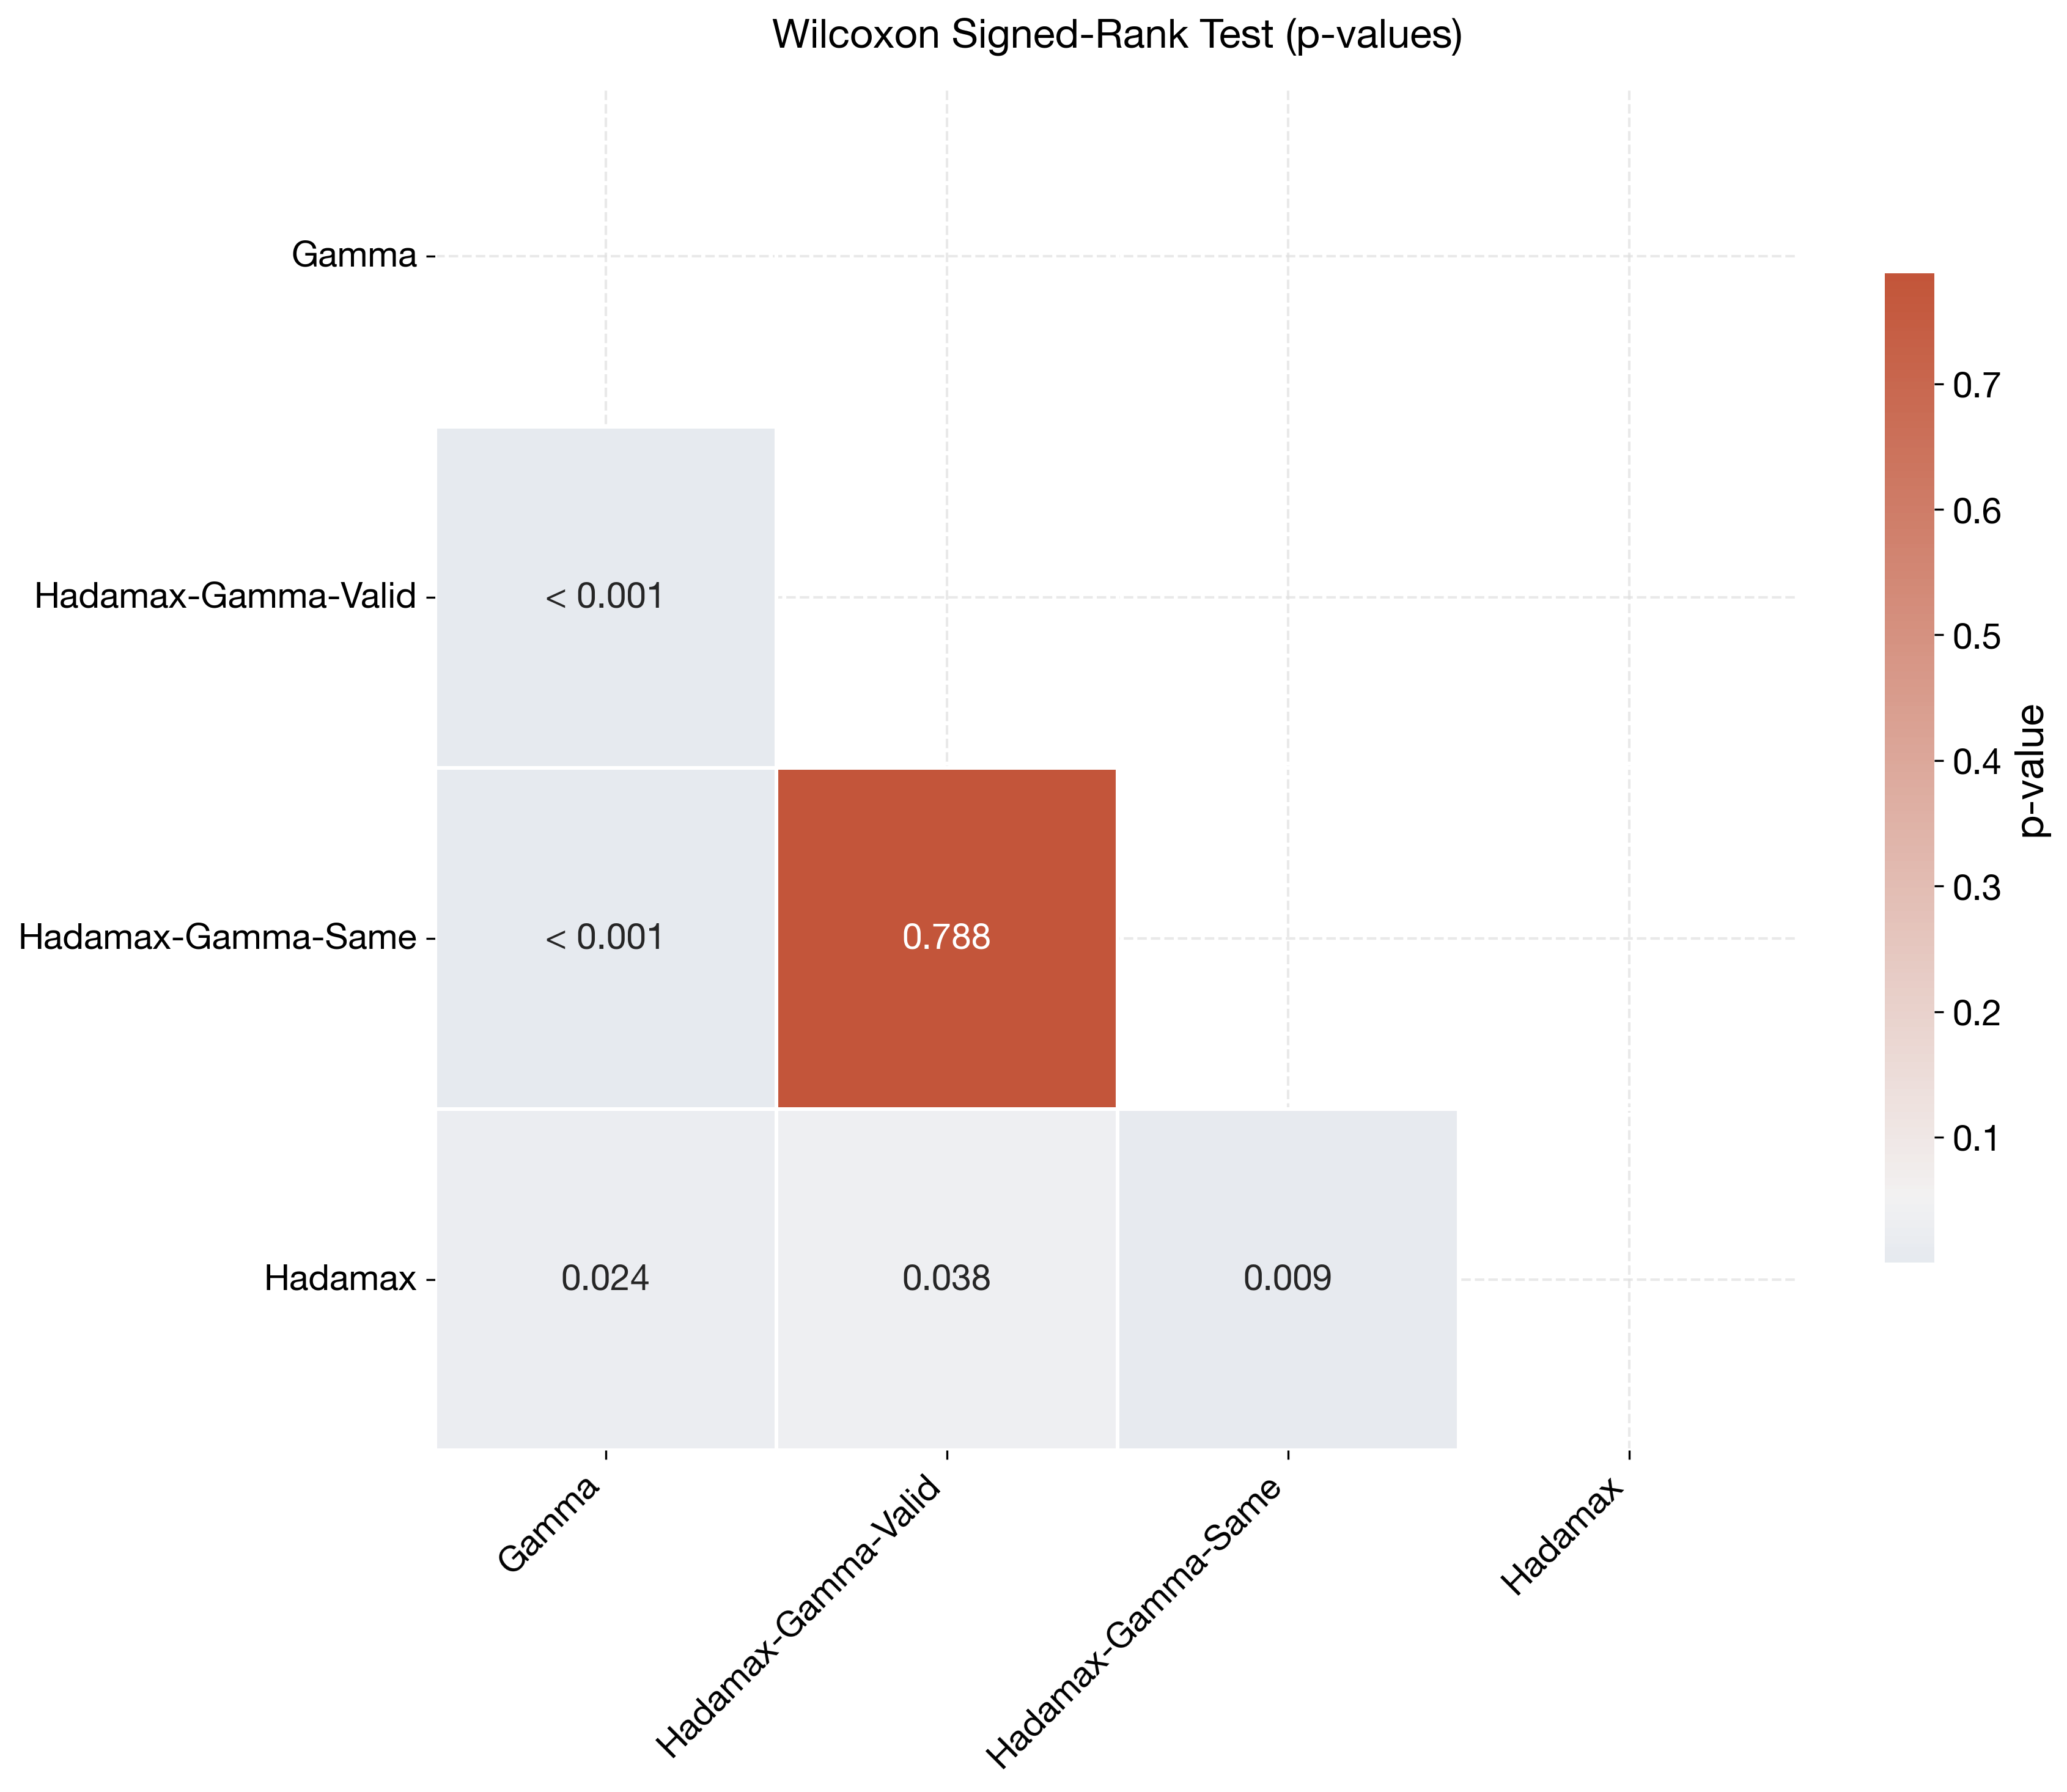
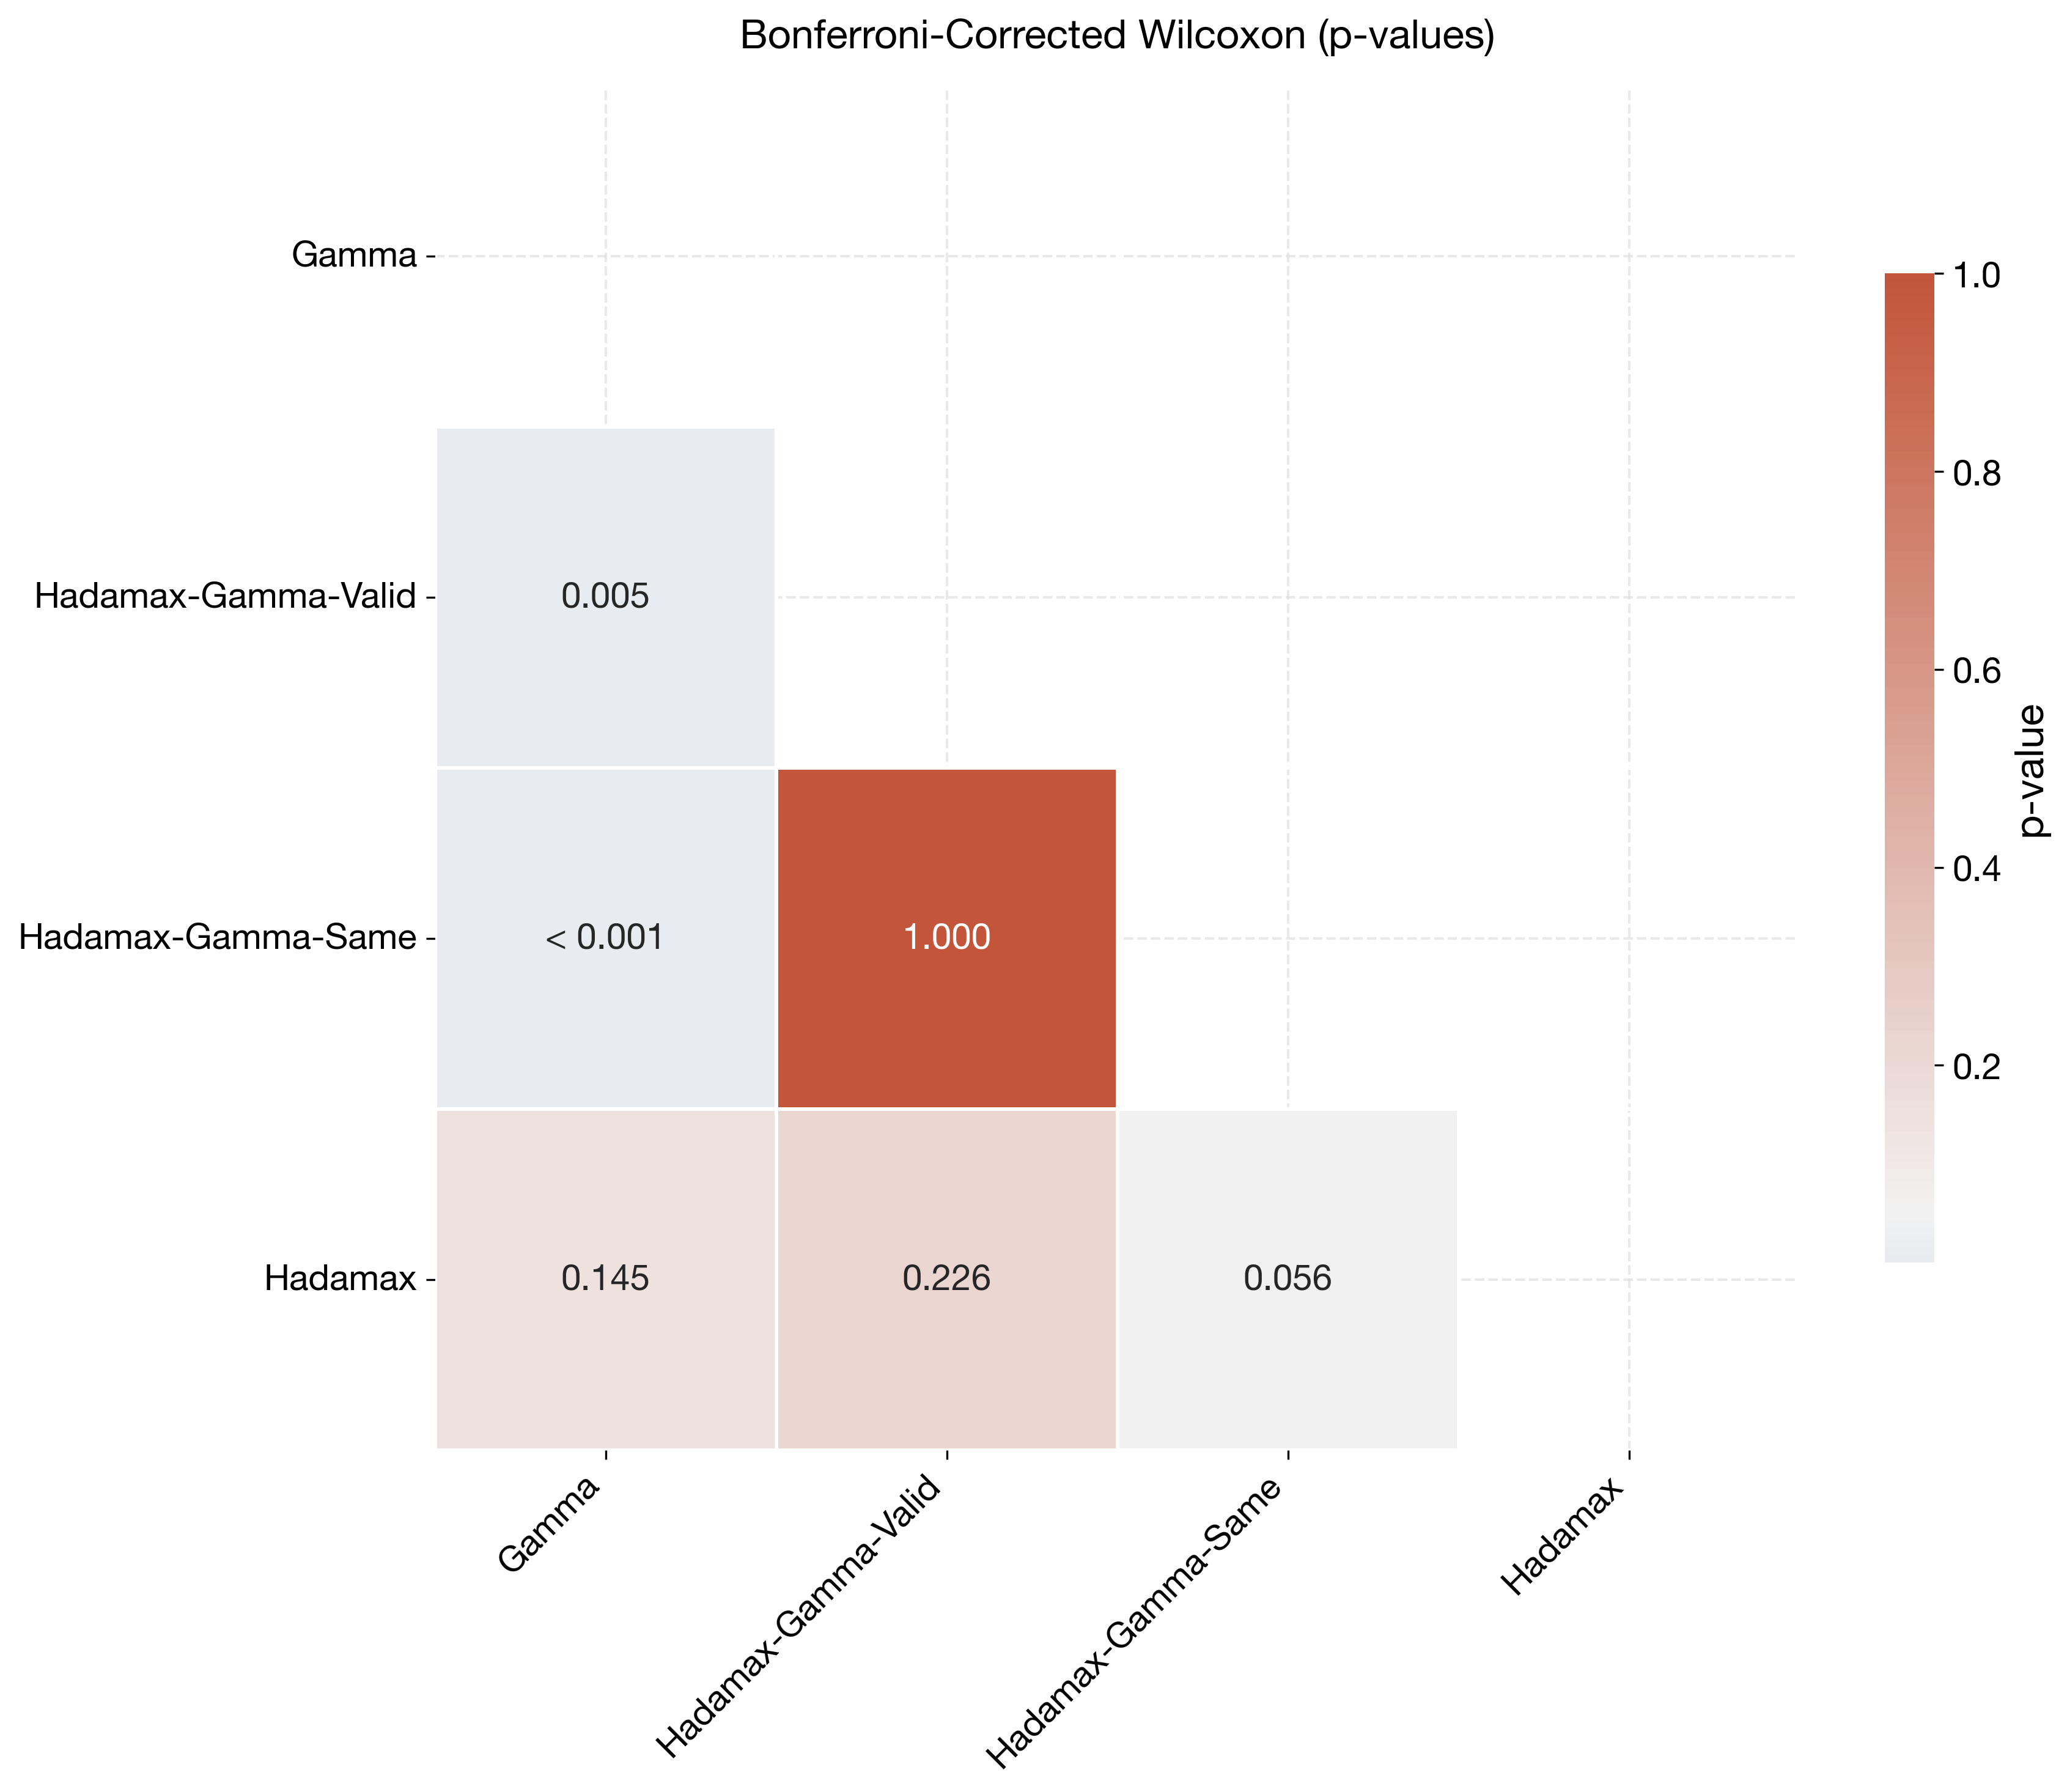
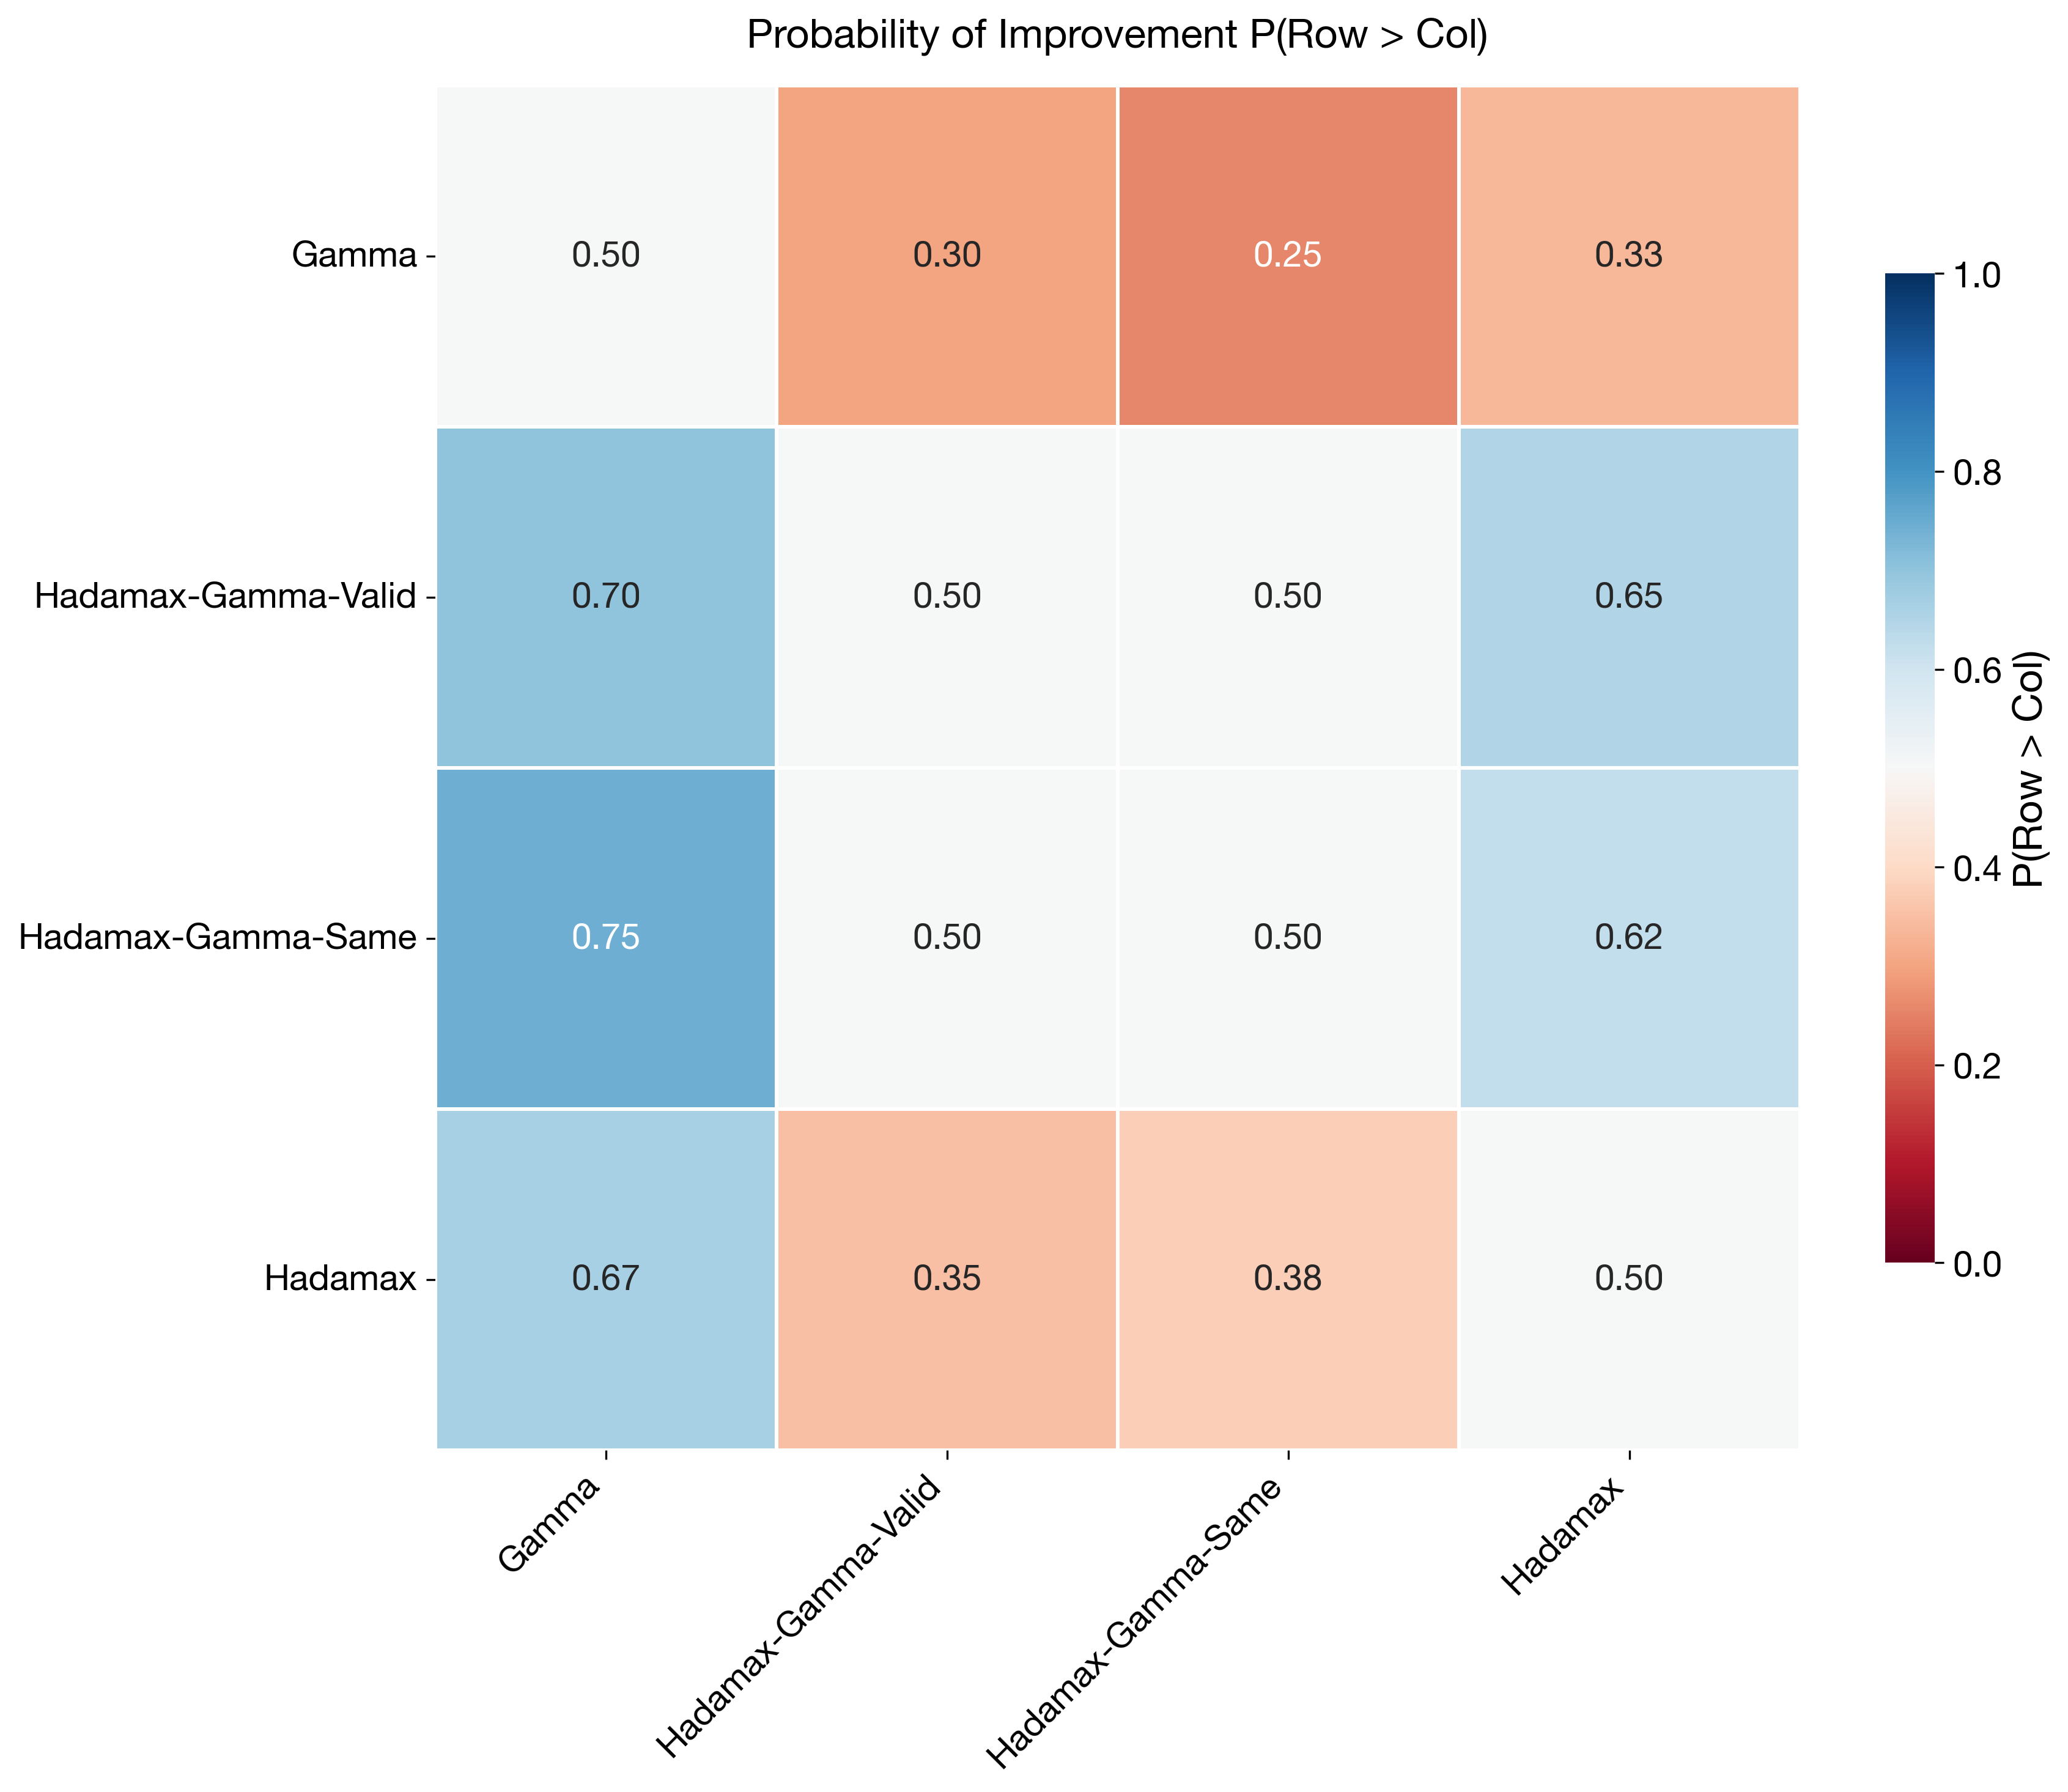
Statistical Significance
Encoder Experiments
| Wilcoxon Signed Rank Test | Wilcoxon Signed Rank Test (Corrected) |
|---|---|
|
|
| Probability of Improvement | |
|
|
Hadamax Experiments
| Wilcoxon Signed Rank Test | Wilcoxon Signed Rank Test (Corrected) |
|---|---|
|
|
| Probability of Improvement | |
|
|
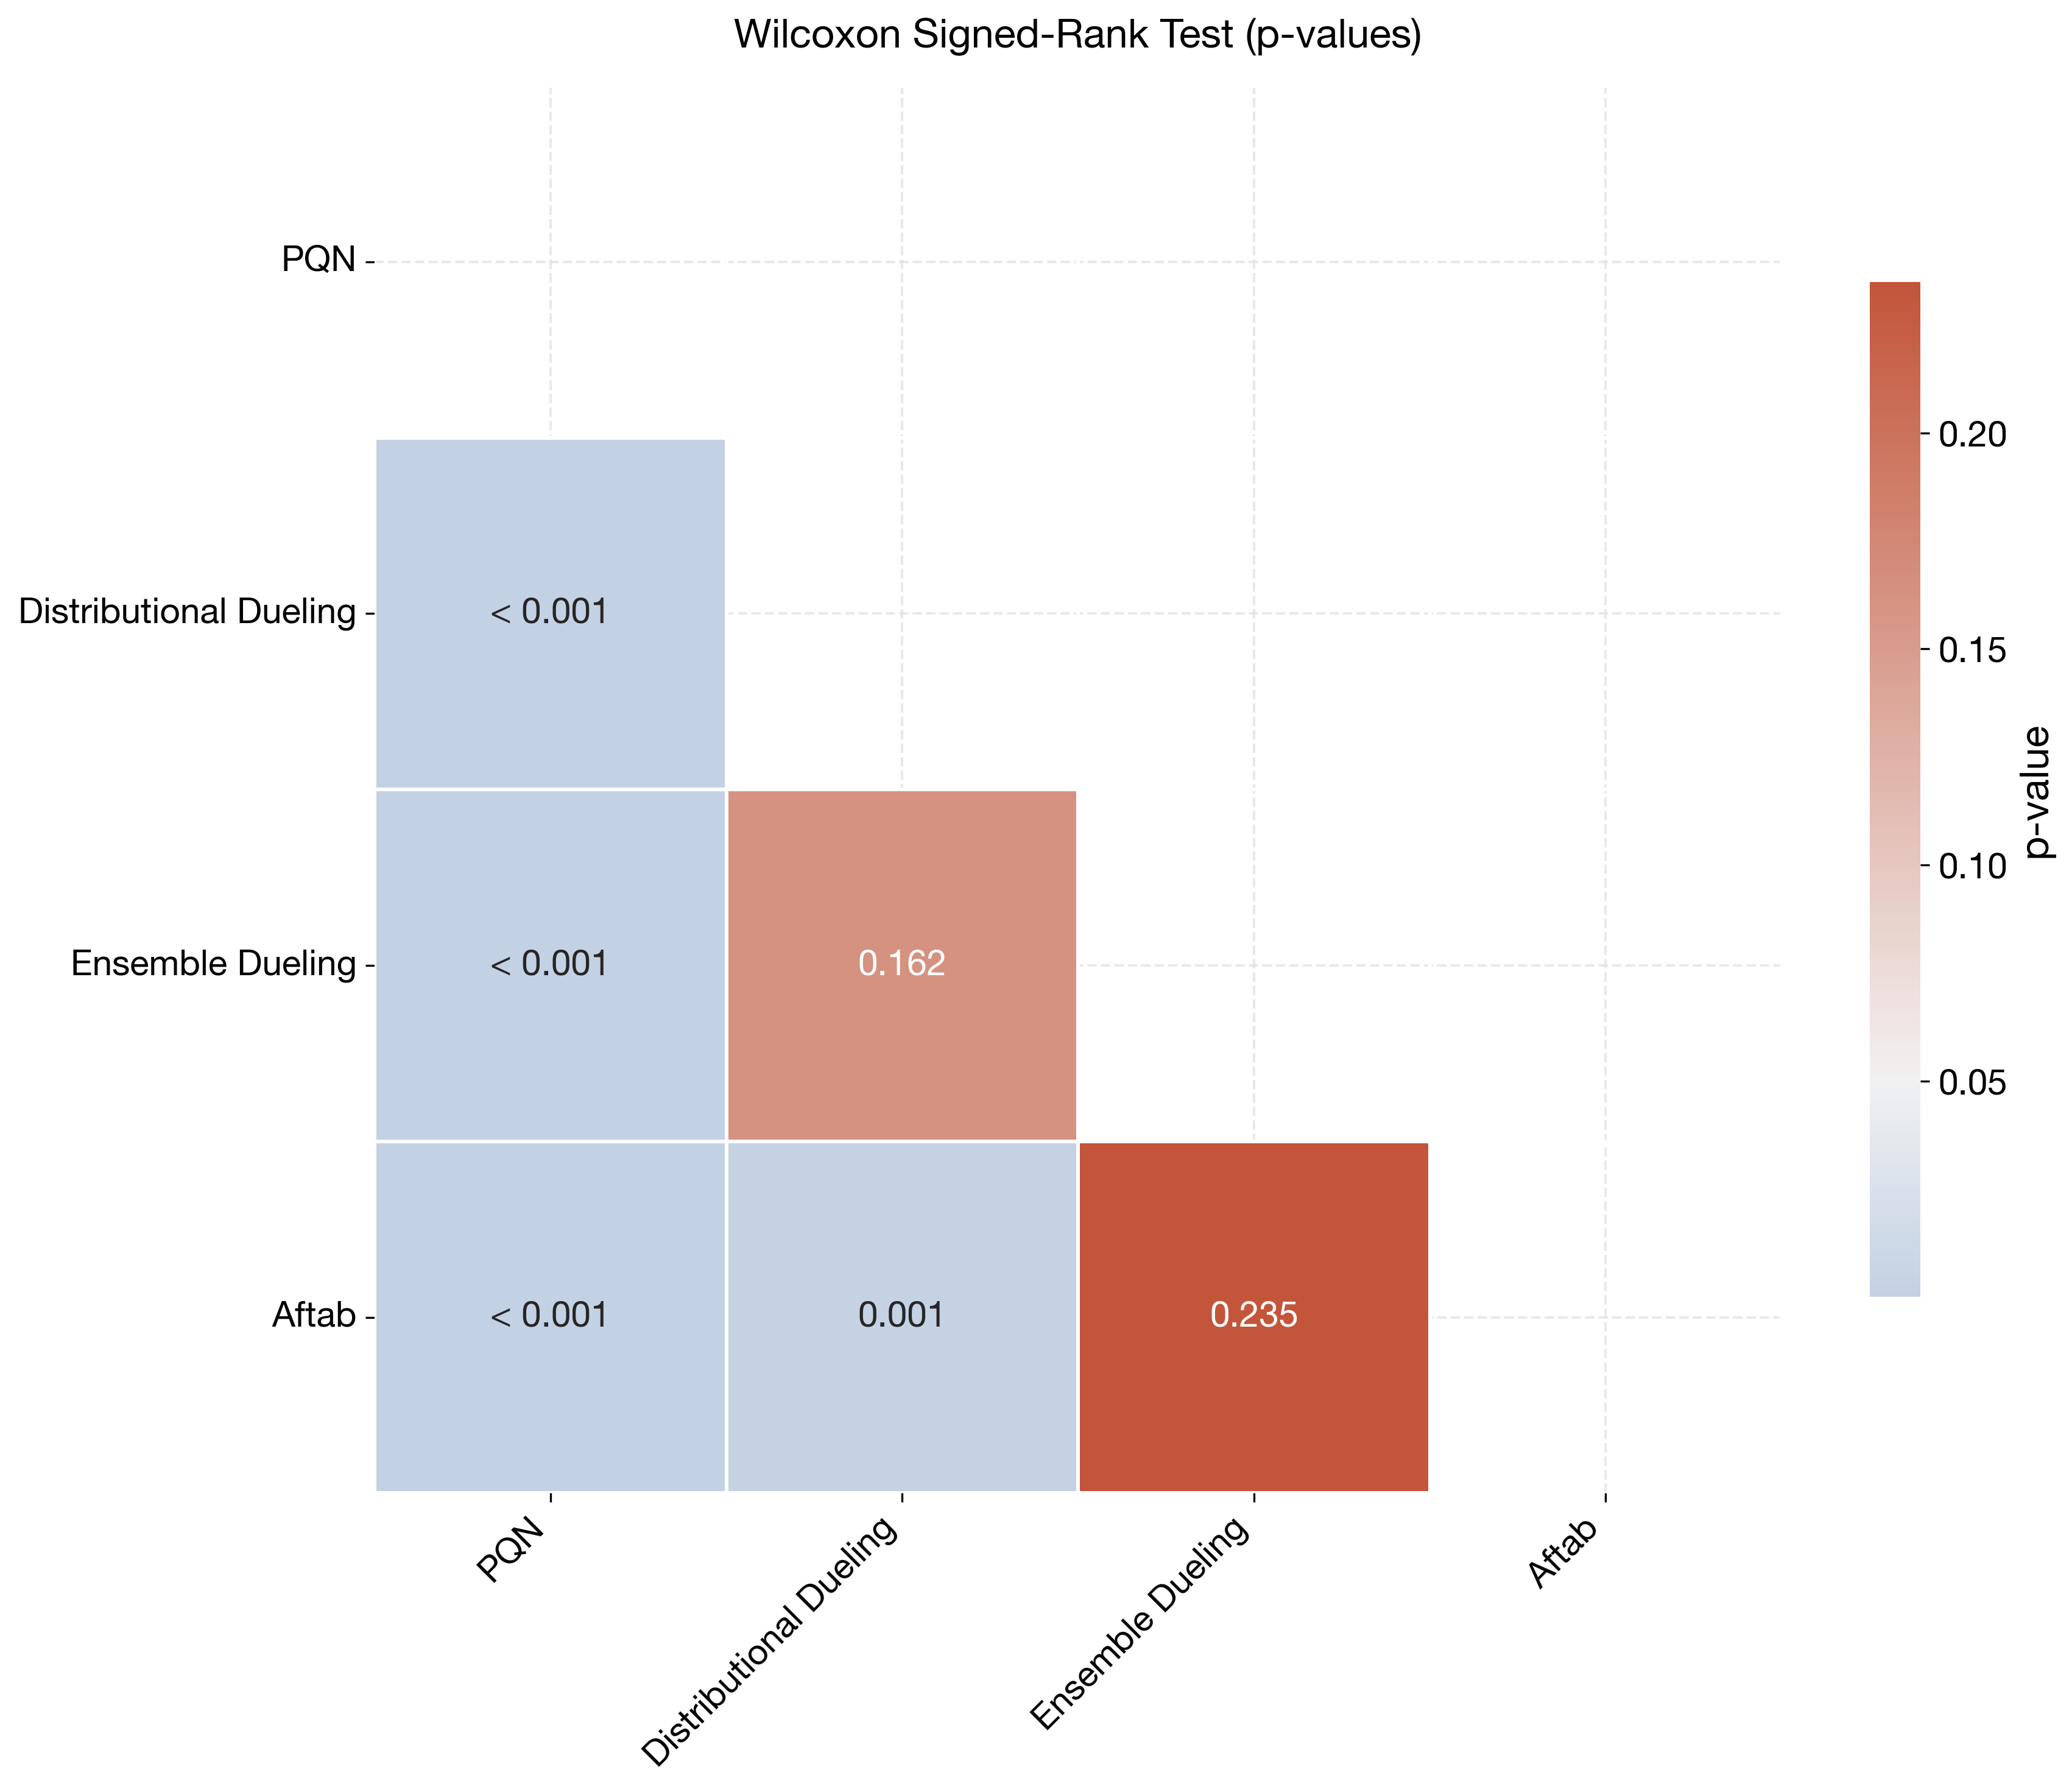
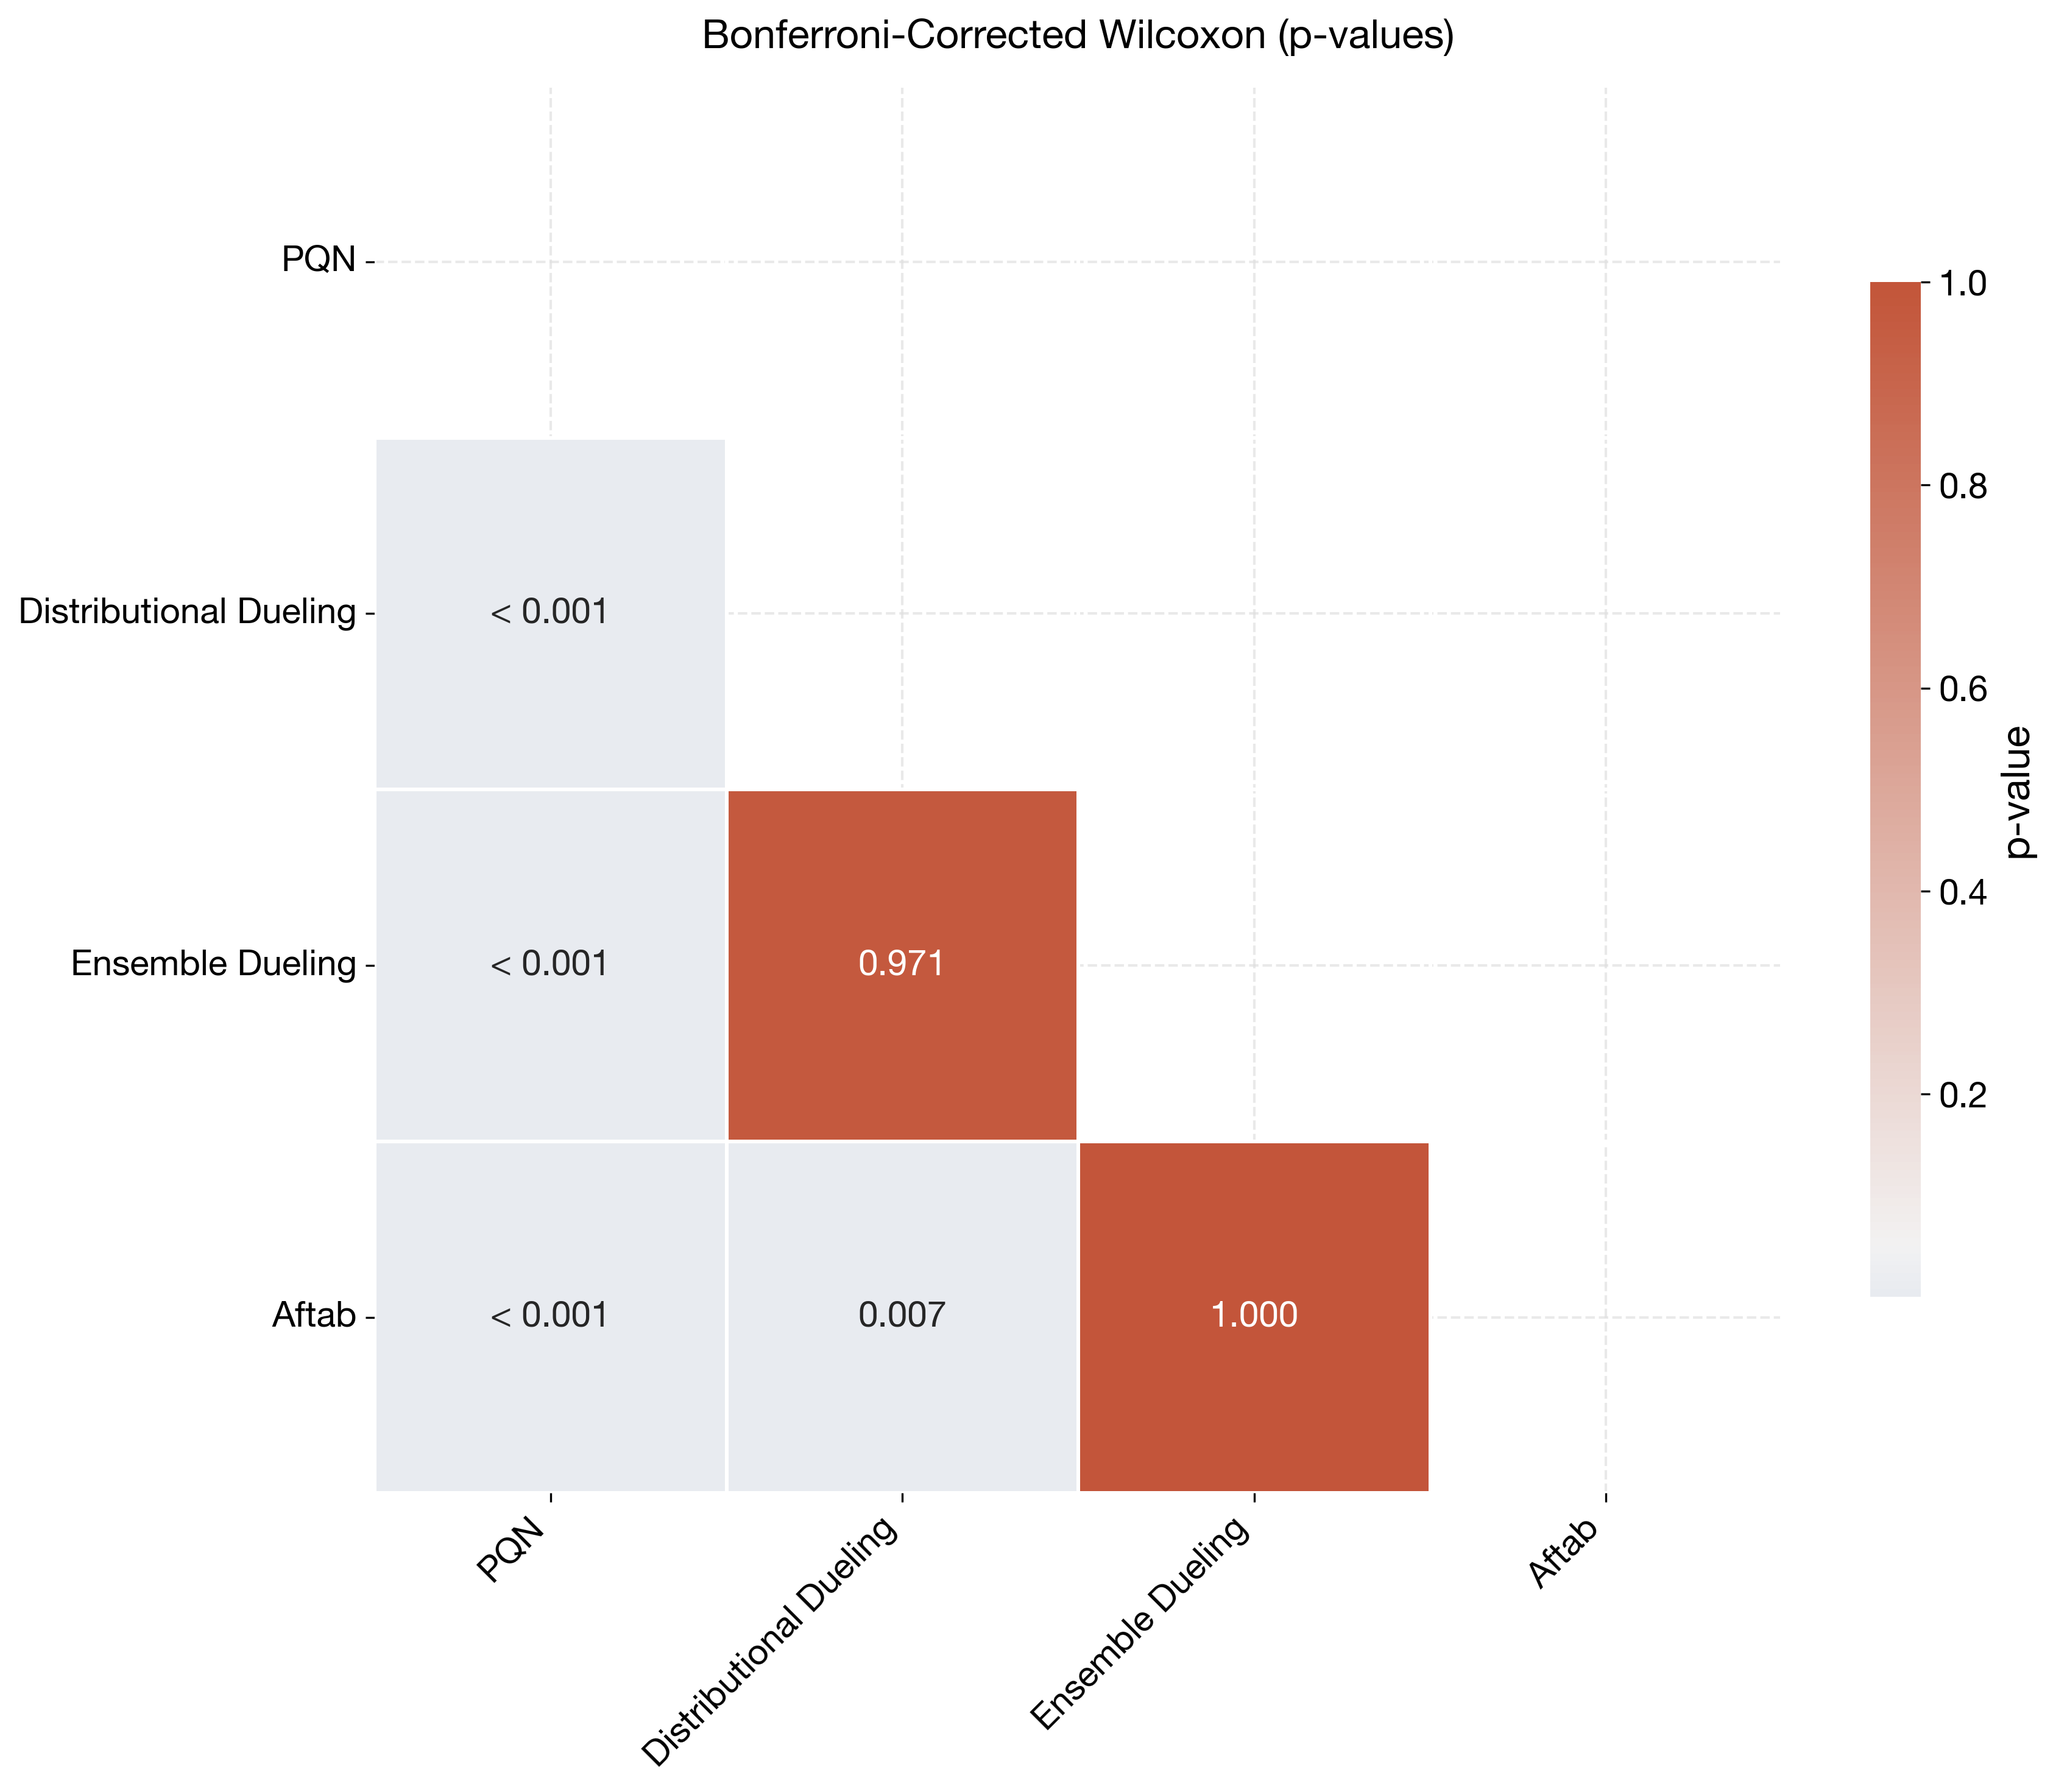
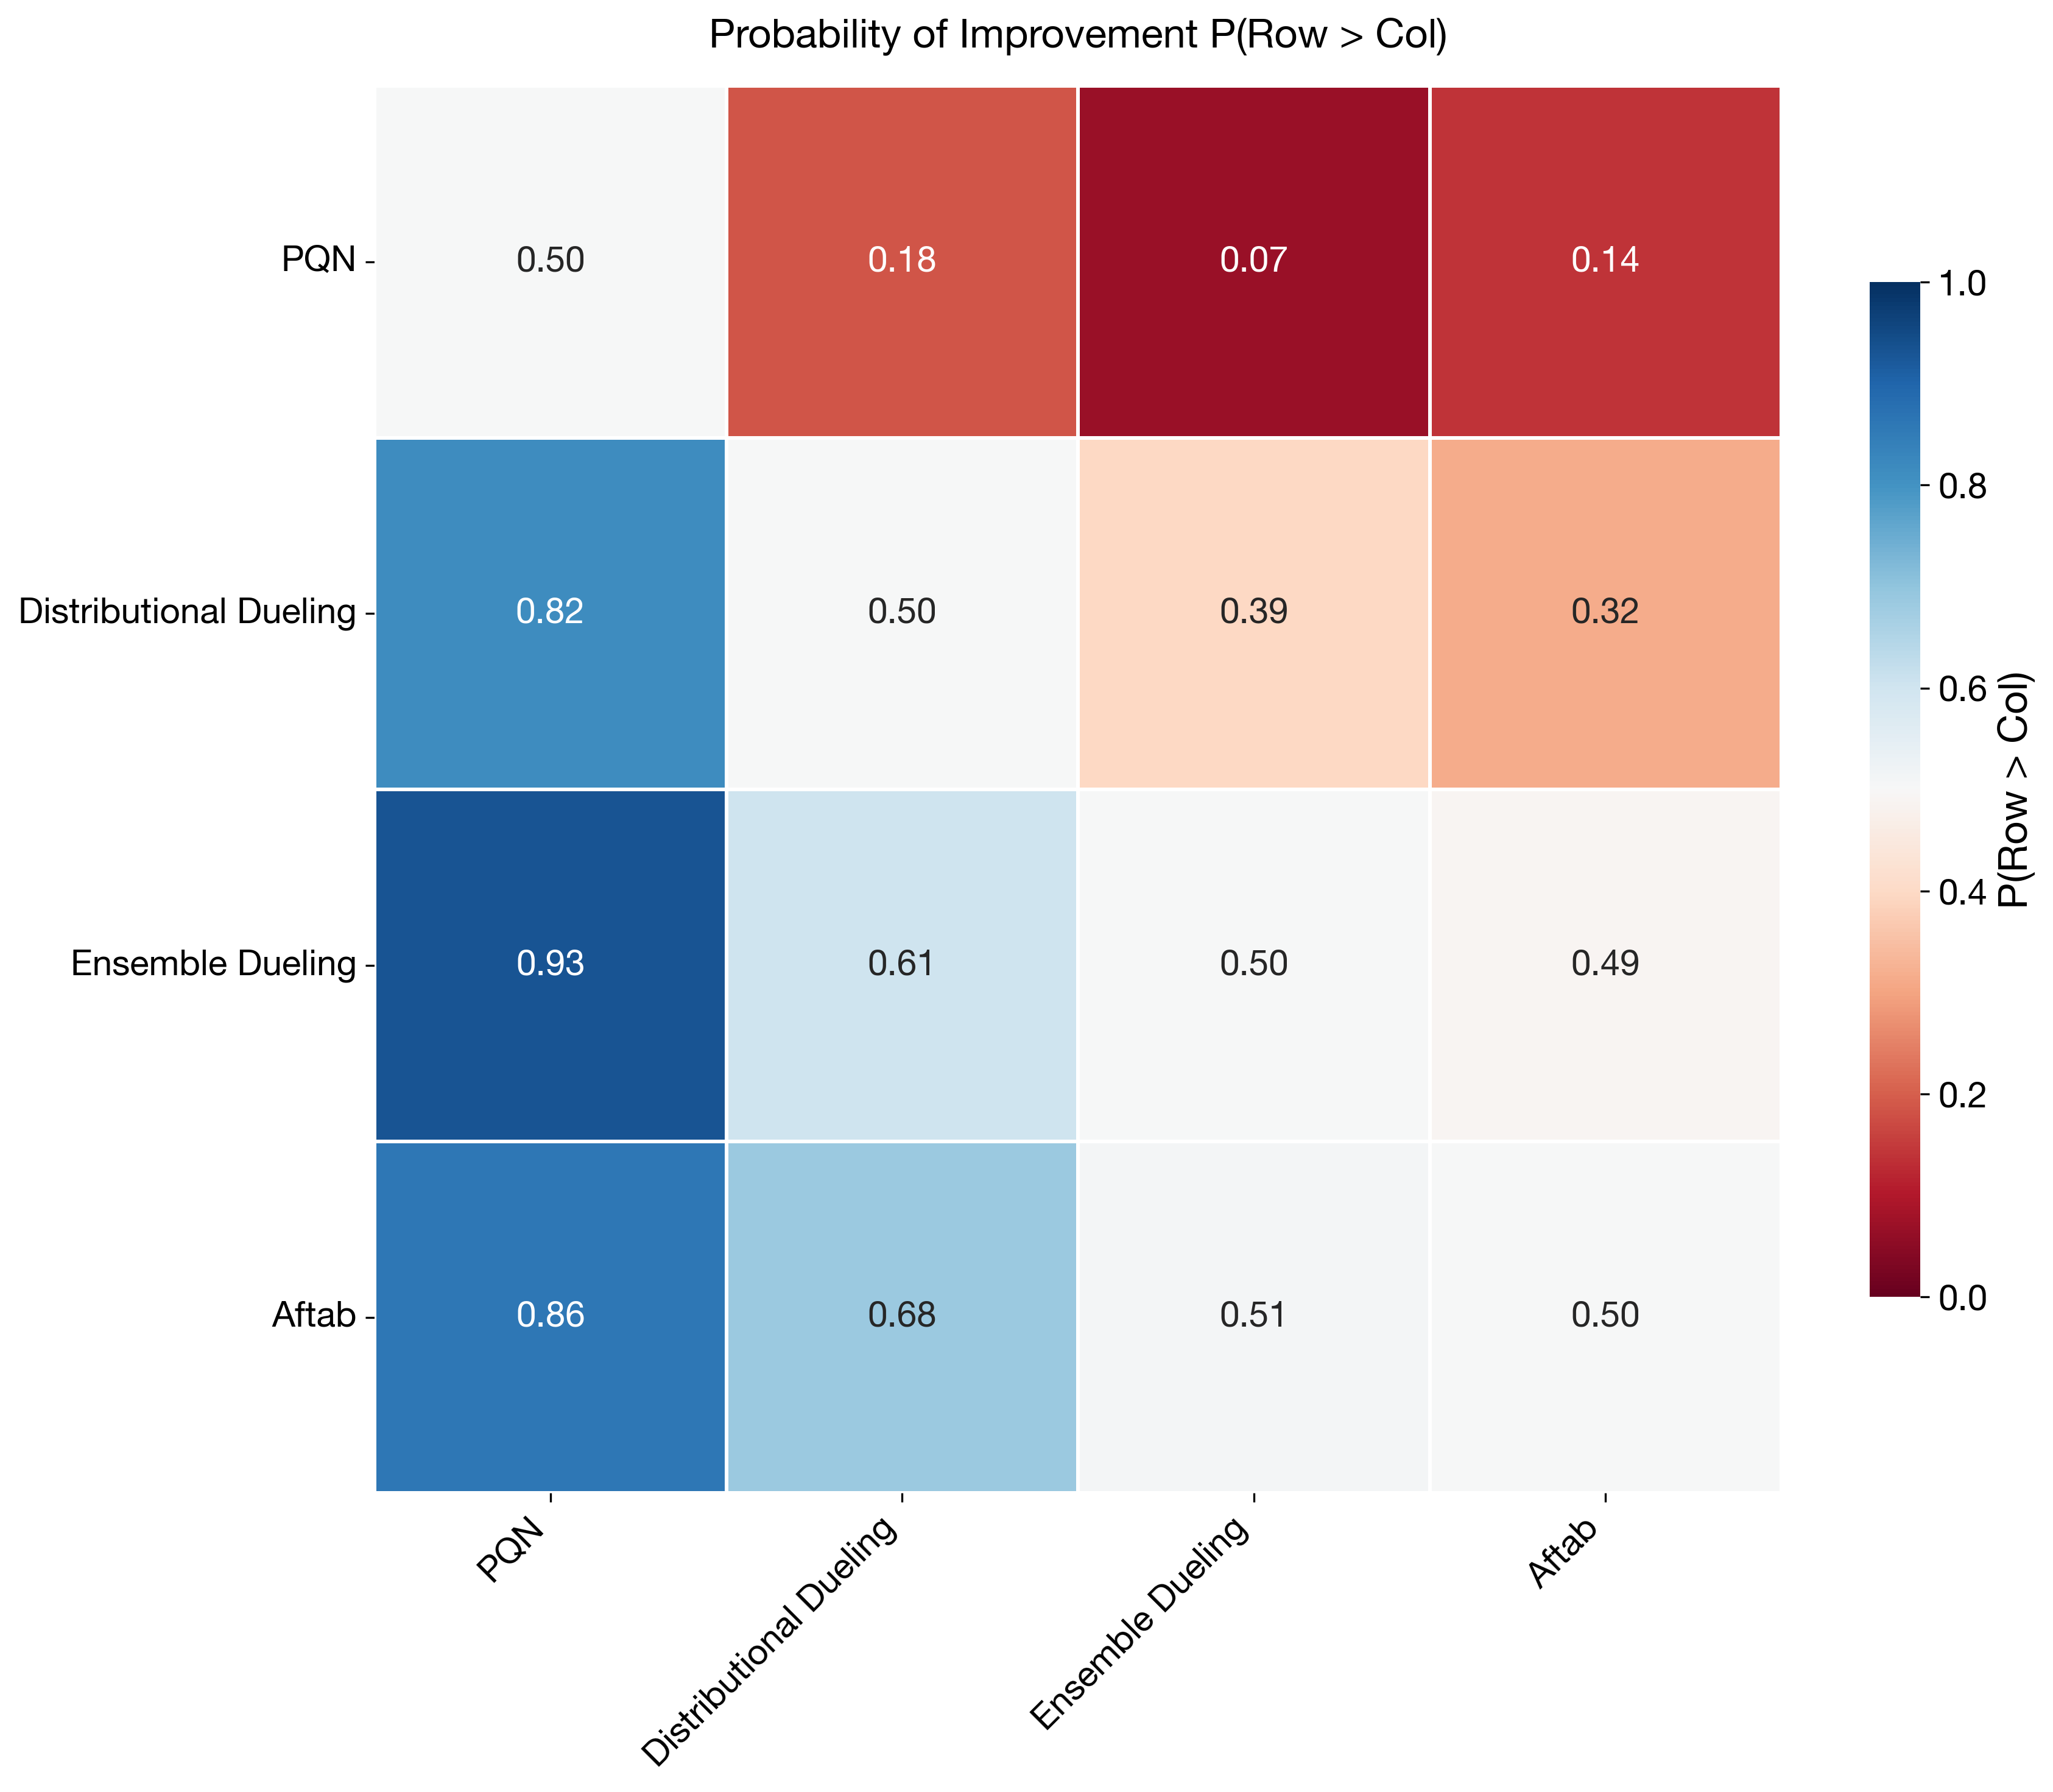
Q-Value Experiments
| Wilcoxon Signed Rank Test | Wilcoxon Signed Rank Test (Corrected) |
|---|---|
|
|
| Probability of Improvement | |
|
|
Reproducibility
Due to the stochastic nature of deep reinforcement learning, exact reproducibility via fixed datasets is not feasible.
Instead, we provide a set of random seeds used in our experiments.
from aftab import aftab_seeds

print(aftab_seeds)
Full experiment replication:
from aftab import Aftab
from aftab import aftab_environments
from aftab import aftab_seeds

for environment in aftab_environments:
    agent = Aftab()
    for seed in aftab_seeds:
        agent.train(environment=environment, seed=seed)
        agent.log()
A comprehensive set of Atari environments is available via EnvPool:
https://envpool.readthedocs.io/en/latest/env/atari.html#available-tasks
Procgen environments use their native RGB observations with shape (3, 64, 64).
Aftab reads each task's EnvPool configuration and only applies supported options.
Atari-only options such as noop, frame_skip, frame_stack,
train_episodic_life, and EnvPool reward clipping are therefore not passed to
Procgen.
A comprehensive set of Procgen environments is available via EnvPool:
https://envpool.readthedocs.io/en/latest/env/procgen.html#available-tasks
Hardware
Nvidia A40 GPUs were used to run all the experiments in this experiment.
| Specification | Details |
|---|---|
| GPU Memory | 48 GB GDDR6 with error-correcting code (ECC) |
| GPU Memory Bandwidth | 696 GB/s |
| Interconnect | NVIDIA NVLink 112.5 GB/s (bidirectional); PCIe Gen4: 64 GB/s |
| NVLink | 2-way low profile (2-slot) |
| Display Ports | 3x DisplayPort 1.4* |
| Max Power Consumption | 300 W |
| Form Factor | 4.4" (H) x 10.5" (L), Dual Slot |
| Thermal | Passive |
| vGPU Software Support | NVIDIA Virtual PC, NVIDIA Virtual Applications, NVIDIA RTX Virtual Workstation, NVIDIA Virtual Compute Server, NVIDIA AI Enterprise |
| vGPU Profiles Supported | See the Virtual GPU Licensing Guide |
| NVENC / NVDEC | 1x / 2x (includes AV1 decode) |
| Secure Boot | Secure and Measured Boot with Hardware Root of Trust (optional) |
| NEBS Ready | Level 3 |
| Power Connector | 8-pin CPU |
Citation
Repository:
@software{aftab2026,
  author = {Taha Shieenavaz},
  title = {Aftab: A Progressive Design Study of Visual Encoders and Value Estimation for Replay-Free Parallelized Q-Learning},
  year = {2026},
  publisher = {GitHub},
  journal = {GitHub Repository},
  howpublished = {\url{https://github.com/tahashieenavaz/aftab}},
}
Preprint:
@misc{2608.07335,
  Author = {Taha Shieenavaz and Shabnam Zareshahraki and Loris Nanni},
  Title = {Aftab: A Progressive Design Study of Visual Encoders and Value Estimation for Replay-Free Parallelized Q-Learning},
  Year = {2026},
  Eprint = {arXiv:2608.07335},
}
Related Works
@misc{2407.04811,
  Title = {Simplifying Deep Temporal Difference Learning},
  Author = {Matteo Gallici and Mattie Fellows and Benjamin Ellis and Bartomeu Pou and Ivan Masmitja and Jakob Nicolaus Foerster and Mario Martin},
  Year = {2024},
  Eprint = {arXiv:2407.04811},
}
@misc{2403.03950,
  Title = {Stop Regressing: Training Value Functions via Classification for Scalable Deep RL},
  Author = {Jesse Farebrother and Jordi Orbay and Quan Vuong and Adrien Ali Taïga and Yevgen Chebotar and Ted Xiao and Alex Irpan and Sergey Levine and Pablo Samuel Castro and Aleksandra Faust and Aviral Kumar and Rishabh Agarwal},
  Year = {2024},
  Eprint = {arXiv:2403.03950},
}
@misc{1511.06581,
  Title = {Dueling Network Architectures for Deep Reinforcement Learning},
  Author = {Ziyu Wang and Tom Schaul and Matteo Hessel and Hado van Hasselt and Marc Lanctot and Nando de Freitas},
  Year = {2015},
  Eprint = {arXiv:1511.06581},
}
@misc{1806.04613,
  Title = {Improving Regression Performance with Distributional Losses},
  Author = {Ehsan Imani and Martha White},
  Year = {2018},
  Eprint = {arXiv:1806.04613},
}
@misc{1602.04621,
  Title = {Deep Exploration via Bootstrapped DQN},
  Author = {Ian Osband and Charles Blundell and Alexander Pritzel and Benjamin Van Roy},
  Year = {2016},
  Eprint = {arXiv:1602.04621},
}
Useful Links
- Wikipedia: Reinforcement Learning (RL)
- Wikipedia: Deep Reinforcement Learning (DRL)
- Wikipedia: Q-Learning
- Wikipedia: PyTorch
- Wikipedia: Statistical Hypothesis Test
- Wikipedia: Wilcoxon Signed-Rank Test
- PyTorch
Font
The Vazirmatn font is used for both Persian and English text throughout the GitHub repository header and the project's landing page.
Translations
Translations were generated by AI using GPT-5.6 Sol @ Wednesday August 19th, ~14:00.
License
© 2025 Taha Shieenavaz.
Licensed under CC BY-NC 4.0: https://creativecommons.org/licenses/by-nc/4.0/
1 maintainer

Metadata
1 maintainer
Release files for aftab 1.0.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| aftab-1.0.6.tar.gz | 61.5 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| aftab-1.0.6-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 61.5 MB
Release files / aftab-1.0.6.tar.gz
| Download URL | aftab-1.0.6.tar.gz |
|---|---|
| Size | 61.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1ed6b4f039beb7083b8d017d88f53c0d166106fd633434b0a6cdea25abdc7f50
|
|
BLAKE2b-256 checksum How to use checksums |
5dfbdbe5b9c4621ece8cfe8feca76233b4a9c74561cb6a9289b54fd42f24ba50
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 17, 2026.
Transparency logRelease files / aftab-1.0.6-py3-none-any.whl
| Download URL | aftab-1.0.6-py3-none-any.whl |
|---|---|
| Size | 68.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
96bbefe977ab2c8aee71b4fc59a90c3f9e529ae3800262b12504ce18db20f4d6
|
|
BLAKE2b-256 checksum How to use checksums |
c76121c694d7c16fdf4e2b9cc0dff9dc7559133ec2dd2844856fa3aa3ae9d2ab
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 17, 2026.
Transparency log













