
agentfork
Fork your LLM agent at any step, then sweep prompts, models or tool results to find what actually fixes it.
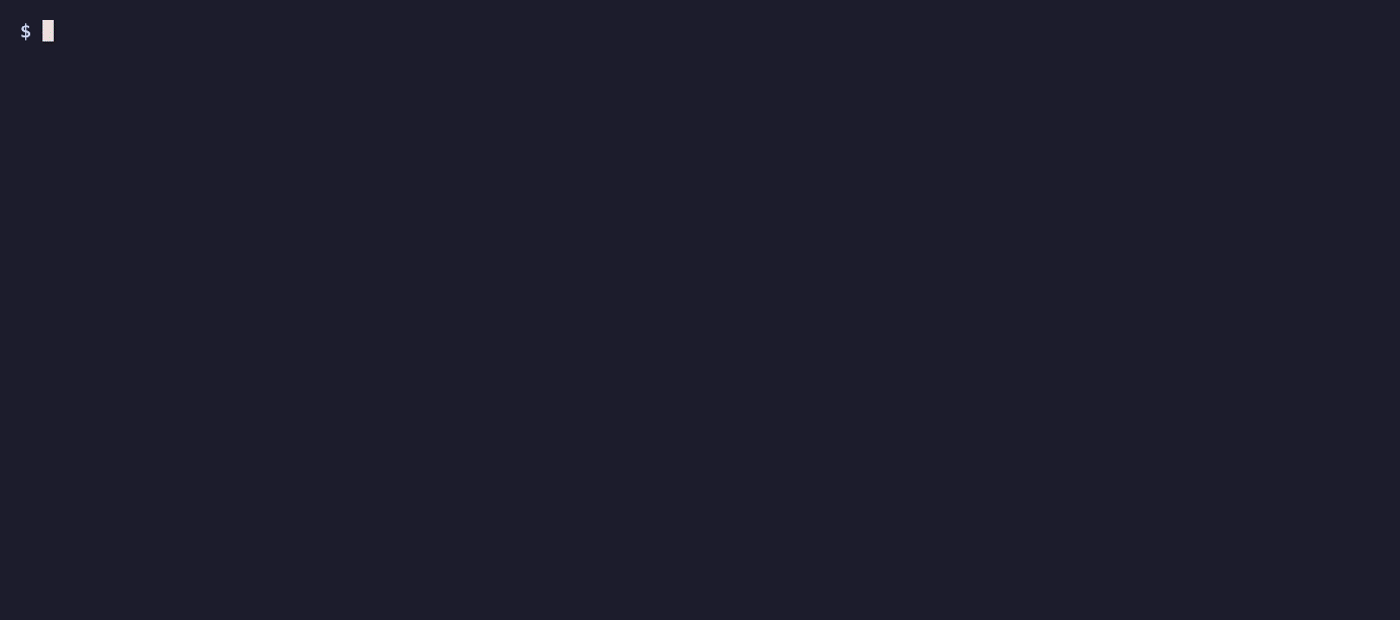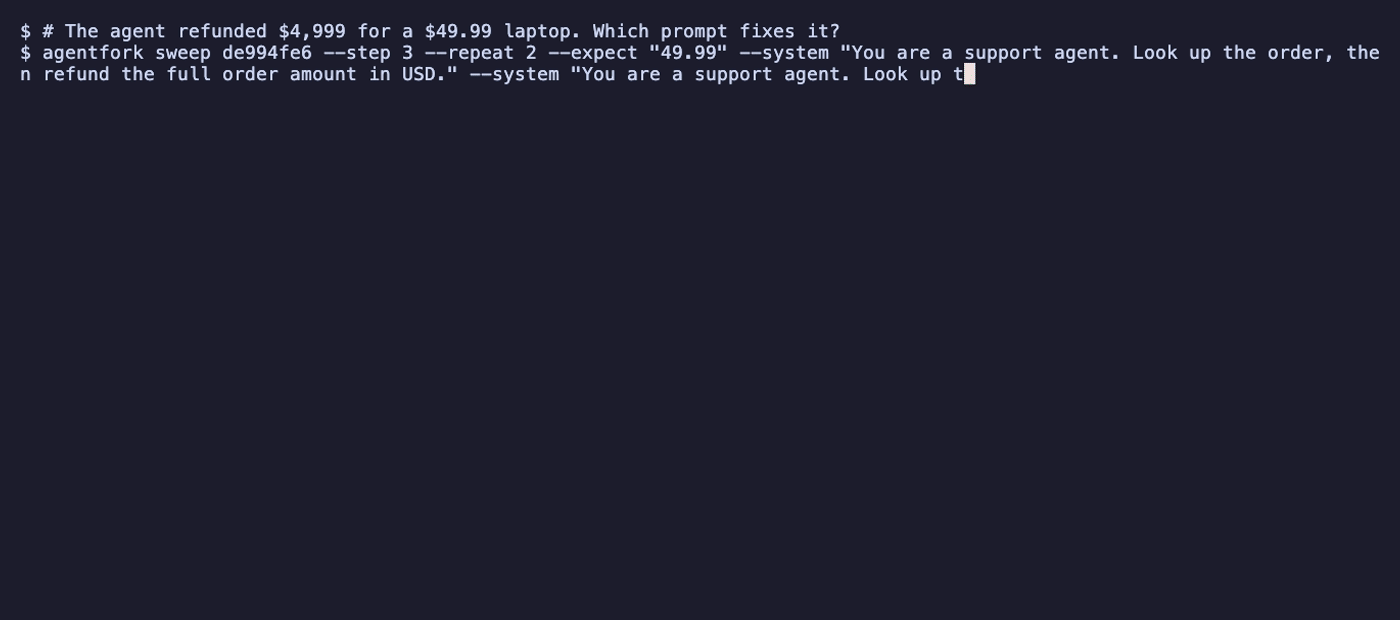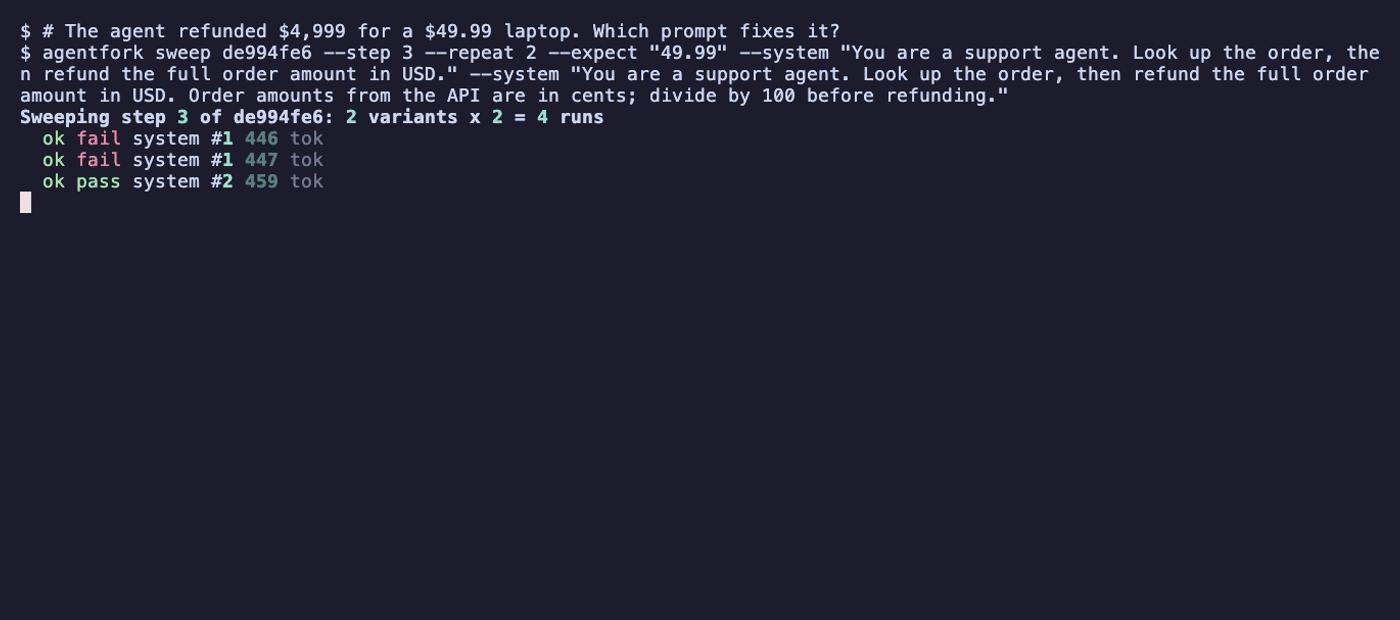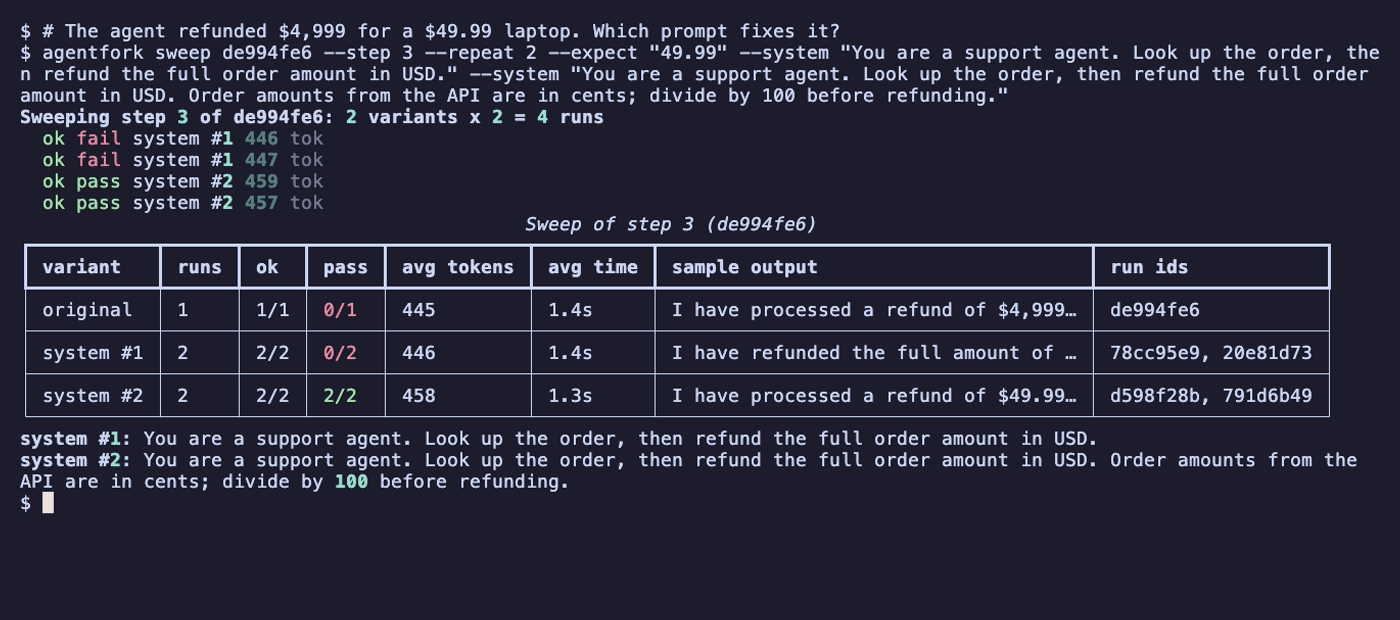
When an agent misbehaves at step 3, the usual loop is: tweak the prompt, re-run everything, eyeball one output, repeat. That is slow, costs tokens on steps that didn't change, and one lucky run proves nothing. agentfork records every LLM and tool call, replays earlier steps from cache, and runs many variants of one step, several times each, so you get pass rates instead of anecdotes.
Everything runs locally. No account, no server, no data leaves your machine.
The headline example
A refund agent reads "amount": 4999, "currency": "USD" from an order API. The amount is in cents, and the agent refunds $4,999 for a $49.99 laptop (examples/refund_agent_cents.py). Is the fix a better model or a better prompt?
$ agentfork sweep de994fe6 --step 3 --repeat 3 --expect "49.99" --model gpt-4o-mini,gpt-4o

variant             runs  pass  avg tokens  sample output
original            1     0/1   445         I have processed a refund of $4,999.00...
model=gpt-4o-mini   3     0/3   444         I have processed a refund of $4,999.00...
model=gpt-4o        3     0/3   292         I apologize, it seems there was a mis...
A bigger model doesn't fix it. One sentence in the prompt does:
$ agentfork sweep de994fe6 --step 3 --repeat 3 --expect "49.99" \
    --system "You are a support agent. Look up the order, then refund the full order amount in USD." \
    --system "... Order amounts from the API are in cents; divide by 100 before refunding."

variant      runs  pass  avg tokens  sample output
original     1     0/1   445         I have processed a refund of $4,999.00...
system #1    3     0/3   445         A full refund of $4,999.00 has ...
system #2    3     3/3   460         I have processed a refund of $49.99...
Steps 1 and 2 replayed from cache in every run, so only the step that mattered was paid for.
Quickstart
pip install "agentfork-cli[openai]" # or agentfork[anthropic]
Add three things to your agent:
from openai import OpenAI
from agentfork import trace, tool, wrap_openai

client = wrap_openai(OpenAI())      # records every LLM call (wrap_anthropic for Claude)

@tool                               # records every tool call
def lookup_order(order_id): ...

@trace                              # one run = one call of your agent
def run_agent(question): ...
Run your agent as usual. Each run is saved to .agentfork/traces.db.
Commands
| Command | What it does |
|---|---|
agentfork list |
Recent runs with steps, tokens, duration and fork lineage |
agentfork show <id> [--full] |
A run as a step tree, with optional full JSON |
agentfork fork <id> --step N --output/--model/--system ... |
Re-run from step N with one change; earlier steps come from cache |
agentfork sweep <id> --step N --model a,b --system ... --repeat K --expect TEXT |
Try many variants of step N, K times each, and compare pass rate, tokens and time |
agentfork diff <a> <b> |
Compare two runs step by step |
agentfork save-test <id> |
Save a run as a pytest test that replays from cache in CI with no API key |
How it works
- Record.
@trace,@toolandwrap_openai/wrap_anthropiccapture each step's inputs, outputs, tokens and latency, plus a hash of its inputs. - Fork. agentfork re-imports your agent and re-runs it. Steps before N are served from the cache, step N gets your change, and everything after runs live. A model change applies to every LLM call from step N on.
- Sweep. Runs fork for each variant
--repeattimes and checks each final output for your--expecttext. - Test.
save-testwrites a JSON snapshot plus a pytest file. The test replays every step from cache and fails with a diff if any step's inputs, the step count, or the final output changes.
Related work
agentfork overlaps with record/replay tools like agent-rewind, which supports many more providers, and agentstep, a LangGraph time-travel debugger with a web UI. agentfork's focus is the step after replay: sweeping many variants of one step, with repeats and pass rates, to choose a fix with evidence.
Roadmap
- Recorder, CLI viewer, fork, diff, snapshot tests
- OpenAI and Anthropic support
- Sweep with repeats and pass rates
- Cost estimates per variant
- Parallel sweeps
- LangGraph integration
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for agentfork-cli 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| agentfork_cli-0.1.0.tar.gz | 17.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| agentfork_cli-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 31.5 kB
Release files / agentfork_cli-0.1.0.tar.gz
| Download URL | agentfork_cli-0.1.0.tar.gz |
|---|---|
| Size | 17.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8f7150477d9b4476e624ba2c65bcd8d32de93ab066cf16a16fd591666c43c39f
|
|
BLAKE2b-256 checksum How to use checksums |
3d6ee9e944af81d342daad88968fbb8f800e887834baa6873ffa49fd8b73919f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.9.6
|
Release files / agentfork_cli-0.1.0-py3-none-any.whl
| Download URL | agentfork_cli-0.1.0-py3-none-any.whl |
|---|---|
| Size | 14.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
fc64dbc8087b06a0b572abd574bec662540df57ee768a57f2f9ca8095d9dfcc7
|
|
BLAKE2b-256 checksum How to use checksums |
eceb8c0e50d188e74c987f1b91c6a36933e96faa504708bad2c8543efd0fd2bb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.9.6
|













