
⚛️ AgentKthx R06.3
Status: Alpha
A minimal, hackable agentic framework for autonomous AI agents. Runs locally with Ollama, in the cloud with OpenRouter and ZAI. Extensible via a manifest-based plugin system for additional backends and features.
Inspired by the architecture of OpenClaw, rebuilt from scratch for local-first operation.
Written by VTSTech · GitHub Discord
ℹ️ Renamed from
AgentNova(R06.0)This project was previously named
AgentNova. As of R06.0, the package has been renamed toAgentKthx(PyPI:agentkthx, CLI:agentkthx). The oldagentnovaPyPI package still works as a redirect — existing scripts and env vars (AGENTNOVA_*) continue to work without changes. See the Migration Guide section below.






📚 Documentation
| Document | Description |
|---|---|
| ARCH.md | Technical documentation for developers (directory structure, core design, orchestrator modes) |
| CHANGELOG.md | Version history and release notes (includes LocalClaw history) |
| TESTS.md | Benchmark results, model recommendations, and testing guide |
| PLUGIN_SPEC.md | Plugin system specification (manifest format, API, lifecycle) |
| JEV_API_MODE.md | JEV API mode — System-One decisions via any free LLM (Jev-compatible shape) |
| ZAI_API_TECHNICAL_REFERENCE.md | ZAI API technical reference (auth, endpoints, parameters, error codes) |
| OPENROUTER_API_TECHNICAL_REFERENCE.md | OpenRouter API technical reference (sampling params, model catalog, provider routing, rate limits) |
| CREDITS.md | Acknowledges every project, inspiration, API, model creator, and specification that makes AgentKthx possible |
Features
- Zero dependencies — Uses Python stdlib only (urllib for HTTP)
- Plugin system — Manifest-based plugin discovery, lazy loading, and dependency resolution (R05.0)
- Native + plugin backends — Ollama built-in; OpenRouter, BitNet, ZAI, ACP, TurboQuant as plugins
- Multi-cloud support — Access to 500+ models from OpenRouter, OpenAI, Anthropic, Google, Cohere
- Dual API support — OpenResponses (
--api openre) and OpenAI Chat-Completions (--api openai) - JEV decision mode — System-One decisions via any free LLM (
--api jev) — Jev-compatible shape, no TypeSafe API key required - Thinking controls —
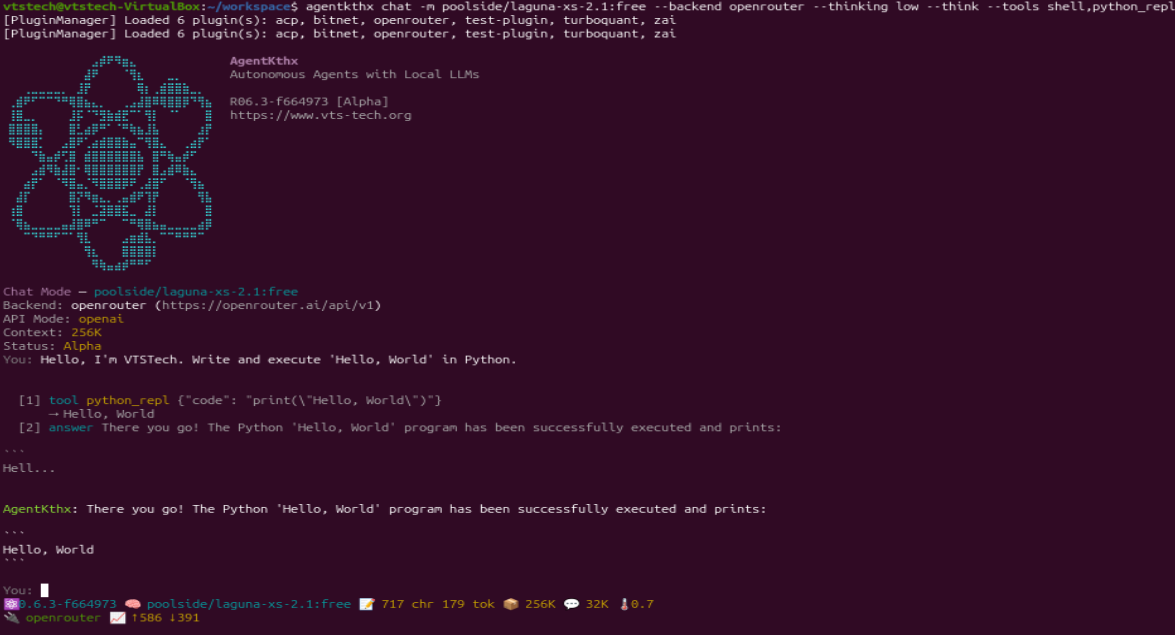
--thinking off|auto|low|medium|highto control model reasoning effort,--thinkflag to display reasoning_content (chain-of-thought) in CLI output - Three-tier tool support — Native, ReAct, or none (auto-detected)
- Small model optimized — Fuzzy matching, argument normalization
- Built-in security — Path validation, command blocklist, SSRF protection (toggleable via
--security max|off) - Multi-agent orchestration — Router, pipeline, and parallel modes
- Soul Spec v0.5 — Persona packages with progressive disclosure
- AgentSkills spec — Skill loading with SPDX license validation
- Thinking models support — Automatic handling of qwen3, deepseek-r1 thinking mode
- Ctrl+C cancellation — Graceful interrupt at backend, tool, and agent loop levels (R05.0)
- Persistent memory — SQLite-backed conversation persistence with session management (
--session) - 17 built-in tools — Calculator, shell, file ops (read/write/edit/list/find), HTTP, web search, JSON parse, Python REPL, todo list, datetime, word/char count
- Dangerous tool confirmation —
--confirmflag for interactive approval of destructive operations - Audit logging — Automatic JSON-lines logging of shell, write, and edit operations
- Argument normalization — ~100+ tool argument aliases for small model compatibility
- JSON structured output —
--response-format jsonfor structured JSON responses - Self-update —
agentkthx updateto update to latest version from GitHub - Persistent status footer — 2-line terminal footer with live model/backend/token info (R05.4, scroll-region based)
- OpenRouter 429 retry — Automatic retry with
Retry-Afterheader support for rate-limited providers (R05.4) - Tool-call visibility — Tool calls and results displayed in chat mode (R05.4)
Installation
# Latest Development Release
pip install git+https://github.com/VTSTech/AgentKthx.git --force-reinstall

# Last Stable (as stable as Alpha can be) Release
pip install agentkthx
Quick Start
CLI Usage
# Run a single prompt
agentkthx run "What is 15 * 8?" --tools calculator

# Interactive chat
agentkthx chat -m qwen2.5:0.5b --tools calculator,shell

# Autonomous agent mode
agentkthx agent -m qwen2.5:7b --tools calculator,shell,write_file

# Use OpenAI Chat-Completions API
agentkthx chat -m qwen2.5:0.5b --api openai

# List available models
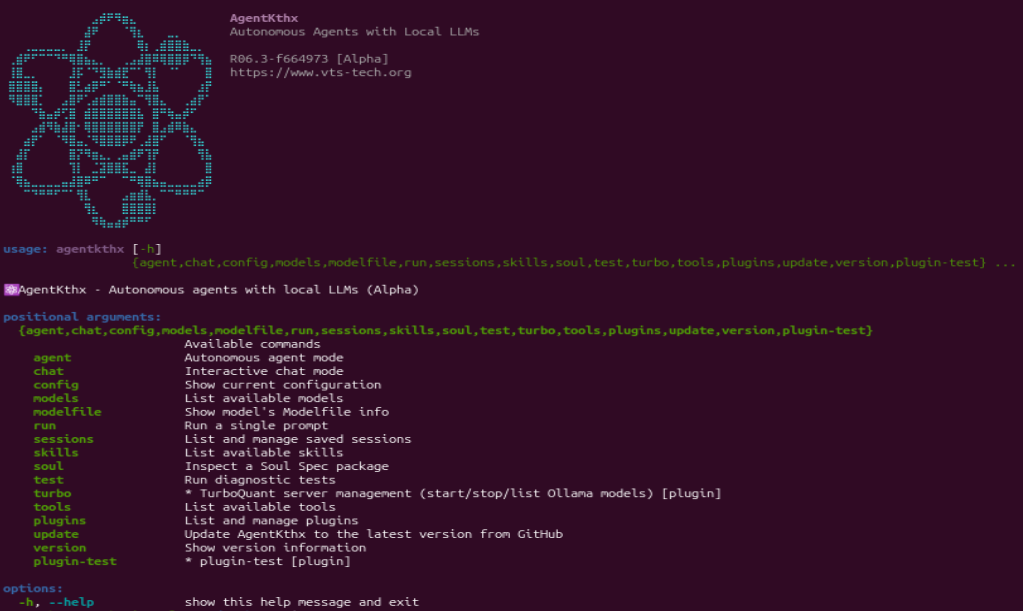
agentkthx models

# List available tools
agentkthx tools

# Resume a previous session
agentkthx chat -m qwen2.5:0.5b --session my-session

# Dangerous tool confirmation
agentkthx agent -m qwen2.5:7b --tools shell,write_file --confirm

# Force ReAct mode
agentkthx run "What is 15 * 8?" --tools calculator --force-react

# List persistent memory sessions
agentkthx sessions

# TurboQuant server management
agentkthx turbo list
agentkthx turbo start qwen2.5:7b
agentkthx turbo status
agentkthx turbo stop

# Self-update
agentkthx update
Backend Options
# Native backends (always available)
agentkthx chat -m qwen2.5:0.5b --backend ollama         # Ollama (default)
agentkthx chat -m qwen2.5:7b --backend llama-server      # llama.cpp / TurboQuant

# Plugin backends (loaded on demand)
agentkthx chat -m poolside/laguna-xs-2.1:free --backend openrouter     # OpenRouter (free tier, plugin)
agentkthx chat -m openai/gpt-4o --backend openrouter                # OpenRouter (OpenAI models)
agentkthx chat -m anthropic/claude-3.5-sonnet --backend openrouter   # OpenRouter (Anthropic models)
agentkthx chat -m bitnet-b1.58-2b-4t --backend bitnet              # BitNet (plugin)
agentkthx chat -m glm-4.5-flash --backend zai                       # ZAI (free tier, plugin)
agentkthx chat -m glm-5.1 --backend zai                             # ZAI (paid, plugin)

# Plugin management
agentkthx plugins                    # List discovered plugins
JEV API Mode — System-One Decisions
JEV mode wraps any free chat-capable LLM with a constrained decision prompt,
returning a Jev-compatible envelope {decision, probability, alternatives}.
No TypeSafe API key or waitlist required — uses your existing ZAI / OpenRouter /
Ollama free models.
# Classify an email using ZAI free model
agentkthx run "Email subject: 'You won a prize!' — classify as spam/inbox/promotions" \
    --api jev --backend zai --model glm-4.5-flash

# Route a ticket using free OpenRouter model
agentkthx run "Task: calculate 15 * 8 and save to file — route to math/file/general agent" \
    --api jev --backend openrouter --model poolside/laguna-xs-2.1:free

# Local Ollama model making a decision
agentkthx run "Is this a bug or feature request? 'App crashes on startup'" \
    --api jev --backend ollama --model qwen2.5:0.5b
Output is a JSON decision envelope:
{
  "decision": "spam",
  "probability": 0.92,
  "alternatives": [
    {"value": "promotions", "probability": 0.06},
    {"value": "inbox", "probability": 0.02}
  ]
}
See JEV_API_MODE.md for the full spec, Python API, and architecture details.
Thinking Controls
Two CLI flags give you fine-grained control over thinking-capable models (GLM-4.5+, OpenAI o-series, deepseek-r1, qwen3 in thinking mode, etc.):
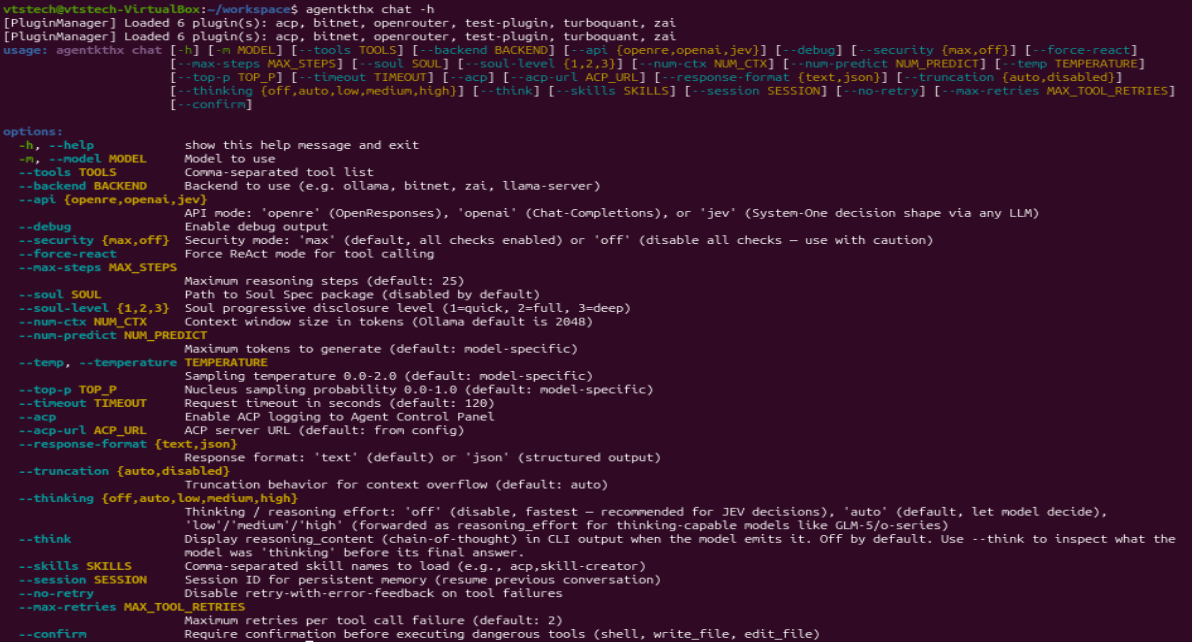
--thinking off|auto|low|medium|high— controls model thinking behavioroff→ disable thinking entirely (fastest, recommended for JEV decisions)auto→ let the model decide (default)low/medium/high→ forwardreasoning_effortto OpenAI-compatible models
--think— display the model'sreasoning_content(chain-of-thought) in the CLI output under each step. Off by default.
# Fast JEV decision — disable thinking entirely
# (drops GLM-4.5-flash latency from ~22s to ~2-3s on trivial classifications)
agentkthx run "Is this spam?" --api jev --backend zai -m glm-4.5-flash --thinking off

# Heavy reasoning — for hard problems where you want maximum thinking
agentkthx run "Prove that the sum of two odds is even." --thinking high

# Inspect what the model was thinking
agentkthx run "What is 15 * 8?" --think

# Combine: heavy thinking + show the chain-of-thought
agentkthx run "Design a load balancer for 10k RPS" --thinking high --think
Python API:
from agentkthx import Agent
from agentkthx.core.types import parse_thinking_arg

# Parse a level string → (think, reasoning_effort) tuple
think, effort = parse_thinking_arg("high")  # (True, "high")

agent = Agent(
    model="glm-5.1",
    backend="zai",
    thinking_level="high",       # or pass think=True, reasoning_effort="high"
    show_reasoning=True,         # equivalent to --think
)

# Decisions also respect --thinking off (fixes JEV latency)
from agentkthx.backends import get_backend
backend = get_backend("zai", api_mode="jev")
decision = backend.generate_decision(
    model="glm-4.5-flash",
    state="...",
    choices=["a", "b"],
    think=False,  # disable thinking for fast decisions
)
Python API
from agentkthx import Agent
from agentkthx.tools import make_builtin_registry

# Create tools
tools = make_builtin_registry().subset(["calculator", "shell"])

# Create agent
agent = Agent(
    model="qwen2.5:0.5b",
    tools=tools,
    backend="ollama",
)

# Run
result = agent.run("What is 15 * 8?")
print(result.final_answer)
print(f"Completed in {result.total_ms:.0f}ms")
Persistent Memory
from agentkthx import Agent

# Create agent with session persistence
agent = Agent(
    model="qwen2.5:0.5b",
    tools=["calculator"],
    session_id="my-session",  # Enables persistent memory
)

result = agent.run("What is 15 * 8?")
print(result.final_answer)  # "120"

# Later... resume the session
agent2 = Agent(
    model="qwen2.5:0.5b",
    tools=["calculator"],
    session_id="my-session",
)
# Previous conversation is restored from SQLite

# Clean up when done
agent.memory.close()
Dangerous Tool Confirmation
agent = Agent(
    model="qwen2.5:7b",
    tools=["shell", "write_file", "edit_file"],
    confirm_dangerous=lambda tool, args: input(f"Run {tool}? [y/N] ").lower() == "y",
)
JSON Structured Output
agent = Agent(
    model="qwen2.5:0.5b",
    response_format={"type": "json_object"},  # Enables JSON mode, disables tools
)
result = agent.run('Return JSON with keys: "name", "age", "city"')
print(result.final_answer)  # Valid JSON string
TurboQuant Server Management
from agentkthx.turbo import start_server, stop_server, get_status

# Start TurboQuant server with an Ollama model
state = start_server("qwen2.5:7b", ctx=8192)

# Check status
status = get_status()
if status:
    print(f"Running: {status.model_name} on port {status.port}")

# Stop server
stop_server()
OpenRouter Configuration
OpenRouter provides access to 500+ models from Anthropic, OpenAI, Google, Cohere, and other providers.
Environment Variables
export OPENROUTER_API_KEY="your_api_key_here"                    # Required
export OPENROUTER_BASE_URL="https://openrouter.ai/api/v1"        # Optional (default)
export OPENROUTER_DEFAULT_MODEL="anthropic/claude-3.5-sonnet"    # Optional
export OPENROUTER_FREE_ONLY="1"                                 # Optional (filter to free models)
Usage Examples
# Basic usage with free model
agentkthx chat --backend openrouter --model poolside/laguna-xs-2.1:free

# OpenAI models via OpenRouter
agentkthx chat --backend openrouter --model openai/gpt-4o

# Anthropic models via OpenRouter
agentkthx chat --backend openrouter --model anthropic/claude-3.5-sonnet

# Google models via OpenRouter
agentkthx chat --backend openrouter --model google/gemini-flash

# List available models
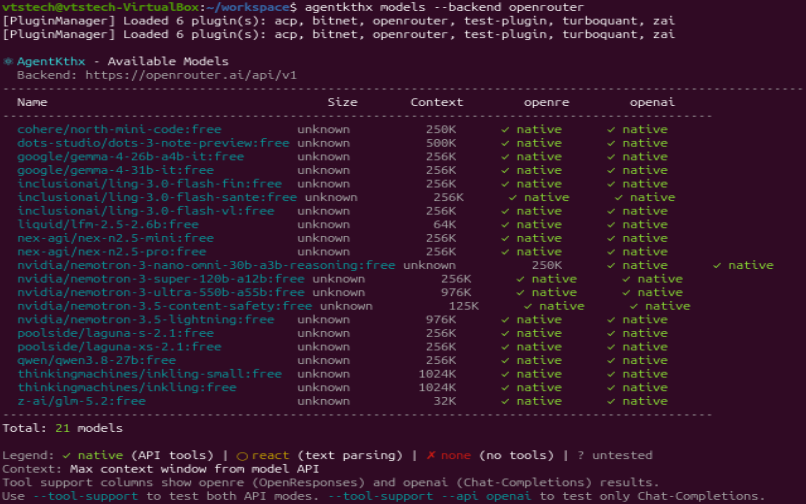
agentkthx models --backend openrouter

# Free models only
OPENROUTER_FREE_ONLY=1 agentkthx models --backend openrouter
Chat-Completions Streaming
from agentkthx.backends import get_backend
from agentkthx.core.types import ApiMode

# Use Chat-Completions mode with streaming
backend = get_backend("ollama", api_mode=ApiMode.OPENAI)

for chunk in backend.generate_completions_stream(
    model="qwen2.5:0.5b",
    messages=[{"role": "user", "content": "Hello!"}],
    response_format={"type": "json_object"}
):
    print(chunk["delta"], end="", flush=True)
JEV Decision Mode
from agentkthx.backends import get_backend

# Get a JEV-mode backend (uses any free LLM underneath)
backend = get_backend("zai", api_mode="jev")

# Make a structured decision
decision = backend.generate_decision(
    model="glm-4.5-flash",
    state="Email from unknown@xyz.com — subject: 'You won a prize!'",
    choices=["spam", "inbox", "promotions"],
    question="Where should this email be routed?",
)

print(decision["decision"])      # "spam"
print(decision["probability"])   # 0.92
print(decision["alternatives"])  # [{"value": "promotions", "probability": 0.06}, ...]
print(decision["usage"])         # {"input_tokens": 100, "output_tokens": 20, ...}
Skill License Validation
from agentkthx.skills import validate_spdx_license, parse_compatibility

# Validate SPDX license identifier
valid, msg = validate_spdx_license("MIT")  # (True, "Valid SPDX identifier: MIT")
valid, msg = validate_spdx_license("Custom")  # (False, "Unknown license...")

# Parse compatibility requirements
compat = parse_compatibility("python>=3.8, ollama")
# Returns: {"python": ">=3.8", "runtimes": ["ollama"], "frameworks": []}
Multi-Agent Orchestration
from agentkthx import Agent, Orchestrator, AgentCard

orchestrator = Orchestrator(mode="router")

# Register specialized agents
orchestrator.register(AgentCard(
    name="math_agent",
    description="Handles mathematical calculations",
    capabilities=["calculate", "math", "compute"],
    tools=["calculator"],
))

orchestrator.register(AgentCard(
    name="file_agent",
    description="Handles file operations",
    capabilities=["read", "write", "file"],
    tools=["read_file", "write_file"],
))

# Route tasks to appropriate agent
result = orchestrator.run("Calculate 15 * 8 and save to file")
Tool Support Levels
AgentKthx supports three levels of tool use:
- Native — Models with built-in function calling (qwen2.5, llama3.1+, mistral, granite, functiongemma)
- ReAct — Text-based tool use via reasoning prompts (qwen2.5-coder, qwen3)
- None — Pure reasoning without tools
Tool support is auto-detected by running agentkthx models --tool-support. Results are cached in ~/.cache/agentkthx/tool_support.json.
# Test and cache tool support for all models
agentkthx models --tool-support

# Re-test (ignore cache)
agentkthx models --tool-support --no-cache
You can also force ReAct mode:
agent = Agent(model="qwen2.5:0.5b", force_react=True)
# Force ReAct mode via CLI
agentkthx run "What is 15 * 8?" --tools calculator --force-react
Model Families
Configured model families with optimized prompts:
- qwen2.5 — Native tool support, excellent performance
- llama3.1/3.2/3.3 — Native tool support
- mistral/mixtral — Native tool support
- gemma2/gemma3 — ReAct mode, special prompting
- granite/granitemoe — Native tool support
- phi3 — Native tool support
- deepseek — Native with
<think/>tag handling - qwen3 — ReAct mode, thinking model (auto think=False)
- qwen3.5 — Native on OpenAI, ReAct on OpenResponses
- glm (ZAI) — Native tool support via ZAI cloud API (GLM 4.5/4.6/4.7/5/5.1)
- dolphin — ReAct mode
Security Features
Built-in security for safe operation, with a runtime-toggleable mode:
- Two security modes —
max(default, all checks enabled) andoff(all checks disabled) - Toggle at runtime —
/security maxor/security offin chat mode, or--security offat startup - Command blocklist — Blocks dangerous shell commands (rm, sudo, etc.)
- Path validation — Prevents access to sensitive directories
- SSRF protection — Blocks requests to local/internal URLs
- Injection detection — Detects shell injection patterns (
&&,||,|,;,$(), backticks, etc.) - Dangerous tool confirmation —
--confirmflag requires interactive approval before shell, write, or edit operations - Audit logging — Shell, write, and edit operations logged to
~/.agentkthx/audit.log - Response size limits — Files capped at 512KB, HTTP responses at 256KB
# Default — all security checks enabled
agentkthx chat --backend openrouter --tools shell,python_repl

# Disable all security checks (use with caution — model can run any command)
agentkthx chat --backend openrouter --tools shell,python_repl --security off
In chat mode, toggle at runtime:
/security              — show current mode
/security max          — enable all checks (default)
/security off          — disable ALL checks (model can run any command,
                        read/write any path, fetch any URL)
Warning: --security off disables ALL safety checks. Only use when you trust the model and need unrestricted access (e.g., local dev with a fine-tuned model that legitimately uses &&, |, etc.).
Configuration
Environment variables:
# Backend URLs
OLLAMA_BASE_URL=https://your-ollama-server.com    # Default: http://localhost:11434
LLAMA_SERVER_BASE_URL=http://localhost:8764     # llama-server URL (default: 8764)

# BitNet plugin
BITNET_BASE_URL=http://localhost:8765              # BitNet server URL
BITNET_TUNNEL=https://your-tunnel.com              # Alternative BitNet URL

# ZAI plugin
ZAI_BASE_URL=https://api.z.ai                    # ZAI API endpoint
ZAI_API_KEY=sk-...                                # ZAI API key (required)
ZAI_FREE_ONLY=true                               # Restrict to free models only
ZAI_FREE_FALLBACK_MODEL=glm-4.5-flash            # Fallback when credits run out

# ACP plugin
ACP_BASE_URL=http://localhost:8766                 # ACP server URL

# TurboQuant plugin
TURBOQUANT_SERVER_PATH=llama-server                # llama-server binary path
TURBOQUANT_PORT=8764                               # TurboQuant server port
TURBOQUANT_CTX=8192                                # Context window size

# Agent settings
AGENTNOVA_BACKEND=ollama      # Default backend: ollama, llama-server, bitnet, zai, ...
AGENTNOVA_MODEL=qwen2.5:0.5b  # Default model
AGENTNOVA_MAX_STEPS=10        # Maximum reasoning steps
AGENTNOVA_DEBUG=false         # Enable debug output

# Retry settings
AGENTNOVA_RETRY_ON_ERROR=true          # Retry failed tool calls with error feedback
AGENTNOVA_MAX_TOOL_RETRIES=2           # Maximum retries per tool call failure
Check current configuration:
agentkthx config
agentkthx config --urls  # Show only URLs
CLI Options (run, chat, agent)
| Option | Description |
|---|---|
--api openre|openai|jev |
API mode: OpenResponses (default), OpenAI Chat-Completions, or JEV (System-One decisions via any LLM) |
--thinking off|auto|low|medium|high |
Thinking / reasoning effort: off (fastest, recommended for JEV), auto (default), or low/medium/high (forwarded as reasoning_effort for thinking-capable models) |
--think |
Display reasoning_content (chain-of-thought) in CLI output when the model emits it. Off by default. |
--response-format text|json |
Response format (Chat-Completions mode) |
--truncation auto|disabled |
Truncation behavior for long responses |
--soul <path> |
Load Soul Spec persona package |
--soul-level 1-3 |
Progressive disclosure level |
--num-ctx <tokens> |
Context window size (default: 4096) |
--timeout <seconds> |
Request timeout (default: 120) |
--acp |
Enable ACP (Agent Control Panel) logging |
--acp-url <url> |
ACP server URL |
--confirm |
Require y/N confirmation before dangerous tools (shell, write_file, edit_file) |
--session <name> |
Resume or create a persistent memory session |
--force-react |
Force ReAct text-based tool calling (skip native tool detection) |
--num-predict <tokens> |
Maximum tokens to generate |
--stream |
Stream output in real-time |
-q, --quiet |
Suppress header and summary output |
-v, --verbose |
Verbose output |
--no-retry |
Disable retry-with-error-feedback on tool failures |
--max-retries N |
Maximum retries per tool call failure (default: 2) |
--security max|off |
Security mode: max (default, all checks) or off (disable all checks) |
LocalClaw Redirect
The localclaw command is provided for backward compatibility:
# Both work identically
localclaw run "What is 2+2?"
agentkthx run "What is 2+2?"
Tests & Examples
AgentKthx includes a comprehensive suite of tests for validating agent capabilities across reasoning, knowledge, and tool usage:
# Basic agent test (no tools)
python -m agentkthx.examples.00_basic_agent

# Quick 5-question diagnostic
python -m agentkthx.examples.01_quick_diagnostic

# Tool usage tests (calculator, shell, datetime, file, python_repl)
python -m agentkthx.examples.02_tool_test

# Logic and reasoning tests (BBH-style)
python -m agentkthx.examples.03_reasoning_test

# GSM8K math benchmark (50 questions)
python -m agentkthx.examples.04_gsm8k_benchmark

# Common sense reasoning (BIG-bench)
python -m agentkthx.examples.05_common_sense

# Causal reasoning (BIG-bench)
python -m agentkthx.examples.06_causal_reasoning

# Logical deduction (BIG-bench)
python -m agentkthx.examples.07_logical_deduction

# Reading comprehension
python -m agentkthx.examples.08_reading_comprehension

# General knowledge (BIG-bench)
python -m agentkthx.examples.09_general_knowledge

# Implicit reasoning
python -m agentkthx.examples.10_implicit_reasoning

# Analogical reasoning
python -m agentkthx.examples.11_analogical_reasoning
Test Categories
| Test | Questions | Focus |
|---|---|---|
| Basic Agent | 1 | Single prompt, no tools |
| Quick Diagnostic | 5 | Calculator tool, multi-step reasoning |
| Tool Test | 10 | Calculator, shell, datetime, file, python_repl tools |
| Reasoning Test | 14 | Logic, deduction, patterns, spatial |
| GSM8K Benchmark | 50 | Math word problems |
| Common Sense | 25 | Physical properties, everyday reasoning |
| Causal Reasoning | 25 | Cause and effect relationships |
| Logical Deduction | 25 | Formal logic puzzles |
| Reading Comprehension | 25 | Passage-based Q&A |
| General Knowledge | 25 | Science, history, geography |
| Implicit Reasoning | 25 | Unstated assumptions and inference |
| Analogical Reasoning | 25 | Pattern matching and analogies |
Benchmark Results (Quick Diagnostic)
| Model | Score | Time | Tool Support |
|---|---|---|---|
| functiongemma:270m | 5/5 (100%) | ~20s | native |
| granite4:350m | 5/5 (100%) | ~50s | native |
| qwen2.5:0.5b | 5/5 (100%) | 38s | native |
| qwen2.5-coder:0.5b | 5/5 (100%) | 93s | native |
| qwen3:0.6b | 5/5 (100%) | 70s | react |
| deepseek-r1:1.5b | 5/5 (100%) | ~305s | native |
All tested models achieve 100% on the Quick Diagnostic. Native models are ~2x faster than ReAct models due to direct API tool calling.
Development
# Install dev dependencies
pip install -e ".[dev]"

# Run unit tests
pytest

# Format code
black agentkthx
ruff check agentkthx
License
MIT License - See LICENSE file for details.
Author
VTSTech — https://www.vts-tech.org
Contributing
Contributions welcome!
Changelog
See docs/CHANGELOG.md for detailed version history and release notes.
Migration from AgentNova
R06.0 renamed the project from AgentNova → AgentKthx. The rename was driven by name collisions in the AI agent space (multiple projects, Instagram accounts, etc. were using the AgentNova name).
What changed
| Old | New |
|---|---|
PyPI package: agentnova |
agentkthx |
CLI command: agentnova |
agentkthx |
Python import: import agentnova |
import agentkthx |
GitHub repo: VTSTech/AgentNova |
VTSTech/AgentKthx |
What stays the same (backward compat)
- ✅ The
agentnovaCLI command still works (redirects toagentkthx) - ✅
import agentnovastill works (re-exports fromagentkthx, emits DeprecationWarning) - ✅ All
AGENTNOVA_*env vars still work unchanged - ✅
localclawCLI command still works (redirects through toagentkthx) - ✅ All existing skills, souls, plugins, and configs continue to work
- ✅ SQLite persistent memory sessions remain compatible
Migration steps (recommended but not required)
# Uninstall old package (optional — both can coexist)
pip uninstall agentnova

# Install new package
pip install agentkthx

# Update your scripts (optional — old imports still work with a warning)
# Old: from agentnova import Agent
# New: from agentkthx import Agent
Why "AgentKthx"?
The name honors the IRC-era slang "kthx" (OK, thanks) — a callback to early internet culture. It's distinctive, memorable, and (most importantly) completely unused by any other AI agent project as of September 2026. The CLI binary agentkthx is short and easy to type.
1 maintainer

Release files for agentkthx 0.6.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| agentkthx-0.6.3.tar.gz | 437.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| agentkthx-0.6.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 896.2 kB
Release files / agentkthx-0.6.3.tar.gz
| Download URL | agentkthx-0.6.3.tar.gz |
|---|---|
| Size | 437.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8be089b2577f897960e0d3d7389de3e6c000c32d3b81e0f2fdc84d85a75d54b0
|
|
BLAKE2b-256 checksum How to use checksums |
d3d55dcbb69f5df9470d98ccd57de1ec1b8d14cdc2a463c16e6aac7e245cea4e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.4
|
Release files / agentkthx-0.6.3-py3-none-any.whl
| Download URL | agentkthx-0.6.3-py3-none-any.whl |
|---|---|
| Size | 459.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3be7fd754d88db38fcef530e5a171c749f67f39a75fe8e30399b8724aa69225c
|
|
BLAKE2b-256 checksum How to use checksums |
2714727348105eec8a0889db3435af9c8eb0489e7aa789349b22c53aee219657
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.4
|














