
AgentMandate
What is your AI agent actually allowed to do?


AgentMandate is a design-time authority analyser for agentic AI systems. An AI agent is a goal-directed system, usually built around a language model, whose runtime supplies tools, identity, memory, policy, and the ability to cause effects. Those tools may each look safe on their own. AgentMandate finds the limits the agent can exceed by combining individually permitted calls, and tells you when a release widened what it can reach.
A mandate is the reviewed, bounded unit of work the agent is allowed to carry out while its issuer may be absent. The manifest is the repository's machine-readable description of that mandate. AgentMandate analyses authority, not whether the model is likely to choose a particular path.
Alpha. Apache-2.0.
See it in thirty seconds
pip install "agentmandate[yaml]"
A payment-dispute agent has one reviewed mandate. Refunds are capped at 500 GBP per case, every refund needs human approval, and the mandate may move 500 GBP in total. It passes:
$ mandate lint examples/dispute-resolver.yaml
no single-manifest findings
The next release adds one tool. Read-only, moves no money, changes nothing:
  - name: search_cases
    effect: read
    produces: case
    unbounded: true
Nobody blocks that in review. It still passes lint, because no single tool is
wrong:
$ mandate reach examples/dispute-resolver-v2.yaml
BREACH  cumulative value 1000 GBP exceeds limit 500 GBP
  1. open_case(case#1)
  2. search_cases(case#2)
  3. issue_refund(case#1, 500 GBP)
  4. issue_refund(case#2, 500 GBP)
The cap is measured per case. The new tool hands the agent cases it did not open, and there is no fixed number of them, so a per-case ceiling stops bounding the mandate. Four individually permitted calls, both refunds approved by a human, 1,000 GBP reachable.

Why a config diff is not an authority diff
That change is one read-only tool in a pull request. Here is what it did to the agent's effective authority:
$ mandate diff examples/dispute-resolver.yaml examples/dispute-resolver-v2.yaml
authority diff  v1 -> v2
  + tool: gained search_cases
  + extractable value: 500 -> 2000 GBP
  + reachable breach: gained cumulative_value

verdict: WIDENING
a widening change needs named review before release
Exit code 1. A pull request shows what somebody typed. It does not show what the agent can now do, because reachability composes and text does not. Adding a read tool, relaxing an enum in a schema, or removing one precondition can each open a path that did not exist, and none of them look like a permission change.
Same reason git diff never replaced type checking. The question is not what
changed, it is what the change makes possible.
Put it in CI
- uses: mrwersa/agentmandate@v0.8.0
  with:
    manifest: mandate.yaml
    baseline: mandate-released.yaml   # optional: did this widen authority?
    source: src/agent                 # optional: has the manifest drifted?
Only the checks you give inputs for run, so a manifest alone is enough to
start. The counterexample renders in the job summary as a graph, and
sarif-file is an output you hand to github/codeql-action/upload-sarif so it
annotates the diff. fail-on: never reports without blocking, which is how to
turn this on over an existing repository without stopping everyone on day one.
Details, including why uploading the SARIF is deliberately your step and not the action's: docs/ci.md.
See the whole thing working: agent-release-gate takes one agent from Python source to a gate decision. Seven checks, one exit code, offline.
Where it fits, and what already exists
This is design-time analysis, not runtime enforcement. It runs in CI against a manifest and does not sit in the request path. The agent's model proposes a tool call; the surrounding runtime supplies the tools and state. The deployment's identity, authorisation, and application components still control whether the real-world effect occurs.
| Tool | What it does | Relationship |
|---|---|---|
| Policy in Amazon Bedrock AgentCore | Evaluates all applicable Cedar policies for each gateway tool invocation, with default-deny, forbid-wins, and analysis that flags always-allow and always-deny policies | Enforces each invocation. Its documented analysis is policy-level, not a model of a sequence of permitted calls |
| AgentWard | Runtime proxy enforcing policy per call, diffs two policy files | Enforces. Diffs declared text rather than reachable authority |
| AgentShield (affaan-m) | Scans agent configuration and MCP servers, drift gate over findings | Scans. Drift is over finding counts, not effective-authority direction; it is distinct from the aiconnai project with the same name |
| AgentGuard | Attribute-based access control for tool calls | Enforces |
| OPA, Cedar | Decide one authorisation at a time | Enforces |
Use those to enforce. AgentMandate is the offline half: it analyses sequences of individually permitted calls and compares effective authority—what the agent can actually reach—across releases.
If you already run AgentCore Policy, the gap is specific. The policy engine answers "may this principal invoke this tool now" by evaluating all applicable policies, and its documented analysis catches policy-level problems such as an unconditional allow. It does not model whether four separately permitted calls compose into a 1,000 GBP breach or whether a release widened what the agent can reach. AgentMandate is vendor-neutral and runs in CI before deployment, so it complements the gateway rather than duplicating it.
The closest prior art in a neighbouring domain is IAM Access Analyzer, which derives reachable access from policy by automated reasoning rather than waiting for a log event. This is that idea pointed at agent tool graphs.
The lint command deliberately overlaps the scanners above. A tool that reported only compound findings would need one of them running alongside it to be usable at all.
Starting from an existing agent
You do not have to write the first manifest by hand. From agent code:
$ mandate scan --source src/agent --agent dispute-resolver > mandate.yaml
That reads @tool, @function_tool, and @ai_function declarations and the
tools=[...] list they are passed to. It is a static read: nothing is
imported, nothing is executed, and the framework need not be installed.
One manifest describes one agent, so a source building two of them is refused
until you name the one you mean with --binding. A union would let reach
compose a path across tools that never share a run. What the read could not
enumerate is reported rather than dropped, because a tool missing from today's
manifest shows up in tomorrow's diff as authority that was never added. See
docs/inventory.md.
Or from an MCP catalogue:
$ mandate scan examples/mcp-tools.json --agent dispute-resolver > mandate.yaml
The skeleton is loadable straight away, and every judgement the catalogue could not supply is marked:
  - name: issue_refund
    # REVIEW: effect guessed from the name. read | write | irreversible
    effect: irreversible
    # REVIEW: does this spend the caller's authority or a service account?
    principal: caller
    requires: [case]
    # REVIEW: amount looks like a value argument. A ceiling needs scope_key too.
    # value_arg: amount
    # scope_key: case
    # ceiling: { amount: 0, currency: GBP }
    requires_approval: true
Unrecognised verbs are proposed as irreversible, because under-calling an
effect is the more expensive mistake.
Keeping the manifest honest
A manifest is a reviewed claim about one mandate. Two things quietly falsify it: somebody adds a tool to the agent and nobody edits the YAML, or a signature changes and the argument a ceiling was counted against stops existing.
$ mandate drift mandate.yaml --source src/agent
  UNDECLARED  issue_credit_note
      the agent is given this tool and the mandate does not declare it, so
      every reach and diff run so far analysed a smaller graph than the real one

  ARGUMENT    issue_refund
      value_arg names 'amount', which is not an argument this tool takes any
      more (it takes: case_id, total, currency). A ceiling counted against an
      argument that does not exist is not a ceiling.

  REMOVED     close_case
      the mandate declares this tool and the agent is not given it in source,
      so the analysis is defending authority nobody has.
The second finding is the one worth having. The manifest still parses, reach
still runs, and the ceiling counts against nothing.
A tool list the read cannot enumerate, such as tools=load_tools(), is itself
a finding. Reporting no drift from evidence that could not see the whole list
would be the false assurance this package exists to prevent.
Reviewed dynamic inventories can discharge that uncertainty only when drift
also receives the declaration, captured bytes, deployment selection, and an
explicit evaluation date. See the
dynamic-inventory contract.
The manifest
Reachability needs three facts per tool that an ordinary tool schema does not carry: the effect class, which argument spends value, and which scope the limit is measured against.
version: 1
agent: dispute-resolver
identity: spiffe://bank/agents/dispute-resolver

limits:
  total: { amount: 500, currency: GBP }
  depth: 8
  effects:                    # optional. an absent class is unbounded
    irreversible: 3           # at most three irreversible calls in one run

tools:
  - name: open_case
    effect: read              # read | write | irreversible
    produces: case            # mints a binding of scope "case"

  - name: issue_refund
    effect: irreversible
    principal: caller         # caller | service
    requires: [case]
    value_arg: amount
    scope_key: case           # the ceiling is per case
    ceiling: { amount: 500, currency: GBP }
    requires_approval: true
Asking for full preconditions and postconditions would be more expressive and would not get written. This is the minimum that makes compound analysis possible.
A cumulative constraint makes a decision depend on qualifying earlier
actions. Its limit is the configured bound; its consumed state is what the
runtime has already counted. In manifest v1, a ceiling is the maximum
cumulative value one tool may spend against one binding of its scope_key.
unbounded: true marks a tool that can be called repeatedly to mint fresh
bindings, which is what turns a per-scope limit into no mandate-wide bound at
all.
Commands
| Command | What it does |
|---|---|
mandate scan |
Derives a manifest skeleton from agent source (--source) or an MCP tools/list catalogue, with a REVIEW marker on every guess |
mandate drift |
Compares the declared mandate against the agent's source and fails when the two have separated |
mandate lint |
Single-manifest control checks: separation of duties, ungated irreversible effects, service-account principals, ceilings scoped to nothing |
mandate reach |
Bounded search over a manifest or reviewed --ir snapshot for a legal call sequence that breaches a limit, reported as a counterexample |
mandate ir |
Exports a manifest as canonical Authority IR or structurally validates a snapshot without accepting its evidence as authority |
mandate inventory |
Structurally validates a dynamic-inventory declaration without accepting its membership as authority |
mandate conditions |
Structurally validates a tool-condition or condition-context artifact without accepting it as authority |
mandate delegations |
Structurally validates a delegation attachment or chain without accepting it as authority |
mandate producers |
Structurally validates a finite-producer boundary without accepting its sources as authority |
mandate continuity |
Structurally validates continuity evidence or reconciles whether consumed authority safely survives a named transition |
mandate cedar |
Structurally validates managed policy evidence, aligns exact decisions with reviewed authority, or compares matched requests across policy revisions |
mandate diff |
Effective-authority comparison of two manifests, including limits, preconditions, approvals, effects, and scope minting. --record emits a change record |
mandate verify |
Replays recorded tool calls against the manifest and fails closed when evidence required by a declared control is missing. Reads OpenTelemetry traces with --otel |
mandate obligations |
Derives reviewable test obligations from reachable authority, and renders reviewed ones as an AgentVerity decision suite |
mandate scenarios |
Exports reachable breach paths with blank environment, agent-input, and expected-control fields for human review and execution by an external evaluation harness |
Every analysis command takes --json and exits non-zero on a finding, so they
drop into CI unchanged. scan and ir export write artifacts to standard
output and are not gates. Exit codes and CI wiring: docs/ci.md.
Canonical authority artifacts
Export reviewed intent once, validate the artifact at a boundary, then analyze that exact snapshot:
mandate ir export mandate.yaml > authority-ir.json
mandate ir validate authority-ir.json
mandate reach --ir authority-ir.json --json > authority-result.json
ir validate proves only that the snapshot is structurally valid. It does not
turn contested, heuristic, or unknown evidence into policy. reach --ir
applies the stricter manifest-v1 analysis profile and refuses anything except
exact, accepted reviewed facts from supported adapters. Its --json output is
a canonical, hashed result envelope containing the search boundary, ordered
counterexamples, and provenance graph. There is deliberately no import
command: parsing evidence is not accepting authority. The format and hash
boundaries are specified in docs/authority-ir.md.
Reviewed finite-producer evidence can replace an unbounded: true transition
with an evidence-backed concurrent maximum for one exact deployment, output,
and partition. Validate the boundary structurally, then pass every named source
byte, the explicit selection, and the review date to reach:
mandate producers validate reviewed-boundary.json
mandate reach mandate.yaml \
  --producer-boundary reviewed-boundary.json \
  --producer-source evidence/catalogue.json=catalogue.json \
  --producer-source evidence/outcomes.json=outcomes.json \
  --producer-source evidence/adapter.py=adapter.py \
  --producer-selection '{"source":"evidence/adapter.py","binding":"mint_token","producer":"reviewed.provider","producer_version":"1.0","partition_argument":"tenant","partition_binding":"reviewed-tenant","output_scope":"token"}' \
  --producer-as-of 2026-09-03 --json
The result is the canonical agentmandate.producers/v1 envelope. Unreviewed,
expired, incomplete, conflicting, mismatched, or unverifiable evidence remains
visible as a finding and leaves the stronger manifest authority unchanged.
Producer inputs currently refuse Authority IR, SARIF, Mermaid, conditional,
and delegation composition before output. The boundary describes analyzed
authority; it is not runtime quota enforcement. See
the bounded-producer contract.
Authority continuity is a separate lifecycle question: did consumed state stay attached to the same mandate across a session, handoff, or policy revision? The runnable example uses a common customer-support control: one mandate may refund at most GBP 1,000. It refunds GBP 600, reconnects in a fresh provider session, and attempts another GBP 600. The safe result denies the second refund because the first remains consumed. A reset would allow GBP 1,200 under one mandate even though each session looks locally compliant.
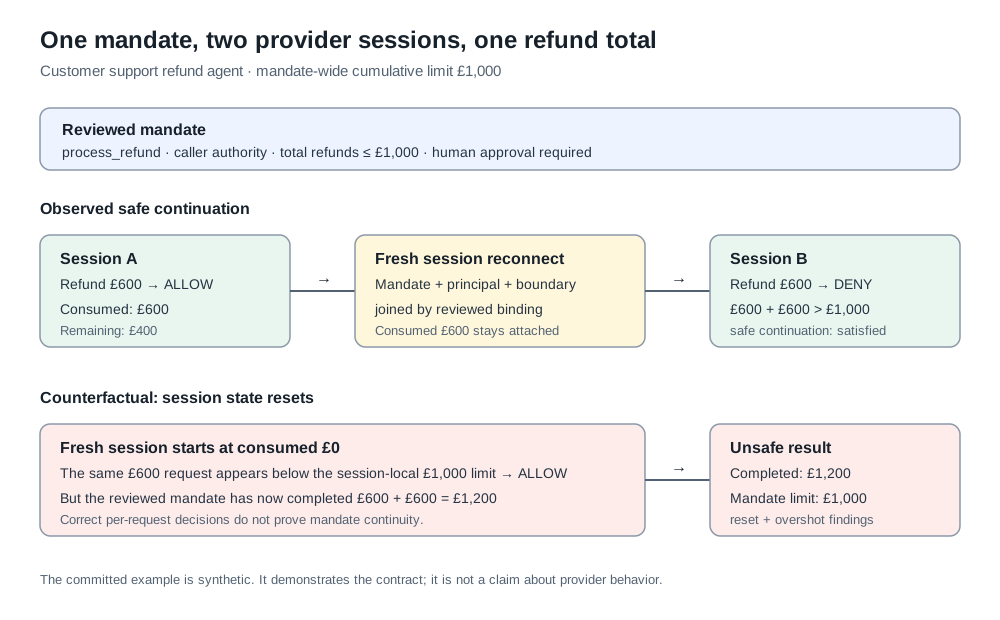
Run the deterministic synthetic example:
mandate continuity reconcile examples/continuity-refund/manifest.json \
  --continuity-provider examples/continuity-refund/provider.json \
  --continuity-source examples/continuity-refund/provider-control.json=examples/continuity-refund/provider-control.json \
  --continuity-binding examples/continuity-refund/binding.json \
  --continuity-binding-source examples/continuity-refund/binding-verification.json=examples/continuity-refund/binding-verification.json \
  --continuity-binding-source examples/continuity-refund/policy.json=examples/continuity-refund/policy.json \
  --continuity-as-of 2026-09-06T12:00:00Z --json
The canonical agentmandate.continuity/v1 result reports state continuity,
authority change, admission, comparability, issuer amendment, and a
three-valued safe_continuation verdict for each transition. A session
identifier is never treated as a mandate. Violated or unresolved continuity
exits 1 after complete output; malformed, incomplete, or unsupported composed
inputs exit 2 with empty standard output. See the
example walkthrough and
authority-continuity contract.
verify is what keeps the rest honest. A manifest nobody checks is a wish, and
the declaration drifts from the implementation the moment somebody ships a
connector change. For a spending tool, each trace record must carry the scope,
value, currency, approval state, and executing principal. Missing or malformed
control evidence does not pass as an empty value.
From authority to evaluation
AgentMandate produces two different test inputs:
obligationsnames consequential decision points that reviewed bounded decision tests should reachscenariospreserves compound counterexample paths that a multi-step scenario test should attempt
It does not execute either test. Promptfoo, LangSmith, AgentCore Evaluations, pytest, or an internal harness owns behaviour and outcome grading. AgentVerity can qualify the repeated bounded decisions after correctness passes.
reachability -> reviewed obligations and scenarios -> external evaluation
      ^                                               |
      |                                               v
manifest <- reviewed production incidents <- runtime policy and traces
Read the complete evaluation-loop workflow.
Scope
Read every finding as permitted by the reviewed mandate within this bounded abstraction. It is not proof that the model will choose the path or that an undeclared downstream invariant will accept it.
What this does not do, on purpose:
- No enforcement. No proxy, no runtime interception, no blocking.
- No data-flow reachability. Finding that a read tool feeds an exfiltration path needs taint labels the manifest does not carry. Cumulative value and scope minting are what the current model supports honestly.
- No model behaviour. Whether the agent would take a path is a different question from whether it may. This measures permitted authority.
- No session or budget broker. A runtime session is not automatically the reviewed mandate, and a configured cumulative limit is not enough unless its consumed state remains attached to that mandate. Continuity across sessions, handoffs, and policy revisions is evidence-backed roadmap work, not a claim made by the current reachability command.
- No inference of the fields that matter.
mandate scanreads agent source or an MCP catalogue and writes the skeleton, but it cannot know whether an effect is reversible or what a ceiling is measured against. It guesses conservatively and marks every guessREVIEW. Extract then annotate, never extract and trust.
Search is bounded by limits.depth. No breach at depth 8 is not proof that none exists at depth 20, and the report says when it truncated.
Documentation
- docs/README.md — a map of current contracts, experimental work, decision records, and evidence
- DESIGN.md — the authority model, why the search is shaped this way, and what was left out
- docs/evaluation-loop.md — how authority analysis, scenario evaluation, runtime policy, and production feedback remain distinct
- docs/test-obligations.md — decision-point obligations and the AgentVerity bridge
- CONTRIBUTING.md — branch and review workflow
- SECURITY.md — reporting, and what a manifest may contain
- STABILITY.md — what is guaranteed before 1.0
- docs/ci.md — the action, SARIF, the diff gate, and exit codes
- ROADMAP.md — adoption work, planned model extensions, and the path to 1.0
- CHANGELOG.md
Development
python -m pip install -e ".[dev]"
python -m pytest -q
python -m pytest -q --cov=agentmandate --cov-fail-under=100
ruff check .
main is protected. Every change lands through a pull request with CI green.
Status
Alpha. The version is in the badge above and on PyPI, so it is not repeated here where it would go stale. The authority model is the part most likely to change, because it has not yet been pointed at enough real tool graphs to know where it is too coarse. Issues describing a graph it models badly are the most useful thing you can file.
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file agentmandate-0.17.0.tar.gz.
File metadata
- Download URL: agentmandate-0.17.0.tar.gz
- Upload date:
- Size: 760.5 kB
- Tags: Source
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
2f5e0bc7ba2e4ceed4c6f1b32494218be5900f0d95c4c25b6d59a2ac8541ad2a
|
|
| MD5 |
172a29b933f420f8b46745b5261dbee2
|
|
| BLAKE2b-256 |
8a3a159e58a6d44d947f39291604d4e87bc256268217089ef26866aa2e465966
|
Provenance
The following attestation bundles were made for agentmandate-0.17.0.tar.gz:
Publisher:
release.yml on mrwersa/agentmandate
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
agentmandate-0.17.0.tar.gz -
Subject digest:
2f5e0bc7ba2e4ceed4c6f1b32494218be5900f0d95c4c25b6d59a2ac8541ad2a - Sigstore transparency entry: 2794461190
- Sigstore integration time:
-
Permalink:
mrwersa/agentmandate@59bfbc1cb2481e077daf1394f10c110cf7dd69ad -
Branch / Tag:
refs/heads/main - Owner: https://github.com/mrwersa
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@59bfbc1cb2481e077daf1394f10c110cf7dd69ad -
Trigger Event:
workflow_run
-
Statement type:
File details
Details for the file agentmandate-0.17.0-py3-none-any.whl.
File metadata
- Download URL: agentmandate-0.17.0-py3-none-any.whl
- Upload date:
- Size: 163.6 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
ef054699a8f240fd50f00b81cf0b712edece4e5d591f804a7a82f368f3a1753a
|
|
| MD5 |
b193a6ebcdc0684bd7d4a2887caf9071
|
|
| BLAKE2b-256 |
64d14d864eb0d31b5d31e31aff771f1b92bc745c1c20743af82f8b5947f401a2
|
Provenance
The following attestation bundles were made for agentmandate-0.17.0-py3-none-any.whl:
Publisher:
release.yml on mrwersa/agentmandate
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
agentmandate-0.17.0-py3-none-any.whl -
Subject digest:
ef054699a8f240fd50f00b81cf0b712edece4e5d591f804a7a82f368f3a1753a - Sigstore transparency entry: 2794461434
- Sigstore integration time:
-
Permalink:
mrwersa/agentmandate@59bfbc1cb2481e077daf1394f10c110cf7dd69ad -
Branch / Tag:
refs/heads/main - Owner: https://github.com/mrwersa
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@59bfbc1cb2481e077daf1394f10c110cf7dd69ad -
Trigger Event:
workflow_run
-
Statement type:














