AgentTwin
The VCR for agents. Record one agent run to a tape, replay it offline afterwards, and you have a unit test you can commit to CI.


Not a trace dashboard, not a monitoring platform: no service, no database, no dashboard, just one JSONL file and one ordinary assertion.
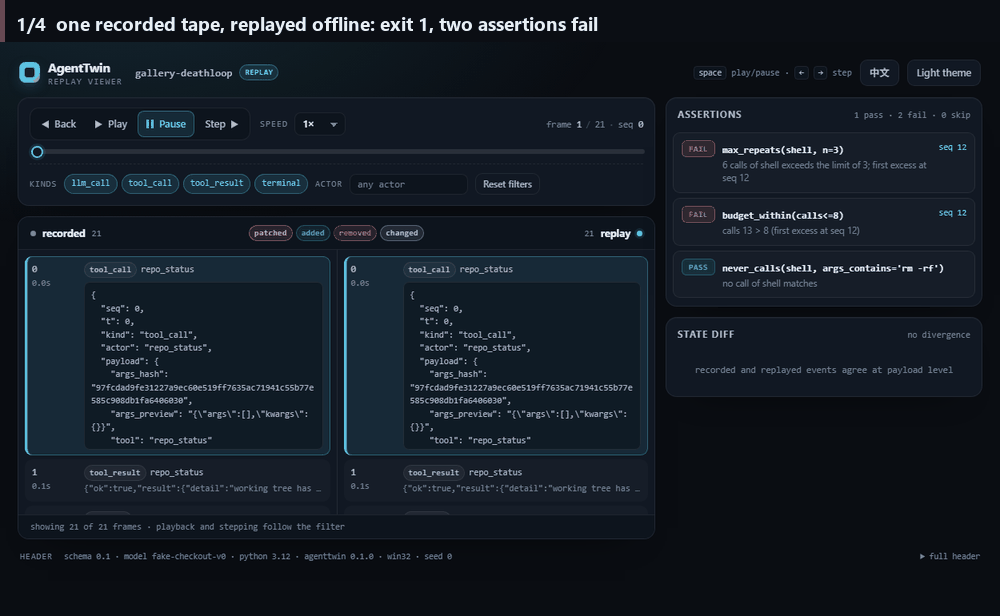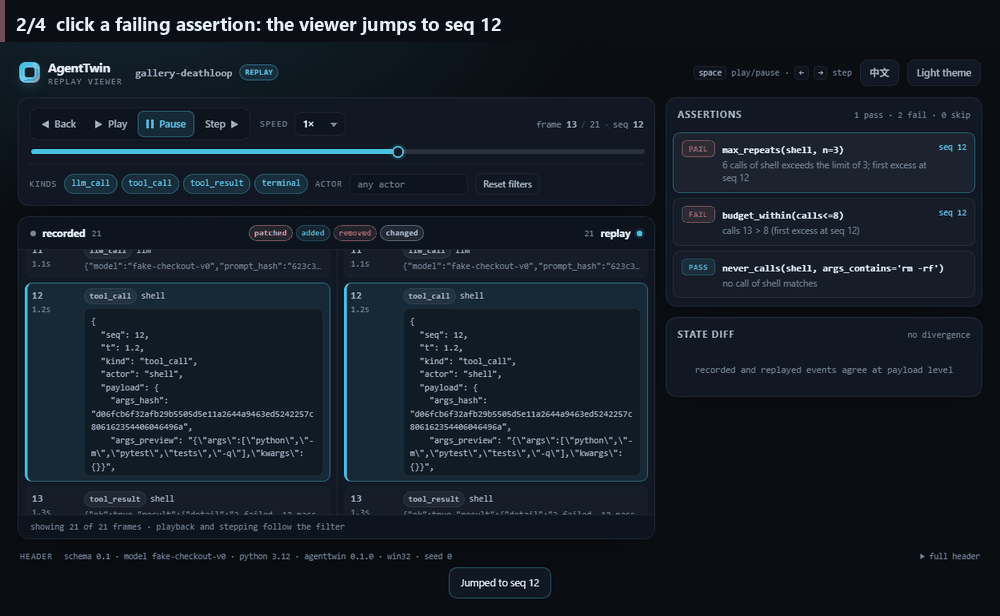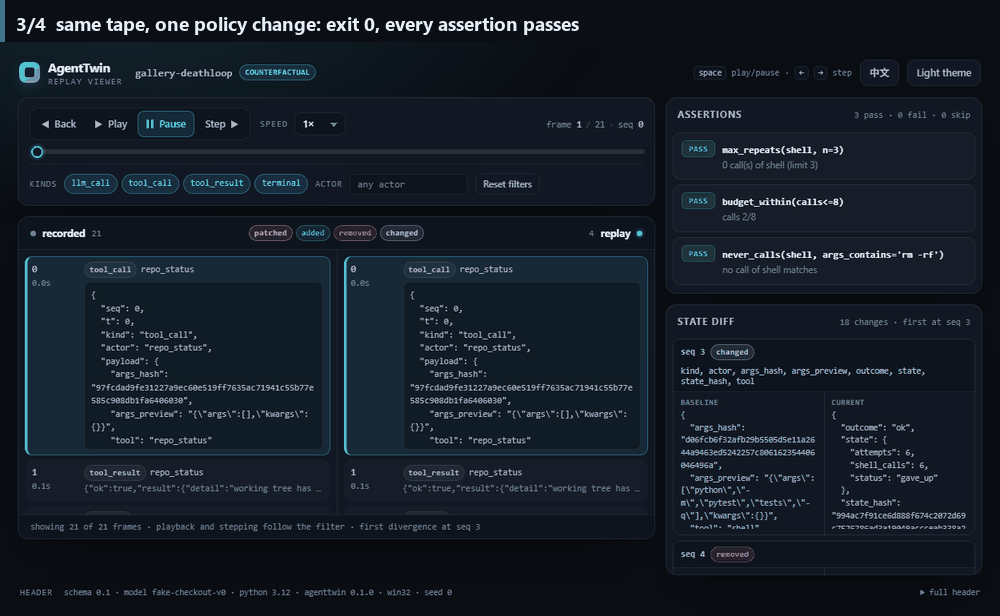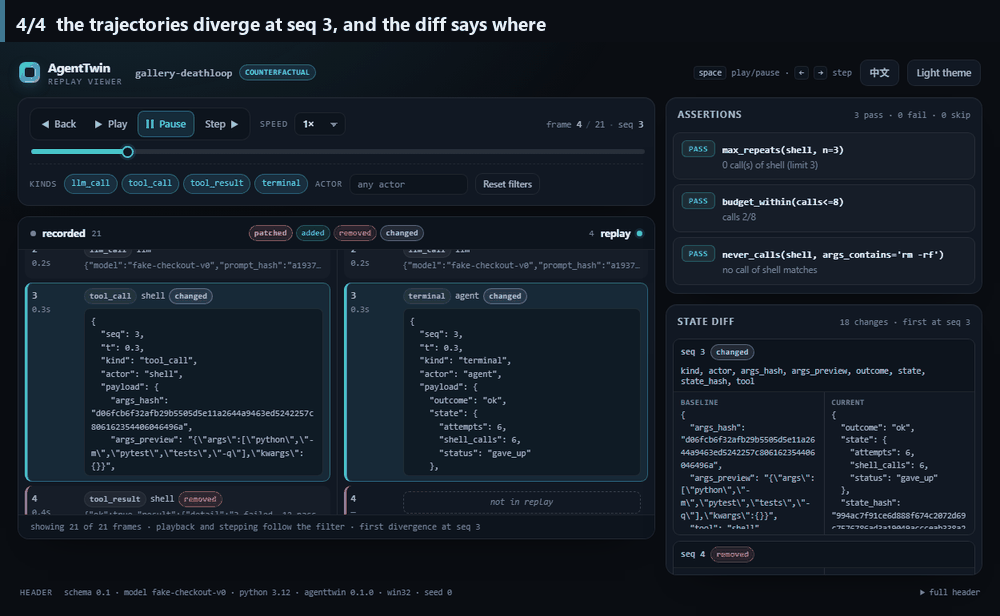
One committed tape, replayed twice with no model call: two assertions fail, one policy key changes, all three pass. What you are looking at is a single HTML file, opened from file:// — open the interactive demo, or watch the four-frame walkthrough.
Try it without installing anything. The online demo replays this tape twice, side by side, and shows the diff between the two runs.
The 30-second version:
- Recording calls the model and writes the request hash and the response into the tape;
- Replay calls no model and executes no real tool; it walks the tape event by event;
- A mismatch is a failure (not "run it again and see"); the assertion result ends up as a process exit code.
Every code block below was actually run against this repository. The Python and YAML blocks run in order on the tape recorded by the first one; the shell blocks only need the fixtures that ship inside the package. The output under a block is the output of that run.
1. Record one run
record_demo.py
"""Record one agent run to a JSONL tape.  Run: python record_demo.py"""
import json

from agenttwin import Twin


def fake_llm(request):                    # stands in for your model client
    return {"text": f"order {request['prompt']} is on its way"}


def lookup_order(order_id):               # stands in for a real, side-effecting tool
    return {"order_id": order_id, "status": "paid"}


def agent(llm, tools):                    # your agent: identical when replaying
    reply = llm({"prompt": "A-1"})
    order = tools["lookup_order"]("A-1")
    return {"answer": reply["text"], "status": order["status"]}


with Twin.record("checkout", out="checkout.jsonl",
                 llm=fake_llm, tools={"lookup_order": lookup_order}) as rec:
    rec.returned(agent(rec.llm, rec.tools()))     # leaving the block writes the tape

lines = open("checkout.jsonl", encoding="utf-8").read().splitlines()
header = json.loads(lines[0])
print("header:", header["schema_version"], header["trace_id"], "seed=" + str(header["seed"]))
print("events:", " -> ".join(json.loads(line)["kind"] for line in lines[1:]))
print("line 2:", lines[1][:96] + " ...")
Output:
header: 0.1 checkout seed=0
events: llm_call -> tool_call -> tool_result -> terminal
line 2: {"actor":"llm","kind":"llm_call","payload":{"prompt_hash":"1d783fcd9d8b565fc5b19532a4538139c2ab6 ...
Only the last three lines do the recording: run the agent once inside with Twin.record(...) as rec:, keep the return value with rec.returned(...), and the tape is written when the with block exits.
checkout.jsonl is plain JSONL: the first line is the header (schema_version / trace_id / seed / env_fingerprint / redaction), then one event per line; there are exactly 8 kinds: llm_call, tool_call, tool_result, state_patch, decision, human_input, error, terminal. Any text tool can read it.
2. Replay offline, then assert
Keep going in the same directory:
replay_demo.py
"""Replay the tape offline and assert on it.  Run after record_demo.py, same dir."""
import sys

from agenttwin import Twin, asserts


def agent(llm, tools):                    # the same agent, character for character
    reply = llm({"prompt": "A-1"})
    order = tools["lookup_order"]("A-1")
    return {"answer": reply["text"], "status": order["status"]}


report = Twin.load("checkout.jsonl").replay(agent)   # note: no llm=, no tools=
report.assert_(
    asserts.max_repeats("lookup_order", n=1),
    asserts.never_calls("refund"),
    asserts.terminates_within(10),
)

for result in report.results:
    status = "SKIP" if result.passed is None else ("PASS" if result.passed else "FAIL")
    print(f"{status}  {result.name}")
page = report.html("report.html")         # one self-contained file, opens from file://
print(f"html: {page.name} ({page.stat().st_size} bytes)")
print(f"divergent: {report.divergent}")
print(f"exit code: {report.exit_code}")
sys.exit(report.exit_code)
Output:
PASS  max_repeats(lookup_order, n=1)
PASS  never_calls(refund)
PASS  terminates_within(n=10)
html: report.html (56546 bytes)
divergent: False
exit code: 0
Two things that are easy to miss:
Twin.load("checkout.jsonl").replay(agent)takes nollm=and notools=: both the model and the tools come from the tape.llm(...)returns the response as recorded,tools["lookup_order"](...)returns the result as recorded, and the real functions are never called.sys.exit(report.exit_code)turns the assertion result into an ordinary exit code thatpytestor any CI consumes directly.
The same result in three shapes: report.markdown() (a table for humans), report.json() (for machines, with fixed top-level keys schema_version / trace_id / mode / divergent / exit_code / results / misses / drifts / diff / header), and report.html("report.html") (a single-file report, no external references, opens straight from file://; the byte count above varies a little with the tape and the environment). The viewer carries an English/Chinese switch in its header (the choice is remembered in localStorage); the recorded tape text itself is never translated.
The whole loop in one command
examples/hero.py is the animation at the top of this page: one tape from the fixtures that ship with the package, replayed twice, with one policy key changed between the two runs.
PYTHONPATH=src python examples/hero.py
Output:
tape: deathloop.jsonl  (21 events)
no model call, no network, no API key: the tape is the whole environment

before  mode=replay  recorded (no policy passed)
  exit code 1
  FAIL  max_repeats(shell, n=3)  -- 6 calls of shell exceeds the limit of 3; first excess at seq 12  (seq 12)
  FAIL  budget_within(calls<=8)  -- calls 13 > 8 (first excess at seq 12)  (seq 12)
  PASS  never_calls(shell, args_contains='rm -rf')  -- no call of shell matches

after   mode=counterfactual  policy={'max_attempts': 6, 'stop_on_failure': True}
  exit code 0
  PASS  max_repeats(shell, n=3)  -- 0 call(s) of shell (limit 3)
  PASS  budget_within(calls<=8)  -- calls 2/8
  PASS  never_calls(shell, args_contains='rm -rf')  -- no call of shell matches

first divergence: seq 3  (same tape, different trajectory)
reports: build/hero/before.html  build/hero/after.html
The word counterfactual in that banner is the point. A replay that carries a patch or its own policy is asking "what if", so the viewer labels it as one and its divergence is not a failure. A replay that carries neither has to reproduce the tape event for event, and divergence there is still exit code 2.
3. A changed request is a hard failure
"""A changed request is a hard failure, not a flaky test.  Run after record_demo.py."""
from agenttwin import DriftError, Twin


def changed_agent(llm, tools):
    llm({"prompt": "A-2"})                # one value changed in the request
    tools["lookup_order"]("A-1")


try:
    Twin.load("checkout.jsonl").replay(changed_agent)
except DriftError as exc:                 # PromptDrift / ArgsDrift / FingerprintDrift
    detail = exc.message.replace(exc.expected, exc.expected[:8] + "...").replace(exc.actual, exc.actual[:8] + "...")
    print(f"{type(exc).__name__}: {detail}")
    raise SystemExit(2)
Output:
PromptDrift: prompt_hash mismatch at seq 0: tape expects 1d783fcd..., controller sent 4250ccd5...
Note that it raises instead of noting the mismatch and carrying on: the replay stops right there, and SystemExit(2) turns it into a red job in CI.
4. Assertions can be data too (optional [yaml])
asserts.yaml:
# The same three checks as replay_demo.py, kept as data.
- {spec: max_repeats, args: {tool: lookup_order, n: 1}}
- {spec: never_calls, args: {tool: refund}}
- {spec: terminates_within, args: {n: 10}}
yaml_demo.py:
"""The same three checks as data.  Run after record_demo.py."""
from agenttwin import Twin, asserts


def agent(llm, tools):
    reply = llm({"prompt": "A-1"})
    order = tools["lookup_order"]("A-1")
    return {"answer": reply["text"], "status": order["status"]}


report = Twin.load("checkout.jsonl").replay(agent)
report.assert_(*asserts.load_yaml("asserts.yaml"))   # needs the [yaml] extra

for result in report.results:
    print(f"{'PASS' if result.passed else 'FAIL'}  {result.name}")
print("exit code:", report.exit_code)
Output:
PASS  max_repeats(lookup_order, n=1)
PASS  never_calls(refund)
PASS  terminates_within(n=10)
exit code: 0
What this tape does not promise
This section sits on the second screen because the most common question is "why did nothing change when I changed the temperature".
- What is frozen is the request and the response as recorded, not an inference pass you can run again. The model is not called a second time during replay, so sampling parameters (temperature / top_p / seed) do not participate and do not affect the result. Conversely, if your agent puts temperature into the request dict, it is part of the request, it changes the
prompt_hash, and it raisesPromptDrift: a changed request is supposed to fail. - No real side effects. A tool call during replay returns the
resultfrom the tape and the real function does not execute; there is no "call it for real while we are here" either,Twin.load(..., allow_real=True)raisesValueErroroutright. - No second model call. No network requests, no token bill; as many
llm_calls as the tape holds is as many replays as you get, and not one more appears out of nowhere. - All four drift kinds are hard failures.
DriftErrorand its three subclassesPromptDrift/ArgsDrift/FingerprintDriftare raised and stop the replay;TapeMiss(nothing recorded for that call) is not a drift and is not raised, but it also turnsexit_codeinto 2. - Replay is not "run the agent again". A tape hit does not re-execute the model or the tool, and a tape miss does not degrade into a real call.
What it does not do
| Not doing | Why |
|---|---|
| Calling the LLM again | Replay is worth exactly its determinism and its zero cost; for new results, record a new tape |
| Producing real side effects | Replay has to run in CI, on a machine with no network |
| Promising zero-config support for every framework | You write the agent as agent(llm, tools), or as an object with run(llm, tools); the tape knows nothing about your framework |
| SaaS / dashboard / database | The tape is a file and the report is a file; there is no backend to host |
| LLM-as-judge for pass or fail | The verdict has to be a deterministic assertion; asking a model to grade brings the uncertainty right back |
Install
python -m pip install agenttwin
Working on a clone of this repository instead, python -m pip install -e ..
An extra dependency is needed only to read and write YAML assertion files (pyyaml is imported lazily, inside load_yaml() only):
python -m pip install "agenttwin[yaml]"
Python 3.10+, zero third-party dependencies at runtime: pyproject.toml declares dependencies = [], and import agenttwin does not pull in pyyaml.
Exit codes
| code | meaning |
|---|---|
| 0 | everything PASSes (SKIP is not a failure) |
| 1 | an assertion FAILed |
| 2 | Drift / TapeMiss / SchemaError / incompatible schema |
| 3 | configuration or install error (missing tape, broken assertion file, missing dependency) |
--strict turns SKIP into 1, with precedence 3 > 2 > 1 > 0. Report.exit_code only ever produces 0 / 1 / 2; 3 comes from the CLI's usage and configuration layer (EXIT_USAGE = 3 in agenttwin.cli: the tape does not exist, --agent is malformed, the assertion file cannot be read).
Command line
Once installed, agenttwin and python -m agenttwin are the same entry point (agenttwin.cli:main), with five subcommands: record / replay / diff / doctor / gallery. To see the twelve fixtures shipped with the repo (six before/after pairs, one per assertion family), without recording a tape first:
python -m agenttwin gallery list
python -m agenttwin gallery run deathloop
Output (the second command prints the head of a report and its assertion table; the Diff / Fingerprint / Redaction sections in between are elided, ... marks the gap):
deathloop  Checkout retry loop
repaired  Checkout that stops on the failed observation
cleanup  Cleanup that deletes build/ with rm -rf
cleanup_guarded  Cleanup that leaves the tree alone
write_first  Release note written before the search
search_first  Release note that cites what it found
partial_receipt  Receipt without the charged total
full_receipt  Receipt that carries the total it charged
double_shipping  Order that pays shipping twice
correct_shipping  Order priced once
late_stop  Export poller that ignores completion
early_stop  Export poller that stops on completion

# AgentTwin report: gallery-deathloop

verdict: FAIL (exit code 1)
mode: replay
divergent: no
strict: no
...
| name | status | detail | first_offense_seq |
| --- | --- | --- | --- |
| max_repeats(shell, n=3) | FAIL | 6 calls of shell exceeds the limit of 3; first excess at seq 12 | 12 |
| budget_within(calls<=8) | FAIL | calls 13 > 8 (first excess at seq 12) | 12 |
| never_calls(shell, args_contains='rm -rf') | PASS | no call of shell matches | - |
gallery run deathloop exits 1 and gallery run repaired exits 0: same assertion set, and the only difference is whether the agent stops after the first failed observation. The other five pairs are the same shape: cleanup / cleanup_guarded (never_calls), write_first / search_first (call_order), partial_receipt / full_receipt (output_schema), double_shipping / correct_shipping (state_invariant), late_stop / early_stop (terminates_within). python -m agenttwin <command> --help shows the arguments of each command.
python -m agenttwin gallery run late_stop exits 1: the export is already complete, but the controller keeps polling until its finite guard returns at seq 9. python -m agenttwin gallery run early_stop exits 0: changing only stop_on_done returns at seq 3. Both use terminates_within(9), which requires the terminal seq to be strictly less than 9; the repeat and call budgets pass in both halves.
Two flags exist because a CI job is the thing that consumes them. agenttwin gallery run <id> --html PATH writes the same single-file viewer the library produces while keeping the Markdown output and the exit code exactly as they were (1 for deathloop, 0 for repaired). agenttwin diff A B --json [PATH] prints or writes the comparison as JSON — first_divergence_seq, per-change counts and the changed rows — and keeps the exit codes: 0 when the tapes agree, 1 when they diverge, 2 when one of them cannot be loaded.
Status
0.1.2 is published: agenttwin on PyPI, Apache-2.0, Python 3.10+. What changed in each release: CHANGELOG.md.
- Done and tested: the record/replay core (
Twin.record/Twin.load), drift detection, 9 assertion factories plus the combinators and YAML loading,TraceDiff,Report(JSON / Markdown / single-file HTML), the fiveagenttwinsubcommands, the openai-compatible adapter (duck-typed, no SDK import), and the twelve bundled fixtures (six before/after pairs). - Verified on GitHub: CI runs on every push to
main— nine jobs: Python 3.10–3.13 on Ubuntu, 3.12 on macOS and Windows, two stdlib-only import checks that uninstall PyYAML first, and a coverage job, plus a console-script step in each tests job. The first run failed on a fixture that usedplatform: linuxand therefore matched the realsys.platformon the Ubuntu runners; that was a test bug, fixed in6c5dae7, and the suite has been green since. - Verified from a clean install:
python -m pip install agenttwininto an empty venv from the public index givesagenttwin --version→agenttwin 0.1.2, all twelve fixtures fromagenttwin gallery list, the bundled single-file HTML replayer,gallery run repaired→ 0 andgallery run deathloop→ 1. A record → offline replay →.html()loop run from an empty directory outside the repository produced a report with no unfilled placeholder and no external resource in it. - Coverage floor: 82% of statements, declared once in
pyproject.toml([tool.coverage.report] fail_under) and enforced by thecoverageCI job, which fails the build when the number drops below it. The suite currently measures 94%. - Not done yet: any hosted service or dashboard. The examples above run with
PYTHONPATH=srcso they work without installing anything.
1 maintainer

Metadata
1 maintainer
Release files for agenttwin 0.1.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| agenttwin-0.1.2.tar.gz | 153.1 kB | Without provenance | Details for agenttwin-0.1.2.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| agenttwin-0.1.2-py3-none-any.whl | Python 3 | none | any | Details for agenttwin-0.1.2-py3-none-any.whl |
Total release size: 364.8 kB
Release files / agenttwin-0.1.2.tar.gz
| Download URL | agenttwin-0.1.2.tar.gz |
|---|---|
| Size | 153.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
22e119922d3ec9e111fe431981c02706fba78a7c5bbb34424b9a1d1431746008
|
|
BLAKE2b-256 checksum How to use checksums |
fed13b1c2efbb4438e82fd12be7e2dba4f8e632f6808204ac370f78bfe8e7c4b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.7
|
Release files / agenttwin-0.1.2-py3-none-any.whl
| Download URL | agenttwin-0.1.2-py3-none-any.whl |
|---|---|
| Size | 211.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7b767ac7da93151f8844b90a84f95de1a9f8adae7c6d09173dde80d58fdb1567
|
|
BLAKE2b-256 checksum How to use checksums |
3b3e1c66cb1ff1d469a71cfdb4aeb68adaf046b10592dce3aab3751bb0e0d7ce
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.7
|
Security for agenttwin 0.1.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.