
Agentvow
When a coding agent says "all tests pass" or "nothing else depends on this", Agentvow checks that against the repository and tells you what it could confirm, what it contradicted, and what it could not check. It runs outside the agent (an agent must not grade itself), uses no LLM, and never approves, rejects or merges anything.
Status: 0.1.0 release candidate (prototype). Not a safety verdict. Python repositories; running tests needs macOS or Linux (bubblewrap). See Known limits and docs/SECURITY_MODEL.md.
Name: Agentvow (an agent's claims are vows; this checks them). It was developed under the working name AgentMirror; the name was changed because that name, and its Python module, belong to an unrelated PyPI project.
Quick start
pip install agentvow                    # once published; from a checkout: pip install .  or: pip install dist/agentvow-0.1.0-py3-none-any.whl  (no dependencies; Python 3.10+)
agentvow doctor --repo /path/to/project       # checks your setup and runs the whole hook path end to end
echo "I changed X. All 12 tests pass. Nothing else depends on it." | agentvow check --repo /path/to/project
agentvow check --repo . --transcript msg.txt --run-tests --python venv/bin/python   # also run the tests (sandboxed, macOS/Linux)
agentvow check --repo . --transcript msg.txt --ci --html report.html                # also read CI results; write a visual report
Exit codes: 0 no contradiction found (scoped), 1 review required, 2 insufficient evidence, 3 tool error. Other options: --markdown, --json, --session <Claude Code session.jsonl>, --base <ref>, --test-cmd, --test-timeout, --setup auto, --new-test-failures review.
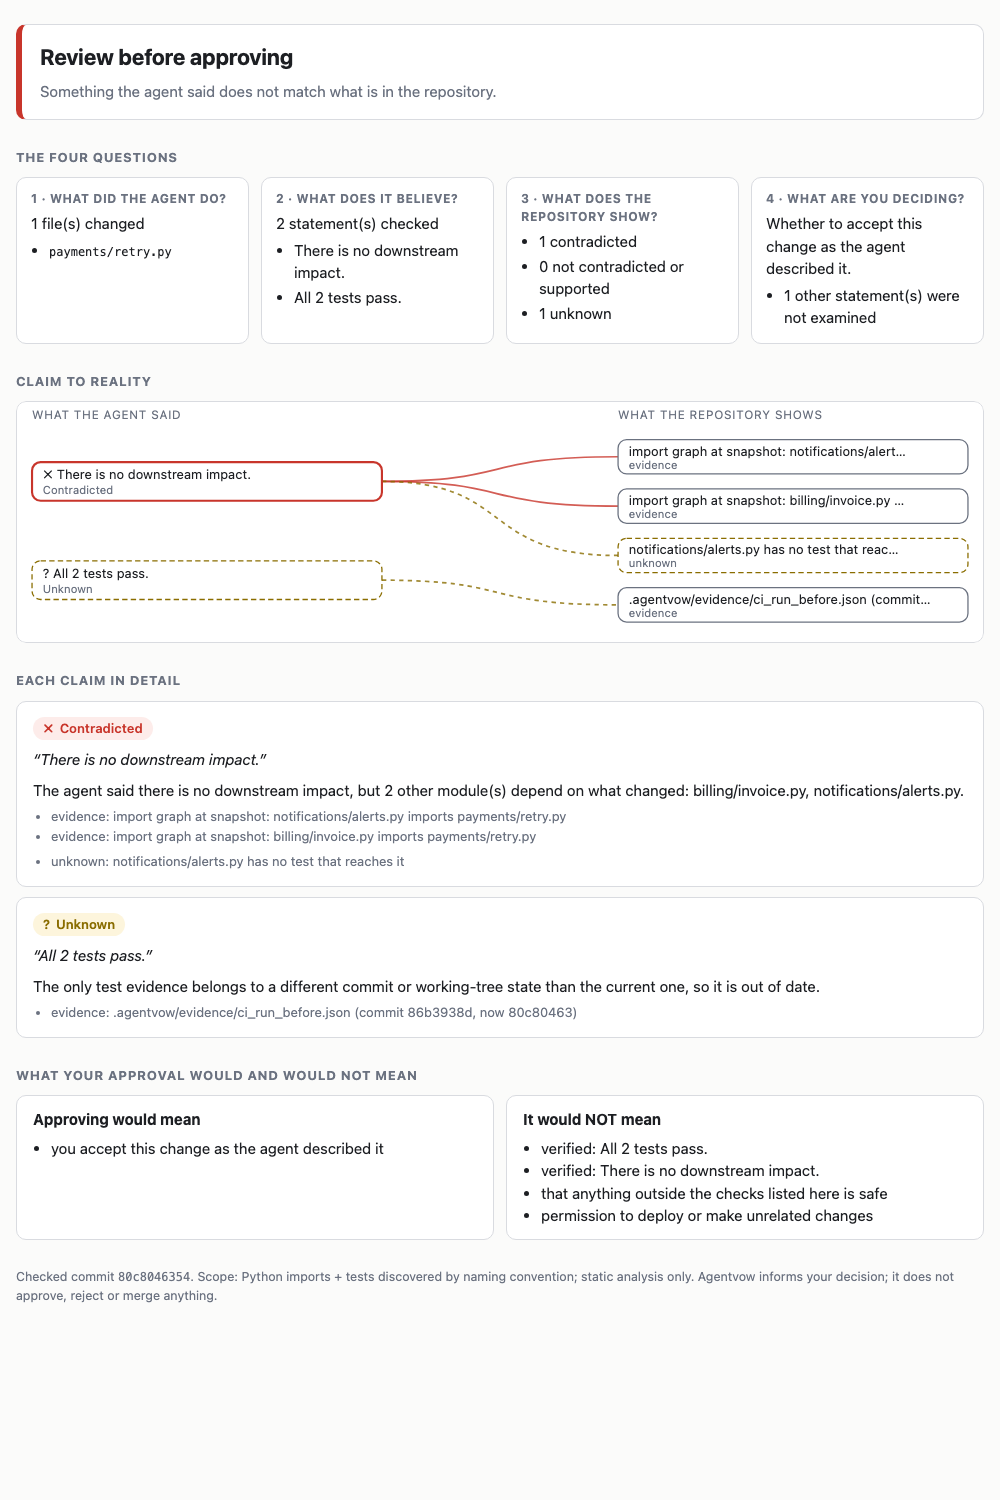
See it in 10 seconds
agentvow demo # builds a small demo repo, checks "no downstream impact" against it and writes a sealed result
In VS Code run Agentvow: Try the demo: it shows the red verdict panel and copies a prompt you can paste into Copilot (in the demo folder, with the hook added) to see the same on a real agent turn.
What it checks
| Claim in the agent's message | How it is checked |
|---|---|
| "tests pass" (with an optional count) | tests run at the base and head states in a sandbox; a regression is a test that passed before and fails now; the claimed count is compared; failures that also occur at base are treated as environmental; deleted/skipped tests and modified existing tests prevent a plain "supported"; CI test jobs for the commit are read with --ci |
| "backward compatible" | static public-API diff of changed Python files (removed or renamed names and parameters, new required parameters, __init__ re-exports) |
| "no downstream impact" | static import graph (src layout aware); deleted modules, dynamic imports and non-Python code make the result UNKNOWN |
Anything else the agent says is listed as unchecked, and the report says how many statements were not examined. UNKNOWN is a real result: missing evidence, a failed collector, an unreadable message or an unfamiliar format never become "OK". The best possible status is NO CONTRADICTION FOUND (scoped, not a safety verdict).
Where it plugs in (and how well each is verified)
| Where | How | Status |
|---|---|---|
| GitHub Copilot in VS Code (agent chat, Copilot CLI engine) | .github/hooks/agentvow.json (extension command Agentvow: Add the agent hook) |
Verified on a real run: Copilot ran the hook, its payload and session file (events.jsonl) are parsed, the result is sealed and detected by the extension. Hooks are a Preview feature |
| Claude Code | Stop hook agentvow check --hook |
Session format and payload verified |
| Copilot CLI (terminal), Copilot cloud agent | same hook file | From documentation only |
| Codex, Cursor, Gemini CLI | their stop hooks → agentvow check --hook |
Not tested; AGENTVOW_DEBUG=1 records only the structure of what an agent sends so an adapter can be built |
| Any agent's pull request | GitHub Action action.yml: PR description as the claim, CI results, comment + report |
Shell step tested locally; not run on GitHub |
| Anything else | paste or pipe the message; VS Code commands for clipboard/selection | Tested |
Seeing the verdict
Copilot keeps only decision/reason from a hook's output, so a hook cannot add text to Copilot's own reply. The verdict is shown in:
- the VS Code status bar, a notification (
agentvow.notify:reviewdefault,always,never) and the report panel; the extension logs to the Agentvow output channel; @agentvowin the chat: prints the last sealed verdict as its own message (not part of Copilot's reply);agentvow agent-instructions --write .github/copilot-instructions.md: tells the chat agent to run the check itself and show its output (works through the model; the agent chooses the draft it checks, so the independent hook remains the check that does not depend on the agent);agentvow check --hook --feedback-to-agent(opt-in): asks the agent, once, to revise an answer with a contradicted claim (the only mode in which the hook can block);agentvow check --hook --background-tests(opt-in): the hook answers at once with what it can see, then runs your tests in the background (sandboxed, macOS/Linux) and updates the verdict when they finish, so slow suites do not hit the agent's hook timeout. Changes are counted since the previous check in the repository (not since your last commit), so earlier uncommitted work is not blamed on the agent.- experimental, off by default: a
UserPromptSubmithook (agentvow prompt-hook) that tells the agent the last verdict on your next prompt. In one live session the first delivery coincided with a Copilot chat that stalled (cause unproven). Details and a step-by-step live test:docs/LIVE_TESTING.md.
Install the VS Code extension
"/Applications/Visual Studio Code.app/Contents/Resources/app/bin/code" --install-extension dist/agentvow-0.1.0.vsix --force
Then Developer: Reload Window. The extension is plain JavaScript with no dependencies; it calls the agentvow command, which must be reachable by path (use the full path in agentvow.command if VS Code does not see your shell's PATH).
Safety in one paragraph
Running tests executes the project's code. It runs in a sandbox: macOS sandbox-exec or Linux bubblewrap (apt install bubblewrap; on Ubuntu 24.04+ unprivileged user namespaces must be allowed, e.g. sysctl kernel.apparmor_restrict_unprivileged_userns=0; agentvow doctor tells you). Network denied, file writes only inside a throwaway worktree plus a private scratch directory, signing key and credential folders unreadable, whole process group killed on timeout; on Windows, or where no working sandbox exists, Agentvow refuses to run tests (static checks and CI reading still work; agentvow doctor says which). The Linux sandbox makes the whole filesystem read-only; the macOS one allows OS services by default (a review showed a Mach service could still write outside it; common helpers like open/defaults/osascript are blocked, which is not complete containment). Results are HMAC-sealed with a key outside the repository, which stops casual forgery and files copied from elsewhere, but test results are only as trustworthy as the repository's own test code: a hostile conftest.py can print fake pass counts. Treat a "no contradiction" on an untrusted repository accordingly. Text from agents and repositories is length-bounded, stripped of control characters and escaped in reports and in plain-text output. Full model, reviews and open weaknesses: docs/SECURITY_MODEL.md, docs/research/RISKS.md.
Evidence so far (and what it does not show)
- Agent PR claims in the wild (688 public Python PRs from five agents that claim tests pass): CI test jobs could judge 33%; of those about 27% had a failing test job (clustered in a few repositories; not an agent ranking).
docs/research/CI_CLAIM_STUDY.md - Local runs on unfamiliar repos with automatic setup reached a verdict for 29% of PRs; half stopped on a missing dependency.
docs/research/LOCAL_COVERAGE.md - Planted faults (authored by us, 15 real PRs): 26 of 30 test-detectable breaks attributed, no false alarms. Detection on real bad PRs is not demonstrated (the zero-config setup could not run most of them).
docs/research/PLANTED_FAULTS.md,docs/research/DETECTION_STUDY.md - Novelty is not claimed: the closest prior work (Assay, EA-Graph, backcheck and others) and what remains open are in
docs/research/NOVELTY_BOUNDARY.md.
Known limits
Python only for impact and API checks; claim extraction is rule-based (three claim types); CI job classification is by name; trivialised tests are not detected; tests that start daemons can hang under the sandbox (ends at --test-timeout); hooks and Copilot integration are Preview features and only the Copilot CLI engine inside VS Code has been observed live; Windows has no test sandbox (tests are refused there); the chat-injection routes go through the model; one annotator behind every hand-validated number.
Develop and validate
scripts/validate_all.sh        # tests, consistency, secret scan, wheel + clean-room install, extension package, leaks (builds dist/)
python3 -m unittest discover -s tests && node --test vscode/test/extension.test.js vscode/test/helpers.test.js
Design and research: docs/research/ (start with NOVELTY_BOUNDARY.md, RISKS.md, PILOT_P0.md), product notes docs/product/, rules for contributors CLAUDE.md. License: MIT (LICENSE).
1 maintainer

Metadata
1 maintainer
Release files for agentvow 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| agentvow-0.1.0.tar.gz | 275.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| agentvow-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 333.1 kB
Release files / agentvow-0.1.0.tar.gz
| Download URL | agentvow-0.1.0.tar.gz |
|---|---|
| Size | 275.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
479e768c20461bcd2e18816e80f844108aaa4573ca6c23220459a10243677bca
|
|
BLAKE2b-256 checksum How to use checksums |
80ef23a854c243bd0a016e9dd97efbe30c8694a942879198af56e0d58f6d59a3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 9, 2026.
Transparency logRelease files / agentvow-0.1.0-py3-none-any.whl
| Download URL | agentvow-0.1.0-py3-none-any.whl |
|---|---|
| Size | 57.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3544005407a23cdcb7d4d320426ac1053c30a6a92a0f28acdfa562139121a2da
|
|
BLAKE2b-256 checksum How to use checksums |
96e05ef2f2395420cb8513ca188ebf9329f5afd537334d712749aa305cd133f7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 9, 2026.
Transparency log













